
README
Awesome-LLM-as-a-judge Survey


Awesome-LLM-as-a-judge: A Survey
This repo include the papers discussed in our latest survey paper on Awesome-LLM-as-a-judge.
Our official websit: Website
:book: Read the full paper here: Paper Link
🔔 News
2025-5We update our paper list and include papers of LLM-as-a-judge in April & May 2025!2025-4We update our paper list and include papers of LLM-as-a-judge in March 2025!2025-3Want to learn more about risks and safety problems of using LLM-based annotation? Check out our new paper list on AI supervision risk!2025-3We update our paper list and include papers of LLM-as-a-judge in February 2025, together with papers about thinking LLM as a judge!2025-2We update our paper list and include papers of LLM-as-a-judge in January 2025!2025-2Check our new paper about preference leakage in LLM-as-a-judge!2024-12Also check our paper list and survey on LLM-based data annotation and synthesis!2024-12We update our paper list and include papers of LLM-as-a-judge in December 2024!2024-12We update the slides, talk and report of our paper, check them in our Website!
Reference
If our survey is useful for your research, please kindly cite our paper:
@article{li2024llmasajudge,
  title   = {From Generation to Judgment: Opportunities and Challenges of LLM-as-a-judge},
  author  = {Dawei Li and Bohan Jiang and Liangjie Huang and Alimohammad Beigi and Chengshuai Zhao and Zhen Tan and Amrita Bhattacharjee and Yuxuan Jiang and Canyu Chen and Tianhao Wu and Kai Shu and Lu Cheng and Huan Liu},
  year    = {2024},
  journal = {arXiv preprint arXiv: 2411.16594}
}
Overview of Awesome-LLM-as-a-judge:
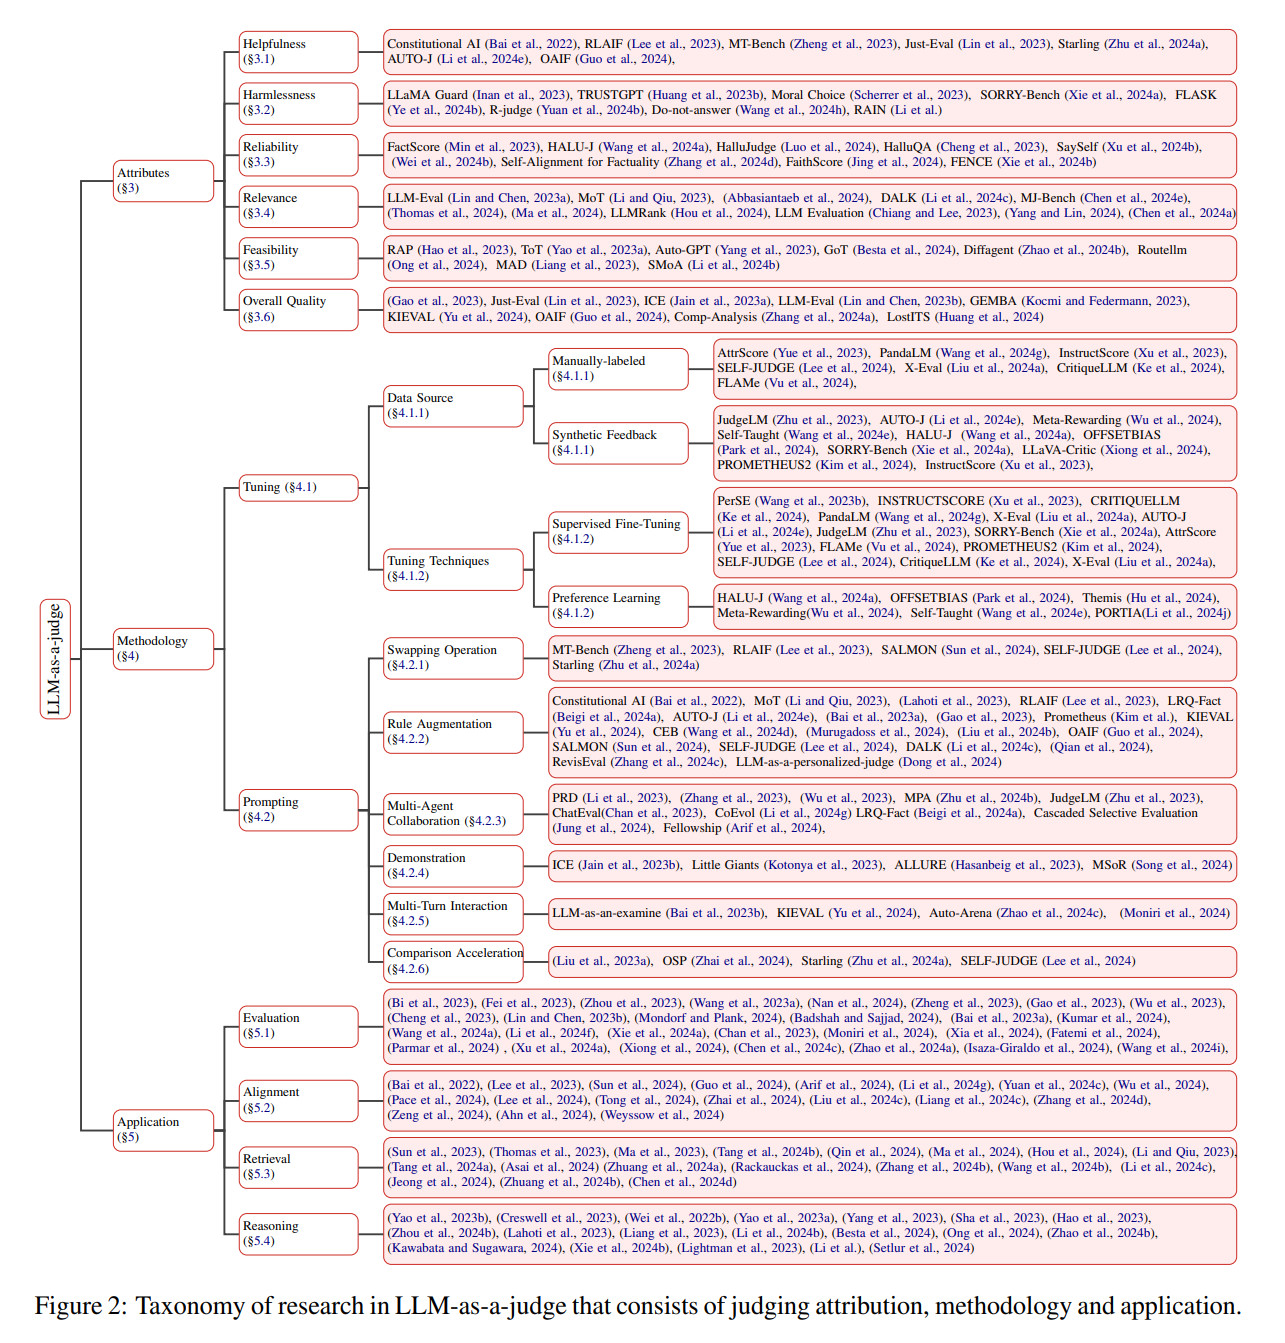
Table of Content (ToC)
- Awesome-LLM-as-a-judge Survey
Thinking LLM-as-a-judge
Papers
- MCTS-Judge: Test-Time Scaling in LLM-as-a-Judge for Code Correctness Evaluation. ArXiv preprint (2025) [Paper]
- Learning to Plan & Reason for Evaluation with Thinking-LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Verdict: A Library for Scaling Judge-Time Compute. ArXiv preprint (2025) [Paper]
- AgentRM: Enhancing Agent Generalization with Reward Modeling. ArXiv preprint (2025) [Paper]
- JudgeLRM: Large Reasoning Models as a Judge. ArXiv preprint (2025) [Paper]
- GenPRM: Scaling Test-Time Compute of Process Reward Models via Generative Reasoning. ArXiv preprint (2025) [Paper]
- Inference-Time Scaling for Generalist Reward Modeling. ArXiv preprint (2025) [Paper]
- RM-R1: Reward Modeling as Reasoning. ArXiv preprint (2025) [Paper]
- J1: Incentivizing Thinking in LLM-as-a-Judge via Reinforcement Learning. ArXiv preprint (2025) [Paper]
Update
07/2025
04/2025 & 05/2025
- Multi-Agent LLM Judge: automatic personalized LLM judge design for evaluating natural language generation applications. ArXiv preprint (2025) [Paper]
- Prompt-Reverse Inconsistency: LLM Self-Inconsistency Beyond Generative Randomness and Prompt Paraphrasing. ArXiv preprint (2025) [Paper]
- Do LLM Evaluators Prefer Themselves for a Reason?. ArXiv preprint (2025) [Paper]
- M-Prometheus: A Suite of Open Multilingual LLM Judges. ArXiv preprint (2025) [Paper]
- HypoEval: Hypothesis-Guided Evaluation for Natural Language Generation. ArXiv preprint (2025) [Paper]
- AgentAda: Skill-Adaptive Data Analytics for Tailored Insight Discovery. ArXiv preprint (2025) [Paper]
- Benchmarking Adversarial Robustness to Bias Elicitation in Large Language Models: Scalable Automated Assessment with LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- AgentRewardBench: Evaluating Automatic Evaluations of Web Agent Trajectories. ArXiv preprint (2025) [Paper]
- MLRC-Bench: Can Language Agents Solve Machine Learning Research Challenges?. ArXiv preprint (2025) [Paper]
- Reasoning Court: Combining Reasoning, Action, and Judgment for Multi-Hop Reasoning. ArXiv preprint (2025) [Paper]
- Evaluation Under Imperfect Benchmarks and Ratings: A Case Study in Text Simplification. ArXiv preprint (2025) [Paper]
- An LLM-as-a-judge Approach for Scalable Gender-Neutral Translation Evaluation. ArXiv preprint (2025) [Paper]
- Efficient MAP Estimation of LLM Judgment Performance with Prior Transfer. ArXiv preprint (2025) [Paper]
- Validating LLM-Generated Relevance Labels for Educational Resource Search. ArXiv preprint (2025) [Paper]
- Assessing Judging Bias in Large Reasoning Models: An Empirical Study. ArXiv preprint (2025) [Paper]
- CodeVisionary: An Agent-based Framework for Evaluating Large Language Models in Code Generation. ArXiv preprint (2025) [Paper]
- Pairwise or Pointwise? Evaluating Feedback Protocols for Bias in LLM-Based Evaluation. ArXiv preprint (2025) [Paper]
- Automatic Evaluation Metrics for Document-level Translation: Overview, Challenges and Trends. ArXiv preprint (2025) [Paper]
- Support Evaluation for the TREC 2024 RAG Track: Comparing Human versus LLM Judges. ArXiv preprint (2025) [Paper]
- Evaluating Judges as Evaluators: The JETTS Benchmark of LLM-as-Judges as Test-Time Scaling Evaluators. ArXiv preprint (2025) [Paper]
- LLM-as-a-Judge: Reassessing the Performance of LLMs in Extractive QA. ArXiv preprint (2025) [Paper]
- Leveraging LLMs as Meta-Judges: A Multi-Agent Framework for Evaluating LLM Judgments. ArXiv preprint (2025) [Paper]
- Spark: A System for Scientifically Creative Idea Generation. ArXiv preprint (2025) [Paper]
- LLM-Evaluation Tropes: Perspectives on the Validity of LLM-Evaluations. ArXiv preprint (2025) [Paper]
- Evaluate-and-Purify: Fortifying Code Language Models Against Adversarial Attacks Using LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- AutoLibra: Agent Metric Induction from Open-Ended Feedback. ArXiv preprint (2025) [Paper]
- To Judge or not to Judge: Using LLM Judgements for Advertiser Keyphrase Relevance at eBay. ArXiv preprint (2025) [Paper]
- Benchmarking LLM Faithfulness in RAG with Evolving Leaderboards. ArXiv preprint (2025) [Paper]
- Sentient Agent as a Judge: Evaluating Higher-Order Social Cognition in Large Language Models. ArXiv preprint (2025) [Paper]
- From Calculation to Adjudication: Examining LLM judges on Mathematical Reasoning Tasks. ArXiv preprint (2024) [Paper]
- J1: Incentivizing Thinking in LLM-as-a-Judge via Reinforcement Learning. ArXiv preprint (2025) [Paper]
- ContrastScore: Towards Higher Quality, Less Biased, More Efficient Evaluation Metrics with Contrastive Evaluation. ArXiv preprint (2025) [Paper]
- Meta-Evaluating Local LLMs: Rethinking Performance Metrics for Serious Games. ArXiv preprint (2025) [Paper]
- CliniChat: A Multi-Source Knowledge-Driven Framework for Clinical Interview Dialogue Reconstruction and Evaluation. ArXiv preprint (2025) [Paper]
- The Great Nugget Recall: Automating Fact Extraction and RAG Evaluation with Large Language Models. ArXiv preprint (2025) [Paper]
- Same evaluation, more tokens: On the effect of input length for machine translation evaluation using Large Language Models. ArXiv preprint (2025) [Paper]
- Unbiased Evaluation of Large Language Models from a Causal Perspective. ArXiv preprint (2025) [Paper]
- Spec2Assertion: Automatic Pre-RTL Assertion Generation using Large Language Models with Progressive Regularization. ArXiv preprint (2025) [Paper]
- LCES: Zero-shot Automated Essay Scoring via Pairwise Comparisons Using Large Language Models. ArXiv preprint (2025) [Paper]
- Generative AI for Autonomous Driving: Frontiers and Opportunities. ArXiv preprint (2025) [Paper]
- From Rankings to Insights: Evaluation Should Shift Focus from Leaderboard to Feedback. ArXiv preprint (2025) [Paper]
- Drug recommendation system based on symptoms and user sentiment analysis (DRecSys-SUSA). ArXiv preprint (2025) [Paper]
- Building Trust in AI via Safe and Responsible Use of LLMs. ArXiv preprint (2025) [Paper]
- SymPlanner: Deliberate Planning in Language Models with Symbolic Representation. ArXiv preprint (2025) [Paper]
- Which agent causes task failures and when? on automated failure attribution of llm multi-agent systems. ArXiv preprint (2025) [Paper]
- Sentiment and Social Signals in the Climate Crisis: A Survey on Analyzing Social Media Responses to Extreme Weather Events. ArXiv preprint (2025) [Paper]
- Context over Categories: Implementing the Theory of Constructed Emotion with LLM-Guided User Analysis. ArXiv preprint (2025) [Paper]
- Benchmarking LLM-based Relevance Judgment Methods. ArXiv preprint (2025) [Paper]
- Explainable AI in Usable Privacy and Security: Challenges and Opportunities. ArXiv preprint (2025) [Paper]
- Persona-judge: Personalized Alignment of Large Language Models via Token-level Self-judgment. ArXiv preprint (2025) [Paper]
- A Human-AI Comparative Analysis of Prompt Sensitivity in LLM-Based Relevance Judgment. ArXiv preprint (2025) [Paper]
- Heimdall: test-time scaling on the generative verification. ArXiv preprint (2025) [Paper]
- Deep Reasoning Translation via Reinforcement Learning. ArXiv preprint (2025) [Paper]
- QM-ToT: A Medical Tree of Thoughts Reasoning Framework for Quantized Model. ArXiv preprint (2025) [Paper]
- NorEval: A Norwegian Language Understanding and Generation Evaluation Benchmark. ArXiv preprint (2025) [Paper]
- Beyond Accuracy: The Role of Calibration in Self-Improving Large Language Models. ArXiv preprint (2025) [Paper]
- Do We Truly Need So Many Samples? Multi-LLM Repeated Sampling Efficiently Scale Test-Time Compute. ArXiv preprint (2025) [Paper]
- Zero-shot Benchmarking: A Framework for Flexible and Scalable Automatic Evaluation of Language Models. ArXiv preprint (2025) [Paper]
- Beyond Single-Point Judgment: Distribution Alignment for LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Enhancing User-Oriented Proactivity in Open-Domain Dialogues with Critic Guidance. ArXiv preprint (2025) [Paper]
- ESC-Judge: A Framework for Comparing Emotional Support Conversational Agents. ArXiv preprint (2025) [Paper]
- Decentralized Arena: Towards Democratic and Scalable Automatic Evaluation of Language Models. ArXiv preprint (2025) [Paper]
- Investigating the Vulnerability of LLM-as-a-Judge Architectures to Prompt-Injection Attacks. ArXiv preprint (2025) [Paper]
- MR. Judge: Multimodal Reasoner as a Judge. ArXiv preprint (2025) [Paper]
- Truth or Twist? Optimal Model Selection for Reliable Label Flipping Evaluation in LLM-based Counterfactuals. ArXiv preprint (2025) [Paper]
- Think-J: Learning to Think for Generative LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- MindVote: How LLMs Predict Human Decision-Making in Social Media Polls. ArXiv preprint (2025) [Paper]
- J4R: Learning to Judge with Equivalent Initial State Group Relative Policy Optimization. ArXiv preprint (2025) [Paper]
- WebNovelBench: Placing LLM Novelists on the Web Novel Distribution. ArXiv preprint (2025) [Paper]
- ModelingAgent: Bridging LLMs and Mathematical Modeling for Real-World Challenges. ArXiv preprint (2025) [Paper]
- Any Large Language Model Can Be a Reliable Judge: Debiasing with a Reasoning-based Bias Detector. ArXiv preprint (2025) [Paper]
- Generalised Probabilistic Modelling and Improved Uncertainty Estimation in Comparative LLM-as-a-judge. ArXiv preprint (2025) [Paper]
- AI vs. Human Judgment of Content Moderation: LLM-as-a-Judge and Ethics-Based Response Refusals. ArXiv preprint (2025) [Paper]
- Reverse Engineering Human Preferences with Reinforcement Learning. ArXiv preprint (2025) [Paper]
- SLMEval: Entropy-Based Calibration for Human-Aligned Evaluation of Large Language Models. ArXiv preprint (2025) [Paper]
- Don't Judge Code by Its Cover: Exploring Biases in LLM Judges for Code Evaluation. ArXiv preprint (2025) [Paper]
- But what is your honest answer? Aiding LLM-judges with honest alternatives using steering vectors. ArXiv preprint (2025) [Paper]
- Flex-Judge: Think Once, Judge Anywhere. ArXiv preprint (2025) [Paper]
- Adaptive Prediction-Powered AutoEval with Reliability and Efficiency Guarantees. ArXiv preprint (2025) [Paper]
- Assistant-Guided Mitigation of Teacher Preference Bias in LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- DeepResearchGym: A Free, Transparent, and Reproducible Evaluation Sandbox for Deep Research. ArXiv preprint (2025) [Paper]
- Judging with Many Minds: Do More Perspectives Mean Less Prejudice?. ArXiv preprint (2025) [Paper]
- MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research. ArXiv preprint (2025) [Paper]
- PandaGuard: Systematic Evaluation of LLM Safety against Jailbreaking Attacks. ArXiv preprint (2025) [Paper]
- Amulet: Putting Complex Multi-Turn Conversations on the Stand with LLM Juries. ArXiv preprint (2025) [Paper]
- Monocle: Hybrid Local-Global In-Context Evaluation for Long-Text Generation with Uncertainty-Based Active Learning. ArXiv preprint (2025) [Paper]
- FRABench and GenEval: Scaling Fine-Grained Aspect Evaluation across Tasks, Modalities. ArXiv preprint (2025) [Paper]
- An LLM-as-Judge Metric for Bridging the Gap with Human Evaluation in SE Tasks. ArXiv preprint (2025) [Paper]
- Judging LLMs on a Simplex. ArXiv preprint (2025) [Paper]
- AstroVisBench: A Code Benchmark for Scientific Computing and Visualization in Astronomy. ArXiv preprint (2025) [Paper]
- EmergentTTS-Eval: Evaluating TTS Models on Complex Prosodic, Expressiveness, and Linguistic Challenges Using Model-as-a-Judge. ArXiv preprint (2025) [Paper]
- FutureGen: LLM-RAG Approach to Generate the Future Work of Scientific Article. ArXiv preprint (2025) [Paper]
- YESciEval: Robust LLM-as-a-Judge for Scientific Question Answering. ArXiv preprint (2025) [Paper]
- Set-LLM: A Permutation-Invariant LLM. ArXiv preprint (2025) [Paper]
- Long-Form Information Alignment Evaluation Beyond Atomic Facts. ArXiv preprint (2025) [Paper]
- HiMATE: A Hierarchical Multi-Agent Framework for Machine Translation Evaluation. ArXiv preprint (2025) [Paper]
- ELSPR: Evaluator LLM Training Data Self-Purification on Non-Transitive Preferences via Tournament Graph Reconstruction. ArXiv preprint (2025) [Paper]
- Integrating Counterfactual Simulations with Language Models for Explaining Multi-Agent Behaviour. ArXiv preprint (2025) [Paper]
- T2I-Eval-R1: Reinforcement Learning-Driven Reasoning for Interpretable Text-to-Image Evaluation. ArXiv preprint (2025) [Paper]
- Evaluating Text Creativity across Diverse Domains: A Dataset and Large Language Model Evaluator. ArXiv preprint (2025) [Paper]
- BizFinBench: A Business-Driven Real-World Financial Benchmark for Evaluating LLMs. ArXiv preprint (2025) [Paper]
- MTR-Bench: A Comprehensive Benchmark for Multi-Turn Reasoning Evaluation. ArXiv preprint (2025) [Paper]
- RAG-Zeval: Towards Robust and Interpretable Evaluation on RAG Responses through End-to-End Rule-Guided Reasoning. ArXiv preprint (2025) [Paper]
- MEDAL: A Framework for Benchmarking LLMs as Multilingual Open-Domain Chatbots and Dialogue Evaluators. ArXiv preprint (2025) [Paper]
- TSTBench: A Comprehensive Benchmark for Text Style Transfer. ArXiv preprint (2025) [Paper]
- A Large Language Model-Enabled Control Architecture for Dynamic Resource Capability Exploration in Multi-Agent Manufacturing Systems. ArXiv preprint (2025) [Paper]
- Towards Conversational Development Environments: Using Theory-of-Mind and Multi-Agent Architectures for Requirements Refinement. ArXiv preprint (2025) [Paper]
- The Mirage of Multimodality: Where Truth is Tested and Honesty Unravels. ArXiv preprint (2025) [Paper]
- DOGe: Defensive Output Generation for LLM Protection Against Knowledge Distillation. ArXiv preprint (2025) [Paper]
- Multi-Domain Explainability of Preferences. ArXiv preprint (2025) [Paper]
- CODE-DITING: A Reasoning-Based Metric for Functional Alignment in Code Evaluation. ArXiv preprint (2025) [Paper]
- Understanding and Mitigating Overrefusal in LLMs from an Unveiling Perspective of Safety Decision Boundary. ArXiv preprint (2025) [Paper]
- Misaligning Reasoning with Answers--A Framework for Assessing LLM CoT Robustness. ArXiv preprint (2025) [Paper]
- Chart-to-Experience: Benchmarking Multimodal LLMs for Predicting Experiential Impact of Charts. ArXiv preprint (2025) [Paper]
- Can Large Language Models Understand Internet Buzzwords Through User-Generated Content. ArXiv preprint (2025) [Paper]
- Data Optimization for LLMs: A Survey. ArXiv preprint (2025) [Paper]
- Teach2Eval: An Indirect Evaluation Method for LLM by Judging How It Teaches. ArXiv preprint (2025) [Paper]
03/2025
- Beyond Exact Match: Semantically Reassessing Event Extraction by Large Language Models. ArXiv preprint (2025) [Paper]
- BadJudge: Backdoor Vulnerabilities of LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Evaluating Personalized Tool-Augmented LLMs from the Perspectives of Personalization and Proactivity. ArXiv preprint (2025) [Paper]
- Inference to the Best Explanation in Large Language Models. ArXiv preprint (2024) [Paper]
- Unmasking Implicit Bias: Evaluating Persona-Prompted LLM Responses in Power-Disparate Social Scenarios. ArXiv preprint (2025) [Paper]
- Evaluating LLMs' Assessment of Mixed-Context Hallucination Through the Lens of Summarization. ArXiv preprint (2025) [Paper]
- From Code to Courtroom: LLMs as the New Software Judges. ArXiv preprint (2025) [Paper]
- Improving LLM-as-a-Judge Inference with the Judgment Distribution. ArXiv preprint (2025) [Paper]
- Process-based Self-Rewarding Language Models. ArXiv preprint (2025) [Paper]
- TRACT: Regression-Aware Fine-tuning Meets Chain-of-Thought Reasoning for LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Know Thy Judge: On the Robustness Meta-Evaluation of LLM Safety Judges. ArXiv preprint (2025) [Paper]
- RocketEval: Efficient Automated LLM Evaluation via Grading Checklist. ArXiv preprint (2025) [Paper]
- Extracting and Emulsifying Cultural Explanation to Improve Multilingual Capability of LLMs. ArXiv preprint (2025) [Paper]
- Dynamic Knowledge Integration for Evidence-Driven Counter-Argument Generation with Large Language Models. ArXiv preprint (2025) [Paper]
- An Empirical Study of Conformal Prediction in LLM with ASP Scaffolds for Robust Reasoning. ArXiv preprint (2025) [Paper]
- GRP: Goal-Reversed Prompting for Zero-Shot Evaluation with LLMs. ArXiv preprint (2025) [Paper]
- DAFE: LLM-Based Evaluation Through Dynamic Arbitration for Free-Form Question-Answering. ArXiv preprint (2025) [Paper]
- Validating LLM-as-a-Judge Systems in the Absence of Gold Labels. ArXiv preprint (2025) [Paper]
- Safer or Luckier? LLMs as Safety Evaluators Are Not Robust to Artifacts. ArXiv preprint (2025) [Paper]
- CheckEval: A reliable LLM-as-a-Judge framework for evaluating text generation using checklists. ArXiv preprint (2024) [Paper]
- CapArena: Benchmarking and Analyzing Detailed Image Captioning in the LLM Era. ArXiv preprint (2025) [Paper]
- GraphEval: A Lightweight Graph-Based LLM Framework for Idea Evaluation. ArXiv preprint (2025) [Paper]
- REPA: Russian Error Types Annotation for Evaluating Text Generation and Judgment Capabilities. ArXiv preprint (2025) [Paper]
- Why Do Multi-Agent LLM Systems Fail?. ArXiv preprint (2025) [Paper]
- Does Context Matter? ContextualJudgeBench for Evaluating LLM-based Judges in Contextual Settings. ArXiv preprint (2025) [Paper]
- Safety Aware Task Planning via Large Language Models in Robotics. ArXiv preprint (2025) [Paper]
- FutureGen: LLM-RAG Approach to Generate the Future Work of Scientific Article. ArXiv preprint (2025) [Paper]
- Summarization Metrics for Spanish and Basque: Do Automatic Scores and LLM-Judges Correlate with Humans?. ArXiv preprint (2025) [Paper]
- Improving Preference Extraction In LLMs By Identifying Latent Knowledge Through Classifying Probes. ArXiv preprint (2025) [Paper]
- GeoBenchX: Benchmarking LLMs for Multistep Geospatial Tasks. ArXiv preprint (2025) [Paper]
- Video SimpleQA: Towards Factuality Evaluation in Large Video Language Models. ArXiv preprint (2025) [Paper]
- Rankers, Judges, and Assistants: Towards Understanding the Interplay of LLMs in Information Retrieval Evaluation. ArXiv preprint (2025) [Paper]
- TN-Eval: Rubric and Evaluation Protocols for Measuring the Quality of Behavioral Therapy Notes. ArXiv preprint (2025) [Paper]
- OpenHuEval: Evaluating Large Language Model on Hungarian Specifics. ArXiv preprint (2025) [Paper]
- Prompt, Divide, and Conquer: Bypassing Large Language Model Safety Filters via Segmented and Distributed Prompt Processing. ArXiv preprint (2025) [Paper]
- Debate-Driven Multi-Agent LLMs for Phishing Email Detection. ArXiv preprint (2025) [Paper]
- Learning to Align Multi-Faceted Evaluation: A Unified and Robust Framework. ArXiv preprint (2025) [Paper]
- Adaptively evaluating models with task elicitation. ArXiv preprint (2025) [Paper]
- SEOE: A Scalable and Reliable Semantic Evaluation Framework for Open Domain Event Detection. ArXiv preprint (2025) [Paper]
- Exploring the Multilingual NLG Evaluation Abilities of LLM-Based Evaluators. ArXiv preprint (2025) [Paper]
- IFIR: A Comprehensive Benchmark for Evaluating Instruction-Following in Expert-Domain Information Retrieval. ArXiv preprint (2025) [Paper]
- Dynamic-KGQA: A Scalable Framework for Generating Adaptive Question Answering Datasets. ArXiv preprint (2025) [Paper]
- Human Implicit Preference-Based Policy Fine-tuning for Multi-Agent Reinforcement Learning in USV Swarm. ArXiv preprint (2025) [Paper]
- Quantifying the Reasoning Abilities of LLMs on Real-world Clinical Cases. ArXiv preprint (2025) [Paper]
- Exploring the Potential of Large Multimodal Models as Effective Alternatives for Pronunciation Assessment. ArXiv preprint (2025) [Paper]
- OpeNLGauge: An Explainable Metric for NLG Evaluation with Open-Weights LLMs. ArXiv preprint (2025) [Paper]
- NSF-SciFy: Mining the NSF Awards Database for Scientific Claims. ArXiv preprint (2025) [Paper]
- Argument Summarization and its Evaluation in the Era of Large Language Models. ArXiv preprint (2025) [Paper]
- Automated Non-Functional Requirements Generation in Software Engineering with Large Language Models: A Comparative Study. ArXiv preprint (2025) [Paper]
- AutoDrive-QA- Automated Generation of Multiple-Choice Questions for Autonomous Driving Datasets Using Large Vision-Language Models. ArXiv preprint (2025) [Paper]
- F¨´x¨¬: A Benchmark for Evaluating Language Models on Ancient Chinese Text Understanding and Generation. ArXiv preprint (2025) [Paper]
- VBench-2.0: Advancing Video Generation Benchmark Suite for Intrinsic Faithfulness. ArXiv preprint (2025) [Paper]
- Debiasing Multimodal Large Language Models via Noise-Aware Preference Optimization. ArXiv preprint (2025) [Paper]
- A Multi-Model Adaptation of Speculative Decoding for Classification. ArXiv preprint (2025) [Paper]
- Judge Anything: MLLM as a Judge Across Any Modality. ArXiv preprint (2025) [Paper]
- From Chaos to Order: The Atomic Reasoner Framework for Fine-grained Reasoning in Large Language Models. ArXiv preprint (2025) [Paper]
- Tuning LLMs by RAG Principles: Towards LLM-native Memory. ArXiv preprint (2025) [Paper]
- D3: Diversity, Difficulty, and Dependability-Aware Data Selection for Sample-Efficient LLM Instruction Tuning. ArXiv preprint (2025) [Paper]
- Towards reasoning era: A survey of long chain-of-thought for reasoning large language models. ArXiv preprint (2025) [Paper]
- DeepReview: Improving LLM-based Paper Review with Human-like Deep Thinking Process. ArXiv preprint (2025) [Paper]
- Exploring Industry Practices and Perspectives on AI Attribution in Co-Creative Use Cases. ArXiv preprint (2025) [Paper]
- Reasoning Through Execution: Unifying Process and Outcome Rewards for Code Generation. ArXiv preprint (2025) [Paper]
- Quantifying the Robustness of Retrieval-Augmented Language Models Against Spurious Features in Grounding Data. ArXiv preprint (2025) [Paper]
- No Free Labels: Limitations of LLM-as-a-Judge Without Human Grounding. ArXiv preprint (2025) [Paper]
- Graph-augmented reasoning: Evolving step-by-step knowledge graph retrieval for llm reasoning. ArXiv preprint (2025) [Paper]
02/2025
- RPGBENCH: Evaluating Large Language Models as Role-Playing Game Engines. ArXiv preprint (2025) [Paper]
- CollabLLM: From Passive Responders to Active Collaborators. ArXiv preprint (2025) [Paper]
- Towards Safer Chatbots: A Framework for Policy Compliance Evaluation of Custom GPTs. ArXiv preprint (2025) [Paper]
- Preference Leakage: A Contamination Problem in LLM-as-a-judge. ArXiv preprint (2025) [Paper]
- Tuning LLM Judge Design Decisions for 1/1000 of the Cost. ArXiv preprint (2025) [Paper]
- Reasoning-as-Logic-Units: Scaling Test-Time Reasoning in Large Language Models Through Logic Unit Alignment. ArXiv preprint (2025) [Paper]
- Training an LLM-as-a-Judge Model: Pipeline, Insights, and Practical Lessons. ArXiv preprint (2025) [Paper]
- SPRI: Aligning Large Language Models with Context-Situated Principles. ArXiv preprint (2025) [Paper]
- Great Models Think Alike and this Undermines AI Oversight. ArXiv preprint (2025) [Paper]
- Aligning Black-box Language Models with Human Judgments. ArXiv preprint (2025) [Paper]
- Bridging the Gap between Expert and Language Models: Concept-guided Chess Commentary Generation and Evaluation. ArXiv preprint (2024) [Paper]
- Quality Assurance for LLM-RAG Systems: Empirical Insights from Tourism Application Testing. ArXiv preprint (2025) [Paper]
- Can LLMs Replace Human Evaluators? An Empirical Study of LLM-as-a-Judge in Software Engineering. ArXiv preprint (2025) [Paper]
- Confidence Improves Self-Consistency in LLMs. ArXiv preprint (2025) [Paper]
- Expect the Unexpected: FailSafe Long Context QA for Finance. ArXiv preprint (2025) [Paper]
- GuideLLM: Exploring LLM-Guided Conversation with Applications in Autobiography Interviewing. ArXiv preprint (2025) [Paper]
- Towards Internet-Scale Training For Agents. ArXiv preprint (2025) [Paper]
- Language Model Council: Democratically Benchmarking Foundation Models on Highly Subjective Tasks. ArXiv preprint (2024) [Paper]
- Large Language Models and Synthetic Data for Monitoring Dataset Mentions in Research Papers. ArXiv preprint (2025) [Paper]
- VibeCheck: Discover and Quantify Qualitative Differences in Large Language Models. ArXiv preprint (2024) [Paper]
- An Empirical Analysis of Uncertainty in Large Language Model Evaluations. ArXiv preprint (2025) [Paper]
- NitiBench: A Comprehensive Studies of LLM Frameworks Capabilities for Thai Legal Question Answering. ArXiv preprint (2025) [Paper]
- Leveraging Uncertainty Estimation for Efficient LLM Routing. ArXiv preprint (2025) [Paper]
- Vendi-RAG: Adaptively Trading-Off Diversity And Quality Significantly Improves Retrieval Augmented Generation With LLMs. ArXiv preprint (2025) [Paper]
- Uncertainty-Aware Step-wise Verification with Generative Reward Models. ArXiv preprint (2025) [Paper]
- Towards Reasoning Ability of Small Language Models. ArXiv preprint (2025) [Paper]
- Improve LLM-as-a-Judge Ability as a General Ability. ArXiv preprint (2025) [Paper]
- Table-Critic: A Multi-Agent Framework for Collaborative Criticism and Refinement in Table Reasoning. ArXiv preprint (2025) [Paper]
- Can LLM Agents Maintain a Persona in Discourse?. ArXiv preprint (2025) [Paper]
- Sociodemographic Prompting is Not Yet an Effective Approach for Simulating Subjective Judgments with LLMs. ArXiv preprint (2025) [Paper]
- Idiosyncrasies in Large Language Models. ArXiv preprint (2025) [Paper]
- MCTS-Judge: Test-Time Scaling in LLM-as-a-Judge for Code Correctness Evaluation. ArXiv preprint (2025) [Paper]
- Truth Knows No Language: Evaluating Truthfulness Beyond English. ArXiv preprint (2025) [Paper]
- SimpleVQA: Multimodal Factuality Evaluation for Multimodal Large Language Models. ArXiv preprint (2025) [Paper]
- Theorem Prover as a Judge for Synthetic Data Generation. ArXiv preprint (2025) [Paper]
- Prompting a Weighting Mechanism into LLM-as-a-Judge in Two-Step: A Case Study. ArXiv preprint (2025) [Paper]
- PairJudge RM: Perform Best-of-N Sampling with Knockout Tournament. ArXiv preprint (2025) [Paper]
- RAG-Gym: Optimizing Reasoning and Search Agents with Process Supervision. ArXiv preprint (2025) [Paper]
- Investigating Non-Transitivity in LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Selective Self-to-Supervised Fine-Tuning for Generalization in Large Language Models. ArXiv preprint (2025) [Paper]
- Judging It, Washing It: Scoring and Greenwashing Corporate Climate Disclosures using Large Language Models. ArXiv preprint (2025) [Paper]
- On Targeted Manipulation and Deception when Optimizing LLMs for User Feedback. ArXiv preprint (2024) [Paper]
- Towards Fully-Automated Materials Discovery via Large-Scale Synthesis Dataset and Expert-Level LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- On-Policy Self-Alignment with Fine-grained Knowledge Feedback for Hallucination Mitigation. ArXiv preprint (2024) [Paper]
- HealthQ: Unveiling Questioning Capabilities of LLM Chains in Healthcare Conversations. ArXiv preprint (2024) [Paper]
- Verdict: A Library for Scaling Judge-Time Compute. ArXiv preprint (2025) [Paper]
- MEMERAG: A Multilingual End-to-End Meta-Evaluation Benchmark for Retrieval Augmented Generation. ArXiv preprint (2025) [Paper]
- Debt Collection Negotiations with Large Language Models: An Evaluation System and Optimizing Decision Making with Multi-Agent. ArXiv preprint (2025) [Paper]
- AgentRM: Enhancing Agent Generalization with Reward Modeling. ArXiv preprint (2025) [Paper]
- Better Instruction-Following Through Minimum Bayes Risk. ArXiv preprint (2024) [Paper]
- Judge as A Judge: Improving the Evaluation of Retrieval-Augmented Generation through the Judge-Consistency of Large Language Models. ArXiv preprint (2025) [Paper]
- Can Large Language Models Outperform Non-Experts in Poetry Evaluation? A Comparative Study Using the Consensual Assessment Technique. ArXiv preprint (2025) [Paper]
- Bi'an: A Bilingual Benchmark and Model for Hallucination Detection in Retrieval-Augmented Generation. ArXiv preprint (2025) [Paper]
- Learning to Generate Unit Tests for Automated Debugging. ArXiv preprint (2025) [Paper]
- Stay Focused: Problem Drift in Multi-Agent Debate. ArXiv preprint (2025) [Paper]
- AIR: Complex Instruction Generation via Automatic Iterative Refinement. ArXiv preprint (2025) [Paper]
- LLM Evaluation Based on Aerospace Manufacturing Expertise: Automated Generation and Multi-Model Question Answering. ArXiv preprint (2025) [Paper]
- Defense Against the Dark Prompts: Mitigating Best-of-N Jailbreaking with Prompt Evaluation. ArXiv preprint (2025) [Paper]
- Using LLM-Based Approaches to Enhance and Automate Topic Labeling. ArXiv preprint (2025) [Paper]
- A Systematic Approach for Assessing Large Language Models' Test Case Generation Capability. ArXiv preprint (2025) [Paper]
- Decoding AI Judgment: How LLMs Assess News Credibility and Bias. ArXiv preprint (2025) [Paper]
- Unifying AI Tutor Evaluation: An Evaluation Taxonomy for Pedagogical Ability Assessment of LLM-Powered AI Tutors. ArXiv preprint (2024) [Paper]
- Investigating the Shortcomings of LLMs in Step-by-Step Legal Reasoning. ArXiv preprint (2025) [Paper]
- Revisiting Benchmark and Assessment: An Agent-based Exploratory Dynamic Evaluation Framework for LLMs. ArXiv preprint (2024) [Paper]
- Bridging the Evaluation Gap: Leveraging Large Language Models for Topic Model Evaluation. ArXiv preprint (2025) [Paper]
- On Iterative Evaluation and Enhancement of Code Quality Using GPT-4o. ArXiv preprint (2025) [Paper]
- Copilot Arena: A Platform for Code LLM Evaluation in the Wild. ArXiv preprint (2025) [Paper]
- Faithful, Unfaithful or Ambiguous? Multi-Agent Debate with Initial Stance for Summary Evaluation. ArXiv preprint (2025) [Paper]
- LLMs can Perform Multi-Dimensional Analytic Writing Assessments: A Case Study of L2 Graduate-Level Academic English Writing. ArXiv preprint (2025) [Paper]
- A Dual-Perspective NLG Meta-Evaluation Framework with Automatic Benchmark and Better Interpretability. ArXiv preprint (2025) [Paper]
- MT-RAIG: Novel Benchmark and Evaluation Framework for Retrieval-Augmented Insight Generation over Multiple Tables. ArXiv preprint (2025) [Paper]
- HPSS: Heuristic Prompting Strategy Search for LLM Evaluators. ArXiv preprint (2025) [Paper]
- Rate, Explain and Cite (REC): Enhanced Explanation and Attribution in Automatic Evaluation by Large Language Models. ArXiv preprint (2024) [Paper]
- Assessing the Reasoning Capabilities of LLMs in the context of Evidence-based Claim Verification. ArXiv preprint (2024) [Paper]
- StructFlowBench: A Structured Flow Benchmark for Multi-turn Instruction Following. ArXiv preprint (2025) [Paper]
- How to Get Your LLM to Generate Challenging Problems for Evaluation. ArXiv preprint (2025) [Paper]
- Training Turn-by-Turn Verifiers for Dialogue Tutoring Agents: The Curious Case of LLMs as Your Coding Tutors. ArXiv preprint (2025) [Paper]
- CVE-LLM : Ontology-Assisted Automatic Vulnerability Evaluation Using Large Language Models. ArXiv preprint (2025) [Paper]
- ReviewEval: An Evaluation Framework for AI-Generated Reviews. ArXiv preprint (2025) [Paper]
- IPO: Your Language Model is Secretly a Preference Classifier. ArXiv preprint (2025) [Paper]
- Recent Advances in Large Langauge Model Benchmarks against Data Contamination: From Static to Dynamic Evaluation. ArXiv preprint (2025) [Paper]
- GuidedBench: Equipping Jailbreak Evaluation with Guidelines. ArXiv preprint (2025) [Paper]
- A Meta-Evaluation of Style and Attribute Transfer Metrics. ArXiv preprint (2025) [Paper]
- How Good Are LLMs for Literary Translation, Really? Literary Translation Evaluation with Humans and LLMs. ArXiv preprint (2024) [Paper]
- RefuteBench 2.0 -- Agentic Benchmark for Dynamic Evaluation of LLM Responses to Refutation Instruction. ArXiv preprint (2025) [Paper]
- LongEval: A Comprehensive Analysis of Long-Text Generation Through a Plan-based Paradigm. ArXiv preprint (2025) [Paper]
- Factual consistency evaluation of summarization in the Era of large language models. ArXiv preprint (2024) [Paper]
- CopyJudge: Automated Copyright Infringement Identification and Mitigation in Text-to-Image Diffusion Models. ArXiv preprint (2025) [Paper]
01/2025
- CoReQA: Uncovering Potentials of Language Models in Code Repository Question Answering. ArXiv preprint (2025) [Paper]
- MTRAG: A Multi-Turn Conversational Benchmark for Evaluating Retrieval-Augmented Generation Systems. ArXiv preprint (2025) [Paper]
- SMIR: Efficient Synthetic Data Pipeline To Improve Multi-Image Reasoning. ArXiv preprint (2025) [Paper]
- EpiCoder: Encompassing Diversity and Complexity in Code Generation. ArXiv preprint (2025) [Paper]
- Leveraging Large Language Models for Zero-shot Lay Summarisation in Biomedicine and Beyond. ArXiv preprint (2025) [Paper]
- Measuring the Robustness of Reference-Free Dialogue Evaluation Systems. ArXiv preprint (2025) [Paper]
- The Lessons of Developing Process Reward Models in Mathematical Reasoning. ArXiv preprint (2025) [Paper]
- U-MATH: A University-Level Benchmark for Evaluating Mathematical Skills in LLMs. ArXiv preprint (2024) [Paper]
- Agent-as-Judge for Factual Summarization of Long Narratives. ArXiv preprint (2025) [Paper]
- The Alternative Annotator Test for LLM-as-a-Judge: How to Statistically Justify Replacing Human Annotators with LLMs. ArXiv preprint (2025) [Paper]
- The Dual-use Dilemma in LLMs: Do Empowering Ethical Capacities Make a Degraded Utility?. ArXiv preprint (2025) [Paper]
- Potential and Perils of Large Language Models as Judges of Unstructured Textual Data. ArXiv preprint (2025) [Paper]
- Early evidence of how LLMs outperform traditional systems on OCR/HTR tasks for historical records. ArXiv preprint (2025) [Paper]
- Towards Interpretable Radiology Report Generation via Concept Bottlenecks using a Multi-Agentic RAG. ArXiv preprint (2024) [Paper]
- Refining Input Guardrails: Enhancing LLM-as-a-Judge Efficiency Through Chain-of-Thought Fine-Tuning and Alignment. ArXiv preprint (2025) [Paper]
- SedarEval: Automated Evaluation using Self-Adaptive Rubrics. ArXiv preprint (2025) [Paper]
- Beyond correlation: The Impact of Human Uncertainty in Measuring the Effectiveness of Automatic Evaluation and LLM-as-a-Judge. ArXiv preprint (2024) [Paper]
- VeriFact: Verifying Facts in LLM-Generated Clinical Text with Electronic Health Records. ArXiv preprint (2025) [Paper]
- MultiChallenge: A Realistic Multi-Turn Conversation Evaluation Benchmark Challenging to Frontier LLMs. ArXiv preprint (2025) [Paper]
- LLMs can be Fooled into Labelling a Document as Relevant (best cafиж near me; this paper is perfectly relevant). ArXiv preprint (2025) [Paper]
- Learning to Plan & Reason for Evaluation with Thinking-LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- GroUSE: A Benchmark to Evaluate Evaluators in Grounded Question Answering. ArXiv preprint (2024) [Paper]
- Illusions of Relevance: Using Content Injection Attacks to Deceive Retrievers, Rerankers, and LLM Judges. ArXiv preprint (2025) [Paper]
- Judge Decoding: Faster Speculative Sampling Requires Going Beyond Model Alignment. ArXiv preprint (2025) [Paper]
- Distilling Desired Comments for Enhanced Code Review with Large Language Models. ArXiv preprint (2024) [Paper]
- LLMPC: Large Language Model Predictive Control. ArXiv preprint (2025) [Paper]
- Can LLMs Design Good Questions Based on Context?. ArXiv preprint (2025) [Paper]
- CodEv: An Automated Grading Framework Leveraging Large Language Models for Consistent and Constructive Feedback. ArXiv preprint (2025) [Paper]
- Can Many-Shot In-Context Learning Help LLMs as Evaluators? A Preliminary Empirical Study. ArXiv preprint (2024) [Paper]
- Hierarchical Divide-and-Conquer for Fine-Grained Alignment in LLM-Based Medical Evaluation. ArXiv preprint (2025) [Paper]
- LLM Reading Tea Leaves: Automatically Evaluating Topic Models with Large Language Models. ArXiv preprint (2024) [Paper]
- Evaluating Mathematical Reasoning Beyond Accuracy. ArXiv preprint (2024) [Paper]
- PASS: Presentation Automation for Slide Generation and Speech. ArXiv preprint (2025) [Paper]
- The Veln(ia)s is in the Details: Evaluating LLM Judgment on Latvian and Lithuanian Short Answer Matching. ArXiv preprint (2025) [Paper]
- Aligning with Human Judgement: The Role of Pairwise Preference in Large Language Model Evaluators. ArXiv preprint (2024) [Paper]
- Exploring the Reliability of Large Language Models as Customized Evaluators for Diverse NLP Tasks. ArXiv preprint (2025) [Paper]
- Synthetic Data Can Mislead Evaluations: Membership Inference as Machine Text Detection. ArXiv preprint (2025) [Paper]
- Exploring GPT's Ability as a Judge in Music Understanding. ArXiv preprint (2025) [Paper]
- AdEval: Alignment-based Dynamic Evaluation to Mitigate Data Contamination in Large Language Models. ArXiv preprint (2025) [Paper]
- Recording for Eyes, Not Echoing to Ears: Contextualized Spoken-to-Written Conversion of ASR Transcripts. ArXiv preprint (2024) [Paper]
- ExPerT: Effective and Explainable Evaluation of Personalized Long-Form Text Generation. ArXiv preprint (2025) [Paper]
- Do LLMs Have Visualization Literacy? An Evaluation on Modified Visualizations to Test Generalization in Data Interpretation. ArXiv preprint (2025) [Paper]
- On A Scale From 1 to 5: Quantifying Hallucination in Faithfulness Evaluation. ArXiv preprint (2024) [Paper]
- Audio Large Language Models Can Be Descriptive Speech Quality Evaluators. ArXiv preprint (2025) [Paper]
- Large Language Model Critics for Execution-Free Evaluation of Code Changes. ArXiv preprint (2025) [Paper]
- CSEval: Towards Automated, Multi-Dimensional, and Reference-Free Counterspeech Evaluation using Auto-Calibrated LLMs. ArXiv preprint (2025) [Paper]
- Generative Information Retrieval Evaluation. ArXiv preprint (2024) [Paper]
- Normative Evaluation of Large Language Models with Everyday Moral Dilemmas. ArXiv preprint (2025) [Paper]
- LLM Cyber Evaluations Don't Capture Real-World Risk. ArXiv preprint (2025) [Paper]
- GPT-4o as the Gold Standard: A Scalable and General Purpose Approach to Filter Language Model Pretraining Data. ArXiv preprint (2024) [Paper]
- Large Language Models' Accuracy in Emulating Human Experts' Evaluation of Public Sentiments about Heated Tobacco Products on Social Media. ArXiv preprint (2025) [Paper]
- E2CL: Exploration-based Error Correction Learning for Embodied Agents. ArXiv preprint (2024) [Paper]
- Aligning with Human Judgement: The Role of Pairwise Preference in Large Language Model Evaluators. ArXiv preprint (2024) [Paper]
- Fairer Preferences Elicit Improved Human-Aligned Large Language Model Judgments. ArXiv preprint (2024) [Paper]
- Aligning with Logic: Measuring, Evaluating and Improving Logical Consistency in Large Language Models. ArXiv preprint (2024) [Paper]
- Visual Large Language Models for Generalized and Specialized Applications. ArXiv preprint (2025) [Paper]
- TalBot: An LLM-based robot assisted language learning system for children with language vulnerabilities. ArXiv preprint (2025) [Paper]
- TiEBe: A Benchmark for Assessing the Current Knowledge of Large Language Models. ArXiv preprint (2025) [Paper]
- Solving the Unsolvable: Translating Case Law in Hong Kong. ArXiv preprint (2025) [Paper]
- Atla Selene Mini: A General Purpose Evaluation Model. ArXiv preprint (2025) [Paper]
- M-MAD: Multidimensional Multi-Agent Debate Framework for Fine-grained Machine Translation Evaluation. ArXiv preprint (2024) [Paper]
12/2024
-
CaseSumm: A Large-Scale Dataset for Long-Context Summarization from U.S. Supreme Court Opinions. ArXiv preprint (2024) [Paper]
-
Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models Fan Zhang, Shulin Tian, Ziqi Huang, Yu Qiao, Ziwei Liu. ArXiv preprint (2024) [Paper]
-
Engineering AI Judge Systems Jiahuei Lin (Justina), Dayi Lin, Sky Zhang, Ahmed E. Hassan. ArXiv preprint (2024) [Paper]
-
LMUnit: Fine-grained Evaluation with Natural Language Unit Tests Jon Saad-Falcon, Rajan Vivek, William Berrios, Nandita Shankar Naik, Matija Franklin, Bertie Vidgen, Amanpreet Singh, Douwe Kiela, Shikib Mehri. ArXiv preprint (2024) [Paper]
-
ACE-M3: Automatic Capability Evaluator for Multimodal Medical Models Xiechi Zhang, Shunfan Zheng, Linlin Wang, Gerard de Melo, Zhu Cao, Xiaoling Wang, Liang He. ArXiv preprint (2024) [Paper]
-
IQA-EVAL: Automatic Evaluation of Human-Model Interactive Question Answering Ruosen Li, Ruochen Li, Barry Wang, Xinya Du. ArXiv preprint (2024) [Paper]
-
StrategyLLM: Large Language Models as Strategy Generators, Executors, Optimizers, and Evaluators for Problem Solving Chang Gao, Haiyun Jiang, Deng Cai, Shuming Shi, Wai Lam. ArXiv preprint (2024) [Paper]
-
ALI-Agent: Assessing LLMs' Alignment with Human Values via Agent-based Evaluation Jingnan Zheng, Han Wang, An Zhang, Tai D. Nguyen, Jun Sun, Tat-Seng Chua. ArXiv preprint (2024) [Paper]
-
On scalable oversight with weak LLMs judging strong LLMs Zachary Kenton, Noah Y. Siegel, János Kramár, Jonah Brown-Cohen, Samuel Albanie, Jannis Bulian, Rishabh Agarwal, David Lindner, Yunhao Tang, Noah D. Goodman, Rohin Shah. ArXiv preprint (2024) [Paper]
-
Easy-to-Hard Generalization: Scalable Alignment Beyond Human Supervision Zhiqing Sun, Longhui Yu, Yikang Shen, Weiyang Liu, Yiming Yang, Sean Welleck, Chuang Gan. ArXiv preprint (2024) [Paper]
-
CriticEval: Evaluating Large Language Model as Critic Tian Lan, Wenwei Zhang, Chen Xu, Heyan Huang, Dahua Lin, Kai Chen, Xian-ling Mao. ArXiv preprint (2024) [Paper]
-
Adaptive Image Quality Assessment via Teaching Large Multimodal Model to Compare Hanwei Zhu, Haoning Wu, Yixuan Li, Zicheng Zhang, Baoliang Chen, Lingyu Zhu, Yuming Fang, Guangtao Zhai, Weisi Lin, Shiqi Wang. ArXiv preprint (2024) [Paper]
-
Beyond Guilt: Legal Judgment Prediction with Trichotomous Reasoning Kepu Zhang, Haoyue Yang, Xu Tang, Weijie Yu, Jun Xu. ArXiv preprint (2024) [Paper]
-
Let your LLM generate a few tokens and you will reduce the need for retrieval Hervé Déjean. ArXiv preprint (2024) [Paper]
-
Can You Trust LLM Judgments? Reliability of LLM-as-a-Judge Kayla Schroeder, Zach Wood-Doughty. ArXiv preprint (2024) [Paper]
-
Using LLM-Generated Draft Replies to Support Human Experts in Responding to Stakeholder Inquiries in Maritime Industry: A Real-World Case Study of Industrial AI Tita Alissa Bach, Aleksandar Babic, Narae Park, Tor Sporsem, Rasmus Ulfsnes, Henrik Smith-Meyer, Torkel Skeie. ArXiv preprint (2024) [Paper]
-
An Exploratory Study of ML Sketches and Visual Code Assistants Luís F. Gomes, Vincent J. Hellendoorn, Jonathan Aldrich, Rui Abreu. ArXiv preprint (2024) [Paper]
-
Steering Large Language Models to Evaluate and Amplify Creativity Matthew Lyle Olson, Neale Ratzlaff, Musashi Hinck, Shao-yen Tseng, Vasudev Lal. ArXiv preprint (2024) [Paper]
-
Optimizing Alignment with Less: Leveraging Data Augmentation for Personalized Evaluation Javad Seraj, Mohammad Mahdi Mohajeri, Mohammad Javad Dousti, Majid Nili Ahmadabadi. ArXiv preprint (2024) [Paper]
-
Exploring Large Language Models on Cross-Cultural Values in Connection with Training Methodology Minsang Kim, Seungjun Baek. ArXiv preprint (2024) [Paper]
-
GLIDER: Grading LLM Interactions and Decisions using Explainable Ranking Darshan Deshpande, Selvan Sunitha Ravi, Sky CH-Wang, Bartosz Mielczarek, Anand Kannappan, Rebecca Qian. ArXiv preprint (2024) [Paper]
-
CharacterBench: Benchmarking Character Customization of Large Language Models Jinfeng Zhou, Yongkang Huang, Bosi Wen, Guanqun Bi, Yuxuan Chen, Pei Ke, Zhuang Chen, Xiyao Xiao, Libiao Peng, Kuntian Tang, Rongsheng Zhang, Le Zhang, Tangjie Lv, Zhipeng Hu, Hongning Wang, Minlie Huang. ArXiv preprint (2024) [Paper]
-
LongBench v2: Towards Deeper Understanding and Reasoning on Realistic Long-context Multitasks Yushi Bai, Shangqing Tu, Jiajie Zhang, Hao Peng, Xiaozhi Wang, Xin Lv, Shulin Cao, Jiazheng Xu, Lei Hou, Yuxiao Dong, Jie Tang, Juanzi Li. ArXiv preprint (2024) [Paper]
-
JudgeBlender: Ensembling Judgments for Automatic Relevance Assessment Hossein A. Rahmani, Emine Yilmaz, Nick Craswell, Bhaskar Mitra. ArXiv preprint (2024) [Paper]
-
Assessing the Impact of Conspiracy Theories Using Large Language Models Bohan Jiang, Dawei Li, Zhen Tan, Xinyi Zhou, Ashwin Rao, Kristina Lerman, H. Russell Bernard, Huan Liu. ArXiv preprint (2024) [Paper]
-
Outcome-Refining Process Supervision for Code Generation Zhuohao Yu, Weizheng Gu, Yidong Wang, Zhengran Zeng, Jindong Wang, Wei Ye, Shikun Zhang. ArXiv preprint (2024) [Paper]
-
RAG-RewardBench: Benchmarking Reward Models in Retrieval Augmented Generation for Preference Alignment Zhuoran Jin, Hongbang Yuan, Tianyi Men, Pengfei Cao, Yubo Chen, Kang Liu, Jun Zhao. ArXiv preprint (2024) [Paper]
-
JuStRank: Benchmarking LLM Judges for System Ranking Ariel Gera, Odellia Boni, Yotam Perlitz, Roy Bar-Haim, Lilach Eden, Asaf Yehudai. ArXiv preprint (2024) [Paper]
-
INDICT: Code Generation with Internal Dialogues of Critiques for Both Security and Helpfulness Hung Le, Yingbo Zhou, Caiming Xiong, Silvio Savarese, Doyen Sahoo. ArXiv preprint (2024) [Paper]
-
LLM Evaluators Recognize and Favor Their Own Generations Arjun Panickssery, Samuel R. Bowman, Shi Feng. ArXiv preprint (2024) [Paper]
-
Training Language Models to Critique With Multi-agent Feedback Tian Lan, Wenwei Zhang, Chengqi Lyu, Shuaibin Li, Chen Xu, Heyan Huang, Dahua Lin, Xian-Ling Mao, Kai Chen. ArXiv preprint (2024) [Paper]
-
Beyond Exact Match: Semantically Reassessing Event Extraction by Large Language Models Yi-Fan Lu, Xian-Ling Mao, Tian Lan, Chen Xu, Heyan Huang. ArXiv preprint (2024) [Paper]
-
Automatic Evaluation for Text-to-image Generation: Task-decomposed Framework, Distilled Training, and Meta-evaluation Benchmark Rong-Cheng Tu, Zi-Ao Ma, Tian Lan, Yuehao Zhao, Heyan Huang, Xian-Ling Mao. ArXiv preprint (2024) [Paper]
-
Multi-modal Retrieval Augmented Multi-modal Generation: A Benchmark, Evaluate Metrics and Strong Baselines Zi-Ao Ma, Tian Lan, Rong-Cheng Tu, Yong Hu, Heyan Huang, Xian-Ling Mao. ArXiv preprint (2024) [Paper]
-
LLM-AS-AN-INTERVIEWER: Beyond Static Testing Through Dynamic LLM Evaluation Eunsu Kim, Juyoung Suk, Seungone Kim, Niklas Muennighoff, Dongkwan Kim, Alice Oh. ArXiv preprint (2024) [Paper]
-
MAG-V: A Multi-Agent Framework for Synthetic Data Generation and Verification Saptarshi Sengupta, Kristal Curtis, Akshay Mallipeddi, Abhinav Mathur, Joseph Ross, Liang Gou. ArXiv preprint (2024) [Paper]
-
Law of the Weakest Link: Cross Capabilities of Large Language Models Ming Zhong, Aston Zhang, Xuewei Wang, Rui Hou, Wenhan Xiong, Chenguang Zhu, Zhengxing Chen, Liang Tan, Chloe Bi, Mike Lewis, Sravya Popuri, Sharan Narang, Melanie Kambadur, Dhruv Mahajan, Sergey Edunov, Jiawei Han, Laurens van der Maaten. ArXiv preprint (2024) [Paper]
-
MCQG-SRefine: Multiple Choice Question Generation and Evaluation with Iterative Self-Critique, Correction, and Comparison Feedback Zonghai Yao, Aditya Parashar, Huixue Zhou, Won Seok Jang, Feiyun Ouyang, Zhichao Yang, Hong Yu. ArXiv preprint (2024) [Paper]
-
ALMA: Alignment with Minimal Annotation Michihiro Yasunaga, Leonid Shamis, Chunting Zhou, Andrew Cohen, Jason Weston, Luke Zettlemoyer, Marjan Ghazvininejad. ArXiv preprint (2024) [Paper]
-
ConQRet: Benchmarking Fine-Grained Evaluation of Retrieval Augmented Argumentation with LLM Judges Kaustubh D. Dhole, Kai Shu, Eugene Agichtein. ArXiv preprint (2024) [Paper]
-
Evaluating and Aligning CodeLLMs on Human Preference Jian Yang, Jiaxi Yang, Ke Jin, Yibo Miao, Lei Zhang, Liqun Yang, Zeyu Cui, Yichang Zhang, Binyuan Hui, Junyang Lin. ArXiv preprint (2024) [Paper]
-
Benchmarking LLMs' Judgments with No Gold Standard Shengwei Xu, Yuxuan Lu, Grant Schoenebeck, Yuqing Kong. ArXiv preprint (2024) [Paper]
-
The Vulnerability of Language Model Benchmarks: Do They Accurately Reflect True LLM Performance? Sourav Banerjee, Ayushi Agarwal, Eishkaran Singh. ArXiv preprint (2024) [Paper]
-
Breaking Event Rumor Detection via Stance-Separated Multi-Agent Debate Mingqing Zhang, Haisong Gong, Qiang Liu, Shu Wu, Liang Wang. ArXiv preprint (2024) [Paper]
-
Can Large Language Models Serve as Evaluators for Code Summarization? Yang Wu, Yao Wan, Zhaoyang Chu, Wenting Zhao, Ye Liu, Hongyu Zhang, Xuanhua Shi, Philip S. Yu. ArXiv preprint (2024) [Paper]
1 Attributes
1.1 Helpfulness
- RLAIF: "RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback". Harrison Lee, Samrat Phatale, Hassan Mansoor, Thomas Mesnard, Johan Ferret, Kellie Lu, Colton Bishop, Ethan Hall, Victor Carbune, Abhinav Rastogi, Sushant Prakash ICML 2024. [Paper]
- MT-Bench:Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena Lianmin Zheng, Wei-Lin Chiang, Ying Sheng, Siyuan Zhuang, Zhanghao Wu, Yonghao Zhuang, Zi Lin, Zhuohan Li, Dacheng Li, Eric Xing, Hao Zhang, Joseph E. Gonzalez, Ion Stoica. NeurIPS 2023 . [Paper] [Huggingface]
- Just-Eval: The unlocking spell on base llms: Rethinking alignment via in-context learning. Bill Yuchen Lin, Abhilasha Ravichander, Ximing Lu, Nouha Dziri, Melanie Sclar, Khyathi Chandu, Chandra Bhagavatula, Yejin Choi. ICLR 2024. [Paper]
- Starling: Starling-7b: Improving helpfulness and harmlessness with rlaif. Banghua Zhu, Evan Frick, Tianhao Wu, Hanlin Zhu, Karthik Ganesan, Wei-Lin Chiang, Jian Zhang, Jiantao Jiao. COLM 2024. [Paper][Github]
- AUTO-J: Generative Judge for Evaluating Alignment. Junlong Li, Shichao Sun, Weizhe Yuan, Run-Ze Fan, Hai Zhao, Pengfei Liu. Arxiv 2023. [Paper][Github]
- OAIF: Direct language model alignment from online ai feedback. Shangmin Guo, Biao Zhang, Tianlin Liu, Tianqi Liu, Misha Khalman, Felipe Llinares, Alexandre Rame, Thomas Mesnard, Yao Zhao, Bilal Piot, Johan Ferret, Mathieu Blondeli. Arxiv 2024. [Paper]
- Constitutional AI: "Constitutional AI: Harmlessness from AI Feedback". Yuntao Bai, Saurav Kadavath, Sandipan Kundu, Amanda Askell, Jackson Kernion, Andy Jones, Anna Chen, Anna Goldie, Azalia Mirhoseini, Cameron McKinnon, Carol Chen, Catherine Olsson, Christopher Olah, Danny Hernandez, Dawn Drain, Deep Ganguli, Dustin Li, Eli Tran-Johnson, Ethan Perez, Jamie Kerr, Jared Mueller, Jeffrey Ladish, Joshua Landau, Kamal Ndousse, Kamile Lukosuite, Liane Lovitt,Michael Sellitto, Nelson Elhage, Nicholas Schiefer, Noemi Mercado, Nova DasSarma,Robert Lasenby, Robin Larson, Sam Ringer, Scott Johnston, Shauna Kravec,Sheer El Showk, Stanislav Fort, Tamera Lanham, Timothy Telleen-Lawton, Tom Conerly, Tom Henighan, Tristan Hume, Samuel R. Bowman, Zac Hatfield-Dodds, Ben Mann,Dario Amodei, Nicholas Joseph, Sam McCandlish, Tom Brown, Jared Kaplan arXiv 2022. [Paper] [Github]
1.2 Harmlessness
- LLaMA Guard:Llama guard: Llm-based input-output safeguard for human-ai conversations. Hakan Inan, Kartikeya Upasani, Jianfeng Chi, Rashi Rungta, Krithika Iyer, Yuning Mao, Michael Tontchev, Qing Hu, Brian Fuller, Davide Testuggine, Madian Khabsa. Arxiv, 2023. [Paper] [Code] [Model]
- TRUSTGPT:Enhancing chat language models by scaling high-quality instructional conversations. Ning Ding, Yulin Chen, Bokai Xu, Yujia Qin, Zhi Zheng, Shengding Hu, Zhiyuan Liu, Maosong Sun, and Bowen Zhou. EMNLP 2023. [Paper] [Code]
- Moral Choice:SlimOrca: An Open Dataset of GPT-4 Augmented FLAN Reasoning Traces, with Verification. Wing Lian, Guan Wang, Bleys Goodson, Eugene Pentland, Austin Cook, Chanvichet Vong, and "Teknium". Huggingface, 2023. [Data]
- SORRY-Bench:Stanford Alpaca: An Instruction-following LLaMA model. Rohan Taori, Ishaan Gulrajani, Tianyi Zhang, Yann Dubois, Xuechen Li, Carlos Guestrin, Percy Liang, and Tatsunori B. Hashimoto. GitHub, 2023. [Blog] [Github] [HuggingFace]
- FLASK:OpenChat: Advancing Open-source Language Models with Mixed-Quality Data. Guan Wang, Sijie Cheng, Xianyuan Zhan, Xiangang Li, Sen Song, and Yang Liu. ICLR, 2024. [Paper] [Code] [HuggingFace]
- R-judge:Training language models to follow instructions with human feedback. Long Ouyang, Jeffrey Wu, Xu Jiang, Diogo Almeida, Carroll Wainwright, Pamela Mishkin, Chong Zhang, Sandhini Agarwal, Katarina Slama, Alex Ray, et al. NeurIPS, 2022. [Paper]
- Do-not-answer: Do-Not-Answer: Evaluating Safeguards in {LLM}s. Wang, Yuxia , Li, Haonan , Han, Xudong , Nakov, Preslav , and Baldwin, Timothy. Findings of the Association for Computational Linguistics: EACL 2024 (2024) [Paper]
1.3 Reliability
- RAIN: Your Language Models Can Align Themselves without Finetuning. Li, Yuhui, Wei, Fangyun, Zhao, Jinjing, Zhang, Chao, and Zhang, Hongyang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- FActScore: Fine-grained Atomic Evaluation of Factual Precision in Long Form Text Generation. Min, Sewon , Krishna, Kalpesh , Lyu, Xinxi , Lewis, Mike , Yih, Wen-tau , Koh, Pang , Iyyer, Mohit , Zettlemoyer, Luke , and Hajishirzi, Hannaneh. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Halu-J: Critique-Based Hallucination Judge. Wang, Binjie, Chern, Steffi, Chern, Ethan, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
- HalluDial: A Large-Scale Benchmark for Automatic Dialogue-Level Hallucination Evaluation. Luo, Wen, Shen, Tianshu, Li, Wei, Peng, Guangyue, Xuan, Richeng, Wang, Houfeng, and Yang, Xi. ArXiv preprint (2024) [Paper]
- Evaluating hallucinations in chinese large language models. Cheng, Qinyuan, Sun, Tianxiang, Zhang, Wenwei, Wang, Siyin, Liu, Xiangyang, Zhang, Mozhi, He, Junliang, Huang, Mianqiu, Yin, Zhangyue, Chen, Kai, and others. ArXiv preprint (2023) [Paper]
- SaySelf: Teaching LLMs to Express Confidence with Self-Reflective Rationales. Xu, Tianyang, Wu, Shujin, Diao, Shizhe, Liu, Xiaoze, Wang, Xingyao, Chen, Yangyi, and Gao, Jing. ArXiv preprint (2024) [Paper]
- Long-form factuality in large language models. Wei, Jerry, Yang, Chengrun, Song, Xinying, Lu, Yifeng, Hu, Nathan, Tran, Dustin, Peng, Daiyi, Liu, Ruibo, Huang, Da, Du, Cosmo, and others. ArXiv preprint (2024) [Paper]
- Self-alignment for factuality: Mitigating hallucinations in llms via self-evaluation. Zhang, Xiaoying, Peng, Baolin, Tian, Ye, Zhou, Jingyan, Jin, Lifeng, Song, Linfeng, Mi, Haitao, and Meng, Helen. ArXiv preprint (2024) [Paper]
- FaithScore: Fine-grained Evaluations of Hallucinations in Large Vision-Language Models. Jing, Liqiang, Li, Ruosen, Chen, Yunmo, and Du, Xinya. Findings of the Association for Computational Linguistics: EMNLP 2024 (2024) [Paper]
- Improving Model Factuality with Fine-grained Critique-based Evaluator. Xie, Yiqing, Zhou, Wenxuan, Prakash, Pradyot, Jin, Di, Mao, Yuning, Fettes, Quintin, Talebzadeh, Arya, Wang, Sinong, Fang, Han, Rose, Carolyn, and others. arXiv preprint arXiv:2410.18359 (2024) [Paper]
1.4 Relevance
- LLM-Eval: Unified Multi-Dimensional Automatic Evaluation for Open-Domain Conversations with Large Language Models. Lin, Yen-Ting , and Chen, Yun-Nung. Proceedings of the 5th Workshop on NLP for Conversational AI (NLP4ConvAI 2023) (2023) [Paper]
- MoT: Memory-of-Thought Enables {C}hat{GPT} to Self-Improve. Li, Xiaonan , and Qiu, Xipeng. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Can We Use Large Language Models to Fill Relevance Judgment Holes?. Abbasiantaeb, Zahra, Meng, Chuan, Azzopardi, Leif, and Aliannejadi, Mohammad. ArXiv preprint (2024) [Paper]
- DALK: Dynamic Co-Augmentation of LLMs and KG to answer Alzheimer's Disease Questions with Scientific Literature. Li, Dawei, Yang, Shu, Tan, Zhen, Baik, Jae Young, Yun, Sunkwon, Lee, Joseph, Chacko, Aaron, Hou, Bojian, Duong-Tran, Duy, Ding, Ying, and others. ArXiv preprint (2024) [Paper]
- MJ-Bench: Is Your Multimodal Reward Model Really a Good Judge for Text-to-Image Generation?. Chen, Zhaorun, Du, Yichao, Wen, Zichen, Zhou, Yiyang, Cui, Chenhang, Weng, Zhenzhen, Tu, Haoqin, Wang, Chaoqi, Tong, Zhengwei, Huang, Qinglan, and others. ArXiv preprint (2024) [Paper]
- Large language models can accurately predict searcher preferences. Thomas, Paul, Spielman, Seth, Craswell, Nick, and Mitra, Bhaskar. Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval (2024) [Paper]
- Leveraging Large Language Models for Relevance Judgments in Legal Case Retrieval. Ma, Shengjie, Chen, Chong, Chu, Qi, and Mao, Jiaxin. ArXiv preprint (2024) [Paper]
- Large Language Models are Zero-Shot Rankers for Recommender Systems. Hou, Yupeng, Zhang, Junjie, Lin, Zihan, Lu, Hongyu, Xie, Ruobing, McAuley, Julian, and Zhao, Wayne Xin. European Conference on Information Retrieval (2024) [Paper]
- Can Large Language Models Be an Alternative to Human Evaluations?. Chiang, Cheng-Han , and Lee, Hung-yi. Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2023) [Paper]
- Toward Automatic Relevance Judgment using Vision--Language Models for Image--Text Retrieval Evaluation. Yang, Jheng-Hong, and Lin, Jimmy. ArXiv preprint (2024) [Paper]
- MLLM-as-a-Judge: Assessing Multimodal {LLM}-as-a-Judge with Vision-Language BenchmarkDongping Chen, Ruoxi Chen, Shilin Zhang, Yinuo Liu, Yaochen Wang, Huichi Zhou, Qihui Zhang, Yao Wan, Pan Zhou, Lichao Sun. ArXiv preprint (2024) [Paper]
1.5 Feasibility
- Reasoning with Language Model is Planning with World Model. Hao, Shibo , Gu, Yi , Ma, Haodi , Hong, Joshua , Wang, Zhen , Wang, Daisy , and Hu, Zhiting. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Tree of Thoughts: Deliberate Problem Solving with Large Language Models. Shunyu Yao, Dian Yu, Jeffrey Zhao, Izhak Shafran, Tom Griffiths, Yuan Cao, and Karthik Narasimhan. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Auto-gpt for online decision making: Benchmarks and additional opinions. Yang, Hui, Yue, Sifu, and He, Yunzhong. ArXiv preprint (2023) [Paper]
- Graph of Thoughts: Solving Elaborate Problems with Large Language Models. Maciej Besta, Nils Blach, Ales Kubicek, Robert Gerstenberger, Michal Podstawski, Lukas Gianinazzi, Joanna Gajda, Tomasz Lehmann, Hubert Niewiadomski, Piotr Nyczyk, and Torsten Hoefler. Thirty-Eighth {AAAI} Conference on Artificial Intelligence, {AAAI} 2024, Thirty-Sixth Conference on Innovative Applications of Artificial Intelligence, {IAAI} 2024, Fourteenth Symposium on Educational Advances in Artificial Intelligence, {EAAI} 2014, February 20-27, 2024, Vancouver, Canada (2024) [Paper]
- DiffAgent: Fast and Accurate Text-to-Image API Selection with Large Language Model. Zhao, Lirui, Yang, Yue, Zhang, Kaipeng, Shao, Wenqi, Zhang, Yuxin, Qiao, Yu, Luo, Ping, and Ji, Rongrong. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (2024) [Paper]
- Routellm: Learning to route llms with preference data. Ong, Isaac, Almahairi, Amjad, Wu, Vincent, Chiang, Wei-Lin, Wu, Tianhao, Gonzalez, Joseph E, Kadous, M Waleed, and Stoica, Ion. ArXiv preprint (2024) [Paper]
- Encouraging divergent thinking in large language models through multi-agent debate. Liang, Tian, He, Zhiwei, Jiao, Wenxiang, Wang, Xing, Wang, Yan, Wang, Rui, Yang, Yujiu, Tu, Zhaopeng, and Shi, Shuming. ArXiv preprint (2023) [Paper]
- SMoA: Improving Multi-agent Large Language Models with Sparse Mixture-of-Agents. Li, Dawei, Tan, Zhen, Qian, Peijia, Li, Yifan, Chaudhary, Kumar Satvik, Hu, Lijie, and Shen, Jiayi. ArXiv preprint (2024) [Paper]
1.6 Overall Quality
- Human-like summarization evaluation with chatgpt. Gao, Mingqi, Ruan, Jie, Sun, Renliang, Yin, Xunjian, Yang, Shiping, and Wan, Xiaojun. ArXiv preprint (2023) [Paper]
- The unlocking spell on base llms: Rethinking alignment via in-context learning. Lin, Bill Yuchen, Ravichander, Abhilasha, Lu, Ximing, Dziri, Nouha, Sclar, Melanie, Chandu, Khyathi, Bhagavatula, Chandra, and Choi, Yejin. The Twelfth International Conference on Learning Representations (2023) [Paper]
- Multi-Dimensional Evaluation of Text Summarization with In-Context Learning. Jain, Sameer , Keshava, Vaishakh , Mysore Sathyendra, Swarnashree , Fernandes, Patrick , Liu, Pengfei , Neubig, Graham , and Zhou, Chunting. Findings of the Association for Computational Linguistics: ACL 2023 (2023) [Paper]
- LLM-Eval: Unified Multi-Dimensional Automatic Evaluation for Open-Domain Conversations with Large Language Models. Lin, Yen-Ting , and Chen, Yun-Nung. Proceedings of the 5th Workshop on NLP for Conversational AI (NLP4ConvAI 2023) (2023) [Paper]
- Large Language Models Are State-of-the-Art Evaluators of Translation Quality. Kocmi, Tom , and Federmann, Christian. Proceedings of the 24th Annual Conference of the European Association for Machine Translation (2023) [Paper]
- Kieval: A knowledge-grounded interactive evaluation framework for large language models. Yu, Zhuohao, Gao, Chang, Yao, Wenjin, Wang, Yidong, Ye, Wei, Wang, Jindong, Xie, Xing, Zhang, Yue, and Zhang, Shikun. ArXiv preprint (2024) [Paper]
- Direct language model alignment from online ai feedback. Guo, Shangmin, Zhang, Biao, Liu, Tianlin, Liu, Tianqi, Khalman, Misha, Llinares, Felipe, Rame, Alexandre, Mesnard, Thomas, Zhao, Yao, Piot, Bilal, and others. ArXiv preprint (2024) [Paper]
- A Comprehensive Analysis of the Effectiveness of Large Language Models as Automatic Dialogue Evaluators. Chen Zhang, Luis Fernando D'Haro, Yiming Chen, Malu Zhang, and Haizhou Li. Thirty-Eighth {AAAI} Conference on Artificial Intelligence, {AAAI} 2024, Thirty-Sixth Conference on Innovative Applications of Artificial Intelligence, {IAAI} 2024, Fourteenth Symposium on Educational Advances in Artificial Intelligence, {EAAI} 2014, February 20-27, 2024, Vancouver, Canada (2024) [Paper]
- Lost in the Source Language: How Large Language Models Evaluate the Quality of Machine Translation. Xu Huang, Zhirui Zhang, Xiang Geng, Yichao Du, Jiajun Chen, and Shujian Huang. Annual Meeting of the Association for Computational Linguistics (2024) [Paper]
2 Methodology
2.1 Tuning
Data Source
Manually-labeled
- Automatic Evaluation of Attribution by Large Language Models. Yue, Xiang , Wang, Boshi , Chen, Ziru , Zhang, Kai , Su, Yu , and Sun, Huan. Findings of the Association for Computational Linguistics: EMNLP 2023 (2023) [Paper]
- INSTRUCTSCORE: Towards Explainable Text Generation Evaluation with Automatic Feedback. Xu, Wenda , Wang, Danqing , Pan, Liangming , Song, Zhenqiao , Freitag, Markus , Wang, William , and Li, Lei. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- X-Eval: Generalizable Multi-aspect Text Evaluation via Augmented Instruction Tuning with Auxiliary Evaluation Aspects. Liu, Minqian , Shen, Ying , Xu, Zhiyang , Cao, Yixin , Cho, Eunah , Kumar, Vaibhav , Ghanadan, Reza , and Huang, Lifu. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (2024) [Paper]
- CritiqueLLM: Towards an informative critique generation model for evaluation of large language model generation. Ke, Pei, Wen, Bosi, Feng, Andrew, Liu, Xiao, Lei, Xuanyu, Cheng, Jiale, Wang, Shengyuan, Zeng, Aohan, Dong, Yuxiao, Wang, Hongning, and others. Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2024) [Paper]
- Foundational autoraters: Taming large language models for better automatic evaluation. Vu, Tu, Krishna, Kalpesh, Alzubi, Salaheddin, Tar, Chris, Faruqui, Manaal, and Sung, Yun-Hsuan. ArXiv preprint (2024) [Paper]
Synthetic Feedback
- Judgelm: Fine-tuned large language models are scalable judges. Zhu, Lianghui, Wang, Xinggang, and Wang, Xinlong. ArXiv preprint (2023) [Paper]
- Meta-rewarding language models: Self-improving alignment with llm-as-a-meta-judge. Wu, Tianhao, Yuan, Weizhe, Golovneva, Olga, Xu, Jing, Tian, Yuandong, Jiao, Jiantao, Weston, Jason, and Sukhbaatar, Sainbayar. ArXiv preprint (2024) [Paper]
- Self-taught evaluators. Wang, Tianlu, Kulikov, Ilia, Golovneva, Olga, Yu, Ping, Yuan, Weizhe, Dwivedi-Yu, Jane, Pang, Richard Yuanzhe, Fazel-Zarandi, Maryam, Weston, Jason, and Li, Xian. ArXiv preprint (2024) [Paper]
- Halu-J: Critique-Based Hallucination Judge. Wang, Binjie, Chern, Steffi, Chern, Ethan, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
- Offsetbias: Leveraging debiased data for tuning evaluators. Park, Junsoo, Jwa, Seungyeon, Ren, Meiying, Kim, Daeyoung, and Choi, Sanghyuk. ArXiv preprint (2024) [Paper]
- Sorry-bench: Systematically evaluating large language model safety refusal behaviors. Xie, Tinghao, Qi, Xiangyu, Zeng, Yi, Huang, Yangsibo, Sehwag, Udari Madhushani, Huang, Kaixuan, He, Luxi, Wei, Boyi, Li, Dacheng, Sheng, Ying, and others. ArXiv preprint (2024) [Paper]
- LLaVA-Critic: Learning to Evaluate Multimodal Models. Xiong, Tianyi, Wang, Xiyao, Guo, Dong, Ye, Qinghao, Fan, Haoqi, Gu, Quanquan, Huang, Heng, and Li, Chunyuan. ArXiv preprint (2024) [Paper]
- Prometheus 2: An open source language model specialized in evaluating other language models. Kim, Seungone, Suk, Juyoung, Longpre, Shayne, Lin, Bill Yuchen, Shin, Jamin, Welleck, Sean, Neubig, Graham, Lee, Moontae, Lee, Kyungjae, and Seo, Minjoon. ArXiv preprint (2024) [Paper]
- INSTRUCTSCORE: Towards Explainable Text Generation Evaluation with Automatic Feedback. Xu, Wenda , Wang, Danqing , Pan, Liangming , Song, Zhenqiao , Freitag, Markus , Wang, William , and Li, Lei. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
Tuning Techiniques
Supervised Fine-Tuning
- Learning personalized story evaluation. Wang, Danqing, Yang, Kevin, Zhu, Hanlin, Yang, Xiaomeng, Cohen, Andrew, Li, Lei, and Tian, Yuandong. ArXiv preprint (2023) [Paper]
- INSTRUCTSCORE: Towards Explainable Text Generation Evaluation with Automatic Feedback. Xu, Wenda , Wang, Danqing , Pan, Liangming , Song, Zhenqiao , Freitag, Markus , Wang, William , and Li, Lei. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- CritiqueLLM: Towards an informative critique generation model for evaluation of large language model generation. Ke, Pei, Wen, Bosi, Feng, Andrew, Liu, Xiao, Lei, Xuanyu, Cheng, Jiale, Wang, Shengyuan, Zeng, Aohan, Dong, Yuxiao, Wang, Hongning, and others. Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2024) [Paper]
- X-Eval: Generalizable Multi-aspect Text Evaluation via Augmented Instruction Tuning with Auxiliary Evaluation Aspects. Liu, Minqian , Shen, Ying , Xu, Zhiyang , Cao, Yixin , Cho, Eunah , Kumar, Vaibhav , Ghanadan, Reza , and Huang, Lifu. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (2024) [Paper]
- Judgelm: Fine-tuned large language models are scalable judges. Zhu, Lianghui, Wang, Xinggang, and Wang, Xinlong. ArXiv preprint (2023) [Paper]
- Sorry-bench: Systematically evaluating large language model safety refusal behaviors. Xie, Tinghao, Qi, Xiangyu, Zeng, Yi, Huang, Yangsibo, Sehwag, Udari Madhushani, Huang, Kaixuan, He, Luxi, Wei, Boyi, Li, Dacheng, Sheng, Ying, and others. ArXiv preprint (2024) [Paper]
- Automatic Evaluation of Attribution by Large Language Models. Yue, Xiang , Wang, Boshi , Chen, Ziru , Zhang, Kai , Su, Yu , and Sun, Huan. Findings of the Association for Computational Linguistics: EMNLP 2023 (2023) [Paper]
- Foundational autoraters: Taming large language models for better automatic evaluation. Vu, Tu, Krishna, Kalpesh, Alzubi, Salaheddin, Tar, Chris, Faruqui, Manaal, and Sung, Yun-Hsuan. ArXiv preprint (2024) [Paper]
- Prometheus 2: An open source language model specialized in evaluating other language models. Kim, Seungone, Suk, Juyoung, Longpre, Shayne, Lin, Bill Yuchen, Shin, Jamin, Welleck, Sean, Neubig, Graham, Lee, Moontae, Lee, Kyungjae, and Seo, Minjoon. ArXiv preprint (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- CritiqueLLM: Towards an informative critique generation model for evaluation of large language model generation. Ke, Pei, Wen, Bosi, Feng, Andrew, Liu, Xiao, Lei, Xuanyu, Cheng, Jiale, Wang, Shengyuan, Zeng, Aohan, Dong, Yuxiao, Wang, Hongning, and others. Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2024) [Paper]
- X-Eval: Generalizable Multi-aspect Text Evaluation via Augmented Instruction Tuning with Auxiliary Evaluation Aspects. Liu, Minqian , Shen, Ying , Xu, Zhiyang , Cao, Yixin , Cho, Eunah , Kumar, Vaibhav , Ghanadan, Reza , and Huang, Lifu. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (2024) [Paper]
Preference Learning
- Halu-J: Critique-Based Hallucination Judge. Wang, Binjie, Chern, Steffi, Chern, Ethan, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
- Offsetbias: Leveraging debiased data for tuning evaluators. Park, Junsoo, Jwa, Seungyeon, Ren, Meiying, Kim, Daeyoung, and Choi, Sanghyuk. ArXiv preprint (2024) [Paper]
- Themis: A Reference-free NLG Evaluation Language Model with Flexibility and Interpretability. Hu, Xinyu, Lin, Li, Gao, Mingqi, Yin, Xunjian, and Wan, Xiaojun. ArXiv preprint (2024) [Paper]
- Meta-rewarding language models: Self-improving alignment with llm-as-a-meta-judge. Wu, Tianhao, Yuan, Weizhe, Golovneva, Olga, Xu, Jing, Tian, Yuandong, Jiao, Jiantao, Weston, Jason, and Sukhbaatar, Sainbayar. ArXiv preprint (2024) [Paper]
- Self-taught evaluators. Wang, Tianlu, Kulikov, Ilia, Golovneva, Olga, Yu, Ping, Yuan, Weizhe, Dwivedi-Yu, Jane, Pang, Richard Yuanzhe, Fazel-Zarandi, Maryam, Weston, Jason, and Li, Xian. ArXiv preprint (2024) [Paper]
- Split and Merge: Aligning Position Biases in LLM-based Evaluators. Li, Zongjie, Wang, Chaozheng, Ma, Pingchuan, Wu, Daoyuan, Wang, Shuai, Gao, Cuiyun, and Liu, Yang. Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing (2024) [Paper]
2.2 Prompting
Swapping Operation
- Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena. Lianmin Zheng, Wei{-}Lin Chiang, Ying Sheng, Siyuan Zhuang, Zhanghao Wu, Yonghao Zhuang, Zi Lin, Zhuohan Li, Dacheng Li, Eric P. Xing, Hao Zhang, Joseph E. Gonzalez, and Ion Stoica. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Rlaif: Scaling reinforcement learning from human feedback with ai feedback. Lee, Harrison, Phatale, Samrat, Mansoor, Hassan, Mesnard, Thomas, Ferret, Johan, Lu, Kellie, Bishop, Colton, Hall, Ethan, Carbune, Victor, Rastogi, Abhinav, and others. ArXiv preprint (2023) [Paper]
- SALMON: Self-Alignment with Instructable Reward Models. Sun, Zhiqing, Shen, Yikang, Zhang, Hongxin, Zhou, Qinhong, Chen, Zhenfang, Cox, David Daniel, Yang, Yiming, and Gan, Chuang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- Starling-7b: Improving helpfulness and harmlessness with rlaif. Zhu, Banghua, Frick, Evan, Wu, Tianhao, Zhu, Hanlin, Ganesan, Karthik, Chiang, Wei-Lin, Zhang, Jian, and Jiao, Jiantao. First Conference on Language Modeling (2024) [Paper]
Rule Augmentation
- Constitutional ai: Harmlessness from ai feedback. Bai, Yuntao, Kadavath, Saurav, Kundu, Sandipan, Askell, Amanda, Kernion, Jackson, Jones, Andy, Chen, Anna, Goldie, Anna, Mirhoseini, Azalia, McKinnon, Cameron, and others. ArXiv preprint (2022) [Paper]
- MoT: Memory-of-Thought Enables {C}hat{GPT} to Self-Improve. Li, Xiaonan , and Qiu, Xipeng. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Improving Diversity of Demographic Representation in Large Language Models via Collective-Critiques and Self-Voting. Lahoti, Preethi , Blumm, Nicholas , Ma, Xiao , Kotikalapudi, Raghavendra , Potluri, Sahitya , Tan, Qijun , Srinivasan, Hansa , Packer, Ben , Beirami, Ahmad , Beutel, Alex , and Chen, Jilin. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Rlaif: Scaling reinforcement learning from human feedback with ai feedback. Lee, Harrison, Phatale, Samrat, Mansoor, Hassan, Mesnard, Thomas, Ferret, Johan, Lu, Kellie, Bishop, Colton, Hall, Ethan, Carbune, Victor, Rastogi, Abhinav, and others. ArXiv preprint (2023) [Paper]
- LRQ-Fact: LLM-Generated Relevant Questions for Multimodal Fact-Checking. Beigi, Alimohammad, Jiang, Bohan, Li, Dawei, Kumarage, Tharindu, Tan, Zhen, Shaeri, Pouya, and Liu, Huan. ArXiv preprint (2024) [Paper]
- Benchmarking Foundation Models with Language-Model-as-an-Examiner. Yushi Bai, Jiahao Ying, Yixin Cao, Xin Lv, Yuze He, Xiaozhi Wang, Jifan Yu, Kaisheng Zeng, Yijia Xiao, Haozhe Lyu, Jiayin Zhang, Juanzi Li, and Lei Hou. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Human-like summarization evaluation with chatgpt. Gao, Mingqi, Ruan, Jie, Sun, Renliang, Yin, Xunjian, Yang, Shiping, and Wan, Xiaojun. ArXiv preprint (2023) [Paper]
- Prometheus: Inducing fine-grained evaluation capability in language models. Kim, Seungone, Shin, Jamin, Cho, Yejin, Jang, Joel, Longpre, Shayne, Lee, Hwaran, Yun, Sangdoo, Shin, Seongjin, Kim, Sungdong, Thorne, James, and others. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Kieval: A knowledge-grounded interactive evaluation framework for large language models. Yu, Zhuohao, Gao, Chang, Yao, Wenjin, Wang, Yidong, Ye, Wei, Wang, Jindong, Xie, Xing, Zhang, Yue, and Zhang, Shikun. ArXiv preprint (2024) [Paper]
- CEB: Compositional Evaluation Benchmark for Fairness in Large Language Models. Wang, Song, Wang, Peng, Zhou, Tong, Dong, Yushun, Tan, Zhen, and Li, Jundong. ArXiv preprint (2024) [Paper]
- Evaluating the Evaluator: Measuring LLMs' Adherence to Task Evaluation Instructions. Murugadoss, Bhuvanashree, Poelitz, Christian, Drosos, Ian, Le, Vu, McKenna, Nick, Negreanu, Carina Suzana, Parnin, Chris, and Sarkar, Advait. ArXiv preprint (2024) [Paper]
- Calibrating {LLM}-Based Evaluator. Liu, Yuxuan , Yang, Tianchi , Huang, Shaohan , Zhang, Zihan , Huang, Haizhen , Wei, Furu , Deng, Weiwei , Sun, Feng , and Zhang, Qi. Proceedings of the 2024 Joint International Conference on Computational Linguistics, Language Resources and Evaluation (LREC-COLING 2024) (2024) [Paper]
- Direct language model alignment from online ai feedback. Guo, Shangmin, Zhang, Biao, Liu, Tianlin, Liu, Tianqi, Khalman, Misha, Llinares, Felipe, Rame, Alexandre, Mesnard, Thomas, Zhao, Yao, Piot, Bilal, and others. ArXiv preprint (2024) [Paper]
- SALMON: Self-Alignment with Instructable Reward Models. Sun, Zhiqing, Shen, Yikang, Zhang, Hongxin, Zhou, Qinhong, Chen, Zhenfang, Cox, David Daniel, Yang, Yiming, and Gan, Chuang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- DALK: Dynamic Co-Augmentation of LLMs and KG to answer Alzheimer's Disease Questions with Scientific Literature. Li, Dawei, Yang, Shu, Tan, Zhen, Baik, Jae Young, Yun, Sunkwon, Lee, Joseph, Chacko, Aaron, Hou, Bojian, Duong-Tran, Duy, Ding, Ying, and others. ArXiv preprint (2024) [Paper]
- What do Large Language Models Need for Machine Translation Evaluation?. Qian, Shenbin, Sindhujan, Archchana, Kabra, Minnie, Kanojia, Diptesh, Ora{\v{s}}an, Constantin, Ranasinghe, Tharindu, and Blain, Fred. Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing (2024) [Paper]
- RevisEval: Improving LLM-as-a-Judge via Response-Adapted References. Zhang, Qiyuan, Wang, Yufei, Yu, Tiezheng, Jiang, Yuxin, Wu, Chuhan, Li, Liangyou, Wang, Yasheng, Jiang, Xin, Shang, Lifeng, Tang, Ruiming, and others. ArXiv preprint (2024) [Paper]
- Can LLM be a Personalized Judge?. Dong, Yijiang River, Hu, Tiancheng, and Collier, Nigel. ArXiv preprint (2024) [Paper]
Multi-Agent Collaboration
- Prd: Peer rank and discussion improve large language model based evaluations. Li, Ruosen, Patel, Teerth, and Du, Xinya. ArXiv preprint (2023) [Paper]
- Wider and deeper llm networks are fairer llm evaluators. Zhang, Xinghua, Yu, Bowen, Yu, Haiyang, Lv, Yangyu, Liu, Tingwen, Huang, Fei, Xu, Hongbo, and Li, Yongbin. ArXiv preprint (2023) [Paper]
- Large language models are diverse role-players for summarization evaluation. Wu, Ning, Gong, Ming, Shou, Linjun, Liang, Shining, and Jiang, Daxin. CCF International Conference on Natural Language Processing and Chinese Computing (2023) [Paper]
- Dynamic Evaluation of Large Language Models by Meta Probing Agents. Zhu, Kaijie, Wang, Jindong, Zhao, Qinlin, Xu, Ruochen, and Xie, Xing. Forty-first International Conference on Machine Learning (2024) [Paper]
- Judgelm: Fine-tuned large language models are scalable judges. Zhu, Lianghui, Wang, Xinggang, and Wang, Xinlong. ArXiv preprint (2023) [Paper]
- ChatEval: Towards Better LLM-based Evaluators through Multi-Agent Debate. Chan, Chi-Min, Chen, Weize, Su, Yusheng, Yu, Jianxuan, Xue, Wei, Zhang, Shanghang, Fu, Jie, and Liu, Zhiyuan. The Twelfth International Conference on Learning Representations (2023) [Paper]
- CoEvol: Constructing Better Responses for Instruction Finetuning through Multi-Agent Cooperation. Li, Renhao, Tan, Minghuan, Wong, Derek F, and Yang, Min. ArXiv preprint (2024) [Paper]
- LRQ-Fact: LLM-Generated Relevant Questions for Multimodal Fact-Checking. Beigi, Alimohammad, Jiang, Bohan, Li, Dawei, Kumarage, Tharindu, Tan, Zhen, Shaeri, Pouya, and Liu, Huan. ArXiv preprint (2024) [Paper]
- Trust or Escalate: LLM Judges with Provable Guarantees for Human Agreement. Jung, Jaehun, Brahman, Faeze, and Choi, Yejin. ArXiv preprint (2024) [Paper]
- The Fellowship of the LLMs: Multi-Agent Workflows for Synthetic Preference Optimization Dataset Generation. Arif, Samee, Farid, Sualeha, Azeemi, Abdul Hameed, Athar, Awais, and Raza, Agha Ali. ArXiv preprint (2024) [Paper]
Demonstration
- Multi-Dimensional Evaluation of Text Summarization with In-Context Learning. Jain, Sameer , Keshava, Vaishakh , Mysore Sathyendra, Swarnashree , Fernandes, Patrick , Liu, Pengfei , Neubig, Graham , and Zhou, Chunting. Findings of the Association for Computational Linguistics: ACL 2023 (2023) [Paper]
- Little Giants: Exploring the Potential of Small {LLM}s as Evaluation Metrics in Summarization in the {E}val4{NLP} 2023 Shared Task. Kotonya, Neema , Krishnasamy, Saran , Tetreault, Joel , and Jaimes, Alejandro. Proceedings of the 4th Workshop on Evaluation and Comparison of NLP Systems (2023) [Paper]
- ALLURE: auditing and improving llm-based evaluation of text using iterative in-context-learning. Hasanbeig, Hosein, Sharma, Hiteshi, Betthauser, Leo, Vieira Frujeri, Felipe, and Momennejad, Ida. arXiv e-prints (2023) [Paper]
- Can Many-Shot In-Context Learning Help Long-Context LLM Judges? See More, Judge Better!. Song, Mingyang, Zheng, Mao, and Luo, Xuan. ArXiv preprint (2024) [Paper]
Multi-Turn Interaction
- Benchmarking Foundation Models with Language-Model-as-an-Examiner. Yushi Bai, Jiahao Ying, Yixin Cao, Xin Lv, Yuze He, Xiaozhi Wang, Jifan Yu, Kaisheng Zeng, Yijia Xiao, Haozhe Lyu, Jiayin Zhang, Juanzi Li, and Lei Hou. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Kieval: A knowledge-grounded interactive evaluation framework for large language models. Yu, Zhuohao, Gao, Chang, Yao, Wenjin, Wang, Yidong, Ye, Wei, Wang, Jindong, Xie, Xing, Zhang, Yue, and Zhang, Shikun. ArXiv preprint (2024) [Paper]
- Auto Arena of LLMs: Automating LLM Evaluations with Agent Peer-battles and Committee Discussions. Zhao, Ruochen, Zhang, Wenxuan, Chia, Yew Ken, Zhao, Deli, and Bing, Lidong. ArXiv preprint (2024) [Paper]
- Evaluating the Performance of Large Language Models via Debates. Moniri, Behrad, Hassani, Hamed, and Dobriban, Edgar. ArXiv preprint (2024) [Paper]
Comparison Acceleration
- Statistical rejection sampling improves preference optimization. Liu, Tianqi, Zhao, Yao, Joshi, Rishabh, Khalman, Misha, Saleh, Mohammad, Liu, Peter J, and Liu, Jialu. ArXiv preprint (2023) [Paper]
- Online Self-Preferring Language Models. Zhai, Yuanzhao, Zhang, Zhuo, Xu, Kele, Peng, Hanyang, Yu, Yue, Feng, Dawei, Yang, Cheng, Ding, Bo, and Wang, Huaimin. ArXiv preprint (2024) [Paper]
- Starling-7b: Improving helpfulness and harmlessness with rlaif. Zhu, Banghua, Frick, Evan, Wu, Tianhao, Zhu, Hanlin, Ganesan, Karthik, Chiang, Wei-Lin, Zhang, Jian, and Jiao, Jiantao. First Conference on Language Modeling (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
3 Application
3.1 Evaluation
-
FutureAGI agent-opt - Open-source library for automated optimization of AI agent workflows with evaluation-driven prompt and config tuning, including LLM-as-judge support.
-
Oceangpt: A large language model for ocean science tasks. Bi, Zhen, Zhang, Ningyu, Xue, Yida, Ou, Yixin, Ji, Daxiong, Zheng, Guozhou, and Chen, Huajun. ArXiv preprint (2023) [Paper]
-
Lawbench: Benchmarking legal knowledge of large language models. Fei, Zhiwei, Shen, Xiaoyu, Zhu, Dawei, Zhou, Fengzhe, Han, Zhuo, Zhang, Songyang, Chen, Kai, Shen, Zongwen, and Ge, Jidong. ArXiv preprint (2023) [Paper]
-
Sotopia: Interactive evaluation for social intelligence in language agents. Zhou, Xuhui, Zhu, Hao, Mathur, Leena, Zhang, Ruohong, Yu, Haofei, Qi, Zhengyang, Morency, Louis-Philippe, Bisk, Yonatan, Fried, Daniel, Neubig, Graham, and others. ArXiv preprint (2023) [Paper]
-
Can {C}hat{GPT} Defend its Belief in Truth? Evaluating {LLM} Reasoning via Debate. Wang, Boshi , Yue, Xiang , and Sun, Huan. Findings of the Association for Computational Linguistics: EMNLP 2023 (2023) [Paper]
-
On Evaluating the Integration of Reasoning and Action in {LLM} Agents with Database Question Answering. Nan, Linyong , Zhang, Ellen , Zou, Weijin , Zhao, Yilun , Zhou, Wenfei , and Cohan, Arman. Findings of the Association for Computational Linguistics: NAACL 2024 (2024) [Paper]
-
Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena. Lianmin Zheng, Wei{-}Lin Chiang, Ying Sheng, Siyuan Zhuang, Zhanghao Wu, Yonghao Zhuang, Zi Lin, Zhuohan Li, Dacheng Li, Eric P. Xing, Hao Zhang, Joseph E. Gonzalez, and Ion Stoica. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
-
Human-like summarization evaluation with chatgpt. Gao, Mingqi, Ruan, Jie, Sun, Renliang, Yin, Xunjian, Yang, Shiping, and Wan, Xiaojun. ArXiv preprint (2023) [Paper]
-
Large language models are diverse role-players for summarization evaluation. Wu, Ning, Gong, Ming, Shou, Linjun, Liang, Shining, and Jiang, Daxin. CCF International Conference on Natural Language Processing and Chinese Computing (2023) [Paper]
-
Evaluating hallucinations in chinese large language models. Cheng, Qinyuan, Sun, Tianxiang, Zhang, Wenwei, Wang, Siyin, Liu, Xiangyang, Zhang, Mozhi, He, Junliang, Huang, Mianqiu, Yin, Zhangyue, Chen, Kai, and others. ArXiv preprint (2023) [Paper]
-
LLM-Eval: Unified Multi-Dimensional Automatic Evaluation for Open-Domain Conversations with Large Language Models. Lin, Yen-Ting , and Chen, Yun-Nung. Proceedings of the 5th Workshop on NLP for Conversational AI (NLP4ConvAI 2023) (2023) [Paper]
-
Beyond Accuracy: Evaluating the Reasoning Behavior of Large Language Models--A Survey. Mondorf, Philipp, and Plank, Barbara. ArXiv preprint (2024) [Paper]
-
Reference-Guided Verdict: LLMs-as-Judges in Automatic Evaluation of Free-Form Text. Badshah, Sher, and Sajjad, Hassan. ArXiv preprint (2024) [Paper]
-
Benchmarking Foundation Models with Language-Model-as-an-Examiner. Yushi Bai, Jiahao Ying, Yixin Cao, Xin Lv, Yuze He, Xiaozhi Wang, Jifan Yu, Kaisheng Zeng, Yijia Xiao, Haozhe Lyu, Jiayin Zhang, Juanzi Li, and Lei Hou. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
-
Decoding biases: Automated methods and llm judges for gender bias detection in language models. Kumar, Shachi H, Sahay, Saurav, Mazumder, Sahisnu, Okur, Eda, Manuvinakurike, Ramesh, Beckage, Nicole, Su, Hsuan, Lee, Hung-yi, and Nachman, Lama. ArXiv preprint (2024) [Paper]
-
Halu-J: Critique-Based Hallucination Judge. Wang, Binjie, Chern, Steffi, Chern, Ethan, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
-
Salad-bench: A hierarchical and comprehensive safety benchmark for large language models. Li, Lijun, Dong, Bowen, Wang, Ruohui, Hu, Xuhao, Zuo, Wangmeng, Lin, Dahua, Qiao, Yu, and Shao, Jing. ArXiv preprint (2024) [Paper]
-
Sorry-bench: Systematically evaluating large language model safety refusal behaviors. Xie, Tinghao, Qi, Xiangyu, Zeng, Yi, Huang, Yangsibo, Sehwag, Udari Madhushani, Huang, Kaixuan, He, Luxi, Wei, Boyi, Li, Dacheng, Sheng, Ying, and others. ArXiv preprint (2024) [Paper]
-
ChatEval: Towards Better LLM-based Evaluators through Multi-Agent Debate. Chan, Chi-Min, Chen, Weize, Su, Yusheng, Yu, Jianxuan, Xue, Wei, Zhang, Shanghang, Fu, Jie, and Liu, Zhiyuan. The Twelfth International Conference on Learning Representations (2023) [Paper]
-
Evaluating the Performance of Large Language Models via Debates. Moniri, Behrad, Hassani, Hamed, and Dobriban, Edgar. ArXiv preprint (2024) [Paper]
-
Evaluating Mathematical Reasoning Beyond Accuracy. Xia, Shijie, Li, Xuefeng, Liu, Yixin, Wu, Tongshuang, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
-
Test of Time: A Benchmark for Evaluating LLMs on Temporal Reasoning. Fatemi, Bahare, Kazemi, Mehran, Tsitsulin, Anton, Malkan, Karishma, Yim, Jinyeong, Palowitch, John, Seo, Sungyong, Halcrow, Jonathan, and Perozzi, Bryan. ArXiv preprint (2024) [Paper]
-
LogicBench: Towards systematic evaluation of logical reasoning ability of large language models. Parmar, Mihir, Patel, Nisarg, Varshney, Neeraj, Nakamura, Mutsumi, Luo, Man, Mashetty, Santosh, Mitra, Arindam, and Baral, Chitta. Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2024) [Paper]
-
Academically intelligent LLMs are not necessarily socially intelligent. Xu, Ruoxi, Lin, Hongyu, Han, Xianpei, Sun, Le, and Sun, Yingfei. ArXiv preprint (2024) [Paper]
-
LLaVA-Critic: Learning to Evaluate Multimodal Models. Xiong, Tianyi, Wang, Xiyao, Guo, Dong, Ye, Qinghao, Fan, Haoqi, Gu, Quanquan, Huang, Heng, and Li, Chunyuan. ArXiv preprint (2024) [Paper]
-
Automated evaluation of large vision-language models on self-driving corner cases. Chen, Kai, Li, Yanze, Zhang, Wenhua, Liu, Yanxin, Li, Pengxiang, Gao, Ruiyuan, Hong, Lanqing, Tian, Meng, Zhao, Xinhai, Li, Zhenguo, and others. ArXiv preprint (2024) [Paper]
-
CodeJudge-Eval: A Benchmark for Evaluating Code Generation. Zhao, John, and others. ArXiv preprint (2024) [Paper]
-
Prompt-Gaming: A Pilot Study on LLM-Evaluating Agent in a Meaningful Energy Game. Isaza-Giraldo, Andr{'e}s, Bala, Paulo, Campos, Pedro F, and Pereira, Lucas. Extended Abstracts of the CHI Conference on Human Factors in Computing Systems (2024) [Paper]
-
HealthQ: Unveiling Questioning Capabilities of LLM Chains in Healthcare Conversations. Wang, Ziyu, Li, Hao, Huang, Di, and Rahmani, Amir M. ArXiv preprint (2024) [Paper]
3.2 Alignment
- Constitutional ai: Harmlessness from ai feedback. Bai, Yuntao, Kadavath, Saurav, Kundu, Sandipan, Askell, Amanda, Kernion, Jackson, Jones, Andy, Chen, Anna, Goldie, Anna, Mirhoseini, Azalia, McKinnon, Cameron, and others. ArXiv preprint (2022) [Paper]
- Rlaif: Scaling reinforcement learning from human feedback with ai feedback. Lee, Harrison, Phatale, Samrat, Mansoor, Hassan, Mesnard, Thomas, Ferret, Johan, Lu, Kellie, Bishop, Colton, Hall, Ethan, Carbune, Victor, Rastogi, Abhinav, and others. ArXiv preprint (2023) [Paper]
- SALMON: Self-Alignment with Instructable Reward Models. Sun, Zhiqing, Shen, Yikang, Zhang, Hongxin, Zhou, Qinhong, Chen, Zhenfang, Cox, David Daniel, Yang, Yiming, and Gan, Chuang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Direct language model alignment from online ai feedback. Guo, Shangmin, Zhang, Biao, Liu, Tianlin, Liu, Tianqi, Khalman, Misha, Llinares, Felipe, Rame, Alexandre, Mesnard, Thomas, Zhao, Yao, Piot, Bilal, and others. ArXiv preprint (2024) [Paper]
- The Fellowship of the LLMs: Multi-Agent Workflows for Synthetic Preference Optimization Dataset Generation. Arif, Samee, Farid, Sualeha, Azeemi, Abdul Hameed, Athar, Awais, and Raza, Agha Ali. ArXiv preprint (2024) [Paper]
- CoEvol: Constructing Better Responses for Instruction Finetuning through Multi-Agent Cooperation. Li, Renhao, Tan, Minghuan, Wong, Derek F, and Yang, Min. ArXiv preprint (2024) [Paper]
- Self-rewarding language models. Yuan, Weizhe, Pang, Richard Yuanzhe, Cho, Kyunghyun, Sukhbaatar, Sainbayar, Xu, Jing, and Weston, Jason. ArXiv preprint (2024) [Paper]
- Meta-rewarding language models: Self-improving alignment with llm-as-a-meta-judge. Wu, Tianhao, Yuan, Weizhe, Golovneva, Olga, Xu, Jing, Tian, Yuandong, Jiao, Jiantao, Weston, Jason, and Sukhbaatar, Sainbayar. ArXiv preprint (2024) [Paper]
- West-of-n: Synthetic preference generation for improved reward modeling. Pace, Aliz{'e}e, Mallinson, Jonathan, Malmi, Eric, Krause, Sebastian, and Severyn, Aliaksei. ArXiv preprint (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- Optimizing Language Model's Reasoning Abilities with Weak Supervision. Tong, Yongqi, Wang, Sizhe, Li, Dawei, Wang, Yifan, Han, Simeng, Lin, Zi, Huang, Chengsong, Huang, Jiaxin, and Shang, Jingbo. ArXiv preprint (2024) [Paper]
- Online Self-Preferring Language Models. Zhai, Yuanzhao, Zhang, Zhuo, Xu, Kele, Peng, Hanyang, Yu, Yue, Feng, Dawei, Yang, Cheng, Ding, Bo, and Wang, Huaimin. ArXiv preprint (2024) [Paper]
- Meta Ranking: Less Capable Language Models are Capable for Single Response Judgement. Liu, Zijun, Kou, Boqun, Li, Peng, Yan, Ming, Zhang, Ji, Huang, Fei, and Liu, Yang. ArXiv preprint (2024) [Paper]
- I-SHEEP: Self-Alignment of LLM from Scratch through an Iterative Self-Enhancement Paradigm. Liang, Yiming, Zhang, Ge, Qu, Xingwei, Zheng, Tianyu, Guo, Jiawei, Du, Xinrun, Yang, Zhenzhu, Liu, Jiaheng, Lin, Chenghua, Ma, Lei, and others. ArXiv preprint (2024) [Paper]
- Self-alignment for factuality: Mitigating hallucinations in llms via self-evaluation. Zhang, Xiaoying, Peng, Baolin, Tian, Ye, Zhou, Jingyan, Jin, Lifeng, Song, Linfeng, Mi, Haitao, and Meng, Helen. ArXiv preprint (2024) [Paper]
- Learning Reward for Robot Skills Using Large Language Models via Self-Alignment. Zeng, Yuwei, Mu, Yao, and Shao, Lin. ArXiv preprint (2024) [Paper]
- i-SRT: Aligning Large Multimodal Models for Videos by Iterative Self-Retrospective Judgment. Ahn, Daechul, Choi, Yura, Kim, San, Yu, Youngjae, Kang, Dongyeop, and Choi, Jonghyun. ArXiv preprint (2024) [Paper]
- CodeUltraFeedback: An LLM-as-a-Judge Dataset for Aligning Large Language Models to Coding Preferences. Weyssow, Martin, Kamanda, Aton, and Sahraoui, Houari. arXiv preprint arXiv:2403.09032 (2024) [Paper]
3.3 Retrieval
- Is ChatGPT Good at Search? Investigating Large Language Models as Re-Ranking Agents. Sun, Weiwei , Yan, Lingyong , Ma, Xinyu , Wang, Shuaiqiang , Ren, Pengjie , Chen, Zhumin , Yin, Dawei , and Ren, Zhaochun. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Large language models can accurately predict searcher preferences, 2023. Thomas, Paul, Spielman, Seth, Craswell, Nick, and Mitra, Bhaskar. ArXiv preprint (2023) [Paper]
- Zero-shot listwise document reranking with a large language model. Ma, Xueguang, Zhang, Xinyu, Pradeep, Ronak, and Lin, Jimmy. ArXiv preprint (2023) [Paper]
- Found in the Middle: Permutation Self-Consistency Improves Listwise Ranking in Large Language Models. Tang, Raphael , Zhang, Crystina , Ma, Xueguang , Lin, Jimmy , and Ture, Ferhan. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (2024) [Paper]
- Large Language Models are Effective Text Rankers with Pairwise Ranking Prompting. Qin, Zhen , Jagerman, Rolf , Hui, Kai , Zhuang, Honglei , Wu, Junru , Yan, Le , Shen, Jiaming , Liu, Tianqi , Liu, Jialu , Metzler, Donald , Wang, Xuanhui , and Bendersky, Michael. Findings of the Association for Computational Linguistics: NAACL 2024 (2024) [Paper]
- Leveraging Large Language Models for Relevance Judgments in Legal Case Retrieval. Ma, Shengjie, Chen, Chong, Chu, Qi, and Mao, Jiaxin. ArXiv preprint (2024) [Paper]
- Large Language Models are Zero-Shot Rankers for Recommender Systems. Hou, Yupeng, Zhang, Junjie, Lin, Zihan, Lu, Hongyu, Xie, Ruobing, McAuley, Julian, and Zhao, Wayne Xin. European Conference on Information Retrieval (2024) [Paper]
- MoT: Memory-of-Thought Enables {C}hat{GPT} to Self-Improve. Li, Xiaonan , and Qiu, Xipeng. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Self-Retrieval: Building an Information Retrieval System with One Large Language Model. Tang, Qiaoyu, Chen, Jiawei, Yu, Bowen, Lu, Yaojie, Fu, Cheng, Yu, Haiyang, Lin, Hongyu, Huang, Fei, He, Ben, Han, Xianpei, and others. ArXiv preprint (2024) [Paper]
- Self-{RAG}: Learning to Retrieve, Generate, and Critique through Self-Reflection. Akari Asai, Zeqiu Wu, Yizhong Wang, Avirup Sil, and Hannaneh Hajishirzi. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Beyond Yes and No: Improving Zero-Shot {LLM} Rankers via Scoring Fine-Grained Relevance Labels. Zhuang, Honglei , Qin, Zhen , Hui, Kai , Wu, Junru , Yan, Le , Wang, Xuanhui , and Bendersky, Michael. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 2: Short Papers) (2024) [Paper]
- Evaluating rag-fusion with ragelo: an automated elo-based framework. Rackauckas, Zackary, C{^a}mara, Arthur, and Zavrel, Jakub. ArXiv preprint (2024) [Paper]
- Are Large Language Models Good at Utility Judgments?. Zhang, Hengran, Zhang, Ruqing, Guo, Jiafeng, de Rijke, Maarten, Fan, Yixing, and Cheng, Xueqi. Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval (2024) [Paper]
- BioRAG: A RAG-LLM Framework for Biological Question Reasoning. Wang, Chengrui, Long, Qingqing, Meng, Xiao, Cai, Xunxin, Wu, Chengjun, Meng, Zhen, Wang, Xuezhi, and Zhou, Yuanchun. ArXiv preprint (2024) [Paper]
- DALK: Dynamic Co-Augmentation of LLMs and KG to answer Alzheimer's Disease Questions with Scientific Literature. Li, Dawei, Yang, Shu, Tan, Zhen, Baik, Jae Young, Yun, Sunkwon, Lee, Joseph, Chacko, Aaron, Hou, Bojian, Duong-Tran, Duy, Ding, Ying, and others. ArXiv preprint (2024) [Paper]
- Improving medical reasoning through retrieval and self-reflection with retrieval-augmented large language models. Jeong, Minbyul, Sohn, Jiwoong, Sung, Mujeen, and Kang, Jaewoo. Bioinformatics (2024) [Paper]
- A setwise approach for effective and highly efficient zero-shot ranking with large language models. Zhuang, Shengyao, Zhuang, Honglei, Koopman, Bevan, and Zuccon, Guido. Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval (2024) [Paper]
- LLMs are Biased Evaluators But Not Biased for Retrieval Augmented Generation. Chen, Yen-Shan, Jin, Jing, Kuo, Peng-Ting, Huang, Chao-Wei, and Chen, Yun-Nung. ArXiv preprint (2024) [Paper]
3.4 Reasoning
- ReAct: Synergizing Reasoning and Acting in Language Models. Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik R. Narasimhan, and Yuan Cao. The Eleventh International Conference on Learning Representations, {ICLR} 2023, Kigali, Rwanda, May 1-5, 2023 (2023) [Paper]
- Selection-Inference: Exploiting Large Language Models for Interpretable Logical Reasoning. Antonia Creswell, Murray Shanahan, and Irina Higgins. The Eleventh International Conference on Learning Representations, {ICLR} 2023, Kigali, Rwanda, May 1-5, 2023 (2023) [Paper]
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. Jason Wei, Xuezhi Wang, Dale Schuurmans, Maarten Bosma, Brian Ichter, Fei Xia, Ed H. Chi, Quoc V. Le, and Denny Zhou. Advances in Neural Information Processing Systems 35: Annual Conference on Neural Information Processing Systems 2022, NeurIPS 2022, New Orleans, LA, USA, November 28 - December 9, 2022 (2022) [Paper]
- Tree of Thoughts: Deliberate Problem Solving with Large Language Models. Shunyu Yao, Dian Yu, Jeffrey Zhao, Izhak Shafran, Tom Griffiths, Yuan Cao, and Karthik Narasimhan. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Auto-gpt for online decision making: Benchmarks and additional opinions. Yang, Hui, Yue, Sifu, and He, Yunzhong. ArXiv preprint (2023) [Paper]
- Languagempc: Large language models as decision makers for autonomous driving. Sha, Hao, Mu, Yao, Jiang, Yuxuan, Chen, Li, Xu, Chenfeng, Luo, Ping, Li, Shengbo Eben, Tomizuka, Masayoshi, Zhan, Wei, and Ding, Mingyu. ArXiv preprint (2023) [Paper]
- Reasoning with Language Model is Planning with World Model. Hao, Shibo , Gu, Yi , Ma, Haodi , Hong, Joshua , Wang, Zhen , Wang, Daisy , and Hu, Zhiting. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Self-discover: Large language models self-compose reasoning structures. Zhou, Pei, Pujara, Jay, Ren, Xiang, Chen, Xinyun, Cheng, Heng-Tze, Le, Quoc V, Chi, Ed H, Zhou, Denny, Mishra, Swaroop, and Zheng, Huaixiu Steven. ArXiv preprint (2024) [Paper]
- Improving Diversity of Demographic Representation in Large Language Models via Collective-Critiques and Self-Voting. Lahoti, Preethi , Blumm, Nicholas , Ma, Xiao , Kotikalapudi, Raghavendra , Potluri, Sahitya , Tan, Qijun , Srinivasan, Hansa , Packer, Ben , Beirami, Ahmad , Beutel, Alex , and Chen, Jilin. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Encouraging divergent thinking in large language models through multi-agent debate. Liang, Tian, He, Zhiwei, Jiao, Wenxiang, Wang, Xing, Wang, Yan, Wang, Rui, Yang, Yujiu, Tu, Zhaopeng, and Shi, Shuming. ArXiv preprint (2023) [Paper]
- SMoA: Improving Multi-agent Large Language Models with Sparse Mixture-of-Agents. Li, Dawei, Tan, Zhen, Qian, Peijia, Li, Yifan, Chaudhary, Kumar Satvik, Hu, Lijie, and Shen, Jiayi. ArXiv preprint (2024) [Paper]
- Graph of Thoughts: Solving Elaborate Problems with Large Language Models. Maciej Besta, Nils Blach, Ales Kubicek, Robert Gerstenberger, Michal Podstawski, Lukas Gianinazzi, Joanna Gajda, Tomasz Lehmann, Hubert Niewiadomski, Piotr Nyczyk, and Torsten Hoefler. Thirty-Eighth {AAAI} Conference on Artificial Intelligence, {AAAI} 2024, Thirty-Sixth Conference on Innovative Applications of Artificial Intelligence, {IAAI} 2024, Fourteenth Symposium on Educational Advances in Artificial Intelligence, {EAAI} 2014, February 20-27, 2024, Vancouver, Canada (2024) [Paper]
- Routellm: Learning to route llms with preference data. Ong, Isaac, Almahairi, Amjad, Wu, Vincent, Chiang, Wei-Lin, Wu, Tianhao, Gonzalez, Joseph E, Kadous, M Waleed, and Stoica, Ion. ArXiv preprint (2024) [Paper]
- DiffAgent: Fast and Accurate Text-to-Image API Selection with Large Language Model. Zhao, Lirui, Yang, Yue, Zhang, Kaipeng, Shao, Wenqi, Zhang, Yuxin, Qiao, Yu, Luo, Ping, and Ji, Rongrong. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (2024) [Paper]
- Rationale-Aware Answer Verification by Pairwise Self-Evaluation. Kawabata, Akira, and Sugawara, Saku. Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing (2024) [Paper]
- Improving Model Factuality with Fine-grained Critique-based Evaluator. Xie, Yiqing, Zhou, Wenxuan, Prakash, Pradyot, Jin, Di, Mao, Yuning, Fettes, Quintin, Talebzadeh, Arya, Wang, Sinong, Fang, Han, Rose, Carolyn, and others. arXiv preprint arXiv:2410.18359 (2024) [Paper]
- Let's verify step by step. Lightman, Hunter, Kosaraju, Vineet, Burda, Yura, Edwards, Harri, Baker, Bowen, Lee, Teddy, Leike, Jan, Schulman, John, Sutskever, Ilya, and Cobbe, Karl. arXiv preprint arXiv:2305.20050 (2023) [Paper]
- RAIN: Your Language Models Can Align Themselves without Finetuning. Li, Yuhui, Wei, Fangyun, Zhao, Jinjing, Zhang, Chao, and Zhang, Hongyang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Rewarding Progress: Scaling Automated Process Verifiers for LLM Reasoning. Setlur, Amrith, Nagpal, Chirag, Fisch, Adam, Geng, Xinyang, Eisenstein, Jacob, Agarwal, Rishabh, Agarwal, Alekh, Berant, Jonathan, and Kumar, Aviral. arXiv preprint arXiv:2410.08146 (2024) [Paper]
Contributors


Similar repos


README
Awesome-LLM-as-a-judge Survey
Awesome-LLM-as-a-judge: A Survey
This repo include the papers discussed in our latest survey paper on Awesome-LLM-as-a-judge.
Our official websit: Website
:book: Read the full paper here: Paper Link
🔔 News
2025-5We update our paper list and include papers of LLM-as-a-judge in April & May 2025!2025-4We update our paper list and include papers of LLM-as-a-judge in March 2025!2025-3Want to learn more about risks and safety problems of using LLM-based annotation? Check out our new paper list on AI supervision risk!2025-3We update our paper list and include papers of LLM-as-a-judge in February 2025, together with papers about thinking LLM as a judge!2025-2We update our paper list and include papers of LLM-as-a-judge in January 2025!2025-2Check our new paper about preference leakage in LLM-as-a-judge!2024-12Also check our paper list and survey on LLM-based data annotation and synthesis!2024-12We update our paper list and include papers of LLM-as-a-judge in December 2024!2024-12We update the slides, talk and report of our paper, check them in our Website!
Reference
If our survey is useful for your research, please kindly cite our paper:
@article{li2024llmasajudge,
  title   = {From Generation to Judgment: Opportunities and Challenges of LLM-as-a-judge},
  author  = {Dawei Li and Bohan Jiang and Liangjie Huang and Alimohammad Beigi and Chengshuai Zhao and Zhen Tan and Amrita Bhattacharjee and Yuxuan Jiang and Canyu Chen and Tianhao Wu and Kai Shu and Lu Cheng and Huan Liu},
  year    = {2024},
  journal = {arXiv preprint arXiv: 2411.16594}
}
Overview of Awesome-LLM-as-a-judge:
Table of Content (ToC)
- Awesome-LLM-as-a-judge Survey
Thinking LLM-as-a-judge
Papers
- MCTS-Judge: Test-Time Scaling in LLM-as-a-Judge for Code Correctness Evaluation. ArXiv preprint (2025) [Paper]
- Learning to Plan & Reason for Evaluation with Thinking-LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Verdict: A Library for Scaling Judge-Time Compute. ArXiv preprint (2025) [Paper]
- AgentRM: Enhancing Agent Generalization with Reward Modeling. ArXiv preprint (2025) [Paper]
- JudgeLRM: Large Reasoning Models as a Judge. ArXiv preprint (2025) [Paper]
- GenPRM: Scaling Test-Time Compute of Process Reward Models via Generative Reasoning. ArXiv preprint (2025) [Paper]
- Inference-Time Scaling for Generalist Reward Modeling. ArXiv preprint (2025) [Paper]
- RM-R1: Reward Modeling as Reasoning. ArXiv preprint (2025) [Paper]
- J1: Incentivizing Thinking in LLM-as-a-Judge via Reinforcement Learning. ArXiv preprint (2025) [Paper]
Update
07/2025
04/2025 & 05/2025
- Multi-Agent LLM Judge: automatic personalized LLM judge design for evaluating natural language generation applications. ArXiv preprint (2025) [Paper]
- Prompt-Reverse Inconsistency: LLM Self-Inconsistency Beyond Generative Randomness and Prompt Paraphrasing. ArXiv preprint (2025) [Paper]
- Do LLM Evaluators Prefer Themselves for a Reason?. ArXiv preprint (2025) [Paper]
- M-Prometheus: A Suite of Open Multilingual LLM Judges. ArXiv preprint (2025) [Paper]
- HypoEval: Hypothesis-Guided Evaluation for Natural Language Generation. ArXiv preprint (2025) [Paper]
- AgentAda: Skill-Adaptive Data Analytics for Tailored Insight Discovery. ArXiv preprint (2025) [Paper]
- Benchmarking Adversarial Robustness to Bias Elicitation in Large Language Models: Scalable Automated Assessment with LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- AgentRewardBench: Evaluating Automatic Evaluations of Web Agent Trajectories. ArXiv preprint (2025) [Paper]
- MLRC-Bench: Can Language Agents Solve Machine Learning Research Challenges?. ArXiv preprint (2025) [Paper]
- Reasoning Court: Combining Reasoning, Action, and Judgment for Multi-Hop Reasoning. ArXiv preprint (2025) [Paper]
- Evaluation Under Imperfect Benchmarks and Ratings: A Case Study in Text Simplification. ArXiv preprint (2025) [Paper]
- An LLM-as-a-judge Approach for Scalable Gender-Neutral Translation Evaluation. ArXiv preprint (2025) [Paper]
- Efficient MAP Estimation of LLM Judgment Performance with Prior Transfer. ArXiv preprint (2025) [Paper]
- Validating LLM-Generated Relevance Labels for Educational Resource Search. ArXiv preprint (2025) [Paper]
- Assessing Judging Bias in Large Reasoning Models: An Empirical Study. ArXiv preprint (2025) [Paper]
- CodeVisionary: An Agent-based Framework for Evaluating Large Language Models in Code Generation. ArXiv preprint (2025) [Paper]
- Pairwise or Pointwise? Evaluating Feedback Protocols for Bias in LLM-Based Evaluation. ArXiv preprint (2025) [Paper]
- Automatic Evaluation Metrics for Document-level Translation: Overview, Challenges and Trends. ArXiv preprint (2025) [Paper]
- Support Evaluation for the TREC 2024 RAG Track: Comparing Human versus LLM Judges. ArXiv preprint (2025) [Paper]
- Evaluating Judges as Evaluators: The JETTS Benchmark of LLM-as-Judges as Test-Time Scaling Evaluators. ArXiv preprint (2025) [Paper]
- LLM-as-a-Judge: Reassessing the Performance of LLMs in Extractive QA. ArXiv preprint (2025) [Paper]
- Leveraging LLMs as Meta-Judges: A Multi-Agent Framework for Evaluating LLM Judgments. ArXiv preprint (2025) [Paper]
- Spark: A System for Scientifically Creative Idea Generation. ArXiv preprint (2025) [Paper]
- LLM-Evaluation Tropes: Perspectives on the Validity of LLM-Evaluations. ArXiv preprint (2025) [Paper]
- Evaluate-and-Purify: Fortifying Code Language Models Against Adversarial Attacks Using LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- AutoLibra: Agent Metric Induction from Open-Ended Feedback. ArXiv preprint (2025) [Paper]
- To Judge or not to Judge: Using LLM Judgements for Advertiser Keyphrase Relevance at eBay. ArXiv preprint (2025) [Paper]
- Benchmarking LLM Faithfulness in RAG with Evolving Leaderboards. ArXiv preprint (2025) [Paper]
- Sentient Agent as a Judge: Evaluating Higher-Order Social Cognition in Large Language Models. ArXiv preprint (2025) [Paper]
- From Calculation to Adjudication: Examining LLM judges on Mathematical Reasoning Tasks. ArXiv preprint (2024) [Paper]
- J1: Incentivizing Thinking in LLM-as-a-Judge via Reinforcement Learning. ArXiv preprint (2025) [Paper]
- ContrastScore: Towards Higher Quality, Less Biased, More Efficient Evaluation Metrics with Contrastive Evaluation. ArXiv preprint (2025) [Paper]
- Meta-Evaluating Local LLMs: Rethinking Performance Metrics for Serious Games. ArXiv preprint (2025) [Paper]
- CliniChat: A Multi-Source Knowledge-Driven Framework for Clinical Interview Dialogue Reconstruction and Evaluation. ArXiv preprint (2025) [Paper]
- The Great Nugget Recall: Automating Fact Extraction and RAG Evaluation with Large Language Models. ArXiv preprint (2025) [Paper]
- Same evaluation, more tokens: On the effect of input length for machine translation evaluation using Large Language Models. ArXiv preprint (2025) [Paper]
- Unbiased Evaluation of Large Language Models from a Causal Perspective. ArXiv preprint (2025) [Paper]
- Spec2Assertion: Automatic Pre-RTL Assertion Generation using Large Language Models with Progressive Regularization. ArXiv preprint (2025) [Paper]
- LCES: Zero-shot Automated Essay Scoring via Pairwise Comparisons Using Large Language Models. ArXiv preprint (2025) [Paper]
- Generative AI for Autonomous Driving: Frontiers and Opportunities. ArXiv preprint (2025) [Paper]
- From Rankings to Insights: Evaluation Should Shift Focus from Leaderboard to Feedback. ArXiv preprint (2025) [Paper]
- Drug recommendation system based on symptoms and user sentiment analysis (DRecSys-SUSA). ArXiv preprint (2025) [Paper]
- Building Trust in AI via Safe and Responsible Use of LLMs. ArXiv preprint (2025) [Paper]
- SymPlanner: Deliberate Planning in Language Models with Symbolic Representation. ArXiv preprint (2025) [Paper]
- Which agent causes task failures and when? on automated failure attribution of llm multi-agent systems. ArXiv preprint (2025) [Paper]
- Sentiment and Social Signals in the Climate Crisis: A Survey on Analyzing Social Media Responses to Extreme Weather Events. ArXiv preprint (2025) [Paper]
- Context over Categories: Implementing the Theory of Constructed Emotion with LLM-Guided User Analysis. ArXiv preprint (2025) [Paper]
- Benchmarking LLM-based Relevance Judgment Methods. ArXiv preprint (2025) [Paper]
- Explainable AI in Usable Privacy and Security: Challenges and Opportunities. ArXiv preprint (2025) [Paper]
- Persona-judge: Personalized Alignment of Large Language Models via Token-level Self-judgment. ArXiv preprint (2025) [Paper]
- A Human-AI Comparative Analysis of Prompt Sensitivity in LLM-Based Relevance Judgment. ArXiv preprint (2025) [Paper]
- Heimdall: test-time scaling on the generative verification. ArXiv preprint (2025) [Paper]
- Deep Reasoning Translation via Reinforcement Learning. ArXiv preprint (2025) [Paper]
- QM-ToT: A Medical Tree of Thoughts Reasoning Framework for Quantized Model. ArXiv preprint (2025) [Paper]
- NorEval: A Norwegian Language Understanding and Generation Evaluation Benchmark. ArXiv preprint (2025) [Paper]
- Beyond Accuracy: The Role of Calibration in Self-Improving Large Language Models. ArXiv preprint (2025) [Paper]
- Do We Truly Need So Many Samples? Multi-LLM Repeated Sampling Efficiently Scale Test-Time Compute. ArXiv preprint (2025) [Paper]
- Zero-shot Benchmarking: A Framework for Flexible and Scalable Automatic Evaluation of Language Models. ArXiv preprint (2025) [Paper]
- Beyond Single-Point Judgment: Distribution Alignment for LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Enhancing User-Oriented Proactivity in Open-Domain Dialogues with Critic Guidance. ArXiv preprint (2025) [Paper]
- ESC-Judge: A Framework for Comparing Emotional Support Conversational Agents. ArXiv preprint (2025) [Paper]
- Decentralized Arena: Towards Democratic and Scalable Automatic Evaluation of Language Models. ArXiv preprint (2025) [Paper]
- Investigating the Vulnerability of LLM-as-a-Judge Architectures to Prompt-Injection Attacks. ArXiv preprint (2025) [Paper]
- MR. Judge: Multimodal Reasoner as a Judge. ArXiv preprint (2025) [Paper]
- Truth or Twist? Optimal Model Selection for Reliable Label Flipping Evaluation in LLM-based Counterfactuals. ArXiv preprint (2025) [Paper]
- Think-J: Learning to Think for Generative LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- MindVote: How LLMs Predict Human Decision-Making in Social Media Polls. ArXiv preprint (2025) [Paper]
- J4R: Learning to Judge with Equivalent Initial State Group Relative Policy Optimization. ArXiv preprint (2025) [Paper]
- WebNovelBench: Placing LLM Novelists on the Web Novel Distribution. ArXiv preprint (2025) [Paper]
- ModelingAgent: Bridging LLMs and Mathematical Modeling for Real-World Challenges. ArXiv preprint (2025) [Paper]
- Any Large Language Model Can Be a Reliable Judge: Debiasing with a Reasoning-based Bias Detector. ArXiv preprint (2025) [Paper]
- Generalised Probabilistic Modelling and Improved Uncertainty Estimation in Comparative LLM-as-a-judge. ArXiv preprint (2025) [Paper]
- AI vs. Human Judgment of Content Moderation: LLM-as-a-Judge and Ethics-Based Response Refusals. ArXiv preprint (2025) [Paper]
- Reverse Engineering Human Preferences with Reinforcement Learning. ArXiv preprint (2025) [Paper]
- SLMEval: Entropy-Based Calibration for Human-Aligned Evaluation of Large Language Models. ArXiv preprint (2025) [Paper]
- Don't Judge Code by Its Cover: Exploring Biases in LLM Judges for Code Evaluation. ArXiv preprint (2025) [Paper]
- But what is your honest answer? Aiding LLM-judges with honest alternatives using steering vectors. ArXiv preprint (2025) [Paper]
- Flex-Judge: Think Once, Judge Anywhere. ArXiv preprint (2025) [Paper]
- Adaptive Prediction-Powered AutoEval with Reliability and Efficiency Guarantees. ArXiv preprint (2025) [Paper]
- Assistant-Guided Mitigation of Teacher Preference Bias in LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- DeepResearchGym: A Free, Transparent, and Reproducible Evaluation Sandbox for Deep Research. ArXiv preprint (2025) [Paper]
- Judging with Many Minds: Do More Perspectives Mean Less Prejudice?. ArXiv preprint (2025) [Paper]
- MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research. ArXiv preprint (2025) [Paper]
- PandaGuard: Systematic Evaluation of LLM Safety against Jailbreaking Attacks. ArXiv preprint (2025) [Paper]
- Amulet: Putting Complex Multi-Turn Conversations on the Stand with LLM Juries. ArXiv preprint (2025) [Paper]
- Monocle: Hybrid Local-Global In-Context Evaluation for Long-Text Generation with Uncertainty-Based Active Learning. ArXiv preprint (2025) [Paper]
- FRABench and GenEval: Scaling Fine-Grained Aspect Evaluation across Tasks, Modalities. ArXiv preprint (2025) [Paper]
- An LLM-as-Judge Metric for Bridging the Gap with Human Evaluation in SE Tasks. ArXiv preprint (2025) [Paper]
- Judging LLMs on a Simplex. ArXiv preprint (2025) [Paper]
- AstroVisBench: A Code Benchmark for Scientific Computing and Visualization in Astronomy. ArXiv preprint (2025) [Paper]
- EmergentTTS-Eval: Evaluating TTS Models on Complex Prosodic, Expressiveness, and Linguistic Challenges Using Model-as-a-Judge. ArXiv preprint (2025) [Paper]
- FutureGen: LLM-RAG Approach to Generate the Future Work of Scientific Article. ArXiv preprint (2025) [Paper]
- YESciEval: Robust LLM-as-a-Judge for Scientific Question Answering. ArXiv preprint (2025) [Paper]
- Set-LLM: A Permutation-Invariant LLM. ArXiv preprint (2025) [Paper]
- Long-Form Information Alignment Evaluation Beyond Atomic Facts. ArXiv preprint (2025) [Paper]
- HiMATE: A Hierarchical Multi-Agent Framework for Machine Translation Evaluation. ArXiv preprint (2025) [Paper]
- ELSPR: Evaluator LLM Training Data Self-Purification on Non-Transitive Preferences via Tournament Graph Reconstruction. ArXiv preprint (2025) [Paper]
- Integrating Counterfactual Simulations with Language Models for Explaining Multi-Agent Behaviour. ArXiv preprint (2025) [Paper]
- T2I-Eval-R1: Reinforcement Learning-Driven Reasoning for Interpretable Text-to-Image Evaluation. ArXiv preprint (2025) [Paper]
- Evaluating Text Creativity across Diverse Domains: A Dataset and Large Language Model Evaluator. ArXiv preprint (2025) [Paper]
- BizFinBench: A Business-Driven Real-World Financial Benchmark for Evaluating LLMs. ArXiv preprint (2025) [Paper]
- MTR-Bench: A Comprehensive Benchmark for Multi-Turn Reasoning Evaluation. ArXiv preprint (2025) [Paper]
- RAG-Zeval: Towards Robust and Interpretable Evaluation on RAG Responses through End-to-End Rule-Guided Reasoning. ArXiv preprint (2025) [Paper]
- MEDAL: A Framework for Benchmarking LLMs as Multilingual Open-Domain Chatbots and Dialogue Evaluators. ArXiv preprint (2025) [Paper]
- TSTBench: A Comprehensive Benchmark for Text Style Transfer. ArXiv preprint (2025) [Paper]
- A Large Language Model-Enabled Control Architecture for Dynamic Resource Capability Exploration in Multi-Agent Manufacturing Systems. ArXiv preprint (2025) [Paper]
- Towards Conversational Development Environments: Using Theory-of-Mind and Multi-Agent Architectures for Requirements Refinement. ArXiv preprint (2025) [Paper]
- The Mirage of Multimodality: Where Truth is Tested and Honesty Unravels. ArXiv preprint (2025) [Paper]
- DOGe: Defensive Output Generation for LLM Protection Against Knowledge Distillation. ArXiv preprint (2025) [Paper]
- Multi-Domain Explainability of Preferences. ArXiv preprint (2025) [Paper]
- CODE-DITING: A Reasoning-Based Metric for Functional Alignment in Code Evaluation. ArXiv preprint (2025) [Paper]
- Understanding and Mitigating Overrefusal in LLMs from an Unveiling Perspective of Safety Decision Boundary. ArXiv preprint (2025) [Paper]
- Misaligning Reasoning with Answers--A Framework for Assessing LLM CoT Robustness. ArXiv preprint (2025) [Paper]
- Chart-to-Experience: Benchmarking Multimodal LLMs for Predicting Experiential Impact of Charts. ArXiv preprint (2025) [Paper]
- Can Large Language Models Understand Internet Buzzwords Through User-Generated Content. ArXiv preprint (2025) [Paper]
- Data Optimization for LLMs: A Survey. ArXiv preprint (2025) [Paper]
- Teach2Eval: An Indirect Evaluation Method for LLM by Judging How It Teaches. ArXiv preprint (2025) [Paper]
03/2025
- Beyond Exact Match: Semantically Reassessing Event Extraction by Large Language Models. ArXiv preprint (2025) [Paper]
- BadJudge: Backdoor Vulnerabilities of LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Evaluating Personalized Tool-Augmented LLMs from the Perspectives of Personalization and Proactivity. ArXiv preprint (2025) [Paper]
- Inference to the Best Explanation in Large Language Models. ArXiv preprint (2024) [Paper]
- Unmasking Implicit Bias: Evaluating Persona-Prompted LLM Responses in Power-Disparate Social Scenarios. ArXiv preprint (2025) [Paper]
- Evaluating LLMs' Assessment of Mixed-Context Hallucination Through the Lens of Summarization. ArXiv preprint (2025) [Paper]
- From Code to Courtroom: LLMs as the New Software Judges. ArXiv preprint (2025) [Paper]
- Improving LLM-as-a-Judge Inference with the Judgment Distribution. ArXiv preprint (2025) [Paper]
- Process-based Self-Rewarding Language Models. ArXiv preprint (2025) [Paper]
- TRACT: Regression-Aware Fine-tuning Meets Chain-of-Thought Reasoning for LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Know Thy Judge: On the Robustness Meta-Evaluation of LLM Safety Judges. ArXiv preprint (2025) [Paper]
- RocketEval: Efficient Automated LLM Evaluation via Grading Checklist. ArXiv preprint (2025) [Paper]
- Extracting and Emulsifying Cultural Explanation to Improve Multilingual Capability of LLMs. ArXiv preprint (2025) [Paper]
- Dynamic Knowledge Integration for Evidence-Driven Counter-Argument Generation with Large Language Models. ArXiv preprint (2025) [Paper]
- An Empirical Study of Conformal Prediction in LLM with ASP Scaffolds for Robust Reasoning. ArXiv preprint (2025) [Paper]
- GRP: Goal-Reversed Prompting for Zero-Shot Evaluation with LLMs. ArXiv preprint (2025) [Paper]
- DAFE: LLM-Based Evaluation Through Dynamic Arbitration for Free-Form Question-Answering. ArXiv preprint (2025) [Paper]
- Validating LLM-as-a-Judge Systems in the Absence of Gold Labels. ArXiv preprint (2025) [Paper]
- Safer or Luckier? LLMs as Safety Evaluators Are Not Robust to Artifacts. ArXiv preprint (2025) [Paper]
- CheckEval: A reliable LLM-as-a-Judge framework for evaluating text generation using checklists. ArXiv preprint (2024) [Paper]
- CapArena: Benchmarking and Analyzing Detailed Image Captioning in the LLM Era. ArXiv preprint (2025) [Paper]
- GraphEval: A Lightweight Graph-Based LLM Framework for Idea Evaluation. ArXiv preprint (2025) [Paper]
- REPA: Russian Error Types Annotation for Evaluating Text Generation and Judgment Capabilities. ArXiv preprint (2025) [Paper]
- Why Do Multi-Agent LLM Systems Fail?. ArXiv preprint (2025) [Paper]
- Does Context Matter? ContextualJudgeBench for Evaluating LLM-based Judges in Contextual Settings. ArXiv preprint (2025) [Paper]
- Safety Aware Task Planning via Large Language Models in Robotics. ArXiv preprint (2025) [Paper]
- FutureGen: LLM-RAG Approach to Generate the Future Work of Scientific Article. ArXiv preprint (2025) [Paper]
- Summarization Metrics for Spanish and Basque: Do Automatic Scores and LLM-Judges Correlate with Humans?. ArXiv preprint (2025) [Paper]
- Improving Preference Extraction In LLMs By Identifying Latent Knowledge Through Classifying Probes. ArXiv preprint (2025) [Paper]
- GeoBenchX: Benchmarking LLMs for Multistep Geospatial Tasks. ArXiv preprint (2025) [Paper]
- Video SimpleQA: Towards Factuality Evaluation in Large Video Language Models. ArXiv preprint (2025) [Paper]
- Rankers, Judges, and Assistants: Towards Understanding the Interplay of LLMs in Information Retrieval Evaluation. ArXiv preprint (2025) [Paper]
- TN-Eval: Rubric and Evaluation Protocols for Measuring the Quality of Behavioral Therapy Notes. ArXiv preprint (2025) [Paper]
- OpenHuEval: Evaluating Large Language Model on Hungarian Specifics. ArXiv preprint (2025) [Paper]
- Prompt, Divide, and Conquer: Bypassing Large Language Model Safety Filters via Segmented and Distributed Prompt Processing. ArXiv preprint (2025) [Paper]
- Debate-Driven Multi-Agent LLMs for Phishing Email Detection. ArXiv preprint (2025) [Paper]
- Learning to Align Multi-Faceted Evaluation: A Unified and Robust Framework. ArXiv preprint (2025) [Paper]
- Adaptively evaluating models with task elicitation. ArXiv preprint (2025) [Paper]
- SEOE: A Scalable and Reliable Semantic Evaluation Framework for Open Domain Event Detection. ArXiv preprint (2025) [Paper]
- Exploring the Multilingual NLG Evaluation Abilities of LLM-Based Evaluators. ArXiv preprint (2025) [Paper]
- IFIR: A Comprehensive Benchmark for Evaluating Instruction-Following in Expert-Domain Information Retrieval. ArXiv preprint (2025) [Paper]
- Dynamic-KGQA: A Scalable Framework for Generating Adaptive Question Answering Datasets. ArXiv preprint (2025) [Paper]
- Human Implicit Preference-Based Policy Fine-tuning for Multi-Agent Reinforcement Learning in USV Swarm. ArXiv preprint (2025) [Paper]
- Quantifying the Reasoning Abilities of LLMs on Real-world Clinical Cases. ArXiv preprint (2025) [Paper]
- Exploring the Potential of Large Multimodal Models as Effective Alternatives for Pronunciation Assessment. ArXiv preprint (2025) [Paper]
- OpeNLGauge: An Explainable Metric for NLG Evaluation with Open-Weights LLMs. ArXiv preprint (2025) [Paper]
- NSF-SciFy: Mining the NSF Awards Database for Scientific Claims. ArXiv preprint (2025) [Paper]
- Argument Summarization and its Evaluation in the Era of Large Language Models. ArXiv preprint (2025) [Paper]
- Automated Non-Functional Requirements Generation in Software Engineering with Large Language Models: A Comparative Study. ArXiv preprint (2025) [Paper]
- AutoDrive-QA- Automated Generation of Multiple-Choice Questions for Autonomous Driving Datasets Using Large Vision-Language Models. ArXiv preprint (2025) [Paper]
- F¨´x¨¬: A Benchmark for Evaluating Language Models on Ancient Chinese Text Understanding and Generation. ArXiv preprint (2025) [Paper]
- VBench-2.0: Advancing Video Generation Benchmark Suite for Intrinsic Faithfulness. ArXiv preprint (2025) [Paper]
- Debiasing Multimodal Large Language Models via Noise-Aware Preference Optimization. ArXiv preprint (2025) [Paper]
- A Multi-Model Adaptation of Speculative Decoding for Classification. ArXiv preprint (2025) [Paper]
- Judge Anything: MLLM as a Judge Across Any Modality. ArXiv preprint (2025) [Paper]
- From Chaos to Order: The Atomic Reasoner Framework for Fine-grained Reasoning in Large Language Models. ArXiv preprint (2025) [Paper]
- Tuning LLMs by RAG Principles: Towards LLM-native Memory. ArXiv preprint (2025) [Paper]
- D3: Diversity, Difficulty, and Dependability-Aware Data Selection for Sample-Efficient LLM Instruction Tuning. ArXiv preprint (2025) [Paper]
- Towards reasoning era: A survey of long chain-of-thought for reasoning large language models. ArXiv preprint (2025) [Paper]
- DeepReview: Improving LLM-based Paper Review with Human-like Deep Thinking Process. ArXiv preprint (2025) [Paper]
- Exploring Industry Practices and Perspectives on AI Attribution in Co-Creative Use Cases. ArXiv preprint (2025) [Paper]
- Reasoning Through Execution: Unifying Process and Outcome Rewards for Code Generation. ArXiv preprint (2025) [Paper]
- Quantifying the Robustness of Retrieval-Augmented Language Models Against Spurious Features in Grounding Data. ArXiv preprint (2025) [Paper]
- No Free Labels: Limitations of LLM-as-a-Judge Without Human Grounding. ArXiv preprint (2025) [Paper]
- Graph-augmented reasoning: Evolving step-by-step knowledge graph retrieval for llm reasoning. ArXiv preprint (2025) [Paper]
02/2025
- RPGBENCH: Evaluating Large Language Models as Role-Playing Game Engines. ArXiv preprint (2025) [Paper]
- CollabLLM: From Passive Responders to Active Collaborators. ArXiv preprint (2025) [Paper]
- Towards Safer Chatbots: A Framework for Policy Compliance Evaluation of Custom GPTs. ArXiv preprint (2025) [Paper]
- Preference Leakage: A Contamination Problem in LLM-as-a-judge. ArXiv preprint (2025) [Paper]
- Tuning LLM Judge Design Decisions for 1/1000 of the Cost. ArXiv preprint (2025) [Paper]
- Reasoning-as-Logic-Units: Scaling Test-Time Reasoning in Large Language Models Through Logic Unit Alignment. ArXiv preprint (2025) [Paper]
- Training an LLM-as-a-Judge Model: Pipeline, Insights, and Practical Lessons. ArXiv preprint (2025) [Paper]
- SPRI: Aligning Large Language Models with Context-Situated Principles. ArXiv preprint (2025) [Paper]
- Great Models Think Alike and this Undermines AI Oversight. ArXiv preprint (2025) [Paper]
- Aligning Black-box Language Models with Human Judgments. ArXiv preprint (2025) [Paper]
- Bridging the Gap between Expert and Language Models: Concept-guided Chess Commentary Generation and Evaluation. ArXiv preprint (2024) [Paper]
- Quality Assurance for LLM-RAG Systems: Empirical Insights from Tourism Application Testing. ArXiv preprint (2025) [Paper]
- Can LLMs Replace Human Evaluators? An Empirical Study of LLM-as-a-Judge in Software Engineering. ArXiv preprint (2025) [Paper]
- Confidence Improves Self-Consistency in LLMs. ArXiv preprint (2025) [Paper]
- Expect the Unexpected: FailSafe Long Context QA for Finance. ArXiv preprint (2025) [Paper]
- GuideLLM: Exploring LLM-Guided Conversation with Applications in Autobiography Interviewing. ArXiv preprint (2025) [Paper]
- Towards Internet-Scale Training For Agents. ArXiv preprint (2025) [Paper]
- Language Model Council: Democratically Benchmarking Foundation Models on Highly Subjective Tasks. ArXiv preprint (2024) [Paper]
- Large Language Models and Synthetic Data for Monitoring Dataset Mentions in Research Papers. ArXiv preprint (2025) [Paper]
- VibeCheck: Discover and Quantify Qualitative Differences in Large Language Models. ArXiv preprint (2024) [Paper]
- An Empirical Analysis of Uncertainty in Large Language Model Evaluations. ArXiv preprint (2025) [Paper]
- NitiBench: A Comprehensive Studies of LLM Frameworks Capabilities for Thai Legal Question Answering. ArXiv preprint (2025) [Paper]
- Leveraging Uncertainty Estimation for Efficient LLM Routing. ArXiv preprint (2025) [Paper]
- Vendi-RAG: Adaptively Trading-Off Diversity And Quality Significantly Improves Retrieval Augmented Generation With LLMs. ArXiv preprint (2025) [Paper]
- Uncertainty-Aware Step-wise Verification with Generative Reward Models. ArXiv preprint (2025) [Paper]
- Towards Reasoning Ability of Small Language Models. ArXiv preprint (2025) [Paper]
- Improve LLM-as-a-Judge Ability as a General Ability. ArXiv preprint (2025) [Paper]
- Table-Critic: A Multi-Agent Framework for Collaborative Criticism and Refinement in Table Reasoning. ArXiv preprint (2025) [Paper]
- Can LLM Agents Maintain a Persona in Discourse?. ArXiv preprint (2025) [Paper]
- Sociodemographic Prompting is Not Yet an Effective Approach for Simulating Subjective Judgments with LLMs. ArXiv preprint (2025) [Paper]
- Idiosyncrasies in Large Language Models. ArXiv preprint (2025) [Paper]
- MCTS-Judge: Test-Time Scaling in LLM-as-a-Judge for Code Correctness Evaluation. ArXiv preprint (2025) [Paper]
- Truth Knows No Language: Evaluating Truthfulness Beyond English. ArXiv preprint (2025) [Paper]
- SimpleVQA: Multimodal Factuality Evaluation for Multimodal Large Language Models. ArXiv preprint (2025) [Paper]
- Theorem Prover as a Judge for Synthetic Data Generation. ArXiv preprint (2025) [Paper]
- Prompting a Weighting Mechanism into LLM-as-a-Judge in Two-Step: A Case Study. ArXiv preprint (2025) [Paper]
- PairJudge RM: Perform Best-of-N Sampling with Knockout Tournament. ArXiv preprint (2025) [Paper]
- RAG-Gym: Optimizing Reasoning and Search Agents with Process Supervision. ArXiv preprint (2025) [Paper]
- Investigating Non-Transitivity in LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- Selective Self-to-Supervised Fine-Tuning for Generalization in Large Language Models. ArXiv preprint (2025) [Paper]
- Judging It, Washing It: Scoring and Greenwashing Corporate Climate Disclosures using Large Language Models. ArXiv preprint (2025) [Paper]
- On Targeted Manipulation and Deception when Optimizing LLMs for User Feedback. ArXiv preprint (2024) [Paper]
- Towards Fully-Automated Materials Discovery via Large-Scale Synthesis Dataset and Expert-Level LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- On-Policy Self-Alignment with Fine-grained Knowledge Feedback for Hallucination Mitigation. ArXiv preprint (2024) [Paper]
- HealthQ: Unveiling Questioning Capabilities of LLM Chains in Healthcare Conversations. ArXiv preprint (2024) [Paper]
- Verdict: A Library for Scaling Judge-Time Compute. ArXiv preprint (2025) [Paper]
- MEMERAG: A Multilingual End-to-End Meta-Evaluation Benchmark for Retrieval Augmented Generation. ArXiv preprint (2025) [Paper]
- Debt Collection Negotiations with Large Language Models: An Evaluation System and Optimizing Decision Making with Multi-Agent. ArXiv preprint (2025) [Paper]
- AgentRM: Enhancing Agent Generalization with Reward Modeling. ArXiv preprint (2025) [Paper]
- Better Instruction-Following Through Minimum Bayes Risk. ArXiv preprint (2024) [Paper]
- Judge as A Judge: Improving the Evaluation of Retrieval-Augmented Generation through the Judge-Consistency of Large Language Models. ArXiv preprint (2025) [Paper]
- Can Large Language Models Outperform Non-Experts in Poetry Evaluation? A Comparative Study Using the Consensual Assessment Technique. ArXiv preprint (2025) [Paper]
- Bi'an: A Bilingual Benchmark and Model for Hallucination Detection in Retrieval-Augmented Generation. ArXiv preprint (2025) [Paper]
- Learning to Generate Unit Tests for Automated Debugging. ArXiv preprint (2025) [Paper]
- Stay Focused: Problem Drift in Multi-Agent Debate. ArXiv preprint (2025) [Paper]
- AIR: Complex Instruction Generation via Automatic Iterative Refinement. ArXiv preprint (2025) [Paper]
- LLM Evaluation Based on Aerospace Manufacturing Expertise: Automated Generation and Multi-Model Question Answering. ArXiv preprint (2025) [Paper]
- Defense Against the Dark Prompts: Mitigating Best-of-N Jailbreaking with Prompt Evaluation. ArXiv preprint (2025) [Paper]
- Using LLM-Based Approaches to Enhance and Automate Topic Labeling. ArXiv preprint (2025) [Paper]
- A Systematic Approach for Assessing Large Language Models' Test Case Generation Capability. ArXiv preprint (2025) [Paper]
- Decoding AI Judgment: How LLMs Assess News Credibility and Bias. ArXiv preprint (2025) [Paper]
- Unifying AI Tutor Evaluation: An Evaluation Taxonomy for Pedagogical Ability Assessment of LLM-Powered AI Tutors. ArXiv preprint (2024) [Paper]
- Investigating the Shortcomings of LLMs in Step-by-Step Legal Reasoning. ArXiv preprint (2025) [Paper]
- Revisiting Benchmark and Assessment: An Agent-based Exploratory Dynamic Evaluation Framework for LLMs. ArXiv preprint (2024) [Paper]
- Bridging the Evaluation Gap: Leveraging Large Language Models for Topic Model Evaluation. ArXiv preprint (2025) [Paper]
- On Iterative Evaluation and Enhancement of Code Quality Using GPT-4o. ArXiv preprint (2025) [Paper]
- Copilot Arena: A Platform for Code LLM Evaluation in the Wild. ArXiv preprint (2025) [Paper]
- Faithful, Unfaithful or Ambiguous? Multi-Agent Debate with Initial Stance for Summary Evaluation. ArXiv preprint (2025) [Paper]
- LLMs can Perform Multi-Dimensional Analytic Writing Assessments: A Case Study of L2 Graduate-Level Academic English Writing. ArXiv preprint (2025) [Paper]
- A Dual-Perspective NLG Meta-Evaluation Framework with Automatic Benchmark and Better Interpretability. ArXiv preprint (2025) [Paper]
- MT-RAIG: Novel Benchmark and Evaluation Framework for Retrieval-Augmented Insight Generation over Multiple Tables. ArXiv preprint (2025) [Paper]
- HPSS: Heuristic Prompting Strategy Search for LLM Evaluators. ArXiv preprint (2025) [Paper]
- Rate, Explain and Cite (REC): Enhanced Explanation and Attribution in Automatic Evaluation by Large Language Models. ArXiv preprint (2024) [Paper]
- Assessing the Reasoning Capabilities of LLMs in the context of Evidence-based Claim Verification. ArXiv preprint (2024) [Paper]
- StructFlowBench: A Structured Flow Benchmark for Multi-turn Instruction Following. ArXiv preprint (2025) [Paper]
- How to Get Your LLM to Generate Challenging Problems for Evaluation. ArXiv preprint (2025) [Paper]
- Training Turn-by-Turn Verifiers for Dialogue Tutoring Agents: The Curious Case of LLMs as Your Coding Tutors. ArXiv preprint (2025) [Paper]
- CVE-LLM : Ontology-Assisted Automatic Vulnerability Evaluation Using Large Language Models. ArXiv preprint (2025) [Paper]
- ReviewEval: An Evaluation Framework for AI-Generated Reviews. ArXiv preprint (2025) [Paper]
- IPO: Your Language Model is Secretly a Preference Classifier. ArXiv preprint (2025) [Paper]
- Recent Advances in Large Langauge Model Benchmarks against Data Contamination: From Static to Dynamic Evaluation. ArXiv preprint (2025) [Paper]
- GuidedBench: Equipping Jailbreak Evaluation with Guidelines. ArXiv preprint (2025) [Paper]
- A Meta-Evaluation of Style and Attribute Transfer Metrics. ArXiv preprint (2025) [Paper]
- How Good Are LLMs for Literary Translation, Really? Literary Translation Evaluation with Humans and LLMs. ArXiv preprint (2024) [Paper]
- RefuteBench 2.0 -- Agentic Benchmark for Dynamic Evaluation of LLM Responses to Refutation Instruction. ArXiv preprint (2025) [Paper]
- LongEval: A Comprehensive Analysis of Long-Text Generation Through a Plan-based Paradigm. ArXiv preprint (2025) [Paper]
- Factual consistency evaluation of summarization in the Era of large language models. ArXiv preprint (2024) [Paper]
- CopyJudge: Automated Copyright Infringement Identification and Mitigation in Text-to-Image Diffusion Models. ArXiv preprint (2025) [Paper]
01/2025
- CoReQA: Uncovering Potentials of Language Models in Code Repository Question Answering. ArXiv preprint (2025) [Paper]
- MTRAG: A Multi-Turn Conversational Benchmark for Evaluating Retrieval-Augmented Generation Systems. ArXiv preprint (2025) [Paper]
- SMIR: Efficient Synthetic Data Pipeline To Improve Multi-Image Reasoning. ArXiv preprint (2025) [Paper]
- EpiCoder: Encompassing Diversity and Complexity in Code Generation. ArXiv preprint (2025) [Paper]
- Leveraging Large Language Models for Zero-shot Lay Summarisation in Biomedicine and Beyond. ArXiv preprint (2025) [Paper]
- Measuring the Robustness of Reference-Free Dialogue Evaluation Systems. ArXiv preprint (2025) [Paper]
- The Lessons of Developing Process Reward Models in Mathematical Reasoning. ArXiv preprint (2025) [Paper]
- U-MATH: A University-Level Benchmark for Evaluating Mathematical Skills in LLMs. ArXiv preprint (2024) [Paper]
- Agent-as-Judge for Factual Summarization of Long Narratives. ArXiv preprint (2025) [Paper]
- The Alternative Annotator Test for LLM-as-a-Judge: How to Statistically Justify Replacing Human Annotators with LLMs. ArXiv preprint (2025) [Paper]
- The Dual-use Dilemma in LLMs: Do Empowering Ethical Capacities Make a Degraded Utility?. ArXiv preprint (2025) [Paper]
- Potential and Perils of Large Language Models as Judges of Unstructured Textual Data. ArXiv preprint (2025) [Paper]
- Early evidence of how LLMs outperform traditional systems on OCR/HTR tasks for historical records. ArXiv preprint (2025) [Paper]
- Towards Interpretable Radiology Report Generation via Concept Bottlenecks using a Multi-Agentic RAG. ArXiv preprint (2024) [Paper]
- Refining Input Guardrails: Enhancing LLM-as-a-Judge Efficiency Through Chain-of-Thought Fine-Tuning and Alignment. ArXiv preprint (2025) [Paper]
- SedarEval: Automated Evaluation using Self-Adaptive Rubrics. ArXiv preprint (2025) [Paper]
- Beyond correlation: The Impact of Human Uncertainty in Measuring the Effectiveness of Automatic Evaluation and LLM-as-a-Judge. ArXiv preprint (2024) [Paper]
- VeriFact: Verifying Facts in LLM-Generated Clinical Text with Electronic Health Records. ArXiv preprint (2025) [Paper]
- MultiChallenge: A Realistic Multi-Turn Conversation Evaluation Benchmark Challenging to Frontier LLMs. ArXiv preprint (2025) [Paper]
- LLMs can be Fooled into Labelling a Document as Relevant (best cafиж near me; this paper is perfectly relevant). ArXiv preprint (2025) [Paper]
- Learning to Plan & Reason for Evaluation with Thinking-LLM-as-a-Judge. ArXiv preprint (2025) [Paper]
- GroUSE: A Benchmark to Evaluate Evaluators in Grounded Question Answering. ArXiv preprint (2024) [Paper]
- Illusions of Relevance: Using Content Injection Attacks to Deceive Retrievers, Rerankers, and LLM Judges. ArXiv preprint (2025) [Paper]
- Judge Decoding: Faster Speculative Sampling Requires Going Beyond Model Alignment. ArXiv preprint (2025) [Paper]
- Distilling Desired Comments for Enhanced Code Review with Large Language Models. ArXiv preprint (2024) [Paper]
- LLMPC: Large Language Model Predictive Control. ArXiv preprint (2025) [Paper]
- Can LLMs Design Good Questions Based on Context?. ArXiv preprint (2025) [Paper]
- CodEv: An Automated Grading Framework Leveraging Large Language Models for Consistent and Constructive Feedback. ArXiv preprint (2025) [Paper]
- Can Many-Shot In-Context Learning Help LLMs as Evaluators? A Preliminary Empirical Study. ArXiv preprint (2024) [Paper]
- Hierarchical Divide-and-Conquer for Fine-Grained Alignment in LLM-Based Medical Evaluation. ArXiv preprint (2025) [Paper]
- LLM Reading Tea Leaves: Automatically Evaluating Topic Models with Large Language Models. ArXiv preprint (2024) [Paper]
- Evaluating Mathematical Reasoning Beyond Accuracy. ArXiv preprint (2024) [Paper]
- PASS: Presentation Automation for Slide Generation and Speech. ArXiv preprint (2025) [Paper]
- The Veln(ia)s is in the Details: Evaluating LLM Judgment on Latvian and Lithuanian Short Answer Matching. ArXiv preprint (2025) [Paper]
- Aligning with Human Judgement: The Role of Pairwise Preference in Large Language Model Evaluators. ArXiv preprint (2024) [Paper]
- Exploring the Reliability of Large Language Models as Customized Evaluators for Diverse NLP Tasks. ArXiv preprint (2025) [Paper]
- Synthetic Data Can Mislead Evaluations: Membership Inference as Machine Text Detection. ArXiv preprint (2025) [Paper]
- Exploring GPT's Ability as a Judge in Music Understanding. ArXiv preprint (2025) [Paper]
- AdEval: Alignment-based Dynamic Evaluation to Mitigate Data Contamination in Large Language Models. ArXiv preprint (2025) [Paper]
- Recording for Eyes, Not Echoing to Ears: Contextualized Spoken-to-Written Conversion of ASR Transcripts. ArXiv preprint (2024) [Paper]
- ExPerT: Effective and Explainable Evaluation of Personalized Long-Form Text Generation. ArXiv preprint (2025) [Paper]
- Do LLMs Have Visualization Literacy? An Evaluation on Modified Visualizations to Test Generalization in Data Interpretation. ArXiv preprint (2025) [Paper]
- On A Scale From 1 to 5: Quantifying Hallucination in Faithfulness Evaluation. ArXiv preprint (2024) [Paper]
- Audio Large Language Models Can Be Descriptive Speech Quality Evaluators. ArXiv preprint (2025) [Paper]
- Large Language Model Critics for Execution-Free Evaluation of Code Changes. ArXiv preprint (2025) [Paper]
- CSEval: Towards Automated, Multi-Dimensional, and Reference-Free Counterspeech Evaluation using Auto-Calibrated LLMs. ArXiv preprint (2025) [Paper]
- Generative Information Retrieval Evaluation. ArXiv preprint (2024) [Paper]
- Normative Evaluation of Large Language Models with Everyday Moral Dilemmas. ArXiv preprint (2025) [Paper]
- LLM Cyber Evaluations Don't Capture Real-World Risk. ArXiv preprint (2025) [Paper]
- GPT-4o as the Gold Standard: A Scalable and General Purpose Approach to Filter Language Model Pretraining Data. ArXiv preprint (2024) [Paper]
- Large Language Models' Accuracy in Emulating Human Experts' Evaluation of Public Sentiments about Heated Tobacco Products on Social Media. ArXiv preprint (2025) [Paper]
- E2CL: Exploration-based Error Correction Learning for Embodied Agents. ArXiv preprint (2024) [Paper]
- Aligning with Human Judgement: The Role of Pairwise Preference in Large Language Model Evaluators. ArXiv preprint (2024) [Paper]
- Fairer Preferences Elicit Improved Human-Aligned Large Language Model Judgments. ArXiv preprint (2024) [Paper]
- Aligning with Logic: Measuring, Evaluating and Improving Logical Consistency in Large Language Models. ArXiv preprint (2024) [Paper]
- Visual Large Language Models for Generalized and Specialized Applications. ArXiv preprint (2025) [Paper]
- TalBot: An LLM-based robot assisted language learning system for children with language vulnerabilities. ArXiv preprint (2025) [Paper]
- TiEBe: A Benchmark for Assessing the Current Knowledge of Large Language Models. ArXiv preprint (2025) [Paper]
- Solving the Unsolvable: Translating Case Law in Hong Kong. ArXiv preprint (2025) [Paper]
- Atla Selene Mini: A General Purpose Evaluation Model. ArXiv preprint (2025) [Paper]
- M-MAD: Multidimensional Multi-Agent Debate Framework for Fine-grained Machine Translation Evaluation. ArXiv preprint (2024) [Paper]
12/2024
-
CaseSumm: A Large-Scale Dataset for Long-Context Summarization from U.S. Supreme Court Opinions. ArXiv preprint (2024) [Paper]
-
Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models Fan Zhang, Shulin Tian, Ziqi Huang, Yu Qiao, Ziwei Liu. ArXiv preprint (2024) [Paper]
-
Engineering AI Judge Systems Jiahuei Lin (Justina), Dayi Lin, Sky Zhang, Ahmed E. Hassan. ArXiv preprint (2024) [Paper]
-
LMUnit: Fine-grained Evaluation with Natural Language Unit Tests Jon Saad-Falcon, Rajan Vivek, William Berrios, Nandita Shankar Naik, Matija Franklin, Bertie Vidgen, Amanpreet Singh, Douwe Kiela, Shikib Mehri. ArXiv preprint (2024) [Paper]
-
ACE-M3: Automatic Capability Evaluator for Multimodal Medical Models Xiechi Zhang, Shunfan Zheng, Linlin Wang, Gerard de Melo, Zhu Cao, Xiaoling Wang, Liang He. ArXiv preprint (2024) [Paper]
-
IQA-EVAL: Automatic Evaluation of Human-Model Interactive Question Answering Ruosen Li, Ruochen Li, Barry Wang, Xinya Du. ArXiv preprint (2024) [Paper]
-
StrategyLLM: Large Language Models as Strategy Generators, Executors, Optimizers, and Evaluators for Problem Solving Chang Gao, Haiyun Jiang, Deng Cai, Shuming Shi, Wai Lam. ArXiv preprint (2024) [Paper]
-
ALI-Agent: Assessing LLMs' Alignment with Human Values via Agent-based Evaluation Jingnan Zheng, Han Wang, An Zhang, Tai D. Nguyen, Jun Sun, Tat-Seng Chua. ArXiv preprint (2024) [Paper]
-
On scalable oversight with weak LLMs judging strong LLMs Zachary Kenton, Noah Y. Siegel, János Kramár, Jonah Brown-Cohen, Samuel Albanie, Jannis Bulian, Rishabh Agarwal, David Lindner, Yunhao Tang, Noah D. Goodman, Rohin Shah. ArXiv preprint (2024) [Paper]
-
Easy-to-Hard Generalization: Scalable Alignment Beyond Human Supervision Zhiqing Sun, Longhui Yu, Yikang Shen, Weiyang Liu, Yiming Yang, Sean Welleck, Chuang Gan. ArXiv preprint (2024) [Paper]
-
CriticEval: Evaluating Large Language Model as Critic Tian Lan, Wenwei Zhang, Chen Xu, Heyan Huang, Dahua Lin, Kai Chen, Xian-ling Mao. ArXiv preprint (2024) [Paper]
-
Adaptive Image Quality Assessment via Teaching Large Multimodal Model to Compare Hanwei Zhu, Haoning Wu, Yixuan Li, Zicheng Zhang, Baoliang Chen, Lingyu Zhu, Yuming Fang, Guangtao Zhai, Weisi Lin, Shiqi Wang. ArXiv preprint (2024) [Paper]
-
Beyond Guilt: Legal Judgment Prediction with Trichotomous Reasoning Kepu Zhang, Haoyue Yang, Xu Tang, Weijie Yu, Jun Xu. ArXiv preprint (2024) [Paper]
-
Let your LLM generate a few tokens and you will reduce the need for retrieval Hervé Déjean. ArXiv preprint (2024) [Paper]
-
Can You Trust LLM Judgments? Reliability of LLM-as-a-Judge Kayla Schroeder, Zach Wood-Doughty. ArXiv preprint (2024) [Paper]
-
Using LLM-Generated Draft Replies to Support Human Experts in Responding to Stakeholder Inquiries in Maritime Industry: A Real-World Case Study of Industrial AI Tita Alissa Bach, Aleksandar Babic, Narae Park, Tor Sporsem, Rasmus Ulfsnes, Henrik Smith-Meyer, Torkel Skeie. ArXiv preprint (2024) [Paper]
-
An Exploratory Study of ML Sketches and Visual Code Assistants Luís F. Gomes, Vincent J. Hellendoorn, Jonathan Aldrich, Rui Abreu. ArXiv preprint (2024) [Paper]
-
Steering Large Language Models to Evaluate and Amplify Creativity Matthew Lyle Olson, Neale Ratzlaff, Musashi Hinck, Shao-yen Tseng, Vasudev Lal. ArXiv preprint (2024) [Paper]
-
Optimizing Alignment with Less: Leveraging Data Augmentation for Personalized Evaluation Javad Seraj, Mohammad Mahdi Mohajeri, Mohammad Javad Dousti, Majid Nili Ahmadabadi. ArXiv preprint (2024) [Paper]
-
Exploring Large Language Models on Cross-Cultural Values in Connection with Training Methodology Minsang Kim, Seungjun Baek. ArXiv preprint (2024) [Paper]
-
GLIDER: Grading LLM Interactions and Decisions using Explainable Ranking Darshan Deshpande, Selvan Sunitha Ravi, Sky CH-Wang, Bartosz Mielczarek, Anand Kannappan, Rebecca Qian. ArXiv preprint (2024) [Paper]
-
CharacterBench: Benchmarking Character Customization of Large Language Models Jinfeng Zhou, Yongkang Huang, Bosi Wen, Guanqun Bi, Yuxuan Chen, Pei Ke, Zhuang Chen, Xiyao Xiao, Libiao Peng, Kuntian Tang, Rongsheng Zhang, Le Zhang, Tangjie Lv, Zhipeng Hu, Hongning Wang, Minlie Huang. ArXiv preprint (2024) [Paper]
-
LongBench v2: Towards Deeper Understanding and Reasoning on Realistic Long-context Multitasks Yushi Bai, Shangqing Tu, Jiajie Zhang, Hao Peng, Xiaozhi Wang, Xin Lv, Shulin Cao, Jiazheng Xu, Lei Hou, Yuxiao Dong, Jie Tang, Juanzi Li. ArXiv preprint (2024) [Paper]
-
JudgeBlender: Ensembling Judgments for Automatic Relevance Assessment Hossein A. Rahmani, Emine Yilmaz, Nick Craswell, Bhaskar Mitra. ArXiv preprint (2024) [Paper]
-
Assessing the Impact of Conspiracy Theories Using Large Language Models Bohan Jiang, Dawei Li, Zhen Tan, Xinyi Zhou, Ashwin Rao, Kristina Lerman, H. Russell Bernard, Huan Liu. ArXiv preprint (2024) [Paper]
-
Outcome-Refining Process Supervision for Code Generation Zhuohao Yu, Weizheng Gu, Yidong Wang, Zhengran Zeng, Jindong Wang, Wei Ye, Shikun Zhang. ArXiv preprint (2024) [Paper]
-
RAG-RewardBench: Benchmarking Reward Models in Retrieval Augmented Generation for Preference Alignment Zhuoran Jin, Hongbang Yuan, Tianyi Men, Pengfei Cao, Yubo Chen, Kang Liu, Jun Zhao. ArXiv preprint (2024) [Paper]
-
JuStRank: Benchmarking LLM Judges for System Ranking Ariel Gera, Odellia Boni, Yotam Perlitz, Roy Bar-Haim, Lilach Eden, Asaf Yehudai. ArXiv preprint (2024) [Paper]
-
INDICT: Code Generation with Internal Dialogues of Critiques for Both Security and Helpfulness Hung Le, Yingbo Zhou, Caiming Xiong, Silvio Savarese, Doyen Sahoo. ArXiv preprint (2024) [Paper]
-
LLM Evaluators Recognize and Favor Their Own Generations Arjun Panickssery, Samuel R. Bowman, Shi Feng. ArXiv preprint (2024) [Paper]
-
Training Language Models to Critique With Multi-agent Feedback Tian Lan, Wenwei Zhang, Chengqi Lyu, Shuaibin Li, Chen Xu, Heyan Huang, Dahua Lin, Xian-Ling Mao, Kai Chen. ArXiv preprint (2024) [Paper]
-
Beyond Exact Match: Semantically Reassessing Event Extraction by Large Language Models Yi-Fan Lu, Xian-Ling Mao, Tian Lan, Chen Xu, Heyan Huang. ArXiv preprint (2024) [Paper]
-
Automatic Evaluation for Text-to-image Generation: Task-decomposed Framework, Distilled Training, and Meta-evaluation Benchmark Rong-Cheng Tu, Zi-Ao Ma, Tian Lan, Yuehao Zhao, Heyan Huang, Xian-Ling Mao. ArXiv preprint (2024) [Paper]
-
Multi-modal Retrieval Augmented Multi-modal Generation: A Benchmark, Evaluate Metrics and Strong Baselines Zi-Ao Ma, Tian Lan, Rong-Cheng Tu, Yong Hu, Heyan Huang, Xian-Ling Mao. ArXiv preprint (2024) [Paper]
-
LLM-AS-AN-INTERVIEWER: Beyond Static Testing Through Dynamic LLM Evaluation Eunsu Kim, Juyoung Suk, Seungone Kim, Niklas Muennighoff, Dongkwan Kim, Alice Oh. ArXiv preprint (2024) [Paper]
-
MAG-V: A Multi-Agent Framework for Synthetic Data Generation and Verification Saptarshi Sengupta, Kristal Curtis, Akshay Mallipeddi, Abhinav Mathur, Joseph Ross, Liang Gou. ArXiv preprint (2024) [Paper]
-
Law of the Weakest Link: Cross Capabilities of Large Language Models Ming Zhong, Aston Zhang, Xuewei Wang, Rui Hou, Wenhan Xiong, Chenguang Zhu, Zhengxing Chen, Liang Tan, Chloe Bi, Mike Lewis, Sravya Popuri, Sharan Narang, Melanie Kambadur, Dhruv Mahajan, Sergey Edunov, Jiawei Han, Laurens van der Maaten. ArXiv preprint (2024) [Paper]
-
MCQG-SRefine: Multiple Choice Question Generation and Evaluation with Iterative Self-Critique, Correction, and Comparison Feedback Zonghai Yao, Aditya Parashar, Huixue Zhou, Won Seok Jang, Feiyun Ouyang, Zhichao Yang, Hong Yu. ArXiv preprint (2024) [Paper]
-
ALMA: Alignment with Minimal Annotation Michihiro Yasunaga, Leonid Shamis, Chunting Zhou, Andrew Cohen, Jason Weston, Luke Zettlemoyer, Marjan Ghazvininejad. ArXiv preprint (2024) [Paper]
-
ConQRet: Benchmarking Fine-Grained Evaluation of Retrieval Augmented Argumentation with LLM Judges Kaustubh D. Dhole, Kai Shu, Eugene Agichtein. ArXiv preprint (2024) [Paper]
-
Evaluating and Aligning CodeLLMs on Human Preference Jian Yang, Jiaxi Yang, Ke Jin, Yibo Miao, Lei Zhang, Liqun Yang, Zeyu Cui, Yichang Zhang, Binyuan Hui, Junyang Lin. ArXiv preprint (2024) [Paper]
-
Benchmarking LLMs' Judgments with No Gold Standard Shengwei Xu, Yuxuan Lu, Grant Schoenebeck, Yuqing Kong. ArXiv preprint (2024) [Paper]
-
The Vulnerability of Language Model Benchmarks: Do They Accurately Reflect True LLM Performance? Sourav Banerjee, Ayushi Agarwal, Eishkaran Singh. ArXiv preprint (2024) [Paper]
-
Breaking Event Rumor Detection via Stance-Separated Multi-Agent Debate Mingqing Zhang, Haisong Gong, Qiang Liu, Shu Wu, Liang Wang. ArXiv preprint (2024) [Paper]
-
Can Large Language Models Serve as Evaluators for Code Summarization? Yang Wu, Yao Wan, Zhaoyang Chu, Wenting Zhao, Ye Liu, Hongyu Zhang, Xuanhua Shi, Philip S. Yu. ArXiv preprint (2024) [Paper]
1 Attributes
1.1 Helpfulness
- RLAIF: "RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback". Harrison Lee, Samrat Phatale, Hassan Mansoor, Thomas Mesnard, Johan Ferret, Kellie Lu, Colton Bishop, Ethan Hall, Victor Carbune, Abhinav Rastogi, Sushant Prakash ICML 2024. [Paper]
- MT-Bench:Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena Lianmin Zheng, Wei-Lin Chiang, Ying Sheng, Siyuan Zhuang, Zhanghao Wu, Yonghao Zhuang, Zi Lin, Zhuohan Li, Dacheng Li, Eric Xing, Hao Zhang, Joseph E. Gonzalez, Ion Stoica. NeurIPS 2023 . [Paper] [Huggingface]
- Just-Eval: The unlocking spell on base llms: Rethinking alignment via in-context learning. Bill Yuchen Lin, Abhilasha Ravichander, Ximing Lu, Nouha Dziri, Melanie Sclar, Khyathi Chandu, Chandra Bhagavatula, Yejin Choi. ICLR 2024. [Paper]
- Starling: Starling-7b: Improving helpfulness and harmlessness with rlaif. Banghua Zhu, Evan Frick, Tianhao Wu, Hanlin Zhu, Karthik Ganesan, Wei-Lin Chiang, Jian Zhang, Jiantao Jiao. COLM 2024. [Paper][Github]
- AUTO-J: Generative Judge for Evaluating Alignment. Junlong Li, Shichao Sun, Weizhe Yuan, Run-Ze Fan, Hai Zhao, Pengfei Liu. Arxiv 2023. [Paper][Github]
- OAIF: Direct language model alignment from online ai feedback. Shangmin Guo, Biao Zhang, Tianlin Liu, Tianqi Liu, Misha Khalman, Felipe Llinares, Alexandre Rame, Thomas Mesnard, Yao Zhao, Bilal Piot, Johan Ferret, Mathieu Blondeli. Arxiv 2024. [Paper]
- Constitutional AI: "Constitutional AI: Harmlessness from AI Feedback". Yuntao Bai, Saurav Kadavath, Sandipan Kundu, Amanda Askell, Jackson Kernion, Andy Jones, Anna Chen, Anna Goldie, Azalia Mirhoseini, Cameron McKinnon, Carol Chen, Catherine Olsson, Christopher Olah, Danny Hernandez, Dawn Drain, Deep Ganguli, Dustin Li, Eli Tran-Johnson, Ethan Perez, Jamie Kerr, Jared Mueller, Jeffrey Ladish, Joshua Landau, Kamal Ndousse, Kamile Lukosuite, Liane Lovitt,Michael Sellitto, Nelson Elhage, Nicholas Schiefer, Noemi Mercado, Nova DasSarma,Robert Lasenby, Robin Larson, Sam Ringer, Scott Johnston, Shauna Kravec,Sheer El Showk, Stanislav Fort, Tamera Lanham, Timothy Telleen-Lawton, Tom Conerly, Tom Henighan, Tristan Hume, Samuel R. Bowman, Zac Hatfield-Dodds, Ben Mann,Dario Amodei, Nicholas Joseph, Sam McCandlish, Tom Brown, Jared Kaplan arXiv 2022. [Paper] [Github]
1.2 Harmlessness
- LLaMA Guard:Llama guard: Llm-based input-output safeguard for human-ai conversations. Hakan Inan, Kartikeya Upasani, Jianfeng Chi, Rashi Rungta, Krithika Iyer, Yuning Mao, Michael Tontchev, Qing Hu, Brian Fuller, Davide Testuggine, Madian Khabsa. Arxiv, 2023. [Paper] [Code] [Model]
- TRUSTGPT:Enhancing chat language models by scaling high-quality instructional conversations. Ning Ding, Yulin Chen, Bokai Xu, Yujia Qin, Zhi Zheng, Shengding Hu, Zhiyuan Liu, Maosong Sun, and Bowen Zhou. EMNLP 2023. [Paper] [Code]
- Moral Choice:SlimOrca: An Open Dataset of GPT-4 Augmented FLAN Reasoning Traces, with Verification. Wing Lian, Guan Wang, Bleys Goodson, Eugene Pentland, Austin Cook, Chanvichet Vong, and "Teknium". Huggingface, 2023. [Data]
- SORRY-Bench:Stanford Alpaca: An Instruction-following LLaMA model. Rohan Taori, Ishaan Gulrajani, Tianyi Zhang, Yann Dubois, Xuechen Li, Carlos Guestrin, Percy Liang, and Tatsunori B. Hashimoto. GitHub, 2023. [Blog] [Github] [HuggingFace]
- FLASK:OpenChat: Advancing Open-source Language Models with Mixed-Quality Data. Guan Wang, Sijie Cheng, Xianyuan Zhan, Xiangang Li, Sen Song, and Yang Liu. ICLR, 2024. [Paper] [Code] [HuggingFace]
- R-judge:Training language models to follow instructions with human feedback. Long Ouyang, Jeffrey Wu, Xu Jiang, Diogo Almeida, Carroll Wainwright, Pamela Mishkin, Chong Zhang, Sandhini Agarwal, Katarina Slama, Alex Ray, et al. NeurIPS, 2022. [Paper]
- Do-not-answer: Do-Not-Answer: Evaluating Safeguards in {LLM}s. Wang, Yuxia , Li, Haonan , Han, Xudong , Nakov, Preslav , and Baldwin, Timothy. Findings of the Association for Computational Linguistics: EACL 2024 (2024) [Paper]
1.3 Reliability
- RAIN: Your Language Models Can Align Themselves without Finetuning. Li, Yuhui, Wei, Fangyun, Zhao, Jinjing, Zhang, Chao, and Zhang, Hongyang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- FActScore: Fine-grained Atomic Evaluation of Factual Precision in Long Form Text Generation. Min, Sewon , Krishna, Kalpesh , Lyu, Xinxi , Lewis, Mike , Yih, Wen-tau , Koh, Pang , Iyyer, Mohit , Zettlemoyer, Luke , and Hajishirzi, Hannaneh. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Halu-J: Critique-Based Hallucination Judge. Wang, Binjie, Chern, Steffi, Chern, Ethan, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
- HalluDial: A Large-Scale Benchmark for Automatic Dialogue-Level Hallucination Evaluation. Luo, Wen, Shen, Tianshu, Li, Wei, Peng, Guangyue, Xuan, Richeng, Wang, Houfeng, and Yang, Xi. ArXiv preprint (2024) [Paper]
- Evaluating hallucinations in chinese large language models. Cheng, Qinyuan, Sun, Tianxiang, Zhang, Wenwei, Wang, Siyin, Liu, Xiangyang, Zhang, Mozhi, He, Junliang, Huang, Mianqiu, Yin, Zhangyue, Chen, Kai, and others. ArXiv preprint (2023) [Paper]
- SaySelf: Teaching LLMs to Express Confidence with Self-Reflective Rationales. Xu, Tianyang, Wu, Shujin, Diao, Shizhe, Liu, Xiaoze, Wang, Xingyao, Chen, Yangyi, and Gao, Jing. ArXiv preprint (2024) [Paper]
- Long-form factuality in large language models. Wei, Jerry, Yang, Chengrun, Song, Xinying, Lu, Yifeng, Hu, Nathan, Tran, Dustin, Peng, Daiyi, Liu, Ruibo, Huang, Da, Du, Cosmo, and others. ArXiv preprint (2024) [Paper]
- Self-alignment for factuality: Mitigating hallucinations in llms via self-evaluation. Zhang, Xiaoying, Peng, Baolin, Tian, Ye, Zhou, Jingyan, Jin, Lifeng, Song, Linfeng, Mi, Haitao, and Meng, Helen. ArXiv preprint (2024) [Paper]
- FaithScore: Fine-grained Evaluations of Hallucinations in Large Vision-Language Models. Jing, Liqiang, Li, Ruosen, Chen, Yunmo, and Du, Xinya. Findings of the Association for Computational Linguistics: EMNLP 2024 (2024) [Paper]
- Improving Model Factuality with Fine-grained Critique-based Evaluator. Xie, Yiqing, Zhou, Wenxuan, Prakash, Pradyot, Jin, Di, Mao, Yuning, Fettes, Quintin, Talebzadeh, Arya, Wang, Sinong, Fang, Han, Rose, Carolyn, and others. arXiv preprint arXiv:2410.18359 (2024) [Paper]
1.4 Relevance
- LLM-Eval: Unified Multi-Dimensional Automatic Evaluation for Open-Domain Conversations with Large Language Models. Lin, Yen-Ting , and Chen, Yun-Nung. Proceedings of the 5th Workshop on NLP for Conversational AI (NLP4ConvAI 2023) (2023) [Paper]
- MoT: Memory-of-Thought Enables {C}hat{GPT} to Self-Improve. Li, Xiaonan , and Qiu, Xipeng. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Can We Use Large Language Models to Fill Relevance Judgment Holes?. Abbasiantaeb, Zahra, Meng, Chuan, Azzopardi, Leif, and Aliannejadi, Mohammad. ArXiv preprint (2024) [Paper]
- DALK: Dynamic Co-Augmentation of LLMs and KG to answer Alzheimer's Disease Questions with Scientific Literature. Li, Dawei, Yang, Shu, Tan, Zhen, Baik, Jae Young, Yun, Sunkwon, Lee, Joseph, Chacko, Aaron, Hou, Bojian, Duong-Tran, Duy, Ding, Ying, and others. ArXiv preprint (2024) [Paper]
- MJ-Bench: Is Your Multimodal Reward Model Really a Good Judge for Text-to-Image Generation?. Chen, Zhaorun, Du, Yichao, Wen, Zichen, Zhou, Yiyang, Cui, Chenhang, Weng, Zhenzhen, Tu, Haoqin, Wang, Chaoqi, Tong, Zhengwei, Huang, Qinglan, and others. ArXiv preprint (2024) [Paper]
- Large language models can accurately predict searcher preferences. Thomas, Paul, Spielman, Seth, Craswell, Nick, and Mitra, Bhaskar. Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval (2024) [Paper]
- Leveraging Large Language Models for Relevance Judgments in Legal Case Retrieval. Ma, Shengjie, Chen, Chong, Chu, Qi, and Mao, Jiaxin. ArXiv preprint (2024) [Paper]
- Large Language Models are Zero-Shot Rankers for Recommender Systems. Hou, Yupeng, Zhang, Junjie, Lin, Zihan, Lu, Hongyu, Xie, Ruobing, McAuley, Julian, and Zhao, Wayne Xin. European Conference on Information Retrieval (2024) [Paper]
- Can Large Language Models Be an Alternative to Human Evaluations?. Chiang, Cheng-Han , and Lee, Hung-yi. Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2023) [Paper]
- Toward Automatic Relevance Judgment using Vision--Language Models for Image--Text Retrieval Evaluation. Yang, Jheng-Hong, and Lin, Jimmy. ArXiv preprint (2024) [Paper]
- MLLM-as-a-Judge: Assessing Multimodal {LLM}-as-a-Judge with Vision-Language BenchmarkDongping Chen, Ruoxi Chen, Shilin Zhang, Yinuo Liu, Yaochen Wang, Huichi Zhou, Qihui Zhang, Yao Wan, Pan Zhou, Lichao Sun. ArXiv preprint (2024) [Paper]
1.5 Feasibility
- Reasoning with Language Model is Planning with World Model. Hao, Shibo , Gu, Yi , Ma, Haodi , Hong, Joshua , Wang, Zhen , Wang, Daisy , and Hu, Zhiting. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Tree of Thoughts: Deliberate Problem Solving with Large Language Models. Shunyu Yao, Dian Yu, Jeffrey Zhao, Izhak Shafran, Tom Griffiths, Yuan Cao, and Karthik Narasimhan. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Auto-gpt for online decision making: Benchmarks and additional opinions. Yang, Hui, Yue, Sifu, and He, Yunzhong. ArXiv preprint (2023) [Paper]
- Graph of Thoughts: Solving Elaborate Problems with Large Language Models. Maciej Besta, Nils Blach, Ales Kubicek, Robert Gerstenberger, Michal Podstawski, Lukas Gianinazzi, Joanna Gajda, Tomasz Lehmann, Hubert Niewiadomski, Piotr Nyczyk, and Torsten Hoefler. Thirty-Eighth {AAAI} Conference on Artificial Intelligence, {AAAI} 2024, Thirty-Sixth Conference on Innovative Applications of Artificial Intelligence, {IAAI} 2024, Fourteenth Symposium on Educational Advances in Artificial Intelligence, {EAAI} 2014, February 20-27, 2024, Vancouver, Canada (2024) [Paper]
- DiffAgent: Fast and Accurate Text-to-Image API Selection with Large Language Model. Zhao, Lirui, Yang, Yue, Zhang, Kaipeng, Shao, Wenqi, Zhang, Yuxin, Qiao, Yu, Luo, Ping, and Ji, Rongrong. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (2024) [Paper]
- Routellm: Learning to route llms with preference data. Ong, Isaac, Almahairi, Amjad, Wu, Vincent, Chiang, Wei-Lin, Wu, Tianhao, Gonzalez, Joseph E, Kadous, M Waleed, and Stoica, Ion. ArXiv preprint (2024) [Paper]
- Encouraging divergent thinking in large language models through multi-agent debate. Liang, Tian, He, Zhiwei, Jiao, Wenxiang, Wang, Xing, Wang, Yan, Wang, Rui, Yang, Yujiu, Tu, Zhaopeng, and Shi, Shuming. ArXiv preprint (2023) [Paper]
- SMoA: Improving Multi-agent Large Language Models with Sparse Mixture-of-Agents. Li, Dawei, Tan, Zhen, Qian, Peijia, Li, Yifan, Chaudhary, Kumar Satvik, Hu, Lijie, and Shen, Jiayi. ArXiv preprint (2024) [Paper]
1.6 Overall Quality
- Human-like summarization evaluation with chatgpt. Gao, Mingqi, Ruan, Jie, Sun, Renliang, Yin, Xunjian, Yang, Shiping, and Wan, Xiaojun. ArXiv preprint (2023) [Paper]
- The unlocking spell on base llms: Rethinking alignment via in-context learning. Lin, Bill Yuchen, Ravichander, Abhilasha, Lu, Ximing, Dziri, Nouha, Sclar, Melanie, Chandu, Khyathi, Bhagavatula, Chandra, and Choi, Yejin. The Twelfth International Conference on Learning Representations (2023) [Paper]
- Multi-Dimensional Evaluation of Text Summarization with In-Context Learning. Jain, Sameer , Keshava, Vaishakh , Mysore Sathyendra, Swarnashree , Fernandes, Patrick , Liu, Pengfei , Neubig, Graham , and Zhou, Chunting. Findings of the Association for Computational Linguistics: ACL 2023 (2023) [Paper]
- LLM-Eval: Unified Multi-Dimensional Automatic Evaluation for Open-Domain Conversations with Large Language Models. Lin, Yen-Ting , and Chen, Yun-Nung. Proceedings of the 5th Workshop on NLP for Conversational AI (NLP4ConvAI 2023) (2023) [Paper]
- Large Language Models Are State-of-the-Art Evaluators of Translation Quality. Kocmi, Tom , and Federmann, Christian. Proceedings of the 24th Annual Conference of the European Association for Machine Translation (2023) [Paper]
- Kieval: A knowledge-grounded interactive evaluation framework for large language models. Yu, Zhuohao, Gao, Chang, Yao, Wenjin, Wang, Yidong, Ye, Wei, Wang, Jindong, Xie, Xing, Zhang, Yue, and Zhang, Shikun. ArXiv preprint (2024) [Paper]
- Direct language model alignment from online ai feedback. Guo, Shangmin, Zhang, Biao, Liu, Tianlin, Liu, Tianqi, Khalman, Misha, Llinares, Felipe, Rame, Alexandre, Mesnard, Thomas, Zhao, Yao, Piot, Bilal, and others. ArXiv preprint (2024) [Paper]
- A Comprehensive Analysis of the Effectiveness of Large Language Models as Automatic Dialogue Evaluators. Chen Zhang, Luis Fernando D'Haro, Yiming Chen, Malu Zhang, and Haizhou Li. Thirty-Eighth {AAAI} Conference on Artificial Intelligence, {AAAI} 2024, Thirty-Sixth Conference on Innovative Applications of Artificial Intelligence, {IAAI} 2024, Fourteenth Symposium on Educational Advances in Artificial Intelligence, {EAAI} 2014, February 20-27, 2024, Vancouver, Canada (2024) [Paper]
- Lost in the Source Language: How Large Language Models Evaluate the Quality of Machine Translation. Xu Huang, Zhirui Zhang, Xiang Geng, Yichao Du, Jiajun Chen, and Shujian Huang. Annual Meeting of the Association for Computational Linguistics (2024) [Paper]
2 Methodology
2.1 Tuning
Data Source
Manually-labeled
- Automatic Evaluation of Attribution by Large Language Models. Yue, Xiang , Wang, Boshi , Chen, Ziru , Zhang, Kai , Su, Yu , and Sun, Huan. Findings of the Association for Computational Linguistics: EMNLP 2023 (2023) [Paper]
- INSTRUCTSCORE: Towards Explainable Text Generation Evaluation with Automatic Feedback. Xu, Wenda , Wang, Danqing , Pan, Liangming , Song, Zhenqiao , Freitag, Markus , Wang, William , and Li, Lei. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- X-Eval: Generalizable Multi-aspect Text Evaluation via Augmented Instruction Tuning with Auxiliary Evaluation Aspects. Liu, Minqian , Shen, Ying , Xu, Zhiyang , Cao, Yixin , Cho, Eunah , Kumar, Vaibhav , Ghanadan, Reza , and Huang, Lifu. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (2024) [Paper]
- CritiqueLLM: Towards an informative critique generation model for evaluation of large language model generation. Ke, Pei, Wen, Bosi, Feng, Andrew, Liu, Xiao, Lei, Xuanyu, Cheng, Jiale, Wang, Shengyuan, Zeng, Aohan, Dong, Yuxiao, Wang, Hongning, and others. Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2024) [Paper]
- Foundational autoraters: Taming large language models for better automatic evaluation. Vu, Tu, Krishna, Kalpesh, Alzubi, Salaheddin, Tar, Chris, Faruqui, Manaal, and Sung, Yun-Hsuan. ArXiv preprint (2024) [Paper]
Synthetic Feedback
- Judgelm: Fine-tuned large language models are scalable judges. Zhu, Lianghui, Wang, Xinggang, and Wang, Xinlong. ArXiv preprint (2023) [Paper]
- Meta-rewarding language models: Self-improving alignment with llm-as-a-meta-judge. Wu, Tianhao, Yuan, Weizhe, Golovneva, Olga, Xu, Jing, Tian, Yuandong, Jiao, Jiantao, Weston, Jason, and Sukhbaatar, Sainbayar. ArXiv preprint (2024) [Paper]
- Self-taught evaluators. Wang, Tianlu, Kulikov, Ilia, Golovneva, Olga, Yu, Ping, Yuan, Weizhe, Dwivedi-Yu, Jane, Pang, Richard Yuanzhe, Fazel-Zarandi, Maryam, Weston, Jason, and Li, Xian. ArXiv preprint (2024) [Paper]
- Halu-J: Critique-Based Hallucination Judge. Wang, Binjie, Chern, Steffi, Chern, Ethan, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
- Offsetbias: Leveraging debiased data for tuning evaluators. Park, Junsoo, Jwa, Seungyeon, Ren, Meiying, Kim, Daeyoung, and Choi, Sanghyuk. ArXiv preprint (2024) [Paper]
- Sorry-bench: Systematically evaluating large language model safety refusal behaviors. Xie, Tinghao, Qi, Xiangyu, Zeng, Yi, Huang, Yangsibo, Sehwag, Udari Madhushani, Huang, Kaixuan, He, Luxi, Wei, Boyi, Li, Dacheng, Sheng, Ying, and others. ArXiv preprint (2024) [Paper]
- LLaVA-Critic: Learning to Evaluate Multimodal Models. Xiong, Tianyi, Wang, Xiyao, Guo, Dong, Ye, Qinghao, Fan, Haoqi, Gu, Quanquan, Huang, Heng, and Li, Chunyuan. ArXiv preprint (2024) [Paper]
- Prometheus 2: An open source language model specialized in evaluating other language models. Kim, Seungone, Suk, Juyoung, Longpre, Shayne, Lin, Bill Yuchen, Shin, Jamin, Welleck, Sean, Neubig, Graham, Lee, Moontae, Lee, Kyungjae, and Seo, Minjoon. ArXiv preprint (2024) [Paper]
- INSTRUCTSCORE: Towards Explainable Text Generation Evaluation with Automatic Feedback. Xu, Wenda , Wang, Danqing , Pan, Liangming , Song, Zhenqiao , Freitag, Markus , Wang, William , and Li, Lei. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
Tuning Techiniques
Supervised Fine-Tuning
- Learning personalized story evaluation. Wang, Danqing, Yang, Kevin, Zhu, Hanlin, Yang, Xiaomeng, Cohen, Andrew, Li, Lei, and Tian, Yuandong. ArXiv preprint (2023) [Paper]
- INSTRUCTSCORE: Towards Explainable Text Generation Evaluation with Automatic Feedback. Xu, Wenda , Wang, Danqing , Pan, Liangming , Song, Zhenqiao , Freitag, Markus , Wang, William , and Li, Lei. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- CritiqueLLM: Towards an informative critique generation model for evaluation of large language model generation. Ke, Pei, Wen, Bosi, Feng, Andrew, Liu, Xiao, Lei, Xuanyu, Cheng, Jiale, Wang, Shengyuan, Zeng, Aohan, Dong, Yuxiao, Wang, Hongning, and others. Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2024) [Paper]
- X-Eval: Generalizable Multi-aspect Text Evaluation via Augmented Instruction Tuning with Auxiliary Evaluation Aspects. Liu, Minqian , Shen, Ying , Xu, Zhiyang , Cao, Yixin , Cho, Eunah , Kumar, Vaibhav , Ghanadan, Reza , and Huang, Lifu. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (2024) [Paper]
- Judgelm: Fine-tuned large language models are scalable judges. Zhu, Lianghui, Wang, Xinggang, and Wang, Xinlong. ArXiv preprint (2023) [Paper]
- Sorry-bench: Systematically evaluating large language model safety refusal behaviors. Xie, Tinghao, Qi, Xiangyu, Zeng, Yi, Huang, Yangsibo, Sehwag, Udari Madhushani, Huang, Kaixuan, He, Luxi, Wei, Boyi, Li, Dacheng, Sheng, Ying, and others. ArXiv preprint (2024) [Paper]
- Automatic Evaluation of Attribution by Large Language Models. Yue, Xiang , Wang, Boshi , Chen, Ziru , Zhang, Kai , Su, Yu , and Sun, Huan. Findings of the Association for Computational Linguistics: EMNLP 2023 (2023) [Paper]
- Foundational autoraters: Taming large language models for better automatic evaluation. Vu, Tu, Krishna, Kalpesh, Alzubi, Salaheddin, Tar, Chris, Faruqui, Manaal, and Sung, Yun-Hsuan. ArXiv preprint (2024) [Paper]
- Prometheus 2: An open source language model specialized in evaluating other language models. Kim, Seungone, Suk, Juyoung, Longpre, Shayne, Lin, Bill Yuchen, Shin, Jamin, Welleck, Sean, Neubig, Graham, Lee, Moontae, Lee, Kyungjae, and Seo, Minjoon. ArXiv preprint (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- CritiqueLLM: Towards an informative critique generation model for evaluation of large language model generation. Ke, Pei, Wen, Bosi, Feng, Andrew, Liu, Xiao, Lei, Xuanyu, Cheng, Jiale, Wang, Shengyuan, Zeng, Aohan, Dong, Yuxiao, Wang, Hongning, and others. Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2024) [Paper]
- X-Eval: Generalizable Multi-aspect Text Evaluation via Augmented Instruction Tuning with Auxiliary Evaluation Aspects. Liu, Minqian , Shen, Ying , Xu, Zhiyang , Cao, Yixin , Cho, Eunah , Kumar, Vaibhav , Ghanadan, Reza , and Huang, Lifu. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (2024) [Paper]
Preference Learning
- Halu-J: Critique-Based Hallucination Judge. Wang, Binjie, Chern, Steffi, Chern, Ethan, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
- Offsetbias: Leveraging debiased data for tuning evaluators. Park, Junsoo, Jwa, Seungyeon, Ren, Meiying, Kim, Daeyoung, and Choi, Sanghyuk. ArXiv preprint (2024) [Paper]
- Themis: A Reference-free NLG Evaluation Language Model with Flexibility and Interpretability. Hu, Xinyu, Lin, Li, Gao, Mingqi, Yin, Xunjian, and Wan, Xiaojun. ArXiv preprint (2024) [Paper]
- Meta-rewarding language models: Self-improving alignment with llm-as-a-meta-judge. Wu, Tianhao, Yuan, Weizhe, Golovneva, Olga, Xu, Jing, Tian, Yuandong, Jiao, Jiantao, Weston, Jason, and Sukhbaatar, Sainbayar. ArXiv preprint (2024) [Paper]
- Self-taught evaluators. Wang, Tianlu, Kulikov, Ilia, Golovneva, Olga, Yu, Ping, Yuan, Weizhe, Dwivedi-Yu, Jane, Pang, Richard Yuanzhe, Fazel-Zarandi, Maryam, Weston, Jason, and Li, Xian. ArXiv preprint (2024) [Paper]
- Split and Merge: Aligning Position Biases in LLM-based Evaluators. Li, Zongjie, Wang, Chaozheng, Ma, Pingchuan, Wu, Daoyuan, Wang, Shuai, Gao, Cuiyun, and Liu, Yang. Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing (2024) [Paper]
2.2 Prompting
Swapping Operation
- Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena. Lianmin Zheng, Wei{-}Lin Chiang, Ying Sheng, Siyuan Zhuang, Zhanghao Wu, Yonghao Zhuang, Zi Lin, Zhuohan Li, Dacheng Li, Eric P. Xing, Hao Zhang, Joseph E. Gonzalez, and Ion Stoica. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Rlaif: Scaling reinforcement learning from human feedback with ai feedback. Lee, Harrison, Phatale, Samrat, Mansoor, Hassan, Mesnard, Thomas, Ferret, Johan, Lu, Kellie, Bishop, Colton, Hall, Ethan, Carbune, Victor, Rastogi, Abhinav, and others. ArXiv preprint (2023) [Paper]
- SALMON: Self-Alignment with Instructable Reward Models. Sun, Zhiqing, Shen, Yikang, Zhang, Hongxin, Zhou, Qinhong, Chen, Zhenfang, Cox, David Daniel, Yang, Yiming, and Gan, Chuang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- Starling-7b: Improving helpfulness and harmlessness with rlaif. Zhu, Banghua, Frick, Evan, Wu, Tianhao, Zhu, Hanlin, Ganesan, Karthik, Chiang, Wei-Lin, Zhang, Jian, and Jiao, Jiantao. First Conference on Language Modeling (2024) [Paper]
Rule Augmentation
- Constitutional ai: Harmlessness from ai feedback. Bai, Yuntao, Kadavath, Saurav, Kundu, Sandipan, Askell, Amanda, Kernion, Jackson, Jones, Andy, Chen, Anna, Goldie, Anna, Mirhoseini, Azalia, McKinnon, Cameron, and others. ArXiv preprint (2022) [Paper]
- MoT: Memory-of-Thought Enables {C}hat{GPT} to Self-Improve. Li, Xiaonan , and Qiu, Xipeng. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Improving Diversity of Demographic Representation in Large Language Models via Collective-Critiques and Self-Voting. Lahoti, Preethi , Blumm, Nicholas , Ma, Xiao , Kotikalapudi, Raghavendra , Potluri, Sahitya , Tan, Qijun , Srinivasan, Hansa , Packer, Ben , Beirami, Ahmad , Beutel, Alex , and Chen, Jilin. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Rlaif: Scaling reinforcement learning from human feedback with ai feedback. Lee, Harrison, Phatale, Samrat, Mansoor, Hassan, Mesnard, Thomas, Ferret, Johan, Lu, Kellie, Bishop, Colton, Hall, Ethan, Carbune, Victor, Rastogi, Abhinav, and others. ArXiv preprint (2023) [Paper]
- LRQ-Fact: LLM-Generated Relevant Questions for Multimodal Fact-Checking. Beigi, Alimohammad, Jiang, Bohan, Li, Dawei, Kumarage, Tharindu, Tan, Zhen, Shaeri, Pouya, and Liu, Huan. ArXiv preprint (2024) [Paper]
- Benchmarking Foundation Models with Language-Model-as-an-Examiner. Yushi Bai, Jiahao Ying, Yixin Cao, Xin Lv, Yuze He, Xiaozhi Wang, Jifan Yu, Kaisheng Zeng, Yijia Xiao, Haozhe Lyu, Jiayin Zhang, Juanzi Li, and Lei Hou. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Human-like summarization evaluation with chatgpt. Gao, Mingqi, Ruan, Jie, Sun, Renliang, Yin, Xunjian, Yang, Shiping, and Wan, Xiaojun. ArXiv preprint (2023) [Paper]
- Prometheus: Inducing fine-grained evaluation capability in language models. Kim, Seungone, Shin, Jamin, Cho, Yejin, Jang, Joel, Longpre, Shayne, Lee, Hwaran, Yun, Sangdoo, Shin, Seongjin, Kim, Sungdong, Thorne, James, and others. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Kieval: A knowledge-grounded interactive evaluation framework for large language models. Yu, Zhuohao, Gao, Chang, Yao, Wenjin, Wang, Yidong, Ye, Wei, Wang, Jindong, Xie, Xing, Zhang, Yue, and Zhang, Shikun. ArXiv preprint (2024) [Paper]
- CEB: Compositional Evaluation Benchmark for Fairness in Large Language Models. Wang, Song, Wang, Peng, Zhou, Tong, Dong, Yushun, Tan, Zhen, and Li, Jundong. ArXiv preprint (2024) [Paper]
- Evaluating the Evaluator: Measuring LLMs' Adherence to Task Evaluation Instructions. Murugadoss, Bhuvanashree, Poelitz, Christian, Drosos, Ian, Le, Vu, McKenna, Nick, Negreanu, Carina Suzana, Parnin, Chris, and Sarkar, Advait. ArXiv preprint (2024) [Paper]
- Calibrating {LLM}-Based Evaluator. Liu, Yuxuan , Yang, Tianchi , Huang, Shaohan , Zhang, Zihan , Huang, Haizhen , Wei, Furu , Deng, Weiwei , Sun, Feng , and Zhang, Qi. Proceedings of the 2024 Joint International Conference on Computational Linguistics, Language Resources and Evaluation (LREC-COLING 2024) (2024) [Paper]
- Direct language model alignment from online ai feedback. Guo, Shangmin, Zhang, Biao, Liu, Tianlin, Liu, Tianqi, Khalman, Misha, Llinares, Felipe, Rame, Alexandre, Mesnard, Thomas, Zhao, Yao, Piot, Bilal, and others. ArXiv preprint (2024) [Paper]
- SALMON: Self-Alignment with Instructable Reward Models. Sun, Zhiqing, Shen, Yikang, Zhang, Hongxin, Zhou, Qinhong, Chen, Zhenfang, Cox, David Daniel, Yang, Yiming, and Gan, Chuang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- DALK: Dynamic Co-Augmentation of LLMs and KG to answer Alzheimer's Disease Questions with Scientific Literature. Li, Dawei, Yang, Shu, Tan, Zhen, Baik, Jae Young, Yun, Sunkwon, Lee, Joseph, Chacko, Aaron, Hou, Bojian, Duong-Tran, Duy, Ding, Ying, and others. ArXiv preprint (2024) [Paper]
- What do Large Language Models Need for Machine Translation Evaluation?. Qian, Shenbin, Sindhujan, Archchana, Kabra, Minnie, Kanojia, Diptesh, Ora{\v{s}}an, Constantin, Ranasinghe, Tharindu, and Blain, Fred. Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing (2024) [Paper]
- RevisEval: Improving LLM-as-a-Judge via Response-Adapted References. Zhang, Qiyuan, Wang, Yufei, Yu, Tiezheng, Jiang, Yuxin, Wu, Chuhan, Li, Liangyou, Wang, Yasheng, Jiang, Xin, Shang, Lifeng, Tang, Ruiming, and others. ArXiv preprint (2024) [Paper]
- Can LLM be a Personalized Judge?. Dong, Yijiang River, Hu, Tiancheng, and Collier, Nigel. ArXiv preprint (2024) [Paper]
Multi-Agent Collaboration
- Prd: Peer rank and discussion improve large language model based evaluations. Li, Ruosen, Patel, Teerth, and Du, Xinya. ArXiv preprint (2023) [Paper]
- Wider and deeper llm networks are fairer llm evaluators. Zhang, Xinghua, Yu, Bowen, Yu, Haiyang, Lv, Yangyu, Liu, Tingwen, Huang, Fei, Xu, Hongbo, and Li, Yongbin. ArXiv preprint (2023) [Paper]
- Large language models are diverse role-players for summarization evaluation. Wu, Ning, Gong, Ming, Shou, Linjun, Liang, Shining, and Jiang, Daxin. CCF International Conference on Natural Language Processing and Chinese Computing (2023) [Paper]
- Dynamic Evaluation of Large Language Models by Meta Probing Agents. Zhu, Kaijie, Wang, Jindong, Zhao, Qinlin, Xu, Ruochen, and Xie, Xing. Forty-first International Conference on Machine Learning (2024) [Paper]
- Judgelm: Fine-tuned large language models are scalable judges. Zhu, Lianghui, Wang, Xinggang, and Wang, Xinlong. ArXiv preprint (2023) [Paper]
- ChatEval: Towards Better LLM-based Evaluators through Multi-Agent Debate. Chan, Chi-Min, Chen, Weize, Su, Yusheng, Yu, Jianxuan, Xue, Wei, Zhang, Shanghang, Fu, Jie, and Liu, Zhiyuan. The Twelfth International Conference on Learning Representations (2023) [Paper]
- CoEvol: Constructing Better Responses for Instruction Finetuning through Multi-Agent Cooperation. Li, Renhao, Tan, Minghuan, Wong, Derek F, and Yang, Min. ArXiv preprint (2024) [Paper]
- LRQ-Fact: LLM-Generated Relevant Questions for Multimodal Fact-Checking. Beigi, Alimohammad, Jiang, Bohan, Li, Dawei, Kumarage, Tharindu, Tan, Zhen, Shaeri, Pouya, and Liu, Huan. ArXiv preprint (2024) [Paper]
- Trust or Escalate: LLM Judges with Provable Guarantees for Human Agreement. Jung, Jaehun, Brahman, Faeze, and Choi, Yejin. ArXiv preprint (2024) [Paper]
- The Fellowship of the LLMs: Multi-Agent Workflows for Synthetic Preference Optimization Dataset Generation. Arif, Samee, Farid, Sualeha, Azeemi, Abdul Hameed, Athar, Awais, and Raza, Agha Ali. ArXiv preprint (2024) [Paper]
Demonstration
- Multi-Dimensional Evaluation of Text Summarization with In-Context Learning. Jain, Sameer , Keshava, Vaishakh , Mysore Sathyendra, Swarnashree , Fernandes, Patrick , Liu, Pengfei , Neubig, Graham , and Zhou, Chunting. Findings of the Association for Computational Linguistics: ACL 2023 (2023) [Paper]
- Little Giants: Exploring the Potential of Small {LLM}s as Evaluation Metrics in Summarization in the {E}val4{NLP} 2023 Shared Task. Kotonya, Neema , Krishnasamy, Saran , Tetreault, Joel , and Jaimes, Alejandro. Proceedings of the 4th Workshop on Evaluation and Comparison of NLP Systems (2023) [Paper]
- ALLURE: auditing and improving llm-based evaluation of text using iterative in-context-learning. Hasanbeig, Hosein, Sharma, Hiteshi, Betthauser, Leo, Vieira Frujeri, Felipe, and Momennejad, Ida. arXiv e-prints (2023) [Paper]
- Can Many-Shot In-Context Learning Help Long-Context LLM Judges? See More, Judge Better!. Song, Mingyang, Zheng, Mao, and Luo, Xuan. ArXiv preprint (2024) [Paper]
Multi-Turn Interaction
- Benchmarking Foundation Models with Language-Model-as-an-Examiner. Yushi Bai, Jiahao Ying, Yixin Cao, Xin Lv, Yuze He, Xiaozhi Wang, Jifan Yu, Kaisheng Zeng, Yijia Xiao, Haozhe Lyu, Jiayin Zhang, Juanzi Li, and Lei Hou. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Kieval: A knowledge-grounded interactive evaluation framework for large language models. Yu, Zhuohao, Gao, Chang, Yao, Wenjin, Wang, Yidong, Ye, Wei, Wang, Jindong, Xie, Xing, Zhang, Yue, and Zhang, Shikun. ArXiv preprint (2024) [Paper]
- Auto Arena of LLMs: Automating LLM Evaluations with Agent Peer-battles and Committee Discussions. Zhao, Ruochen, Zhang, Wenxuan, Chia, Yew Ken, Zhao, Deli, and Bing, Lidong. ArXiv preprint (2024) [Paper]
- Evaluating the Performance of Large Language Models via Debates. Moniri, Behrad, Hassani, Hamed, and Dobriban, Edgar. ArXiv preprint (2024) [Paper]
Comparison Acceleration
- Statistical rejection sampling improves preference optimization. Liu, Tianqi, Zhao, Yao, Joshi, Rishabh, Khalman, Misha, Saleh, Mohammad, Liu, Peter J, and Liu, Jialu. ArXiv preprint (2023) [Paper]
- Online Self-Preferring Language Models. Zhai, Yuanzhao, Zhang, Zhuo, Xu, Kele, Peng, Hanyang, Yu, Yue, Feng, Dawei, Yang, Cheng, Ding, Bo, and Wang, Huaimin. ArXiv preprint (2024) [Paper]
- Starling-7b: Improving helpfulness and harmlessness with rlaif. Zhu, Banghua, Frick, Evan, Wu, Tianhao, Zhu, Hanlin, Ganesan, Karthik, Chiang, Wei-Lin, Zhang, Jian, and Jiao, Jiantao. First Conference on Language Modeling (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
3 Application
3.1 Evaluation
-
FutureAGI agent-opt - Open-source library for automated optimization of AI agent workflows with evaluation-driven prompt and config tuning, including LLM-as-judge support.
-
Oceangpt: A large language model for ocean science tasks. Bi, Zhen, Zhang, Ningyu, Xue, Yida, Ou, Yixin, Ji, Daxiong, Zheng, Guozhou, and Chen, Huajun. ArXiv preprint (2023) [Paper]
-
Lawbench: Benchmarking legal knowledge of large language models. Fei, Zhiwei, Shen, Xiaoyu, Zhu, Dawei, Zhou, Fengzhe, Han, Zhuo, Zhang, Songyang, Chen, Kai, Shen, Zongwen, and Ge, Jidong. ArXiv preprint (2023) [Paper]
-
Sotopia: Interactive evaluation for social intelligence in language agents. Zhou, Xuhui, Zhu, Hao, Mathur, Leena, Zhang, Ruohong, Yu, Haofei, Qi, Zhengyang, Morency, Louis-Philippe, Bisk, Yonatan, Fried, Daniel, Neubig, Graham, and others. ArXiv preprint (2023) [Paper]
-
Can {C}hat{GPT} Defend its Belief in Truth? Evaluating {LLM} Reasoning via Debate. Wang, Boshi , Yue, Xiang , and Sun, Huan. Findings of the Association for Computational Linguistics: EMNLP 2023 (2023) [Paper]
-
On Evaluating the Integration of Reasoning and Action in {LLM} Agents with Database Question Answering. Nan, Linyong , Zhang, Ellen , Zou, Weijin , Zhao, Yilun , Zhou, Wenfei , and Cohan, Arman. Findings of the Association for Computational Linguistics: NAACL 2024 (2024) [Paper]
-
Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena. Lianmin Zheng, Wei{-}Lin Chiang, Ying Sheng, Siyuan Zhuang, Zhanghao Wu, Yonghao Zhuang, Zi Lin, Zhuohan Li, Dacheng Li, Eric P. Xing, Hao Zhang, Joseph E. Gonzalez, and Ion Stoica. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
-
Human-like summarization evaluation with chatgpt. Gao, Mingqi, Ruan, Jie, Sun, Renliang, Yin, Xunjian, Yang, Shiping, and Wan, Xiaojun. ArXiv preprint (2023) [Paper]
-
Large language models are diverse role-players for summarization evaluation. Wu, Ning, Gong, Ming, Shou, Linjun, Liang, Shining, and Jiang, Daxin. CCF International Conference on Natural Language Processing and Chinese Computing (2023) [Paper]
-
Evaluating hallucinations in chinese large language models. Cheng, Qinyuan, Sun, Tianxiang, Zhang, Wenwei, Wang, Siyin, Liu, Xiangyang, Zhang, Mozhi, He, Junliang, Huang, Mianqiu, Yin, Zhangyue, Chen, Kai, and others. ArXiv preprint (2023) [Paper]
-
LLM-Eval: Unified Multi-Dimensional Automatic Evaluation for Open-Domain Conversations with Large Language Models. Lin, Yen-Ting , and Chen, Yun-Nung. Proceedings of the 5th Workshop on NLP for Conversational AI (NLP4ConvAI 2023) (2023) [Paper]
-
Beyond Accuracy: Evaluating the Reasoning Behavior of Large Language Models--A Survey. Mondorf, Philipp, and Plank, Barbara. ArXiv preprint (2024) [Paper]
-
Reference-Guided Verdict: LLMs-as-Judges in Automatic Evaluation of Free-Form Text. Badshah, Sher, and Sajjad, Hassan. ArXiv preprint (2024) [Paper]
-
Benchmarking Foundation Models with Language-Model-as-an-Examiner. Yushi Bai, Jiahao Ying, Yixin Cao, Xin Lv, Yuze He, Xiaozhi Wang, Jifan Yu, Kaisheng Zeng, Yijia Xiao, Haozhe Lyu, Jiayin Zhang, Juanzi Li, and Lei Hou. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
-
Decoding biases: Automated methods and llm judges for gender bias detection in language models. Kumar, Shachi H, Sahay, Saurav, Mazumder, Sahisnu, Okur, Eda, Manuvinakurike, Ramesh, Beckage, Nicole, Su, Hsuan, Lee, Hung-yi, and Nachman, Lama. ArXiv preprint (2024) [Paper]
-
Halu-J: Critique-Based Hallucination Judge. Wang, Binjie, Chern, Steffi, Chern, Ethan, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
-
Salad-bench: A hierarchical and comprehensive safety benchmark for large language models. Li, Lijun, Dong, Bowen, Wang, Ruohui, Hu, Xuhao, Zuo, Wangmeng, Lin, Dahua, Qiao, Yu, and Shao, Jing. ArXiv preprint (2024) [Paper]
-
Sorry-bench: Systematically evaluating large language model safety refusal behaviors. Xie, Tinghao, Qi, Xiangyu, Zeng, Yi, Huang, Yangsibo, Sehwag, Udari Madhushani, Huang, Kaixuan, He, Luxi, Wei, Boyi, Li, Dacheng, Sheng, Ying, and others. ArXiv preprint (2024) [Paper]
-
ChatEval: Towards Better LLM-based Evaluators through Multi-Agent Debate. Chan, Chi-Min, Chen, Weize, Su, Yusheng, Yu, Jianxuan, Xue, Wei, Zhang, Shanghang, Fu, Jie, and Liu, Zhiyuan. The Twelfth International Conference on Learning Representations (2023) [Paper]
-
Evaluating the Performance of Large Language Models via Debates. Moniri, Behrad, Hassani, Hamed, and Dobriban, Edgar. ArXiv preprint (2024) [Paper]
-
Evaluating Mathematical Reasoning Beyond Accuracy. Xia, Shijie, Li, Xuefeng, Liu, Yixin, Wu, Tongshuang, and Liu, Pengfei. ArXiv preprint (2024) [Paper]
-
Test of Time: A Benchmark for Evaluating LLMs on Temporal Reasoning. Fatemi, Bahare, Kazemi, Mehran, Tsitsulin, Anton, Malkan, Karishma, Yim, Jinyeong, Palowitch, John, Seo, Sungyong, Halcrow, Jonathan, and Perozzi, Bryan. ArXiv preprint (2024) [Paper]
-
LogicBench: Towards systematic evaluation of logical reasoning ability of large language models. Parmar, Mihir, Patel, Nisarg, Varshney, Neeraj, Nakamura, Mutsumi, Luo, Man, Mashetty, Santosh, Mitra, Arindam, and Baral, Chitta. Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (2024) [Paper]
-
Academically intelligent LLMs are not necessarily socially intelligent. Xu, Ruoxi, Lin, Hongyu, Han, Xianpei, Sun, Le, and Sun, Yingfei. ArXiv preprint (2024) [Paper]
-
LLaVA-Critic: Learning to Evaluate Multimodal Models. Xiong, Tianyi, Wang, Xiyao, Guo, Dong, Ye, Qinghao, Fan, Haoqi, Gu, Quanquan, Huang, Heng, and Li, Chunyuan. ArXiv preprint (2024) [Paper]
-
Automated evaluation of large vision-language models on self-driving corner cases. Chen, Kai, Li, Yanze, Zhang, Wenhua, Liu, Yanxin, Li, Pengxiang, Gao, Ruiyuan, Hong, Lanqing, Tian, Meng, Zhao, Xinhai, Li, Zhenguo, and others. ArXiv preprint (2024) [Paper]
-
CodeJudge-Eval: A Benchmark for Evaluating Code Generation. Zhao, John, and others. ArXiv preprint (2024) [Paper]
-
Prompt-Gaming: A Pilot Study on LLM-Evaluating Agent in a Meaningful Energy Game. Isaza-Giraldo, Andr{'e}s, Bala, Paulo, Campos, Pedro F, and Pereira, Lucas. Extended Abstracts of the CHI Conference on Human Factors in Computing Systems (2024) [Paper]
-
HealthQ: Unveiling Questioning Capabilities of LLM Chains in Healthcare Conversations. Wang, Ziyu, Li, Hao, Huang, Di, and Rahmani, Amir M. ArXiv preprint (2024) [Paper]
3.2 Alignment
- Constitutional ai: Harmlessness from ai feedback. Bai, Yuntao, Kadavath, Saurav, Kundu, Sandipan, Askell, Amanda, Kernion, Jackson, Jones, Andy, Chen, Anna, Goldie, Anna, Mirhoseini, Azalia, McKinnon, Cameron, and others. ArXiv preprint (2022) [Paper]
- Rlaif: Scaling reinforcement learning from human feedback with ai feedback. Lee, Harrison, Phatale, Samrat, Mansoor, Hassan, Mesnard, Thomas, Ferret, Johan, Lu, Kellie, Bishop, Colton, Hall, Ethan, Carbune, Victor, Rastogi, Abhinav, and others. ArXiv preprint (2023) [Paper]
- SALMON: Self-Alignment with Instructable Reward Models. Sun, Zhiqing, Shen, Yikang, Zhang, Hongxin, Zhou, Qinhong, Chen, Zhenfang, Cox, David Daniel, Yang, Yiming, and Gan, Chuang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Direct language model alignment from online ai feedback. Guo, Shangmin, Zhang, Biao, Liu, Tianlin, Liu, Tianqi, Khalman, Misha, Llinares, Felipe, Rame, Alexandre, Mesnard, Thomas, Zhao, Yao, Piot, Bilal, and others. ArXiv preprint (2024) [Paper]
- The Fellowship of the LLMs: Multi-Agent Workflows for Synthetic Preference Optimization Dataset Generation. Arif, Samee, Farid, Sualeha, Azeemi, Abdul Hameed, Athar, Awais, and Raza, Agha Ali. ArXiv preprint (2024) [Paper]
- CoEvol: Constructing Better Responses for Instruction Finetuning through Multi-Agent Cooperation. Li, Renhao, Tan, Minghuan, Wong, Derek F, and Yang, Min. ArXiv preprint (2024) [Paper]
- Self-rewarding language models. Yuan, Weizhe, Pang, Richard Yuanzhe, Cho, Kyunghyun, Sukhbaatar, Sainbayar, Xu, Jing, and Weston, Jason. ArXiv preprint (2024) [Paper]
- Meta-rewarding language models: Self-improving alignment with llm-as-a-meta-judge. Wu, Tianhao, Yuan, Weizhe, Golovneva, Olga, Xu, Jing, Tian, Yuandong, Jiao, Jiantao, Weston, Jason, and Sukhbaatar, Sainbayar. ArXiv preprint (2024) [Paper]
- West-of-n: Synthetic preference generation for improved reward modeling. Pace, Aliz{'e}e, Mallinson, Jonathan, Malmi, Eric, Krause, Sebastian, and Severyn, Aliaksei. ArXiv preprint (2024) [Paper]
- Aligning Large Language Models by On-Policy Self-Judgment. Lee, Sangkyu, Kim, Sungdong, Yousefpour, Ashkan, Seo, Minjoon, Yoo, Kang Min, and Yu, Youngjae. ArXiv preprint (2024) [Paper]
- Optimizing Language Model's Reasoning Abilities with Weak Supervision. Tong, Yongqi, Wang, Sizhe, Li, Dawei, Wang, Yifan, Han, Simeng, Lin, Zi, Huang, Chengsong, Huang, Jiaxin, and Shang, Jingbo. ArXiv preprint (2024) [Paper]
- Online Self-Preferring Language Models. Zhai, Yuanzhao, Zhang, Zhuo, Xu, Kele, Peng, Hanyang, Yu, Yue, Feng, Dawei, Yang, Cheng, Ding, Bo, and Wang, Huaimin. ArXiv preprint (2024) [Paper]
- Meta Ranking: Less Capable Language Models are Capable for Single Response Judgement. Liu, Zijun, Kou, Boqun, Li, Peng, Yan, Ming, Zhang, Ji, Huang, Fei, and Liu, Yang. ArXiv preprint (2024) [Paper]
- I-SHEEP: Self-Alignment of LLM from Scratch through an Iterative Self-Enhancement Paradigm. Liang, Yiming, Zhang, Ge, Qu, Xingwei, Zheng, Tianyu, Guo, Jiawei, Du, Xinrun, Yang, Zhenzhu, Liu, Jiaheng, Lin, Chenghua, Ma, Lei, and others. ArXiv preprint (2024) [Paper]
- Self-alignment for factuality: Mitigating hallucinations in llms via self-evaluation. Zhang, Xiaoying, Peng, Baolin, Tian, Ye, Zhou, Jingyan, Jin, Lifeng, Song, Linfeng, Mi, Haitao, and Meng, Helen. ArXiv preprint (2024) [Paper]
- Learning Reward for Robot Skills Using Large Language Models via Self-Alignment. Zeng, Yuwei, Mu, Yao, and Shao, Lin. ArXiv preprint (2024) [Paper]
- i-SRT: Aligning Large Multimodal Models for Videos by Iterative Self-Retrospective Judgment. Ahn, Daechul, Choi, Yura, Kim, San, Yu, Youngjae, Kang, Dongyeop, and Choi, Jonghyun. ArXiv preprint (2024) [Paper]
- CodeUltraFeedback: An LLM-as-a-Judge Dataset for Aligning Large Language Models to Coding Preferences. Weyssow, Martin, Kamanda, Aton, and Sahraoui, Houari. arXiv preprint arXiv:2403.09032 (2024) [Paper]
3.3 Retrieval
- Is ChatGPT Good at Search? Investigating Large Language Models as Re-Ranking Agents. Sun, Weiwei , Yan, Lingyong , Ma, Xinyu , Wang, Shuaiqiang , Ren, Pengjie , Chen, Zhumin , Yin, Dawei , and Ren, Zhaochun. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Large language models can accurately predict searcher preferences, 2023. Thomas, Paul, Spielman, Seth, Craswell, Nick, and Mitra, Bhaskar. ArXiv preprint (2023) [Paper]
- Zero-shot listwise document reranking with a large language model. Ma, Xueguang, Zhang, Xinyu, Pradeep, Ronak, and Lin, Jimmy. ArXiv preprint (2023) [Paper]
- Found in the Middle: Permutation Self-Consistency Improves Listwise Ranking in Large Language Models. Tang, Raphael , Zhang, Crystina , Ma, Xueguang , Lin, Jimmy , and Ture, Ferhan. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (2024) [Paper]
- Large Language Models are Effective Text Rankers with Pairwise Ranking Prompting. Qin, Zhen , Jagerman, Rolf , Hui, Kai , Zhuang, Honglei , Wu, Junru , Yan, Le , Shen, Jiaming , Liu, Tianqi , Liu, Jialu , Metzler, Donald , Wang, Xuanhui , and Bendersky, Michael. Findings of the Association for Computational Linguistics: NAACL 2024 (2024) [Paper]
- Leveraging Large Language Models for Relevance Judgments in Legal Case Retrieval. Ma, Shengjie, Chen, Chong, Chu, Qi, and Mao, Jiaxin. ArXiv preprint (2024) [Paper]
- Large Language Models are Zero-Shot Rankers for Recommender Systems. Hou, Yupeng, Zhang, Junjie, Lin, Zihan, Lu, Hongyu, Xie, Ruobing, McAuley, Julian, and Zhao, Wayne Xin. European Conference on Information Retrieval (2024) [Paper]
- MoT: Memory-of-Thought Enables {C}hat{GPT} to Self-Improve. Li, Xiaonan , and Qiu, Xipeng. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Self-Retrieval: Building an Information Retrieval System with One Large Language Model. Tang, Qiaoyu, Chen, Jiawei, Yu, Bowen, Lu, Yaojie, Fu, Cheng, Yu, Haiyang, Lin, Hongyu, Huang, Fei, He, Ben, Han, Xianpei, and others. ArXiv preprint (2024) [Paper]
- Self-{RAG}: Learning to Retrieve, Generate, and Critique through Self-Reflection. Akari Asai, Zeqiu Wu, Yizhong Wang, Avirup Sil, and Hannaneh Hajishirzi. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Beyond Yes and No: Improving Zero-Shot {LLM} Rankers via Scoring Fine-Grained Relevance Labels. Zhuang, Honglei , Qin, Zhen , Hui, Kai , Wu, Junru , Yan, Le , Wang, Xuanhui , and Bendersky, Michael. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 2: Short Papers) (2024) [Paper]
- Evaluating rag-fusion with ragelo: an automated elo-based framework. Rackauckas, Zackary, C{^a}mara, Arthur, and Zavrel, Jakub. ArXiv preprint (2024) [Paper]
- Are Large Language Models Good at Utility Judgments?. Zhang, Hengran, Zhang, Ruqing, Guo, Jiafeng, de Rijke, Maarten, Fan, Yixing, and Cheng, Xueqi. Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval (2024) [Paper]
- BioRAG: A RAG-LLM Framework for Biological Question Reasoning. Wang, Chengrui, Long, Qingqing, Meng, Xiao, Cai, Xunxin, Wu, Chengjun, Meng, Zhen, Wang, Xuezhi, and Zhou, Yuanchun. ArXiv preprint (2024) [Paper]
- DALK: Dynamic Co-Augmentation of LLMs and KG to answer Alzheimer's Disease Questions with Scientific Literature. Li, Dawei, Yang, Shu, Tan, Zhen, Baik, Jae Young, Yun, Sunkwon, Lee, Joseph, Chacko, Aaron, Hou, Bojian, Duong-Tran, Duy, Ding, Ying, and others. ArXiv preprint (2024) [Paper]
- Improving medical reasoning through retrieval and self-reflection with retrieval-augmented large language models. Jeong, Minbyul, Sohn, Jiwoong, Sung, Mujeen, and Kang, Jaewoo. Bioinformatics (2024) [Paper]
- A setwise approach for effective and highly efficient zero-shot ranking with large language models. Zhuang, Shengyao, Zhuang, Honglei, Koopman, Bevan, and Zuccon, Guido. Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval (2024) [Paper]
- LLMs are Biased Evaluators But Not Biased for Retrieval Augmented Generation. Chen, Yen-Shan, Jin, Jing, Kuo, Peng-Ting, Huang, Chao-Wei, and Chen, Yun-Nung. ArXiv preprint (2024) [Paper]
3.4 Reasoning
- ReAct: Synergizing Reasoning and Acting in Language Models. Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik R. Narasimhan, and Yuan Cao. The Eleventh International Conference on Learning Representations, {ICLR} 2023, Kigali, Rwanda, May 1-5, 2023 (2023) [Paper]
- Selection-Inference: Exploiting Large Language Models for Interpretable Logical Reasoning. Antonia Creswell, Murray Shanahan, and Irina Higgins. The Eleventh International Conference on Learning Representations, {ICLR} 2023, Kigali, Rwanda, May 1-5, 2023 (2023) [Paper]
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. Jason Wei, Xuezhi Wang, Dale Schuurmans, Maarten Bosma, Brian Ichter, Fei Xia, Ed H. Chi, Quoc V. Le, and Denny Zhou. Advances in Neural Information Processing Systems 35: Annual Conference on Neural Information Processing Systems 2022, NeurIPS 2022, New Orleans, LA, USA, November 28 - December 9, 2022 (2022) [Paper]
- Tree of Thoughts: Deliberate Problem Solving with Large Language Models. Shunyu Yao, Dian Yu, Jeffrey Zhao, Izhak Shafran, Tom Griffiths, Yuan Cao, and Karthik Narasimhan. Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023 (2023) [Paper]
- Auto-gpt for online decision making: Benchmarks and additional opinions. Yang, Hui, Yue, Sifu, and He, Yunzhong. ArXiv preprint (2023) [Paper]
- Languagempc: Large language models as decision makers for autonomous driving. Sha, Hao, Mu, Yao, Jiang, Yuxuan, Chen, Li, Xu, Chenfeng, Luo, Ping, Li, Shengbo Eben, Tomizuka, Masayoshi, Zhan, Wei, and Ding, Mingyu. ArXiv preprint (2023) [Paper]
- Reasoning with Language Model is Planning with World Model. Hao, Shibo , Gu, Yi , Ma, Haodi , Hong, Joshua , Wang, Zhen , Wang, Daisy , and Hu, Zhiting. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Self-discover: Large language models self-compose reasoning structures. Zhou, Pei, Pujara, Jay, Ren, Xiang, Chen, Xinyun, Cheng, Heng-Tze, Le, Quoc V, Chi, Ed H, Zhou, Denny, Mishra, Swaroop, and Zheng, Huaixiu Steven. ArXiv preprint (2024) [Paper]
- Improving Diversity of Demographic Representation in Large Language Models via Collective-Critiques and Self-Voting. Lahoti, Preethi , Blumm, Nicholas , Ma, Xiao , Kotikalapudi, Raghavendra , Potluri, Sahitya , Tan, Qijun , Srinivasan, Hansa , Packer, Ben , Beirami, Ahmad , Beutel, Alex , and Chen, Jilin. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (2023) [Paper]
- Encouraging divergent thinking in large language models through multi-agent debate. Liang, Tian, He, Zhiwei, Jiao, Wenxiang, Wang, Xing, Wang, Yan, Wang, Rui, Yang, Yujiu, Tu, Zhaopeng, and Shi, Shuming. ArXiv preprint (2023) [Paper]
- SMoA: Improving Multi-agent Large Language Models with Sparse Mixture-of-Agents. Li, Dawei, Tan, Zhen, Qian, Peijia, Li, Yifan, Chaudhary, Kumar Satvik, Hu, Lijie, and Shen, Jiayi. ArXiv preprint (2024) [Paper]
- Graph of Thoughts: Solving Elaborate Problems with Large Language Models. Maciej Besta, Nils Blach, Ales Kubicek, Robert Gerstenberger, Michal Podstawski, Lukas Gianinazzi, Joanna Gajda, Tomasz Lehmann, Hubert Niewiadomski, Piotr Nyczyk, and Torsten Hoefler. Thirty-Eighth {AAAI} Conference on Artificial Intelligence, {AAAI} 2024, Thirty-Sixth Conference on Innovative Applications of Artificial Intelligence, {IAAI} 2024, Fourteenth Symposium on Educational Advances in Artificial Intelligence, {EAAI} 2014, February 20-27, 2024, Vancouver, Canada (2024) [Paper]
- Routellm: Learning to route llms with preference data. Ong, Isaac, Almahairi, Amjad, Wu, Vincent, Chiang, Wei-Lin, Wu, Tianhao, Gonzalez, Joseph E, Kadous, M Waleed, and Stoica, Ion. ArXiv preprint (2024) [Paper]
- DiffAgent: Fast and Accurate Text-to-Image API Selection with Large Language Model. Zhao, Lirui, Yang, Yue, Zhang, Kaipeng, Shao, Wenqi, Zhang, Yuxin, Qiao, Yu, Luo, Ping, and Ji, Rongrong. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (2024) [Paper]
- Rationale-Aware Answer Verification by Pairwise Self-Evaluation. Kawabata, Akira, and Sugawara, Saku. Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing (2024) [Paper]
- Improving Model Factuality with Fine-grained Critique-based Evaluator. Xie, Yiqing, Zhou, Wenxuan, Prakash, Pradyot, Jin, Di, Mao, Yuning, Fettes, Quintin, Talebzadeh, Arya, Wang, Sinong, Fang, Han, Rose, Carolyn, and others. arXiv preprint arXiv:2410.18359 (2024) [Paper]
- Let's verify step by step. Lightman, Hunter, Kosaraju, Vineet, Burda, Yura, Edwards, Harri, Baker, Bowen, Lee, Teddy, Leike, Jan, Schulman, John, Sutskever, Ilya, and Cobbe, Karl. arXiv preprint arXiv:2305.20050 (2023) [Paper]
- RAIN: Your Language Models Can Align Themselves without Finetuning. Li, Yuhui, Wei, Fangyun, Zhao, Jinjing, Zhang, Chao, and Zhang, Hongyang. The Twelfth International Conference on Learning Representations (2024) [Paper]
- Rewarding Progress: Scaling Automated Process Verifiers for LLM Reasoning. Setlur, Amrith, Nagpal, Chirag, Fisch, Adam, Geng, Xinyang, Eisenstein, Jacob, Agarwal, Rishabh, Agarwal, Alekh, Berant, Jonathan, and Kumar, Aviral. arXiv preprint arXiv:2410.08146 (2024) [Paper]