
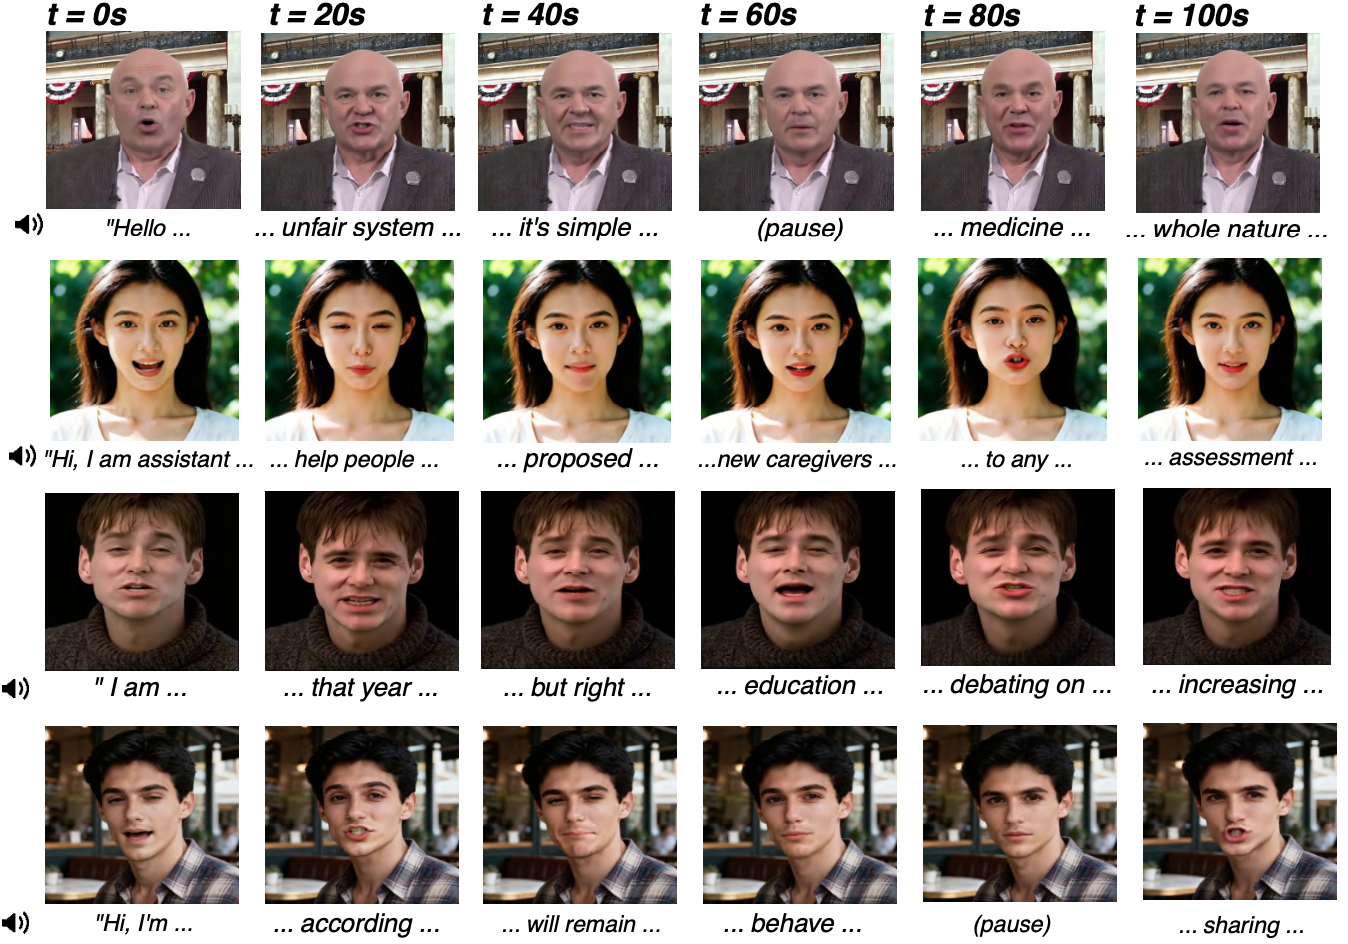
LiveTalk enables real-time multimodal interactive avatar video generation through an improved on-policy distillation approach. By distilling bidirectional diffusion models into causal, few-step autoregressive models, LiveTalk achieves over 20× speedup, enabling seamless real-time interactive experience.
We tested this repo on the following setup:
Clone the LiveTalk respository:
git clone https://github.com/GAIR-NLP/livetalk.git
cd livetalk
Clone the OmniAvatar repository from within the current LiveTalk repository:
git clone https://github.com/Omni-Avatar/OmniAvatar
Apply patches on OmniAvatar:
bash scripts/add_patch.sh
Create a conda environment and install dependencies:
conda create -n livetalk python=3.10 -y
conda activate livetalk
pip install -r requirements.txt
conda install -c conda-forge ffmpeg
pip install https://github.com/Dao-AILab/flash-attention/releases/download/v2.8.3/flash_attn-2.8.3+cu12torch2.8cxx11abiFALSE-cp310-cp310-linux_x86_64.whl
python setup.py develop
Download the required model checkpoints:
# Download Wan2.1 base model
huggingface-cli download Wan-AI/Wan2.1-T2V-1.3B --local-dir-use-symlinks False --local-dir pretrained_checkpoints/Wan2.1-T2V-1.3B

# Download LiveTalk model checkpoint
huggingface-cli download GAIR/LiveTalk-1.3B-V0.1 --local-dir-use-symlinks False --local-dir pretrained_checkpoints/LiveTalk-1.3B-V0.1

# Download Wav2Vec2 model for audio processing
huggingface-cli download facebook/wav2vec2-base-960h --local-dir-use-symlinks False --local-dir pretrained_checkpoints/wav2vec2
The file structure will be:
.livetalk
|-- ...
|-- OmniAvatar
|-- pretrained_checkpoints
|   |-- LiveTalk-1.3B-V0.1
|   |-- Wan2.1-T2V-1.3B
|   |-- wav2vec2
We currently offer a simple script for running video inference, but it does not support streaming input and output. The inference requires approximately 20GB of GPU memory usage.
Execute the inference script with your configuration:
bash ./scripts/inference.sh
Input Requirements:
Output:
video_duration parameterOur approach addresses challenges in distilling multimodal video diffusion models:
Challenge: Self Forcing encounters visual artifacts (flickering, black frames, quality degradation) with multimodal conditioning.
Our Solution:
These improvements eliminate training instability and deliver high-quality results across perceptual metrics, audio-visual synchronization, and aesthetic quality.
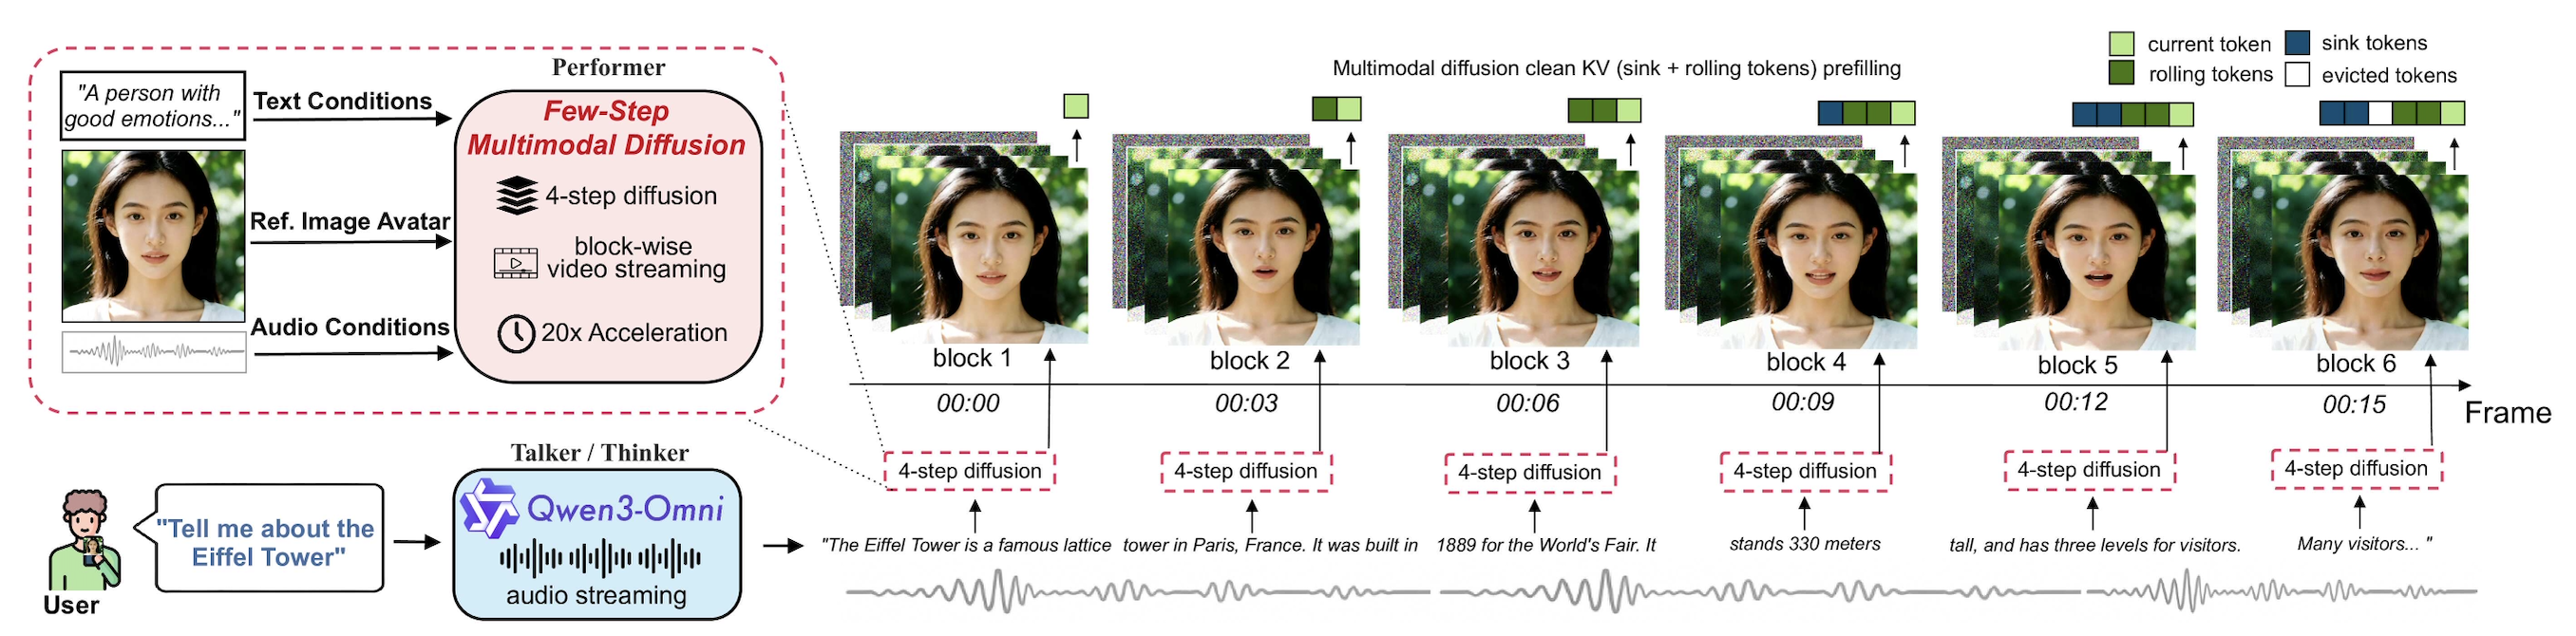
Built on the distilled few-step multimodal diffusion model, our system turns the recipe into an end-to-end, real-time talking avatar pipeline:
Together with the improved on-policy distillation recipe, this system delivers high-fidelity, lip-synced avatar videos with sub-second first-frame latency, supporting natural multi-turn multimodal interaction.
This codebase builds upon:
This project is released under the Apache 2.0 license.
If you find this codebase useful for your research, please cite our paper:
@article{chern2025livetalk,
  title={LiveTalk: Real-Time Multimodal Interactive Video Diffusion via Improved On-Policy Distillation},
  author={Chern, Ethan and Hu, Zhulin and Tang, Bohao and Su, Jiadi and Chern, Steffi and Deng, Zhijie and Liu, Pengfei},
  journal={arXiv preprint arXiv:2512.23576},
  year={2025}
}
830 followers · starred Jan 2026
278 followers · starred Dec 2025
2,064 followers · starred Dec 2025
65 followers · starred Jan 2026
LiveTalk enables real-time multimodal interactive avatar video generation through an improved on-policy distillation approach. By distilling bidirectional diffusion models into causal, few-step autoregressive models, LiveTalk achieves over 20× speedup, enabling seamless real-time interactive experience.
We tested this repo on the following setup:
Clone the LiveTalk respository:
git clone https://github.com/GAIR-NLP/livetalk.git
cd livetalk
Clone the OmniAvatar repository from within the current LiveTalk repository:
git clone https://github.com/Omni-Avatar/OmniAvatar
Apply patches on OmniAvatar:
bash scripts/add_patch.sh
Create a conda environment and install dependencies:
conda create -n livetalk python=3.10 -y
conda activate livetalk
pip install -r requirements.txt
conda install -c conda-forge ffmpeg
pip install https://github.com/Dao-AILab/flash-attention/releases/download/v2.8.3/flash_attn-2.8.3+cu12torch2.8cxx11abiFALSE-cp310-cp310-linux_x86_64.whl
python setup.py develop
Download the required model checkpoints:
# Download Wan2.1 base model
huggingface-cli download Wan-AI/Wan2.1-T2V-1.3B --local-dir-use-symlinks False --local-dir pretrained_checkpoints/Wan2.1-T2V-1.3B

# Download LiveTalk model checkpoint
huggingface-cli download GAIR/LiveTalk-1.3B-V0.1 --local-dir-use-symlinks False --local-dir pretrained_checkpoints/LiveTalk-1.3B-V0.1

# Download Wav2Vec2 model for audio processing
huggingface-cli download facebook/wav2vec2-base-960h --local-dir-use-symlinks False --local-dir pretrained_checkpoints/wav2vec2
The file structure will be:
.livetalk
|-- ...
|-- OmniAvatar
|-- pretrained_checkpoints
|   |-- LiveTalk-1.3B-V0.1
|   |-- Wan2.1-T2V-1.3B
|   |-- wav2vec2
We currently offer a simple script for running video inference, but it does not support streaming input and output. The inference requires approximately 20GB of GPU memory usage.
Execute the inference script with your configuration:
bash ./scripts/inference.sh
Input Requirements:
Output:
video_duration parameterOur approach addresses challenges in distilling multimodal video diffusion models:
Challenge: Self Forcing encounters visual artifacts (flickering, black frames, quality degradation) with multimodal conditioning.
Our Solution:
These improvements eliminate training instability and deliver high-quality results across perceptual metrics, audio-visual synchronization, and aesthetic quality.
Built on the distilled few-step multimodal diffusion model, our system turns the recipe into an end-to-end, real-time talking avatar pipeline:
Together with the improved on-policy distillation recipe, this system delivers high-fidelity, lip-synced avatar videos with sub-second first-frame latency, supporting natural multi-turn multimodal interaction.
This codebase builds upon:
This project is released under the Apache 2.0 license.
If you find this codebase useful for your research, please cite our paper:
@article{chern2025livetalk,
  title={LiveTalk: Real-Time Multimodal Interactive Video Diffusion via Improved On-Policy Distillation},
  author={Chern, Ethan and Hu, Zhulin and Tang, Bohao and Su, Jiadi and Chern, Steffi and Deng, Zhijie and Liu, Pengfei},
  journal={arXiv preprint arXiv:2512.23576},
  year={2025}
}
830 followers · starred Jan 2026
278 followers · starred Dec 2025
2,064 followers · starred Dec 2025
65 followers · starred Jan 2026