[ECCV 2026 Spotlight] Implementation of "Live Avatar: Streaming Real-time Audio-Driven Avatar Generation with Infinite Length"
Python
2,476
33 commits
updated Aug 24, 2026
Yubo Huang1,2 · Hailong Guo2,3 · Fangtai Wu2,4 · Weiqiang Wang5 · Shifeng Zhang2 · Shijie Huang2 · Qijun Gan4 · Lin Liu1 · Ruihua Huang2,* · Sirui Zhao1,* · Enhong Chen1,* · Jiaming Liu2,*,‡ · Steven Hoi2
1 University of Science and Technology of China 2 Alibaba Group 3 Beijing University of Posts and Telecommunications 4 Zhejiang University 5 Monash University
* Corresponding authors. ‡ Project leader.


TL;DR: Live Avatar is an algorithm–system co-designed framework that enables real-time, streaming, infinite-length interactive avatar video generation. Powered by a 14B-parameter diffusion model, it achieves 45 FPS on multi-card H800 GPUs with 4-step sampling and supports Block-wise Autoregressive processing for 10,000+ second streaming videos.
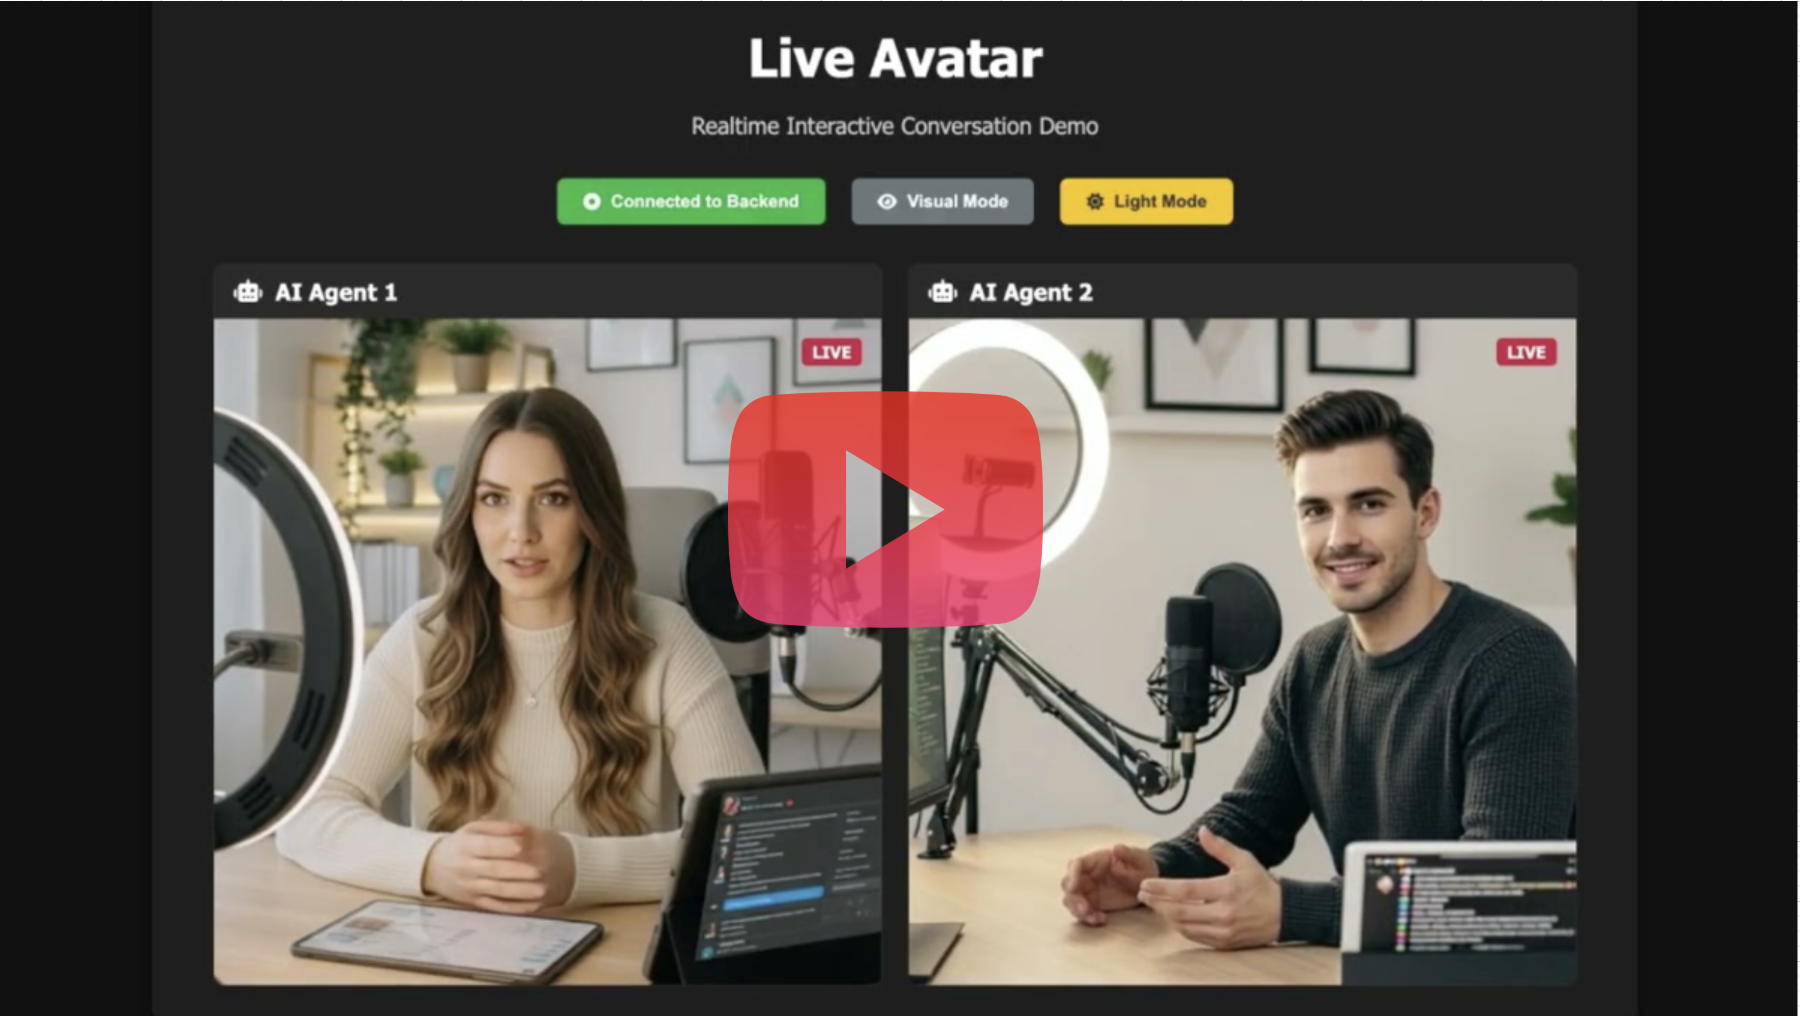
👀 More Demos:
🤖 Human-AI Conversation | ♾️ Infinite Video | 🎭 Diverse Characters | 🎬 Animated Tech Explanation
👉 Click Here to Visit Project Page! 🌐
- ⚡ Real-time Streaming Interaction - Achieve 45 FPS real-time streaming with low latency
- ♾️ Infinite-length Autoregressive Generation - Support 10,000+ second continuous video generation
- 🎨 Generalization Performances - Strong generalization across cartoon characters, singing, and diverse scenarios
Please follow the steps below to set up the environment.
conda create -n liveavatar python=3.10 -y
conda activate liveavatar
conda install nvidia/label/cuda-12.4.1::cuda -y
conda install -c nvidia/label/cuda-12.4.1 cudatoolkit -y
pip install torch==2.8.0 torchvision==0.23.0 --index-url https://download.pytorch.org/whl/cu128

# If you are using NVIDIA Hopper architecture (H800/H200, etc.), FlashAttention 3 is recommended for a significant speedup:
pip install flash_attn_3 --find-links https://windreamer.github.io/flash-attention3-wheels/cu128_torch280 --extra-index-url https://download.pytorch.org/whl/cu128

# Otherwise, use FlashAttention 2:
pip install flash-attn==2.8.3 --no-build-isolation
pip install -r requirements.txt
apt-get update && apt-get install -y ffmpeg
Please download the pretrained checkpoints from links below and place them in the ./ckpt/ directory.
| Model Component | Description | Link |
|---|---|---|
WanS2V-14B | base model | 🤗 Huggingface |
liveAvatar | our lora model | 🤗 Huggingface |
# If you are in china mainland, run this first: export HF_ENDPOINT=https://hf-mirror.com
pip install "huggingface_hub[cli]"
huggingface-cli download Wan-AI/Wan2.2-S2V-14B --local-dir ./ckpt/Wan2.2-S2V-14B
huggingface-cli download Quark-Vision/Live-Avatar --local-dir ./ckpt/LiveAvatar
After downloading, your directory structure should look like this:
ckpt/
├── Wan2.2-S2V-14B/          # Base model
│   ├── config.json
│   ├── diffusion_pytorch_model-*.safetensors
│   └── ...
└── LiveAvatar/              # Our LoRA model
    ├── liveavatar.safetensors
    └── ...
💡 Currently, This command can run on GPUs with at least 80GB VRAM.
# CLI Inference
bash infinite_inference_multi_gpu.sh
# Gradio Web UI
bash gradio_multi_gpu.sh
💡 The model can generate videos from audio input combined with reference image and optional text prompt.
💡 The
sizeparameter represents the area of the generated video, with the aspect ratio following that of the original input image.
💡 The
--num_clipparameter controls the number of video clips generated, useful for quick preview with shorter generation time.
💡 Currently, our TPP pipeline requires five GPUs for inference. We are planning to develop a 3-step version that can be deployed on a 4-GPU cluster. Furthermore, we are planning to integrate the LightX2V VAE component. This integration will eliminate the dependency on additional single-GPU VAE parallelism and support 4-step inference within a 4-GPU setup.
💡 Compilation (
ENABLE_COMPILE): Enabling compilation will cause a long wait time during the first inference as the model compiles, but subsequent runs will see significant performance improvements. This is highly valuable for streaming long video scenarios. However, if you just want to quickly run a few test cases, we recommend disabling it by settingexport ENABLE_COMPILE=falsein your inference script.
💡 FP8 Quantization (
ENABLE_FP8): FP8 offers notable VRAM savings, enabling inference on 48GB GPUs, and also provides modest performance gains. Note that this may cause slight quality degradation. You can enable it by settingexport ENABLE_FP8=truein your inference script.
Please visit our project page to see more examples and learn about the scenarios suitable for this model.
💡 This command can run on a single GPU with at least 80GB VRAM.
# CLI Inference
bash infinite_inference_single_gpu.sh
# Gradio Web UI
bash gradio_single_gpu.sh
💡 If you encounter OOM errors after multiple runs in the Gradio Web UI, please try lowering the resolution (the
sizeparameter) as a temporary fix. We are actively developing enhanced single GPU memory optimization; track our progress in the "Later updates" section.
💡 To avoid performance degradation caused by frequent CPU offloading, we set the
enable_online_decodeparameter tofalseby default in the single-GPU scripts. This may slightly reduce quality when generating extremely long videos; in such cases, consider adding--enable_online_decodeto your inference command.
If you find this project useful for your research, please consider citing our paper:
@misc{huang2025liveavatarstreamingrealtime,
      title={Live Avatar: Streaming Real-time Audio-Driven Avatar Generation with Infinite Length},
      author={Yubo Huang and Hailong Guo and Fangtai Wu and Shifeng Zhang and Shijie Huang and Qijun Gan and Lin Liu and Sirui Zhao and Enhong Chen and Jiaming Liu and Steven Hoi},
      year={2025},
      eprint={2512.04677},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2512.04677},
}
We would like to express our gratitude to the following projects:
316 followers · starred Dec 2025
958 followers · starred Apr 2026
160 followers · starred Apr 2026
193 followers · starred Dec 2025
[ECCV 2026 Spotlight] Implementation of "Live Avatar: Streaming Real-time Audio-Driven Avatar Generation with Infinite Length"
Python
2,476
33 commits
updated Aug 24, 2026
Yubo Huang1,2 · Hailong Guo2,3 · Fangtai Wu2,4 · Weiqiang Wang5 · Shifeng Zhang2 · Shijie Huang2 · Qijun Gan4 · Lin Liu1 · Ruihua Huang2,* · Sirui Zhao1,* · Enhong Chen1,* · Jiaming Liu2,*,‡ · Steven Hoi2
1 University of Science and Technology of China 2 Alibaba Group 3 Beijing University of Posts and Telecommunications 4 Zhejiang University 5 Monash University
* Corresponding authors. ‡ Project leader.
TL;DR: Live Avatar is an algorithm–system co-designed framework that enables real-time, streaming, infinite-length interactive avatar video generation. Powered by a 14B-parameter diffusion model, it achieves 45 FPS on multi-card H800 GPUs with 4-step sampling and supports Block-wise Autoregressive processing for 10,000+ second streaming videos.
👀 More Demos:
🤖 Human-AI Conversation | ♾️ Infinite Video | 🎭 Diverse Characters | 🎬 Animated Tech Explanation
👉 Click Here to Visit Project Page! 🌐
- ⚡ Real-time Streaming Interaction - Achieve 45 FPS real-time streaming with low latency
- ♾️ Infinite-length Autoregressive Generation - Support 10,000+ second continuous video generation
- 🎨 Generalization Performances - Strong generalization across cartoon characters, singing, and diverse scenarios
Please follow the steps below to set up the environment.
conda create -n liveavatar python=3.10 -y
conda activate liveavatar
conda install nvidia/label/cuda-12.4.1::cuda -y
conda install -c nvidia/label/cuda-12.4.1 cudatoolkit -y
pip install torch==2.8.0 torchvision==0.23.0 --index-url https://download.pytorch.org/whl/cu128

# If you are using NVIDIA Hopper architecture (H800/H200, etc.), FlashAttention 3 is recommended for a significant speedup:
pip install flash_attn_3 --find-links https://windreamer.github.io/flash-attention3-wheels/cu128_torch280 --extra-index-url https://download.pytorch.org/whl/cu128

# Otherwise, use FlashAttention 2:
pip install flash-attn==2.8.3 --no-build-isolation
pip install -r requirements.txt
apt-get update && apt-get install -y ffmpeg
Please download the pretrained checkpoints from links below and place them in the ./ckpt/ directory.
| Model Component | Description | Link |
|---|---|---|
WanS2V-14B | base model | 🤗 Huggingface |
liveAvatar | our lora model | 🤗 Huggingface |
# If you are in china mainland, run this first: export HF_ENDPOINT=https://hf-mirror.com
pip install "huggingface_hub[cli]"
huggingface-cli download Wan-AI/Wan2.2-S2V-14B --local-dir ./ckpt/Wan2.2-S2V-14B
huggingface-cli download Quark-Vision/Live-Avatar --local-dir ./ckpt/LiveAvatar
After downloading, your directory structure should look like this:
ckpt/
├── Wan2.2-S2V-14B/          # Base model
│   ├── config.json
│   ├── diffusion_pytorch_model-*.safetensors
│   └── ...
└── LiveAvatar/              # Our LoRA model
    ├── liveavatar.safetensors
    └── ...
💡 Currently, This command can run on GPUs with at least 80GB VRAM.
# CLI Inference
bash infinite_inference_multi_gpu.sh
# Gradio Web UI
bash gradio_multi_gpu.sh
💡 The model can generate videos from audio input combined with reference image and optional text prompt.
💡 The
sizeparameter represents the area of the generated video, with the aspect ratio following that of the original input image.
💡 The
--num_clipparameter controls the number of video clips generated, useful for quick preview with shorter generation time.
💡 Currently, our TPP pipeline requires five GPUs for inference. We are planning to develop a 3-step version that can be deployed on a 4-GPU cluster. Furthermore, we are planning to integrate the LightX2V VAE component. This integration will eliminate the dependency on additional single-GPU VAE parallelism and support 4-step inference within a 4-GPU setup.
💡 Compilation (
ENABLE_COMPILE): Enabling compilation will cause a long wait time during the first inference as the model compiles, but subsequent runs will see significant performance improvements. This is highly valuable for streaming long video scenarios. However, if you just want to quickly run a few test cases, we recommend disabling it by settingexport ENABLE_COMPILE=falsein your inference script.
💡 FP8 Quantization (
ENABLE_FP8): FP8 offers notable VRAM savings, enabling inference on 48GB GPUs, and also provides modest performance gains. Note that this may cause slight quality degradation. You can enable it by settingexport ENABLE_FP8=truein your inference script.
Please visit our project page to see more examples and learn about the scenarios suitable for this model.
💡 This command can run on a single GPU with at least 80GB VRAM.
# CLI Inference
bash infinite_inference_single_gpu.sh
# Gradio Web UI
bash gradio_single_gpu.sh
💡 If you encounter OOM errors after multiple runs in the Gradio Web UI, please try lowering the resolution (the
sizeparameter) as a temporary fix. We are actively developing enhanced single GPU memory optimization; track our progress in the "Later updates" section.
💡 To avoid performance degradation caused by frequent CPU offloading, we set the
enable_online_decodeparameter tofalseby default in the single-GPU scripts. This may slightly reduce quality when generating extremely long videos; in such cases, consider adding--enable_online_decodeto your inference command.
If you find this project useful for your research, please consider citing our paper:
@misc{huang2025liveavatarstreamingrealtime,
      title={Live Avatar: Streaming Real-time Audio-Driven Avatar Generation with Infinite Length},
      author={Yubo Huang and Hailong Guo and Fangtai Wu and Shifeng Zhang and Shijie Huang and Qijun Gan and Lin Liu and Sirui Zhao and Enhong Chen and Jiaming Liu and Steven Hoi},
      year={2025},
      eprint={2512.04677},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2512.04677},
}
We would like to express our gratitude to the following projects:
316 followers · starred Dec 2025
958 followers · starred Apr 2026
160 followers · starred Apr 2026
193 followers · starred Dec 2025