Awesome list and survey website for agents in the era of experience
See the code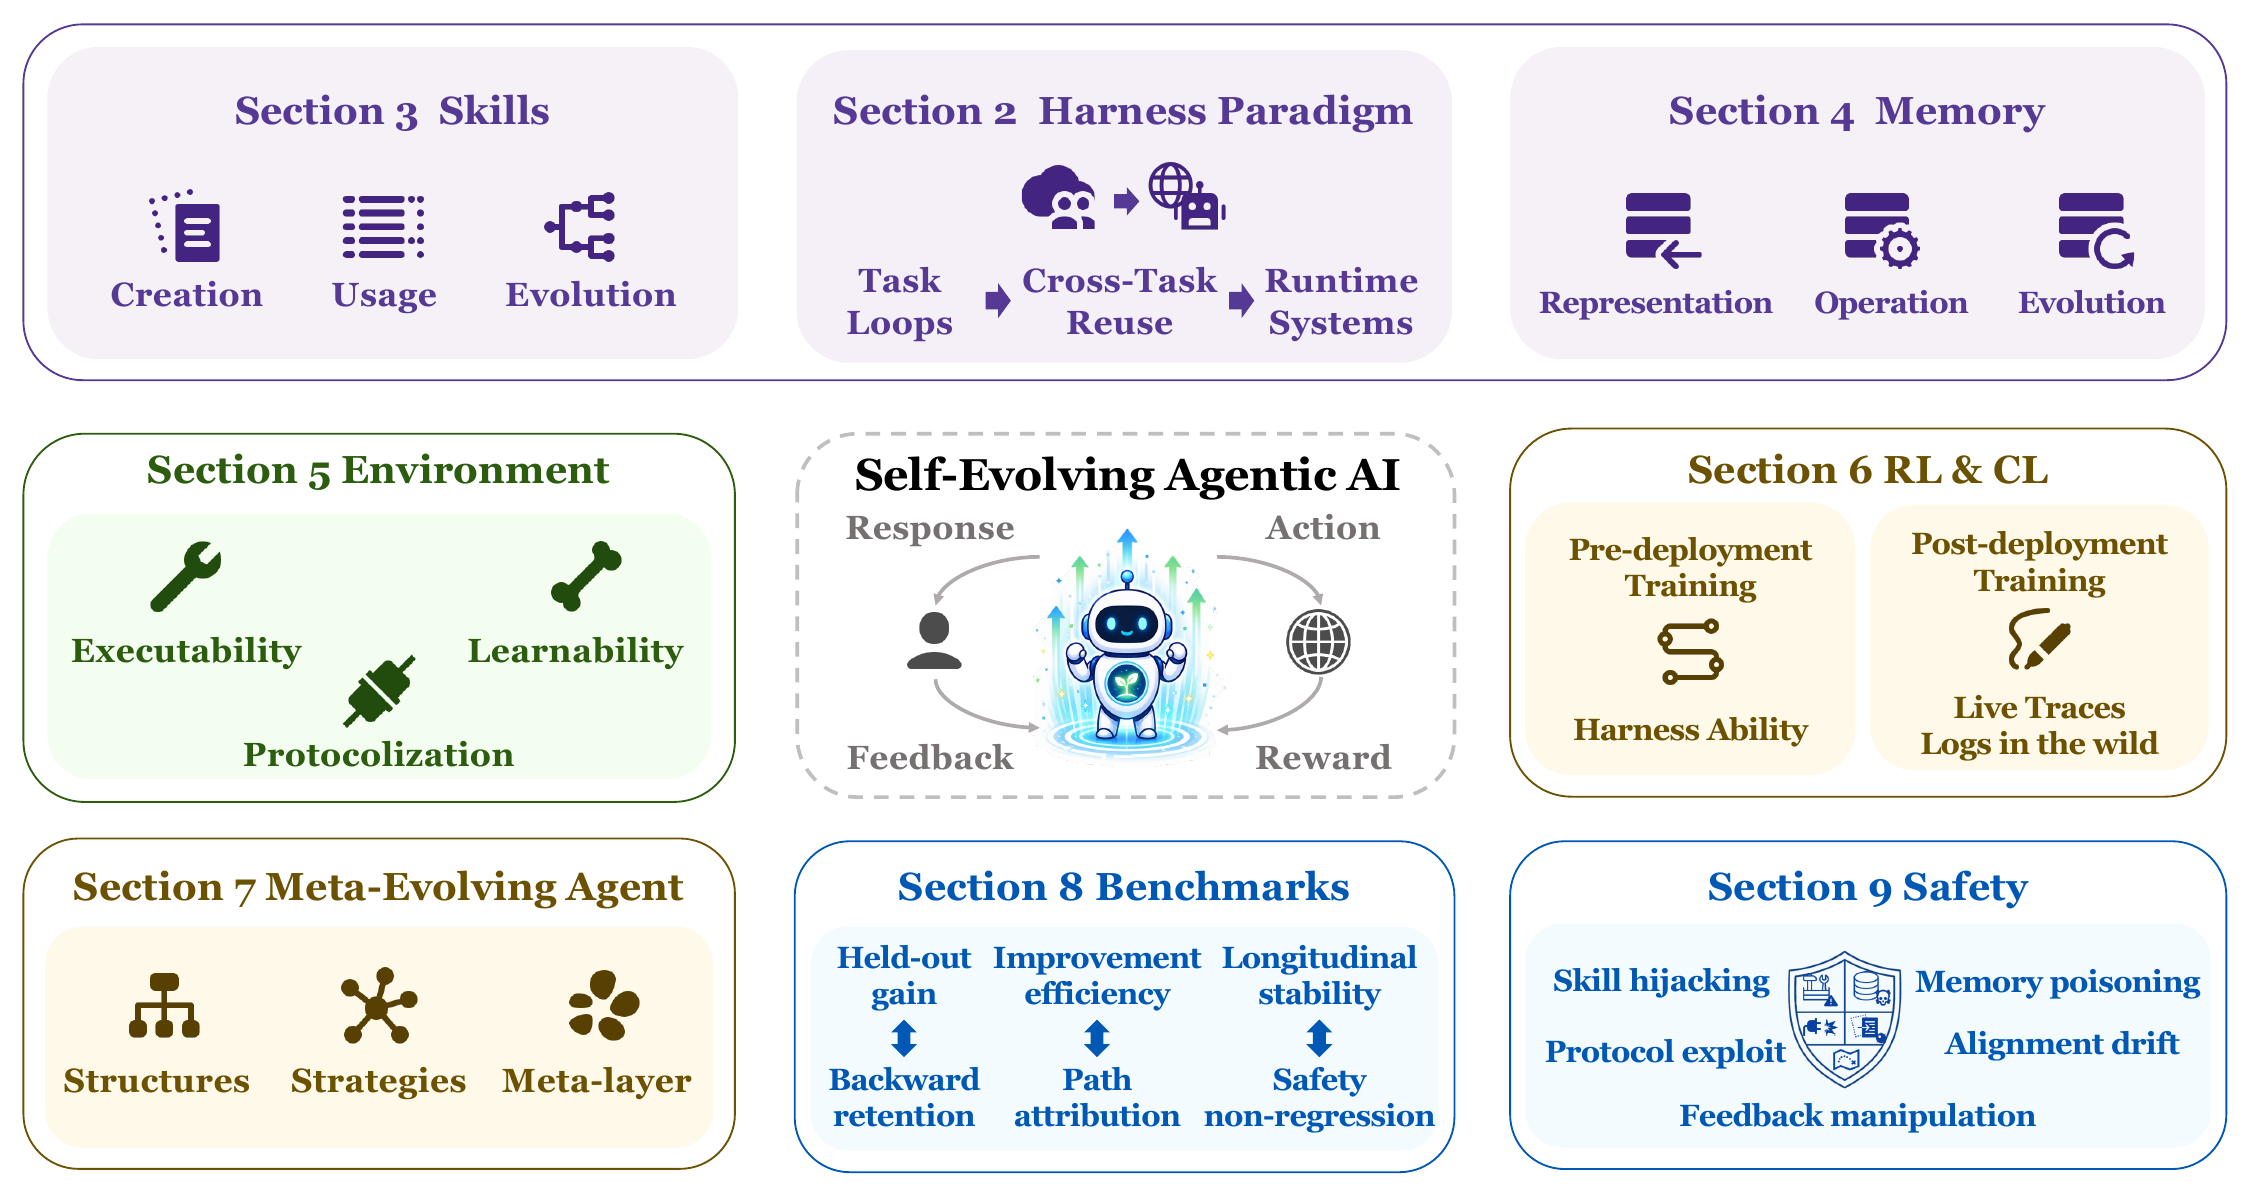
We welcome issues and pull requests for missing work on harness agents, agent skills, memory, self-improvement, agent RL, evaluation, and safety.
If you find this survey or paper list helpful, please cite our work:
@article{jiang2026selfimprovingagents,
  title={Self-Improving Agents in the Era of Experience: A Survey of Self- to Meta-Evolution},
  author={Che Jiang and Jincheng Zhong and Yu Fu and Kai Tian and Junlin Yang and Kaikai Zhao and Yuchong Wang and Tianwei Luo and Weizhi Wang and Yuxin Zuo and Guoli Jia and Xingtai Lv and Dianqiao Lei and Sihang Zeng and Yuru Wang and Zhenzhao Yuan and Xinwei Long and Ermo Hua and Can Ren and Xin Jiang and Shulei Xie and Yuanchun Zheng and Youbang Sun and Biqing Qi and Ning Ding and Kaiyan Zhang and Bowen Zhou},
  journal={OpenReview Archive},
  year={2026},
  url={https://openreview.net/pdf?id=IUltZSgLMm}
}
This repository collects papers, systems, benchmarks, and resources for studying how deployed agentic AI systems become more capable after deployment.
We organize the landscape around the harness agent: a deployed runtime system whose behavior is jointly shaped by a base model, a mutable harness, a user-facing interface, and an environment-facing interface. Under this view, self-improvement first appears as fast runtime adaptation over external surfaces such as skills, memory, context, tools, and execution environments. Repeated experience may later be consolidated into model parameters through reinforcement learning, fine-tuning, or continual learning.
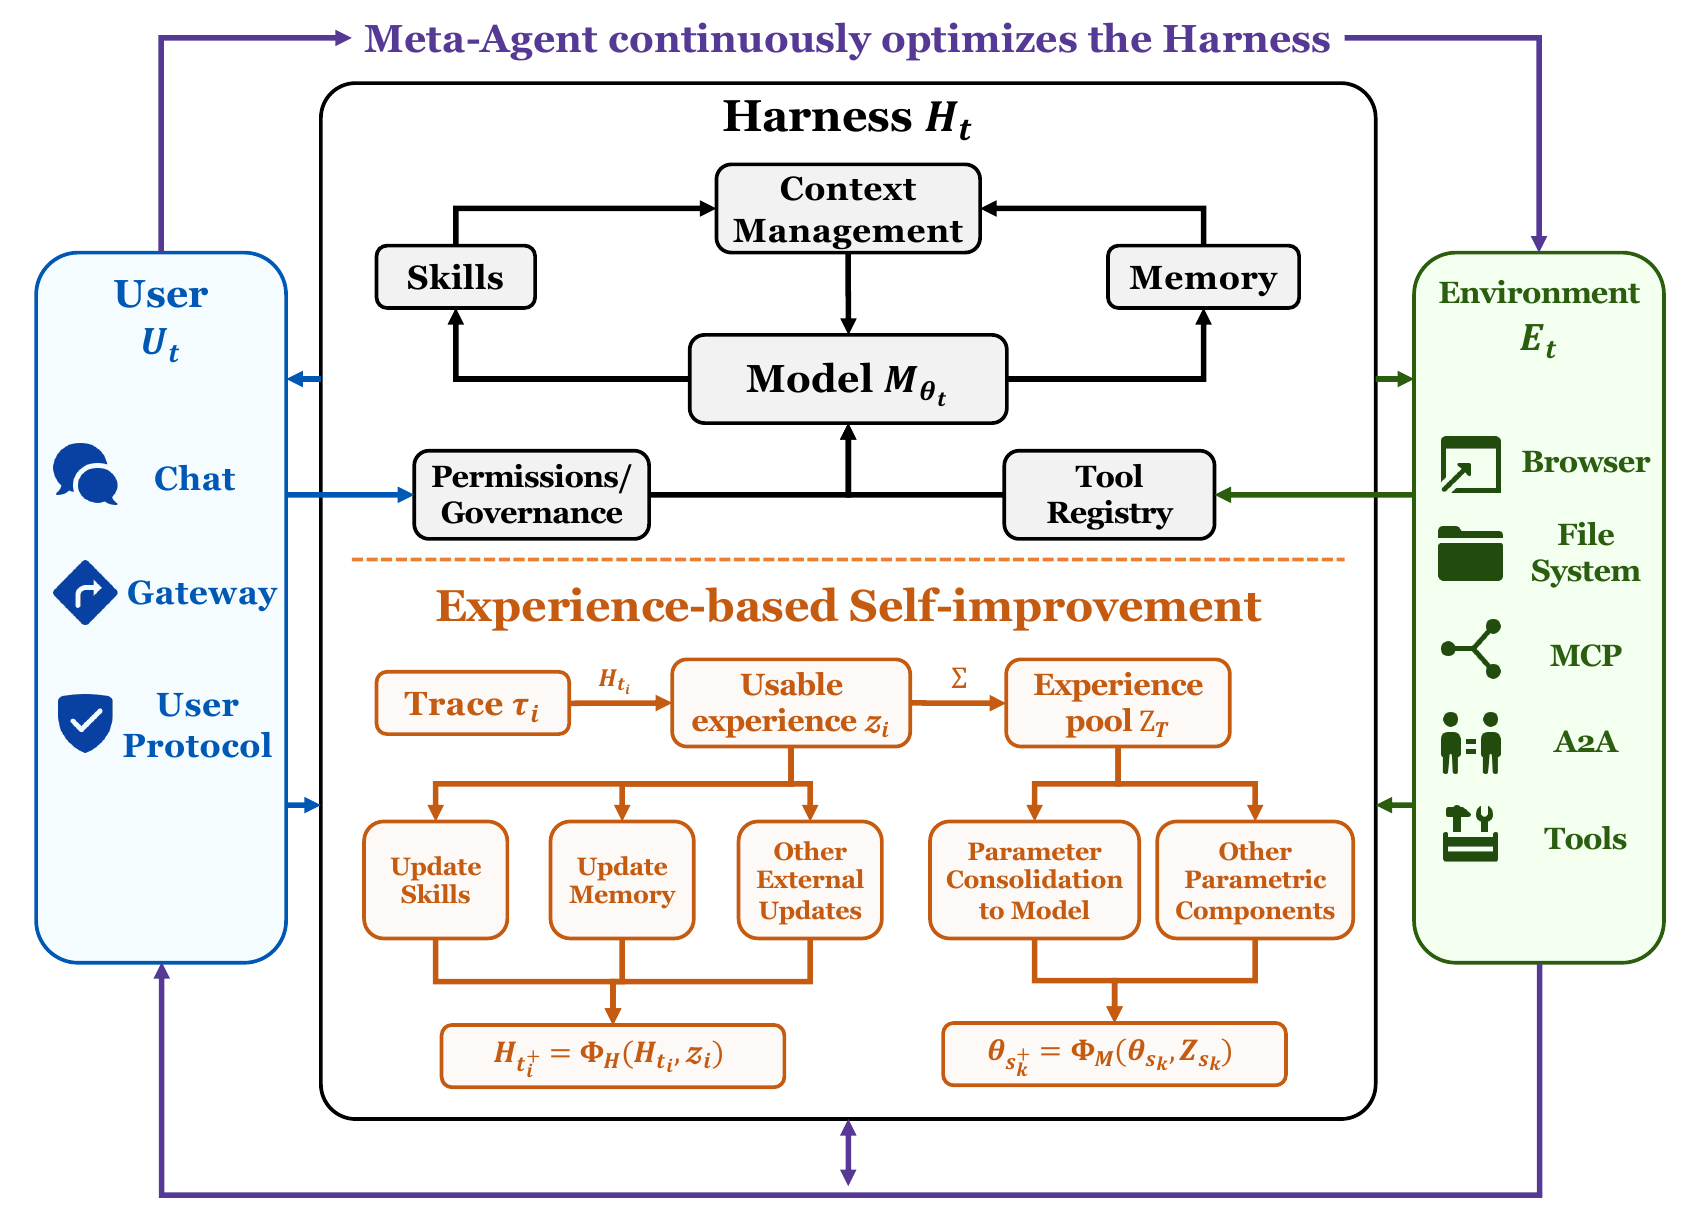
We organize the survey into four parts:
The catalog snapshot is 2026-09-11. This section shows up to 20 papers added in the past 7 days.
| Added | Paper | Survey chapter | Links |
|---|---|---|---|
| 2026-09-11 | Who Maintains Agent Skills? A Longitudinal Study of Human-Governed, AI-Assisted Skill Maintenance | Measuring Self-Improvement | Paper |
| 2026-09-11 | TROVE: Adaptive Agent Skill Orchestration via Trace-Grounded Route Validation and Editing | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement | Introduction | Paper |
| 2026-09-11 | SQL-Zero: Self-Evolving Text-to-SQL | RL and Continual Learning | Paper |
| 2026-09-11 | SkillAdam: Stable and Efficient Skill Evolution for Agents | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | SE-GoS: Self-Evolving Graph-of-Skills for Skill Library at Scale | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | RobustSGPO: Search-Space Control for Agent Harness Evolution | Harness as Experience Infrastructure | Paper |
| 2026-09-11 | Procedural Graphs: Self-Evolving Execution Structures for LLM Agents | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness | RL and Continual Learning | Paper |
| 2026-09-11 | MetaRSI / RSI2: A Meta-Recursive Self-Improving System for Recursive Self-Improving Systems Themselves | Meta-Evolving Agents | Paper |
| 2026-09-11 | Harness-agnostic detection and immunization of reward hacking in self-evolving language models | Safety: Self-Improvement as a Moving Attack Surface | Paper |
| 2026-09-11 | Graph-Based Personalized Memory for LLM Agents: Representation, Evolution, Retrieval, and Evaluation | Memory: Experience Becomes Persistent State | Paper |
| 2026-09-11 | From Interaction Traces to Persistent Skills: Online Evolution for Computer-Use Agents | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | Experience Funnel: A State-Policy Alternating Loop for Self-Evolving Agents | RL and Continual Learning | Paper |
| 2026-09-11 | Environments as Scaffold: Enriching Feedback to Bootstrap Self-Evolving Agents in Long-Horizon Tasks | Environment: The Boundary of What Agents Can Experience | Paper |
| 2026-09-11 | Ecdysis: Efficient and Effective Training of Runtime Harnesses for LLM Agents | Harness as Experience Infrastructure | Paper |
| 2026-09-11 | CoSkill: Joint Reinforcement Learning of Reasoning and Meta-Skill Agents for Hierarchical Skill Evolution | RL and Continual Learning | Paper |
| 2026-09-11 | COBRA-Skills: Contextual Bandit-Guided Evolution for Agent Skill Optimization | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | Co-Evolving Harnesses and Models: On-Policy Correction Helps Weaker Models Catch Up Where Imitation Fails | RL and Continual Learning | Paper |
| 2026-09-11 | Closing the Consistency Gap: Self-Evolving Agents That Learn to Stay on Course | Memory: Experience Becomes Persistent State | Paper |
The complete collection contains 416 papers organized around the survey's nine chapters.
| Survey chapter | Scope | Papers |
|---|---|---|
| Introduction | Foundations, definitions, and surveys that frame self-improving agents. | 22 |
| Harness as Experience Infrastructure | Runtime architectures that capture experience and expose mutable agent surfaces. | 35 |
| Skills: Experience Becomes Reusable Procedure | Skill creation, retrieval, composition, execution, and evolution. | 50 |
| Memory: Experience Becomes Persistent State | Representing, retrieving, consolidating, and evolving agent memory. | 50 |
| Environment: The Boundary of What Agents Can Experience | Tools, executable environments, protocols, and verifiable runtime feedback. | 48 |
| RL and Continual Learning | Consolidating stable experience into model parameters and durable behavior. | 35 |
| Meta-Evolving Agents | Systems that decide what, when, and how an agent should evolve. | 61 |
| Measuring Self-Improvement | Benchmarks and protocols for gain, retention, attribution, and efficiency. | 55 |
| Safety: Self-Improvement as a Moving Attack Surface | Threats, controls, and governance for agents that change after deployment. | 60 |
Search and filter all 416 papers on the project website →
Paper metadata is maintained in data/papers.json. To suggest a missing work, open a pull request with its public paper link and the most relevant survey chapter.
This repository is maintained by the FrontisAI and Tsinghua University survey team. Its README structure follows the public awesome-list style of TsinghuaC3I/Awesome-RL-for-LRMs.
Awesome list and survey website for agents in the era of experience
See the code
We welcome issues and pull requests for missing work on harness agents, agent skills, memory, self-improvement, agent RL, evaluation, and safety.
If you find this survey or paper list helpful, please cite our work:
@article{jiang2026selfimprovingagents,
  title={Self-Improving Agents in the Era of Experience: A Survey of Self- to Meta-Evolution},
  author={Che Jiang and Jincheng Zhong and Yu Fu and Kai Tian and Junlin Yang and Kaikai Zhao and Yuchong Wang and Tianwei Luo and Weizhi Wang and Yuxin Zuo and Guoli Jia and Xingtai Lv and Dianqiao Lei and Sihang Zeng and Yuru Wang and Zhenzhao Yuan and Xinwei Long and Ermo Hua and Can Ren and Xin Jiang and Shulei Xie and Yuanchun Zheng and Youbang Sun and Biqing Qi and Ning Ding and Kaiyan Zhang and Bowen Zhou},
  journal={OpenReview Archive},
  year={2026},
  url={https://openreview.net/pdf?id=IUltZSgLMm}
}
This repository collects papers, systems, benchmarks, and resources for studying how deployed agentic AI systems become more capable after deployment.
We organize the landscape around the harness agent: a deployed runtime system whose behavior is jointly shaped by a base model, a mutable harness, a user-facing interface, and an environment-facing interface. Under this view, self-improvement first appears as fast runtime adaptation over external surfaces such as skills, memory, context, tools, and execution environments. Repeated experience may later be consolidated into model parameters through reinforcement learning, fine-tuning, or continual learning.
We organize the survey into four parts:
The catalog snapshot is 2026-09-11. This section shows up to 20 papers added in the past 7 days.
| Added | Paper | Survey chapter | Links |
|---|---|---|---|
| 2026-09-11 | Who Maintains Agent Skills? A Longitudinal Study of Human-Governed, AI-Assisted Skill Maintenance | Measuring Self-Improvement | Paper |
| 2026-09-11 | TROVE: Adaptive Agent Skill Orchestration via Trace-Grounded Route Validation and Editing | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement | Introduction | Paper |
| 2026-09-11 | SQL-Zero: Self-Evolving Text-to-SQL | RL and Continual Learning | Paper |
| 2026-09-11 | SkillAdam: Stable and Efficient Skill Evolution for Agents | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | SE-GoS: Self-Evolving Graph-of-Skills for Skill Library at Scale | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | RobustSGPO: Search-Space Control for Agent Harness Evolution | Harness as Experience Infrastructure | Paper |
| 2026-09-11 | Procedural Graphs: Self-Evolving Execution Structures for LLM Agents | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness | RL and Continual Learning | Paper |
| 2026-09-11 | MetaRSI / RSI2: A Meta-Recursive Self-Improving System for Recursive Self-Improving Systems Themselves | Meta-Evolving Agents | Paper |
| 2026-09-11 | Harness-agnostic detection and immunization of reward hacking in self-evolving language models | Safety: Self-Improvement as a Moving Attack Surface | Paper |
| 2026-09-11 | Graph-Based Personalized Memory for LLM Agents: Representation, Evolution, Retrieval, and Evaluation | Memory: Experience Becomes Persistent State | Paper |
| 2026-09-11 | From Interaction Traces to Persistent Skills: Online Evolution for Computer-Use Agents | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | Experience Funnel: A State-Policy Alternating Loop for Self-Evolving Agents | RL and Continual Learning | Paper |
| 2026-09-11 | Environments as Scaffold: Enriching Feedback to Bootstrap Self-Evolving Agents in Long-Horizon Tasks | Environment: The Boundary of What Agents Can Experience | Paper |
| 2026-09-11 | Ecdysis: Efficient and Effective Training of Runtime Harnesses for LLM Agents | Harness as Experience Infrastructure | Paper |
| 2026-09-11 | CoSkill: Joint Reinforcement Learning of Reasoning and Meta-Skill Agents for Hierarchical Skill Evolution | RL and Continual Learning | Paper |
| 2026-09-11 | COBRA-Skills: Contextual Bandit-Guided Evolution for Agent Skill Optimization | Skills: Experience Becomes Reusable Procedure | Paper |
| 2026-09-11 | Co-Evolving Harnesses and Models: On-Policy Correction Helps Weaker Models Catch Up Where Imitation Fails | RL and Continual Learning | Paper |
| 2026-09-11 | Closing the Consistency Gap: Self-Evolving Agents That Learn to Stay on Course | Memory: Experience Becomes Persistent State | Paper |
The complete collection contains 416 papers organized around the survey's nine chapters.
| Survey chapter | Scope | Papers |
|---|---|---|
| Introduction | Foundations, definitions, and surveys that frame self-improving agents. | 22 |
| Harness as Experience Infrastructure | Runtime architectures that capture experience and expose mutable agent surfaces. | 35 |
| Skills: Experience Becomes Reusable Procedure | Skill creation, retrieval, composition, execution, and evolution. | 50 |
| Memory: Experience Becomes Persistent State | Representing, retrieving, consolidating, and evolving agent memory. | 50 |
| Environment: The Boundary of What Agents Can Experience | Tools, executable environments, protocols, and verifiable runtime feedback. | 48 |
| RL and Continual Learning | Consolidating stable experience into model parameters and durable behavior. | 35 |
| Meta-Evolving Agents | Systems that decide what, when, and how an agent should evolve. | 61 |
| Measuring Self-Improvement | Benchmarks and protocols for gain, retention, attribution, and efficiency. | 55 |
| Safety: Self-Improvement as a Moving Attack Surface | Threats, controls, and governance for agents that change after deployment. | 60 |
Search and filter all 416 papers on the project website →
Paper metadata is maintained in data/papers.json. To suggest a missing work, open a pull request with its public paper link and the most relevant survey chapter.
This repository is maintained by the FrontisAI and Tsinghua University survey team. Its README structure follows the public awesome-list style of TsinghuaC3I/Awesome-RL-for-LRMs.





