
Repository for Self-Evolving Coding Agents
See the codeREADME
Self-Evolving Coding Agents



📖 Introduction
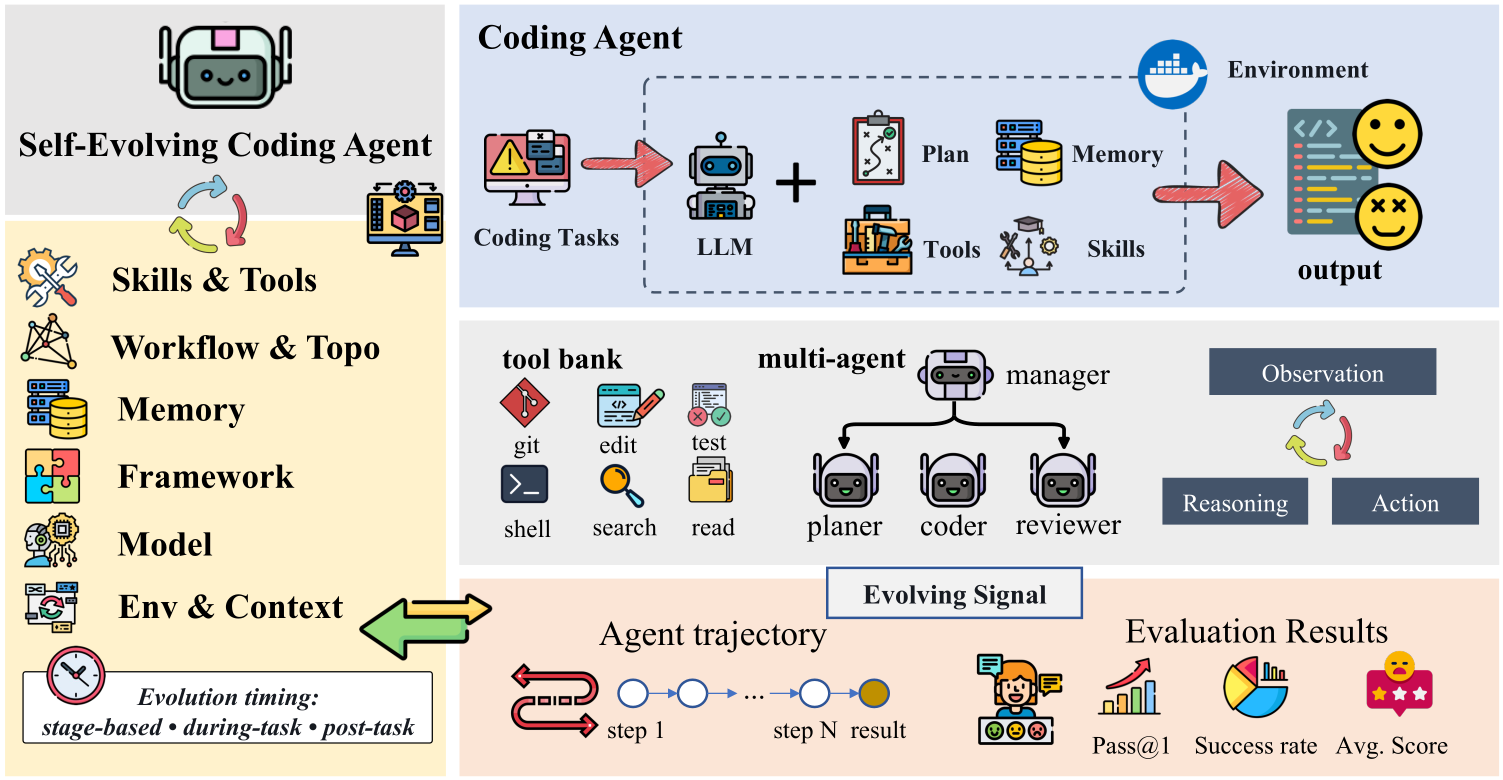
Overview of self-evolving coding agents.
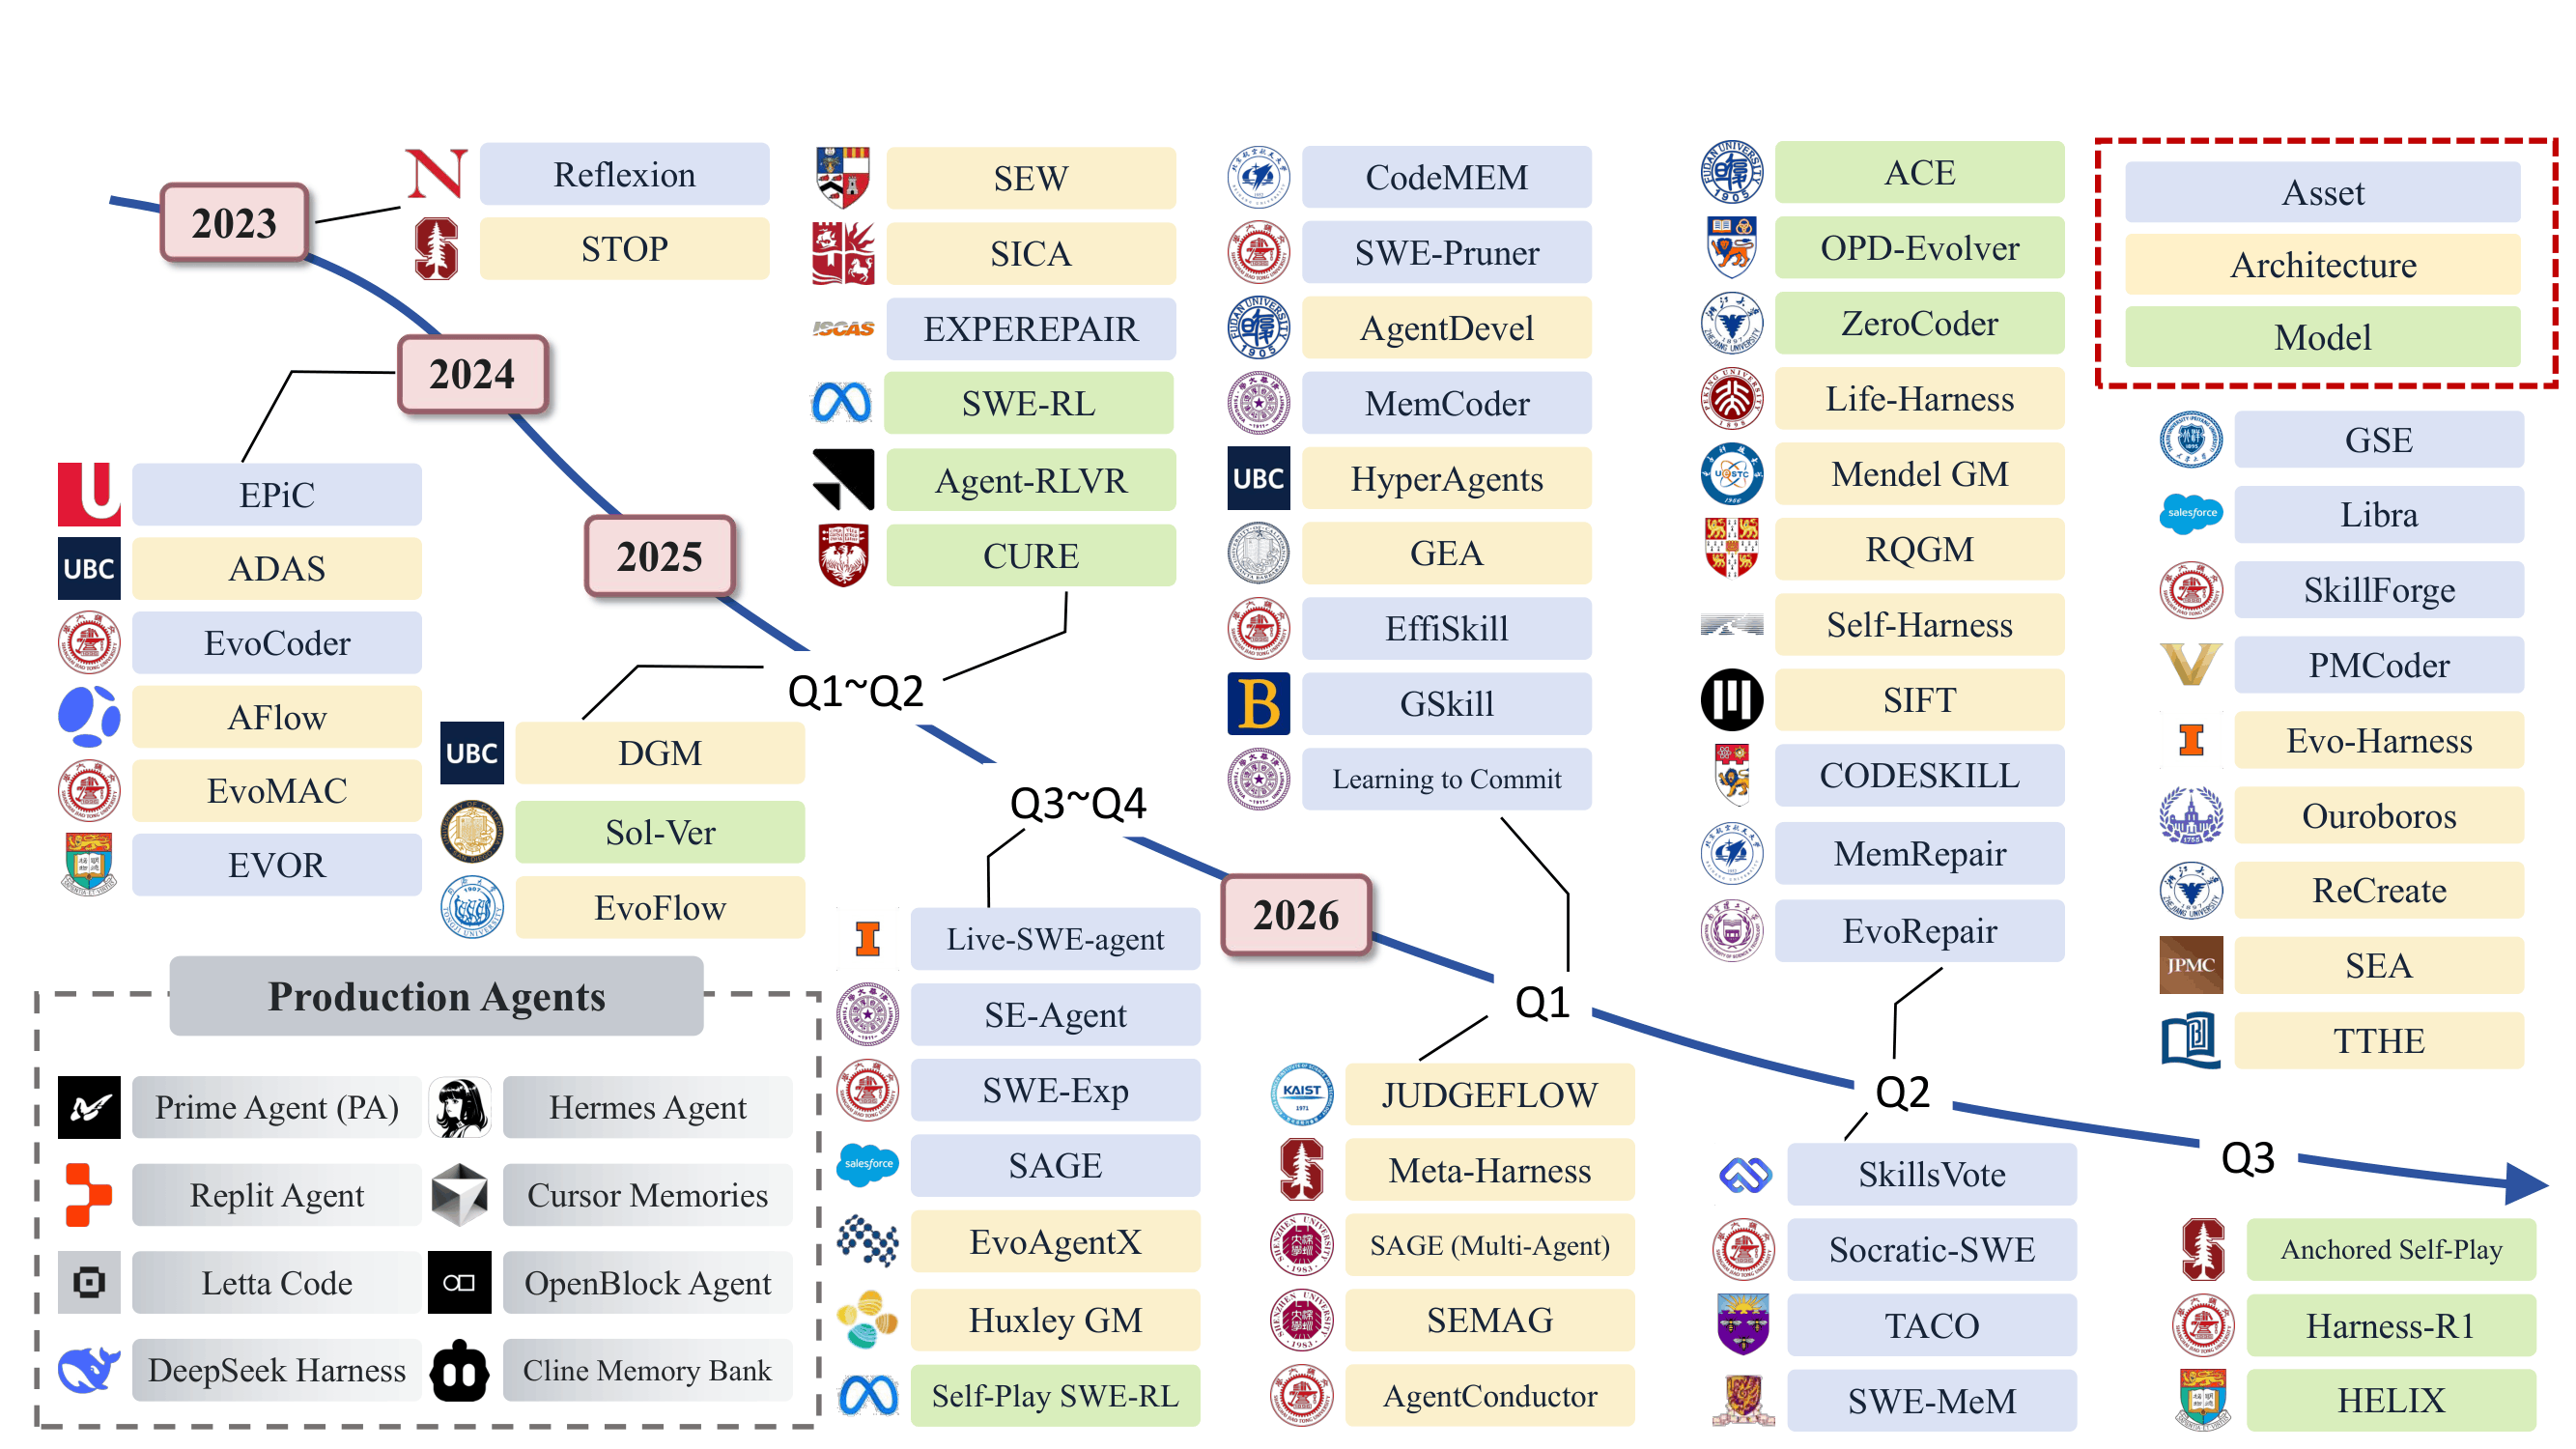
Coding agents increasingly learn from execution outcomes, trajectories, accumulated experience, and environmental feedback, improving the persistent components of their own software-engineering workflow. This repository accompanies our survey and curates its paper corpus, related methods, benchmarks, products, and related surveys. Self-evolving systems are organized into three layers: assets (memory, skills, tools, context), architecture (harness, workflow, multi-agent structures), and model weights.
🎯 Scope
This repository covers five groups of resources:
-
Self-Evolving Coding Agents: curated systems organized by which part of the agent gets modified: assets (memory, skills, tools, context), architecture (harness, workflow, topology), or model weights.
-
General Self-Evolution Methods in Coding Settings: General agent self-evolution methods whose improvements are evaluated on code generation, program execution, or software engineering tasks.
-
Benchmarks and Empirical Studies: Conventional benchmarks for repository-level software engineering and general coding, dedicated benchmarks for agent self-evolution, and empirical studies of coding-agent self-evolution.
-
Products: deployed coding products with persistent adaptation mechanisms, mapped to the same target vocabulary.
-
Related Surveys: surveys covering self-evolving agents, coding agents, and their intersection.
🌐 Contents
- Introduction
- Scope
- 1. Self-Evolving Coding Agents
- 3. Benchmarks and Empirical Studies
- 4. Self-Evolving Coding Products
- 5. Related Surveys
🤖 1. Self-Evolving Coding Agents
1.1 Assets Self-Evolution
1.1.1 Memory Self-Evolution
1.1.1.1 Experience-Derived Memory
- Self-Abstraction from Grounded Experience for Plan-Guided Policy Refinement (SAGE)
[2025-arXiv] - SWE-Exp: Experience-Driven Software Issue Resolution
[2025-arXiv]· [Code] - LLMs as Continuous Learners: Improving the Reproduction of Defective Code in Software Issues (EvoCoder)
[2024-arXiv] - Structurally Aligned Subtask-Level Memory for Software Engineering Agents (Subtask Memory)
[2026-arXiv] - EvoRepair: Enhancing Vulnerability Repair Agents Through Experience-Based Self-Evolution
[2026-arXiv] - Coupling Planning with Episodic Memory in LLM Agents for Software Issue Resolution (PMCoder)
[2026-arXiv] - EXPEREPAIR: Dual-Memory Enhanced LLM-based Repository-Level Program Repair
[2026-FSE]· [Code] - VeriAgent: A Tool-Integrated Multi-Agent System with Evolving Memory for PPA-Aware RTL Code Generation
[2026-arXiv] - MemRepair: Hierarchical Memory for Agentic Repository-Level Vulnerability Repair
[2026-arXiv] - ReasoningBank: Scaling Agent Self-Evolving with Reasoning Memory
[2026-ICLR]· [Code] - Reflexion: Language Agents with Verbal Reinforcement Learning
[2023-NeurIPS]· [Code] - SE-Agent: Self-Evolution Trajectory Optimization in Multi-Step Reasoning with LLM-Based Agents
[2025-NeurIPS]· [Code] - Agent KB: Leveraging Cross-Domain Experience for Agentic Problem Solving
[2025-ICML Workshop]· [Code] - Adaptive Self-improvement LLM Agentic System for ML Library Development
[2025-ICML]· [Code] - PILOT in the Loop: Live Self-Improvement for Long-Horizon Agents
[2026-arXiv] - SWE-MeM: Learning Adaptive Memory Management for Long-Horizon Coding Agents
[2026-arXiv] - From Knowledge to Noise: CTIM-Rover and the Pitfalls of Episodic Memory in Software Engineering Agents
[2025-REALM]· [Code]
1.1.1.2 External Knowledge Memory
- Improving Code Localization with Repository Memory
[2026-ICLR] - Your Code Agent Can Grow Alongside You with Structured Memory (MemCoder)
[2026-arXiv] - Learning to Commit: Generating Organic Pull Requests via Online Repository Memory
[2026-arXiv] - Self-Improving AI Coding Agents Through Accumulated Behavioral Rules: A Closed-Loop Framework
[2026-IEEE ICE]
1.1.2 Skill Self-Evolution
1.1.2.1 Skill Acquisition
- CODESKILL: Learning Self-Evolving Skills for Coding Agents
[2026-arXiv] - Automatically Learning Skills for Coding Agents (GSkill)
[2026-ACM CAIS] - Socratic-SWE: Self-Evolving Coding Agents via Trace-Derived Agent Skills
[2026-arXiv] - Learning Globally Reusable Skills for Coding Agents (GSE)
[2026-arXiv] - SkillForge: Self-Distilling Agents for Project-Specific Issue Resolution
[2026-arXiv]· [Code] - Verilog-Evolve: Feedback-Driven and Skill-Evolving Verilog Generation
[2026-arXiv]· [Code] - Trace2Skill: Verifier-Guided Skill Evolution for Long-Context EDA Agents
[2026-arXiv] - From Procedural Skills to Strategy Genes: Towards Experience-Driven Test-Time Evolution
[2026-arXiv]· [Code]
1.1.2.2 Skill Optimization
- EffiSkill: Agent Skill Based Automated Code Efficiency Optimization
[2026-arXiv] - Do Personalized Skills Help Coding Agents? An Empirical Study of Developer Interaction Histories
[2026-arXiv] - SkillMOO: Multi-objective Optimization of Agent Skills for Software Engineering
[2026-ASE]· [Code] - daVinci-kernel: Co-Evolving Skill Selection, Summarization, and Utilization via RL for GPU Kernel Optimization
[2026-arXiv]· [Code]
1.1.2.3 Skill Governance
- Ratchet: How Reliable Must an LLM Judge Be to Retire a Skill?
[2026-arXiv]· [Code] - SkillsVote: Lifecycle Governance of Agent Skills from Collection, Recommendation to Evolution
[2026-arXiv]· [Code] - Who Grades the Grader? Co-Evolving Evaluation Metrics and Skills for Self-Improving LLM Agents
[2026-arXiv]· [Code]
1.1.2.4 Skill Safety
- Library Drift: Diagnosing and Fixing a Silent Failure Mode in Self-Evolving LLM Skill Libraries
[2026-arXiv]· [Code] - When Self-Evolution Backfires: Pre-Commit Gating against Skill Contamination in LLM Agents
[2026-arXiv] - EVOMAL: Self-Poisoning in Self-Evolving Coding Agents
[2026-arXiv]
1.1.3 Tool Self-Evolution
- Live-SWE-agent: Can Software Engineering Agents Self-Evolve on the Fly?
[2025-arXiv]· [Code] - SIGA: Self-Evolving Coding-Agent Adapters for Scientific Simulation
[2026-arXiv]
1.1.4 Context Self-Evolution
1.1.4.1 Context Retrieval
- EVOR: Evolving Retrieval for Code Generation
[2024-EMNLP Findings]· [Code] - CodeMEM: AST-Guided Adaptive Memory for Repository-Level Iterative Code Generation
[2026-ACL Findings]· [Code]
1.1.4.2 Context Compression
- A Self-Evolving Framework for Efficient Terminal Agents via Observational Context Compression (TACO)
[2026-arXiv]· [Code] - SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents
[2026-arXiv]· [Code]
1.1.4.3 Prompt Evolution
- Automated Prompt Engineering for Cost-Effective Code Generation Using Evolutionary Algorithm (EPiC)
[2026-TOSEM]· [Code] - Prompt Optimization for LLM Code Generation via Reinforcement Learning
[2026-arXiv] - SePO: Self-Evolving Prompt Agent for System Prompt Optimization
[2026-arXiv] - From Failing to Passing: Evolving Natural Language Prompt Optimization Rules for LLM Code Generation
[2026-arXiv]
1.1.4.4 Environment Evolution
- Libra: Training the Environment for Agentic Information Retrieval
[2026-arXiv]· [Code] - Learning to Build the Environment: Self-Evolving Reasoning RL via Verifiable Environment Synthesis (EvoEnv)
[2026-arXiv]
1.2 Architecture Self-Evolution
1.2.1 Harness Evolution
1.2.1.1 Archive-Based Evolution
- Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents (DGM)
[2026-ICLR]· [Code] - Mendel Gödel Machine: Comparative Evolution Enables State-of-the-Art Self-Improving Coding Agents (Mendel GM)
[2026-OpenReview]· [Code] - Huxley Gödel Machine: Human-Level Coding Agent Development by an Approximation of the Optimal Self-Improving Machine (Huxley GM)
[2026-ICLR]· [Code] - Self-Improvement via Fast Tree-Search (SIFT)
[2026-ICLR] - The Red Queen Gödel Machine: Co-Evolving Agents and Their Evaluators (RQGM)
[2026-arXiv] - HyperAgents
[2026-arXiv]· [Code]
1.2.1.2 Iteration-Based Evolution
- A Self-Improving Coding Agent (SICA)
[2025-ICLR]· [Code] - Self-Taught Optimizer (STOP): Recursively Self-Improving Code Generation
[2024-COLM]· [Code] - Ouroboros: A Self-Developing Frontier Coding Agent with Reviewed Core Evolution
[2026-arXiv]· [Code]
1.2.1.3 Trace-Driven Evolution
- Self-Harness: Harnesses That Improve Themselves
[2026-arXiv]· [Code] - AutoSaddler: Automatic Harness Optimization with Durable Updates from Agent Execution Traces
[2026-arXiv]· [Code] - Evo-Harness: Context-to-Harness Skill Compilation for Self-Evolving Agents
[2026-arXiv]· [Code] - Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses (AHE)
[2026-arXiv]· [Code] - From Failed Trajectories to Reliable LLM Agents: Diagnosing and Repairing Harness Flaws (HarnessFix)
[2026-arXiv]· [Code] - ReCreate: Reasoning and Creating Domain Agents Driven by Experience
[2026-ACL]· [Code] - Harness-of-Harness: Multi-Day Autonomous Software Development with Continual Improvement
[2026-arXiv]· [Code] - One Recipe, Many Harnesses: What Self-Evolution Encodes Across Languages and Models
[2026-arXiv]
1.2.1.4 Population-Based Search
- DarwinX: Evolving Agent Harnesses Through Natural Selection
[2026-arXiv] - HarnessBank: Semantic Gene-Bank Search with Gated Verification for Agent-Harness Self-Evolution
[2026-arXiv] - EvolveNet: Collaborative Harness Evolution for Agent Self-Improvement
[2026-arXiv]· [Code] - HarnessCompass: Guiding Automatic Harness Evolution toward Generalizable and Effective Agent Harnesses
[2026-arXiv] - Automated Design of Agentic Systems (ADAS)
[2025-ICLR]· [Code]
1.2.1.5 Pipeline-Driven Evolution
- Meta-Harness: End-to-End Optimization of Model Harnesses
[2026-arXiv]· [Code] - AgentDevel: Reframing Self-Evolving LLM Agents as Release Engineering
[2026-arXiv] - HarnessX: A Composable, Adaptive, and Evolvable Agent Harness Foundry
[2026-arXiv]· [Code] - Confucius Code Agent: Scalable Agent Scaffolding for Real-World Codebases (CCA)
[2025-arXiv]· [Code] - Autogenesis: A Self-Evolving Agent Protocol
[2026-arXiv]· [Code] - Self-Evolving Agents with Anytime-Valid Certificates (SEA)
[2026-arXiv]
1.2.1.6 Runtime Evolution
- TTHE: Test-Time Harness Evolution
[2026-arXiv]· [Code] - Adapting the Interface, Not the Model: Runtime Harness Adaptation for Deterministic LLM Agents (Life-Harness)
[2026-arXiv]· [Code] - Argus: A General-Purpose Agentic Reasoning Runtime for Long-Horizon Tasks
[2026-arXiv]· [Code]
1.2.2 Workflow Evolution
- AFlow: Automating Agentic Workflow Generation
[2025-ICLR]· [Code] - SEW: Self-Evolving Agentic Workflows for Automated Code Generation
[2025-arXiv]· [Code] - EvoFlow: Evolving Diverse Agentic Workflows On The Fly
[2025-arXiv] - EvoAgentX: An Automated Framework for Evolving Agentic Workflows
[2025-EMNLP Demos]· [Code] - FlowEvo: Self-Evolving Agents through the Co-Evolution of Workflows and Executable Skills
[2026-arXiv]· [Code] - JUDGEFLOW: Agentic Workflow Optimization via Block Judge
[2026-arXiv]
1.2.3 Multi-Agent Evolution
- Self-Evolving Multi-Agent Collaboration Networks for Software Development (EvoMAC)
[2025-ICLR]· [Code] - AgentConductor: Topology Evolution for Multi-Agent Competition-Level Code Generation
[2026-ICML] - SEMAG: Self-Evolutionary Multi-Agent Code Generation
[2026-arXiv] - Group-Evolving Agents: Open-Ended Self-Improvement via Experience Sharing (GEA)
[2026-arXiv]· [Code] - SAGE: Multi-Agent Self-Evolution for LLM Reasoning
[2026-arXiv] - Evolve as a Team: Collaborative Self-Evolution for LLM-Based Multi-Agent Systems
[2026-arXiv]· [Code]
1.3 Model Self-Evolution
1.3.1 Self-Play Co-Evolution
- Toward Training Superintelligent Software Agents through Self-Play SWE-RL
[2026-ICML] - ReVeal: Self-Evolving Code Agents via Iterative Generation-Verification
[2026-ICLR]· [Code] - CURE: Co-Evolving LLM Coder and Unit Tester via Reinforcement Learning
[2025-NeurIPS]· [Code] - ZeroCoder: Can LLMs Improve Code Generation Without Ground-Truth Supervision?
[2026-arXiv] - Learning to Solve and Verify: A Self-Play Framework for Code and Test Generation (Sol-Ver)
[2025-NeurIPS] - ACE: Self-Evolving LLM Coding Framework via Adversarial Unit Test Generation and Preference Optimization
[2026-arXiv] - Anchored Self-Play for Code Repair
[2026-ICML] - Absolute Zero: Reinforced Self-Play Reasoning with Zero Data
[2025-NeurIPS]· [Code] - OPD-Evolver: Cultivating Holistic Agent Evolver via On-Policy Distillation
[2026-arXiv]· [Code]
1.3.2 Environment-Reward RL
- Agent-RLVR: Training Software Engineering Agents via Guidance and Environment Rewards
[2026-ICLR] - SWE-RL: Advancing LLM Reasoning via Reinforcement Learning on Open Software Evolution
[2025-NeurIPS]· [Code] - Self-Improving Language Models for Evolutionary Program Synthesis: A Case Study on ARC-AGI (SOAR)
[2025-ICML]· [Code]
1.3.3 Harness Co-Evolution
- Harness-R1: Learning to Edit Executable Runtime Harnesses from Agent Failure Trajectories
[2026-arXiv]· [Code] - HELIX: Model-Harness Co-evolution for Recursive Self-Improvement
[2026-arXiv]· [Code]
📊 3. Benchmarks and Empirical Studies
This section brings together repository-level software engineering benchmarks and general coding benchmarks to assess coding capabilities, self-evolution benchmarks to evaluate agents' ability to improve themselves, and empirical studies to examine the performance gains, computational costs, and failure modes of self-evolving coding agents.
3.1 Repository-Level Software Engineering Benchmarks
- SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
[2024-ICLR] - SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?
[2026-ICML] - SWE-EVO: Benchmarking Coding Agents in Long-Horizon Software Evolution Scenarios
[2025-arXiv] - SWE-bench Multimodal: Do AI Systems Generalize to Visual Software Domains?
[2025-ICLR] - Multi-SWE-bench: A Multilingual Benchmark for Issue Resolving
[2025-NeurIPS Datasets and Benchmarks] - SWE-PolyBench: A Multi-Language Benchmark for Repository Level Evaluation of Coding Agents
[2025-arXiv] - SWE-bench Goes Live! (SWE-bench-Live)
[2025-NeurIPS Datasets and Benchmarks] - SWE-bench Multilingual
[2025-Benchmark] - BeyondSWE: Can Current Code Agent Survive Beyond Single-Repo Bug Fixing?
[2026-arXiv] - LoCoBench: A Benchmark for Long-Context Large Language Models in Complex Software Engineering
[2025-arXiv] - CoderEval: A Benchmark of Pragmatic Code Generation with Generative Pre-trained Models
[2024-ICSE] - DevEval: A Manually-Annotated Code Generation Benchmark Aligned with Real-World Code Repositories
[2024-ACL Findings] - SWE-QA: Can Language Models Answer Repository-level Code Questions?
[2026-ACL Findings] - LongCodeBench: Evaluating Coding LLMs at 1M Context Windows
[2025-COLM] - CRUST-Bench: A Comprehensive Benchmark for C-to-safe-Rust Transpilation
[2025-COLM] - PATCHEVAL: A New Benchmark for Evaluating LLMs on Patching Real-World Vulnerabilities
[2025-arXiv] - SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks
[2025-NeurIPS] - Vul4J: A Dataset of Reproducible Java Vulnerabilities Geared Towards the Study of Program Repair Techniques
[2022-MSR] - CRAVE: Code Review Agent Verdict Evaluation
[2025-Dataset] - Self-Evolving Multi-Agent Collaboration Networks for Software Development (rSDE-Bench)
[2025-ICLR] - GameCraft-Bench: Can Agents Build Playable Games End-to-End in a Real Game Engine?
[2026-arXiv] - ProgramBench: Can Language Models Rebuild Programs From Scratch?
[2026-arXiv] - FrontierSWE
[2026-Benchmark] - CompileBench: Can AI Compile 22-year-old Code?
[2025-Benchmark]
3.2 General Coding Benchmarks
- Evaluating Large Language Models Trained on Code (HumanEval)
[2021-arXiv] - Program Synthesis with Large Language Models (MBPP)
[2021-arXiv] - Measuring Coding Challenge Competence with APPS
[2021-NeurIPS Datasets and Benchmarks] - Competition-Level Code Generation with AlphaCode (CodeContests)
[2022-Science] - LiveCodeBench: Holistic and Contamination Free Evaluation of Large Language Models for Code
[2025-ICLR] - BigCodeBench: Benchmarking Code Generation with Diverse Function Calls and Complex Instructions
[2025-ICLR] - Is Your Code Generated by ChatGPT Really Correct? Rigorous Evaluation of Large Language Models for Code Generation (EvalPlus)
[2023-NeurIPS] - MultiPL-E: A Scalable and Extensible Approach to Benchmarking Neural Code Generation
[2023-IEEE TSE] - DS-1000: A Natural and Reliable Benchmark for Data Science Code Generation
[2023-ICML] - CRUXEval: A Benchmark for Code Reasoning, Understanding and Execution
[2024-ICML] - xCodeEval: A Large Scale Multilingual Multitask Benchmark for Code Understanding, Generation, Translation and Retrieval
[2024-ACL] - EffiBench-X: A Multi-Language Benchmark for Measuring Efficiency of LLM-Generated Code
[2025-NeurIPS Datasets and Benchmarks] - Aider Polyglot Benchmark
[2024-Benchmark] - Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces
[2026-ICLR] - Let It Flow: Agentic Crafting on Rock and Roll, Building the ROME Model within an Open Agentic Learning Ecosystem (Terminal-Bench Pro)
[2025-arXiv] - TerminalWorld: Benchmarking Agents on Real-World Terminal Tasks
[2026-arXiv] - DebugBench: Evaluating Debugging Capability of Large Language Models
[2024-ACL Findings] - Anchored Self-Play for Code Repair (BugSourceBench)
[2026-ICML] - CodeIF-Bench: Evaluating Instruction-Following Capabilities of Large Language Models in Interactive Code Generation
[2025-arXiv] - LongCoder: A Long-Range Pre-trained Language Model for Code Completion (LCC)
[2023-ICML] - EvoR: Evolving Retrieval for Code Generation (EvoR-bench)
[2024-EMNLP Findings] - Can LLM Already Serve as A Database Interface? A BIg Bench for Large-Scale Database Grounded Text-to-SQLs (BIRD)
[2023-NeurIPS Datasets and Benchmarks] - Spider 2.0: Evaluating Language Models on Real-World Enterprise Text-to-SQL Workflows
[2025-ICLR] - DA-Code: Agent Data Science Code Generation Benchmark for Large Language Models
[2024-EMNLP] - InterCode: Standardizing and Benchmarking Interactive Coding with Execution Feedback
[2023-NeurIPS Datasets and Benchmarks] - VerilogEval: Evaluating Large Language Models for Verilog Code Generation
[2023-ICCAD] - RTLLM: An Open-Source Benchmark for Design RTL Generation with Large Language Model
[2024-ASP-DAC] - Comprehensive Verilog Design Problems: A Next-Generation Benchmark Dataset for Evaluating Large Language Models and Agents on RTL Design and Verification (CVDP)
[2025-arXiv] - KernelBench: Can LLMs Write Efficient GPU Kernels?
[2025-ICML] - SOL-ExecBench: Speed-of-Light Benchmarking for Real-World GPU Kernels Against Hardware Limits
[2026-arXiv] - LiveBench: A Challenging, Contamination-Limited LLM Benchmark (Coding Subset)
[2025-ICLR] - SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks (Software Engineering Subset)
[2026-arXiv]
3.3 Self-Evolution Benchmarks
- HarnessDev: Can LLMs Create and Evolve Their Own Agent Harness?
[2026-arXiv] - EvoAgentBench: Benchmarking Agent Self-Evolution via Ability Transfer (Coding and Software Engineering Subsets)
[2026-arXiv] - SkillEvolBench: Benchmarking the Evolution from Episodic Experience to Procedural Skills (Code Modification Subset)
[2026-arXiv] - RSIBench-Data: Benchmarking Data-Centric Research for Recursive Self-Improvement
[2026-arXiv] - AI4AI-Bench: Benchmarking LLM Agents in Algorithmic Design for Recursive Self-Improvement
[2026-arXiv] - SWE-Bench-CL: Continual Learning for Coding Agents
[2025-arXiv]
3.4 Empirical Studies
- Rethinking the Evaluation of Harness Evolution for Agents
[2026-arXiv] - Harness Updating Is Not Harness Benefit: Disentangling Evolution Capabilities in Self-Evolving LLM Agents
[2026-arXiv] - Phantom Guardrails: When Self-Improving Agent Harnesses Fix Failures That Never Happened
[2026-arXiv] - Behind EvoMap: Characterizing a Self-Evolving Agent-to-Agent Collaboration Network
[2026-arXiv] - Don't Blame the Large Language Model: How Agent Harness Evolution Shapes Coding Agent Quality
[2026-arXiv] - The Scaffold Effect in Coding Agents: Harness Choice as a Hidden Variable in Coding-Agent Evaluation
[2026-arXiv] - Prompt-Induced Waste in Coding Agents: Reasoning, Effort, Harness Design, and End-to-End Cost
[2026-arXiv] - Harness Engineering: Anatomy, Architecture, and Evolution of Coding Agents -- A Source-Code Study of Eleven Systems
[2026-arXiv] - Self-Authored Verification Is Unreliable in Heuristic Self-Improving Agents
[2026-arXiv] - Memory Reward Inflation in Self-Improving LLM Agents
[2026-arXiv] - Auditing Harness Tampering in Self-Improving Agents
[2026-arXiv] - From Raw Experience to Skill Consumption: A Systematic Study of Model-Generated Agent Skills
[2026-arXiv] - Memory Transfer Learning: How Memories are Transferred Across Domains in Coding Agents
[2026-arXiv] - How Memory Management Impacts LLM Agents: An Empirical Study of Experience-Following Behavior
[2026-ACL]
🧩 4. Self-Evolving Coding Products
These products and open-source tools support persistent memory, reusable skills, context updates, and harness customization through automatic or user-guided refinement. The table summarizes adaptation targets and mechanisms. Inclusion reflects documented capabilities, not necessarily a fully autonomous, experimentally validated self-evolution loop.
Target legend: 🔵 Assets — Memory, Skill, Tool, Context (including environment adaptation) · 🟣 Architecture — Harness, Workflow, Multi-Agent.
| Product | Company / Year | Target | Mechanism in Practice | Resources |
|---|---|---|---|---|
| Prime Agent (PA) | Prime Intellect2026 | 🔵 AssetsMemory · Skill · Context🟣 Architecture Harness · Multi-Agent | Refines agent components from task trajectories. | Code |
| DeepSeek Harness (DSH) | DeepSeek2026 | 🟣 ArchitectureHarness | Tests plugins and creates presets through Creator Mode. | Code |
| Gemini CLI Auto Memory (GCAM) | Google2026 | 🔵 AssetsMemory · Skill | Proposes memory and skill updates for user review. | Changelog |
| GitHub Copilot Memory (GCM) | GitHub2026 | 🔵 AssetsMemory | Stores repository facts and validates them before reuse. | Announcement |
| Augment Agent / Cosmos Learning Flywheel (AA/CLF) | Augment Code2025–2026 | 🔵 AssetsMemory · Context | Distills team feedback into shared memory and context. | Memory review |
| Claude Code Auto Memory (CCAM) | Anthropic2026 | 🔵 AssetsMemory | Automatically saves corrections, preferences, and project learnings. | Changelog |
| Cursor Memories / Automations (CMA) | Cursor2025–2026 | 🔵 AssetsMemory | Retains useful context across sessions and automation runs. | Memories |
| Devin Session Insights / Knowledge / Playbooks (Devin SIKP) | Cognition2025–2026 | 🔵 AssetsMemory · Skill · Context | Uses session analysis to guide knowledge and configuration updates. | Advanced capabilities |
| Windsurf Cascade Memories (WCM) | Windsurf / Cognition2025–2026 | 🔵 AssetsMemory | Creates workspace memories and retrieves them when relevant. | Docs |
| OpenBlock Agent (OB-1) | OpenBlock Labs2026 | 🔵 AssetsMemory | Learns codebase patterns for subsequent tasks. | Waitlist |
| Letta Code | Letta2025–2026 | 🔵 AssetsMemory · Skill · Context | Reviews sessions to refine memory and context; versions skills. | Code |
| Hermes Agent | Nous Research2026 | 🔵 AssetsMemory · Skill | Creates skills from experience and refines them through reuse. | Skills Code |
| Kiro Web / Autonomous Agent | AWS2025–2026 | 🔵 AssetsMemory | Learns team conventions from code-review feedback. | Product |
| Replit Agent | Replit2025–2026 | 🔵 AssetsMemory · Skill · Context | Maintains replit.md and creates reusable skills. | Announcement |
| OpenClaw | OpenClaw Foundation / Community2026 | 🔵 AssetsMemory | Consolidates session notes into persistent memory. | Coding integration Code |
| Cline Memory Bank | Cline / Community2025 | 🔵 AssetsMemory · Context | Maintains structured project memory through configured instructions. | Documentation |
From memory to architecture: Most products adapt assets such as memory, skills, and context. Prime Agent and DeepSeek Harness also expose mechanisms for modifying the surrounding agent harness.
📚 5. Related Surveys
5.1 Surveys on Self-Evolving Agents
- A Survey of Self-Evolving Agents: What, When, How, and Where to Evolve on the Path to Artificial Super Intelligence
[2026-TMLR] - A Comprehensive Survey of Self-Evolving AI Agents: A New Paradigm Bridging Foundation Models and Lifelong Agentic Systems
[2025-arXiv] - A Systematic Survey of Self-Evolving Agents: From Model-Centric to Environment-Driven Co-Evolution
[2026-TechRxiv] - Self-Improvements in Modern Agentic Systems: A Survey
[2026-arXiv] - Self-Improving Agents in the Era of Experience: A Survey of Self- to Meta-Evolution
[2026-OpenReview] - A Survey on Self-Evolution of Large Language Models
[2024-arXiv] - Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering
[2026-arXiv] - Diving into Reliable Self-Evolving Agents: A Survey
[2026-OpenReview] - The Path to Recursive Self-Improving Agents: Foundation, Framework, and Future Directions
[2026-Preprints.org] - Self-Evolving Agents as Dynamic Graph Transformation: A Survey and New Perspective
[2026-arXiv]
5.2 Surveys on Coding Agents
- Large Language Model-Based Agents for Software Engineering: A Survey
[2025-TOSEM] - Agents in Software Engineering: Survey, Landscape, and Vision
[2025-Automated Software Engineering] - LLM-Based Multi-Agent Systems for Software Engineering: Literature Review, Vision, and the Road Ahead
[2025-TOSEM] - Large Language Models for Software Engineering: A Systematic Literature Review
[2024-TOSEM] - A Survey on Large Language Models for Code Generation
[2026-TOSEM] - Advances and Frontiers of LLM-Based Issue Resolution in Software Engineering: A Comprehensive Survey
[2026-arXiv]
Citation
@misc{zhou2026selfevolvingcodingagents,
      title={Self-Evolving Coding Agents},
      author={Hao Zhou and Haichuan Hu and Tianyu Luo and Ye Shang and Chunrong Fang and Zhenyu Chen and Liang Xiao and Quanjun Zhang},
      year={2026},
      eprint={2608.03392},
      archivePrefix={arXiv},
      primaryClass={cs.SE},
      url={https://arxiv.org/abs/2608.03392},
}
🤝 Contributions are welcome! If you find any missing or incorrect information, please feel free to open an issue or submit a pull request.
Contributors


Similar repos


Repository for Self-Evolving Coding Agents
See the codeREADME
Self-Evolving Coding Agents
📖 Introduction
Overview of self-evolving coding agents.
Coding agents increasingly learn from execution outcomes, trajectories, accumulated experience, and environmental feedback, improving the persistent components of their own software-engineering workflow. This repository accompanies our survey and curates its paper corpus, related methods, benchmarks, products, and related surveys. Self-evolving systems are organized into three layers: assets (memory, skills, tools, context), architecture (harness, workflow, multi-agent structures), and model weights.
🎯 Scope
This repository covers five groups of resources:
-
Self-Evolving Coding Agents: curated systems organized by which part of the agent gets modified: assets (memory, skills, tools, context), architecture (harness, workflow, topology), or model weights.
-
General Self-Evolution Methods in Coding Settings: General agent self-evolution methods whose improvements are evaluated on code generation, program execution, or software engineering tasks.
-
Benchmarks and Empirical Studies: Conventional benchmarks for repository-level software engineering and general coding, dedicated benchmarks for agent self-evolution, and empirical studies of coding-agent self-evolution.
-
Products: deployed coding products with persistent adaptation mechanisms, mapped to the same target vocabulary.
-
Related Surveys: surveys covering self-evolving agents, coding agents, and their intersection.
🌐 Contents
- Introduction
- Scope
- 1. Self-Evolving Coding Agents
- 3. Benchmarks and Empirical Studies
- 4. Self-Evolving Coding Products
- 5. Related Surveys
🤖 1. Self-Evolving Coding Agents
1.1 Assets Self-Evolution
1.1.1 Memory Self-Evolution
1.1.1.1 Experience-Derived Memory
- Self-Abstraction from Grounded Experience for Plan-Guided Policy Refinement (SAGE)
[2025-arXiv] - SWE-Exp: Experience-Driven Software Issue Resolution
[2025-arXiv]· [Code] - LLMs as Continuous Learners: Improving the Reproduction of Defective Code in Software Issues (EvoCoder)
[2024-arXiv] - Structurally Aligned Subtask-Level Memory for Software Engineering Agents (Subtask Memory)
[2026-arXiv] - EvoRepair: Enhancing Vulnerability Repair Agents Through Experience-Based Self-Evolution
[2026-arXiv] - Coupling Planning with Episodic Memory in LLM Agents for Software Issue Resolution (PMCoder)
[2026-arXiv] - EXPEREPAIR: Dual-Memory Enhanced LLM-based Repository-Level Program Repair
[2026-FSE]· [Code] - VeriAgent: A Tool-Integrated Multi-Agent System with Evolving Memory for PPA-Aware RTL Code Generation
[2026-arXiv] - MemRepair: Hierarchical Memory for Agentic Repository-Level Vulnerability Repair
[2026-arXiv] - ReasoningBank: Scaling Agent Self-Evolving with Reasoning Memory
[2026-ICLR]· [Code] - Reflexion: Language Agents with Verbal Reinforcement Learning
[2023-NeurIPS]· [Code] - SE-Agent: Self-Evolution Trajectory Optimization in Multi-Step Reasoning with LLM-Based Agents
[2025-NeurIPS]· [Code] - Agent KB: Leveraging Cross-Domain Experience for Agentic Problem Solving
[2025-ICML Workshop]· [Code] - Adaptive Self-improvement LLM Agentic System for ML Library Development
[2025-ICML]· [Code] - PILOT in the Loop: Live Self-Improvement for Long-Horizon Agents
[2026-arXiv] - SWE-MeM: Learning Adaptive Memory Management for Long-Horizon Coding Agents
[2026-arXiv] - From Knowledge to Noise: CTIM-Rover and the Pitfalls of Episodic Memory in Software Engineering Agents
[2025-REALM]· [Code]
1.1.1.2 External Knowledge Memory
- Improving Code Localization with Repository Memory
[2026-ICLR] - Your Code Agent Can Grow Alongside You with Structured Memory (MemCoder)
[2026-arXiv] - Learning to Commit: Generating Organic Pull Requests via Online Repository Memory
[2026-arXiv] - Self-Improving AI Coding Agents Through Accumulated Behavioral Rules: A Closed-Loop Framework
[2026-IEEE ICE]
1.1.2 Skill Self-Evolution
1.1.2.1 Skill Acquisition
- CODESKILL: Learning Self-Evolving Skills for Coding Agents
[2026-arXiv] - Automatically Learning Skills for Coding Agents (GSkill)
[2026-ACM CAIS] - Socratic-SWE: Self-Evolving Coding Agents via Trace-Derived Agent Skills
[2026-arXiv] - Learning Globally Reusable Skills for Coding Agents (GSE)
[2026-arXiv] - SkillForge: Self-Distilling Agents for Project-Specific Issue Resolution
[2026-arXiv]· [Code] - Verilog-Evolve: Feedback-Driven and Skill-Evolving Verilog Generation
[2026-arXiv]· [Code] - Trace2Skill: Verifier-Guided Skill Evolution for Long-Context EDA Agents
[2026-arXiv] - From Procedural Skills to Strategy Genes: Towards Experience-Driven Test-Time Evolution
[2026-arXiv]· [Code]
1.1.2.2 Skill Optimization
- EffiSkill: Agent Skill Based Automated Code Efficiency Optimization
[2026-arXiv] - Do Personalized Skills Help Coding Agents? An Empirical Study of Developer Interaction Histories
[2026-arXiv] - SkillMOO: Multi-objective Optimization of Agent Skills for Software Engineering
[2026-ASE]· [Code] - daVinci-kernel: Co-Evolving Skill Selection, Summarization, and Utilization via RL for GPU Kernel Optimization
[2026-arXiv]· [Code]
1.1.2.3 Skill Governance
- Ratchet: How Reliable Must an LLM Judge Be to Retire a Skill?
[2026-arXiv]· [Code] - SkillsVote: Lifecycle Governance of Agent Skills from Collection, Recommendation to Evolution
[2026-arXiv]· [Code] - Who Grades the Grader? Co-Evolving Evaluation Metrics and Skills for Self-Improving LLM Agents
[2026-arXiv]· [Code]
1.1.2.4 Skill Safety
- Library Drift: Diagnosing and Fixing a Silent Failure Mode in Self-Evolving LLM Skill Libraries
[2026-arXiv]· [Code] - When Self-Evolution Backfires: Pre-Commit Gating against Skill Contamination in LLM Agents
[2026-arXiv] - EVOMAL: Self-Poisoning in Self-Evolving Coding Agents
[2026-arXiv]
1.1.3 Tool Self-Evolution
- Live-SWE-agent: Can Software Engineering Agents Self-Evolve on the Fly?
[2025-arXiv]· [Code] - SIGA: Self-Evolving Coding-Agent Adapters for Scientific Simulation
[2026-arXiv]
1.1.4 Context Self-Evolution
1.1.4.1 Context Retrieval
- EVOR: Evolving Retrieval for Code Generation
[2024-EMNLP Findings]· [Code] - CodeMEM: AST-Guided Adaptive Memory for Repository-Level Iterative Code Generation
[2026-ACL Findings]· [Code]
1.1.4.2 Context Compression
- A Self-Evolving Framework for Efficient Terminal Agents via Observational Context Compression (TACO)
[2026-arXiv]· [Code] - SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents
[2026-arXiv]· [Code]
1.1.4.3 Prompt Evolution
- Automated Prompt Engineering for Cost-Effective Code Generation Using Evolutionary Algorithm (EPiC)
[2026-TOSEM]· [Code] - Prompt Optimization for LLM Code Generation via Reinforcement Learning
[2026-arXiv] - SePO: Self-Evolving Prompt Agent for System Prompt Optimization
[2026-arXiv] - From Failing to Passing: Evolving Natural Language Prompt Optimization Rules for LLM Code Generation
[2026-arXiv]
1.1.4.4 Environment Evolution
- Libra: Training the Environment for Agentic Information Retrieval
[2026-arXiv]· [Code] - Learning to Build the Environment: Self-Evolving Reasoning RL via Verifiable Environment Synthesis (EvoEnv)
[2026-arXiv]
1.2 Architecture Self-Evolution
1.2.1 Harness Evolution
1.2.1.1 Archive-Based Evolution
- Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents (DGM)
[2026-ICLR]· [Code] - Mendel Gödel Machine: Comparative Evolution Enables State-of-the-Art Self-Improving Coding Agents (Mendel GM)
[2026-OpenReview]· [Code] - Huxley Gödel Machine: Human-Level Coding Agent Development by an Approximation of the Optimal Self-Improving Machine (Huxley GM)
[2026-ICLR]· [Code] - Self-Improvement via Fast Tree-Search (SIFT)
[2026-ICLR] - The Red Queen Gödel Machine: Co-Evolving Agents and Their Evaluators (RQGM)
[2026-arXiv] - HyperAgents
[2026-arXiv]· [Code]
1.2.1.2 Iteration-Based Evolution
- A Self-Improving Coding Agent (SICA)
[2025-ICLR]· [Code] - Self-Taught Optimizer (STOP): Recursively Self-Improving Code Generation
[2024-COLM]· [Code] - Ouroboros: A Self-Developing Frontier Coding Agent with Reviewed Core Evolution
[2026-arXiv]· [Code]
1.2.1.3 Trace-Driven Evolution
- Self-Harness: Harnesses That Improve Themselves
[2026-arXiv]· [Code] - AutoSaddler: Automatic Harness Optimization with Durable Updates from Agent Execution Traces
[2026-arXiv]· [Code] - Evo-Harness: Context-to-Harness Skill Compilation for Self-Evolving Agents
[2026-arXiv]· [Code] - Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses (AHE)
[2026-arXiv]· [Code] - From Failed Trajectories to Reliable LLM Agents: Diagnosing and Repairing Harness Flaws (HarnessFix)
[2026-arXiv]· [Code] - ReCreate: Reasoning and Creating Domain Agents Driven by Experience
[2026-ACL]· [Code] - Harness-of-Harness: Multi-Day Autonomous Software Development with Continual Improvement
[2026-arXiv]· [Code] - One Recipe, Many Harnesses: What Self-Evolution Encodes Across Languages and Models
[2026-arXiv]
1.2.1.4 Population-Based Search
- DarwinX: Evolving Agent Harnesses Through Natural Selection
[2026-arXiv] - HarnessBank: Semantic Gene-Bank Search with Gated Verification for Agent-Harness Self-Evolution
[2026-arXiv] - EvolveNet: Collaborative Harness Evolution for Agent Self-Improvement
[2026-arXiv]· [Code] - HarnessCompass: Guiding Automatic Harness Evolution toward Generalizable and Effective Agent Harnesses
[2026-arXiv] - Automated Design of Agentic Systems (ADAS)
[2025-ICLR]· [Code]
1.2.1.5 Pipeline-Driven Evolution
- Meta-Harness: End-to-End Optimization of Model Harnesses
[2026-arXiv]· [Code] - AgentDevel: Reframing Self-Evolving LLM Agents as Release Engineering
[2026-arXiv] - HarnessX: A Composable, Adaptive, and Evolvable Agent Harness Foundry
[2026-arXiv]· [Code] - Confucius Code Agent: Scalable Agent Scaffolding for Real-World Codebases (CCA)
[2025-arXiv]· [Code] - Autogenesis: A Self-Evolving Agent Protocol
[2026-arXiv]· [Code] - Self-Evolving Agents with Anytime-Valid Certificates (SEA)
[2026-arXiv]
1.2.1.6 Runtime Evolution
- TTHE: Test-Time Harness Evolution
[2026-arXiv]· [Code] - Adapting the Interface, Not the Model: Runtime Harness Adaptation for Deterministic LLM Agents (Life-Harness)
[2026-arXiv]· [Code] - Argus: A General-Purpose Agentic Reasoning Runtime for Long-Horizon Tasks
[2026-arXiv]· [Code]
1.2.2 Workflow Evolution
- AFlow: Automating Agentic Workflow Generation
[2025-ICLR]· [Code] - SEW: Self-Evolving Agentic Workflows for Automated Code Generation
[2025-arXiv]· [Code] - EvoFlow: Evolving Diverse Agentic Workflows On The Fly
[2025-arXiv] - EvoAgentX: An Automated Framework for Evolving Agentic Workflows
[2025-EMNLP Demos]· [Code] - FlowEvo: Self-Evolving Agents through the Co-Evolution of Workflows and Executable Skills
[2026-arXiv]· [Code] - JUDGEFLOW: Agentic Workflow Optimization via Block Judge
[2026-arXiv]
1.2.3 Multi-Agent Evolution
- Self-Evolving Multi-Agent Collaboration Networks for Software Development (EvoMAC)
[2025-ICLR]· [Code] - AgentConductor: Topology Evolution for Multi-Agent Competition-Level Code Generation
[2026-ICML] - SEMAG: Self-Evolutionary Multi-Agent Code Generation
[2026-arXiv] - Group-Evolving Agents: Open-Ended Self-Improvement via Experience Sharing (GEA)
[2026-arXiv]· [Code] - SAGE: Multi-Agent Self-Evolution for LLM Reasoning
[2026-arXiv] - Evolve as a Team: Collaborative Self-Evolution for LLM-Based Multi-Agent Systems
[2026-arXiv]· [Code]
1.3 Model Self-Evolution
1.3.1 Self-Play Co-Evolution
- Toward Training Superintelligent Software Agents through Self-Play SWE-RL
[2026-ICML] - ReVeal: Self-Evolving Code Agents via Iterative Generation-Verification
[2026-ICLR]· [Code] - CURE: Co-Evolving LLM Coder and Unit Tester via Reinforcement Learning
[2025-NeurIPS]· [Code] - ZeroCoder: Can LLMs Improve Code Generation Without Ground-Truth Supervision?
[2026-arXiv] - Learning to Solve and Verify: A Self-Play Framework for Code and Test Generation (Sol-Ver)
[2025-NeurIPS] - ACE: Self-Evolving LLM Coding Framework via Adversarial Unit Test Generation and Preference Optimization
[2026-arXiv] - Anchored Self-Play for Code Repair
[2026-ICML] - Absolute Zero: Reinforced Self-Play Reasoning with Zero Data
[2025-NeurIPS]· [Code] - OPD-Evolver: Cultivating Holistic Agent Evolver via On-Policy Distillation
[2026-arXiv]· [Code]
1.3.2 Environment-Reward RL
- Agent-RLVR: Training Software Engineering Agents via Guidance and Environment Rewards
[2026-ICLR] - SWE-RL: Advancing LLM Reasoning via Reinforcement Learning on Open Software Evolution
[2025-NeurIPS]· [Code] - Self-Improving Language Models for Evolutionary Program Synthesis: A Case Study on ARC-AGI (SOAR)
[2025-ICML]· [Code]
1.3.3 Harness Co-Evolution
- Harness-R1: Learning to Edit Executable Runtime Harnesses from Agent Failure Trajectories
[2026-arXiv]· [Code] - HELIX: Model-Harness Co-evolution for Recursive Self-Improvement
[2026-arXiv]· [Code]
📊 3. Benchmarks and Empirical Studies
This section brings together repository-level software engineering benchmarks and general coding benchmarks to assess coding capabilities, self-evolution benchmarks to evaluate agents' ability to improve themselves, and empirical studies to examine the performance gains, computational costs, and failure modes of self-evolving coding agents.
3.1 Repository-Level Software Engineering Benchmarks
- SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
[2024-ICLR] - SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?
[2026-ICML] - SWE-EVO: Benchmarking Coding Agents in Long-Horizon Software Evolution Scenarios
[2025-arXiv] - SWE-bench Multimodal: Do AI Systems Generalize to Visual Software Domains?
[2025-ICLR] - Multi-SWE-bench: A Multilingual Benchmark for Issue Resolving
[2025-NeurIPS Datasets and Benchmarks] - SWE-PolyBench: A Multi-Language Benchmark for Repository Level Evaluation of Coding Agents
[2025-arXiv] - SWE-bench Goes Live! (SWE-bench-Live)
[2025-NeurIPS Datasets and Benchmarks] - SWE-bench Multilingual
[2025-Benchmark] - BeyondSWE: Can Current Code Agent Survive Beyond Single-Repo Bug Fixing?
[2026-arXiv] - LoCoBench: A Benchmark for Long-Context Large Language Models in Complex Software Engineering
[2025-arXiv] - CoderEval: A Benchmark of Pragmatic Code Generation with Generative Pre-trained Models
[2024-ICSE] - DevEval: A Manually-Annotated Code Generation Benchmark Aligned with Real-World Code Repositories
[2024-ACL Findings] - SWE-QA: Can Language Models Answer Repository-level Code Questions?
[2026-ACL Findings] - LongCodeBench: Evaluating Coding LLMs at 1M Context Windows
[2025-COLM] - CRUST-Bench: A Comprehensive Benchmark for C-to-safe-Rust Transpilation
[2025-COLM] - PATCHEVAL: A New Benchmark for Evaluating LLMs on Patching Real-World Vulnerabilities
[2025-arXiv] - SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks
[2025-NeurIPS] - Vul4J: A Dataset of Reproducible Java Vulnerabilities Geared Towards the Study of Program Repair Techniques
[2022-MSR] - CRAVE: Code Review Agent Verdict Evaluation
[2025-Dataset] - Self-Evolving Multi-Agent Collaboration Networks for Software Development (rSDE-Bench)
[2025-ICLR] - GameCraft-Bench: Can Agents Build Playable Games End-to-End in a Real Game Engine?
[2026-arXiv] - ProgramBench: Can Language Models Rebuild Programs From Scratch?
[2026-arXiv] - FrontierSWE
[2026-Benchmark] - CompileBench: Can AI Compile 22-year-old Code?
[2025-Benchmark]
3.2 General Coding Benchmarks
- Evaluating Large Language Models Trained on Code (HumanEval)
[2021-arXiv] - Program Synthesis with Large Language Models (MBPP)
[2021-arXiv] - Measuring Coding Challenge Competence with APPS
[2021-NeurIPS Datasets and Benchmarks] - Competition-Level Code Generation with AlphaCode (CodeContests)
[2022-Science] - LiveCodeBench: Holistic and Contamination Free Evaluation of Large Language Models for Code
[2025-ICLR] - BigCodeBench: Benchmarking Code Generation with Diverse Function Calls and Complex Instructions
[2025-ICLR] - Is Your Code Generated by ChatGPT Really Correct? Rigorous Evaluation of Large Language Models for Code Generation (EvalPlus)
[2023-NeurIPS] - MultiPL-E: A Scalable and Extensible Approach to Benchmarking Neural Code Generation
[2023-IEEE TSE] - DS-1000: A Natural and Reliable Benchmark for Data Science Code Generation
[2023-ICML] - CRUXEval: A Benchmark for Code Reasoning, Understanding and Execution
[2024-ICML] - xCodeEval: A Large Scale Multilingual Multitask Benchmark for Code Understanding, Generation, Translation and Retrieval
[2024-ACL] - EffiBench-X: A Multi-Language Benchmark for Measuring Efficiency of LLM-Generated Code
[2025-NeurIPS Datasets and Benchmarks] - Aider Polyglot Benchmark
[2024-Benchmark] - Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces
[2026-ICLR] - Let It Flow: Agentic Crafting on Rock and Roll, Building the ROME Model within an Open Agentic Learning Ecosystem (Terminal-Bench Pro)
[2025-arXiv] - TerminalWorld: Benchmarking Agents on Real-World Terminal Tasks
[2026-arXiv] - DebugBench: Evaluating Debugging Capability of Large Language Models
[2024-ACL Findings] - Anchored Self-Play for Code Repair (BugSourceBench)
[2026-ICML] - CodeIF-Bench: Evaluating Instruction-Following Capabilities of Large Language Models in Interactive Code Generation
[2025-arXiv] - LongCoder: A Long-Range Pre-trained Language Model for Code Completion (LCC)
[2023-ICML] - EvoR: Evolving Retrieval for Code Generation (EvoR-bench)
[2024-EMNLP Findings] - Can LLM Already Serve as A Database Interface? A BIg Bench for Large-Scale Database Grounded Text-to-SQLs (BIRD)
[2023-NeurIPS Datasets and Benchmarks] - Spider 2.0: Evaluating Language Models on Real-World Enterprise Text-to-SQL Workflows
[2025-ICLR] - DA-Code: Agent Data Science Code Generation Benchmark for Large Language Models
[2024-EMNLP] - InterCode: Standardizing and Benchmarking Interactive Coding with Execution Feedback
[2023-NeurIPS Datasets and Benchmarks] - VerilogEval: Evaluating Large Language Models for Verilog Code Generation
[2023-ICCAD] - RTLLM: An Open-Source Benchmark for Design RTL Generation with Large Language Model
[2024-ASP-DAC] - Comprehensive Verilog Design Problems: A Next-Generation Benchmark Dataset for Evaluating Large Language Models and Agents on RTL Design and Verification (CVDP)
[2025-arXiv] - KernelBench: Can LLMs Write Efficient GPU Kernels?
[2025-ICML] - SOL-ExecBench: Speed-of-Light Benchmarking for Real-World GPU Kernels Against Hardware Limits
[2026-arXiv] - LiveBench: A Challenging, Contamination-Limited LLM Benchmark (Coding Subset)
[2025-ICLR] - SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks (Software Engineering Subset)
[2026-arXiv]
3.3 Self-Evolution Benchmarks
- HarnessDev: Can LLMs Create and Evolve Their Own Agent Harness?
[2026-arXiv] - EvoAgentBench: Benchmarking Agent Self-Evolution via Ability Transfer (Coding and Software Engineering Subsets)
[2026-arXiv] - SkillEvolBench: Benchmarking the Evolution from Episodic Experience to Procedural Skills (Code Modification Subset)
[2026-arXiv] - RSIBench-Data: Benchmarking Data-Centric Research for Recursive Self-Improvement
[2026-arXiv] - AI4AI-Bench: Benchmarking LLM Agents in Algorithmic Design for Recursive Self-Improvement
[2026-arXiv] - SWE-Bench-CL: Continual Learning for Coding Agents
[2025-arXiv]
3.4 Empirical Studies
- Rethinking the Evaluation of Harness Evolution for Agents
[2026-arXiv] - Harness Updating Is Not Harness Benefit: Disentangling Evolution Capabilities in Self-Evolving LLM Agents
[2026-arXiv] - Phantom Guardrails: When Self-Improving Agent Harnesses Fix Failures That Never Happened
[2026-arXiv] - Behind EvoMap: Characterizing a Self-Evolving Agent-to-Agent Collaboration Network
[2026-arXiv] - Don't Blame the Large Language Model: How Agent Harness Evolution Shapes Coding Agent Quality
[2026-arXiv] - The Scaffold Effect in Coding Agents: Harness Choice as a Hidden Variable in Coding-Agent Evaluation
[2026-arXiv] - Prompt-Induced Waste in Coding Agents: Reasoning, Effort, Harness Design, and End-to-End Cost
[2026-arXiv] - Harness Engineering: Anatomy, Architecture, and Evolution of Coding Agents -- A Source-Code Study of Eleven Systems
[2026-arXiv] - Self-Authored Verification Is Unreliable in Heuristic Self-Improving Agents
[2026-arXiv] - Memory Reward Inflation in Self-Improving LLM Agents
[2026-arXiv] - Auditing Harness Tampering in Self-Improving Agents
[2026-arXiv] - From Raw Experience to Skill Consumption: A Systematic Study of Model-Generated Agent Skills
[2026-arXiv] - Memory Transfer Learning: How Memories are Transferred Across Domains in Coding Agents
[2026-arXiv] - How Memory Management Impacts LLM Agents: An Empirical Study of Experience-Following Behavior
[2026-ACL]
🧩 4. Self-Evolving Coding Products
These products and open-source tools support persistent memory, reusable skills, context updates, and harness customization through automatic or user-guided refinement. The table summarizes adaptation targets and mechanisms. Inclusion reflects documented capabilities, not necessarily a fully autonomous, experimentally validated self-evolution loop.
Target legend: 🔵 Assets — Memory, Skill, Tool, Context (including environment adaptation) · 🟣 Architecture — Harness, Workflow, Multi-Agent.
| Product | Company / Year | Target | Mechanism in Practice | Resources |
|---|---|---|---|---|
| Prime Agent (PA) | Prime Intellect2026 | 🔵 AssetsMemory · Skill · Context🟣 Architecture Harness · Multi-Agent | Refines agent components from task trajectories. | Code |
| DeepSeek Harness (DSH) | DeepSeek2026 | 🟣 ArchitectureHarness | Tests plugins and creates presets through Creator Mode. | Code |
| Gemini CLI Auto Memory (GCAM) | Google2026 | 🔵 AssetsMemory · Skill | Proposes memory and skill updates for user review. | Changelog |
| GitHub Copilot Memory (GCM) | GitHub2026 | 🔵 AssetsMemory | Stores repository facts and validates them before reuse. | Announcement |
| Augment Agent / Cosmos Learning Flywheel (AA/CLF) | Augment Code2025–2026 | 🔵 AssetsMemory · Context | Distills team feedback into shared memory and context. | Memory review |
| Claude Code Auto Memory (CCAM) | Anthropic2026 | 🔵 AssetsMemory | Automatically saves corrections, preferences, and project learnings. | Changelog |
| Cursor Memories / Automations (CMA) | Cursor2025–2026 | 🔵 AssetsMemory | Retains useful context across sessions and automation runs. | Memories |
| Devin Session Insights / Knowledge / Playbooks (Devin SIKP) | Cognition2025–2026 | 🔵 AssetsMemory · Skill · Context | Uses session analysis to guide knowledge and configuration updates. | Advanced capabilities |
| Windsurf Cascade Memories (WCM) | Windsurf / Cognition2025–2026 | 🔵 AssetsMemory | Creates workspace memories and retrieves them when relevant. | Docs |
| OpenBlock Agent (OB-1) | OpenBlock Labs2026 | 🔵 AssetsMemory | Learns codebase patterns for subsequent tasks. | Waitlist |
| Letta Code | Letta2025–2026 | 🔵 AssetsMemory · Skill · Context | Reviews sessions to refine memory and context; versions skills. | Code |
| Hermes Agent | Nous Research2026 | 🔵 AssetsMemory · Skill | Creates skills from experience and refines them through reuse. | Skills Code |
| Kiro Web / Autonomous Agent | AWS2025–2026 | 🔵 AssetsMemory | Learns team conventions from code-review feedback. | Product |
| Replit Agent | Replit2025–2026 | 🔵 AssetsMemory · Skill · Context | Maintains replit.md and creates reusable skills. | Announcement |
| OpenClaw | OpenClaw Foundation / Community2026 | 🔵 AssetsMemory | Consolidates session notes into persistent memory. | Coding integration Code |
| Cline Memory Bank | Cline / Community2025 | 🔵 AssetsMemory · Context | Maintains structured project memory through configured instructions. | Documentation |
From memory to architecture: Most products adapt assets such as memory, skills, and context. Prime Agent and DeepSeek Harness also expose mechanisms for modifying the surrounding agent harness.
📚 5. Related Surveys
5.1 Surveys on Self-Evolving Agents
- A Survey of Self-Evolving Agents: What, When, How, and Where to Evolve on the Path to Artificial Super Intelligence
[2026-TMLR] - A Comprehensive Survey of Self-Evolving AI Agents: A New Paradigm Bridging Foundation Models and Lifelong Agentic Systems
[2025-arXiv] - A Systematic Survey of Self-Evolving Agents: From Model-Centric to Environment-Driven Co-Evolution
[2026-TechRxiv] - Self-Improvements in Modern Agentic Systems: A Survey
[2026-arXiv] - Self-Improving Agents in the Era of Experience: A Survey of Self- to Meta-Evolution
[2026-OpenReview] - A Survey on Self-Evolution of Large Language Models
[2024-arXiv] - Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering
[2026-arXiv] - Diving into Reliable Self-Evolving Agents: A Survey
[2026-OpenReview] - The Path to Recursive Self-Improving Agents: Foundation, Framework, and Future Directions
[2026-Preprints.org] - Self-Evolving Agents as Dynamic Graph Transformation: A Survey and New Perspective
[2026-arXiv]
5.2 Surveys on Coding Agents
- Large Language Model-Based Agents for Software Engineering: A Survey
[2025-TOSEM] - Agents in Software Engineering: Survey, Landscape, and Vision
[2025-Automated Software Engineering] - LLM-Based Multi-Agent Systems for Software Engineering: Literature Review, Vision, and the Road Ahead
[2025-TOSEM] - Large Language Models for Software Engineering: A Systematic Literature Review
[2024-TOSEM] - A Survey on Large Language Models for Code Generation
[2026-TOSEM] - Advances and Frontiers of LLM-Based Issue Resolution in Software Engineering: A Comprehensive Survey
[2026-arXiv]
Citation
@misc{zhou2026selfevolvingcodingagents,
      title={Self-Evolving Coding Agents},
      author={Hao Zhou and Haichuan Hu and Tianyu Luo and Ye Shang and Chunrong Fang and Zhenyu Chen and Liang Xiao and Quanjun Zhang},
      year={2026},
      eprint={2608.03392},
      archivePrefix={arXiv},
      primaryClass={cs.SE},
      url={https://arxiv.org/abs/2608.03392},
}
🤝 Contributions are welcome! If you find any missing or incorrect information, please feel free to open an issue or submit a pull request.