
The official paper summary of TMLR'25 paper "Survey of Video Diffusion Models: Foundations, Implementations, and Applications"
44
68 commits
updated Feb 2, 2026
README
Survey of Video Diffusion Models: Foundations, Implementations, and Applications

Yimu Wang1,*, Xuye Liu1,*, Wei Pang1,*, Li Ma3,*, Shuai Yuan2,*, Paul Debevec3, Ning Yu3,†
1University of Waterloo, 2Duke University, 3Netflix Eyeline Studios
*Contributed Equally, †Corresponding Author
Abstract
In this survey and github repository, we provide a comprehensive overview of the recent advances in video diffusion models. We cover the foundations of video generative models, including GANs, auto-regressive models, and diffusion models. We also discuss the learning foundations, including classic denoising diffusion models, flow matching, and training-free methods. Additionally, we explore various architectures, including UNet and diffusion transformers. We discuss the applications of video diffusion models, including video generation, enhancement, personalization, and 3D-aware video generation. Finally, we highlight the benefits of video diffusion models to other domains, such as video representation learning and video retrieval.
Moreover, to facilitate the understanding of video diffusion models, we provide a cheatsheet including commonly used training datasets, training engineering techniques, and evaluation metrics. We also provide a list of video diffusion models in academia and industry.
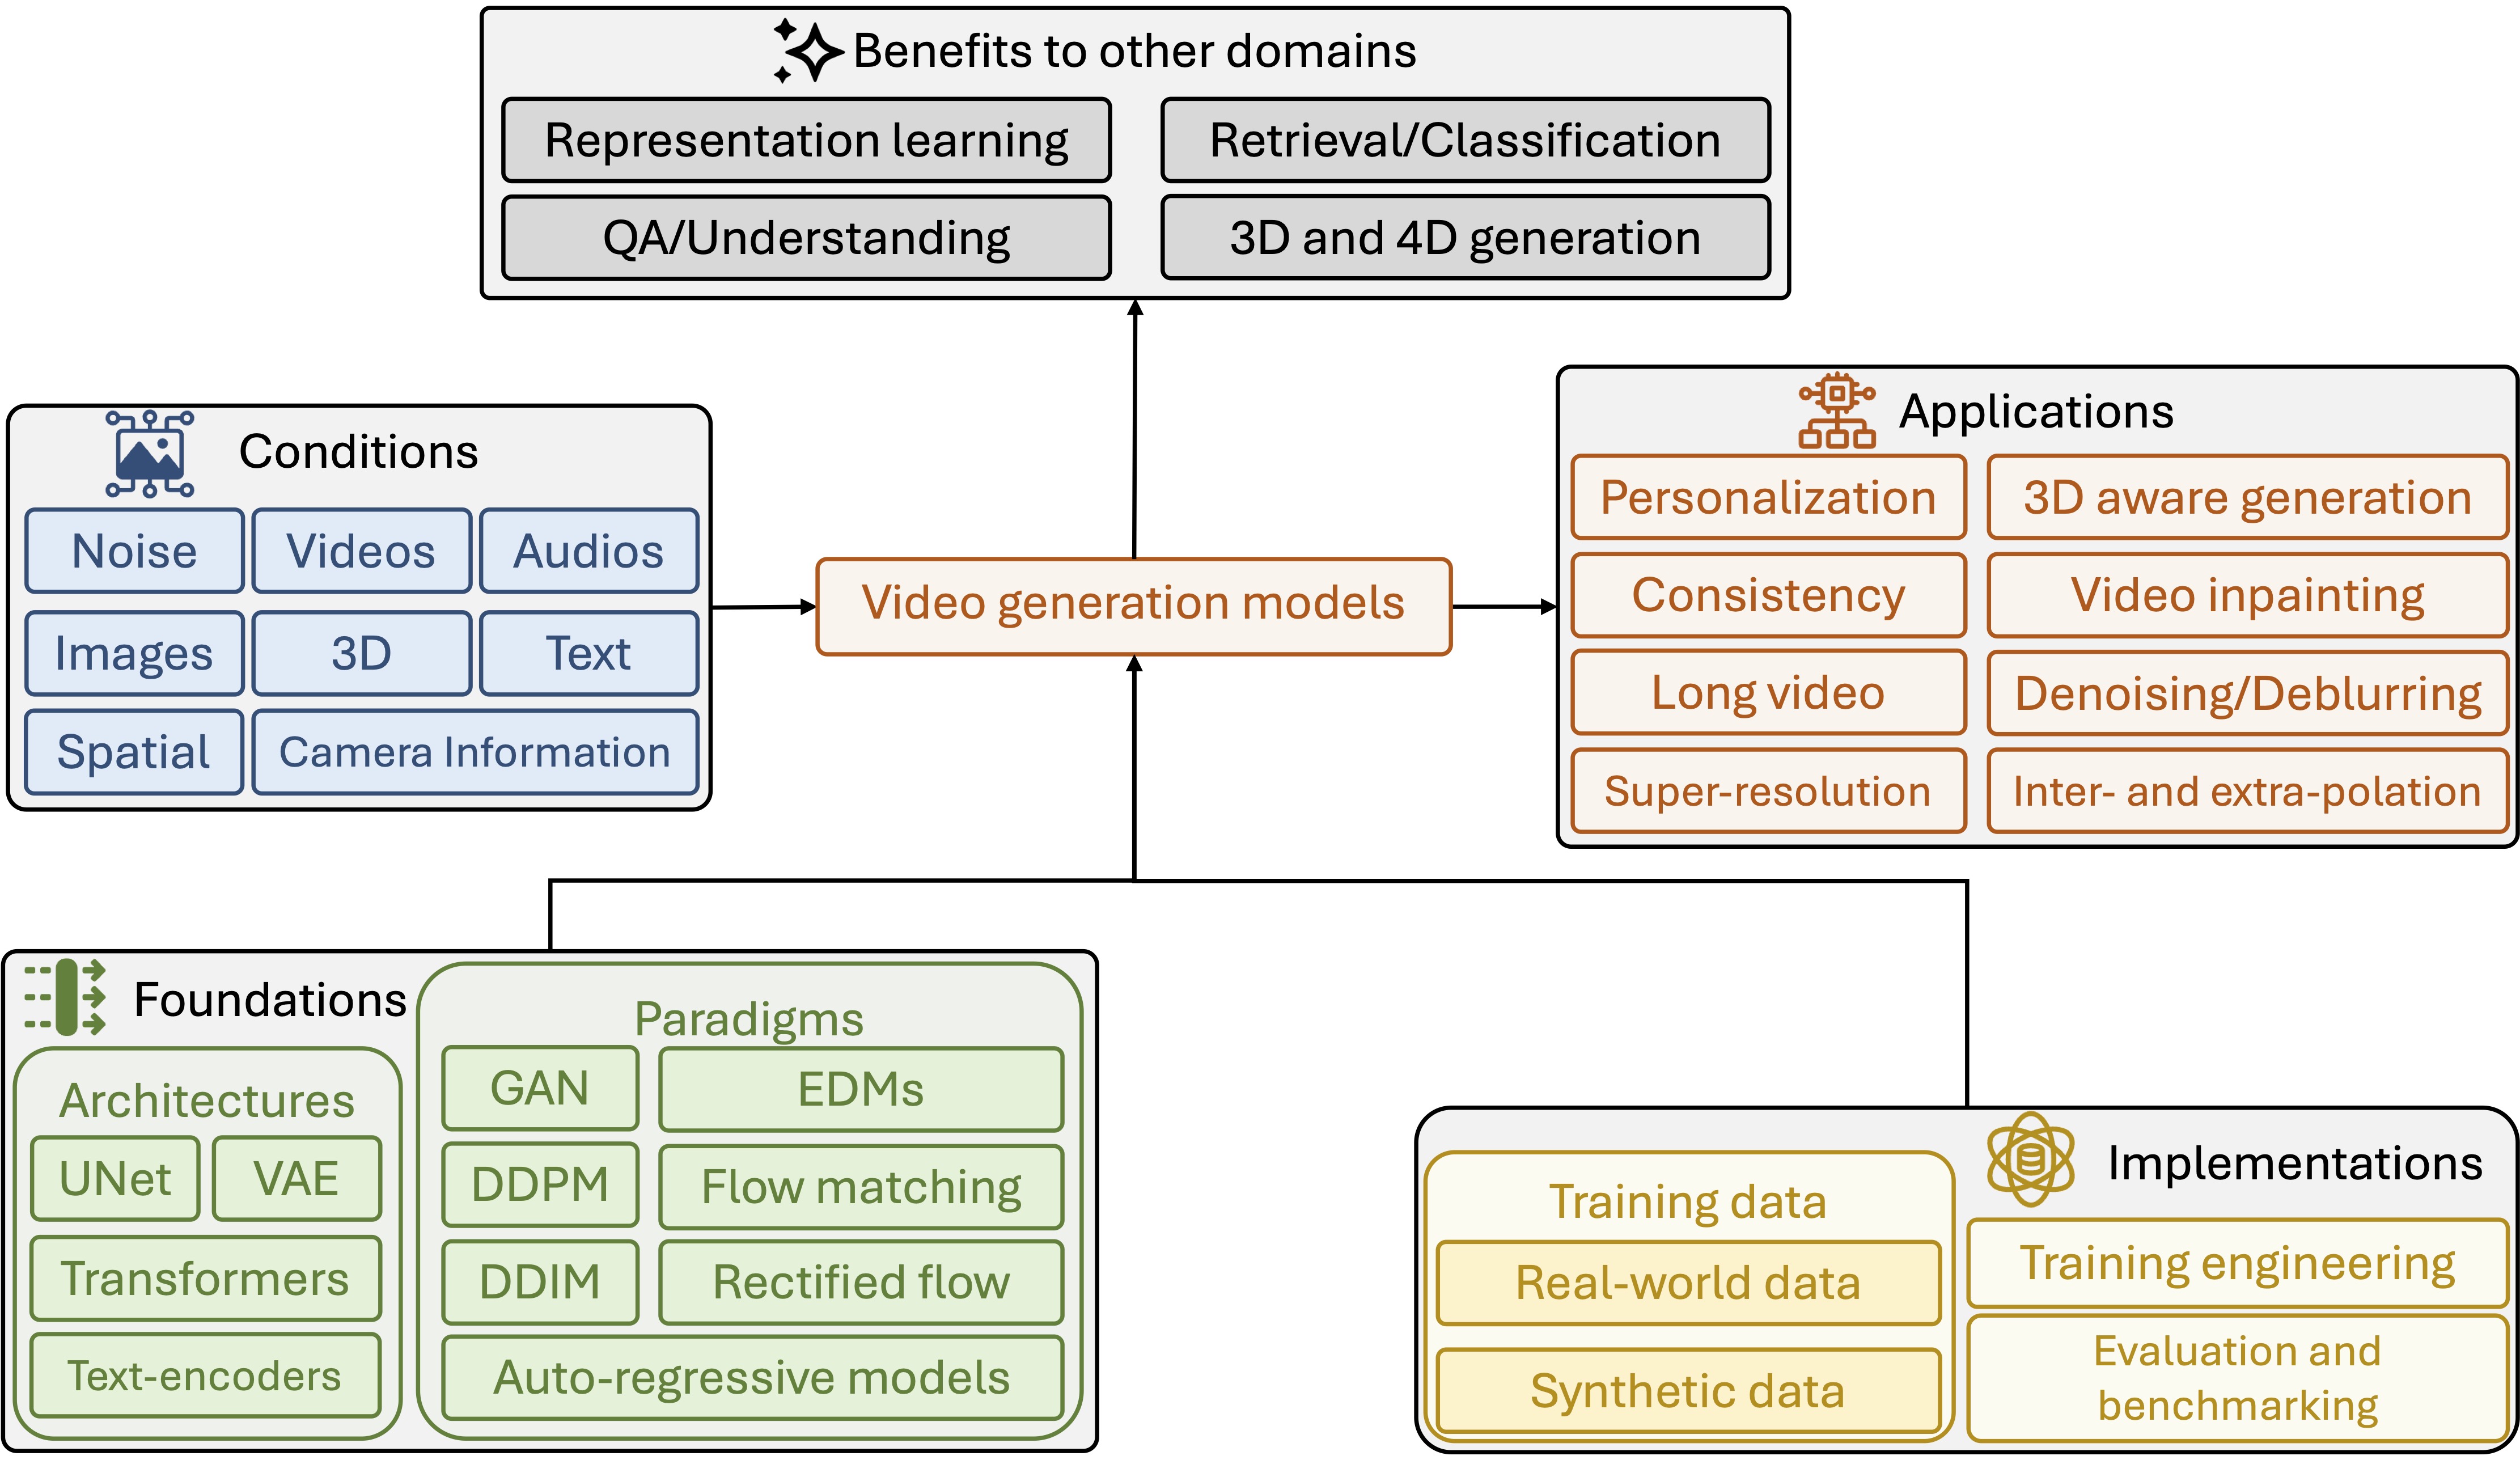
Table of Contents
- Foundations
- Implementation
- Applications
- Benefits to other domains
- Ethical considerations
- Citation
- Acknowledgement
Foundations
Video generative paradigms
GAN video models
Papers are listed generally in reverse order of their publication timestamps.


Auto-regressive video models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| CogVideo: Large-scale Pretraining for Text-to-Video Generation via Transformers |  |  |  | ICLR 2023 |
| Single Image Video Prediction with Auto-Regressive GANs | | - | - | Sensors 2022 |
| HARP: Autoregressive Latent Video Prediction with High-Fidelity Image Generator | | - | | ICIP 2022 |
| Long Video Generation with Time-Agnostic VQGAN and Time-Sensitive Transformer | |  | | ECCV 2022 |
| VideoGPT: Video Generation using VQ-VAE and Transformers | |  | | arXiv 2021 |
| Latent Video Transformer | |  | - | arXiv 2020 |
| Parallel Multiscale Autoregressive Density Estimation | | - | - | ICML 2017 |
| Video Pixel Networks | | - | - | ICML 2017 |
Video diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| CCEdit: Creative and Controllable Video Editing via Diffusion Models | | - | - | arXiv 2024 |
| Align Your Latents: High-Resolution Video Synthesis with Latent Diffusion Models | |  | | CVPR 2023 |
| Make-A-Video: Text-to-Video Generation without Text-Video Data | |  | | arXiv 2022 |
| MagicVideo: Efficient Video Generation with Latent Diffusion Models | | - | | arXiv 2022 |
| Imagen Video: High Definition Video Generation with Diffusion Models | | - | - | arXiv 2022 |
| Video Diffusion Models | |  | | arXiv 2022 |
| Cascaded Diffusion Models for High Fidelity Image Generation | | - | | JMLR 2022 |
| High-Resolution Image Synthesis with Latent Diffusion Models | |  | - | CVPR 2022 |
Auto-regressive video diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| From Slow Bidirectional to Fast Causal Video Generators | |  | | arXiv 2024 |
| Progressive Autoregressive Video Diffusion Models | |  | | arXiv 2024 |
| Pyramidal Flow Matching for Efficient Video Generative Modeling | |  | | arXiv 2024 |
| ART·V: Auto-Regressive Text-to-Video Generation with Diffusion Models | |  | | CVPR 2024 |
Learning foundations
Classic denoising diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Elucidating the Design Space of Diffusion-Based Generative Models | |  | - | NeurIPS 2022 |
| Denoising Diffusion Implicit Models | |  | - | ICLR 2021 |
| Improved Denoising Diffusion Probabilistic Models | |  | - | ICML 2021 |
| Denoising Diffusion Probabilistic Models | |  | | NeurIPS 2020 |
| Deep Unsupervised Learning using Nonequilibrium Thermodynamics | |  | - | ICML 2015 |
Flow matching and rectified flow
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Voicebox: Text-Guided Multilingual Universal Speech Generation at Scale | |  | | NeurIPS 2023 |
| Boosting Fast and High-Quality Speech Synthesis with Linear Diffusion | | - | - | ICASSP 2023 |
| InstaFlow: One Step is Enough for High-Quality Diffusion-Based Text-to-Image Generation | | - | - | ICLR 2024 |
| Stochastic Interpolants: A Unifying Framework for Flows and Diffusions | |  | - | arXiv 2023 |
| Flow Matching for Generative Modeling | | - | - | arXiv 2022 |
Learning from feedback and reward models
Papers are listed generally in reverse order of their publication timestamps.


One-shot and few-shot learning
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Make an Image Move: Few-Shot Based Video Generation Guided by CLIP | - | - | - | ICPR 2025 |
| LAMP: Learn A Motion Pattern for Few-Shot-Based Video Generation | |  | | arXiv 2023 |
| Tune-A-Video: One-Shot Tuning of Image Diffusion Models for Text-to-Video Generation | |  | | ICCV 2023 |
Training-free methods
Papers are listed generally in reverse order of their publication timestamps.


Token learning
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| DreamVideo-2: Zero-Shot Subject-Driven Video Customization with Precise Motion Control | | - | | arXiv 2024 |
| Animate-A-Story: Storytelling with Retrieval-Augmented Video Generation | | - | - | arXiv 2023 |
| An Image is Worth One Word: Personalizing Text-to-Image Generation using Textual Inversion | |  | | ICLR 2023 |
Guidances
Classifier guidance
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| CFG++: Manifold-Constrained Classifier Free Guidance for Diffusion Models | |  | | arXiv 2024 |
| LLM-grounded Video Diffusion Models | |  | | ICLR 2024 |
| Exploring Compositional Visual Generation with Latent Classifier Guidance | | - | - | CVPRW 2023 |
| Diffusion Models Beat GANs on Image Synthesis | | - | - | NeurIPS 2021 |
Classifier-free guidance
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Classifier-Free Diffusion Guidance | |  | | 2022 |
Diffusion model frameworks
Pixel diffusion and latent diffusion
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Latte: Latent Diffusion Transformer for Video Generation | |  | | TMLR 2025 |
| Show-1: Marrying Pixel and Latent Diffusion Models for Text-to-Video Generation | |  | | arXiv 2023 |
| Preserve Your Own Correlation: A Noise Prior for Video Diffusion Models | | - | - | ICCV 2023 |
| ModelScope Text-to-Video Technical Report | | - | | arXiv 2023 |
| Structure and Content-Guided Video Synthesis with Diffusion Models | | - | - | ICCV 2023 |
| Align Your Latents: High-Resolution Video Synthesis with Latent Diffusion Models | | | | CVPR 2023 |
| Text-To-4D Dynamic Scene Generation | | - | | arXiv 2023 |
Optical-flow-based diffusion models
Papers are listed generally in reverse order of their publication timestamps.


Noise scheduling
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Rethinking the Noise Schedule of Diffusion-Based Generative Models | | - | - | ICLR 2024 |
| On the Importance of Noise Scheduling for Diffusion Models | | - | - | arXiv 2023 |
| simple diffusion: End-to-end diffusion for high resolution images | |  | - | ICML 2023 |
| Elucidating the Design Space of Diffusion-Based Generative Models | | | - | NeurIPS 2022 |
| Improved Denoising Diffusion Probabilistic Models | | | - | ICML 2021 |
| Denoising Diffusion Probabilistic Models | | | | NeurIPS 2020 |
| Score-Based Generative Modeling through Stochastic Differential Equations | |  | - | ICLR 2021 |
Agent-based diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| VideoAgent: Self-Improving Video Generation | |  | | ICLR 2025 |
| Mora: Enabling Generalist Video Generation via A Multi-Agent Framework | |  | - | arXiv 2024 |
| MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework | |  | - | arXiv 2023 |
| AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversation Framework | | - | | arXiv 2023 |
| DriveGAN: Towards a Controllable High-Quality Neural Simulation | |  | | CVPR 2021 |
Architectures
UNet
Papers are listed generally in reverse order of their publication timestamps.

Diffusion transformers
Papers are listed generally in reverse order of their publication timestamps.


VAE for latent space compression
Papers are listed generally in reverse order of their publication timestamps.


Text encoders
Papers are listed generally in reverse order of their publication timestamps.


Implementation
Datasets
More datasets could be found on Pixabay, Mixkit, Pond5, Adobe Stock, Shutterstock, Getty, Coverr, Videvo, Depositphotos, Storyblocks, Dissolve, Freepik, Vimeo, and Envato. Also, there are some datasets at Midjourney V5.1 Cleaned Data, Unsplash-lite, AnimateBench, Pexels-400k, and LAION-AESTHETICS.


Training engineering
Papers are listed generally in reverse order of their publication timestamps.


Evaluation metrics and benchmarking findings
Papers are listed generally in reverse order of their publication timestamps.


Industry models
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Magic 1-for-1: Generating one minute video clips within one minute | |  | | arXiv 2025 |
| SkyReels v1: Human-centric video foundation model | |  | - | arXiv 2025 |
| Step-Video-T2V | | - | | arXiv 2024 |
| HunyuanVideo | | - | | arXiv 2024 |
| Sora | - | - | | 2024 |
| STIV | |  | | arXiv 2024 |
| LTX-Video | |  | | arXiv 2024 |
| Allegro | | | | arXiv 2024 |
| Jimeng | | - | | arXiv 2024 |
| Mochi 1 | | - | | arXiv 2024 |
| EasyAnimate | |  | | arXiv 2024 |
| Vidu | - | - | | 2024 |
| VideoCrafter2 | |  | | arXiv 2024 |
| VideoCrafter1 | | | | arXiv 2023 |
| Mira | | - | | arXiv 2024 |
| Hailuo AI | - | - | | 2024 |
| Lumiere | | - | | arXiv 2024 |
| VideoPoet | | - | | arXiv 2023 |
| LumaAI Ray 2 | - | - | | 2024 |
| LumaAI Dream Machine | - | - | | 2023 |
| Veo-2 | - | - | | 2024 |
| Veo-1 | - | - | | 2023 |
| Nova Real | - | - | | 2024 |
| Wanx 2.1 | - | - | | 2024 |
| Kling | - | - | | 2024 |
| Show-1 | | | | NeurIPS 2023 |
| MovieGen | | - | | arXiv 2024 |
| Pika | - | - | | 2023 |
| Vchitect-2.0 | - | - | | 2024 |
| Optis | |  | | NeurIPS 2023 |
| VLogger | |  | | ICCV 2023 |
| Seine | |  | | CVPR 2023 |
| Lavie | |  | | ICCV 2023 |
| MiracleVision | - | - | | 2023 |
| Phenaki | |  | | ICLR 2024 |
| W.A.L.T | | - | | arXiv 2024 |
| Imagen video | | - | | 2022 |
| GEN-3 Alpha | - | - | | 2024 |
| GEN-2 | - | - | | 2023 |
| GEN-1 | - | - | | 2022 |
Academia models


Applications
Conditions
Image condition
Papers are listed generally in reverse order of their publication timestamps.


Spatial condition
Papers are listed generally in reverse order of their publication timestamps.


Camera parameter condition
Papers are listed generally in reverse order of their publication timestamps.


Audio condition
Papers are listed generally in reverse order of their publication timestamps.


High-level video condition
Papers are listed generally in reverse order of their publication timestamps.


Other conditions
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Mind the Time: Temporally-Controlled Multi-Event Video Generation | | - | | CVPR 2025 |
| PhysGen: Rigid-Body Physics-Grounded Image-to-Video Generation | |  | | ECCV 2024 |
| MotionCraft: Physics-based Zero-Shot Video Generation | |  | | AAAI 2025 |
| VideoAgent: Long-form Video Understanding with Large Language Model as Agent | |  | | ECCV 2024 |
| Synthetic Generation of Face Videos with Plethysmograph Physiology | | - | - | CVPR 2022 |
Enhancement
Video denoising and deblurring
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Video restoration based on deep learning: a comprehensive survey | - | - | - | 2022 |
Video inpainting
Papers are listed generally in reverse order of their publication timestamps.


Video interpolation and extrapolation/prediction
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Video interpolation with diffusion models | | - | | CVPR 2024 |
| ToonCrafter: Generative Cartoon Interpolation | |  | | TOG 2024 |
| Ldmvfi: Video frame interpolation with latent diffusion models | |  | | AAAI 2024 |
| Tell me what happened: Unifying text-guided video completion via multimodal masked video generation | |  | | CVPR 2023 |
| MCVD - Masked Conditional Video Diffusion for Prediction | |  | | NeurIPS 2022 |
| Diffusion models for video prediction and infilling | |  | | TMLR 2022 |
Video super-resolution
Papers are listed generally in reverse order of their publication timestamps.


Combining multiple video enhancement tasks
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| UniPaint: Unified Space-time Video Inpainting via Mixture-of-Experts | | - | - | arXiv 2024 |
| VEnhancer: Generative Space-Time Enhancement for Video Generation | |  | | arXiv 2024 |
| MCVD - Masked Conditional Video Diffusion for Prediction | | | | NeurIPS 2022 |
Personalization
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Dynamic Concepts Personalization from Single Videos | | - | | SIGGRAPH 2025 |
| VideoAlchemy: Open-set Personalization in Video Generation | |  | | CVPR 2025 |
| [PersonalVideo: High ID-Fidelity V |
Truncated — view the full README on GitHub.
Contributors


Similar repos


The official paper summary of TMLR'25 paper "Survey of Video Diffusion Models: Foundations, Implementations, and Applications"
44
68 commits
updated Feb 2, 2026
README
Survey of Video Diffusion Models: Foundations, Implementations, and Applications
Yimu Wang1,*, Xuye Liu1,*, Wei Pang1,*, Li Ma3,*, Shuai Yuan2,*, Paul Debevec3, Ning Yu3,†
1University of Waterloo, 2Duke University, 3Netflix Eyeline Studios
*Contributed Equally, †Corresponding Author
Abstract
In this survey and github repository, we provide a comprehensive overview of the recent advances in video diffusion models. We cover the foundations of video generative models, including GANs, auto-regressive models, and diffusion models. We also discuss the learning foundations, including classic denoising diffusion models, flow matching, and training-free methods. Additionally, we explore various architectures, including UNet and diffusion transformers. We discuss the applications of video diffusion models, including video generation, enhancement, personalization, and 3D-aware video generation. Finally, we highlight the benefits of video diffusion models to other domains, such as video representation learning and video retrieval.
Moreover, to facilitate the understanding of video diffusion models, we provide a cheatsheet including commonly used training datasets, training engineering techniques, and evaluation metrics. We also provide a list of video diffusion models in academia and industry.
Table of Contents
- Foundations
- Implementation
- Applications
- Benefits to other domains
- Ethical considerations
- Citation
- Acknowledgement
Foundations
Video generative paradigms
GAN video models
Papers are listed generally in reverse order of their publication timestamps.
Auto-regressive video models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| CogVideo: Large-scale Pretraining for Text-to-Video Generation via Transformers | | | | ICLR 2023 |
| Single Image Video Prediction with Auto-Regressive GANs | | - | - | Sensors 2022 |
| HARP: Autoregressive Latent Video Prediction with High-Fidelity Image Generator | | - | | ICIP 2022 |
| Long Video Generation with Time-Agnostic VQGAN and Time-Sensitive Transformer | | | | ECCV 2022 |
| VideoGPT: Video Generation using VQ-VAE and Transformers | | | | arXiv 2021 |
| Latent Video Transformer | | | - | arXiv 2020 |
| Parallel Multiscale Autoregressive Density Estimation | | - | - | ICML 2017 |
| Video Pixel Networks | | - | - | ICML 2017 |
Video diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| CCEdit: Creative and Controllable Video Editing via Diffusion Models | | - | - | arXiv 2024 |
| Align Your Latents: High-Resolution Video Synthesis with Latent Diffusion Models | | | | CVPR 2023 |
| Make-A-Video: Text-to-Video Generation without Text-Video Data | | | | arXiv 2022 |
| MagicVideo: Efficient Video Generation with Latent Diffusion Models | | - | | arXiv 2022 |
| Imagen Video: High Definition Video Generation with Diffusion Models | | - | - | arXiv 2022 |
| Video Diffusion Models | | | | arXiv 2022 |
| Cascaded Diffusion Models for High Fidelity Image Generation | | - | | JMLR 2022 |
| High-Resolution Image Synthesis with Latent Diffusion Models | | | - | CVPR 2022 |
Auto-regressive video diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| From Slow Bidirectional to Fast Causal Video Generators | | | | arXiv 2024 |
| Progressive Autoregressive Video Diffusion Models | | | | arXiv 2024 |
| Pyramidal Flow Matching for Efficient Video Generative Modeling | | | | arXiv 2024 |
| ART·V: Auto-Regressive Text-to-Video Generation with Diffusion Models | | | | CVPR 2024 |
Learning foundations
Classic denoising diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Elucidating the Design Space of Diffusion-Based Generative Models | | | - | NeurIPS 2022 |
| Denoising Diffusion Implicit Models | | | - | ICLR 2021 |
| Improved Denoising Diffusion Probabilistic Models | | | - | ICML 2021 |
| Denoising Diffusion Probabilistic Models | | | | NeurIPS 2020 |
| Deep Unsupervised Learning using Nonequilibrium Thermodynamics | | | - | ICML 2015 |
Flow matching and rectified flow
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Voicebox: Text-Guided Multilingual Universal Speech Generation at Scale | | | | NeurIPS 2023 |
| Boosting Fast and High-Quality Speech Synthesis with Linear Diffusion | | - | - | ICASSP 2023 |
| InstaFlow: One Step is Enough for High-Quality Diffusion-Based Text-to-Image Generation | | - | - | ICLR 2024 |
| Stochastic Interpolants: A Unifying Framework for Flows and Diffusions | | | - | arXiv 2023 |
| Flow Matching for Generative Modeling | | - | - | arXiv 2022 |
Learning from feedback and reward models
Papers are listed generally in reverse order of their publication timestamps.
One-shot and few-shot learning
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Make an Image Move: Few-Shot Based Video Generation Guided by CLIP | - | - | - | ICPR 2025 |
| LAMP: Learn A Motion Pattern for Few-Shot-Based Video Generation | | | | arXiv 2023 |
| Tune-A-Video: One-Shot Tuning of Image Diffusion Models for Text-to-Video Generation | | | | ICCV 2023 |
Training-free methods
Papers are listed generally in reverse order of their publication timestamps.
Token learning
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| DreamVideo-2: Zero-Shot Subject-Driven Video Customization with Precise Motion Control | | - | | arXiv 2024 |
| Animate-A-Story: Storytelling with Retrieval-Augmented Video Generation | | - | - | arXiv 2023 |
| An Image is Worth One Word: Personalizing Text-to-Image Generation using Textual Inversion | | | | ICLR 2023 |
Guidances
Classifier guidance
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| CFG++: Manifold-Constrained Classifier Free Guidance for Diffusion Models | | | | arXiv 2024 |
| LLM-grounded Video Diffusion Models | | | | ICLR 2024 |
| Exploring Compositional Visual Generation with Latent Classifier Guidance | | - | - | CVPRW 2023 |
| Diffusion Models Beat GANs on Image Synthesis | | - | - | NeurIPS 2021 |
Classifier-free guidance
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Classifier-Free Diffusion Guidance | | | | 2022 |
Diffusion model frameworks
Pixel diffusion and latent diffusion
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Latte: Latent Diffusion Transformer for Video Generation | | | | TMLR 2025 |
| Show-1: Marrying Pixel and Latent Diffusion Models for Text-to-Video Generation | | | | arXiv 2023 |
| Preserve Your Own Correlation: A Noise Prior for Video Diffusion Models | | - | - | ICCV 2023 |
| ModelScope Text-to-Video Technical Report | | - | | arXiv 2023 |
| Structure and Content-Guided Video Synthesis with Diffusion Models | | - | - | ICCV 2023 |
| Align Your Latents: High-Resolution Video Synthesis with Latent Diffusion Models | | | | CVPR 2023 |
| Text-To-4D Dynamic Scene Generation | | - | | arXiv 2023 |
Optical-flow-based diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Noise scheduling
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Rethinking the Noise Schedule of Diffusion-Based Generative Models | | - | - | ICLR 2024 |
| On the Importance of Noise Scheduling for Diffusion Models | | - | - | arXiv 2023 |
| simple diffusion: End-to-end diffusion for high resolution images | | | - | ICML 2023 |
| Elucidating the Design Space of Diffusion-Based Generative Models | | | - | NeurIPS 2022 |
| Improved Denoising Diffusion Probabilistic Models | | | - | ICML 2021 |
| Denoising Diffusion Probabilistic Models | | | | NeurIPS 2020 |
| Score-Based Generative Modeling through Stochastic Differential Equations | | | - | ICLR 2021 |
Agent-based diffusion models
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| VideoAgent: Self-Improving Video Generation | | | | ICLR 2025 |
| Mora: Enabling Generalist Video Generation via A Multi-Agent Framework | | | - | arXiv 2024 |
| MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework | | | - | arXiv 2023 |
| AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversation Framework | | - | | arXiv 2023 |
| DriveGAN: Towards a Controllable High-Quality Neural Simulation | | | | CVPR 2021 |
Architectures
UNet
Papers are listed generally in reverse order of their publication timestamps.
Diffusion transformers
Papers are listed generally in reverse order of their publication timestamps.
VAE for latent space compression
Papers are listed generally in reverse order of their publication timestamps.
Text encoders
Papers are listed generally in reverse order of their publication timestamps.
Implementation
Datasets
More datasets could be found on Pixabay, Mixkit, Pond5, Adobe Stock, Shutterstock, Getty, Coverr, Videvo, Depositphotos, Storyblocks, Dissolve, Freepik, Vimeo, and Envato. Also, there are some datasets at Midjourney V5.1 Cleaned Data, Unsplash-lite, AnimateBench, Pexels-400k, and LAION-AESTHETICS.
Training engineering
Papers are listed generally in reverse order of their publication timestamps.
Evaluation metrics and benchmarking findings
Papers are listed generally in reverse order of their publication timestamps.
Industry models
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Magic 1-for-1: Generating one minute video clips within one minute | | | | arXiv 2025 |
| SkyReels v1: Human-centric video foundation model | | | - | arXiv 2025 |
| Step-Video-T2V | | - | | arXiv 2024 |
| HunyuanVideo | | - | | arXiv 2024 |
| Sora | - | - | | 2024 |
| STIV | | | | arXiv 2024 |
| LTX-Video | | | | arXiv 2024 |
| Allegro | | | | arXiv 2024 |
| Jimeng | | - | | arXiv 2024 |
| Mochi 1 | | - | | arXiv 2024 |
| EasyAnimate | | | | arXiv 2024 |
| Vidu | - | - | | 2024 |
| VideoCrafter2 | | | | arXiv 2024 |
| VideoCrafter1 | | | | arXiv 2023 |
| Mira | | - | | arXiv 2024 |
| Hailuo AI | - | - | | 2024 |
| Lumiere | | - | | arXiv 2024 |
| VideoPoet | | - | | arXiv 2023 |
| LumaAI Ray 2 | - | - | | 2024 |
| LumaAI Dream Machine | - | - | | 2023 |
| Veo-2 | - | - | | 2024 |
| Veo-1 | - | - | | 2023 |
| Nova Real | - | - | | 2024 |
| Wanx 2.1 | - | - | | 2024 |
| Kling | - | - | | 2024 |
| Show-1 | | | | NeurIPS 2023 |
| MovieGen | | - | | arXiv 2024 |
| Pika | - | - | | 2023 |
| Vchitect-2.0 | - | - | | 2024 |
| Optis | | | | NeurIPS 2023 |
| VLogger | | | | ICCV 2023 |
| Seine | | | | CVPR 2023 |
| Lavie | | | | ICCV 2023 |
| MiracleVision | - | - | | 2023 |
| Phenaki | | | | ICLR 2024 |
| W.A.L.T | | - | | arXiv 2024 |
| Imagen video | | - | | 2022 |
| GEN-3 Alpha | - | - | | 2024 |
| GEN-2 | - | - | | 2023 |
| GEN-1 | - | - | | 2022 |
Academia models
Applications
Conditions
Image condition
Papers are listed generally in reverse order of their publication timestamps.
Spatial condition
Papers are listed generally in reverse order of their publication timestamps.
Camera parameter condition
Papers are listed generally in reverse order of their publication timestamps.
Audio condition
Papers are listed generally in reverse order of their publication timestamps.
High-level video condition
Papers are listed generally in reverse order of their publication timestamps.
Other conditions
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Mind the Time: Temporally-Controlled Multi-Event Video Generation | | - | | CVPR 2025 |
| PhysGen: Rigid-Body Physics-Grounded Image-to-Video Generation | | | | ECCV 2024 |
| MotionCraft: Physics-based Zero-Shot Video Generation | | | | AAAI 2025 |
| VideoAgent: Long-form Video Understanding with Large Language Model as Agent | | | | ECCV 2024 |
| Synthetic Generation of Face Videos with Plethysmograph Physiology | | - | - | CVPR 2022 |
Enhancement
Video denoising and deblurring
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Video restoration based on deep learning: a comprehensive survey | - | - | - | 2022 |
Video inpainting
Papers are listed generally in reverse order of their publication timestamps.
Video interpolation and extrapolation/prediction
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Video interpolation with diffusion models | | - | | CVPR 2024 |
| ToonCrafter: Generative Cartoon Interpolation | | | | TOG 2024 |
| Ldmvfi: Video frame interpolation with latent diffusion models | | | | AAAI 2024 |
| Tell me what happened: Unifying text-guided video completion via multimodal masked video generation | | | | CVPR 2023 |
| MCVD - Masked Conditional Video Diffusion for Prediction | | | | NeurIPS 2022 |
| Diffusion models for video prediction and infilling | | | | TMLR 2022 |
Video super-resolution
Papers are listed generally in reverse order of their publication timestamps.
Combining multiple video enhancement tasks
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| UniPaint: Unified Space-time Video Inpainting via Mixture-of-Experts | | - | - | arXiv 2024 |
| VEnhancer: Generative Space-Time Enhancement for Video Generation | | | | arXiv 2024 |
| MCVD - Masked Conditional Video Diffusion for Prediction | | | | NeurIPS 2022 |
Personalization
Papers are listed generally in reverse order of their publication timestamps.
Title | arXiv | GitHub | Website | Conference & Year |
|---|---|---|---|---|
| Dynamic Concepts Personalization from Single Videos | | - | | SIGGRAPH 2025 |
| VideoAlchemy: Open-set Personalization in Video Generation | | | | CVPR 2025 |
| [PersonalVideo: High ID-Fidelity V |
Truncated — view the full README on GitHub.