OpenThinkIMG is an end-to-end open-source framework that empowers LVLMs to think with images.
See the code



"The eye sees only what the mind is prepared to comprehend." – Robertson Davies
Humans don't just passively observe; we actively engage with visual information, sketching, highlighting, and manipulating it to understand. OpenThinkIMG aims to bring this interactive visual cognition to AI, enabling agents that can genuinely "think with images."
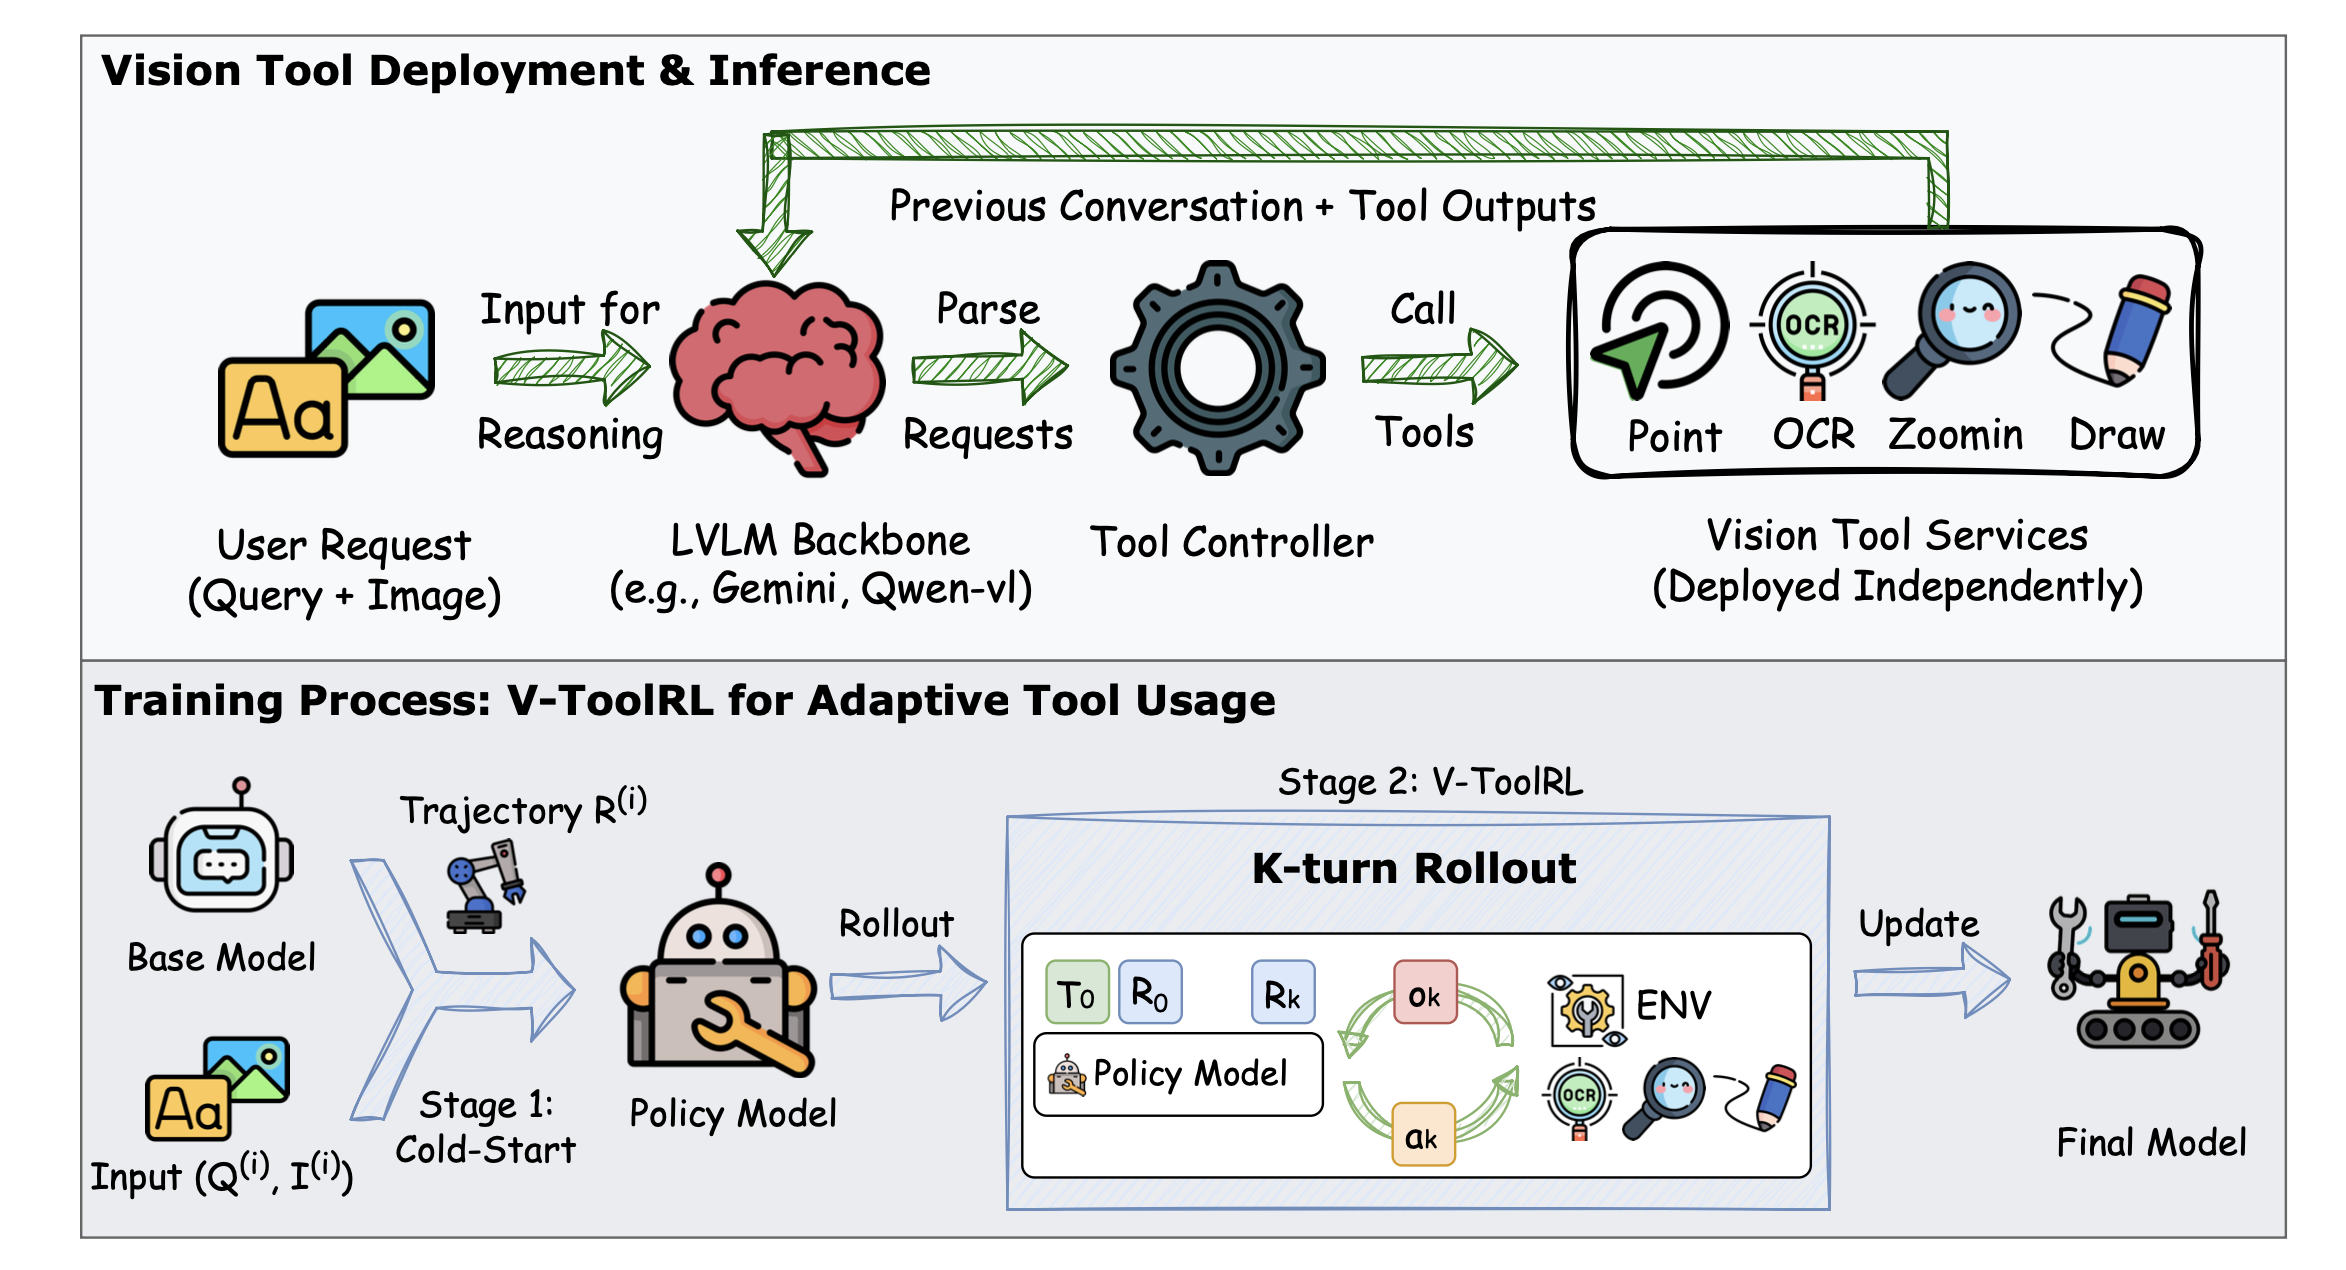
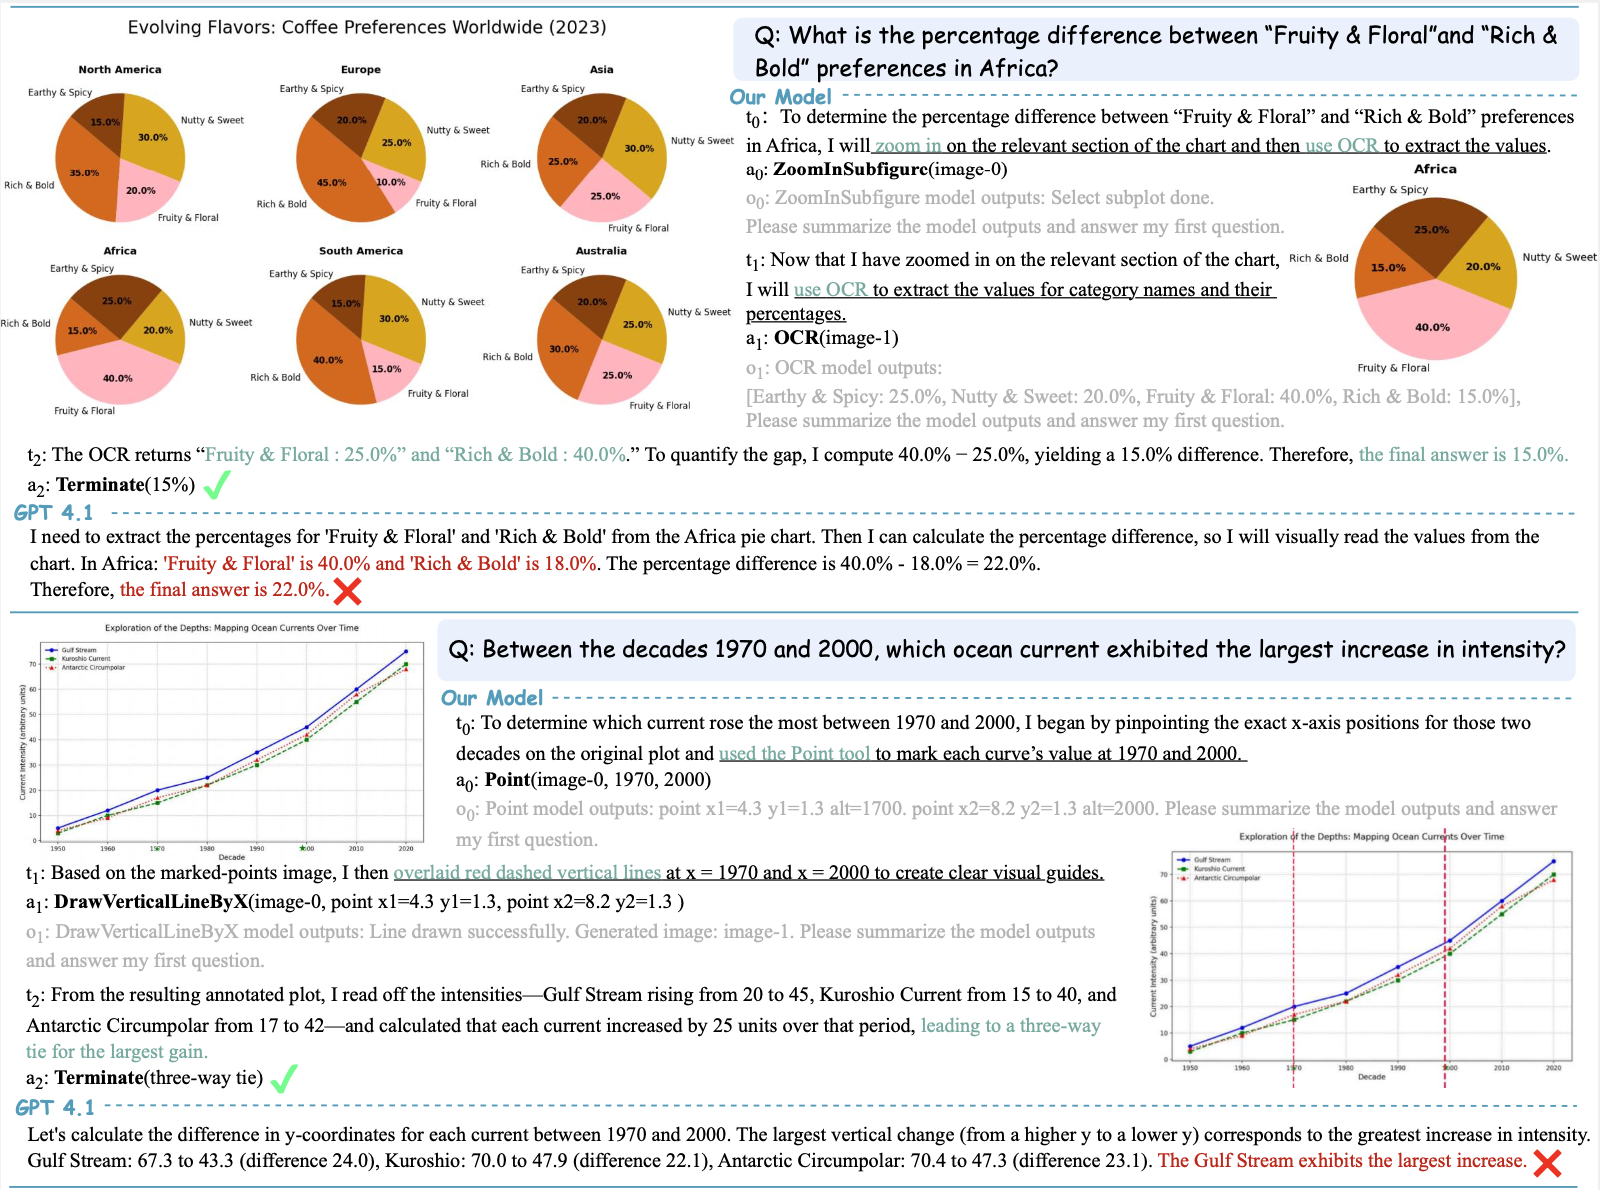
OpenThinkIMG is an end-to-end open-source framework that empowers Large Vision-Language Models (LVLMs) to think with images. It features:
Our goal is to enable AI agents to interactively use visual tools to decompose, analyze, and solve complex visual problems, moving beyond passive observation towards active visual cognition.
Current LVLMs excel at many tasks but often struggle when:
OpenThinkIMG addresses these challenges by:
OpenThinkIMG is currently an alpha release but is actively being developed. The core end-to-end system, including tool integration, trajectory generation, SFT (Cold-Start), and V-ToolRL training, is functional and can be used to replicate the results in our paper.
The project team is actively working on the following key milestones:
We welcome contributions and feedback to help us achieve these goals!
| Tool | Input | Output | Description |
|---|---|---|---|
| GroundingDINO | image + text query | bounding boxes | Object detection producing boxes for any target |
| SAM | image + bounding box | segmentation mask | Generates precise segmentation masks based on provided regions |
| OCR | image | text strings + bounding boxes | Optical character recognition for extracting text from images |
| Crop | image + region coordinates | cropped image | Extracts a sub-region of the image for focused analysis |
| Point | image + target description | point coordinates | Uses a model to predict the location of a specified object |
| DrawHorizontalLineByY | image + Y-coordinate | annotated image | Draws a horizontal line at the given Y-coordinate |
| DrawVerticalLineByX | image + X-coordinate | annotated image | Draws a vertical line at the given X-coordinate |
| ZoominSubplot | image + description (title/pos) | subplot images | Zoomin subplot(s) based on description |
| SegmentRegionAroundPoint | image + point coordinate | localized mask | Refines segmentation around a specified point |
💡 More vision tools are coming soon!
Our V-ToolRL approach significantly boosts performance:
| Model | Method | Accuracy (%) |
|---|---|---|
| GPT-4.1 | Zero-shot | 50.71 |
| Gemini-2.0-flash-exp | Zero-shot | 68.20 |
| --- | --- | --- |
| CogCom | SFT (CoM) | 15.07 |
| TACO | SFT (CoTA) | 30.50 |
| --- | --- | --- |
| Qwen2-vl-2B | Zero-shot | 29.56 |
| Qwen2-vl-2B-SFT | SFT | 45.67 |
| Text-based RL | RL (No Vis) | 51.63 |
| V-ToolRL | V-ToolRL | 59.39 |
V-ToolRL not only enhances our base model by +29.83 points but also outperforms other open-source tool-augmented agents and even strong closed-source models like GPT-4.1.
We provide a general setup that works across most tools. Individual tools may have specific requirements (to be released separately).
# Clone the repository
git clone [email protected]:zhaochen0110/Tool-Factory.git
cd Tool-Factory

# [Optional] Create a clean Conda environment
conda create -n tool-server python=3.10
conda activate tool-server

# Install PyTorch and dependencies (make sure CUDA version matches)
conda install pytorch==2.0.1 torchvision==0.15.2 torchaudio==2.0.2 pytorch-cuda=11.8 -c pytorch -c nvidia

# Install remaining dependencies
pip install -r tool_server_requirements.txt
pip install -e .
💡 Note: The
requirements.txtis tailored for inference & evaluation. For training, refer to the Training Section for additional dependencies.
If you encounter issues, check out our 📄 Documentation.
To enable tool-enhanced inference, start all vision tools before using the inferencer. Each tool runs independently and is launched via a unified config.
## First, modify the config to adapt to your own environment
## tool_server/tool_workers/scripts/launch_scripts/config/all_service_szc.yaml

## Start all services
cd tool_server/tool_workers/scripts/launch_scripts
python start_server_config.py --config ./config/all_service.yaml

## Press control + C to shutdown all services automatically.
accelerate launch  --config_file  ${accelerate_config} \
-m tool_server.tf_eval \
--model qwen2vl \
--model_args pretrained=Qwen/Qwen2-VL-7B-Instruct \
--task_name chartgemma \
--verbosity INFO \
--output_path ./tool_server/tf_eval/scripts/logs/results/chartgemma/qwen2vl.jsonl \
--batch_size 2 \
--max_rounds 3 \
--stop_token <stop>
accelerate launch  --config_file  ${accelerate_config} \
-m tool_server.tf_eval \
--config ${config_file}
- model_args:
    model: qwen2vl
    model_args: pretrained=Qwen/Qwen2-VL-7B-Instruct
    batch_size: 2
    max_rounds: 3
    stop_token: <stop>
  task_args:
    task_name: chartgemma
    resume_from_ckpt:
      chartgemma: ./tool_server/tf_eval/scripts/logs/ckpt/chartgemma/qwen2vl.jsonl
    save_to_ckpt:
      chartgemma: ./tool_server/tf_eval/scripts/logs/ckpt/chartgemma/qwen2vl.jsonl
  script_args:
    verbosity: INFO
    output_path: ./tool_server/tf_eval/scripts/logs/results/chartgemma/qwen2vl.jsonl
For detailed information and config setting please refer to our documentation.
Once the vision tools are properly deployed, we provide a flexible training pipeline to teach models how to plan and invoke tools effectively through SFT and our proposed V-ToolRL methods.
Our training pipeline builds on the solid foundation of OpenR1, integrating visual tools as external reasoning capabilities.
To run the training code, make sure to install the additional required packages:
pip install -r requirements_train.txt
We provide a customized implementation of V-ToolRL for training models to leverage vision tools dynamically in complex tasks.
torchrun --nproc_per_node=${nproc_per_node} \
    --nnodes="1" \
    --node_rank="0" \
    --master_addr="127.0.0.1" \
    --master_port=${master_port} \
    src/open_r1/tool_grpo.py --use_vllm True \
    --output_dir ${output_dir} \
    --model_name_or_path ${model_path} \
    --dataset_name ${data_path} \
    --max_prompt_length 16000 \
    --max_completion_length 2048 \
    --temperature 1.0 \
    --seed 42 \
    --learning_rate 1e-6 \
    --num_generations 8 \
    --lr_scheduler_type "constant" \
    --vllm_gpu_memory_utilization 0.8 \
    --deepspeed ${DS_CONFIG} \
    --per_device_train_batch_size 2 \
    --gradient_accumulation_steps 12 \
    --logging_steps 1 \
    --bf16 true \
    --report_to wandb \
    --gradient_checkpointing true \
    --attn_implementation flash_attention_2 \
    --max_pixels 200000 \
    --num_train_epochs 1 \
    --run_name $RUN_NAME \
    --save_steps 100 \
    --save_only_model true \
    --controller_addr http://SH-IDCA1404-10-140-54-15:20001 \
    --use_tool true
📈 This helps the model learn dynamic planning & tool invocation using environment feedback.
We also support supervised fine-tuning for training models on curated tool usage demonstrations. Modify the config according to your use case:
    accelerate launch --num_machines 1 --num_processes 6 --main_process_port 29502 --multi_gpu\
    src/open_r1/sft.py \
    --output_dir ${output_dir} \
    --model_name_or_path ${model_path} \
    --dataset_name ${data_path} \
    --seed 42 \
    --learning_rate 2e-5 \
    --max_seq_length 4096 \
    --deepspeed config/deepspeed/ds_z3_offload_config.json \
    --per_device_train_batch_size 2 \
    --gradient_accumulation_steps 8 \
    --logging_steps 1 \
    --report_to wandb \
    --gradient_checkpointing true \
    --attn_implementation flash_attention_2 \
    --bf16 \
    --num_train_epochs 2 \
    --run_name $RUN_NAME \
    --save_steps 100 \
    --warmup_ratio 0.1 \
    --save_only_model true
We welcome contributions of all kinds! In our Documentation you’ll find detailed guides for:
To contribute:
feature/new-vision-tool).tests/.We thank the Visual Sketchpad and TACO teams for inspiring our vision-driven reasoning paradigm.
Please cite the following if you find OpenThinkIMG helpful:
@article{su2025openthinkimg,
  title={OpenThinkIMG: Learning to Think with Images via Visual Tool Reinforcement Learning},
  author={Su, Zhaochen and Li, Linjie and Song, Mingyang and Hao, Yunzhuo and Yang, Zhengyuan and Zhang, Jun and Chen, Guanjie and Gu, Jiawei and Li, Juntao and Qu, Xiaoye and others},
  journal={arXiv preprint arXiv:2505.08617},
  year={2025}
}
830 followers · starred Jul 2025
1,306 followers · starred May 2025
43 followers · starred May 2025
253 followers · starred May 2025
OpenThinkIMG is an end-to-end open-source framework that empowers LVLMs to think with images.
See the code
"The eye sees only what the mind is prepared to comprehend." – Robertson Davies
Humans don't just passively observe; we actively engage with visual information, sketching, highlighting, and manipulating it to understand. OpenThinkIMG aims to bring this interactive visual cognition to AI, enabling agents that can genuinely "think with images."
OpenThinkIMG is an end-to-end open-source framework that empowers Large Vision-Language Models (LVLMs) to think with images. It features:
Our goal is to enable AI agents to interactively use visual tools to decompose, analyze, and solve complex visual problems, moving beyond passive observation towards active visual cognition.
Current LVLMs excel at many tasks but often struggle when:
OpenThinkIMG addresses these challenges by:
OpenThinkIMG is currently an alpha release but is actively being developed. The core end-to-end system, including tool integration, trajectory generation, SFT (Cold-Start), and V-ToolRL training, is functional and can be used to replicate the results in our paper.
The project team is actively working on the following key milestones:
We welcome contributions and feedback to help us achieve these goals!
| Tool | Input | Output | Description |
|---|---|---|---|
| GroundingDINO | image + text query | bounding boxes | Object detection producing boxes for any target |
| SAM | image + bounding box | segmentation mask | Generates precise segmentation masks based on provided regions |
| OCR | image | text strings + bounding boxes | Optical character recognition for extracting text from images |
| Crop | image + region coordinates | cropped image | Extracts a sub-region of the image for focused analysis |
| Point | image + target description | point coordinates | Uses a model to predict the location of a specified object |
| DrawHorizontalLineByY | image + Y-coordinate | annotated image | Draws a horizontal line at the given Y-coordinate |
| DrawVerticalLineByX | image + X-coordinate | annotated image | Draws a vertical line at the given X-coordinate |
| ZoominSubplot | image + description (title/pos) | subplot images | Zoomin subplot(s) based on description |
| SegmentRegionAroundPoint | image + point coordinate | localized mask | Refines segmentation around a specified point |
💡 More vision tools are coming soon!
Our V-ToolRL approach significantly boosts performance:
| Model | Method | Accuracy (%) |
|---|---|---|
| GPT-4.1 | Zero-shot | 50.71 |
| Gemini-2.0-flash-exp | Zero-shot | 68.20 |
| --- | --- | --- |
| CogCom | SFT (CoM) | 15.07 |
| TACO | SFT (CoTA) | 30.50 |
| --- | --- | --- |
| Qwen2-vl-2B | Zero-shot | 29.56 |
| Qwen2-vl-2B-SFT | SFT | 45.67 |
| Text-based RL | RL (No Vis) | 51.63 |
| V-ToolRL | V-ToolRL | 59.39 |
V-ToolRL not only enhances our base model by +29.83 points but also outperforms other open-source tool-augmented agents and even strong closed-source models like GPT-4.1.
We provide a general setup that works across most tools. Individual tools may have specific requirements (to be released separately).
# Clone the repository
git clone [email protected]:zhaochen0110/Tool-Factory.git
cd Tool-Factory

# [Optional] Create a clean Conda environment
conda create -n tool-server python=3.10
conda activate tool-server

# Install PyTorch and dependencies (make sure CUDA version matches)
conda install pytorch==2.0.1 torchvision==0.15.2 torchaudio==2.0.2 pytorch-cuda=11.8 -c pytorch -c nvidia

# Install remaining dependencies
pip install -r tool_server_requirements.txt
pip install -e .
💡 Note: The
requirements.txtis tailored for inference & evaluation. For training, refer to the Training Section for additional dependencies.
If you encounter issues, check out our 📄 Documentation.
To enable tool-enhanced inference, start all vision tools before using the inferencer. Each tool runs independently and is launched via a unified config.
## First, modify the config to adapt to your own environment
## tool_server/tool_workers/scripts/launch_scripts/config/all_service_szc.yaml

## Start all services
cd tool_server/tool_workers/scripts/launch_scripts
python start_server_config.py --config ./config/all_service.yaml

## Press control + C to shutdown all services automatically.
accelerate launch  --config_file  ${accelerate_config} \
-m tool_server.tf_eval \
--model qwen2vl \
--model_args pretrained=Qwen/Qwen2-VL-7B-Instruct \
--task_name chartgemma \
--verbosity INFO \
--output_path ./tool_server/tf_eval/scripts/logs/results/chartgemma/qwen2vl.jsonl \
--batch_size 2 \
--max_rounds 3 \
--stop_token <stop>
accelerate launch  --config_file  ${accelerate_config} \
-m tool_server.tf_eval \
--config ${config_file}
- model_args:
    model: qwen2vl
    model_args: pretrained=Qwen/Qwen2-VL-7B-Instruct
    batch_size: 2
    max_rounds: 3
    stop_token: <stop>
  task_args:
    task_name: chartgemma
    resume_from_ckpt:
      chartgemma: ./tool_server/tf_eval/scripts/logs/ckpt/chartgemma/qwen2vl.jsonl
    save_to_ckpt:
      chartgemma: ./tool_server/tf_eval/scripts/logs/ckpt/chartgemma/qwen2vl.jsonl
  script_args:
    verbosity: INFO
    output_path: ./tool_server/tf_eval/scripts/logs/results/chartgemma/qwen2vl.jsonl
For detailed information and config setting please refer to our documentation.
Once the vision tools are properly deployed, we provide a flexible training pipeline to teach models how to plan and invoke tools effectively through SFT and our proposed V-ToolRL methods.
Our training pipeline builds on the solid foundation of OpenR1, integrating visual tools as external reasoning capabilities.
To run the training code, make sure to install the additional required packages:
pip install -r requirements_train.txt
We provide a customized implementation of V-ToolRL for training models to leverage vision tools dynamically in complex tasks.
torchrun --nproc_per_node=${nproc_per_node} \
    --nnodes="1" \
    --node_rank="0" \
    --master_addr="127.0.0.1" \
    --master_port=${master_port} \
    src/open_r1/tool_grpo.py --use_vllm True \
    --output_dir ${output_dir} \
    --model_name_or_path ${model_path} \
    --dataset_name ${data_path} \
    --max_prompt_length 16000 \
    --max_completion_length 2048 \
    --temperature 1.0 \
    --seed 42 \
    --learning_rate 1e-6 \
    --num_generations 8 \
    --lr_scheduler_type "constant" \
    --vllm_gpu_memory_utilization 0.8 \
    --deepspeed ${DS_CONFIG} \
    --per_device_train_batch_size 2 \
    --gradient_accumulation_steps 12 \
    --logging_steps 1 \
    --bf16 true \
    --report_to wandb \
    --gradient_checkpointing true \
    --attn_implementation flash_attention_2 \
    --max_pixels 200000 \
    --num_train_epochs 1 \
    --run_name $RUN_NAME \
    --save_steps 100 \
    --save_only_model true \
    --controller_addr http://SH-IDCA1404-10-140-54-15:20001 \
    --use_tool true
📈 This helps the model learn dynamic planning & tool invocation using environment feedback.
We also support supervised fine-tuning for training models on curated tool usage demonstrations. Modify the config according to your use case:
    accelerate launch --num_machines 1 --num_processes 6 --main_process_port 29502 --multi_gpu\
    src/open_r1/sft.py \
    --output_dir ${output_dir} \
    --model_name_or_path ${model_path} \
    --dataset_name ${data_path} \
    --seed 42 \
    --learning_rate 2e-5 \
    --max_seq_length 4096 \
    --deepspeed config/deepspeed/ds_z3_offload_config.json \
    --per_device_train_batch_size 2 \
    --gradient_accumulation_steps 8 \
    --logging_steps 1 \
    --report_to wandb \
    --gradient_checkpointing true \
    --attn_implementation flash_attention_2 \
    --bf16 \
    --num_train_epochs 2 \
    --run_name $RUN_NAME \
    --save_steps 100 \
    --warmup_ratio 0.1 \
    --save_only_model true
We welcome contributions of all kinds! In our Documentation you’ll find detailed guides for:
To contribute:
feature/new-vision-tool).tests/.We thank the Visual Sketchpad and TACO teams for inspiring our vision-driven reasoning paradigm.
Please cite the following if you find OpenThinkIMG helpful:
@article{su2025openthinkimg,
  title={OpenThinkIMG: Learning to Think with Images via Visual Tool Reinforcement Learning},
  author={Su, Zhaochen and Li, Linjie and Song, Mingyang and Hao, Yunzhuo and Yang, Zhengyuan and Zhang, Jun and Chen, Guanjie and Gu, Jiawei and Li, Juntao and Qu, Xiaoye and others},
  journal={arXiv preprint arXiv:2505.08617},
  year={2025}
}
830 followers · starred Jul 2025
1,306 followers · starred May 2025
43 followers · starred May 2025
253 followers · starred May 2025