ICML 2026 Accepted · Tool-augmented medical MLLM · Think with images · Segmentation and zoom-in grounded reasoning


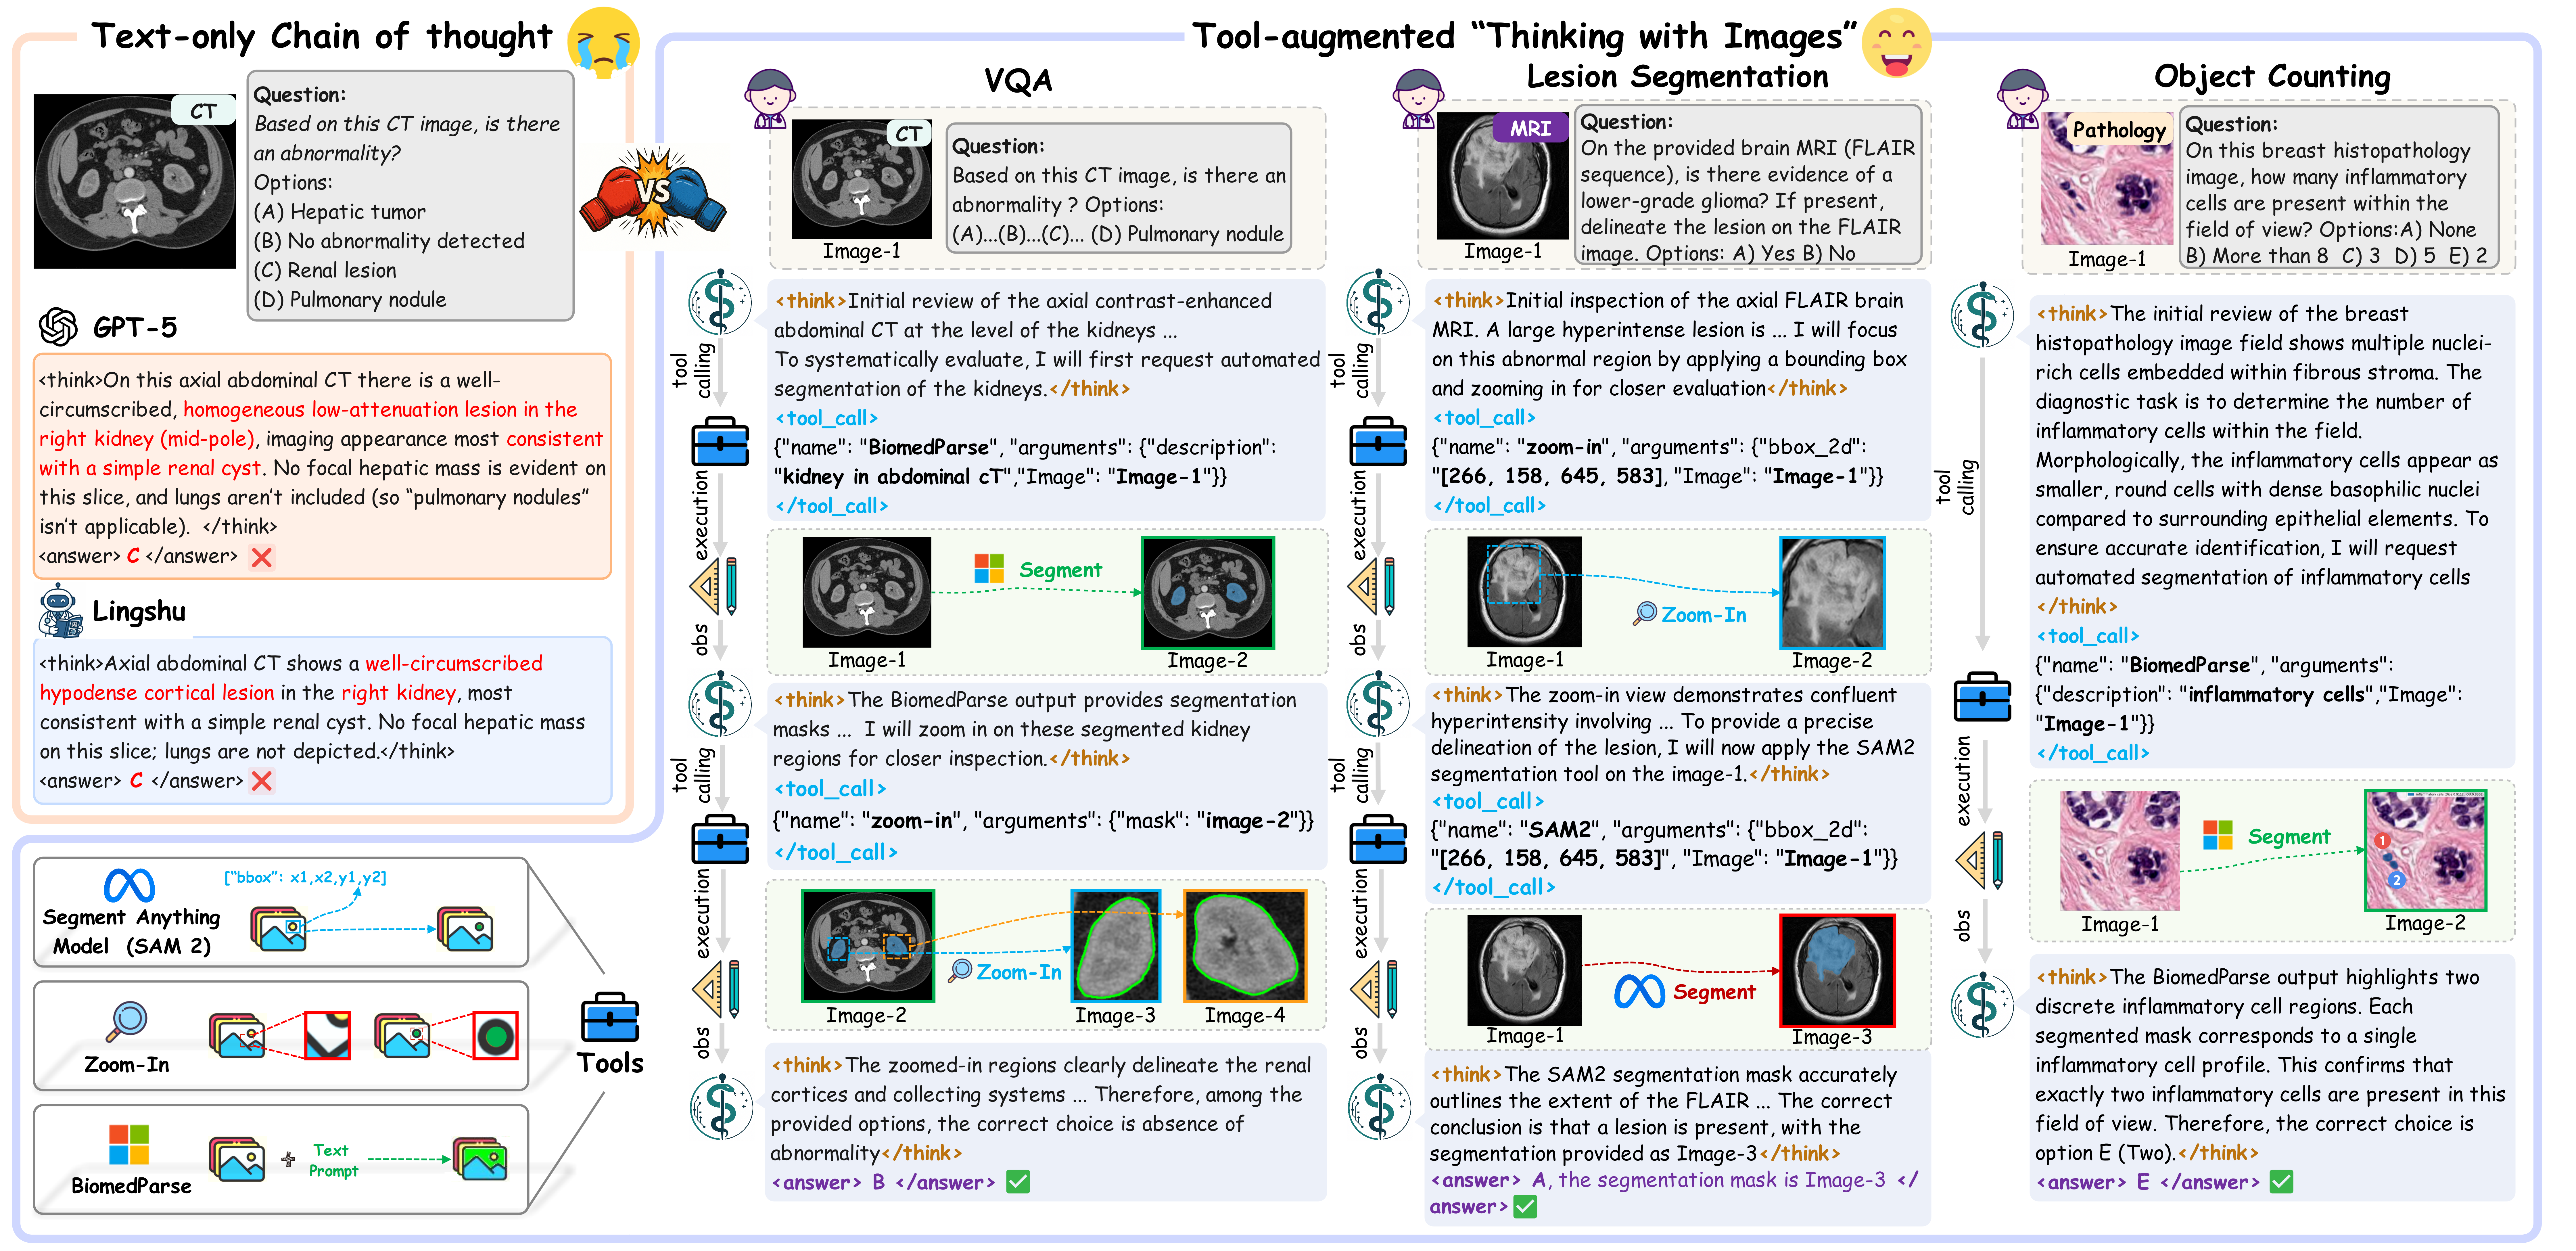
Ophiuchus is a tool-augmented medical multimodal large language model framework that learns to think with images. Instead of relying on a single global view, Ophiuchus performs iterative visual evidence acquisition during reasoning.
It learns to decide:
The core loop is simple and clinically motivated:
Thought → Tool Call → Observation → Grounded Reasoning → Final Answer
This allows Ophiuchus to inspect suspicious regions, verify uncertain hypotheses, and reduce hallucinations by grounding its answers in retrieved image evidence.
Medical image analysis often requires local evidence. Subtle lesions, boundaries, textures, and anatomical relationships may be missed by a single global image encoding. Ophiuchus addresses this limitation with an agentic visual reasoning process.
| Challenge | Ophiuchus response |
|---|---|
| Global views miss subtle findings | Targeted zoom-in retrieves fine-grained evidence |
| Bounding boxes can be unreliable | Text-driven segmentation delegates localization to external tools |
| Tool use may be unnecessary for easy cases | The model learns when to answer directly and when to inspect further |
| Visual hallucination can derail reasoning | Self-reflection and tool observations help the model correct itself |
| Medical tasks are diverse | The same framework supports VQA, detection, understanding, and reasoning-based segmentation |
Ophiuchus is trained to produce interleaved multimodal reasoning traces:
| Token or action | Role |
|---|---|
<think> | Textual reasoning and uncertainty assessment |
<tool_call> or Action | Invoke image tools for segmentation or zoom-in |
<obs> | Inject tool outputs, masks, crops, or overlays into the context |
| Final answer | Produce an answer grounded in accumulated visual evidence |
The model is not only optimized for answer accuracy. It is also encouraged to use tools when evidence is missing, avoid unnecessary calls when the answer is clear, and correct itself when tool observations contradict earlier reasoning.
Ophiuchus uses three complementary tools.
| Tool | Input | Output | Best used for |
|---|---|---|---|
| SAM2 | Bounding boxes proposed by the MLLM | Segmentation masks | Fast region grounding when object location is roughly known |
| BiomedParse | Text prompts | Text-driven segmentation masks | Robust localization when bounding boxes are uncertain |
| Zoom-In | Bounding boxes or masks | Cropped regions and optional contour overlays | Fine-grained inspection of lesion morphology and boundaries |
In practice, Ophiuchus learns to mix these tools according to case difficulty and the type of missing evidence.
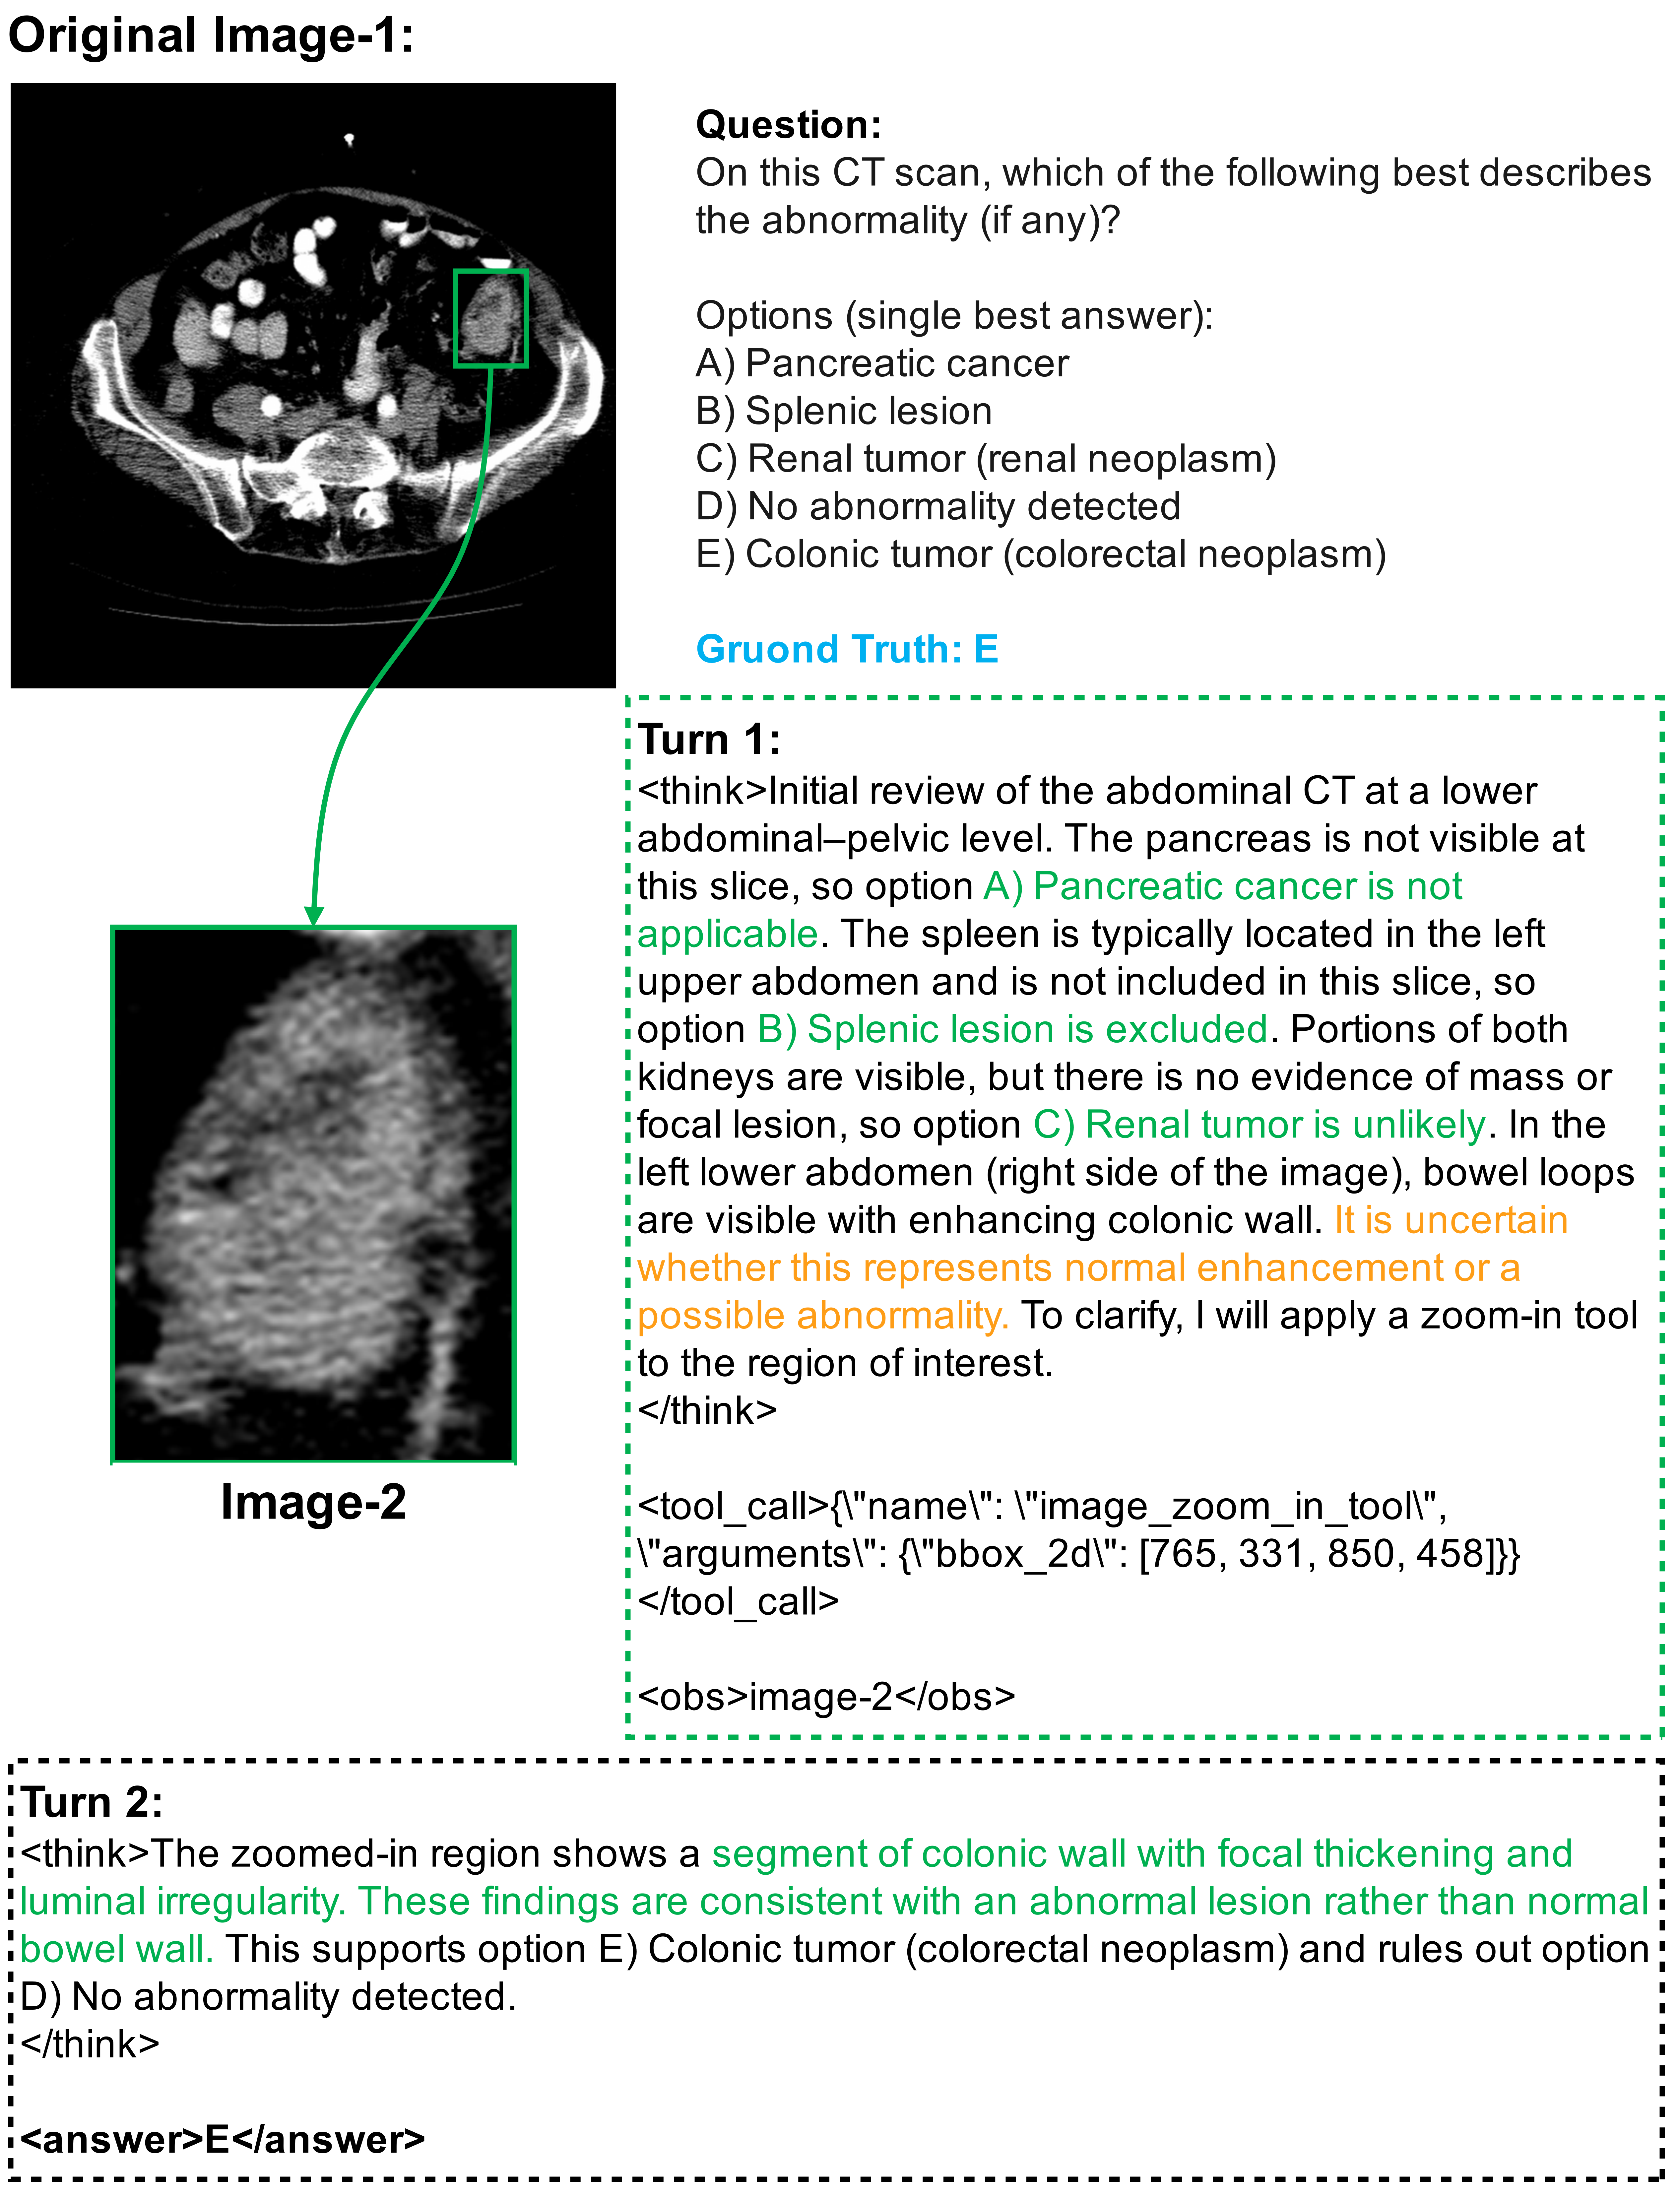
Below are representative qualitative cases. More details, captions, and examples are provided in the paper.
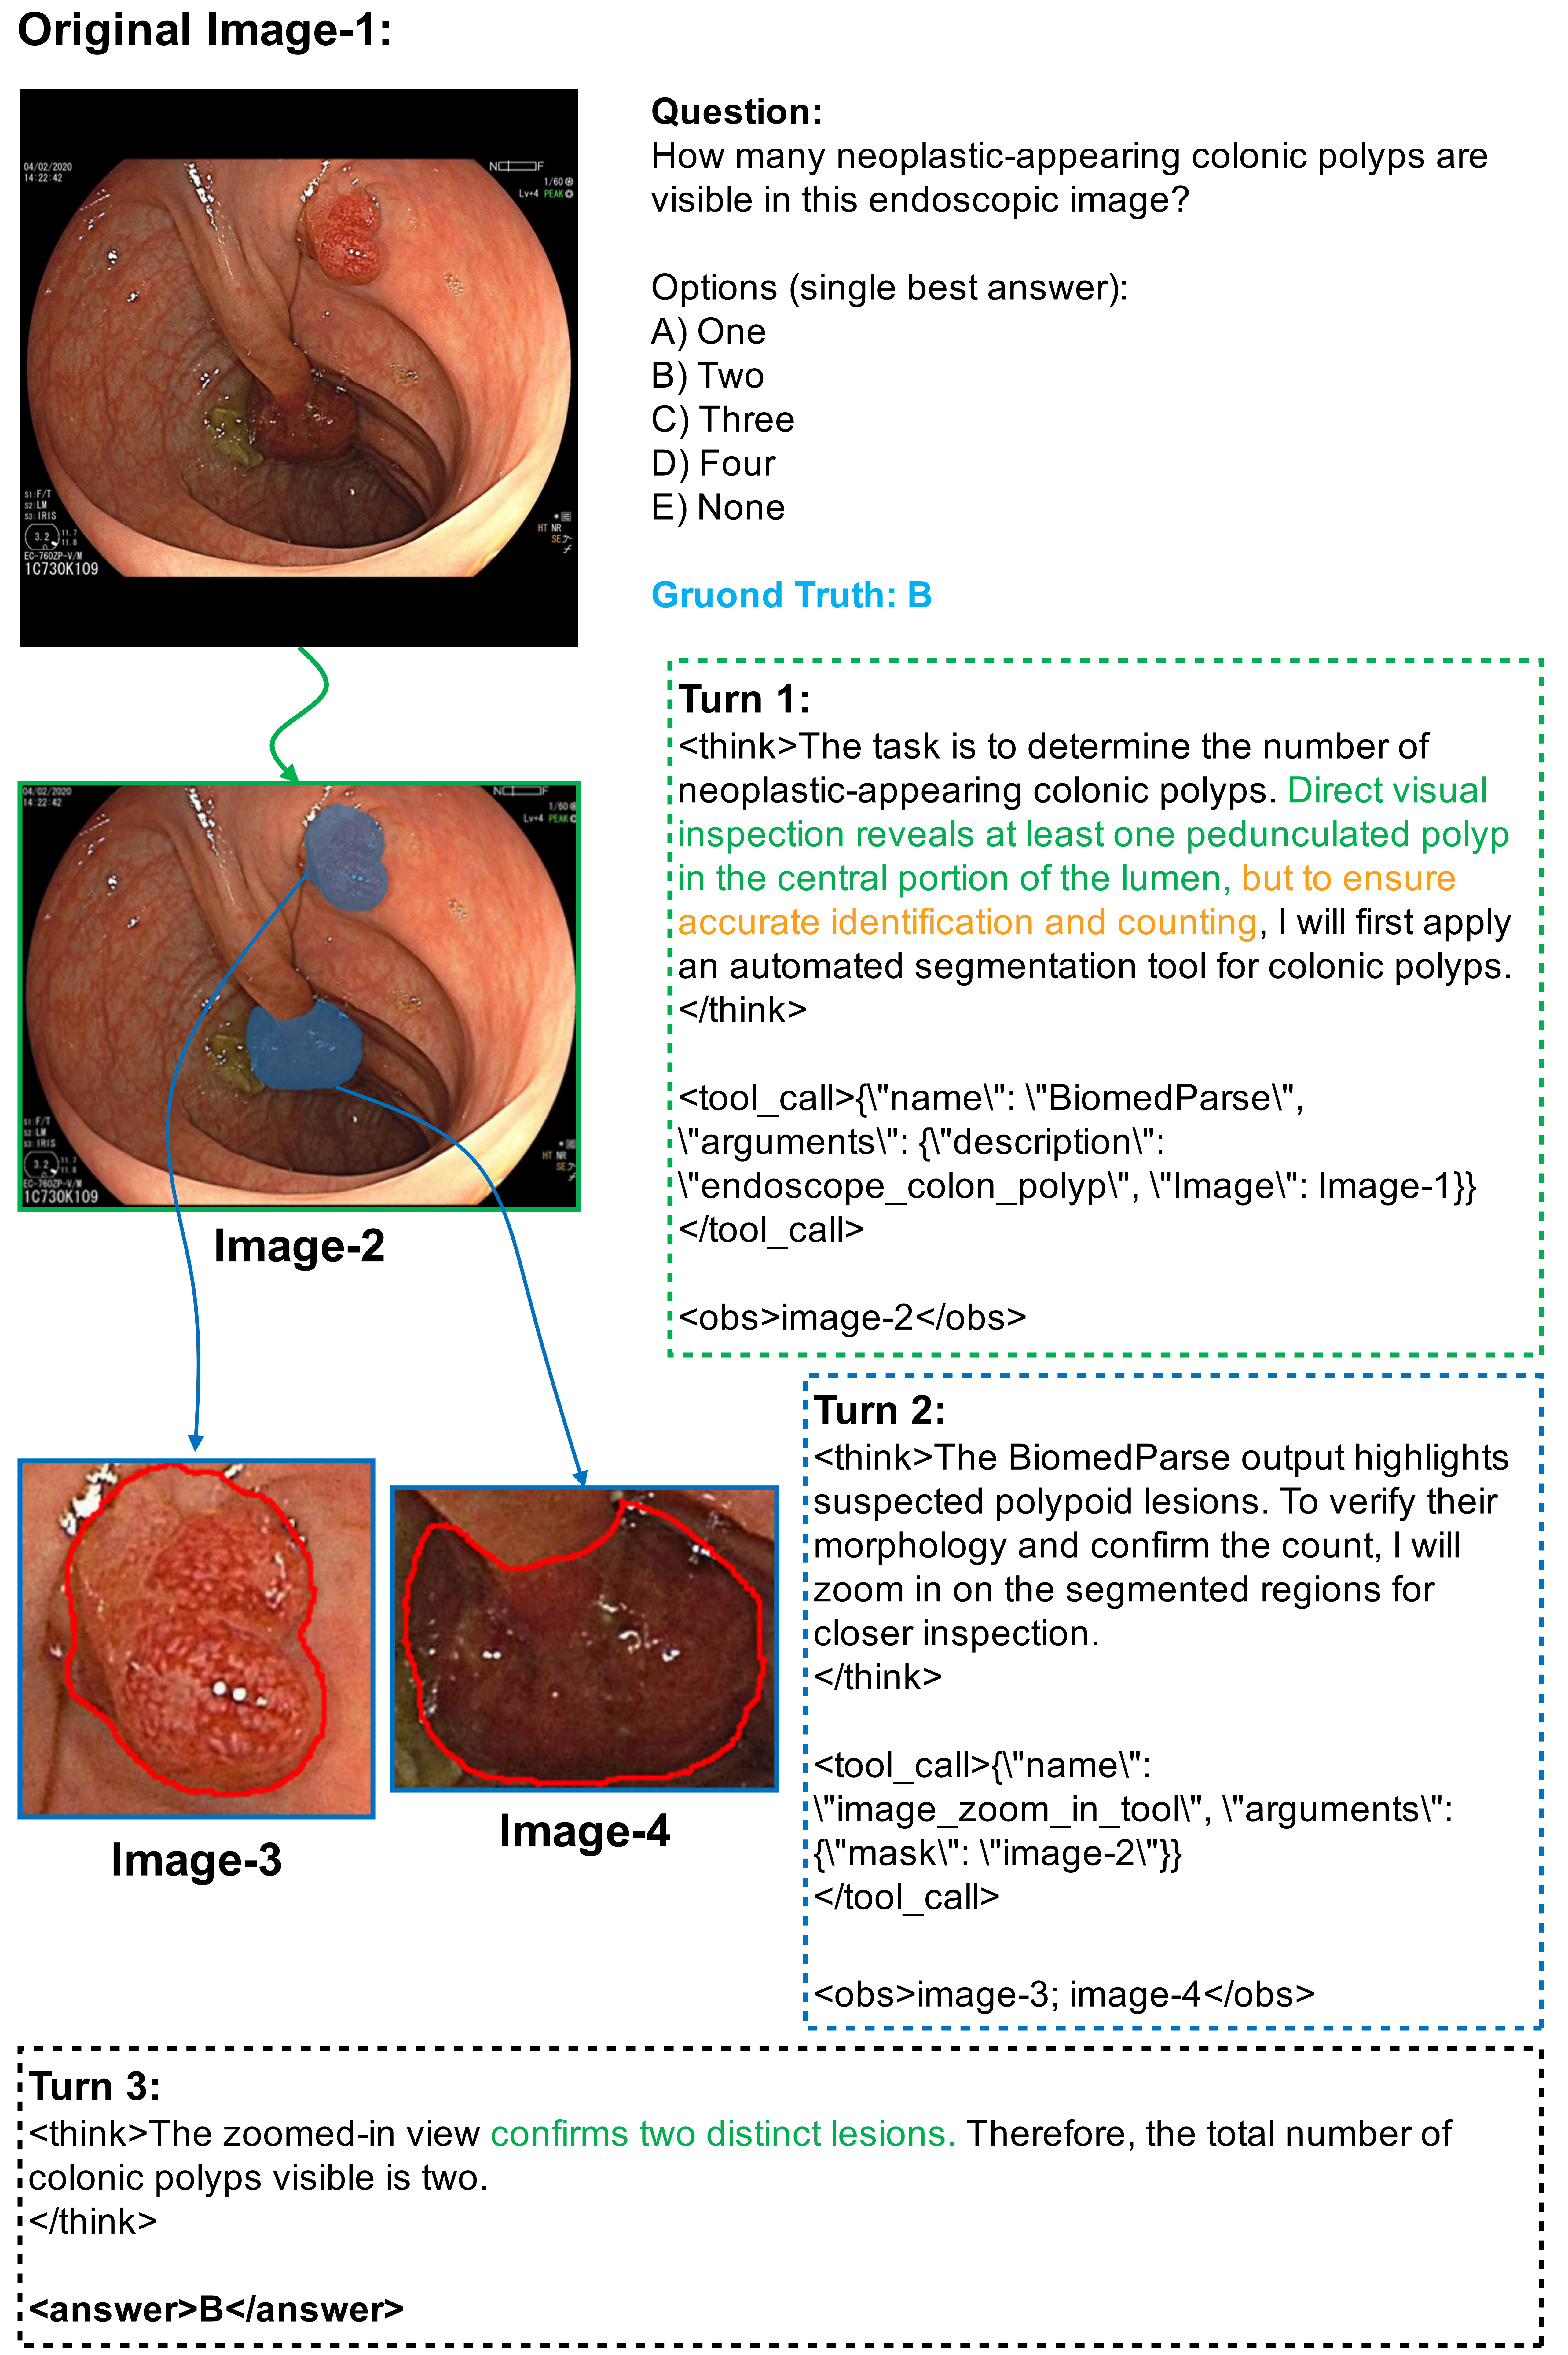
Pattern: the model recognizes that the global view is insufficient, calls segmentation to locate candidate regions, then zooms in to verify subtle visual cues before answering.
Pattern: after forming a tentative hypothesis, the model performs targeted zoom-ins to confirm key visual signatures and reduce uncertainty.
Pattern: the model detects a mismatch between textual reasoning and visual evidence, invokes tools again, and revises the answer with better grounding.
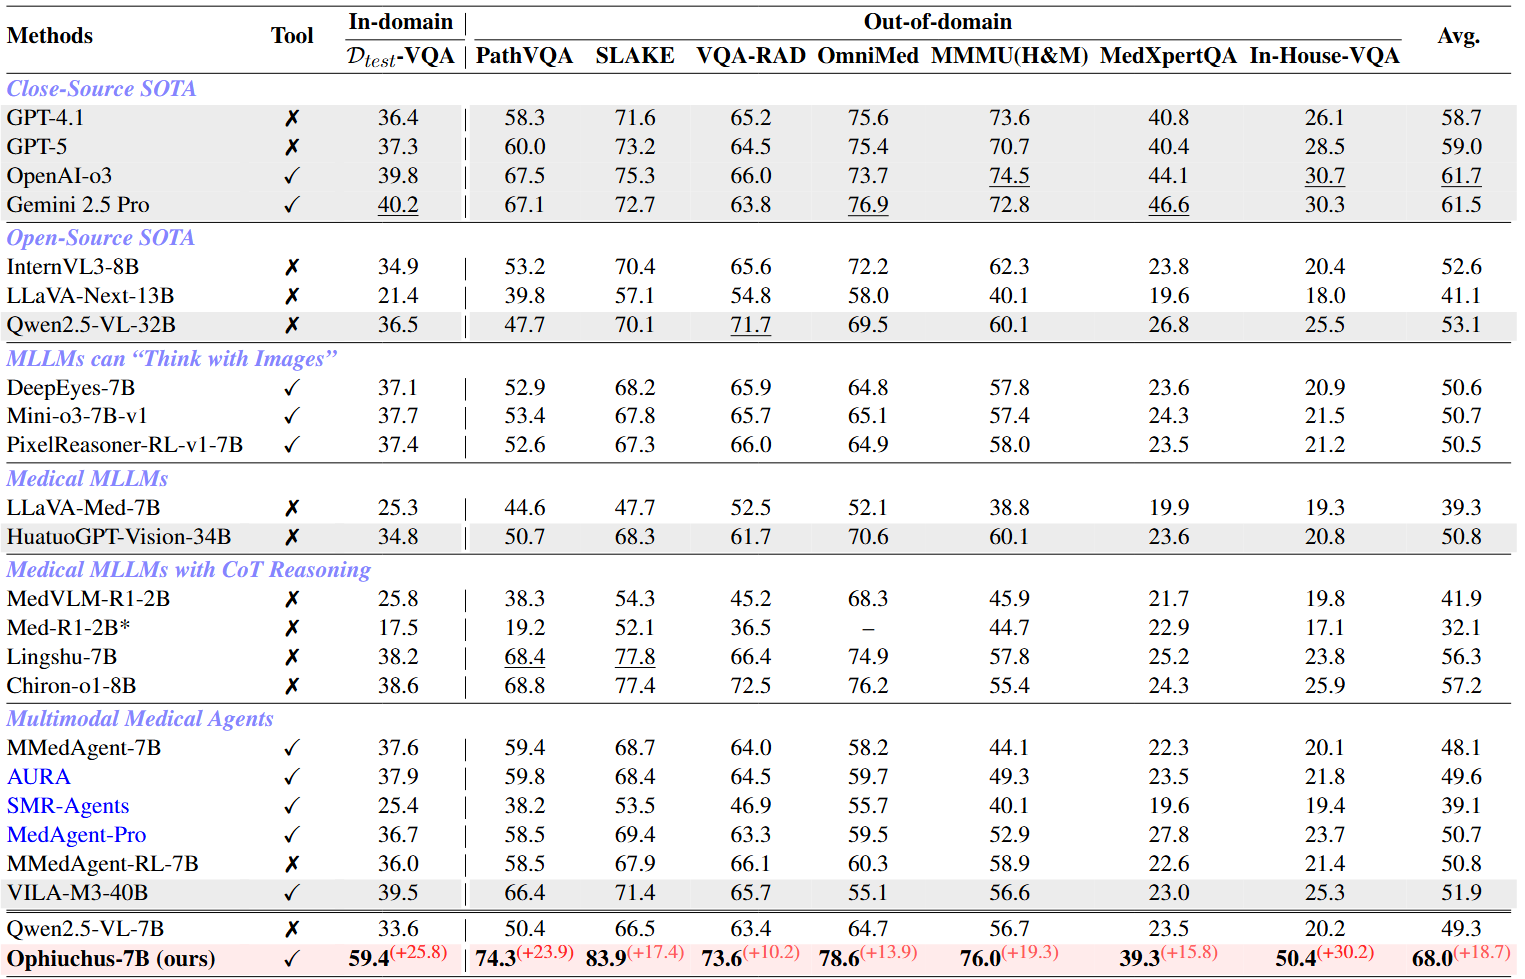
Performance comparison on medical VQA benchmarks. Gray-shaded rows denote large-sized models. Bold and underlined indicate the best and second-best results. Improvement denotes the absolute gain of Ophiuchus over Qwen2.5-VL-7B without tool use. Avg. is the arithmetic mean over seven out-of-domain zero-shot benchmarks. Since Med-R1-2B is trained on part of the OmniMedVQA test set, its Avg. is computed over the remaining six benchmarks.
This repository provides training scripts and a minimal data format example.
A minimal example is provided here:
./data/example/data_case/biomedparser-SFT.json
RL data is a list of records. A simplified case schema is shown below.
{
  "question_id": 1,
  "question_type": "multiple choice | segmentation | open-ended | yes/no",
  "question": "string (the prompt/question)",
  "answer": "string (GT label or text answer)",
  "options": ["string list (only for MCQ / constrained answers)"],
  "data_type": "vqa | seg",
  "image_path": ["string list (one or multiple images)"],
  "source": "string (e.g., BioMedParse)",
  "mask_path": ["string list (only for seg tasks, optional)"],
  "max_steps": 6
}
# Please install verl from our repository.
# This helps visualize reward-component trends during training.
conda create -n verl-agent python==3.12 -y
conda activate verl-agent

pip3 install torch==2.6.0 --index-url https://download.pytorch.org/whl/cu124
pip3 install flash-attn==2.7.4.post1 --no-build-isolation

pip3 install -e .
pip3 install vllm==0.8.5
Important: To run an agent with external tools, install and configure the corresponding tool environment first. We recommend installing each tool in a separate conda environment to avoid package conflicts.
SAM2 requires python>=3.10, torch>=2.5.1, and torchvision>=0.20.1. Please follow the official PyTorch instructions to install PyTorch and TorchVision.
cd ./examples/env_server/sam2/sam2
pip install -e .
Download model checkpoints:
cd ./examples/env_server/sam2/checkpoints && \
./download_ckpts.sh && \
cd ..
Individual checkpoints:
Create a dedicated environment:
cd ./examples/env_server/BiomedParse/BiomedParse-main
conda create -n biomedparse python=3.9.19
conda activate biomedparse
Install PyTorch:
conda install pytorch torchvision torchaudio pytorch-cuda=12.4 -c pytorch -c nvidia
Install dependencies:
pip install -r assets/requirements/requirements.txt
Please download the Hugging Face model openai/clip-vit-base-patch32 into /openai/clip-vit-base-patch32, and download microsoft/BiomedNLP-BiomedBERT-base-uncased-abstract-fulltext into BiomedParse-main/microsoft/BiomedNLP-BiomedBERT-base-uncased-abstract-fulltext.
First, run cold-start SFT and self-reflection fine-tuning. Please specify configurations in:
/scripts/SFT/cold-start/my_qwen2_5vl_lora_sft.yaml
/scripts/SFT/reflective_rejection_fine_tuning/config_reflective.yaml
Update the dataset and model_name_or_path fields before training.
bash ./scripts/SFT/cold-start/train_cold_start.sh
bash ./scripts/SFT/reflective_rejection_fine_tuning/train_reflective.sh
Start the external toolbox first as local API services.
Start the SAM2 server:
bash ./examples/env_server/start_sam2_server.sh
Start the BiomedParse server:
bash ./examples/env_server/start_biomedparse_server.sh
Run GRPO training:
# Customize training parameters according to available hardware to avoid OOM.
bash ./examples/grpo_trainer/run_ATRL.sh
| Model | Base model | Checkpoint | GPU memory |
|---|---|---|---|
| Ophiuchus | Qwen2.5-VL-7B | Coming soon | 17GB |
Detailed evaluation instructions will be updated with the full release. The current release focuses on training scripts, tool environments, and the minimal data schema.
We gratefully acknowledge the inspiring work of VERL, verl-agent, SAM2, and BioMedParse. These projects provided essential foundations and inspiration for Ophiuchus. We also thank the open-source community for building the tools that make reproducible medical AI research possible.
If Ophiuchus helps your research, please cite our paper and star the repository. Citation statistics will be updated after indexing by major academic search engines.
@misc{jiang2025incentivizing,
  title         = {Incentivizing Tool-augmented Thinking with Images for Medical Image Analysis},
  author        = {Yankai Jiang and Yujie Zhang and Peng Zhang and Yichen Li and Jintai Chen and Xiaoming Shi and Shihui Zhen},
  year          = {2025},
  eprint        = {2512.14157},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  doi           = {10.48550/arXiv.2512.14157}
}
ICML 2026 Accepted · Tool-augmented medical MLLM · Think with images · Segmentation and zoom-in grounded reasoning
Ophiuchus is a tool-augmented medical multimodal large language model framework that learns to think with images. Instead of relying on a single global view, Ophiuchus performs iterative visual evidence acquisition during reasoning.
It learns to decide:
The core loop is simple and clinically motivated:
Thought → Tool Call → Observation → Grounded Reasoning → Final Answer
This allows Ophiuchus to inspect suspicious regions, verify uncertain hypotheses, and reduce hallucinations by grounding its answers in retrieved image evidence.
Medical image analysis often requires local evidence. Subtle lesions, boundaries, textures, and anatomical relationships may be missed by a single global image encoding. Ophiuchus addresses this limitation with an agentic visual reasoning process.
| Challenge | Ophiuchus response |
|---|---|
| Global views miss subtle findings | Targeted zoom-in retrieves fine-grained evidence |
| Bounding boxes can be unreliable | Text-driven segmentation delegates localization to external tools |
| Tool use may be unnecessary for easy cases | The model learns when to answer directly and when to inspect further |
| Visual hallucination can derail reasoning | Self-reflection and tool observations help the model correct itself |
| Medical tasks are diverse | The same framework supports VQA, detection, understanding, and reasoning-based segmentation |
Ophiuchus is trained to produce interleaved multimodal reasoning traces:
| Token or action | Role |
|---|---|
<think> | Textual reasoning and uncertainty assessment |
<tool_call> or Action | Invoke image tools for segmentation or zoom-in |
<obs> | Inject tool outputs, masks, crops, or overlays into the context |
| Final answer | Produce an answer grounded in accumulated visual evidence |
The model is not only optimized for answer accuracy. It is also encouraged to use tools when evidence is missing, avoid unnecessary calls when the answer is clear, and correct itself when tool observations contradict earlier reasoning.
Ophiuchus uses three complementary tools.
| Tool | Input | Output | Best used for |
|---|---|---|---|
| SAM2 | Bounding boxes proposed by the MLLM | Segmentation masks | Fast region grounding when object location is roughly known |
| BiomedParse | Text prompts | Text-driven segmentation masks | Robust localization when bounding boxes are uncertain |
| Zoom-In | Bounding boxes or masks | Cropped regions and optional contour overlays | Fine-grained inspection of lesion morphology and boundaries |
In practice, Ophiuchus learns to mix these tools according to case difficulty and the type of missing evidence.
Below are representative qualitative cases. More details, captions, and examples are provided in the paper.
Pattern: the model recognizes that the global view is insufficient, calls segmentation to locate candidate regions, then zooms in to verify subtle visual cues before answering.
Pattern: after forming a tentative hypothesis, the model performs targeted zoom-ins to confirm key visual signatures and reduce uncertainty.
Pattern: the model detects a mismatch between textual reasoning and visual evidence, invokes tools again, and revises the answer with better grounding.
Performance comparison on medical VQA benchmarks. Gray-shaded rows denote large-sized models. Bold and underlined indicate the best and second-best results. Improvement denotes the absolute gain of Ophiuchus over Qwen2.5-VL-7B without tool use. Avg. is the arithmetic mean over seven out-of-domain zero-shot benchmarks. Since Med-R1-2B is trained on part of the OmniMedVQA test set, its Avg. is computed over the remaining six benchmarks.
This repository provides training scripts and a minimal data format example.
A minimal example is provided here:
./data/example/data_case/biomedparser-SFT.json
RL data is a list of records. A simplified case schema is shown below.
{
  "question_id": 1,
  "question_type": "multiple choice | segmentation | open-ended | yes/no",
  "question": "string (the prompt/question)",
  "answer": "string (GT label or text answer)",
  "options": ["string list (only for MCQ / constrained answers)"],
  "data_type": "vqa | seg",
  "image_path": ["string list (one or multiple images)"],
  "source": "string (e.g., BioMedParse)",
  "mask_path": ["string list (only for seg tasks, optional)"],
  "max_steps": 6
}
# Please install verl from our repository.
# This helps visualize reward-component trends during training.
conda create -n verl-agent python==3.12 -y
conda activate verl-agent

pip3 install torch==2.6.0 --index-url https://download.pytorch.org/whl/cu124
pip3 install flash-attn==2.7.4.post1 --no-build-isolation

pip3 install -e .
pip3 install vllm==0.8.5
Important: To run an agent with external tools, install and configure the corresponding tool environment first. We recommend installing each tool in a separate conda environment to avoid package conflicts.
SAM2 requires python>=3.10, torch>=2.5.1, and torchvision>=0.20.1. Please follow the official PyTorch instructions to install PyTorch and TorchVision.
cd ./examples/env_server/sam2/sam2
pip install -e .
Download model checkpoints:
cd ./examples/env_server/sam2/checkpoints && \
./download_ckpts.sh && \
cd ..
Individual checkpoints:
Create a dedicated environment:
cd ./examples/env_server/BiomedParse/BiomedParse-main
conda create -n biomedparse python=3.9.19
conda activate biomedparse
Install PyTorch:
conda install pytorch torchvision torchaudio pytorch-cuda=12.4 -c pytorch -c nvidia
Install dependencies:
pip install -r assets/requirements/requirements.txt
Please download the Hugging Face model openai/clip-vit-base-patch32 into /openai/clip-vit-base-patch32, and download microsoft/BiomedNLP-BiomedBERT-base-uncased-abstract-fulltext into BiomedParse-main/microsoft/BiomedNLP-BiomedBERT-base-uncased-abstract-fulltext.
First, run cold-start SFT and self-reflection fine-tuning. Please specify configurations in:
/scripts/SFT/cold-start/my_qwen2_5vl_lora_sft.yaml
/scripts/SFT/reflective_rejection_fine_tuning/config_reflective.yaml
Update the dataset and model_name_or_path fields before training.
bash ./scripts/SFT/cold-start/train_cold_start.sh
bash ./scripts/SFT/reflective_rejection_fine_tuning/train_reflective.sh
Start the external toolbox first as local API services.
Start the SAM2 server:
bash ./examples/env_server/start_sam2_server.sh
Start the BiomedParse server:
bash ./examples/env_server/start_biomedparse_server.sh
Run GRPO training:
# Customize training parameters according to available hardware to avoid OOM.
bash ./examples/grpo_trainer/run_ATRL.sh
| Model | Base model | Checkpoint | GPU memory |
|---|---|---|---|
| Ophiuchus | Qwen2.5-VL-7B | Coming soon | 17GB |
Detailed evaluation instructions will be updated with the full release. The current release focuses on training scripts, tool environments, and the minimal data schema.
We gratefully acknowledge the inspiring work of VERL, verl-agent, SAM2, and BioMedParse. These projects provided essential foundations and inspiration for Ophiuchus. We also thank the open-source community for building the tools that make reproducible medical AI research possible.
If Ophiuchus helps your research, please cite our paper and star the repository. Citation statistics will be updated after indexing by major academic search engines.
@misc{jiang2025incentivizing,
  title         = {Incentivizing Tool-augmented Thinking with Images for Medical Image Analysis},
  author        = {Yankai Jiang and Yujie Zhang and Peng Zhang and Yichen Li and Jintai Chen and Xiaoming Shi and Shihui Zhen},
  year          = {2025},
  eprint        = {2512.14157},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  doi           = {10.48550/arXiv.2512.14157}
}



