
A curated list of "A Survey on Post-training of Multimodal Large Language Models" research. Watch this repository for latest updates! 🔥
See the codeREADME


Watch this repository for the latest updates!
Feel free to raise pull requests if you find some interesting papers! 🌟
 News
[2026/07/22] 🎉 We release our Paper and Project Page!
[2026/07/19] 🎉 We release our curation list of MLLMs Post-Training methods!
 Introduction
Multimodal Large Language Models (MLLMs) have reshaped AI by enabling perception, reasoning, and interaction across digital and physical environments. While multimodal pretraining establishes broad perceptual capabilities, translating them into behaviors aligned with human intent and real-world demands remains challenging. Multimodal Post-Training (MMPoT) addresses this gap by refining pretrained MLLMs toward reliable, task-oriented behavior. This survey reviews MMPoT from a behavior-shaping perspective and organizes existing methods into five families: instruction following, preference calibration, reasoning enhancement, domain adaptation, and scalable training. We further examine benchmarks and evaluation protocols, identify current limitations, and outline future directions toward general and reliable multimodal intelligence.
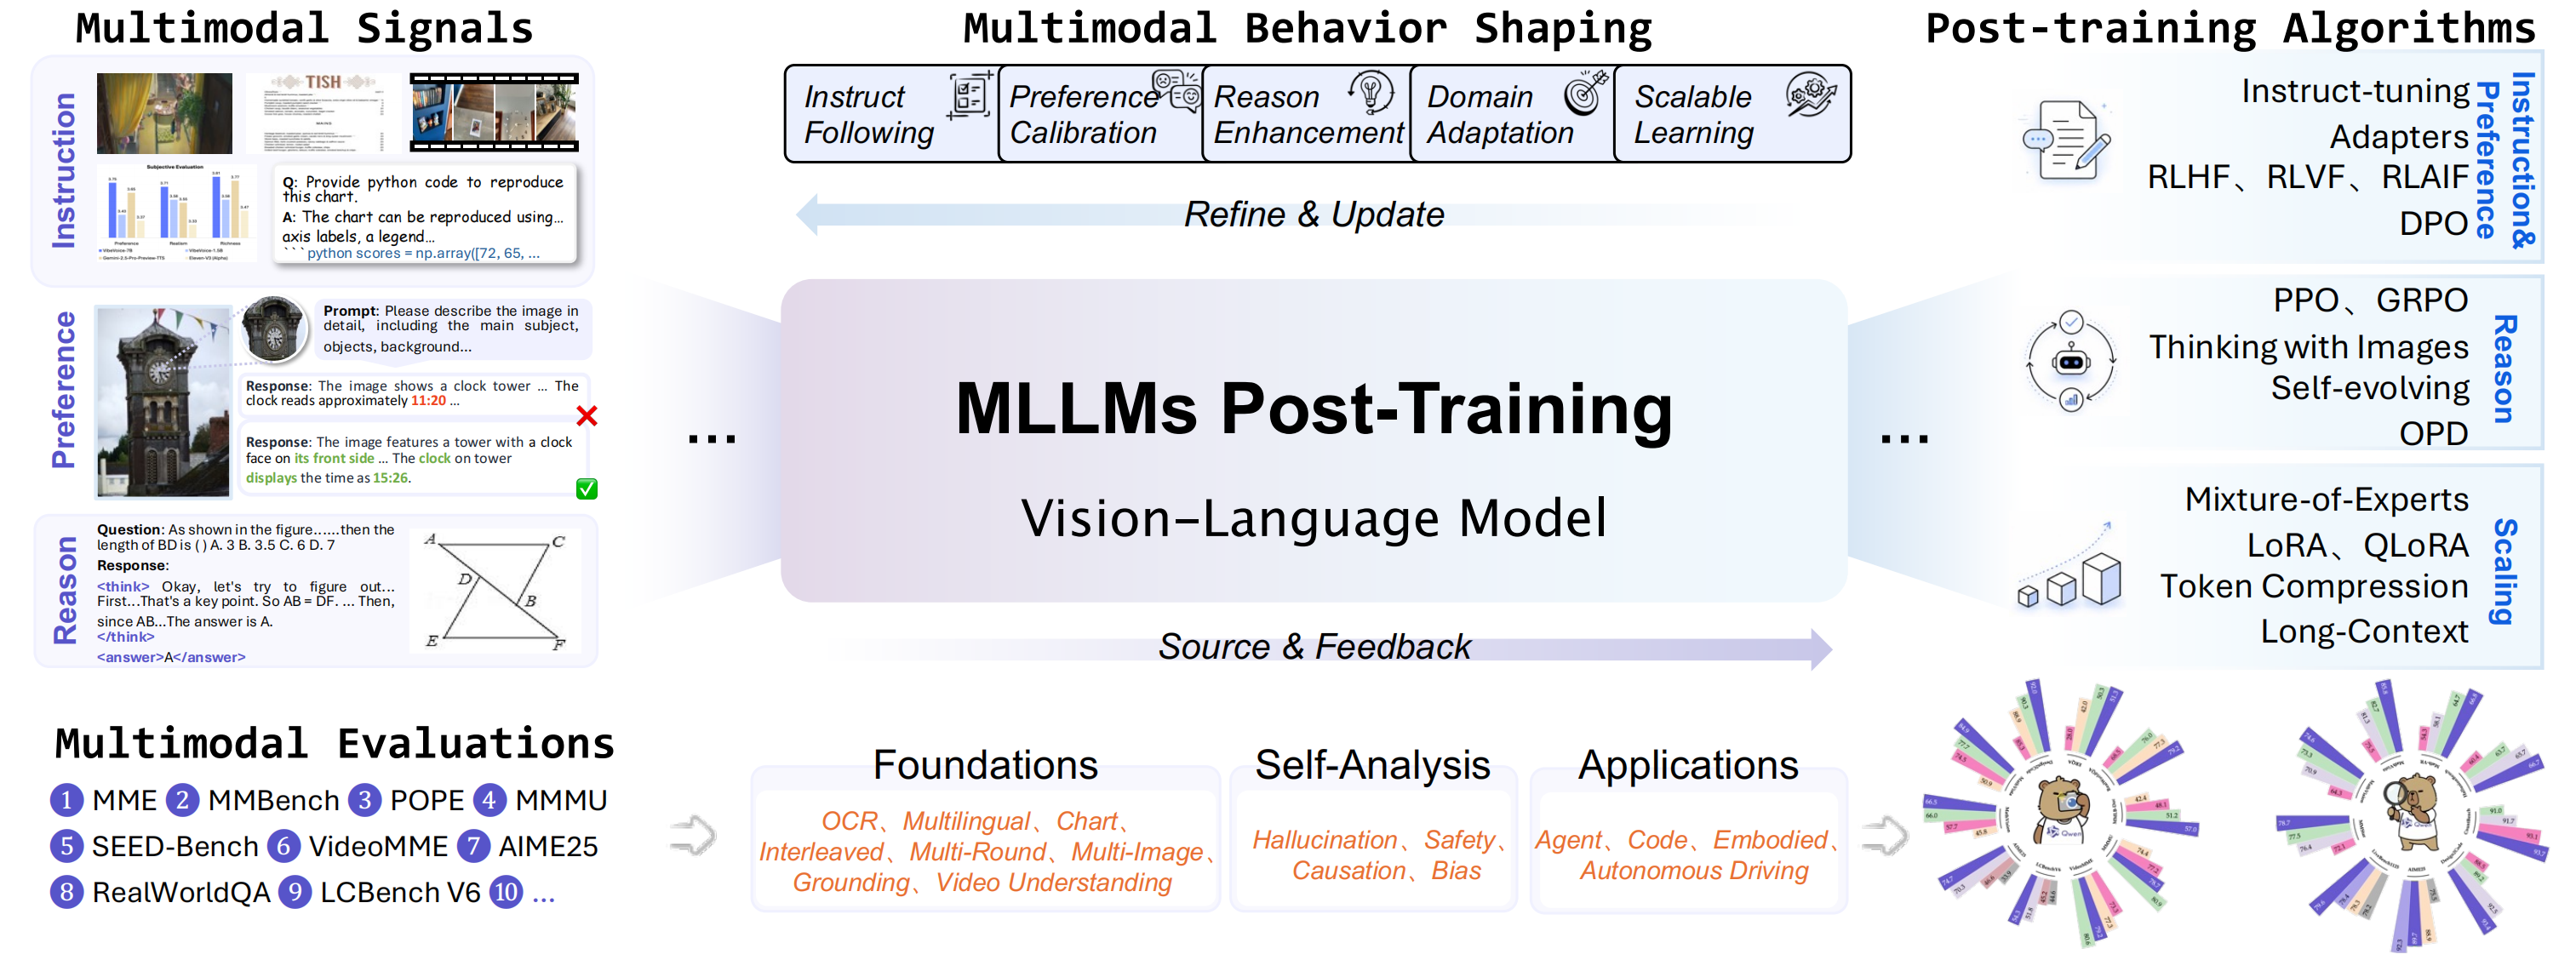 Figure 1. Overview of multimodal behavior shaping for MLLMs post-training. Post-training algorithms can be viewed as behavior-shaping mechanisms that steer pretrained MLLMs toward desired behaviors, while multimodal data and benchmarks provide learning signals and evaluative feedback for iterative refinement.
 Contents
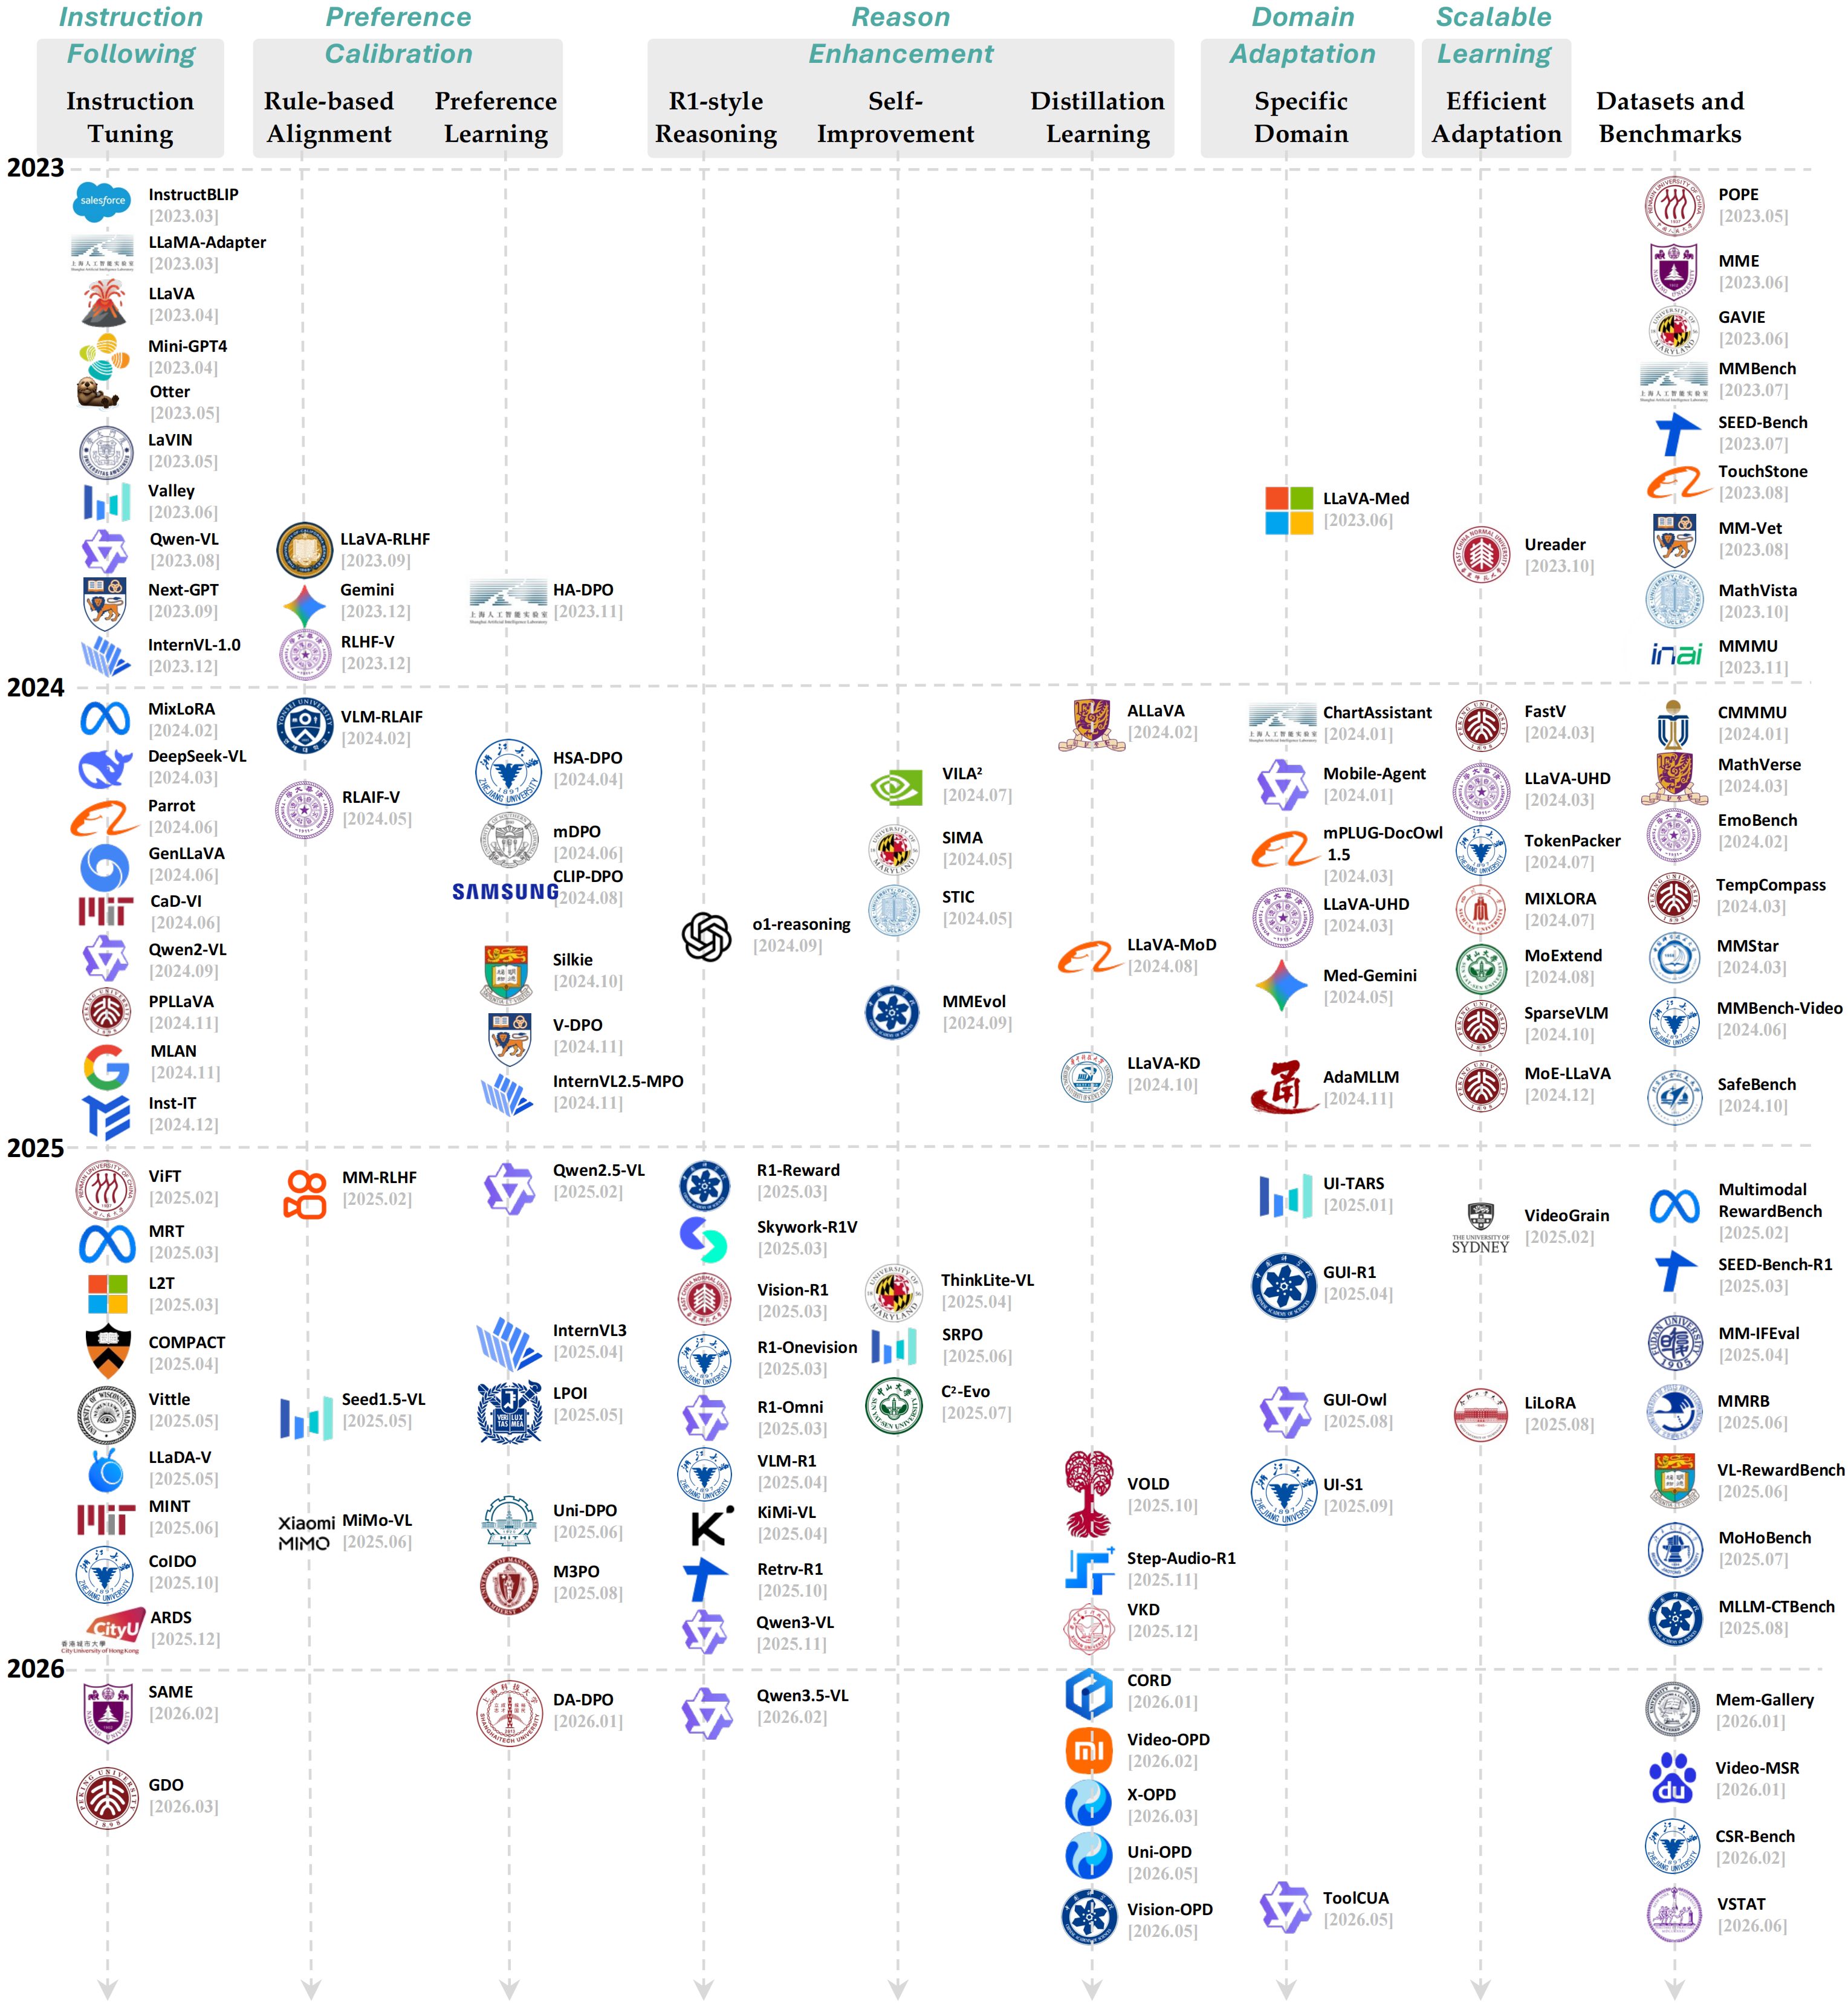 Figure 2. A timeline of MLLMs post-training research.
 Multimodal Instruction Tuning
-
Visual Instruction Tuning [NeurIPS 2023] [Paper] [Code] [Homepage]
University of Wisconsin–Madison, Microsoft Research, Columbia University -
MiniGPT-4: Enhancing Vision-Language Understanding with Advanced Large Language Models [ICLR 2024] [Paper] [Code] [Homepage]
King Abdullah University of Science and Technology -
InstructBLIP: Towards General-purpose Vision-Language Models with Instruction Tuning [NeurIPS 2023] [Paper] [Code]
Salesforce Research, Hong Kong University of Science and Technology, Nanyang Technological University, Singapore -
mPLUG-Owl: Modularization Empowers Large Language Models with Multimodality [arXiv 2023] [Paper] [Code]
DAMO Academy, Alibaba Group -
LLaMA-Adapter V2: Parameter-Efficient Visual Instruction Model [arXiv 2023] [Paper] [Code]
Shanghai Artificial Intelligence Laboratory, CUHK MMLab, Rutgers University -
Improved Baselines with Visual Instruction Tuning [CVPR 2024] [Paper] [Code] [Homepage]
University of Wisconsin–Madison, Microsoft Research, Redmond -
Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond [arXiv 2023] [Paper] [Code]
Alibaba Group -
CogVLM: Visual Expert for Pretrained Language Models [NeurIPS 2024] [Paper] [Code]
Tsinghua University, Zhipu AI -
InternVL: Scaling up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks [CVPR 2024] [Paper] [Code]
OpenGVLab, Shanghai AI Laboratory, Nanjing University, The University of Hong Kong, The Chinese University of Hong Kong, Tsinghua University, University of Science and Technology of China, SenseTime Research -
LLaVA-NeXT: Improved Reasoning, OCR, and World Knowledge [arXiv 2024] [Paper] [Code] [Homepage]
University of Wisconsin-Madison, Microsoft Research -
What matters when building vision-language models? [NeurIPS 2024] [Paper] [HF]
Hugging Face, Sorbonne Université -
Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution [arXiv 2024] [Paper] [Code]
ByteDance, S-Lab, NTU, CUHK, HKUST -
LLaVA-OneVision: Easy Visual Task Transfer [TMLR 2025] [Paper] [Code] [Homepage]
ByteDance, S-Lab, NTU, CUHK, HKUST -
Expanding Performance Boundaries of Open-Source Multimodal Models with Model, Data, and Test-Time Scaling [arXiv 2024] [Paper] [Code] [Homepage]
Shanghai AI Laboratory, SenseTime Research, Tsinghua University, Nanjing University, Fudan University, The Chinese University of Hong Kong, Shanghai Jiao Tong University -
Qwen2.5-VL Technical Report [arXiv 2025] [Paper] [Code]
Alibaba Group -
VILA: On Pre-training for Visual Language Models [CVPR 2024] [Paper] [Code]
NVIDIA, MIT -
MobileVLM : A Fast, Strong and Open Vision Language Assistant for Mobile Devices [arXiv 2023] [Paper] [Code]
Meituan Inc., Zhejiang University, China, Dalian University of Technology, China -
DeepSeek-VL: Towards Real-World Vision-Language Understanding [arXiv 2024] [Paper] [Code]
DeepSeek-AI -
Yi: Open Foundation Models by 01.AI [arXiv 2024] [Paper] [Code] [HF]
01.AI -
Cambrian-1: A Fully Open, Vision-Centric Exploration of Multimodal LLMs [NeurIPS 2024] [Paper] [Code] [Homepage]
New York University -
MiniCPM-V: A GPT-4V Level MLLM on Your Phone [arXiv 2024] [Paper] [Code] [Homepage]
OpenBMB -
Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone [arXiv 2024] [Paper] [HF]
Microsoft -
The Llama 3 Herd of Models [arXiv 2024] [Paper] [HF] [Homepage]
Meta -
Molmo and PixMo: Open Weights and Open Data for State-of-the-Art Vision-Language Models [CVPR 2025] [Paper] [Code] [Homepage]
Allen Institute for AI, University of Washington -
Comparison Visual Instruction Tuning [CVPR 2025 Workshop] [Paper] [Code] [Homepage] [HF]
ELLIS Unit, LIT AI Lab, Institute for Machine Learning, JKU Linz, Austria, TU Graz ICG, Austria, IBM Research, Israel, Weizmann Institute of Science, Israel, Tel-Aviv University, Israel, NXAI GmbH, Austria, MIT-IBM Watson AI Lab, USA -
PaliGemma: A versatile 3B VLM for transfer [arXiv 2024] [Paper] [HF]
Google DeepMind -
Otter: A Multi-Modal Model with In-Context Instruction Tuning [TPAMI 2025] [Paper] [Code]
S-Lab, Nanyang Technological University, Microsoft Research -
LLaMA-Adapter: Efficient Fine-tuning of Language Models with Zero-init Attention [ICLR 2024] [Paper] [Code]
Shanghai Artificial Intelligence Laboratory, CUHK MMLab, University of California, Los Angeles, CPII of InnoHK -
Cheap and Quick: Efficient Vision-Language Instruction Tuning for Large Language Models [NeurIPS 2023] [Paper] [Code]
Key Laboratory of Multimedia Trusted Perception and Efficient Computing, Ministry of Education of China, School of Informatics, Xiamen University, 361005, P.R. China., Institute of Artificial Intelligence, Xiamen University, 361005, P.R. China., Peng Cheng Laboratory, Shenzhen, 518000, China. -
Valley: Video Assistant with Large Language model Enhanced abilitY [arXiv 2023] [Paper] [Code]
ByteDance Inc., Fudan University, East China Normal University -
NExT-GPT: Any-to-Any Multimodal LLM [ICML 2024] [Paper] [Code] [Homepage]
National University of Singapore -
InternVL: Scaling up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks [CVPR 2024] [Paper] [Code]
OpenGVLab, Shanghai AI Laboratory, Nanjing University, The University of Hong Kong, The Chinese University of Hong Kong, Tsinghua University, University of Science and Technology of China, SenseTime Research -
Generative Visual Instruction Tuning [arXiv 2024] [Paper] [Code]
Rice University, Google DeepMind -
MLAN: Language-Based Instruction Tuning Preserves and Transfers Knowledge in Multimodal Language Models [arXiv 2024] [Paper]
Washington University in St. Louis, The University of British Columbia, Google Research, Virginia Tech, University of California, Davis, Sony AI, University of California, Berkeley -
INST-IT: Boosting Instance Understanding via Explicit Visual Prompt Instruction Tuning [NeurIPS 2025] [Paper] [Code] [Homepage]
Institute of Trustworthy Embodied AI, Fudan University, Shanghai Innovation Institute, Huawei Noah, s Ark Lab -
Learning to Instruct for Visual Instruction Tuning [NeurIPS 2025] [Paper] [Code]
Cooperative Medianet Innovation Center, Shanghai Jiao Tong University, Microsoft Research Asia, Hong Kong Baptist University, School of Artificial Intelligence, Shanghai Jiao Tong University -
Visual Compositional Tuning [ICLR 2026 Workshop] [Paper] [Code] [Homepage]
Princeton University, Meta AI -
Visual Instruction Bottleneck Tuning [NeurIPS 2025] [Paper] [Code]
Department of Computer Sciences, University of Wisconsin–Madison -
LLaDA-V: Large Language Diffusion Models with Visual Instruction Tuning [arXiv 2025] [Paper] [Code] [Homepage]
Gaoling School of AI, Renmin University of China, Beijing Key Laboratory of Research on Large Models and Intelligent Governance, Engineering Research Center of Next-Generation Intelligent Search and Recommendation, MOE, Ant Group -
Less Data, Faster Convergence: Goal-Driven Data Optimization for Multimodal Instruction Tuning [ECCV 2026] [Paper] [Code]
Peking University, University of Illinois at Urbana-Champaign, National University of Singapore -
LLaVA-NeXT-Interleave: Tackling Multi-image, Video, and 3D in Large Multimodal Models [ICLR 2025] [Paper] [Code] [Homepage]
ByteDance, HKUST, CUHK, NTU -
MAVIS: Mathematical Visual Instruction Tuning with an Automatic Data Engine [ICLR 2025] [Paper] [Code]
CUHK, Peking University, Shanghai AI Laboratory, ByteDance, Oracle -
MANTIS: Interleaved Multi-Image Instruction Tuning [TMLR 2024] [Paper] [Code] [Homepage]
University of Waterloo, Tsinghua University, Sea AI Lab -
ImageBind-LLM: Multi-modality Instruction Tuning [arXiv 2023] [Paper] [Code]
Shanghai Artificial Intelligence Laboratory, Shanghai, 200030, China., CUHK MMLab, Hong Kong SAR, 999077, China., vivo AI Lab, Shenzhen, 518000, China. -
ShareGPT4V: Improving Large Multi-Modal Models with Better Captions [ECCV 2024] [Paper] [Code] [Homepage]
University of Science and Technology of China, Shanghai AI Laboratory -
MiniGPT-v2: large language model as a unified interface for vision-language multi-task learning [arXiv 2023] [Paper] [Code] [Homepage]
King Abdullah University of Science and Technology (KAUST), Meta AI Research -
ViP-LLaVA: Making Large Multimodal Models Understand Arbitrary Visual Prompts [CVPR 2024] [Paper] [Code] [Homepage]
University of Wisconsin–Madison;Cruise LLC -
MoAI: Mixture of All Intelligence for Large Language and Vision Models [ECCV 2024] [Paper] [Code]
School of Electrical Engineering Korea Advanced Institute of Science and Technology (KAIST) -
Monkey :ImageResolutionandText Label Are Important Things for Large Multi-modal Models [CVPR 2024] [Paper] [Code]
Huazhong University of Science and Technology, Kingsoft Office -
Mini-Gemini: Mining the Potential of Multi-modality Vision Language Models [TPAMI 2026] [Paper] [Code]
The Chinese University of Hong Kong;SmartMore -
Feast Your Eyes: Mixture-of-Resolution Adaptation for Multimodal Large Language Models [ICLR 2025] [Paper] [Code]
Xiamen University -
SPHINX: The Joint Mixing of Weights, Tasks, and Visual Embeddings for Multi-modal Large Language Models [arXiv 2023] [Paper] [Code]
Shanghai AI Laboratory;MMLab, CUHK;ShanghaiTech University
 Multimodal Preference Calibration
Multimodal RLHF
-
ALIGNING LARGE MULTIMODAL MODELS WITH FACTUALLY AUGMENTED RLHF [ACL Findings 2024] [Paper] [Code] [Homepage]
UC Berkeley, Carnegie Mellon University, University of Illinois Urbana-Champaign, University of Wisconsin-Madison, University of Massachusetts Amherst, Microsoft Research, MIT-IBM Watson AI Lab -
RLHF-V: Towards Trustworthy MLLMs via Behavior Alignment from Fine-grained Correctional Human Feedback [CVPR 2024] [Paper] [Code] [Homepage]
Tsinghua University, National University of Singapore -
VisualPRM: An Effective Process Reward Model for Multimodal Reasoning [arXiv 2025] [Paper] [Homepage]
Shanghai AI Laboratory, SenseTime Research, Zhejiang University -
Gemini: A Family of Highly Capable Multimodal Models [arXiv 2023] [Paper] [Homepage]
Google -
Seed1.5-VL Technical Report [arXiv 2025] [Paper] [Code] [Homepage]
ByteDance Seed -
MiMo-VL Technical Report [arXiv 2025] [Paper] [Code]
LLM-Core Xiaomi
Multimodal RLAIF
-
Tuning Large Multimodal Models for Videos using Reinforcement Learning from AI Feedback [ACL 2024] [Paper] [Code] [Homepage]
Yonsei University, University of Minnesota, Seoul National University -
RLAIF-V: Open-Source AI Feedback Leads to Super GPT-4V Trustworthiness [CVPR 2025] [Paper] [Code]
Tsinghua University, Shanghai Qi Zhi Institute, Harbin Institute of Technology, Taobao & Tmall Group of Alibaba, Peng Cheng Laboratory, National University of Singapore -
Oracle-RLAIF: An Improved Fine-Tuning Framework for Multi-modal Video Models using Reinforcement Learning from Ranking Feedback [arXiv 2025] [Paper]
Stanford University, xAI, Microsoft
Multimodal Direct Preference Optimization
-
Silkie: Preference Distillation for Large Visual Language Models [arXiv 2023] [Paper] [Code] [Homepage]
University of Hong Kong, The Chinese University of Hong Kong, Shenzhen, Peng Cheng Laboratory -
Direct Preference Optimization of Video Large Multimodal Models from Language Model Reward [NAACL 2025] [Paper] [Code]
CMULTI, Bytedance, UT Austin, Columbia University, NTU -
ISR-DPO: Aligning Large Multimodal Models for Videos by Iterative Self-Retrospective DPO [AAAI 2025] [Paper] [Code] [Homepage]
Seoul National University, Yonsei University, University of Minnesota -
Beyond Hallucinations: Enhancing LVLMs through Hallucination-Aware Direct Preference Optimization [arXiv 2023] [Paper] [Code] [Homepage]
Shanghai AI Laboratory -
Mitigating Hallucination in Multimodal Large Language Model via Hallucination-targeted Direct Preference Optimization [arXiv 2024] [Paper]
Key Lab of DEKE, Renmin University of China, Machine Learning Platform Department, Tencent -
V-DPO: Mitigating Hallucination in Large Vision Language Models via Vision-Guided Direct Preference Optimization [EMNLP 2024] [Paper] [Code]
National University of Singapore -
CLIP-DPO: Vision-Language Models as a Source of Preference for Fixing Hallucinations in LVLMs [ECCV 2024] [Paper]
Samsung AI Center Cambridge, UK, Technical University of Iasi, Romania, Queen Mary University of London, UK -
Mitigating Hallucinations in Multimodal LLMs via Object-aware Preference Optimization [BMVC 2025] [Paper] [Code]
University of Modena and Reggio Emilia -
MDPO: Conditional Preference Optimization for Multimodal Large Language Models [EMNLP 2024] [Paper] [Code] [Homepage]
University of Southern California, Microsoft Research, University of California, Davis -
PEA-DPO: Perception-Enhanced Alignment Direct Preference Optimization for MLLMs Alignment [OpenReview 2026] [Paper] [Homepage]
University of Science and Technology of China -
MoD-DPO: Towards Mitigating Cross-modal Hallucinations in Omni LLMs using Modality Decoupled Preference Optimization [CVPR 2026] [Paper] [Homepage]
University of Southern California -
OMNI DPO: A Preference Optimization Framework to Address Omni-Modal Hallucination [arXiv 2025] [Paper]
Tsinghua University, Hong Kong University of Science and Technology (Guangzhou), OpenRL, Chongqing University -
DA-DPO: Cost-efficient Difficulty-aware Preference Optimization for Reducing MLLM Hallucinations [TMLR 2025] [Paper] [Code] [Homepage]
ShanghaiTech University, Lingang Laboratory, Shanghai Engineering Research Center of Intelligent Vision and Imaging -
Uncertainty-Aware Exploratory Direct Preference Optimization for Multimodal Large Language Models [arXiv 2026] [Paper]
University of Science and Technology of China -
Mitigating Hallucinations in Large Vision-Language Models via DPO: On-Policy Data Hold the Key [CVPR 2025] [Paper] [Code] [Homepage]
The Chinese University of Hong Kong, Microsoft Research Asia, The Chinese University of Hong Kong, Shenzhen Research Institute -
LPOI: Listwise Preference Optimization for Vision Language Models [ACL 2025] [Paper] [Code]
Seoul National University
 Multimodal Reason Enhancement
R1-based Multimodal Reasoning
-
LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL [arXiv 2025] [Paper] [Code] [Homepage]
Southeast University, The Chinese University of Hong Kong, Fudan University, Ant Group -
VLM-R1: A Stable and Generalizable R1-style Large Vision-Language Model [arXiv 2025] [Paper] [Code]
OM AI Lab -
Visual-RFT: Visual Reinforcement Fine-Tuning [ICCV 2025] [Paper] [Code]
Shanghai AI Laboratory, The Chinese University of Hong Kong (CUHK) -
Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models [ICLR 2026] [Paper] [Code]
East China Normal University, Xiaohongshu Inc. -
VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning [arXiv 2025] [Paper] [Code]
Nanjing University, Shanghai AI Laboratory, The Chinese University of Hong Kong, Shenzhen -
Video-R1: Reinforcing Video Reasoning in MLLMs [NeurIPS 2025] [Paper] [Code]
MMLab, The Chinese University of Hong Kong (CUHK), DataWhale, The Chinese University of Hong Kong, Shenzhen -
VisualPRM: An Effective Process Reward Model for Multimodal Reasoning [arXiv 2025] [Paper] [Homepage]
Shanghai AI Laboratory, SenseTime Research, Zhejiang University -
R1-VL: Learning to Reason with Multimodal Large Language Models via Step-wise Group Relative Policy Optimization [ICCV 2025] [Paper]
Nanyang Technological University (NTU), Nankai University, JD Explore Academy -
R1-Zero's "Aha Moment" in Visual Reasoning on a 2B Non-SFT Model [arXiv 2025] [Paper] [Code]
University of California, Los Angeles (UCLA), TurningPoint AI -
MM-Eureka: Exploring the Frontiers of Multimodal Reasoning with Rule-based Reinforcement Learning [arXiv 2025] [Paper] [Code] [HF]
Shanghai AI Laboratory, SenseTime, The University of Hong Kong -
R1-Onevision: Advancing Generalized Multimodal Reasoning through Cross-Modal Formalization [arXiv 2025] [Paper] [Code]
Alibaba Group -
R1-Omni: Explainable Omni-Multimodal Emotion Recognition with Reinforcement Learning [arXiv 2025] [Paper] [Code]
Alibaba Group, Tongji University -
Retrv-R1: A Reasoning-Driven MLLM Framework for Universal and Efficient Multimodal Retrieval [NeurIPS 2025] [Paper] [Code] [Homepage]
City University of Hong Kong
Thinking with Images
-
GRIT: Teaching MLLMs to Think with Images [NeurIPS 2025] [Paper] [Code] [Homepage]
University of California, Santa Cruz (UCSC) -
Point-RFT: Improving Multimodal Reasoning with Visually Grounded Reinforcement Finetuning [arXiv 2025] [Paper]
Harbin Institute of Technology, Microsoft Research -
OpenThinkIMG: Learning to Think with Images via Visual Tool Reinforcement Learning [arXiv 2025] [Paper] [Code] [HF]
Shanghai Jiao Tong University, Microsoft Research, The Chinese University of Hong Kong (CUHK) -
VisionReasoner: Unified Reasoning-Integrated Visual Perception via Reinforcement Learning [arXiv 2025] [Paper] [Code]
The Chinese University of Hong Kong (CUHK), SmartMore -
DeepEyes: Incentivizing "Thinking with Images" via Reinforcement Learning [ICLR 2026] [Paper] [Code] [HF]
Visual Agent -
VTool-R1: VLMs Learn to Think with Images via Reinforcement Learning on Multimodal Tool Use [ICLR 2026] [Paper] [Code] [Homepage]
University of Illinois Urbana-Champaign (UIUC), University of Michigan -
Visual Planning: Let's Think Only with Images [ICLR 2026] [Paper] [Code]
University of Cambridge -
LanteRn: Latent Visual Structured Reasoning [arXiv 2026] [Paper] [Code] [HF]
Instituto Superior Técnico, TU Darmstadt
Multimodal Self-Evolving
-
VIGC: Visual Instruction Generation and Correction [AAAI 2024] [Paper] [Code] [Homepage]
Shanghai AI Laboratory, SenseTime -
MindGYM: Enhancing Vision-Language Models via Synthetic Self-Challenging Questions [NeurIPS 2025] [Paper] [Code]
Sun Yat-sen University, Alibaba Group -
SRPO: Enhancing Multimodal LLM Reasoning via Reflection-Aware Reinforcement Learning [NeurIPS 2025] [Paper] [Code] [Homepage]
ByteDance Seed -
LLaVA-Critic: Learning to Evaluate Multimodal Models [CVPR 2025] [Paper] [Code] [Homepage]
University of Maryland, ByteDance -
MM-UPT: Unsupervised Post-Training for Multi-Modal LLM Reasoning via GRPO [NeurIPS 2025] [Paper] [Code] [HF]
Shanghai Jiao Tong University, Lehigh University -
LLaVA-Critic-R1: Your Critic Model is Secretly a Strong Policy Model [arXiv 2025] [Paper] [Code]
University of Maryland, Microsoft Research
Multimodal Distillation
-
LLaVA-KD: A Framework of Distilling Multimodal Large Language Models [ICCV 2025] [Paper] [Code]
Huazhong University of Science and Technology, Tencent Youtu Lab -
LLAVADI: What Matters For Multimodal Large Language Models Distillation [arXiv 2024] [Paper]
Peking University, Nanyang Technological University, University of California, Merced -
LLaVA-MoD: Making LLaVA Tiny via MoE Knowledge Distillation [arXiv 2024] [Paper] [Code]
MBZUAI, Alibaba Group, The Chinese University of Hong Kong (CUHK) -
Video-OPD: Efficient Post-Training of Multimodal Large Language Models for Temporal Video Grounding via On-Policy Distillation [arXiv 2026] [Paper]
Tencent AI Lab -
X-OPD: Cross-Modal On-Policy Distillation for Capability Alignment in Speech LLMs [arXiv 2026] [Paper]
Kuaishou, Microsoft Research Asia -
Uni-OPD: Unifying On-Policy Distillation with a Dual-Perspective Recipe [arXiv 2026] [Paper] [Code]
Zhejiang University, Alibaba Group -
Vision-OPD: Learning to See Fine Details for Multimodal LLMs via On-Policy Self-Distillation [arXiv 2026] [Paper] [Code]
Institute of Software, Chinese Academy of Sciences -
VA-OPD: Visual-Advantage On-Policy Distillation for Vision-Language Models [arXiv 2026] [Paper]
Institute of Automation, Chinese Academy of Sciences, Meituan
Multimodal Domain Adaptation
-
Mobile-Agent: Autonomous Multi-Modal Mobile Device Agent with Visual Perception [ICLR 2024 Workshop] [Paper] [Code]
Beijing Jiaotong University, Alibaba Group -
GUI-R1: A Generalist R1-Style Vision-Language Action Model For GUI Agents [arXiv 2025] [Paper] [Code]
National University of Singapore, Chinese Academy of Sciences, University of Chinese Academy of Sciences -
mPLUG-DocOwl 1.5: Unified Structure Learning for OCR-free Document Understanding [EMNLP 2024] [Paper] [Code]
Alibaba Group -
LLaVA-UHD: an LMMPerceiving Any Aspect Ratio and High-Resolution Images [arXiv 2024] [Paper] [Code]
Ruyi Xu, Yuan Yao, Zonghao Guo, Junbo Cui, Zanlin Ni, Chunjiang Ge, Tat-Seng Chua, Zhiyuan Liu, Maosong Sun, Gao Huang -
Capabilities of Gemini Models in Medicine [arXiv 2024] [Paper]
Google Research, Google DeepMind, Verily Life Sciences, Apollo Radiology International, Northwestern Medicine, EyePACS, DeepHealth/RadNet -
On Domain-Specific Post-Training for Multimodal Large Language Models [EMNLP 2025 Findings] [Paper] [Code] [Homepage]
BIGAI, Beihang University, Tsinghua University, Beijing Institute of Technology, Renmin University of China
Multimodal Scalable Training
LoRA-based Methods
-
LLaVA-MoLE: Sparse Mixture of LoRA Experts for Mitigating Data Conflicts in Instruction Finetuning MLLMs [arXiv 2024] [Paper] [Code]
Meituan Inc. -
MixLoRA: Enhancing Large Language Models Fine-Tuning with LoRA-based Mixture of Experts [arXiv 2024] [Paper] [Code]
Sichuan University, Purdue University, Nanyang Technological University, Emory University -
MoKA: Mixture of Kronecker Adapters [arXiv 2025] [Paper] [Code] [Homepage]
Renmin University of China, Beijing Key Laboratory of Research on Large Models and Intelligent Governance, Engineering Research Center of Next-Generation Intelligent Search and Recommendation, Shanghai AI Laboratory -
LoRA in LoRA: Towards Parameter-Efficient Architecture Expansion for Continual Visual Instruction Tuning [AAAI 2026] [Paper] [Code]
Hefei University of Technology, University of Amsterdam, Tsinghua University
MoE-based Methods
-
MoE-LLaVA: Mixture of Experts for Large Vision-Language Models [TMM 2025] [Paper] [Code]
Peking University -
MoE-LLaVA: Mixture of Experts for Large Vision-Language Models [TMM 2025] [Paper] [Code]
Peking University -
MoExtend: Tuning New Experts for Modality and Task Extension [ACL SRW 2024] [Paper] [Code]
Sun Yat-sen University, Harvard University, Singapore Management University -
Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution [arXiv 2024] [Paper] [Code]
ByteDance, S-Lab, NTU, CUHK, HKUST -
Qwen3-Omni Technical Report [arXiv 2025] [Paper] [Code]
Qwen Team, Alibaba Cloud -
Qwen3-VL Technical Report [arXiv 2025] [Paper] [Code]
Qwen Team, Alibaba Cloud -
MiniMax-01: Scaling Foundation Models with Lightning Attention [arXiv 2025] [Paper] [Code]
MiniMax -
Seed1.5-VL Technical Report [arXiv 2025] [Paper] [Code] [Homepage]
ByteDance Seed
Compute-efficient Methods
Efficient Visual Processing (EVP)
-
LLaVA-UHD: an LMMPerceiving Any Aspect Ratio and High-Resolution Images [arXiv 2024] [Paper] [Code]
Ruyi Xu, Yuan Yao, Zonghao Guo, Junbo Cui, Zanlin Ni, Chunjiang Ge, Tat-Seng Chua, Zhiyuan Liu, Maosong Sun, Gao Huang -
Learning to Inference Adaptively for Multimodal Large Language Models [ICCV 2025] [Paper] [Code] [Homepage]
University of Wisconsin-Madison, Purdue University, The University of Hong Kong -
InternVL2: Better than the Best-Expanding Performance Boundaries of Open-Source Multimodal Models with the Progressive Scaling Strategy [arXiv 2024] [Paper] [Code] [Homepage]
OpenGVLab, Shanghai AI Laboratory -
UReader: Universal OCR-free Visually-situated Language Understanding with Multimodal Large Language Model [EMNLP 2023] [Paper] [Code]
Alibaba Group -
Monkey:ImageResolutionandText Label Are Important Things for Large Multi-modal Models [CVPR 2024] [Paper] [Code]
Huazhong University of Science and Technology, Kingsoft Office
Token Compression (TC)
-
An Image is Worth 1/2 Tokens After Layer 2: Plug-and-Play Inference Acceleration for Large Vision-Language Models [ECCV 2024] [Paper] [Code]
National Key Laboratory for Multimedia Information Processing, Peking University, Alibaba Group -
VisionZip: Longer is Better but Not Necessary in Vision Language Models [CVPR 2025] [Paper] [Code]
The Chinese University of Hong Kong, The Hong Kong University of Science and Technology, Harbin Institute of Technology, Shenzhen -
SparseVLM: Visual Token Sparsification for Efficient Vision-Language Model Inference [ICML 2025] [Paper] [Code] [Homepage]
Peking University, Fudan University, University of California Berkeley, Panasonic Holdings Corporation -
TokenPacker: Efficient Visual Projector for Multimodal LLM [IJCV 2025] [Paper] [Code]
Zhejiang University, Ant Group, Nanjing University of Aeronautics and Astronautics, The Hong Kong Polytechnic University
Long-Context Optimization (LCO)
-
BIOSCAN-5M: A Multimodal Dataset for Insect Biodiversity [NeurIPS 2024] [Paper] [Code] [Homepage]
Centre for Biodiversity Genomics, University of Guelph, University of Waterloo, Simon Fraser University, Vector Institute, Institute (Amii), Aalborg University and Pioneer Centre for AI -
LongVILA: Scaling Long-Context Visual Language Models for Long Videos [ICLR 2025] [Paper] [Code]
NVIDIA, MIT -
Long Context Transfer from Language to Vision [TMLR 2025] [Paper] [Code]
LMMs-Lab, S-Lab, Nanyang Technological University, Singapore University of Technology and Design -
An Image Grid Can Be Worth a Video: Zero-shot Video Question Answering Using a VLM [IEEE Access 2024] [Paper] [Code]
Seoul National University -
VideoChat-Flash: Hierarchical Compression for Long-Context Video Modeling [arXiv 2025] [Paper] [Code]
Shanghai AI Laboratory, Nanjing University, Shenzhen Institutes of Advanced Technology, Chinese Academy of Sciences, Shanghai Innovation Institute
Multimodal Benchmarks
Instruction Tuning Benchmarks
-
Visual Instruction Tuning [NeurIPS 2023] [Paper] [Code] [Data]
University of Wisconsin–Madison, Microsoft Research, Columbia University -
SEED-Bench: Benchmarking Multimodal LLMs with Generative Comprehension [CVPR 2024] [Paper] [Code] [Data]
Tencent AI Lab, ARC Lab, Tencent PCG -
MM-Vet: Evaluating Large Multimodal Models for Integrated Capabilities [ICML 2024] [Paper] [Code] [Data]
National University of Singapore, Microsoft Azure AI -
MMBench: Is Your Multi-modal Model an All-around Player? [ECCV 2024] [Paper] [Code] [Data]
Shanghai AI Laboratory, Nanyang Technological University, The Chinese University of Hong Kong, National University of Singapore, Zhejiang University -
ShareGPT4V: Improving Large Multi-Modal Models with Better Captions [ECCV 2024] [Paper] [Code] [Data]
University of Science and Technology of China, Shanghai AI Laboratory -
MIA-Bench: Towards Better Instruction Following Evaluation of Multimodal LLMs [ICLR 2025] [Paper] [Code] [Data]
Apple, The Hong Kong University of Science and Technology -
MM-IFEngine: Towards Multimodal Instruction Following [ICCV 2025] [Paper] [Code] [Data] [Homepage]
Fudan University, Shanghai Innovation Institute -
MME: A Comprehensive Evaluation Benchmark for Multimodal Large Language Models [NeurIPS 2025] [Paper] [Code] [Data]
Nanjing University, Tencent Youtu Lab, Xiamen University, CASIA -
Empowering Reliable Visual-Centric Instruction Following in MLLMs [ACL Findings 2026] [Paper] [Code] [Data]
The Hong Kong University of Science and Technology, Pennsylvania State University
Others: VQAv2, GQA, OK-VQA, TextVQA, VizWiz, Visual7W, BLINK, MME-RealWorld, M3IT, ShareGPT4Video, VideoMME
Alignment Learning Benchmarks
-
Evaluating Object Hallucination in Large Vision-Language Models [EMNLP 2023] [Paper] [Code] [Data]
Gaoling School of Artificial Intelligence, Renmin University of China, School of Information, Renmin University of China, Beijing Key Laboratory of Big Data Management and Analysis Methods, Meituan Group -
ALIGNING LARGE MULTIMODAL MODELS WITH FACTUALLY AUGMENTED RLHF [ACL Findings 2024] [Paper] [Code] [Data]
UC Berkeley, Carnegie Mellon University, University of Illinois Urbana-Champaign, University of Wisconsin-Madison, University of Massachusetts Amherst, Microsoft Research, MIT-IBM Watson AI Lab -
AMBER: An LLM-free Multi-dimensional Benchmark for MLLMs Hallucination Evaluation [arXiv 2023] [Paper] [Code] [Data]
Beijing Jiaotong University, Alibaba Group, Peng Cheng Laboratory -
HallusionBench: An Advanced Diagnostic Suite for Entangled Language Hallucination and Visual Illusion in Large Vision-Language Models [CVPR 2024] [Paper] [Code] [Data]
University of Maryland, College Park -
ALIGNING LARGE MULTIMODAL MODELS WITH FACTUALLY AUGMENTED RLHF [ACL Findings 2024] [Paper] [Code] [Data]
UC Berkeley, Carnegie Mellon University, University of Illinois Urbana-Champaign, University of Wisconsin-Madison, University of Massachusetts Amherst, Microsoft Research, MIT-IBM Watson AI Lab -
RLHF-V: Towards Trustworthy MLLMs via Behavior Alignment from Fine-grained Correctional Human Feedback [CVPR 2024] [Paper] [Code] [Data]
Tsinghua University, National University of Singapore -
Safety Fine-Tuning at (Almost) No Cost: A Baseline for Vision Large Language Models [ICML 2024] [Paper] [Code] [Data] [Homepage]
University of Edinburgh, EPFL -
SPA-VL: A Comprehensive Safety Preference Alignment Dataset for Vision Language Models [CVPR 2025] [Paper] [Code] [Data]
University of Science and Technology of China, Shanghai AI Laboratory -
Lingua-SafetyBench: A Benchmark for Safety Evaluation of Multilingual Vision-Language Models [arXiv 2026] [Paper] [Code] [Data]
Nanjing University of Science and Technology, University of Wisconsin-Madison, University of Chinese Academy of Sciences, National University of Singapore
Others: CHAIR, M-HalDetect, HaELM, MM-SafetyBench, FigStep, JailBreakV-28K, RTVLM
Reasoning Enhancement Benchmarks
-
Learn to Explain: Multimodal Reasoning via Thought Chains for Science Question Answering [NeurIPS 2022] [Paper] [Code] [Data]
University of California, Los Angeles, Arizona State University, Allen Institute for AI -
GQA: A New Dataset for Real-World Visual Reasoning and Compositional Question Answering [CVPR 2019] [Paper] [Code] [Data]
Stanford University -
MMMU: A Massive Multi-discipline Multimodal Understanding and Reasoning Benchmark for Expert AGI [CVPR 2024] [Paper] [Code] [Data]
IN.AI Research, University of Waterloo, The Ohio State University, Carnegie Mellon University, University of Victoria, Princeton University -
MathVista: Evaluating Mathematical Reasoning of Foundation Models in Visual Contexts [ICLR 2024] [Paper] [Code] [Data]
UCLA, University of Washington, Microsoft Research, Redmond -
PuzzleBench: A Fully Dynamic Evaluation Framework for Large Multimodal Models on Puzzle Solving [arXiv 2025] [Paper]
Shanghai Jiao Tong University -
MME-CoT: Benchmarking Chain-of-Thought in Large Multimodal Models for Reasoning Quality, Robustness, and Efficiency [arXiv 2025] [Paper] [Code] [Data] [Homepage]
The Chinese University of Hong Kong, ByteDance, Northeastern University -
MME-Reasoning: A Comprehensive Benchmark for Logical Reasoning in MLLMs [arXiv 2025] [Paper] [Code] [Data] [Homepage]
Fudan University, The Chinese University of Hong Kong, Shanghai AI Laboratory -
A Diagram Is Worth A Dozen Images [ECCV 2016] [Paper] [Code] [Data]
Allen Institute for Artificial Intelligence, University of Washington
Others: CLEVR, OlympiadBench, MathVision, MMMU-Pro, PuzzleVQA, GPQA
Domain Adaptation Benchmarks
-
DocVQA: A Dataset for VQA on Document Images [WACV 2021] [Paper] [Code] [Data]
CVIT, IIIT Hyderabad, India, Computer Vision Center, UAB, Spain -
ChartX & ChartVLM: A Versatile Benchmark and Foundation Model for Complicated Chart Reasoning [TIP 2025] [Paper] [Code] [Data]
Shanghai AI Laboratory, Shanghai Jiao Tong University -
OCRBench: On the Hidden Mystery of OCR in Large Multimodal Models [Science China Information Sciences 2024] [Paper] [Code] [Data]
Shanghai AI Laboratory -
SeeClick: Harnessing GUI Grounding for Advanced Visual GUI Agents [ACL 2024] [Paper] [Code] [Data]
The Chinese University of Hong Kong, Shanghai AI Laboratory -
Mind2Web: Towards a Generalist Agent for the Web [NeurIPS 2023] [Paper] [Code] [Data]
The Ohio State University -
A Dataset of Clinically Generated Visual Questions and Answers about Radiology Images [Scientific Data 2018] [Paper] [Code] [Data]
National Library of Medicine, National Institutes of Health -
PathVQA: 30000+ Questions for Medical Visual Question Answering [arXiv 2020] [Paper] [Code] [Data]
University of California San Diego, Carnegie Mellon University
Others: AndroidControl-Low, AndroidControl-High, GUI-Odyssey, ScreenSpot-Pro, GUI-Act-Web, OmniAct-Web, ChartQA, InfoVQA, TextVQA, ST-VQA
📌 Citation
If this repository or the associated survey is useful for your research, please consider citing the original survey paper and acknowledging this curated paper list.
@article{zhang2026survey,
  title={A Survey on Post-Training of Multimodal Large Language Models},
  author={Haonan Zhang and Pengpeng Zeng and Libin Cao and Wenrui Lai and
          Jinlong Li and Duo Peng and Yi Bin and Xuanhan Wang and Ji Zhang and
          Jingkuan Song and Nicu Sebe and Yuchuan Wu and Yongbin Li and
          Heng Tao Shen and Jieping Ye},
  year={2026},
  publisher={Preprints}
}


Similar repos


A curated list of "A Survey on Post-training of Multimodal Large Language Models" research. Watch this repository for latest updates! 🔥
See the codeREADME
Watch this repository for the latest updates!
Feel free to raise pull requests if you find some interesting papers! 🌟
News
[2026/07/22] 🎉 We release our Paper and Project Page!
[2026/07/19] 🎉 We release our curation list of MLLMs Post-Training methods!
Introduction
Multimodal Large Language Models (MLLMs) have reshaped AI by enabling perception, reasoning, and interaction across digital and physical environments. While multimodal pretraining establishes broad perceptual capabilities, translating them into behaviors aligned with human intent and real-world demands remains challenging. Multimodal Post-Training (MMPoT) addresses this gap by refining pretrained MLLMs toward reliable, task-oriented behavior. This survey reviews MMPoT from a behavior-shaping perspective and organizes existing methods into five families: instruction following, preference calibration, reasoning enhancement, domain adaptation, and scalable training. We further examine benchmarks and evaluation protocols, identify current limitations, and outline future directions toward general and reliable multimodal intelligence.
Figure 1. Overview of multimodal behavior shaping for MLLMs post-training. Post-training algorithms can be viewed as behavior-shaping mechanisms that steer pretrained MLLMs toward desired behaviors, while multimodal data and benchmarks provide learning signals and evaluative feedback for iterative refinement.
Contents
Figure 2. A timeline of MLLMs post-training research.
Multimodal Instruction Tuning
-
Visual Instruction Tuning [NeurIPS 2023] [Paper] [Code] [Homepage]
University of Wisconsin–Madison, Microsoft Research, Columbia University -
MiniGPT-4: Enhancing Vision-Language Understanding with Advanced Large Language Models [ICLR 2024] [Paper] [Code] [Homepage]
King Abdullah University of Science and Technology -
InstructBLIP: Towards General-purpose Vision-Language Models with Instruction Tuning [NeurIPS 2023] [Paper] [Code]
Salesforce Research, Hong Kong University of Science and Technology, Nanyang Technological University, Singapore -
mPLUG-Owl: Modularization Empowers Large Language Models with Multimodality [arXiv 2023] [Paper] [Code]
DAMO Academy, Alibaba Group -
LLaMA-Adapter V2: Parameter-Efficient Visual Instruction Model [arXiv 2023] [Paper] [Code]
Shanghai Artificial Intelligence Laboratory, CUHK MMLab, Rutgers University -
Improved Baselines with Visual Instruction Tuning [CVPR 2024] [Paper] [Code] [Homepage]
University of Wisconsin–Madison, Microsoft Research, Redmond -
Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond [arXiv 2023] [Paper] [Code]
Alibaba Group -
CogVLM: Visual Expert for Pretrained Language Models [NeurIPS 2024] [Paper] [Code]
Tsinghua University, Zhipu AI -
InternVL: Scaling up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks [CVPR 2024] [Paper] [Code]
OpenGVLab, Shanghai AI Laboratory, Nanjing University, The University of Hong Kong, The Chinese University of Hong Kong, Tsinghua University, University of Science and Technology of China, SenseTime Research -
LLaVA-NeXT: Improved Reasoning, OCR, and World Knowledge [arXiv 2024] [Paper] [Code] [Homepage]
University of Wisconsin-Madison, Microsoft Research -
What matters when building vision-language models? [NeurIPS 2024] [Paper] [HF]
Hugging Face, Sorbonne Université -
Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution [arXiv 2024] [Paper] [Code]
ByteDance, S-Lab, NTU, CUHK, HKUST -
LLaVA-OneVision: Easy Visual Task Transfer [TMLR 2025] [Paper] [Code] [Homepage]
ByteDance, S-Lab, NTU, CUHK, HKUST -
Expanding Performance Boundaries of Open-Source Multimodal Models with Model, Data, and Test-Time Scaling [arXiv 2024] [Paper] [Code] [Homepage]
Shanghai AI Laboratory, SenseTime Research, Tsinghua University, Nanjing University, Fudan University, The Chinese University of Hong Kong, Shanghai Jiao Tong University -
Qwen2.5-VL Technical Report [arXiv 2025] [Paper] [Code]
Alibaba Group -
VILA: On Pre-training for Visual Language Models [CVPR 2024] [Paper] [Code]
NVIDIA, MIT -
MobileVLM : A Fast, Strong and Open Vision Language Assistant for Mobile Devices [arXiv 2023] [Paper] [Code]
Meituan Inc., Zhejiang University, China, Dalian University of Technology, China -
DeepSeek-VL: Towards Real-World Vision-Language Understanding [arXiv 2024] [Paper] [Code]
DeepSeek-AI -
Yi: Open Foundation Models by 01.AI [arXiv 2024] [Paper] [Code] [HF]
01.AI -
Cambrian-1: A Fully Open, Vision-Centric Exploration of Multimodal LLMs [NeurIPS 2024] [Paper] [Code] [Homepage]
New York University -
MiniCPM-V: A GPT-4V Level MLLM on Your Phone [arXiv 2024] [Paper] [Code] [Homepage]
OpenBMB -
Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone [arXiv 2024] [Paper] [HF]
Microsoft -
The Llama 3 Herd of Models [arXiv 2024] [Paper] [HF] [Homepage]
Meta -
Molmo and PixMo: Open Weights and Open Data for State-of-the-Art Vision-Language Models [CVPR 2025] [Paper] [Code] [Homepage]
Allen Institute for AI, University of Washington -
Comparison Visual Instruction Tuning [CVPR 2025 Workshop] [Paper] [Code] [Homepage] [HF]
ELLIS Unit, LIT AI Lab, Institute for Machine Learning, JKU Linz, Austria, TU Graz ICG, Austria, IBM Research, Israel, Weizmann Institute of Science, Israel, Tel-Aviv University, Israel, NXAI GmbH, Austria, MIT-IBM Watson AI Lab, USA -
PaliGemma: A versatile 3B VLM for transfer [arXiv 2024] [Paper] [HF]
Google DeepMind -
Otter: A Multi-Modal Model with In-Context Instruction Tuning [TPAMI 2025] [Paper] [Code]
S-Lab, Nanyang Technological University, Microsoft Research -
LLaMA-Adapter: Efficient Fine-tuning of Language Models with Zero-init Attention [ICLR 2024] [Paper] [Code]
Shanghai Artificial Intelligence Laboratory, CUHK MMLab, University of California, Los Angeles, CPII of InnoHK -
Cheap and Quick: Efficient Vision-Language Instruction Tuning for Large Language Models [NeurIPS 2023] [Paper] [Code]
Key Laboratory of Multimedia Trusted Perception and Efficient Computing, Ministry of Education of China, School of Informatics, Xiamen University, 361005, P.R. China., Institute of Artificial Intelligence, Xiamen University, 361005, P.R. China., Peng Cheng Laboratory, Shenzhen, 518000, China. -
Valley: Video Assistant with Large Language model Enhanced abilitY [arXiv 2023] [Paper] [Code]
ByteDance Inc., Fudan University, East China Normal University -
NExT-GPT: Any-to-Any Multimodal LLM [ICML 2024] [Paper] [Code] [Homepage]
National University of Singapore -
InternVL: Scaling up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks [CVPR 2024] [Paper] [Code]
OpenGVLab, Shanghai AI Laboratory, Nanjing University, The University of Hong Kong, The Chinese University of Hong Kong, Tsinghua University, University of Science and Technology of China, SenseTime Research -
Generative Visual Instruction Tuning [arXiv 2024] [Paper] [Code]
Rice University, Google DeepMind -
MLAN: Language-Based Instruction Tuning Preserves and Transfers Knowledge in Multimodal Language Models [arXiv 2024] [Paper]
Washington University in St. Louis, The University of British Columbia, Google Research, Virginia Tech, University of California, Davis, Sony AI, University of California, Berkeley -
INST-IT: Boosting Instance Understanding via Explicit Visual Prompt Instruction Tuning [NeurIPS 2025] [Paper] [Code] [Homepage]
Institute of Trustworthy Embodied AI, Fudan University, Shanghai Innovation Institute, Huawei Noah, s Ark Lab -
Learning to Instruct for Visual Instruction Tuning [NeurIPS 2025] [Paper] [Code]
Cooperative Medianet Innovation Center, Shanghai Jiao Tong University, Microsoft Research Asia, Hong Kong Baptist University, School of Artificial Intelligence, Shanghai Jiao Tong University -
Visual Compositional Tuning [ICLR 2026 Workshop] [Paper] [Code] [Homepage]
Princeton University, Meta AI -
Visual Instruction Bottleneck Tuning [NeurIPS 2025] [Paper] [Code]
Department of Computer Sciences, University of Wisconsin–Madison -
LLaDA-V: Large Language Diffusion Models with Visual Instruction Tuning [arXiv 2025] [Paper] [Code] [Homepage]
Gaoling School of AI, Renmin University of China, Beijing Key Laboratory of Research on Large Models and Intelligent Governance, Engineering Research Center of Next-Generation Intelligent Search and Recommendation, MOE, Ant Group -
Less Data, Faster Convergence: Goal-Driven Data Optimization for Multimodal Instruction Tuning [ECCV 2026] [Paper] [Code]
Peking University, University of Illinois at Urbana-Champaign, National University of Singapore -
LLaVA-NeXT-Interleave: Tackling Multi-image, Video, and 3D in Large Multimodal Models [ICLR 2025] [Paper] [Code] [Homepage]
ByteDance, HKUST, CUHK, NTU -
MAVIS: Mathematical Visual Instruction Tuning with an Automatic Data Engine [ICLR 2025] [Paper] [Code]
CUHK, Peking University, Shanghai AI Laboratory, ByteDance, Oracle -
MANTIS: Interleaved Multi-Image Instruction Tuning [TMLR 2024] [Paper] [Code] [Homepage]
University of Waterloo, Tsinghua University, Sea AI Lab -
ImageBind-LLM: Multi-modality Instruction Tuning [arXiv 2023] [Paper] [Code]
Shanghai Artificial Intelligence Laboratory, Shanghai, 200030, China., CUHK MMLab, Hong Kong SAR, 999077, China., vivo AI Lab, Shenzhen, 518000, China. -
ShareGPT4V: Improving Large Multi-Modal Models with Better Captions [ECCV 2024] [Paper] [Code] [Homepage]
University of Science and Technology of China, Shanghai AI Laboratory -
MiniGPT-v2: large language model as a unified interface for vision-language multi-task learning [arXiv 2023] [Paper] [Code] [Homepage]
King Abdullah University of Science and Technology (KAUST), Meta AI Research -
ViP-LLaVA: Making Large Multimodal Models Understand Arbitrary Visual Prompts [CVPR 2024] [Paper] [Code] [Homepage]
University of Wisconsin–Madison;Cruise LLC -
MoAI: Mixture of All Intelligence for Large Language and Vision Models [ECCV 2024] [Paper] [Code]
School of Electrical Engineering Korea Advanced Institute of Science and Technology (KAIST) -
Monkey :ImageResolutionandText Label Are Important Things for Large Multi-modal Models [CVPR 2024] [Paper] [Code]
Huazhong University of Science and Technology, Kingsoft Office -
Mini-Gemini: Mining the Potential of Multi-modality Vision Language Models [TPAMI 2026] [Paper] [Code]
The Chinese University of Hong Kong;SmartMore -
Feast Your Eyes: Mixture-of-Resolution Adaptation for Multimodal Large Language Models [ICLR 2025] [Paper] [Code]
Xiamen University -
SPHINX: The Joint Mixing of Weights, Tasks, and Visual Embeddings for Multi-modal Large Language Models [arXiv 2023] [Paper] [Code]
Shanghai AI Laboratory;MMLab, CUHK;ShanghaiTech University
Multimodal Preference Calibration
Multimodal RLHF
-
ALIGNING LARGE MULTIMODAL MODELS WITH FACTUALLY AUGMENTED RLHF [ACL Findings 2024] [Paper] [Code] [Homepage]
UC Berkeley, Carnegie Mellon University, University of Illinois Urbana-Champaign, University of Wisconsin-Madison, University of Massachusetts Amherst, Microsoft Research, MIT-IBM Watson AI Lab -
RLHF-V: Towards Trustworthy MLLMs via Behavior Alignment from Fine-grained Correctional Human Feedback [CVPR 2024] [Paper] [Code] [Homepage]
Tsinghua University, National University of Singapore -
VisualPRM: An Effective Process Reward Model for Multimodal Reasoning [arXiv 2025] [Paper] [Homepage]
Shanghai AI Laboratory, SenseTime Research, Zhejiang University -
Gemini: A Family of Highly Capable Multimodal Models [arXiv 2023] [Paper] [Homepage]
Google -
Seed1.5-VL Technical Report [arXiv 2025] [Paper] [Code] [Homepage]
ByteDance Seed -
MiMo-VL Technical Report [arXiv 2025] [Paper] [Code]
LLM-Core Xiaomi
Multimodal RLAIF
-
Tuning Large Multimodal Models for Videos using Reinforcement Learning from AI Feedback [ACL 2024] [Paper] [Code] [Homepage]
Yonsei University, University of Minnesota, Seoul National University -
RLAIF-V: Open-Source AI Feedback Leads to Super GPT-4V Trustworthiness [CVPR 2025] [Paper] [Code]
Tsinghua University, Shanghai Qi Zhi Institute, Harbin Institute of Technology, Taobao & Tmall Group of Alibaba, Peng Cheng Laboratory, National University of Singapore -
Oracle-RLAIF: An Improved Fine-Tuning Framework for Multi-modal Video Models using Reinforcement Learning from Ranking Feedback [arXiv 2025] [Paper]
Stanford University, xAI, Microsoft
Multimodal Direct Preference Optimization
-
Silkie: Preference Distillation for Large Visual Language Models [arXiv 2023] [Paper] [Code] [Homepage]
University of Hong Kong, The Chinese University of Hong Kong, Shenzhen, Peng Cheng Laboratory -
Direct Preference Optimization of Video Large Multimodal Models from Language Model Reward [NAACL 2025] [Paper] [Code]
CMULTI, Bytedance, UT Austin, Columbia University, NTU -
ISR-DPO: Aligning Large Multimodal Models for Videos by Iterative Self-Retrospective DPO [AAAI 2025] [Paper] [Code] [Homepage]
Seoul National University, Yonsei University, University of Minnesota -
Beyond Hallucinations: Enhancing LVLMs through Hallucination-Aware Direct Preference Optimization [arXiv 2023] [Paper] [Code] [Homepage]
Shanghai AI Laboratory -
Mitigating Hallucination in Multimodal Large Language Model via Hallucination-targeted Direct Preference Optimization [arXiv 2024] [Paper]
Key Lab of DEKE, Renmin University of China, Machine Learning Platform Department, Tencent -
V-DPO: Mitigating Hallucination in Large Vision Language Models via Vision-Guided Direct Preference Optimization [EMNLP 2024] [Paper] [Code]
National University of Singapore -
CLIP-DPO: Vision-Language Models as a Source of Preference for Fixing Hallucinations in LVLMs [ECCV 2024] [Paper]
Samsung AI Center Cambridge, UK, Technical University of Iasi, Romania, Queen Mary University of London, UK -
Mitigating Hallucinations in Multimodal LLMs via Object-aware Preference Optimization [BMVC 2025] [Paper] [Code]
University of Modena and Reggio Emilia -
MDPO: Conditional Preference Optimization for Multimodal Large Language Models [EMNLP 2024] [Paper] [Code] [Homepage]
University of Southern California, Microsoft Research, University of California, Davis -
PEA-DPO: Perception-Enhanced Alignment Direct Preference Optimization for MLLMs Alignment [OpenReview 2026] [Paper] [Homepage]
University of Science and Technology of China -
MoD-DPO: Towards Mitigating Cross-modal Hallucinations in Omni LLMs using Modality Decoupled Preference Optimization [CVPR 2026] [Paper] [Homepage]
University of Southern California -
OMNI DPO: A Preference Optimization Framework to Address Omni-Modal Hallucination [arXiv 2025] [Paper]
Tsinghua University, Hong Kong University of Science and Technology (Guangzhou), OpenRL, Chongqing University -
DA-DPO: Cost-efficient Difficulty-aware Preference Optimization for Reducing MLLM Hallucinations [TMLR 2025] [Paper] [Code] [Homepage]
ShanghaiTech University, Lingang Laboratory, Shanghai Engineering Research Center of Intelligent Vision and Imaging -
Uncertainty-Aware Exploratory Direct Preference Optimization for Multimodal Large Language Models [arXiv 2026] [Paper]
University of Science and Technology of China -
Mitigating Hallucinations in Large Vision-Language Models via DPO: On-Policy Data Hold the Key [CVPR 2025] [Paper] [Code] [Homepage]
The Chinese University of Hong Kong, Microsoft Research Asia, The Chinese University of Hong Kong, Shenzhen Research Institute -
LPOI: Listwise Preference Optimization for Vision Language Models [ACL 2025] [Paper] [Code]
Seoul National University
Multimodal Reason Enhancement
R1-based Multimodal Reasoning
-
LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL [arXiv 2025] [Paper] [Code] [Homepage]
Southeast University, The Chinese University of Hong Kong, Fudan University, Ant Group -
VLM-R1: A Stable and Generalizable R1-style Large Vision-Language Model [arXiv 2025] [Paper] [Code]
OM AI Lab -
Visual-RFT: Visual Reinforcement Fine-Tuning [ICCV 2025] [Paper] [Code]
Shanghai AI Laboratory, The Chinese University of Hong Kong (CUHK) -
Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models [ICLR 2026] [Paper] [Code]
East China Normal University, Xiaohongshu Inc. -
VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning [arXiv 2025] [Paper] [Code]
Nanjing University, Shanghai AI Laboratory, The Chinese University of Hong Kong, Shenzhen -
Video-R1: Reinforcing Video Reasoning in MLLMs [NeurIPS 2025] [Paper] [Code]
MMLab, The Chinese University of Hong Kong (CUHK), DataWhale, The Chinese University of Hong Kong, Shenzhen -
VisualPRM: An Effective Process Reward Model for Multimodal Reasoning [arXiv 2025] [Paper] [Homepage]
Shanghai AI Laboratory, SenseTime Research, Zhejiang University -
R1-VL: Learning to Reason with Multimodal Large Language Models via Step-wise Group Relative Policy Optimization [ICCV 2025] [Paper]
Nanyang Technological University (NTU), Nankai University, JD Explore Academy -
R1-Zero's "Aha Moment" in Visual Reasoning on a 2B Non-SFT Model [arXiv 2025] [Paper] [Code]
University of California, Los Angeles (UCLA), TurningPoint AI -
MM-Eureka: Exploring the Frontiers of Multimodal Reasoning with Rule-based Reinforcement Learning [arXiv 2025] [Paper] [Code] [HF]
Shanghai AI Laboratory, SenseTime, The University of Hong Kong -
R1-Onevision: Advancing Generalized Multimodal Reasoning through Cross-Modal Formalization [arXiv 2025] [Paper] [Code]
Alibaba Group -
R1-Omni: Explainable Omni-Multimodal Emotion Recognition with Reinforcement Learning [arXiv 2025] [Paper] [Code]
Alibaba Group, Tongji University -
Retrv-R1: A Reasoning-Driven MLLM Framework for Universal and Efficient Multimodal Retrieval [NeurIPS 2025] [Paper] [Code] [Homepage]
City University of Hong Kong
Thinking with Images
-
GRIT: Teaching MLLMs to Think with Images [NeurIPS 2025] [Paper] [Code] [Homepage]
University of California, Santa Cruz (UCSC) -
Point-RFT: Improving Multimodal Reasoning with Visually Grounded Reinforcement Finetuning [arXiv 2025] [Paper]
Harbin Institute of Technology, Microsoft Research -
OpenThinkIMG: Learning to Think with Images via Visual Tool Reinforcement Learning [arXiv 2025] [Paper] [Code] [HF]
Shanghai Jiao Tong University, Microsoft Research, The Chinese University of Hong Kong (CUHK) -
VisionReasoner: Unified Reasoning-Integrated Visual Perception via Reinforcement Learning [arXiv 2025] [Paper] [Code]
The Chinese University of Hong Kong (CUHK), SmartMore -
DeepEyes: Incentivizing "Thinking with Images" via Reinforcement Learning [ICLR 2026] [Paper] [Code] [HF]
Visual Agent -
VTool-R1: VLMs Learn to Think with Images via Reinforcement Learning on Multimodal Tool Use [ICLR 2026] [Paper] [Code] [Homepage]
University of Illinois Urbana-Champaign (UIUC), University of Michigan -
Visual Planning: Let's Think Only with Images [ICLR 2026] [Paper] [Code]
University of Cambridge -
LanteRn: Latent Visual Structured Reasoning [arXiv 2026] [Paper] [Code] [HF]
Instituto Superior Técnico, TU Darmstadt
Multimodal Self-Evolving
-
VIGC: Visual Instruction Generation and Correction [AAAI 2024] [Paper] [Code] [Homepage]
Shanghai AI Laboratory, SenseTime -
MindGYM: Enhancing Vision-Language Models via Synthetic Self-Challenging Questions [NeurIPS 2025] [Paper] [Code]
Sun Yat-sen University, Alibaba Group -
SRPO: Enhancing Multimodal LLM Reasoning via Reflection-Aware Reinforcement Learning [NeurIPS 2025] [Paper] [Code] [Homepage]
ByteDance Seed -
LLaVA-Critic: Learning to Evaluate Multimodal Models [CVPR 2025] [Paper] [Code] [Homepage]
University of Maryland, ByteDance -
MM-UPT: Unsupervised Post-Training for Multi-Modal LLM Reasoning via GRPO [NeurIPS 2025] [Paper] [Code] [HF]
Shanghai Jiao Tong University, Lehigh University -
LLaVA-Critic-R1: Your Critic Model is Secretly a Strong Policy Model [arXiv 2025] [Paper] [Code]
University of Maryland, Microsoft Research
Multimodal Distillation
-
LLaVA-KD: A Framework of Distilling Multimodal Large Language Models [ICCV 2025] [Paper] [Code]
Huazhong University of Science and Technology, Tencent Youtu Lab -
LLAVADI: What Matters For Multimodal Large Language Models Distillation [arXiv 2024] [Paper]
Peking University, Nanyang Technological University, University of California, Merced -
LLaVA-MoD: Making LLaVA Tiny via MoE Knowledge Distillation [arXiv 2024] [Paper] [Code]
MBZUAI, Alibaba Group, The Chinese University of Hong Kong (CUHK) -
Video-OPD: Efficient Post-Training of Multimodal Large Language Models for Temporal Video Grounding via On-Policy Distillation [arXiv 2026] [Paper]
Tencent AI Lab -
X-OPD: Cross-Modal On-Policy Distillation for Capability Alignment in Speech LLMs [arXiv 2026] [Paper]
Kuaishou, Microsoft Research Asia -
Uni-OPD: Unifying On-Policy Distillation with a Dual-Perspective Recipe [arXiv 2026] [Paper] [Code]
Zhejiang University, Alibaba Group -
Vision-OPD: Learning to See Fine Details for Multimodal LLMs via On-Policy Self-Distillation [arXiv 2026] [Paper] [Code]
Institute of Software, Chinese Academy of Sciences -
VA-OPD: Visual-Advantage On-Policy Distillation for Vision-Language Models [arXiv 2026] [Paper]
Institute of Automation, Chinese Academy of Sciences, Meituan
Multimodal Domain Adaptation
-
Mobile-Agent: Autonomous Multi-Modal Mobile Device Agent with Visual Perception [ICLR 2024 Workshop] [Paper] [Code]
Beijing Jiaotong University, Alibaba Group -
GUI-R1: A Generalist R1-Style Vision-Language Action Model For GUI Agents [arXiv 2025] [Paper] [Code]
National University of Singapore, Chinese Academy of Sciences, University of Chinese Academy of Sciences -
mPLUG-DocOwl 1.5: Unified Structure Learning for OCR-free Document Understanding [EMNLP 2024] [Paper] [Code]
Alibaba Group -
LLaVA-UHD: an LMMPerceiving Any Aspect Ratio and High-Resolution Images [arXiv 2024] [Paper] [Code]
Ruyi Xu, Yuan Yao, Zonghao Guo, Junbo Cui, Zanlin Ni, Chunjiang Ge, Tat-Seng Chua, Zhiyuan Liu, Maosong Sun, Gao Huang -
Capabilities of Gemini Models in Medicine [arXiv 2024] [Paper]
Google Research, Google DeepMind, Verily Life Sciences, Apollo Radiology International, Northwestern Medicine, EyePACS, DeepHealth/RadNet -
On Domain-Specific Post-Training for Multimodal Large Language Models [EMNLP 2025 Findings] [Paper] [Code] [Homepage]
BIGAI, Beihang University, Tsinghua University, Beijing Institute of Technology, Renmin University of China
Multimodal Scalable Training
LoRA-based Methods
-
LLaVA-MoLE: Sparse Mixture of LoRA Experts for Mitigating Data Conflicts in Instruction Finetuning MLLMs [arXiv 2024] [Paper] [Code]
Meituan Inc. -
MixLoRA: Enhancing Large Language Models Fine-Tuning with LoRA-based Mixture of Experts [arXiv 2024] [Paper] [Code]
Sichuan University, Purdue University, Nanyang Technological University, Emory University -
MoKA: Mixture of Kronecker Adapters [arXiv 2025] [Paper] [Code] [Homepage]
Renmin University of China, Beijing Key Laboratory of Research on Large Models and Intelligent Governance, Engineering Research Center of Next-Generation Intelligent Search and Recommendation, Shanghai AI Laboratory -
LoRA in LoRA: Towards Parameter-Efficient Architecture Expansion for Continual Visual Instruction Tuning [AAAI 2026] [Paper] [Code]
Hefei University of Technology, University of Amsterdam, Tsinghua University
MoE-based Methods
-
MoE-LLaVA: Mixture of Experts for Large Vision-Language Models [TMM 2025] [Paper] [Code]
Peking University -
MoE-LLaVA: Mixture of Experts for Large Vision-Language Models [TMM 2025] [Paper] [Code]
Peking University -
MoExtend: Tuning New Experts for Modality and Task Extension [ACL SRW 2024] [Paper] [Code]
Sun Yat-sen University, Harvard University, Singapore Management University -
Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution [arXiv 2024] [Paper] [Code]
ByteDance, S-Lab, NTU, CUHK, HKUST -
Qwen3-Omni Technical Report [arXiv 2025] [Paper] [Code]
Qwen Team, Alibaba Cloud -
Qwen3-VL Technical Report [arXiv 2025] [Paper] [Code]
Qwen Team, Alibaba Cloud -
MiniMax-01: Scaling Foundation Models with Lightning Attention [arXiv 2025] [Paper] [Code]
MiniMax -
Seed1.5-VL Technical Report [arXiv 2025] [Paper] [Code] [Homepage]
ByteDance Seed
Compute-efficient Methods
Efficient Visual Processing (EVP)
-
LLaVA-UHD: an LMMPerceiving Any Aspect Ratio and High-Resolution Images [arXiv 2024] [Paper] [Code]
Ruyi Xu, Yuan Yao, Zonghao Guo, Junbo Cui, Zanlin Ni, Chunjiang Ge, Tat-Seng Chua, Zhiyuan Liu, Maosong Sun, Gao Huang -
Learning to Inference Adaptively for Multimodal Large Language Models [ICCV 2025] [Paper] [Code] [Homepage]
University of Wisconsin-Madison, Purdue University, The University of Hong Kong -
InternVL2: Better than the Best-Expanding Performance Boundaries of Open-Source Multimodal Models with the Progressive Scaling Strategy [arXiv 2024] [Paper] [Code] [Homepage]
OpenGVLab, Shanghai AI Laboratory -
UReader: Universal OCR-free Visually-situated Language Understanding with Multimodal Large Language Model [EMNLP 2023] [Paper] [Code]
Alibaba Group -
Monkey:ImageResolutionandText Label Are Important Things for Large Multi-modal Models [CVPR 2024] [Paper] [Code]
Huazhong University of Science and Technology, Kingsoft Office
Token Compression (TC)
-
An Image is Worth 1/2 Tokens After Layer 2: Plug-and-Play Inference Acceleration for Large Vision-Language Models [ECCV 2024] [Paper] [Code]
National Key Laboratory for Multimedia Information Processing, Peking University, Alibaba Group -
VisionZip: Longer is Better but Not Necessary in Vision Language Models [CVPR 2025] [Paper] [Code]
The Chinese University of Hong Kong, The Hong Kong University of Science and Technology, Harbin Institute of Technology, Shenzhen -
SparseVLM: Visual Token Sparsification for Efficient Vision-Language Model Inference [ICML 2025] [Paper] [Code] [Homepage]
Peking University, Fudan University, University of California Berkeley, Panasonic Holdings Corporation -
TokenPacker: Efficient Visual Projector for Multimodal LLM [IJCV 2025] [Paper] [Code]
Zhejiang University, Ant Group, Nanjing University of Aeronautics and Astronautics, The Hong Kong Polytechnic University
Long-Context Optimization (LCO)
-
BIOSCAN-5M: A Multimodal Dataset for Insect Biodiversity [NeurIPS 2024] [Paper] [Code] [Homepage]
Centre for Biodiversity Genomics, University of Guelph, University of Waterloo, Simon Fraser University, Vector Institute, Institute (Amii), Aalborg University and Pioneer Centre for AI -
LongVILA: Scaling Long-Context Visual Language Models for Long Videos [ICLR 2025] [Paper] [Code]
NVIDIA, MIT -
Long Context Transfer from Language to Vision [TMLR 2025] [Paper] [Code]
LMMs-Lab, S-Lab, Nanyang Technological University, Singapore University of Technology and Design -
An Image Grid Can Be Worth a Video: Zero-shot Video Question Answering Using a VLM [IEEE Access 2024] [Paper] [Code]
Seoul National University -
VideoChat-Flash: Hierarchical Compression for Long-Context Video Modeling [arXiv 2025] [Paper] [Code]
Shanghai AI Laboratory, Nanjing University, Shenzhen Institutes of Advanced Technology, Chinese Academy of Sciences, Shanghai Innovation Institute
Multimodal Benchmarks
Instruction Tuning Benchmarks
-
Visual Instruction Tuning [NeurIPS 2023] [Paper] [Code] [Data]
University of Wisconsin–Madison, Microsoft Research, Columbia University -
SEED-Bench: Benchmarking Multimodal LLMs with Generative Comprehension [CVPR 2024] [Paper] [Code] [Data]
Tencent AI Lab, ARC Lab, Tencent PCG -
MM-Vet: Evaluating Large Multimodal Models for Integrated Capabilities [ICML 2024] [Paper] [Code] [Data]
National University of Singapore, Microsoft Azure AI -
MMBench: Is Your Multi-modal Model an All-around Player? [ECCV 2024] [Paper] [Code] [Data]
Shanghai AI Laboratory, Nanyang Technological University, The Chinese University of Hong Kong, National University of Singapore, Zhejiang University -
ShareGPT4V: Improving Large Multi-Modal Models with Better Captions [ECCV 2024] [Paper] [Code] [Data]
University of Science and Technology of China, Shanghai AI Laboratory -
MIA-Bench: Towards Better Instruction Following Evaluation of Multimodal LLMs [ICLR 2025] [Paper] [Code] [Data]
Apple, The Hong Kong University of Science and Technology -
MM-IFEngine: Towards Multimodal Instruction Following [ICCV 2025] [Paper] [Code] [Data] [Homepage]
Fudan University, Shanghai Innovation Institute -
MME: A Comprehensive Evaluation Benchmark for Multimodal Large Language Models [NeurIPS 2025] [Paper] [Code] [Data]
Nanjing University, Tencent Youtu Lab, Xiamen University, CASIA -
Empowering Reliable Visual-Centric Instruction Following in MLLMs [ACL Findings 2026] [Paper] [Code] [Data]
The Hong Kong University of Science and Technology, Pennsylvania State University
Others: VQAv2, GQA, OK-VQA, TextVQA, VizWiz, Visual7W, BLINK, MME-RealWorld, M3IT, ShareGPT4Video, VideoMME
Alignment Learning Benchmarks
-
Evaluating Object Hallucination in Large Vision-Language Models [EMNLP 2023] [Paper] [Code] [Data]
Gaoling School of Artificial Intelligence, Renmin University of China, School of Information, Renmin University of China, Beijing Key Laboratory of Big Data Management and Analysis Methods, Meituan Group -
ALIGNING LARGE MULTIMODAL MODELS WITH FACTUALLY AUGMENTED RLHF [ACL Findings 2024] [Paper] [Code] [Data]
UC Berkeley, Carnegie Mellon University, University of Illinois Urbana-Champaign, University of Wisconsin-Madison, University of Massachusetts Amherst, Microsoft Research, MIT-IBM Watson AI Lab -
AMBER: An LLM-free Multi-dimensional Benchmark for MLLMs Hallucination Evaluation [arXiv 2023] [Paper] [Code] [Data]
Beijing Jiaotong University, Alibaba Group, Peng Cheng Laboratory -
HallusionBench: An Advanced Diagnostic Suite for Entangled Language Hallucination and Visual Illusion in Large Vision-Language Models [CVPR 2024] [Paper] [Code] [Data]
University of Maryland, College Park -
ALIGNING LARGE MULTIMODAL MODELS WITH FACTUALLY AUGMENTED RLHF [ACL Findings 2024] [Paper] [Code] [Data]
UC Berkeley, Carnegie Mellon University, University of Illinois Urbana-Champaign, University of Wisconsin-Madison, University of Massachusetts Amherst, Microsoft Research, MIT-IBM Watson AI Lab -
RLHF-V: Towards Trustworthy MLLMs via Behavior Alignment from Fine-grained Correctional Human Feedback [CVPR 2024] [Paper] [Code] [Data]
Tsinghua University, National University of Singapore -
Safety Fine-Tuning at (Almost) No Cost: A Baseline for Vision Large Language Models [ICML 2024] [Paper] [Code] [Data] [Homepage]
University of Edinburgh, EPFL -
SPA-VL: A Comprehensive Safety Preference Alignment Dataset for Vision Language Models [CVPR 2025] [Paper] [Code] [Data]
University of Science and Technology of China, Shanghai AI Laboratory -
Lingua-SafetyBench: A Benchmark for Safety Evaluation of Multilingual Vision-Language Models [arXiv 2026] [Paper] [Code] [Data]
Nanjing University of Science and Technology, University of Wisconsin-Madison, University of Chinese Academy of Sciences, National University of Singapore
Others: CHAIR, M-HalDetect, HaELM, MM-SafetyBench, FigStep, JailBreakV-28K, RTVLM
Reasoning Enhancement Benchmarks
-
Learn to Explain: Multimodal Reasoning via Thought Chains for Science Question Answering [NeurIPS 2022] [Paper] [Code] [Data]
University of California, Los Angeles, Arizona State University, Allen Institute for AI -
GQA: A New Dataset for Real-World Visual Reasoning and Compositional Question Answering [CVPR 2019] [Paper] [Code] [Data]
Stanford University -
MMMU: A Massive Multi-discipline Multimodal Understanding and Reasoning Benchmark for Expert AGI [CVPR 2024] [Paper] [Code] [Data]
IN.AI Research, University of Waterloo, The Ohio State University, Carnegie Mellon University, University of Victoria, Princeton University -
MathVista: Evaluating Mathematical Reasoning of Foundation Models in Visual Contexts [ICLR 2024] [Paper] [Code] [Data]
UCLA, University of Washington, Microsoft Research, Redmond -
PuzzleBench: A Fully Dynamic Evaluation Framework for Large Multimodal Models on Puzzle Solving [arXiv 2025] [Paper]
Shanghai Jiao Tong University -
MME-CoT: Benchmarking Chain-of-Thought in Large Multimodal Models for Reasoning Quality, Robustness, and Efficiency [arXiv 2025] [Paper] [Code] [Data] [Homepage]
The Chinese University of Hong Kong, ByteDance, Northeastern University -
MME-Reasoning: A Comprehensive Benchmark for Logical Reasoning in MLLMs [arXiv 2025] [Paper] [Code] [Data] [Homepage]
Fudan University, The Chinese University of Hong Kong, Shanghai AI Laboratory -
A Diagram Is Worth A Dozen Images [ECCV 2016] [Paper] [Code] [Data]
Allen Institute for Artificial Intelligence, University of Washington
Others: CLEVR, OlympiadBench, MathVision, MMMU-Pro, PuzzleVQA, GPQA
Domain Adaptation Benchmarks
-
DocVQA: A Dataset for VQA on Document Images [WACV 2021] [Paper] [Code] [Data]
CVIT, IIIT Hyderabad, India, Computer Vision Center, UAB, Spain -
ChartX & ChartVLM: A Versatile Benchmark and Foundation Model for Complicated Chart Reasoning [TIP 2025] [Paper] [Code] [Data]
Shanghai AI Laboratory, Shanghai Jiao Tong University -
OCRBench: On the Hidden Mystery of OCR in Large Multimodal Models [Science China Information Sciences 2024] [Paper] [Code] [Data]
Shanghai AI Laboratory -
SeeClick: Harnessing GUI Grounding for Advanced Visual GUI Agents [ACL 2024] [Paper] [Code] [Data]
The Chinese University of Hong Kong, Shanghai AI Laboratory -
Mind2Web: Towards a Generalist Agent for the Web [NeurIPS 2023] [Paper] [Code] [Data]
The Ohio State University -
A Dataset of Clinically Generated Visual Questions and Answers about Radiology Images [Scientific Data 2018] [Paper] [Code] [Data]
National Library of Medicine, National Institutes of Health -
PathVQA: 30000+ Questions for Medical Visual Question Answering [arXiv 2020] [Paper] [Code] [Data]
University of California San Diego, Carnegie Mellon University
Others: AndroidControl-Low, AndroidControl-High, GUI-Odyssey, ScreenSpot-Pro, GUI-Act-Web, OmniAct-Web, ChartQA, InfoVQA, TextVQA, ST-VQA
📌 Citation
If this repository or the associated survey is useful for your research, please consider citing the original survey paper and acknowledging this curated paper list.
@article{zhang2026survey,
  title={A Survey on Post-Training of Multimodal Large Language Models},
  author={Haonan Zhang and Pengpeng Zeng and Libin Cao and Wenrui Lai and
          Jinlong Li and Duo Peng and Yi Bin and Xuanhan Wang and Ji Zhang and
          Jingkuan Song and Nicu Sebe and Yuchuan Wu and Yongbin Li and
          Heng Tao Shen and Jieping Ye},
  year={2026},
  publisher={Preprints}
}