
README


Open-source / Comprehensive / Lightweight / Easy-to-use
OpenRLHF is a high-performance RLHF framework built on Ray, DeepSpeed and HF Transformers:
- Simple and easy to use: OpenRLHF is one of the simplest high-performance RLHF libraries currently available, and seamlessly compatible with Huggingface models and datasets.
- High performance: RLHF training spends 80% of the time on the sample generation stage. Thanks to the ability to use a large inference batch size with Ray and Packing Samples and vLLM generation acceleration, the performance of OpenRLHF 3~4x+ that of Optimized DeepSpeedChat with Hybrid Engine.
- Distributed RLHF: OpenRLHF distribute the Actor, Reward, Reference, and Critic models onto separate GPUs using Ray, while placing the Adam optimizer on the CPU. This enables full-scale fine-tuning of 70B+ models with multiple A100 80G GPUs and vLLM and 7B models across multiple 24GB RTX 4090 GPUs.
- Hybrid Engine: OpenRLHF also supports the hybrid engine, allowing all models and vLLM engines to share the GPUs to avoid GPU idling.
- PPO Implementation Optimization: We integrated the implementation tricks for PPO to improve the training stability, referencing Zhihu and Advanced Tricks for Training Large Language Models with Proximal Policy Optimization.
interactions-scaling
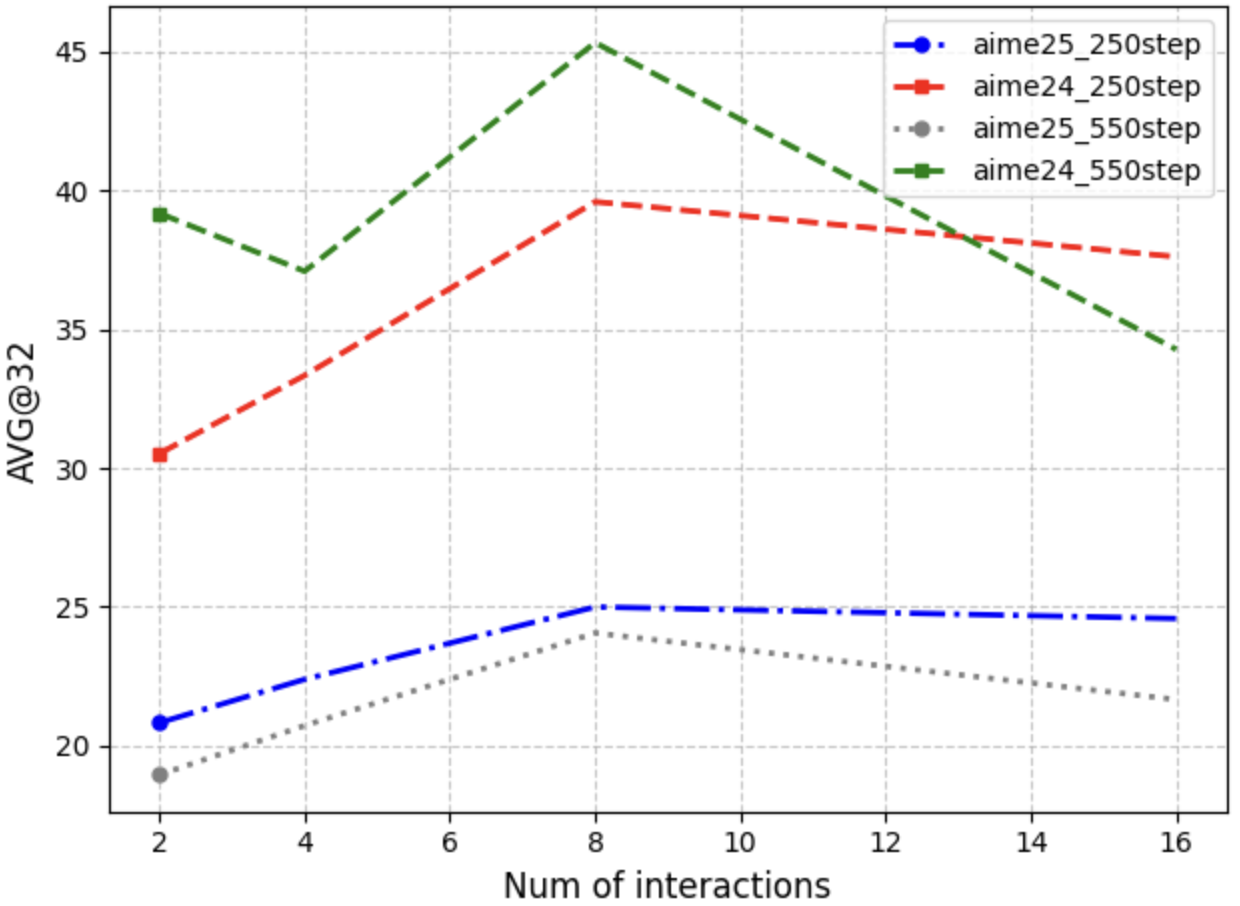 The model is released at huggingface.
The evaluation script is located at ./evaluation. You should be careful to set your openrlhf-path in ./evaluation/my_evaluation.py
Features
- ASYNC-PIPLINE PPO. We have test async-rollout with pipline to incentivize the reasoning ability on math-tasks with multiturn TIR(tool-intergated-reasoning). It has been tested on 7b/32b for reinforce++ and grpo with env-mask to exclude the loss calculation for env-feedback. Zhihu. It achieves better performance on AIME24/25 with fewer training-steps compared to zeor-rl-text-cot.
- DETAIL:
- Based on the OpenRLHF_v082 and add dynamic-batch-size feature from the latest version.
- The clear and simple async-rl pipline, you can check it on ./openrlhf/trainer/ppo_trainer_async.py
- Easy and simple task definition and intergation, you can check it on ./openrlhf/env/reward_config.py, ./openrlhf/env/filter_config.py and ./openrlhf/env/env_config.py
- The agentic-rl now only supports math-tir, you can check it on ./env/math/math_tir_process_single_request.py
- The agentic-rl needs more env and customized inference logic which is fully controlled by user without any magic-features or trivial implementations.
- For agentic-rl, token-in-and-token-out is important for performance and stopping-criteria.
- We add nginx-file-reading for env-interactions each turn and you can change the proxy without interrupting training.
- For agentic-rl, filtering bad-examples is important for stable and long-term training, the filtering-strategy is related to task, when you define a rollout strategy, you should define a reward and filtering python file.
- RUNNING SCRIPT
# apt-get update && \
#     apt-get install -y gosu && \
#     rm -rf /var/lib/apt/lists/*

# apt-get update && apt-get -y install sudo

# export NCCL_P2P_DISABLE=1
# export NCCL_IB_DISABLE=1
# export NCCL_SOCKET_IFNAME=eth0
# export NCCL_SHM_DISABLE=1
# export NCCL_DEBUG=INFO

cd your_openrlhf_path
pip3 install -e . -i  https://mirrors.cloud.aliyuncs.com/pypi/simple --trusted-host mirrors.cloud.aliyuncs.com

pip3 install deepspeed==0.17.0

pip3 install math-verify loguru fastapi uvicorn httpx python-multipart aiohttp aiolimiter pysbd jsonlines coloredlogs pebble aiolimiter -i  https://mirrors.cloud.aliyuncs.com/pypi/simple --trusted-host mirrors.cloud.aliyuncs.com
pip3 install func_timeout sentencex requests_futures timeout_decorator flashtext pygments -i  https://mirrors.cloud.aliyuncs.com/pypi/simple --trusted-host mirrors.cloud.aliyuncs.com

cd your_openrlhf_path
chmod -R 777 ./examples/scripts/

ln -s your_openrlhf_path /openrlhf
cd /openrlhf/examples/scripts
chmod -R 777 /openrlhf/examples/scripts

export VLLM_ENGINE_ITERATION_TIMEOUT_S=1000000000
export USE_MODEL_REWARD='yes'
export NCCL_TIMEOUT=36000000
export MAX_CONCURRENT=512
export TASK_MAX_CONCURRENT=32
export MAX_VLLM_BATCHSIZE=4
export ENV_ITER_NUM='2'
export WARMUP=0.0
export LR=1e-6
export KL=0.0
export OPENRLHF_PATH=your_openrlhf_path
export OPENRLHF_ASYNC_QUEUE_SIZE=1
export N_ROLLOUT=16
export MAX_COMPILE_RETRIES=2
export OPENRLHF_ASYNC_QUEUE_SIZE=1
# export QUALITY_REWARD=0.1
# export OVER_LONG_REWARD=0.1
export CODE_CONCURRENT=32
# export USE_SHORTCUT_REWARD=0.1
# export USE_FORMAT_REWARD='yes'
# export USE_TIR_FORMAT_LOOSE=0.1

mkdir /newcpfs/user/chenhao/outputs/

export SAVE_PATH=your_save_path
export expname=${SAVE_PATH}

export PRETRAIN=base_model_path
export REF_PRETRAIN=ref_model_path
export DATA_PATH=data_path

export TENSORBOARD=${SAVE_PATH}/tensorboard/
export NGINX_IP_FILE=nginx_ip_file_path
export COMPILE_SERVER_PORT='10003'
export MATH_VERIFY_SERVER_PORT='10008'
export XVERIFY_MATH_MODEL_SERVER_PORT='10005'
export REMOTE_RM_URL='http://127.0.0.0:8000'

mkdir ${SAVE_PATH}
mkdir ${TENSORBOARD}
mkdir ${expname}

export PATH=$HOME/.local/bin/:$PATH

set -x
if [ "$RANK" -eq 0 ]; then
    ray start --head --port=6379  --include-dashboard=true --dashboard-host=0.0.0.0 --dashboard-port=8265 --num-gpus 8
    ifconfig net0 | grep 'inet ' | awk '{print $2}' | cut -d/ -f1 > $expname/node_ip.txt
    export MASTER_NODE=$(cat $expname/node_ip.txt)
    sleep 2m
    set -x
    ray job submit --address="http://${MASTER_NODE}:8265/" \
        --runtime-env-json='{"working_dir": "/openrlhf"}' \
        -- python3 -m openrlhf.cli.train_ppo_ray \
        --ref_num_nodes 1 \
        --ref_num_gpus_per_node 8 \
        --actor_num_nodes 1 \
        --actor_num_gpus_per_node 8 \
        --vllm_num_engines 8 \
        --vllm_tensor_parallel_size 1 \
        --colocate_actor_ref \
        --vllm_gpu_memory_utilization 0.9 \
        --gamma 1.0 \
        --l2 0.01 \
        --async_train \
        --dynamic_filtering \
        --dynamic_filtering_reward_range 0.05 0.8 \
        --eps_clip_low_high 0.22 0.28 \
        --advantage_estimator reinforce_baseline \
        --pretrain ${PRETRAIN} \
        --ref_pretrain ${REF_PRETRAIN} \
        --agent_func_path /openrlhf/examples/python/agent_func.py \
        --save_path ${SAVE_PATH} \
        --ckpt_path ${SAVE_PATH} \
        --save_hf_ckpt \
        --micro_train_batch_size 4 \
        --train_batch_size 2048 \
        --micro_rollout_batch_size 4 \
        --rollout_batch_size 128 \
        --n_samples_per_prompt ${N_ROLLOUT} \
        --max_epochs 1 \
        --num_episodes 100000000 \
        --prompt_max_len 1024 \
        --max_samples 100000000 \
        --generate_max_len 8192 \
        --zero_stage 3 \
        --bf16 \
        --init_kl_coef ${KL} \
        --lr_warmup_ratio ${WARMUP} \
        --actor_learning_rate ${LR} \
        --critic_learning_rate 9e-6 \
        --prompt_data ${DATA_PATH} \
        --input_key query \
        --label_key label \
        --normalize_reward \
        --gradient_checkpointing \
        --use_global_token_level_loss \
        --use_dual_policy_loss \
        --use_filter_sample \
        --use_dynamic_batch \
        --use_loss_mask \
        --use_adv_mask_after \
        --grad_accum_dtype fp32 \
        --use_seq_balancing \
        --vllm_sync_backend nccl \
        --vllm_enable_sleep \
        --deepspeed_enable_sleep \
        --adam_offload \
        --flash_attn \
        --normalize_reward \
        --gradient_checkpointing \
        --packing_samples \
        --enforce_eager \
        --load_checkpoint \
        --save_steps 50 \
        --use_tensorboard ${TENSORBOARD} \
        --remote_rm_url ${REMOTE_RM_URL}
else
    sleep 1m
    export MASTER_NODE=$(cat $expname/node_ip.txt)
    ray start --address="${MASTER_NODE}:6379"
fi

sleep 365d
ENV-INTERGERATION
DATA-EXAMPLE:
data = {
    "prompt": xxx,
    "query": xxx,
    "label": json.dumps({
        'uuid': uuid_string,
        'env_func': your_env_key registered in openrlhf/env/env_config.py,
        other_info for your usage
    }),
    "task": your_task_name registered in openrlhf/env/reward_config.py and openrlhf/env/filter_config.py
}
To use your own-env:
- mdkdir in env/your_task
- you should write a reward/filter .py file just like env/synlogic/synlogic_reward.py and env/synlogic/filter_fn_utils.py .
- register your reward and filter in openrlhf/env/reward_config.py and openrlhf/env/filter_config.py with your_task_name defined in your dataset.
REWARD_CONFIG = {
    'math': math_score,
    'math_tir': math_score_tir,
    'kk': kk_score,
    'zebralogic': zebralogic_score,
    'synlogic': synlogic_score,
    your_task_name: your_task_reward
}
FILTER_FN_CONFIG = {
    'math_sample_filter_fn': math_sample_filter_fn,
    'math_exp_filter_fn': math_exp_filter_fn,
    'math_reward_fail_fn': math_reward_fail_fn,
    'math_tir_sample_filter_fn': math_tir_sample_filter_fn,
    'math_tir_exp_filter_fn': math_tir_exp_filter_fn,
    'math_tir_reward_fail_fn': math_tir_reward_fail_fn,
    'synlogic_sample_filter_fn': synlogic_sample_filter_fn,
    'synlogic_exp_filter_fn': synlogic_exp_filter_fn,
    'synlogic_reward_fail_fn': synlogic_reward_fail_fn,
    f"{your_task_name}_sample_filter_fn": xxx_sample_filter_fn,
    f"{your_task_name}_exp_filter_fn": xxx_exp_filter_fn,
    f"{your_task_name}_reward_fail_fn": xxx_reward_fail_fn
}
- If you need multiturn/multitool, you should also write your own generation logic in env/your_task like env/math/math_tir_process_single_request.py
- Then you should register your rollout function in openrlhf/env/env_config.py with your env_func in your data.
ENV_GENERATE_CONFIG = {
    'math_tir_generate': math_tir_generate,
    'math_tir_async': math_tir_generate_async,
    your_env_func: xxx, # the key from the data['label']['env_func']
}
Companies and Organizations using OpenRLHF
- ByteDance
- Tencent
- Alibaba
- Baidu
- China Telecom
- Vivo
- Allen AI
- NexusFlow
- Jülich Supercomputing Centre (JSC)
- Berkeley Starling Team
- M-A-P
- ...
Join Us
How to Join?
- Email us at janhu9527@gmail.com or join GitHub Organization. Please include the following details:
- Your name
- Your GitHub username
- Your areas of interest
- Your skills and experience related to NLP and/or AI
- You can also join us through the official GitHub OpenRLHF ↗ project page. Just create an issue about your interest to contribute and we will get back to you.
What can you do?
- Join the team and participate in the development of the OpenRLHF project.
- Contribute to the project by submitting pull requests.
- Help improve documentation, fix bugs, or create new features.
- Share the project and help us grow the community.
Sponsor Us
Your sponsorship can help us maintain and improve OpenRLHF. If you find this project useful, please consider sponsoring us. You can sponsor us on Open Collective ↗.
Starchart
Contributors
A big thank you to all our contributors! If you want to contribute, feel free to make a pull request or create an issue.
References & Acknowledgements
We would like to express our gratitude to the following projects and organizations for their contributions to the field of AI and NLP:
Our project would also like to thank ColossalChat and DeepSpeedChat. In the early stages of the project, we referred to their code design. Our project would like to thank Netmind.AI for the GPU support of developing ring attention.
(2024/7) Our GitHub organization has changed from OpenLLMAI to OpenRLHF.
Citation
@article{hu2024openrlhf,
  title={OpenRLHF: An Easy-to-use, Scalable and High-performance RLHF Framework},
  author={Jian Hu and Xibin Wu and Zilin Zhu and Xianyu and Weixun Wang and Dehao Zhang and Yu Cao},
  journal={arXiv preprint arXiv:2405.11143},
  year={2024}
}
OpenRLHF © 2025 OpenRLHF. All Rights Reserved.
Contributors

21 commits
Similar repos


Languages
Python
96.8%
Shell
3.2%
README
Open-source / Comprehensive / Lightweight / Easy-to-use
OpenRLHF is a high-performance RLHF framework built on Ray, DeepSpeed and HF Transformers:
- Simple and easy to use: OpenRLHF is one of the simplest high-performance RLHF libraries currently available, and seamlessly compatible with Huggingface models and datasets.
- High performance: RLHF training spends 80% of the time on the sample generation stage. Thanks to the ability to use a large inference batch size with Ray and Packing Samples and vLLM generation acceleration, the performance of OpenRLHF 3~4x+ that of Optimized DeepSpeedChat with Hybrid Engine.
- Distributed RLHF: OpenRLHF distribute the Actor, Reward, Reference, and Critic models onto separate GPUs using Ray, while placing the Adam optimizer on the CPU. This enables full-scale fine-tuning of 70B+ models with multiple A100 80G GPUs and vLLM and 7B models across multiple 24GB RTX 4090 GPUs.
- Hybrid Engine: OpenRLHF also supports the hybrid engine, allowing all models and vLLM engines to share the GPUs to avoid GPU idling.
- PPO Implementation Optimization: We integrated the implementation tricks for PPO to improve the training stability, referencing Zhihu and Advanced Tricks for Training Large Language Models with Proximal Policy Optimization.
interactions-scaling
The model is released at huggingface.
The evaluation script is located at ./evaluation. You should be careful to set your openrlhf-path in ./evaluation/my_evaluation.py
Features
- ASYNC-PIPLINE PPO. We have test async-rollout with pipline to incentivize the reasoning ability on math-tasks with multiturn TIR(tool-intergated-reasoning). It has been tested on 7b/32b for reinforce++ and grpo with env-mask to exclude the loss calculation for env-feedback. Zhihu. It achieves better performance on AIME24/25 with fewer training-steps compared to zeor-rl-text-cot.
- DETAIL:
- Based on the OpenRLHF_v082 and add dynamic-batch-size feature from the latest version.
- The clear and simple async-rl pipline, you can check it on ./openrlhf/trainer/ppo_trainer_async.py
- Easy and simple task definition and intergation, you can check it on ./openrlhf/env/reward_config.py, ./openrlhf/env/filter_config.py and ./openrlhf/env/env_config.py
- The agentic-rl now only supports math-tir, you can check it on ./env/math/math_tir_process_single_request.py
- The agentic-rl needs more env and customized inference logic which is fully controlled by user without any magic-features or trivial implementations.
- For agentic-rl, token-in-and-token-out is important for performance and stopping-criteria.
- We add nginx-file-reading for env-interactions each turn and you can change the proxy without interrupting training.
- For agentic-rl, filtering bad-examples is important for stable and long-term training, the filtering-strategy is related to task, when you define a rollout strategy, you should define a reward and filtering python file.
- RUNNING SCRIPT
# apt-get update && \
#     apt-get install -y gosu && \
#     rm -rf /var/lib/apt/lists/*

# apt-get update && apt-get -y install sudo

# export NCCL_P2P_DISABLE=1
# export NCCL_IB_DISABLE=1
# export NCCL_SOCKET_IFNAME=eth0
# export NCCL_SHM_DISABLE=1
# export NCCL_DEBUG=INFO

cd your_openrlhf_path
pip3 install -e . -i  https://mirrors.cloud.aliyuncs.com/pypi/simple --trusted-host mirrors.cloud.aliyuncs.com

pip3 install deepspeed==0.17.0

pip3 install math-verify loguru fastapi uvicorn httpx python-multipart aiohttp aiolimiter pysbd jsonlines coloredlogs pebble aiolimiter -i  https://mirrors.cloud.aliyuncs.com/pypi/simple --trusted-host mirrors.cloud.aliyuncs.com
pip3 install func_timeout sentencex requests_futures timeout_decorator flashtext pygments -i  https://mirrors.cloud.aliyuncs.com/pypi/simple --trusted-host mirrors.cloud.aliyuncs.com

cd your_openrlhf_path
chmod -R 777 ./examples/scripts/

ln -s your_openrlhf_path /openrlhf
cd /openrlhf/examples/scripts
chmod -R 777 /openrlhf/examples/scripts

export VLLM_ENGINE_ITERATION_TIMEOUT_S=1000000000
export USE_MODEL_REWARD='yes'
export NCCL_TIMEOUT=36000000
export MAX_CONCURRENT=512
export TASK_MAX_CONCURRENT=32
export MAX_VLLM_BATCHSIZE=4
export ENV_ITER_NUM='2'
export WARMUP=0.0
export LR=1e-6
export KL=0.0
export OPENRLHF_PATH=your_openrlhf_path
export OPENRLHF_ASYNC_QUEUE_SIZE=1
export N_ROLLOUT=16
export MAX_COMPILE_RETRIES=2
export OPENRLHF_ASYNC_QUEUE_SIZE=1
# export QUALITY_REWARD=0.1
# export OVER_LONG_REWARD=0.1
export CODE_CONCURRENT=32
# export USE_SHORTCUT_REWARD=0.1
# export USE_FORMAT_REWARD='yes'
# export USE_TIR_FORMAT_LOOSE=0.1

mkdir /newcpfs/user/chenhao/outputs/

export SAVE_PATH=your_save_path
export expname=${SAVE_PATH}

export PRETRAIN=base_model_path
export REF_PRETRAIN=ref_model_path
export DATA_PATH=data_path

export TENSORBOARD=${SAVE_PATH}/tensorboard/
export NGINX_IP_FILE=nginx_ip_file_path
export COMPILE_SERVER_PORT='10003'
export MATH_VERIFY_SERVER_PORT='10008'
export XVERIFY_MATH_MODEL_SERVER_PORT='10005'
export REMOTE_RM_URL='http://127.0.0.0:8000'

mkdir ${SAVE_PATH}
mkdir ${TENSORBOARD}
mkdir ${expname}

export PATH=$HOME/.local/bin/:$PATH

set -x
if [ "$RANK" -eq 0 ]; then
    ray start --head --port=6379  --include-dashboard=true --dashboard-host=0.0.0.0 --dashboard-port=8265 --num-gpus 8
    ifconfig net0 | grep 'inet ' | awk '{print $2}' | cut -d/ -f1 > $expname/node_ip.txt
    export MASTER_NODE=$(cat $expname/node_ip.txt)
    sleep 2m
    set -x
    ray job submit --address="http://${MASTER_NODE}:8265/" \
        --runtime-env-json='{"working_dir": "/openrlhf"}' \
        -- python3 -m openrlhf.cli.train_ppo_ray \
        --ref_num_nodes 1 \
        --ref_num_gpus_per_node 8 \
        --actor_num_nodes 1 \
        --actor_num_gpus_per_node 8 \
        --vllm_num_engines 8 \
        --vllm_tensor_parallel_size 1 \
        --colocate_actor_ref \
        --vllm_gpu_memory_utilization 0.9 \
        --gamma 1.0 \
        --l2 0.01 \
        --async_train \
        --dynamic_filtering \
        --dynamic_filtering_reward_range 0.05 0.8 \
        --eps_clip_low_high 0.22 0.28 \
        --advantage_estimator reinforce_baseline \
        --pretrain ${PRETRAIN} \
        --ref_pretrain ${REF_PRETRAIN} \
        --agent_func_path /openrlhf/examples/python/agent_func.py \
        --save_path ${SAVE_PATH} \
        --ckpt_path ${SAVE_PATH} \
        --save_hf_ckpt \
        --micro_train_batch_size 4 \
        --train_batch_size 2048 \
        --micro_rollout_batch_size 4 \
        --rollout_batch_size 128 \
        --n_samples_per_prompt ${N_ROLLOUT} \
        --max_epochs 1 \
        --num_episodes 100000000 \
        --prompt_max_len 1024 \
        --max_samples 100000000 \
        --generate_max_len 8192 \
        --zero_stage 3 \
        --bf16 \
        --init_kl_coef ${KL} \
        --lr_warmup_ratio ${WARMUP} \
        --actor_learning_rate ${LR} \
        --critic_learning_rate 9e-6 \
        --prompt_data ${DATA_PATH} \
        --input_key query \
        --label_key label \
        --normalize_reward \
        --gradient_checkpointing \
        --use_global_token_level_loss \
        --use_dual_policy_loss \
        --use_filter_sample \
        --use_dynamic_batch \
        --use_loss_mask \
        --use_adv_mask_after \
        --grad_accum_dtype fp32 \
        --use_seq_balancing \
        --vllm_sync_backend nccl \
        --vllm_enable_sleep \
        --deepspeed_enable_sleep \
        --adam_offload \
        --flash_attn \
        --normalize_reward \
        --gradient_checkpointing \
        --packing_samples \
        --enforce_eager \
        --load_checkpoint \
        --save_steps 50 \
        --use_tensorboard ${TENSORBOARD} \
        --remote_rm_url ${REMOTE_RM_URL}
else
    sleep 1m
    export MASTER_NODE=$(cat $expname/node_ip.txt)
    ray start --address="${MASTER_NODE}:6379"
fi

sleep 365d
ENV-INTERGERATION
DATA-EXAMPLE:
data = {
    "prompt": xxx,
    "query": xxx,
    "label": json.dumps({
        'uuid': uuid_string,
        'env_func': your_env_key registered in openrlhf/env/env_config.py,
        other_info for your usage
    }),
    "task": your_task_name registered in openrlhf/env/reward_config.py and openrlhf/env/filter_config.py
}
To use your own-env:
- mdkdir in env/your_task
- you should write a reward/filter .py file just like env/synlogic/synlogic_reward.py and env/synlogic/filter_fn_utils.py .
- register your reward and filter in openrlhf/env/reward_config.py and openrlhf/env/filter_config.py with your_task_name defined in your dataset.
REWARD_CONFIG = {
    'math': math_score,
    'math_tir': math_score_tir,
    'kk': kk_score,
    'zebralogic': zebralogic_score,
    'synlogic': synlogic_score,
    your_task_name: your_task_reward
}
FILTER_FN_CONFIG = {
    'math_sample_filter_fn': math_sample_filter_fn,
    'math_exp_filter_fn': math_exp_filter_fn,
    'math_reward_fail_fn': math_reward_fail_fn,
    'math_tir_sample_filter_fn': math_tir_sample_filter_fn,
    'math_tir_exp_filter_fn': math_tir_exp_filter_fn,
    'math_tir_reward_fail_fn': math_tir_reward_fail_fn,
    'synlogic_sample_filter_fn': synlogic_sample_filter_fn,
    'synlogic_exp_filter_fn': synlogic_exp_filter_fn,
    'synlogic_reward_fail_fn': synlogic_reward_fail_fn,
    f"{your_task_name}_sample_filter_fn": xxx_sample_filter_fn,
    f"{your_task_name}_exp_filter_fn": xxx_exp_filter_fn,
    f"{your_task_name}_reward_fail_fn": xxx_reward_fail_fn
}
- If you need multiturn/multitool, you should also write your own generation logic in env/your_task like env/math/math_tir_process_single_request.py
- Then you should register your rollout function in openrlhf/env/env_config.py with your env_func in your data.
ENV_GENERATE_CONFIG = {
    'math_tir_generate': math_tir_generate,
    'math_tir_async': math_tir_generate_async,
    your_env_func: xxx, # the key from the data['label']['env_func']
}
Companies and Organizations using OpenRLHF
- ByteDance
- Tencent
- Alibaba
- Baidu
- China Telecom
- Vivo
- Allen AI
- NexusFlow
- Jülich Supercomputing Centre (JSC)
- Berkeley Starling Team
- M-A-P
- ...
Join Us
How to Join?
- Email us at janhu9527@gmail.com or join GitHub Organization. Please include the following details:
- Your name
- Your GitHub username
- Your areas of interest
- Your skills and experience related to NLP and/or AI
- You can also join us through the official GitHub OpenRLHF ↗ project page. Just create an issue about your interest to contribute and we will get back to you.
What can you do?
- Join the team and participate in the development of the OpenRLHF project.
- Contribute to the project by submitting pull requests.
- Help improve documentation, fix bugs, or create new features.
- Share the project and help us grow the community.
Sponsor Us
Your sponsorship can help us maintain and improve OpenRLHF. If you find this project useful, please consider sponsoring us. You can sponsor us on Open Collective ↗.
Starchart
Contributors
A big thank you to all our contributors! If you want to contribute, feel free to make a pull request or create an issue.
References & Acknowledgements
We would like to express our gratitude to the following projects and organizations for their contributions to the field of AI and NLP:
Our project would also like to thank ColossalChat and DeepSpeedChat. In the early stages of the project, we referred to their code design. Our project would like to thank Netmind.AI for the GPU support of developing ring attention.
(2024/7) Our GitHub organization has changed from OpenLLMAI to OpenRLHF.
Citation
@article{hu2024openrlhf,
  title={OpenRLHF: An Easy-to-use, Scalable and High-performance RLHF Framework},
  author={Jian Hu and Xibin Wu and Zilin Zhu and Xianyu and Weixun Wang and Dehao Zhang and Yu Cao},
  journal={arXiv preprint arXiv:2405.11143},
  year={2024}
}
OpenRLHF © 2025 OpenRLHF. All Rights Reserved.
Similar repos
Contributors
21 commits
Languages
Python
96.8%
Shell
3.2%