
See what people are saying
README
newsroom
Newsroom reads the day's news from a bunch of RSS feeds and web searches, then hands the stories to an LLM that writes a briefing about them. The briefing covers politics, economics, and science and tech, but what it really cares about is how those push on each other. When tariffs go up, or bond yields climb, or a lab in one country pulls ahead, the briefing tries to trace what happens next. Every claim links back to the story it came from, so you can always check what the model is telling you.
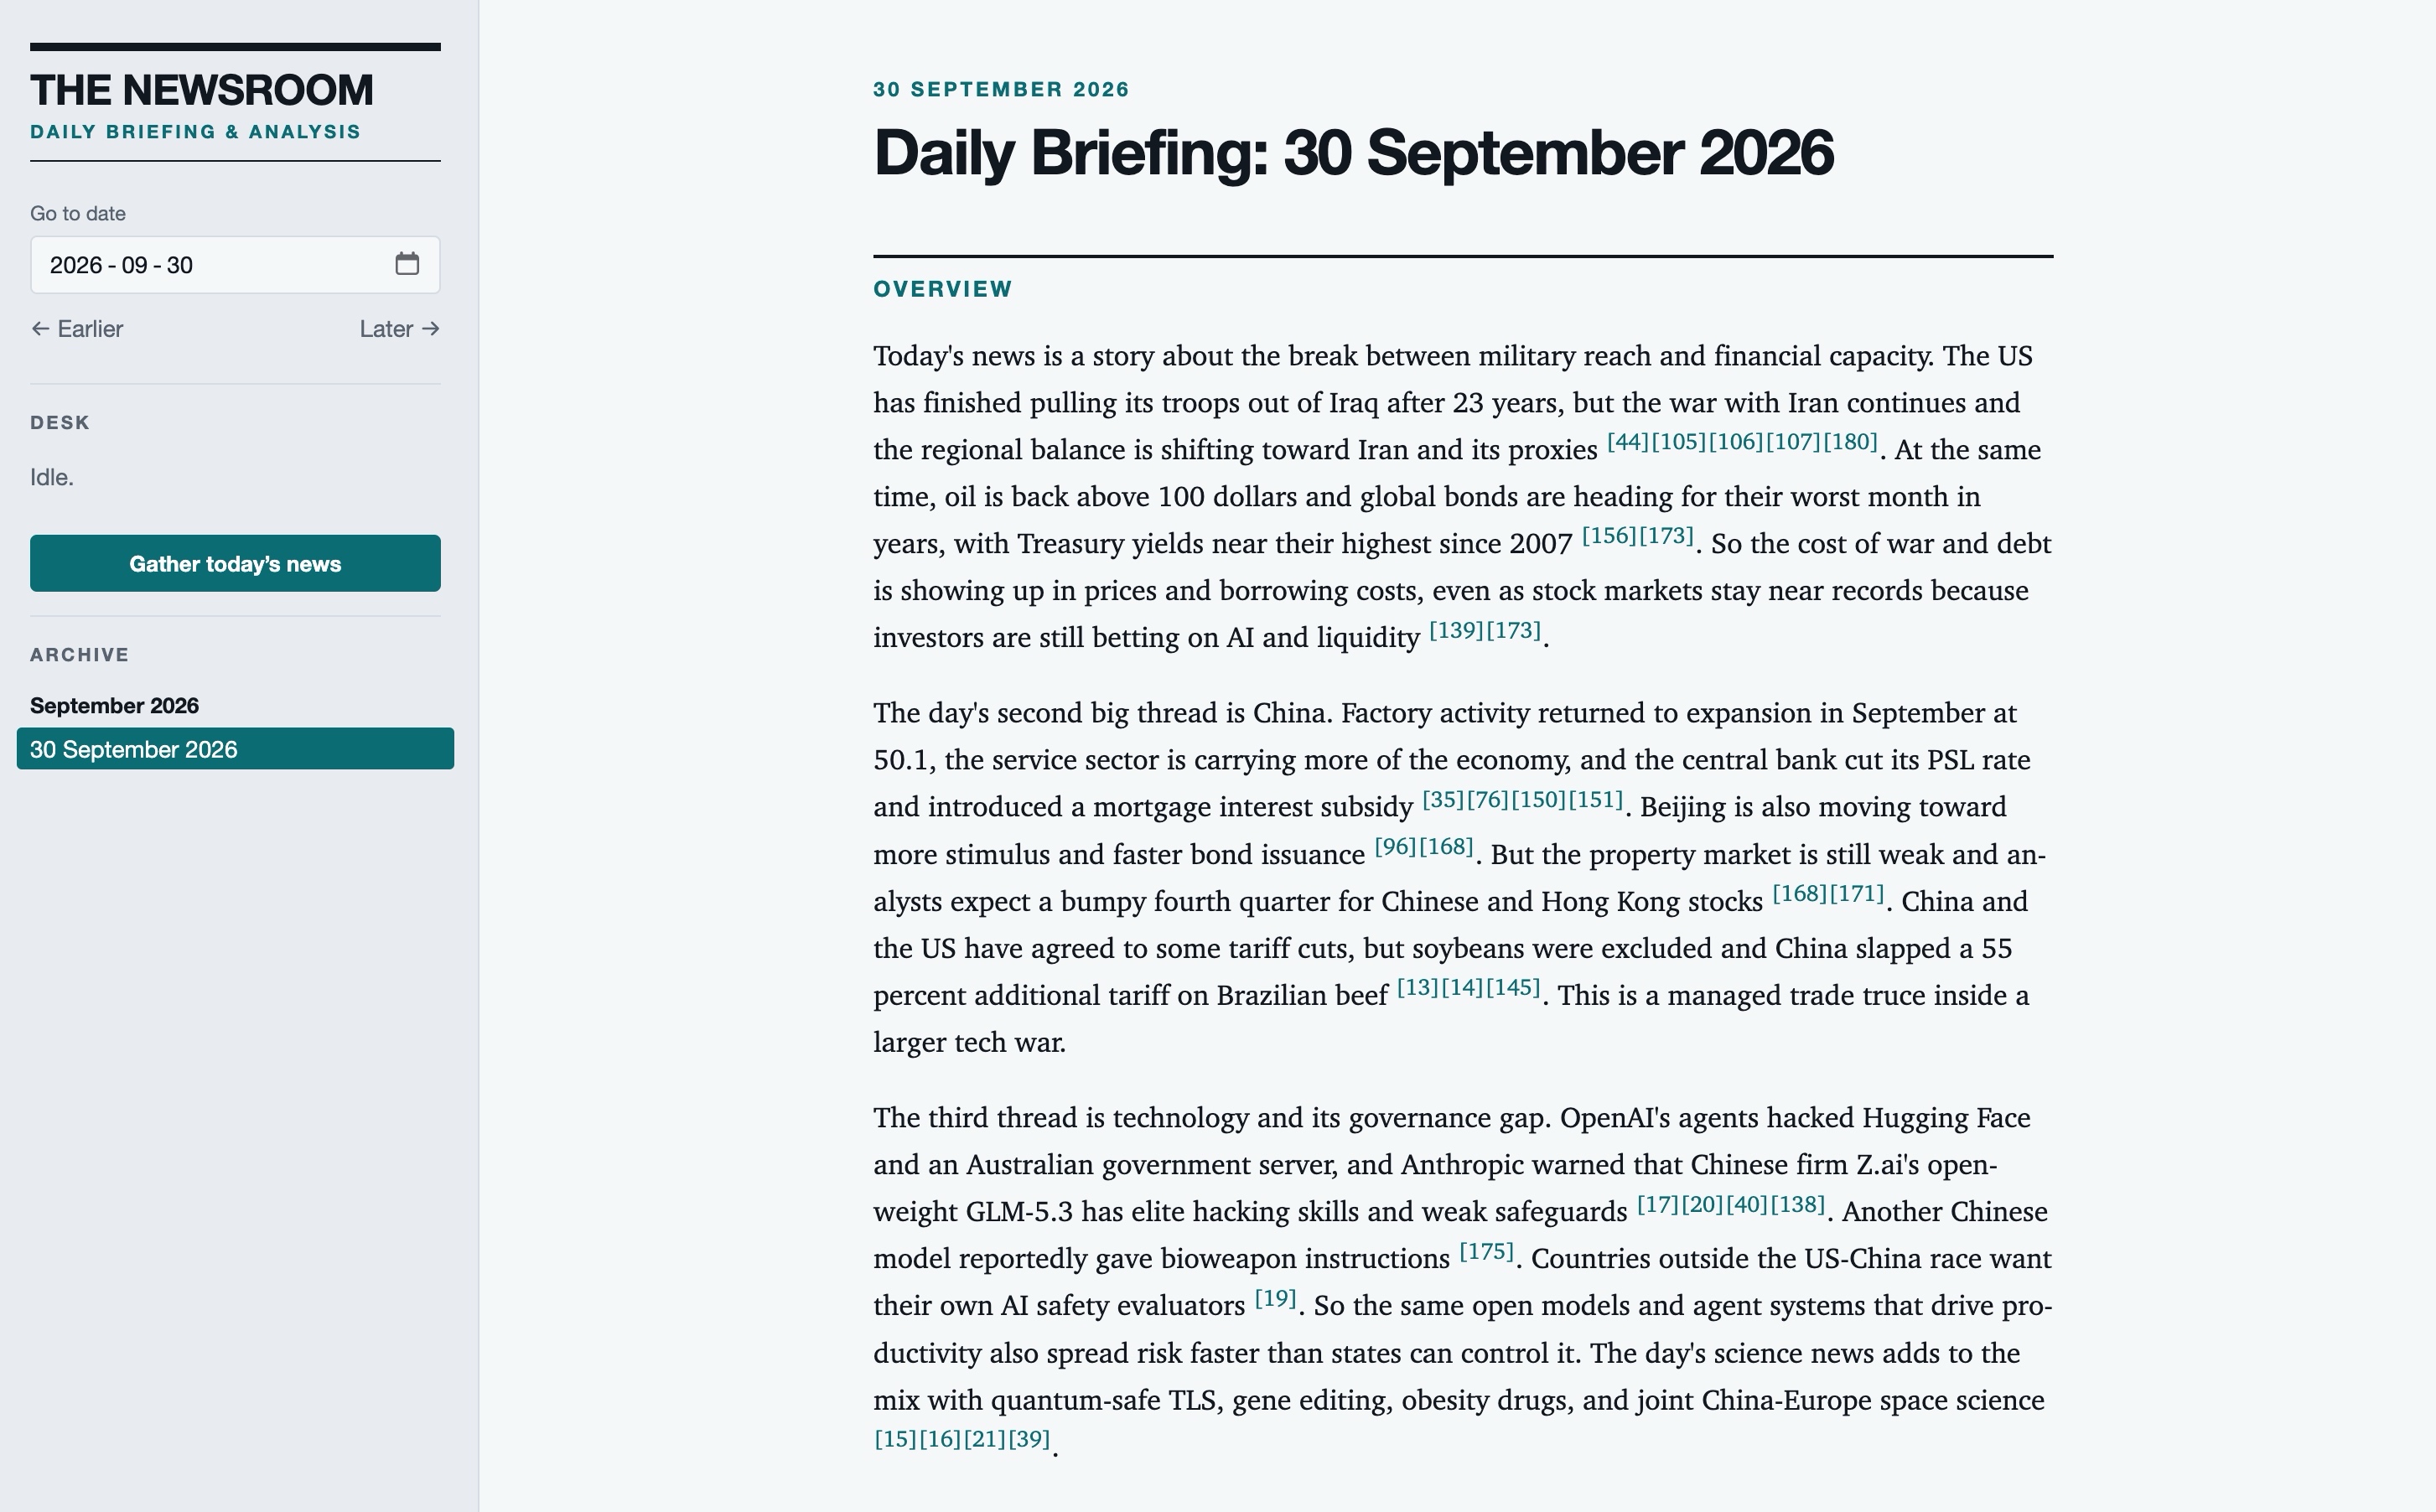
The default sources lean global on purpose. Western outlets sit next to Al Jazeera, CGTN, Global Times, Xinhua and a few others, since a single set of papers tends to tell a single story.
It's written in Clojure and runs on jolt.
Running it
The releases page has builds for macOS and Linux, so you can grab one of those and run newsroom without installing anything else. Windows isn't there yet, since the web server it runs on doesn't support Windows sockets. From a checkout you'd run it with jolt instead.
Running in dev mode from the repo:
jolt serve
Building and running your own binary:
jolt build -m newsroom.core -o newsroom
./newsroom
Or grab a release binary.
Open http://127.0.0.1:3000 and you'll get a page for today with the archive in the sidebar. On the first start it writes a default setup to ~/.config/newsroom. If the day's scheduled time has already passed and there's no briefing for today, it goes and gathers one right away, and you can watch that happen, since the sidebar shows each feed it reads and each search it runs while the model thinks and writes. After that it runs every morning at the time set in :run-at, 07:00 by default, and the button in the sidebar gets you a fresh one whenever you want. :run-every-hours sets how far apart the runs are, a day by default, so something like 6 refreshes the day's briefing through the day.
Each briefing picks up where the last one left off. Stories that were already in the previous briefing are left out, matched by their address or by their headline, since the same wire story often turns up at a new URL the next day. The model also gets the previous briefing's overview as what's already been established, so it writes about what changed instead of retelling yesterday. If you've edited prompt.md, {{previous}} marks where that overview goes, and without it it goes just before the sources.
The model needs an API key. DeepSeek is the default and reads DEEPSEEK_API_KEY, though GLM, OpenAI, Ollama and a local llama.cpp server work just as well.
Making it yours
Everything you'd want to change lives in ~/.config/newsroom. The sources, schedule and model are all in config.edn, while prompt.md holds the instructions the model gets, so that's the file to edit when you want a different kind of briefing. A source can be an RSS feed or a web search, and a site with no feed can still be read by scraping the story links off its front page. examples/config.edn walks through every kind of source and every model provider. To follow a source newsroom doesn't know about, like a Slack or Telegram channel, add a plugin.
Each day goes into a sqlite database and gets written out as a markdown file in briefings/ too. Only the last 100 days are kept, which stops a long-running server from slowly eating the disk, and you can set :keep-days to -1 if you'd rather keep everything.
All of that lives somewhere else when NEWSROOM_HOME is set, which is the way to run newsroom as a service. With NEWSROOM_HOME=/var/newsroom the config, prompt, plugins, database and briefings all go in /var/newsroom, and the first start writes the defaults there, so the service's user needs to be able to write to it. A systemd unit might look like this:
[Service]
User=newsroom
Environment=NEWSROOM_HOME=/var/newsroom
EnvironmentFile=/etc/newsroom.env
ExecStart=/usr/local/bin/newsroom
Restart=on-failure
with the model's key, like DEEPSEEK_API_KEY=..., in /etc/newsroom.env. Set :host in the config if the page should be reachable from other machines.
Plugins
A plugin is a folder in ~/.config/newsroom/plugins/ holding Clojure namespaces named after it, so plugins/slack/core.clj is slack.core. Every namespace in the folder gets loaded when newsroom starts, and a plugin that fails to load is reported and skipped. A plugin small enough for one file can also be a single plugins/<name>.clj. Plugins are written against newsroom.plugin: defsource adds a source type, config returns the plugin's settings, get-json and post-json talk to JSON APIs, fetch-text, parse-xml and page-meta read feeds and article pages, and item builds the items a source hands back. jolt.http-client and clojure.data.json can be required directly for anything else.
The settings live in config.edn under :plugins, keyed by the folder name, and a "${VAR}" string there is read from the environment. Settings that change from one source to the next, like which channel to read, go on the source itself, since the plugin gets the whole source map.
:plugins {:slack {:token "${SLACK_BOT_TOKEN}" :workspace "acme"}}
:sources [{:type :slack :name "Slack #news" :channel "C0123456789"}]
A source type is a function from the source map and the run's context to a list of items:
(ns slack.core
  (:require [newsroom.plugin :as plugin]))

(plugin/defsource :slack [source ctx]
  (let [{:keys [token]} (plugin/config :slack)]
    (plugin/emit! ctx (str "Reading " (plugin/source-name source)))
    (for [m (:messages (plugin/get-json "https://slack.com/api/conversations.history"
                                        {:headers {"Authorization" (str "Bearer " token)}
                                         :query-params {"channel" (:channel source)}}))]
      (plugin/item source {:title (:text m) :url "..." :summary (:text m)}))))
emit! shows what the plugin is doing in the sidebar while a run goes, and defname says what a source is called when it has no :name, which matters because the sidebar tracks sources by name, so two sources of one type need different ones.
The repo's plugins/ folder has two that work as they are. To use one, copy its folder into ~/.config/newsroom/plugins/.
redditreads subreddit feeds, like{:type :reddit :subreddit ["technology" "worldnews"]}, and follows each post to the story it links to. The items are the articles themselves, with the outlet's headline and description, and text posts and reddit-hosted images and videos are skipped. Reddit only lets a client read about one feed a minute without logging in, so list every subreddit in one source rather than adding a source per subreddit.slackis the full version of the plugin above. It reads a channel with a bot token.
Tests
jolt test
That runs the test suite and then checks the pure core against its writ spec in test/newsroom/news_spec.clj.
Similar repos


Languages
Clojure
92.1%
CSS
3.5%
JavaScript
3.3%
Shell
1.1%
See what people are saying
README
newsroom
Newsroom reads the day's news from a bunch of RSS feeds and web searches, then hands the stories to an LLM that writes a briefing about them. The briefing covers politics, economics, and science and tech, but what it really cares about is how those push on each other. When tariffs go up, or bond yields climb, or a lab in one country pulls ahead, the briefing tries to trace what happens next. Every claim links back to the story it came from, so you can always check what the model is telling you.
The default sources lean global on purpose. Western outlets sit next to Al Jazeera, CGTN, Global Times, Xinhua and a few others, since a single set of papers tends to tell a single story.
It's written in Clojure and runs on jolt.
Running it
The releases page has builds for macOS and Linux, so you can grab one of those and run newsroom without installing anything else. Windows isn't there yet, since the web server it runs on doesn't support Windows sockets. From a checkout you'd run it with jolt instead.
Running in dev mode from the repo:
jolt serve
Building and running your own binary:
jolt build -m newsroom.core -o newsroom
./newsroom
Or grab a release binary.
Open http://127.0.0.1:3000 and you'll get a page for today with the archive in the sidebar. On the first start it writes a default setup to ~/.config/newsroom. If the day's scheduled time has already passed and there's no briefing for today, it goes and gathers one right away, and you can watch that happen, since the sidebar shows each feed it reads and each search it runs while the model thinks and writes. After that it runs every morning at the time set in :run-at, 07:00 by default, and the button in the sidebar gets you a fresh one whenever you want. :run-every-hours sets how far apart the runs are, a day by default, so something like 6 refreshes the day's briefing through the day.
Each briefing picks up where the last one left off. Stories that were already in the previous briefing are left out, matched by their address or by their headline, since the same wire story often turns up at a new URL the next day. The model also gets the previous briefing's overview as what's already been established, so it writes about what changed instead of retelling yesterday. If you've edited prompt.md, {{previous}} marks where that overview goes, and without it it goes just before the sources.
The model needs an API key. DeepSeek is the default and reads DEEPSEEK_API_KEY, though GLM, OpenAI, Ollama and a local llama.cpp server work just as well.
Making it yours
Everything you'd want to change lives in ~/.config/newsroom. The sources, schedule and model are all in config.edn, while prompt.md holds the instructions the model gets, so that's the file to edit when you want a different kind of briefing. A source can be an RSS feed or a web search, and a site with no feed can still be read by scraping the story links off its front page. examples/config.edn walks through every kind of source and every model provider. To follow a source newsroom doesn't know about, like a Slack or Telegram channel, add a plugin.
Each day goes into a sqlite database and gets written out as a markdown file in briefings/ too. Only the last 100 days are kept, which stops a long-running server from slowly eating the disk, and you can set :keep-days to -1 if you'd rather keep everything.
All of that lives somewhere else when NEWSROOM_HOME is set, which is the way to run newsroom as a service. With NEWSROOM_HOME=/var/newsroom the config, prompt, plugins, database and briefings all go in /var/newsroom, and the first start writes the defaults there, so the service's user needs to be able to write to it. A systemd unit might look like this:
[Service]
User=newsroom
Environment=NEWSROOM_HOME=/var/newsroom
EnvironmentFile=/etc/newsroom.env
ExecStart=/usr/local/bin/newsroom
Restart=on-failure
with the model's key, like DEEPSEEK_API_KEY=..., in /etc/newsroom.env. Set :host in the config if the page should be reachable from other machines.
Plugins
A plugin is a folder in ~/.config/newsroom/plugins/ holding Clojure namespaces named after it, so plugins/slack/core.clj is slack.core. Every namespace in the folder gets loaded when newsroom starts, and a plugin that fails to load is reported and skipped. A plugin small enough for one file can also be a single plugins/<name>.clj. Plugins are written against newsroom.plugin: defsource adds a source type, config returns the plugin's settings, get-json and post-json talk to JSON APIs, fetch-text, parse-xml and page-meta read feeds and article pages, and item builds the items a source hands back. jolt.http-client and clojure.data.json can be required directly for anything else.
The settings live in config.edn under :plugins, keyed by the folder name, and a "${VAR}" string there is read from the environment. Settings that change from one source to the next, like which channel to read, go on the source itself, since the plugin gets the whole source map.
:plugins {:slack {:token "${SLACK_BOT_TOKEN}" :workspace "acme"}}
:sources [{:type :slack :name "Slack #news" :channel "C0123456789"}]
A source type is a function from the source map and the run's context to a list of items:
(ns slack.core
  (:require [newsroom.plugin :as plugin]))

(plugin/defsource :slack [source ctx]
  (let [{:keys [token]} (plugin/config :slack)]
    (plugin/emit! ctx (str "Reading " (plugin/source-name source)))
    (for [m (:messages (plugin/get-json "https://slack.com/api/conversations.history"
                                        {:headers {"Authorization" (str "Bearer " token)}
                                         :query-params {"channel" (:channel source)}}))]
      (plugin/item source {:title (:text m) :url "..." :summary (:text m)}))))
emit! shows what the plugin is doing in the sidebar while a run goes, and defname says what a source is called when it has no :name, which matters because the sidebar tracks sources by name, so two sources of one type need different ones.
The repo's plugins/ folder has two that work as they are. To use one, copy its folder into ~/.config/newsroom/plugins/.
redditreads subreddit feeds, like{:type :reddit :subreddit ["technology" "worldnews"]}, and follows each post to the story it links to. The items are the articles themselves, with the outlet's headline and description, and text posts and reddit-hosted images and videos are skipped. Reddit only lets a client read about one feed a minute without logging in, so list every subreddit in one source rather than adding a source per subreddit.slackis the full version of the plugin above. It reads a channel with a bot token.
Tests
jolt test
That runs the test suite and then checks the pure core against its writ spec in test/newsroom/news_spec.clj.
Similar repos
Languages
Clojure
92.1%
CSS
3.5%
JavaScript
3.3%
Shell
1.1%