
[ICLR 2026 Oral] Visual Planning: Let's Think Only with Images
Python
377
41 commits
updated Apr 24, 2026
README
Visual Planning: Let's Think Only with Images
If you find this project interesting, please give us a star ⭐ on GitHub to support us. 🙏🙏


📰 News
- [2026.04] We release the training datasets and training scripts for Visual Planning.
- [2026.02] Our paper Visual Planning: Let's Think Only with Images was accepted as an ICLR Oral.
💡 Overview
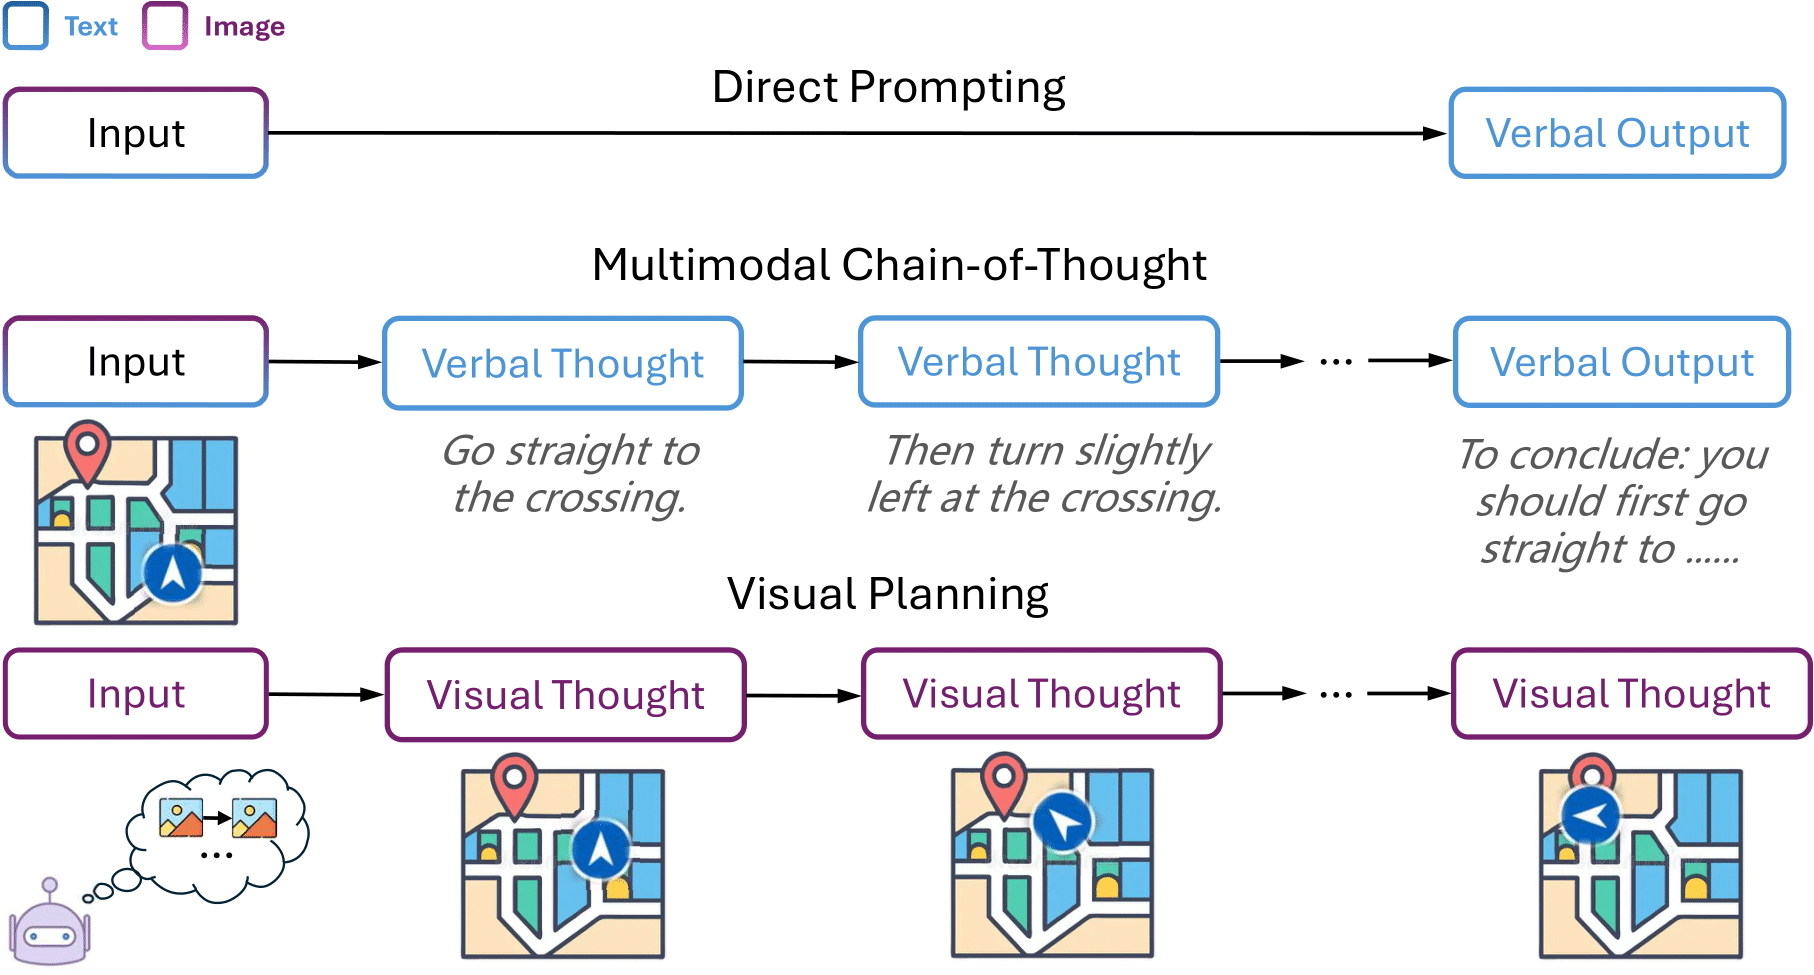
We introduce Visual Planning, a new reasoning paradigm where planning is conducted entirely through sequences of images, without relying on language. Unlike traditional multimodal models that use visual input but still reason in text, our approach enables models to "think" directly in the visual domain. We propose a reinforcement learning framework, VPRL, which significantly outperforms language-based baselines on spatial navigation tasks.
✨ Method
We propose a novel two-stage reinforcement learning training framework:
- Stage 1: Policy Initialization: Acquire the effective exploration capability and produce visually coherent output.
- Stage 2: Reinforcement Learning for Visual Planning: Learn to simulate future visual states and plan effectively via Group Relative Policy Optimization (GRPO), guided by our proposed Progress Reward.
🤗 Models
We release the following model checkpoints on Hugging Face:
| Environment | Checkpoint |
|---|---|
| MiniBehaviour | VPRL-7B-MiniBehaviour |
| Maze | VPRL-7B-Maze |
| FrozenLake | VPRL-7B-FrozenLake |
🛠️ Install
Please first create a conda environment:
conda create -n visualplanning python=3.12.3
conda activate visualplanning
Then run:
bash scripts/install.sh
🚀 Quick Start
VPFT
VPFT corresponds to supervised fine-tuning on optimal trajectories:
bash scripts/sft_optimal.sh frozenlake
bash scripts/sft_optimal.sh maze
bash scripts/sft_optimal.sh minibehaviour
VPRL Stage 1
Stage 1 performs policy initialization with random trajectory supervision:
bash scripts/sft_random.sh frozenlake
bash scripts/sft_random.sh maze
bash scripts/sft_random.sh minibehaviour
VPRL Stage 2
Stage 2 performs reinforcement learning with GRPO:
bash scripts/grpo.sh frozenlake
bash scripts/grpo.sh maze
bash scripts/grpo.sh minibehaviour
📊 Evaluation
We evaluate VPRL across three diverse visual planning environments:
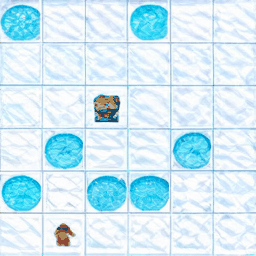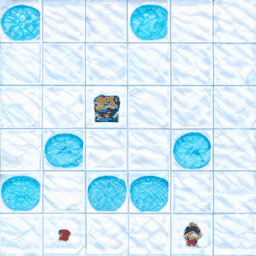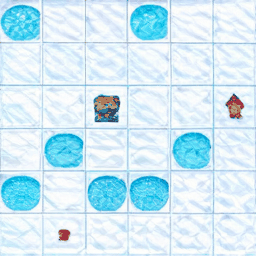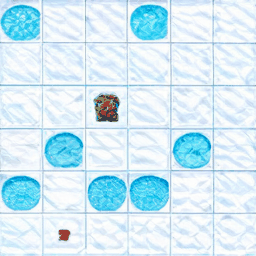
- FrozenLake:
A stochastic gridworld where the agent is supposed to start from the designated position and find its way to the destination safely without falling into the 'holes'
- Maze:
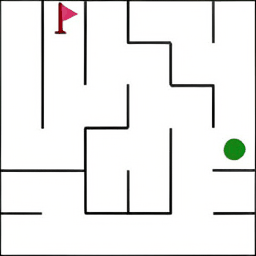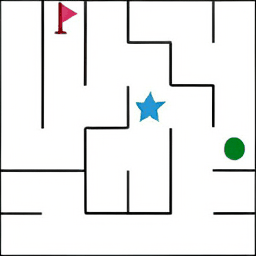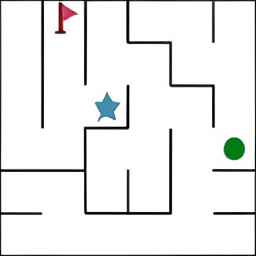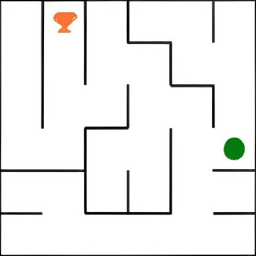
Given an initial image describing the maze layout, the model is supposed to go through the maze from the starting point (green point) to the destination (red flag).
- MiniBehaviour:
The agent is first required to reach the printer from the starting point and pick it up. After that, the agent should go to the table and drop the printer.
📑 Citation
If you find Visual Planning useful for your research and applications, please cite using this BibTeX:
@misc{xu2025visualplanningletsthink,
      title={Visual Planning: Let's Think Only with Images},
      author={Yi Xu and Chengzu Li and Han Zhou and Xingchen Wan and Caiqi Zhang and Anna Korhonen and Ivan Vulić},
      year={2025},
      eprint={2505.11409},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2505.11409},
}
Significant stargazers

4 followers · starred May 2025
Similar repos


[ICLR 2026 Oral] Visual Planning: Let's Think Only with Images
Python
377
41 commits
updated Apr 24, 2026
README
Visual Planning: Let's Think Only with Images
If you find this project interesting, please give us a star ⭐ on GitHub to support us. 🙏🙏
📰 News
- [2026.04] We release the training datasets and training scripts for Visual Planning.
- [2026.02] Our paper Visual Planning: Let's Think Only with Images was accepted as an ICLR Oral.
💡 Overview
We introduce Visual Planning, a new reasoning paradigm where planning is conducted entirely through sequences of images, without relying on language. Unlike traditional multimodal models that use visual input but still reason in text, our approach enables models to "think" directly in the visual domain. We propose a reinforcement learning framework, VPRL, which significantly outperforms language-based baselines on spatial navigation tasks.
✨ Method
We propose a novel two-stage reinforcement learning training framework:
- Stage 1: Policy Initialization: Acquire the effective exploration capability and produce visually coherent output.
- Stage 2: Reinforcement Learning for Visual Planning: Learn to simulate future visual states and plan effectively via Group Relative Policy Optimization (GRPO), guided by our proposed Progress Reward.
🤗 Models
We release the following model checkpoints on Hugging Face:
| Environment | Checkpoint |
|---|---|
| MiniBehaviour | VPRL-7B-MiniBehaviour |
| Maze | VPRL-7B-Maze |
| FrozenLake | VPRL-7B-FrozenLake |
🛠️ Install
Please first create a conda environment:
conda create -n visualplanning python=3.12.3
conda activate visualplanning
Then run:
bash scripts/install.sh
🚀 Quick Start
VPFT
VPFT corresponds to supervised fine-tuning on optimal trajectories:
bash scripts/sft_optimal.sh frozenlake
bash scripts/sft_optimal.sh maze
bash scripts/sft_optimal.sh minibehaviour
VPRL Stage 1
Stage 1 performs policy initialization with random trajectory supervision:
bash scripts/sft_random.sh frozenlake
bash scripts/sft_random.sh maze
bash scripts/sft_random.sh minibehaviour
VPRL Stage 2
Stage 2 performs reinforcement learning with GRPO:
bash scripts/grpo.sh frozenlake
bash scripts/grpo.sh maze
bash scripts/grpo.sh minibehaviour
📊 Evaluation
We evaluate VPRL across three diverse visual planning environments:
- FrozenLake:
A stochastic gridworld where the agent is supposed to start from the designated position and find its way to the destination safely without falling into the 'holes'
- Maze:
Given an initial image describing the maze layout, the model is supposed to go through the maze from the starting point (green point) to the destination (red flag).
- MiniBehaviour:
The agent is first required to reach the printer from the starting point and pick it up. After that, the agent should go to the table and drop the printer.
📑 Citation
If you find Visual Planning useful for your research and applications, please cite using this BibTeX:
@misc{xu2025visualplanningletsthink,
      title={Visual Planning: Let's Think Only with Images},
      author={Yi Xu and Chengzu Li and Han Zhou and Xingchen Wan and Caiqi Zhang and Anna Korhonen and Ivan Vulić},
      year={2025},
      eprint={2505.11409},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2505.11409},
}
Similar repos
Significant stargazers
4 followers · starred May 2025