YaFSDP is a Sharded Data Parallelism framework, designed to work well with transformer-like neural network architectures. YaFSDP is developed and maintained by Yandex.
You can find more info on YaFSDP internals in our blog posts on Medium and Habr.
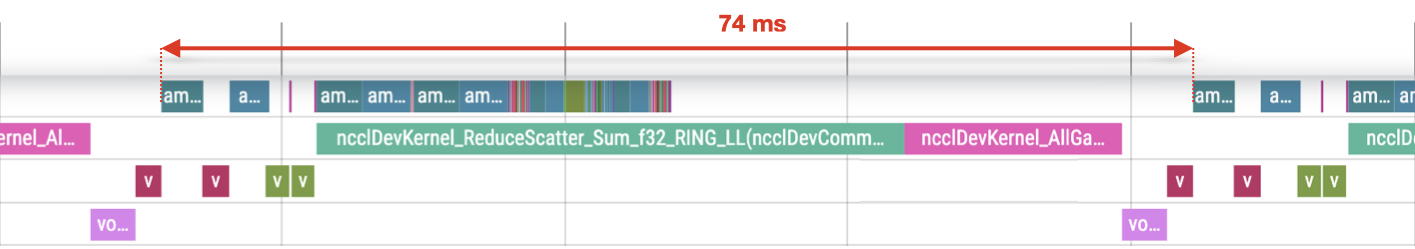
YaFSDP is up to 20% faster for pre-training LLMs and performs better in high memory pressure conditions. It is designed to reduce communications and memory operations overhead.
YaFSDP:
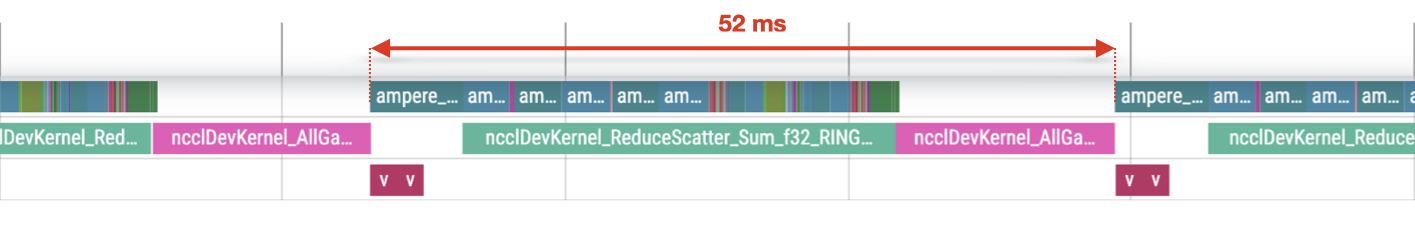
FSDP:
We've compared YaFSDP with FSDP on a variety of pre-training setups ranging from:
| model | gpu-count | seq-len | num-ckpt-layers | speedup | YaFSDP iteration time (s) | FSDP iteration time (s) |
|---|---|---|---|---|---|---|
| Llama 2 7B | 64 | 2048 | 0 | 9.92% | 0.81 | 0.90 |
| Llama 2 7B | 64 | 4096 | 0 | 3.43% | 1.16 | 1.21 |
| Llama 2 7B | 64 | 8192 | 0 | 2.68% | 2.23 | 2.29 |
| Llama 2 7B | 128 | 2048 | 0 | 9.57% | 0.87 | 0.97 |
| Llama 2 7B | 128 | 4096 | 0 | 2.42% | 1.19 | 1.22 |
| Llama 2 7B | 128 | 8192 | 0 | 2.32% | 2.25 | 2.31 |
| Llama 2 13B | 128 | 2048 | 0 | 12.10% | 1.55 | 1.76 |
| Llama 2 13B | 128 | 4096 | 0 | 3.49% | 2.06 | 2.14 |
| Llama 2 34B | 128 | 2048 | 0 | 20.70% | 3.39 | 4.27 |
| Llama 2 34B | 256 | 2048 | 0 | 21.99% | 3.51 | 4.50 |
| Llama 2 34B | 256 | 4096 | 5 | 8.35% | 5.33 | 5.81 |
| Llama 2 70B | 256 | 2048 | 10 | 21.48% | 6.97 | 8.87 |
| Llama 2 70B | 256 | 4096 | 50 | 7.17% | 11.07 | 11.93 |
| Llama 3 8B | 64 | 2048 | 0 | 11.91% | 0.97 | 1.10 |
| Llama 3 8B | 64 | 4096 | 0 | 7.86% | 1.36 | 1.48 |
| Llama 3 70B | 256 | 2048 | 20 | 26.60% | 7.17 | 9.76 |
Details:
speedup represents relative iteration time decrease between YaFSDP and FSDP runs.num-ckpt-layers refers to the number of transformer layers to which
activation checkpointing was applied.You can find examples of LLM training using 🤗 stack in the examples folder:
clm.md for causal pre-trainingsft.md for supervised fine-tuningNotice that both examples require a Docker image, which can be built using
docker/build.sh script. The image is based on the NVIDIA PyTorch
image
with some patched 🤗 libraries. Patches for the libraries can be found in the
patches folder.
If you encounter any bugs of have any questions feel free to open a GitHub issue.
If you use this codebase, please cite it by using the following BibTeX entry:
@misc{YaFSDP2024,
  author =       {Mikhail Khrushchev and Anton Frolov and Ruslan Vasilev},
  title =        {YaFSDP: Yet another Fully Sharded Data Parallel},
  howpublished = {\url{https://github.com/yandex/YaFSDP}},
  year =         {2024}
}
5,294 followers · starred Apr 2025
2,623 followers · starred Apr 2025
215 followers · starred Jun 2024
4,364 followers · starred Jul 2024
YaFSDP is a Sharded Data Parallelism framework, designed to work well with transformer-like neural network architectures. YaFSDP is developed and maintained by Yandex.
You can find more info on YaFSDP internals in our blog posts on Medium and Habr.
YaFSDP is up to 20% faster for pre-training LLMs and performs better in high memory pressure conditions. It is designed to reduce communications and memory operations overhead.
YaFSDP:
FSDP:
We've compared YaFSDP with FSDP on a variety of pre-training setups ranging from:
| model | gpu-count | seq-len | num-ckpt-layers | speedup | YaFSDP iteration time (s) | FSDP iteration time (s) |
|---|---|---|---|---|---|---|
| Llama 2 7B | 64 | 2048 | 0 | 9.92% | 0.81 | 0.90 |
| Llama 2 7B | 64 | 4096 | 0 | 3.43% | 1.16 | 1.21 |
| Llama 2 7B | 64 | 8192 | 0 | 2.68% | 2.23 | 2.29 |
| Llama 2 7B | 128 | 2048 | 0 | 9.57% | 0.87 | 0.97 |
| Llama 2 7B | 128 | 4096 | 0 | 2.42% | 1.19 | 1.22 |
| Llama 2 7B | 128 | 8192 | 0 | 2.32% | 2.25 | 2.31 |
| Llama 2 13B | 128 | 2048 | 0 | 12.10% | 1.55 | 1.76 |
| Llama 2 13B | 128 | 4096 | 0 | 3.49% | 2.06 | 2.14 |
| Llama 2 34B | 128 | 2048 | 0 | 20.70% | 3.39 | 4.27 |
| Llama 2 34B | 256 | 2048 | 0 | 21.99% | 3.51 | 4.50 |
| Llama 2 34B | 256 | 4096 | 5 | 8.35% | 5.33 | 5.81 |
| Llama 2 70B | 256 | 2048 | 10 | 21.48% | 6.97 | 8.87 |
| Llama 2 70B | 256 | 4096 | 50 | 7.17% | 11.07 | 11.93 |
| Llama 3 8B | 64 | 2048 | 0 | 11.91% | 0.97 | 1.10 |
| Llama 3 8B | 64 | 4096 | 0 | 7.86% | 1.36 | 1.48 |
| Llama 3 70B | 256 | 2048 | 20 | 26.60% | 7.17 | 9.76 |
Details:
speedup represents relative iteration time decrease between YaFSDP and FSDP runs.num-ckpt-layers refers to the number of transformer layers to which
activation checkpointing was applied.You can find examples of LLM training using 🤗 stack in the examples folder:
clm.md for causal pre-trainingsft.md for supervised fine-tuningNotice that both examples require a Docker image, which can be built using
docker/build.sh script. The image is based on the NVIDIA PyTorch
image
with some patched 🤗 libraries. Patches for the libraries can be found in the
patches folder.
If you encounter any bugs of have any questions feel free to open a GitHub issue.
If you use this codebase, please cite it by using the following BibTeX entry:
@misc{YaFSDP2024,
  author =       {Mikhail Khrushchev and Anton Frolov and Ruslan Vasilev},
  title =        {YaFSDP: Yet another Fully Sharded Data Parallel},
  howpublished = {\url{https://github.com/yandex/YaFSDP}},
  year =         {2024}
}
5,294 followers · starred Apr 2025
2,623 followers · starred Apr 2025
215 followers · starred Jun 2024
4,364 followers · starred Jul 2024