
[NeurIPS 2026] V-CAST: Video Curvature-Aware Spatio-Temporal Pruning for Efficient Video Large Language Models
See the codeREADME
✂️ V-CAST: Video Curvature-Aware Spatio-Temporal Pruning for Efficient Video Large Language Models
Xinying Lin1,2, Xuyang Liu3, Yiyu Wang4, Teng Ma1, Jiasheng Li4, Zichen Wen4, Wenqi Ren1,2
1 Sun Yat-sen University Shenzhen Campus 2 Shenzhen Loop Area Institute
3 Sichuan University 4 Shanghai Jiao Tong University
⚡ A training-free and plug-and-play Curvature-Aware Spatio-Temporal pruning framework for efficient long-context video inference.
🔥 News
2026.09.25🎉🎉 Our V-CAST has been accepted to NeurIPS 2026!2026.03.26🤗🤗 We opened the V-CAST repository.
🎯 Highlights
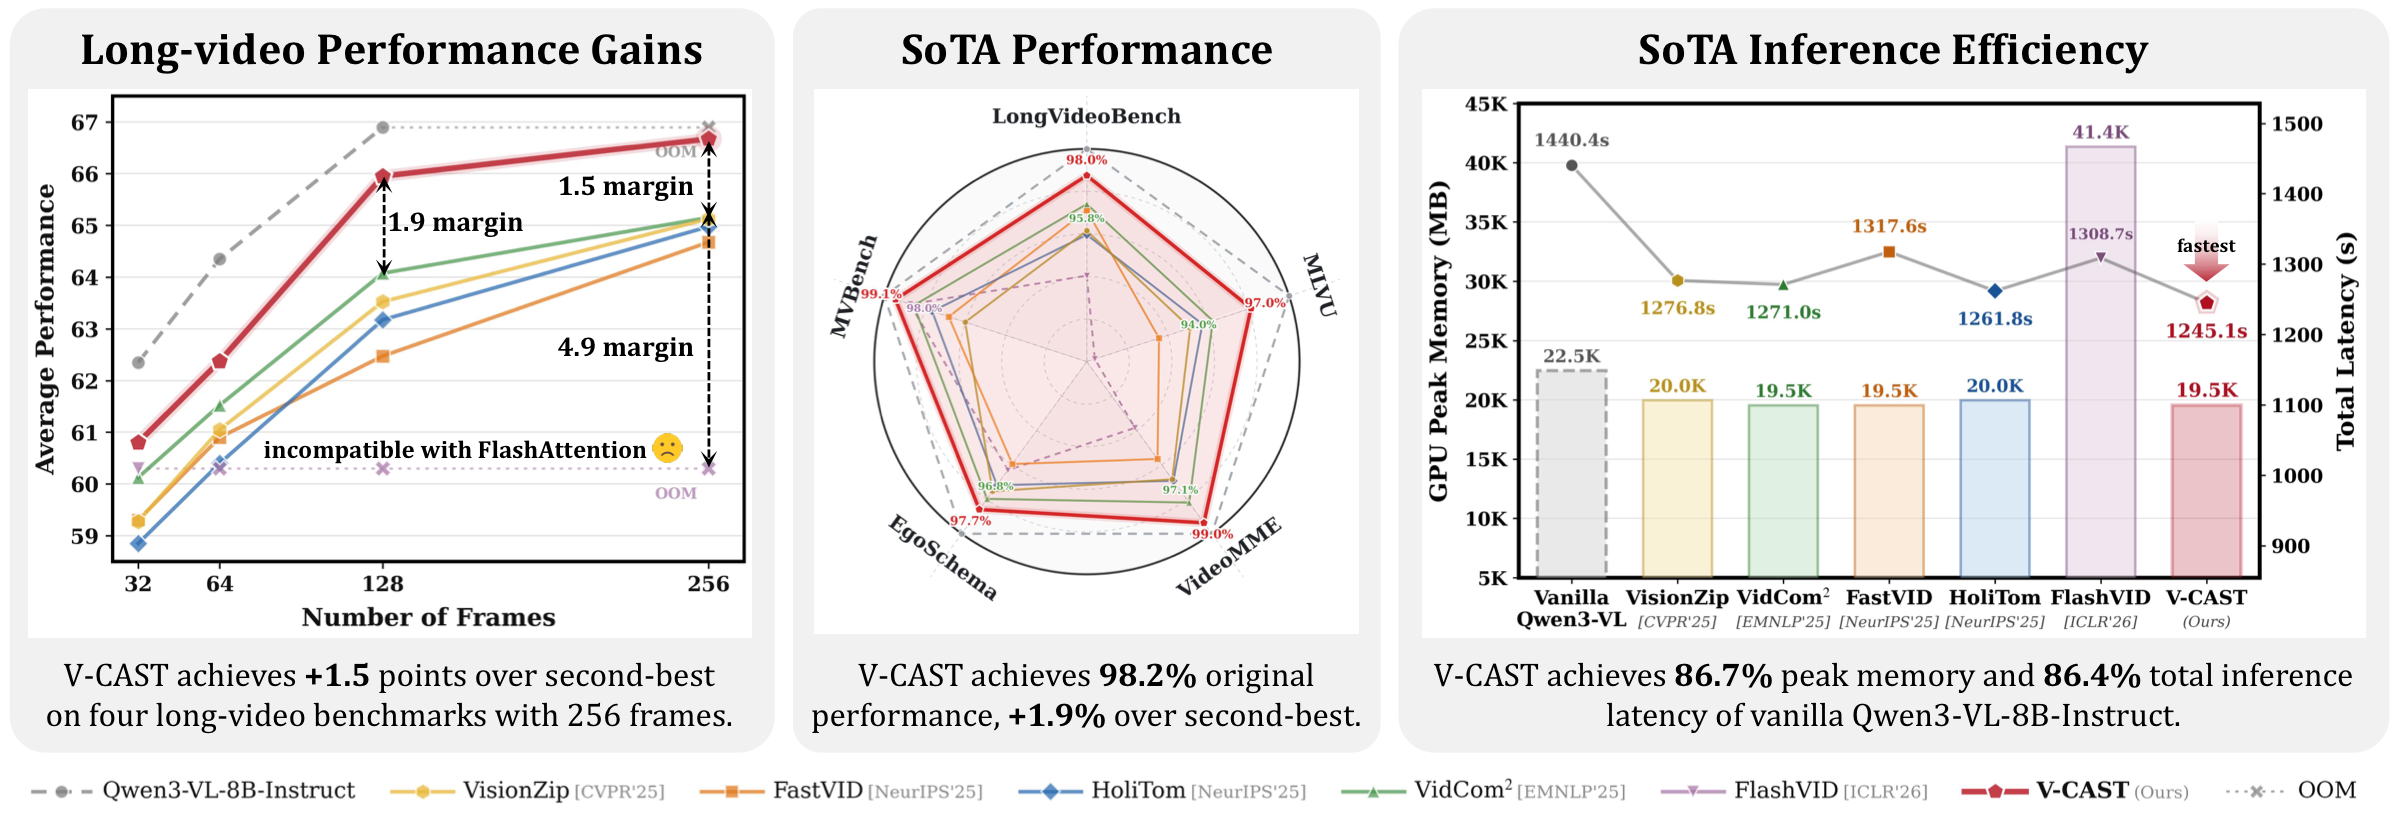
- Curvature-aware spatio-temporal pruning: V-CAST allocates temporal budget according to video curvature and performs coordinate-preserving spatial pruning.
- Training-free and plug-and-play: V-CAST can be integrated into VideoLLMs without retraining.
- Coverage-oriented compression: V-CAST explicitly addresses discontinuous coverage and token-merging-induced position drift.
- Strong accuracy-efficiency trade-off: V-CAST preserves 98.6% of original performance, outperforms the second-best baseline by +1.1% on average, and reduces peak memory and total latency to 86.7% and 86.4% of vanilla Qwen3-VL-8B-Instruct.
✨ Overview
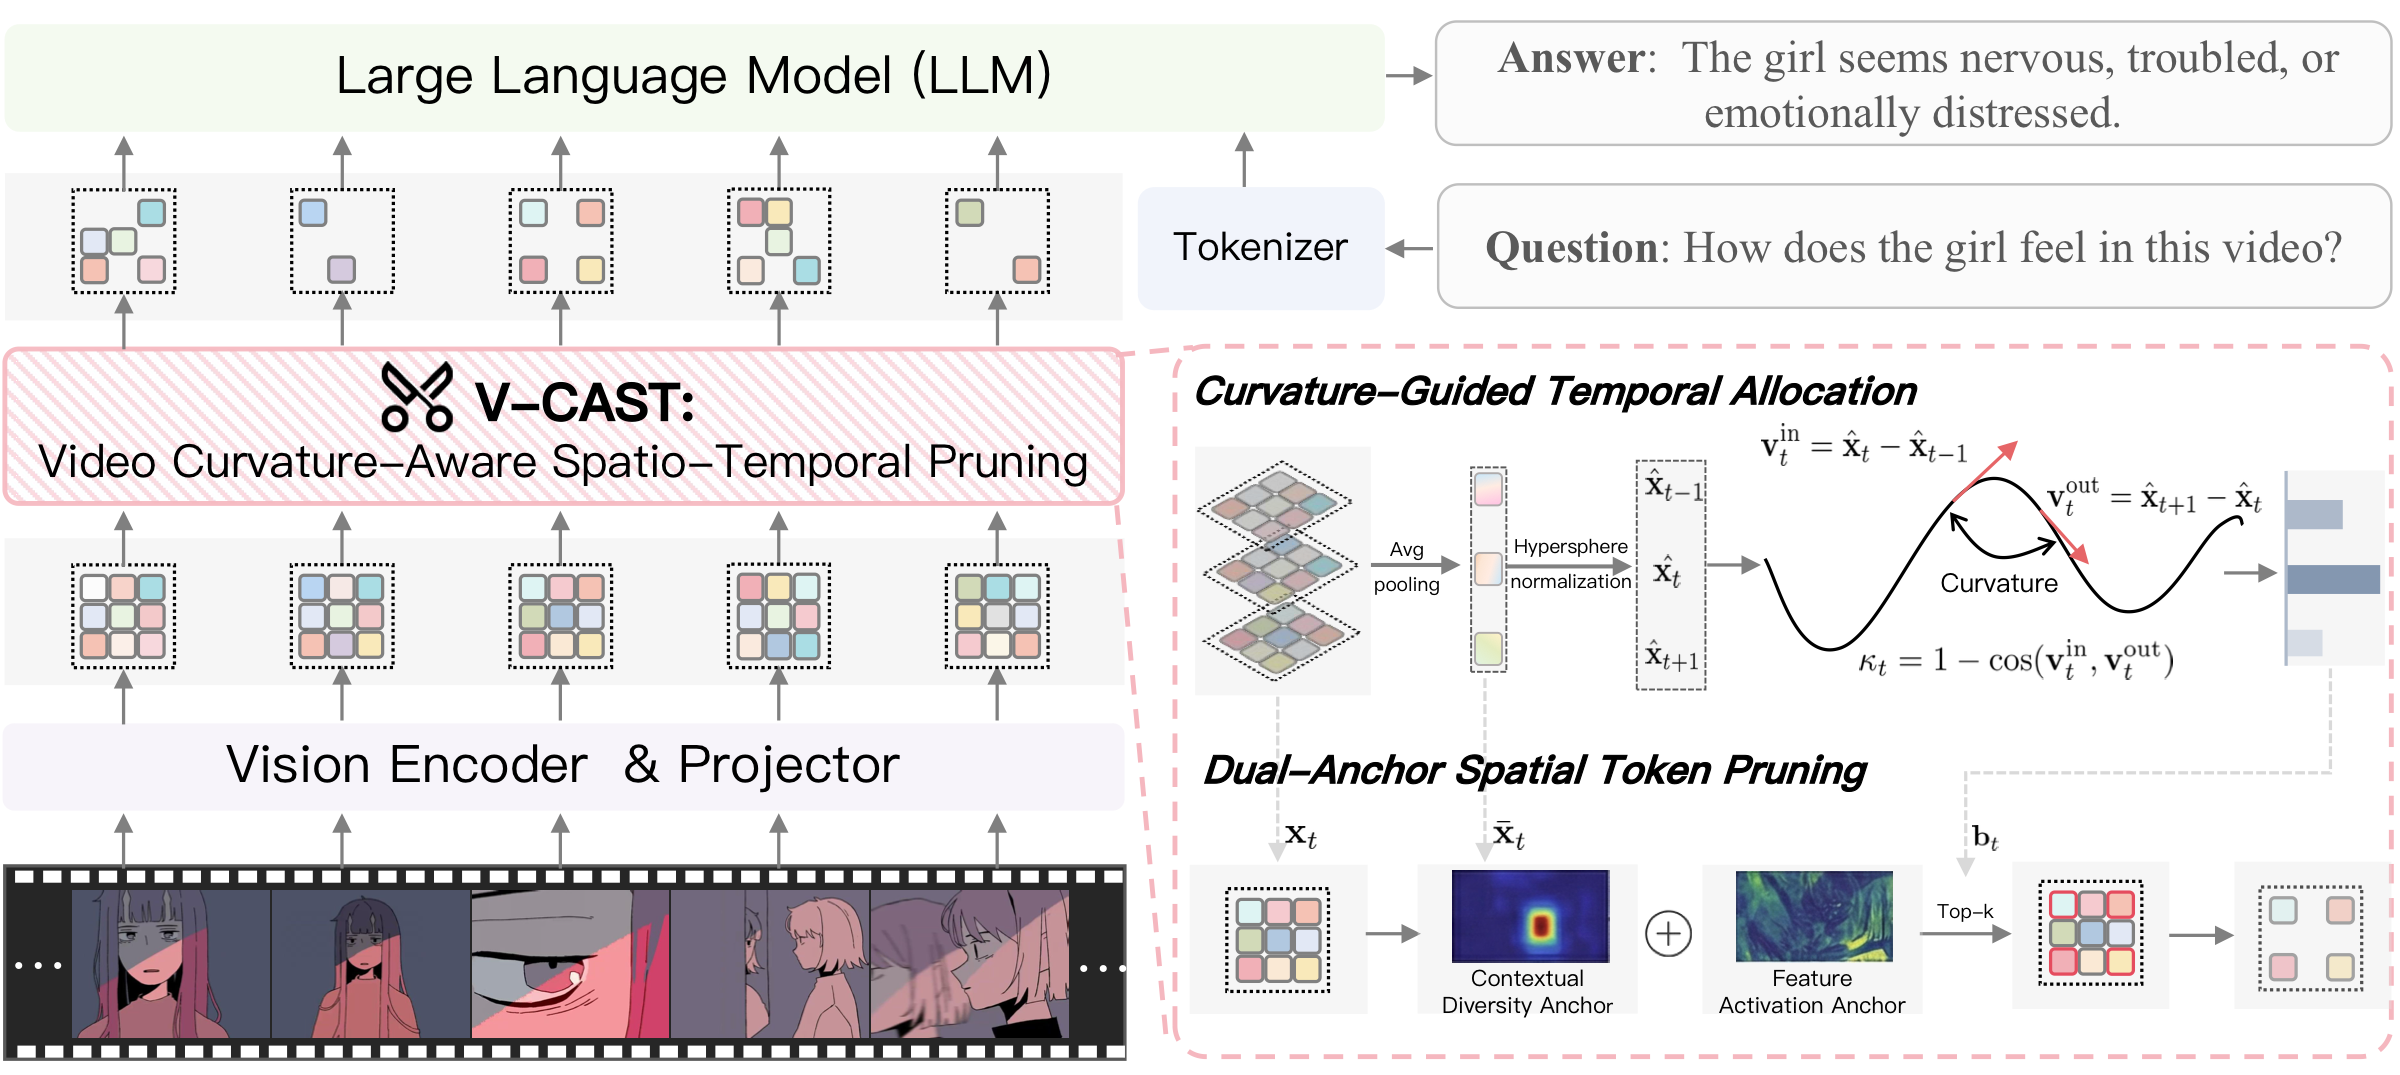
V-CAST is a training-free and plug-and-play curvature-aware spatio-temporal pruning framework for efficient long-context video inference. It revisits token compression from the perspective of spatio-temporal information coverage, and combines:
- Curvature-guided temporal allocation to route more budget to semantic turns and event boundaries.
- Coordinate-preserving spatial pruning to retain informative tokens without breaking the original
(t, h, w)grid. - Compatibility with VideoLLMs through a clean pruning-based design that avoids token merging drift.
🛠 Preparation
- Clone the repository:
git clone https://github.com/xinyouu/V-CAST.git
cd V-CAST
- Create the environment:
conda create -n vcast python=3.10 -y
conda activate vcast
pip install --upgrade pip
pip install -e ".[train]"
- Install lmms-eval:
If you want to measure the latency and GPU memory, please use the custom installation.
cd lmms-eval
pip install -e .
Or you can also use the official installation.
pip install git+https://github.com/EvolvingLMMs-Lab/lmms-eval.git
🚀 Performance Evaluation
| Model Base | Status | Code Path |
|---|---|---|
| Qwen3-VL | ✅ Released | compressor/v_cast/modeling_qwen3_vl_v_cast.py |
| LLaVA-OneVision / LLaVA-Video | 🚧 Planned | - |
| Qwen2.5-Omni / Qwen3-Omni | 🚧 Planned | - |
Our evaluation pipeline is built on top of lmms-eval, a unified toolkit for multimodal evaluation across text, image, video, and audio tasks. The current public release focuses on the Qwen3-VL evaluation path with V-CAST enabled by default, while additional model-family integrations will be released in follow-up updates. Some comparison baselines are also available in the open-source VidCom2 repository.
Quick Start
bash examples/v_cast/inference_qwen3vl_v_cast_64.sh
Core Public Paths
| Component | Path |
|---|---|
| V-CAST wrapper | compressor/v_cast/main.py |
| V-CAST core implementation | compressor/v_cast/modeling_qwen3_vl_v_cast.py |
| Qwen3-VL evaluation wrapper | lmms_eval/models/simple/qwen3_vl.py |
| Example script | examples/v_cast/inference_qwen3vl_v_cast_64.sh |
📌 Citation
If you find this repository useful, please cite:
@article{lin2026vcast,
  title={V-CAST: Video Curvature-Aware Spatio-Temporal Pruning for Efficient Video Large Language Models},
  author={Lin, Xinying and Liu, Xuyang and Wang, Yiyu and Ma, Teng and Ren, Wenqi},
  journal={arXiv preprint arXiv:2603.27650},
  year={2026}
}
👍 Acknowledgment
We extend our gratitude to the open-source efforts of LLaVA-OneVision and Qwen3-VL.
📩 Contact
For any question about our paper or code, please email xinyinglin@slai.edu.cn.
Similar repos


Languages
Python
99.9%
[NeurIPS 2026] V-CAST: Video Curvature-Aware Spatio-Temporal Pruning for Efficient Video Large Language Models
See the codeREADME
✂️ V-CAST: Video Curvature-Aware Spatio-Temporal Pruning for Efficient Video Large Language Models
Xinying Lin1,2, Xuyang Liu3, Yiyu Wang4, Teng Ma1, Jiasheng Li4, Zichen Wen4, Wenqi Ren1,2
1 Sun Yat-sen University Shenzhen Campus 2 Shenzhen Loop Area Institute
3 Sichuan University 4 Shanghai Jiao Tong University
⚡ A training-free and plug-and-play Curvature-Aware Spatio-Temporal pruning framework for efficient long-context video inference.
🔥 News
2026.09.25🎉🎉 Our V-CAST has been accepted to NeurIPS 2026!2026.03.26🤗🤗 We opened the V-CAST repository.
🎯 Highlights
- Curvature-aware spatio-temporal pruning: V-CAST allocates temporal budget according to video curvature and performs coordinate-preserving spatial pruning.
- Training-free and plug-and-play: V-CAST can be integrated into VideoLLMs without retraining.
- Coverage-oriented compression: V-CAST explicitly addresses discontinuous coverage and token-merging-induced position drift.
- Strong accuracy-efficiency trade-off: V-CAST preserves 98.6% of original performance, outperforms the second-best baseline by +1.1% on average, and reduces peak memory and total latency to 86.7% and 86.4% of vanilla Qwen3-VL-8B-Instruct.
✨ Overview
V-CAST is a training-free and plug-and-play curvature-aware spatio-temporal pruning framework for efficient long-context video inference. It revisits token compression from the perspective of spatio-temporal information coverage, and combines:
- Curvature-guided temporal allocation to route more budget to semantic turns and event boundaries.
- Coordinate-preserving spatial pruning to retain informative tokens without breaking the original
(t, h, w)grid. - Compatibility with VideoLLMs through a clean pruning-based design that avoids token merging drift.
🛠 Preparation
- Clone the repository:
git clone https://github.com/xinyouu/V-CAST.git
cd V-CAST
- Create the environment:
conda create -n vcast python=3.10 -y
conda activate vcast
pip install --upgrade pip
pip install -e ".[train]"
- Install lmms-eval:
If you want to measure the latency and GPU memory, please use the custom installation.
cd lmms-eval
pip install -e .
Or you can also use the official installation.
pip install git+https://github.com/EvolvingLMMs-Lab/lmms-eval.git
🚀 Performance Evaluation
| Model Base | Status | Code Path |
|---|---|---|
| Qwen3-VL | ✅ Released | compressor/v_cast/modeling_qwen3_vl_v_cast.py |
| LLaVA-OneVision / LLaVA-Video | 🚧 Planned | - |
| Qwen2.5-Omni / Qwen3-Omni | 🚧 Planned | - |
Our evaluation pipeline is built on top of lmms-eval, a unified toolkit for multimodal evaluation across text, image, video, and audio tasks. The current public release focuses on the Qwen3-VL evaluation path with V-CAST enabled by default, while additional model-family integrations will be released in follow-up updates. Some comparison baselines are also available in the open-source VidCom2 repository.
Quick Start
bash examples/v_cast/inference_qwen3vl_v_cast_64.sh
Core Public Paths
| Component | Path |
|---|---|
| V-CAST wrapper | compressor/v_cast/main.py |
| V-CAST core implementation | compressor/v_cast/modeling_qwen3_vl_v_cast.py |
| Qwen3-VL evaluation wrapper | lmms_eval/models/simple/qwen3_vl.py |
| Example script | examples/v_cast/inference_qwen3vl_v_cast_64.sh |
📌 Citation
If you find this repository useful, please cite:
@article{lin2026vcast,
  title={V-CAST: Video Curvature-Aware Spatio-Temporal Pruning for Efficient Video Large Language Models},
  author={Lin, Xinying and Liu, Xuyang and Wang, Yiyu and Ma, Teng and Ren, Wenqi},
  journal={arXiv preprint arXiv:2603.27650},
  year={2026}
}
👍 Acknowledgment
We extend our gratitude to the open-source efforts of LLaVA-OneVision and Qwen3-VL.
📩 Contact
For any question about our paper or code, please email xinyinglin@slai.edu.cn.
Similar repos
Languages
Python
99.9%