
A comprehensive benchmark suite for multi-view generation models
Python
21
16 commits
updated Jul 14, 2025
README
MVGBench
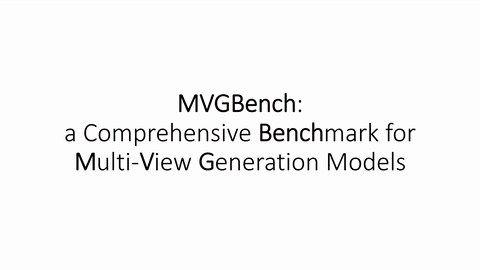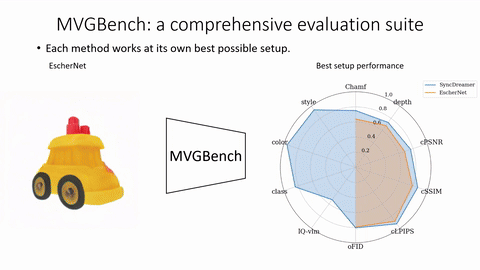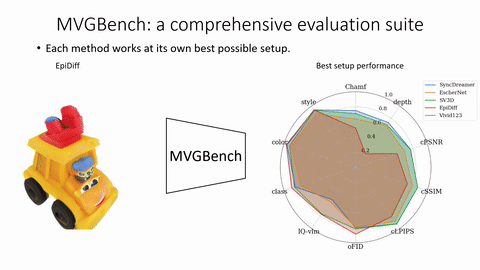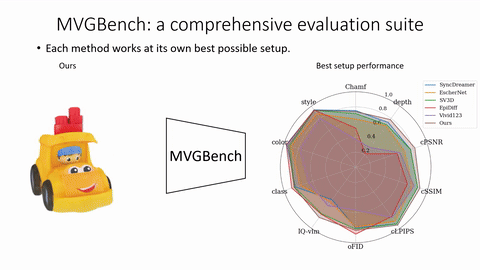
A comprehensive benchmark suite for multi-view generation models (ICCV'25)
Installation
The environment installation is similar to gaussian-splatting environment.
conda create -n mvgbench python=3.10 -y
conda activate mvgbench
pip install trimesh numpy==1.24.3 opencv-python==4.10.0.84 plyfile tqdm pillow==10.2.0 scikit-learn scikit-image lpips
pip install torch==2.2.0 torchvision==0.17.0 torchaudio==2.2.0 --index-url https://download.pytorch.org/whl/cu118

# compile 3dgs dependencies
cd submodules
git clone --recursive https://github.com/ashawkey/diff-gaussian-rasterization
pip install ./diff-gaussian-rasterization
pip install ./simple-knn
Evaluation
We offer different ways to report our metrics using example data:
- Evaluate only the five 3D consistency metrics
- Evaluate only VLM based image quality and semantic consistency
- Report all 10 metrics
For evaluating your own MVG model, please referen to this doc.
3D consistency metric
Download example eval data from this link, and do unzip example-eval.zip. These are the multi-view images generated by SV3D
and SyncDreamer.
Synthetic rendering as input
For input images generated by rendering, where one can accurately control the camera setup.Run 3dgs fitting
# 3DGS fitting
python run_mvfit.py "example/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_*/*" --white_background

# evaluation
python eval/eval_consistency.py \
  --name_odd output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_odd \
  --name_even output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_even
Real images as input
For input images from real data, where the camera poses are unknown.Similar to synthetic images, we first need to do 3DGS fitting and then compute self consistency. We additionally need to perform an alignment on the optimized 3DGS to avoid biased metrics. The alignment takes output of one method as reference and aligns all others w.r.t one 3DGS fitting.
# 3DGS fitting
python run_mvfit.py "example/*co3d2seq*/*" --white_background

python eval/align_3dgs.py --folder_tgt output/consistency/sv3dp+co3d2seq-sv3d-v21-manual+i000_even \
  --folder_src output/consistency/syncdreamer+co3d2seq-mvdfusion-v16-manual+i000_even

# Re-render with the alignment parameters, with the --normalize_gs flag
python render.py --normalize_gs --quiet --resolution 256 -m "output/consistency/syncdreamer+co3d2seq-mvdfusion-v16-manual+i000_*/*"

# Evaluate
python eval/eval_consistency.py \
  --name_odd output/consistency/syncdreamer+co3d2seq-mvdfusion-v16-manual+i000_odd \
  --name_even output/consistency/syncdreamer+co3d2seq-mvdfusion-v16-manual+i000_even \
  --test_name align-icp # use new rendering to evaluate
Add object FID (oFID) as image quality
For this you will need to download reference renderings from here After, extract it to local folder and pass the path to evaluation script:
python eval/eval_consistency.py \
  --name_odd output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_odd \
  --name_even output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_even \
  --rendering_path <root/to/unzipped>/renderings
VLM based image quality and semantic consistency
This evaluation requires 4x48GB (or equivalent) GPU memory to run.
First, download InternVL2.5 checkpoint and install additional dependencies:
# InternVL2.5 checkpoint
huggingface-cli download --resume-download --local-dir-use-symlinks False OpenGVLab/InternVL2_5-78B --local-dir pretrained/InternVL2_5-78B

# additional dependencies
pip install accelerate einops transformers==4.37.2
Second, download VLM annotations for all four datasets from this link and the unzip unzip vlm-annotation.zip -d example
Run evaluation with:
python eval/eval_vlm.py --name_even output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_even
It will print out summary of the four VLM metrics: IQ-vlm, class, color and style semantic consistency.
Accumulate all metrics
After finishing the VLM evaluation in previous step, you can now accumulate all 10 metrics into one file by adding --add_vlm flag
using the 3D consistency evaluation script. Example:
python eval/eval_consistency.py \
  --name_odd output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_odd \
  --name_even output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_even \
  --rendering_path <root/to/unzipped>/renderings --add_vlm
Citation
If you use our code, please cite:
@misc{xie2025MVGBench,
      title={MVGBench: Comprehensive Benchmark for Multi-view Generation Models},
      author={Xianghui Xie and Chuhang Zou and Meher Gitika Karumuri and Jan Eric Lenssen and Gerard Pons-Moll},
      year={2025},
      eprint={2507.00006},
      archivePrefix={arXiv},
      primaryClass={cs.GR},
      url={https://arxiv.org/abs/2507.00006},
}
Contributors

16 commits
Similar repos


Languages
Python
97.2%
Cuda
2.4%
A comprehensive benchmark suite for multi-view generation models
Python
21
16 commits
updated Jul 14, 2025
README
MVGBench
A comprehensive benchmark suite for multi-view generation models (ICCV'25)
Installation
The environment installation is similar to gaussian-splatting environment.
conda create -n mvgbench python=3.10 -y
conda activate mvgbench
pip install trimesh numpy==1.24.3 opencv-python==4.10.0.84 plyfile tqdm pillow==10.2.0 scikit-learn scikit-image lpips
pip install torch==2.2.0 torchvision==0.17.0 torchaudio==2.2.0 --index-url https://download.pytorch.org/whl/cu118

# compile 3dgs dependencies
cd submodules
git clone --recursive https://github.com/ashawkey/diff-gaussian-rasterization
pip install ./diff-gaussian-rasterization
pip install ./simple-knn
Evaluation
We offer different ways to report our metrics using example data:
- Evaluate only the five 3D consistency metrics
- Evaluate only VLM based image quality and semantic consistency
- Report all 10 metrics
For evaluating your own MVG model, please referen to this doc.
3D consistency metric
Download example eval data from this link, and do unzip example-eval.zip. These are the multi-view images generated by SV3D
and SyncDreamer.
Synthetic rendering as input
For input images generated by rendering, where one can accurately control the camera setup.Run 3dgs fitting
# 3DGS fitting
python run_mvfit.py "example/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_*/*" --white_background

# evaluation
python eval/eval_consistency.py \
  --name_odd output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_odd \
  --name_even output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_even
Real images as input
For input images from real data, where the camera poses are unknown.Similar to synthetic images, we first need to do 3DGS fitting and then compute self consistency. We additionally need to perform an alignment on the optimized 3DGS to avoid biased metrics. The alignment takes output of one method as reference and aligns all others w.r.t one 3DGS fitting.
# 3DGS fitting
python run_mvfit.py "example/*co3d2seq*/*" --white_background

python eval/align_3dgs.py --folder_tgt output/consistency/sv3dp+co3d2seq-sv3d-v21-manual+i000_even \
  --folder_src output/consistency/syncdreamer+co3d2seq-mvdfusion-v16-manual+i000_even

# Re-render with the alignment parameters, with the --normalize_gs flag
python render.py --normalize_gs --quiet --resolution 256 -m "output/consistency/syncdreamer+co3d2seq-mvdfusion-v16-manual+i000_*/*"

# Evaluate
python eval/eval_consistency.py \
  --name_odd output/consistency/syncdreamer+co3d2seq-mvdfusion-v16-manual+i000_odd \
  --name_even output/consistency/syncdreamer+co3d2seq-mvdfusion-v16-manual+i000_even \
  --test_name align-icp # use new rendering to evaluate
Add object FID (oFID) as image quality
For this you will need to download reference renderings from here After, extract it to local folder and pass the path to evaluation script:
python eval/eval_consistency.py \
  --name_odd output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_odd \
  --name_even output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_even \
  --rendering_path <root/to/unzipped>/renderings
VLM based image quality and semantic consistency
This evaluation requires 4x48GB (or equivalent) GPU memory to run.
First, download InternVL2.5 checkpoint and install additional dependencies:
# InternVL2.5 checkpoint
huggingface-cli download --resume-download --local-dir-use-symlinks False OpenGVLab/InternVL2_5-78B --local-dir pretrained/InternVL2_5-78B

# additional dependencies
pip install accelerate einops transformers==4.37.2
Second, download VLM annotations for all four datasets from this link and the unzip unzip vlm-annotation.zip -d example
Run evaluation with:
python eval/eval_vlm.py --name_even output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_even
It will print out summary of the four VLM metrics: IQ-vlm, class, color and style semantic consistency.
Accumulate all metrics
After finishing the VLM evaluation in previous step, you can now accumulate all 10 metrics into one file by adding --add_vlm flag
using the 3D consistency evaluation script. Example:
python eval/eval_consistency.py \
  --name_odd output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_odd \
  --name_even output/consistency/syncdreamer+mvdfusion-v16-elev030-amb1.0+i000+sel11v4_even \
  --rendering_path <root/to/unzipped>/renderings --add_vlm
Citation
If you use our code, please cite:
@misc{xie2025MVGBench,
      title={MVGBench: Comprehensive Benchmark for Multi-view Generation Models},
      author={Xianghui Xie and Chuhang Zou and Meher Gitika Karumuri and Jan Eric Lenssen and Gerard Pons-Moll},
      year={2025},
      eprint={2507.00006},
      archivePrefix={arXiv},
      primaryClass={cs.GR},
      url={https://arxiv.org/abs/2507.00006},
}
Similar repos
Contributors
16 commits
Languages
Python
97.2%
Cuda
2.4%