
A curated list of papers and resources based on the survey "Agentic Reasoning for Large Language Models"
See the codeREADME
Awesome Agentic Reasoning Papers





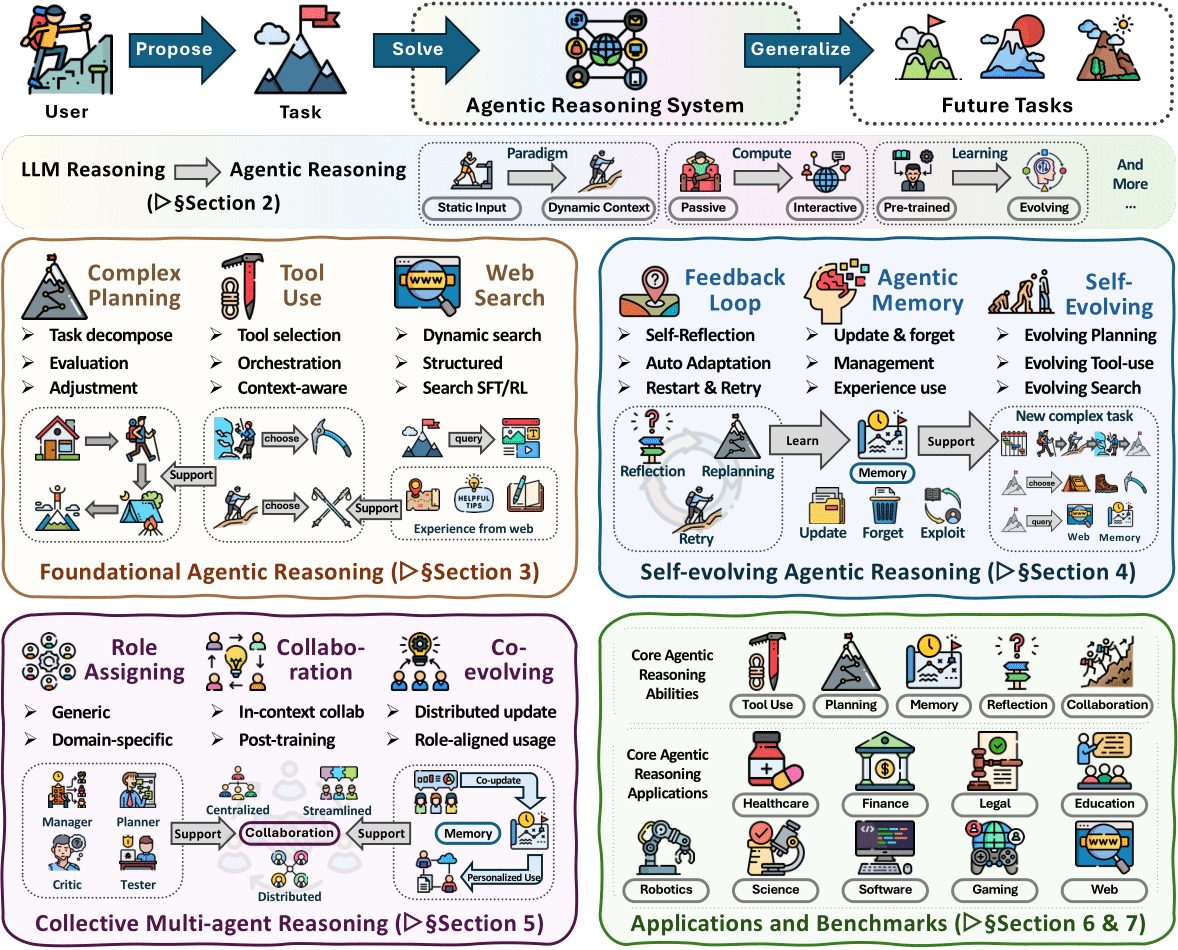
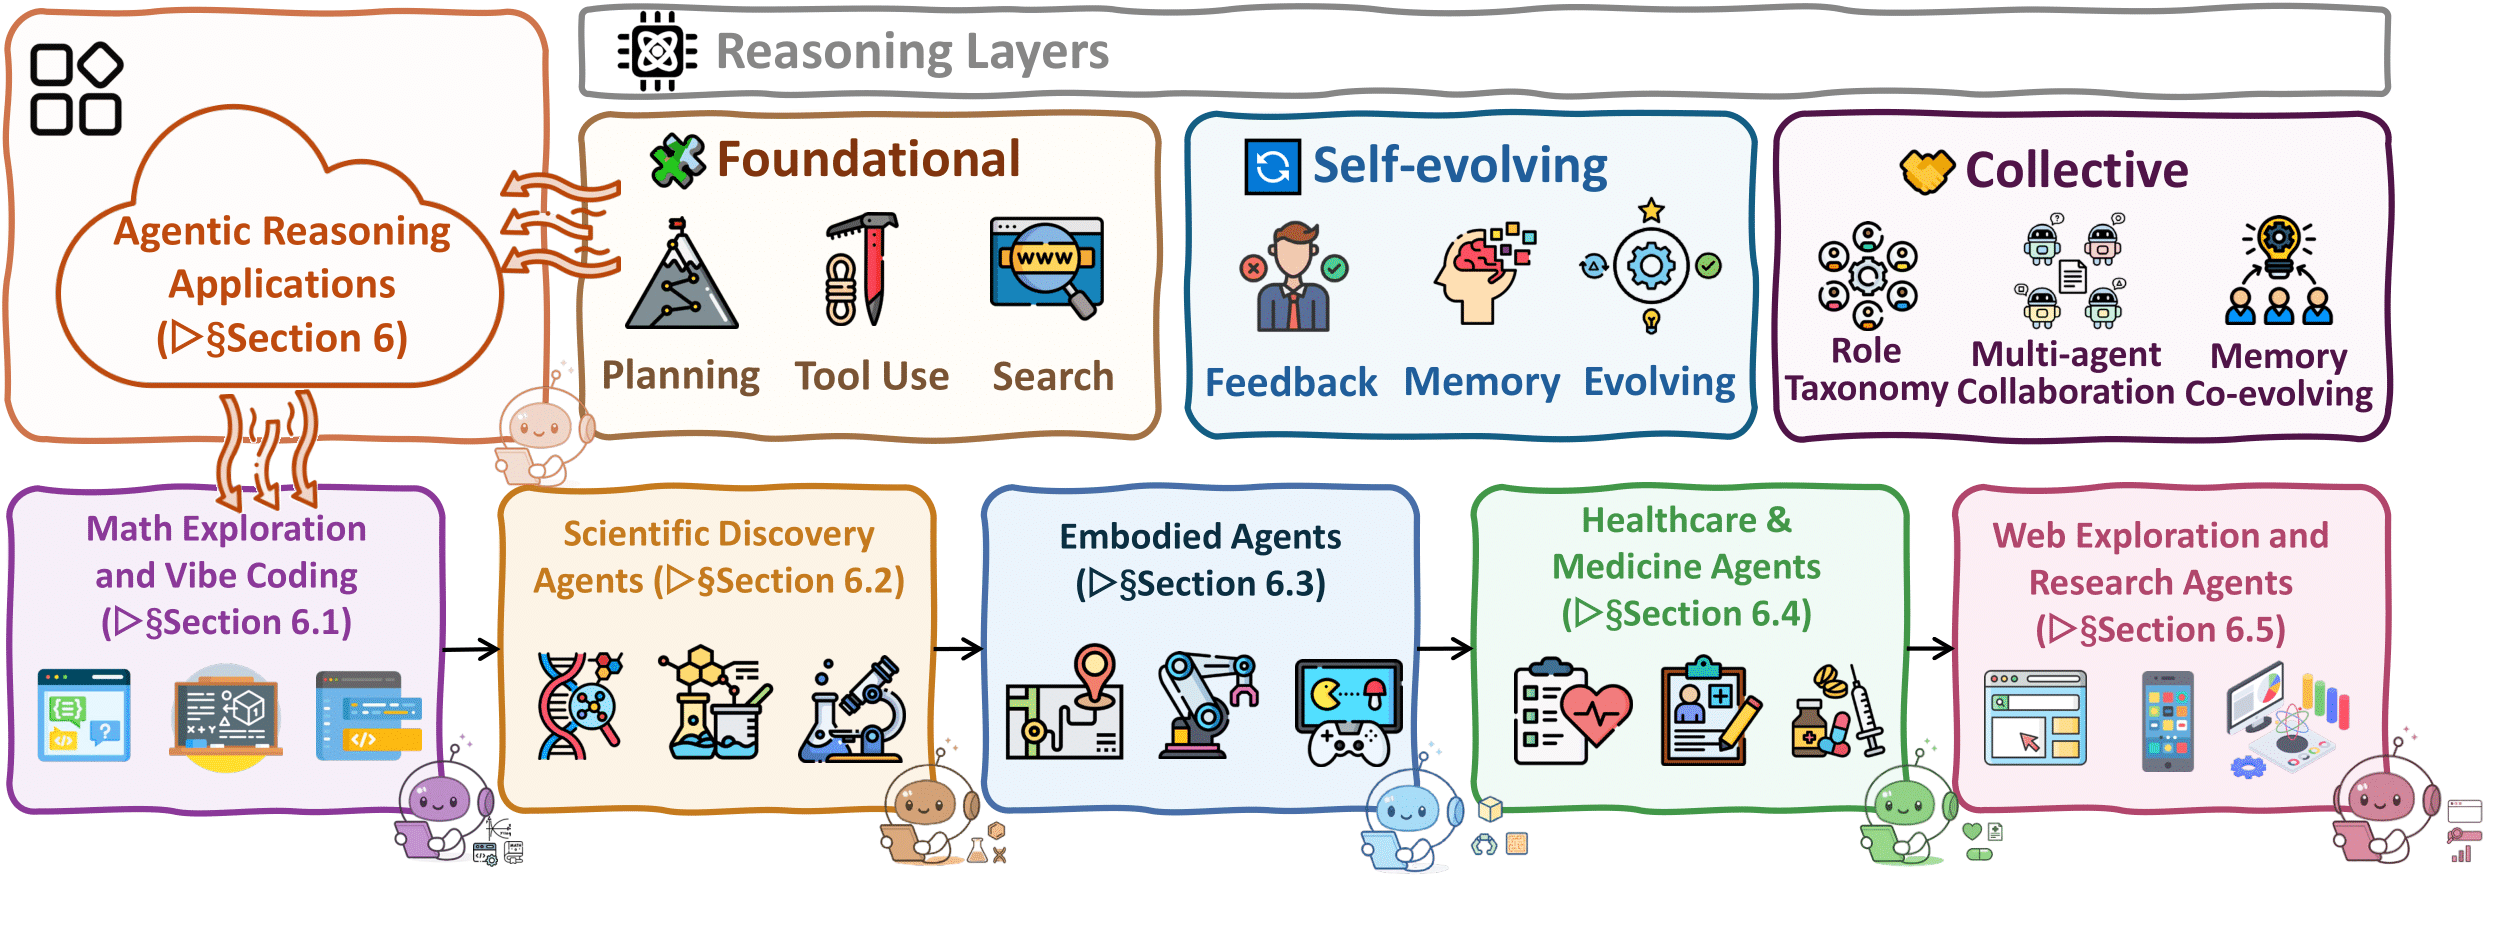
This repository organizes research by thematic areas that integrate reasoning with action, including planning, tool use, search, self-evolution and recursive self-improvement (RSI) through memory and feedback, collective intelligence in multi-agent systems, and real-world applications and benchmarks.
📄 Based on the survey: Agentic Reasoning for Large Language Models: A Survey
🔔 News
[09/19/26] 🎉 Our survey, A Survey of Agentic Reasoning for Large Language Models: Towards Recursively Self-Improving and Collective Agents, has been accepted to Transactions on Machine Learning Research (TMLR)!
[03/09/26] 📊 Slides are now available to provide a clearer overview of the survey and highlight key insights. We will continue updating the paper with further improvements.
[01/21/26] 🚀 We have released a comprehensive survey, A Survey of Agentic Reasoning for Large Language Models: Towards Recursively Self-Improving and Collective Agents! The paper is now available on arxiv and HuggingFace. We welcome contributions from the community to help expand and improve our survey 🤗!
📋 Table of Contents
- 🔔 News
- 📋 Table of Contents
- 🌟 Introduction
- 🤝 Contributing
- 📝 Citation
- 🏗️ Foundational Agentic Reasoning
- 🧬 Self-evolving Agentic Reasoning
- 👥 Collective Multi-agent Reasoning
- 🎨 Applications
- 📊 Benchmarks
🌟 Introduction
Bridging thought and action through autonomous agents that reason, act, and learn via continual interaction with their environments. The goal is to enhance agent capabilities by grounding reasoning in action.
We organize agentic reasoning into three layers, each corresponding to a distinct reasoning paradigm under different environmental dynamics:
🔹 Foundational Reasoning. Core single-agent abilities (planning, tool-use, search) in environments
🔹 Self-Evolving Reasoning. Adaptation through feedback, memory, and learning in dynamic settings
🔹 Collective Reasoning. Multi-agent coordination, role specialization, and collaborative intelligence
Across these layers, we further identify complementary reasoning paradigms defined by their optimization settings.
🔸 In-Context Reasoning. Test-time scaling through structured orchestration and adaptive workflows
🔸 Post-Training Reasoning. Behavior optimization via RL and supervised fine-tuning
🤝 Contributing
This collection is an ongoing effort. We are actively expanding and refining its coverage, and welcome contributions from the community. You can:
- Submit a pull request to add papers or resources
- Open an issue to suggest additional papers or resources
- Email us at twei10@illinois.edu, twli@illinois.edu, liu326@illinois.edu
We regularly update the repository to include new research works on agentic reasoning.
📝 Citation
If you find this repository or paper useful, please consider citing the survey paper:
@article{wei2026agentic,
  title={Agentic Reasoning for Large Language Models},
  author={Wei, Tianxin and Li, Ting-Wei and Liu, Zhining and Ning, Xuying and Yang, Ze and Zou, Jiaru and Zeng, Zhichen and Qiu, Ruizhong and Lin, Xiao and Fu, Dongqi and others},
  journal={arXiv preprint arXiv:2601.12538},
  year={2026}
}
🏗️ Foundational Agentic Reasoning
🗺️ Planning Reasoning
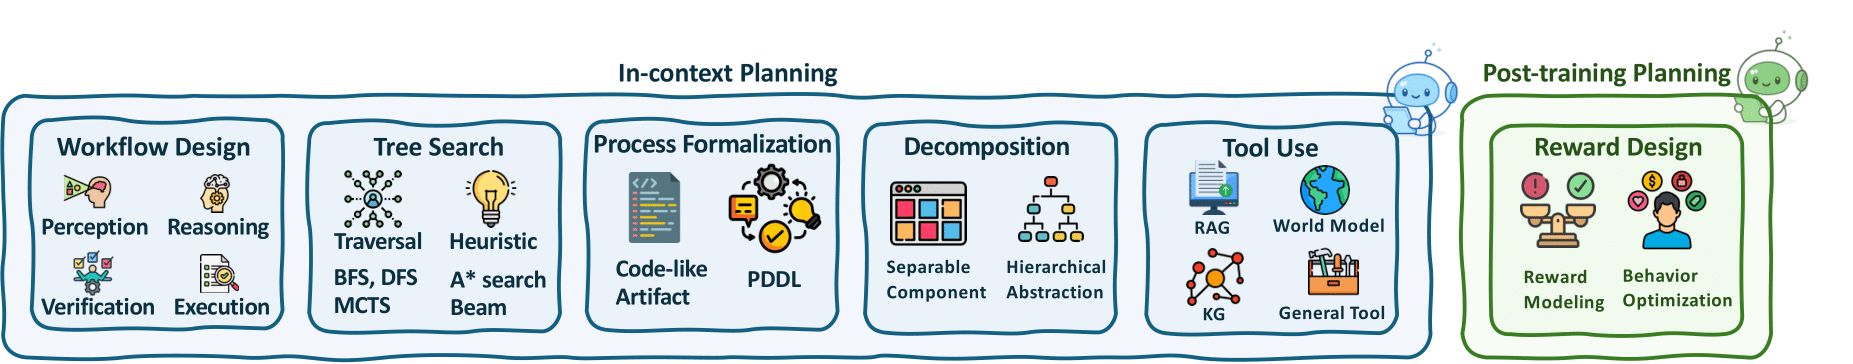
In-context Planning
Workflow Design
Tree Search / Algorithm Simulation
Process Formalization
Decoupling / Decomposition
External Aid / Tool Use
Post-training Planning
🛠️ Tool-Use Optimization
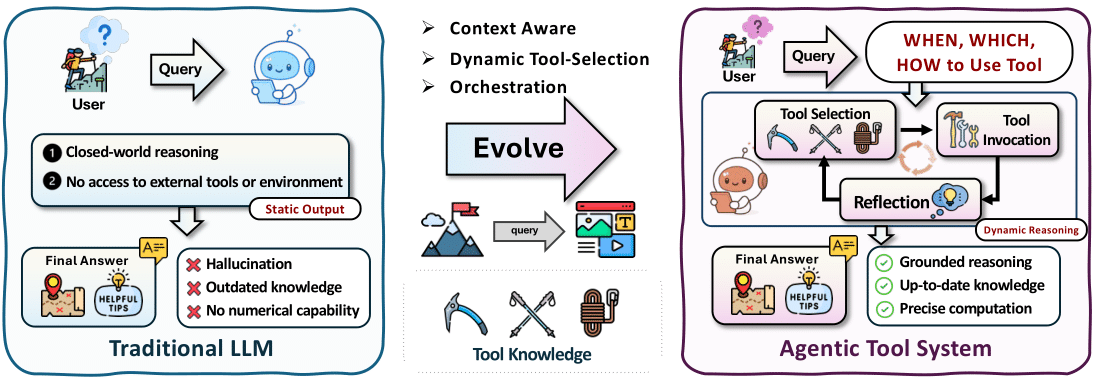
In-Context Tool-Integration
Interleaving Reasoning and Tool Use
Optimizing Context for Tool Interaction
Post-training Tool-Integration
Bootstrapping of Tool Use via SFT
Mastery of Tool Use via RL
Orchestration-based Tool-Integration
Agentic Pipelines for Tool Orchestration
Tool Representations for Orchestration
Practical Tools and Infrastructure
| Resource | Year |
|---|---|
| Agentic Reasoning Protocol (reasoning.json) [code] | 2026 |
| OpenClaw Monitor | 2025 |
🔍 Agentic Search
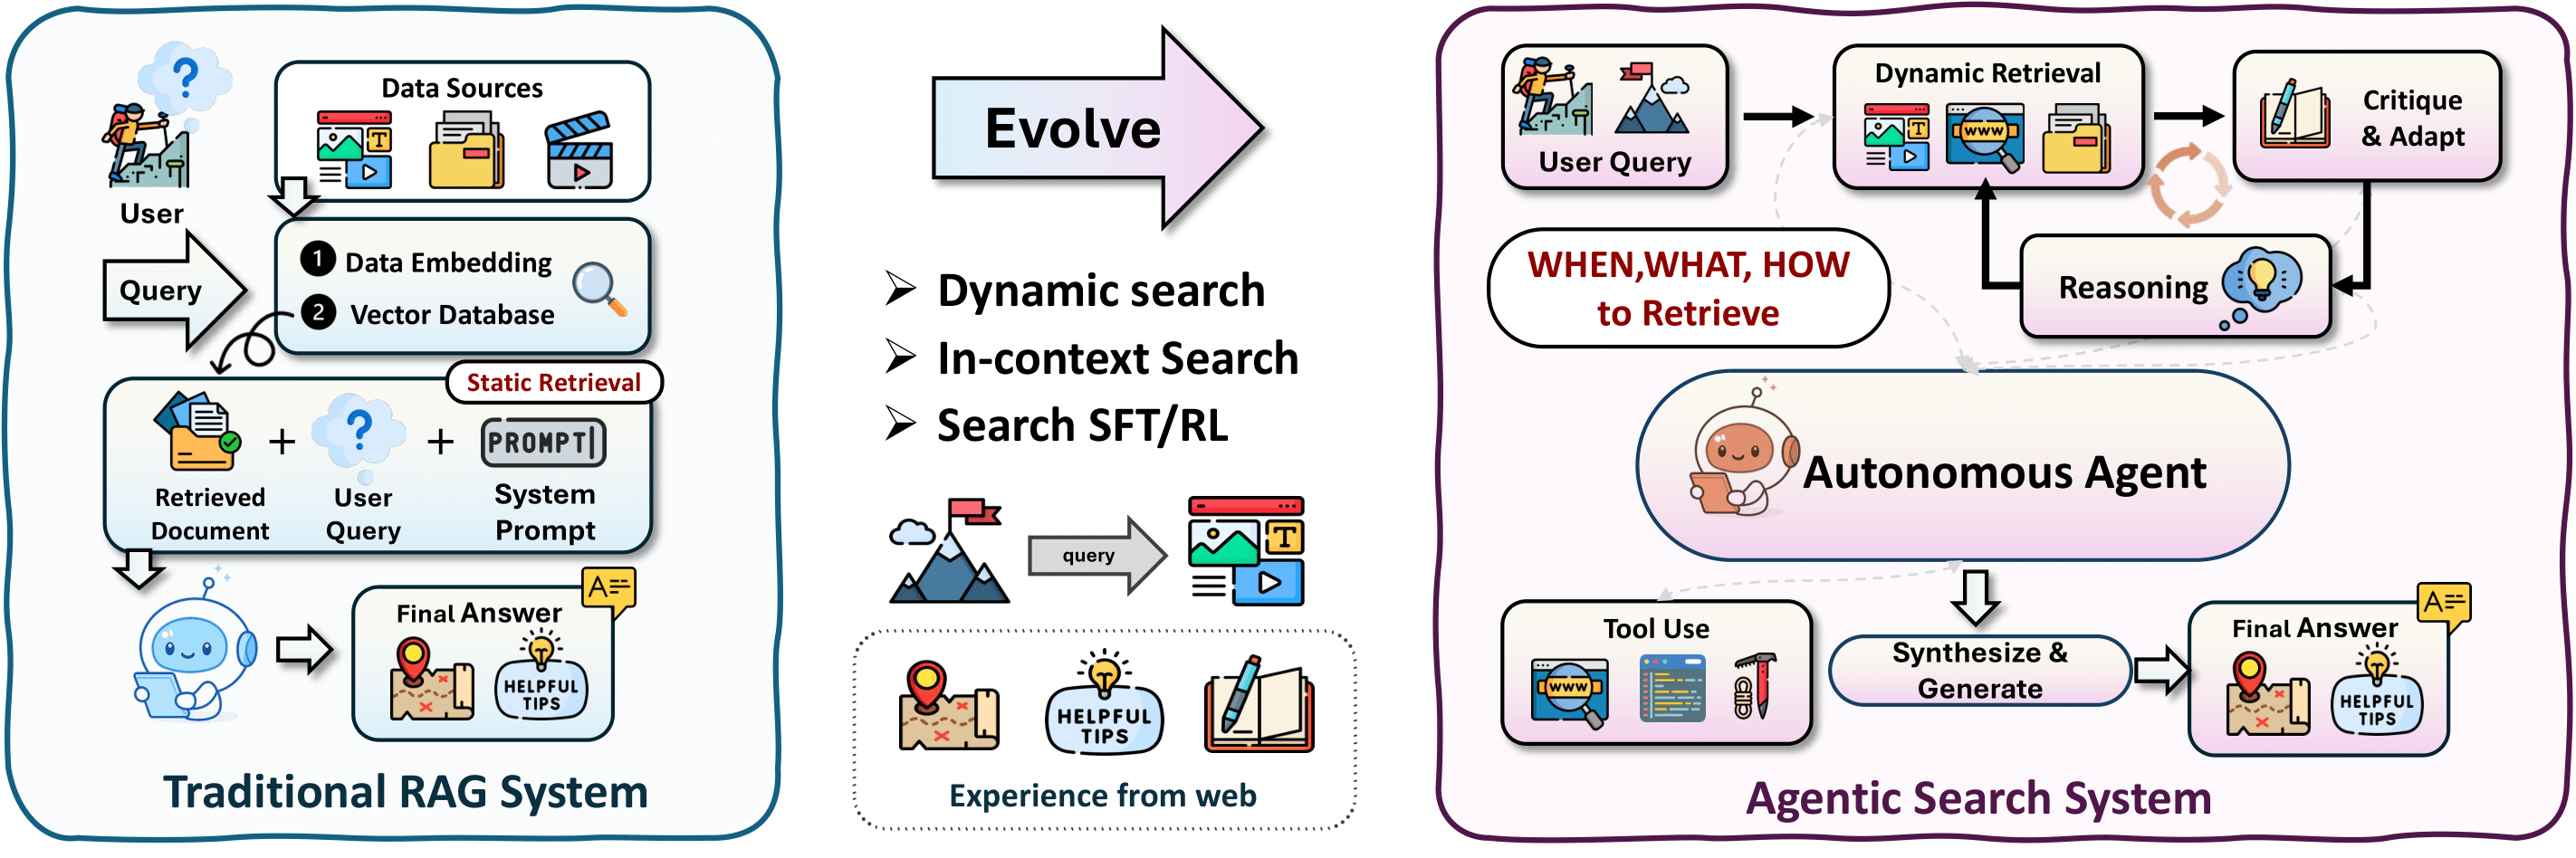
In-Context Search
Interleaving Reasoning and Search
Structure-Enhanced Search
Post-Training Search
SFT-Based Agentic Search
RL-Based Agentic Search
🧬 Self-evolving Agentic Reasoning
🔄 Agentic Feedback Mechanisms
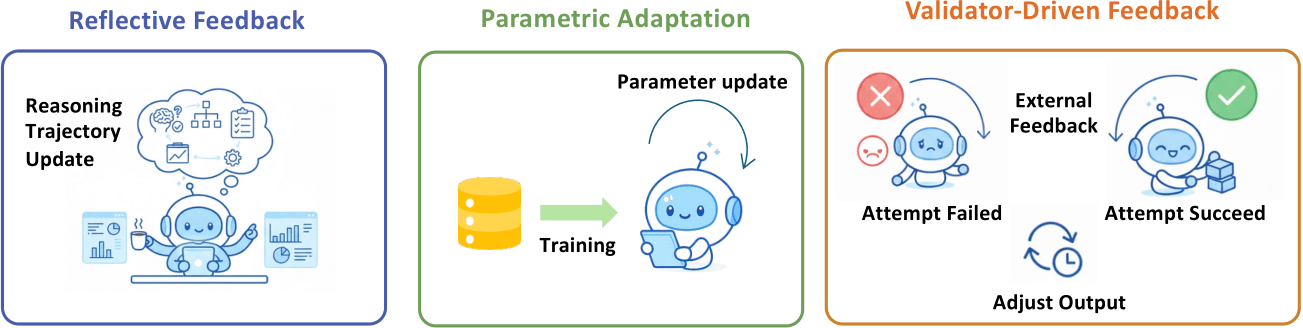
Reflective Feedback
Parametric Adaptation
Validator-Driven Feedback
🧠 Agentic Memory
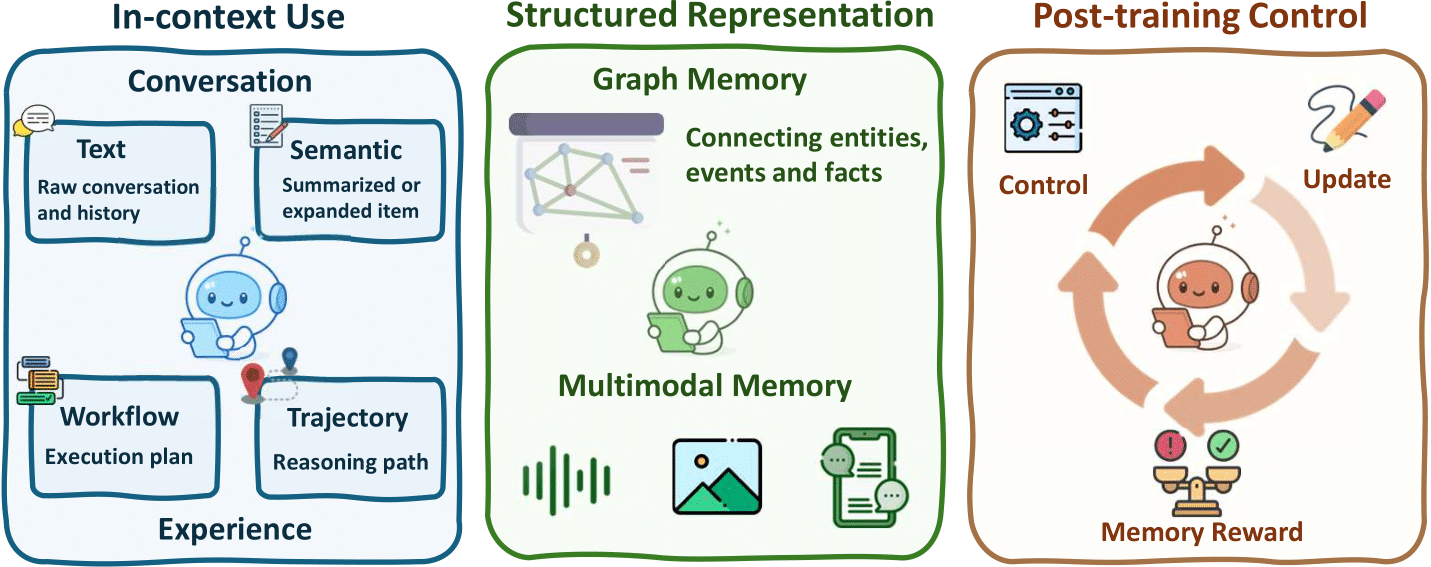
Agentic Use of Flat Memory
Factual Memory
Experience Memory
Structured Use of Memory
Post-training Memory Control
🚀 Evolving Foundational Agentic Capabilities
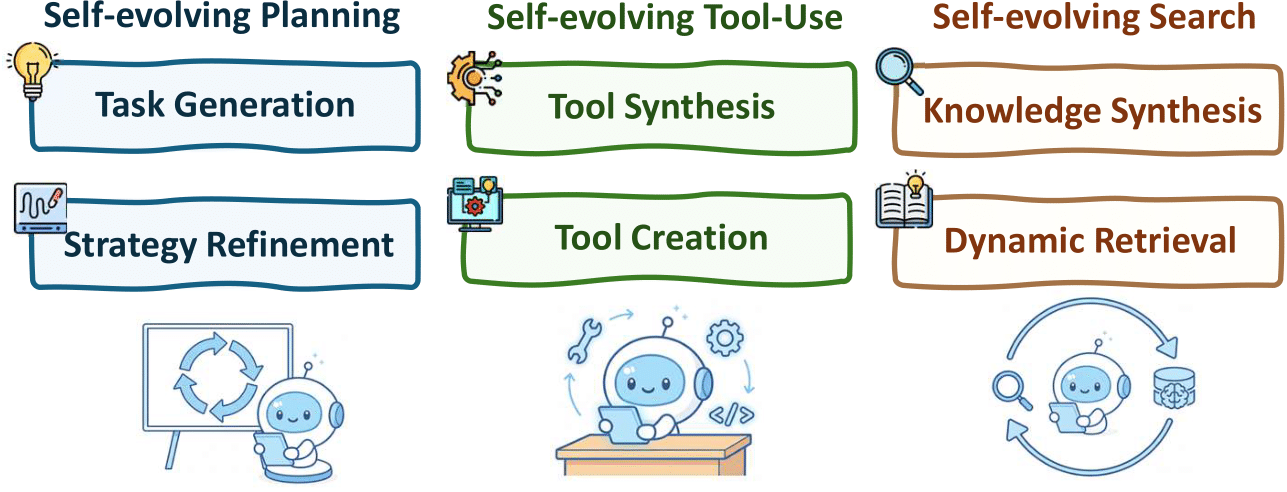
Self-evolving Planning
Self-evolving Tool-use
Self-evolving Search for Memory Retrieval
👥 Collective Multi-agent Reasoning
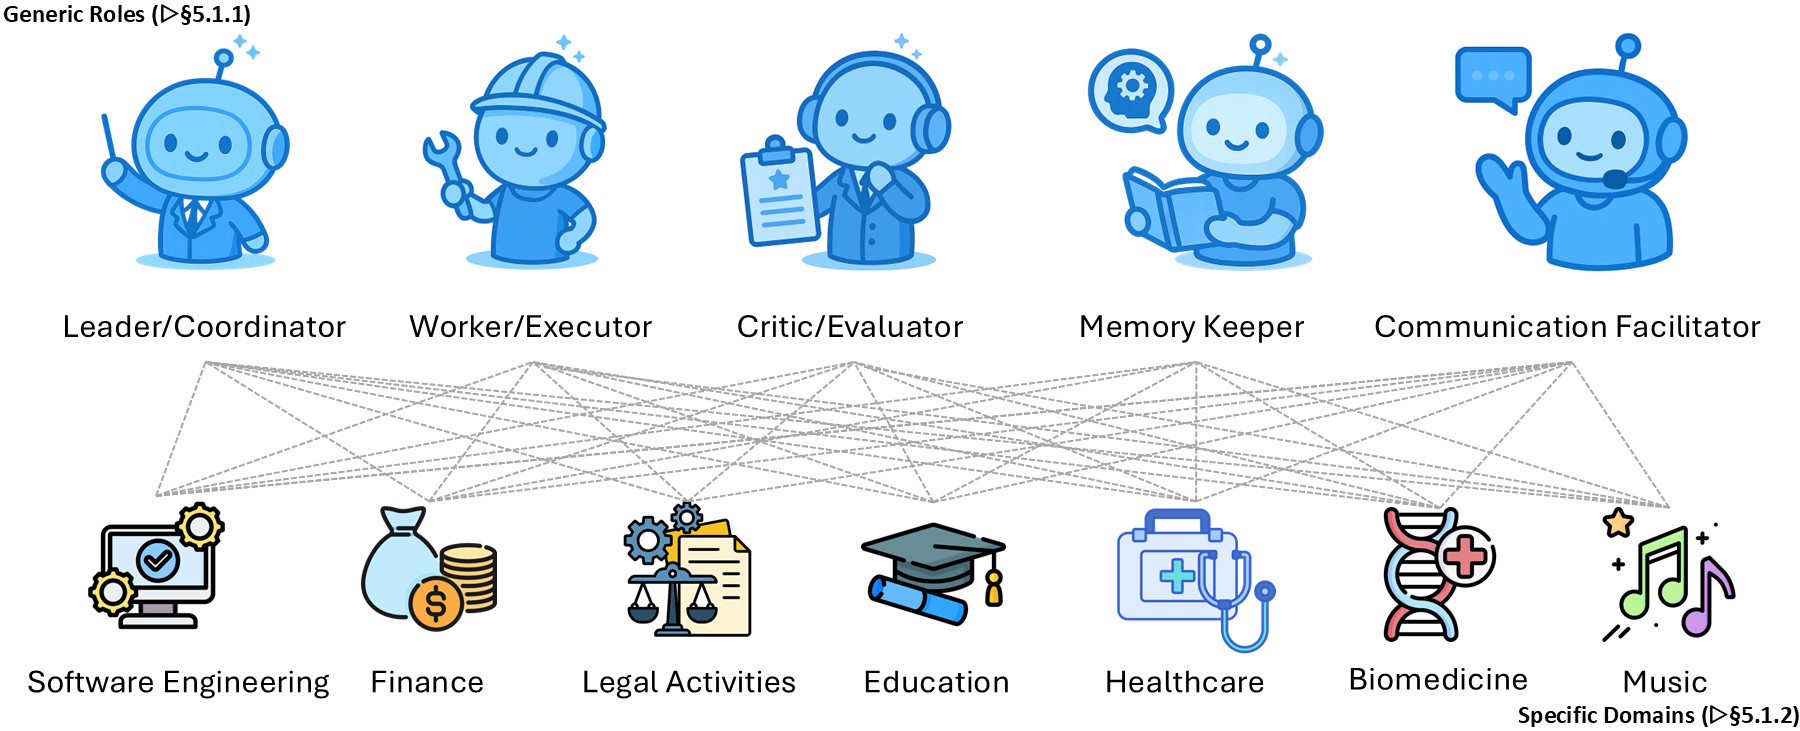
🤝 Collaboration and Division of Labor
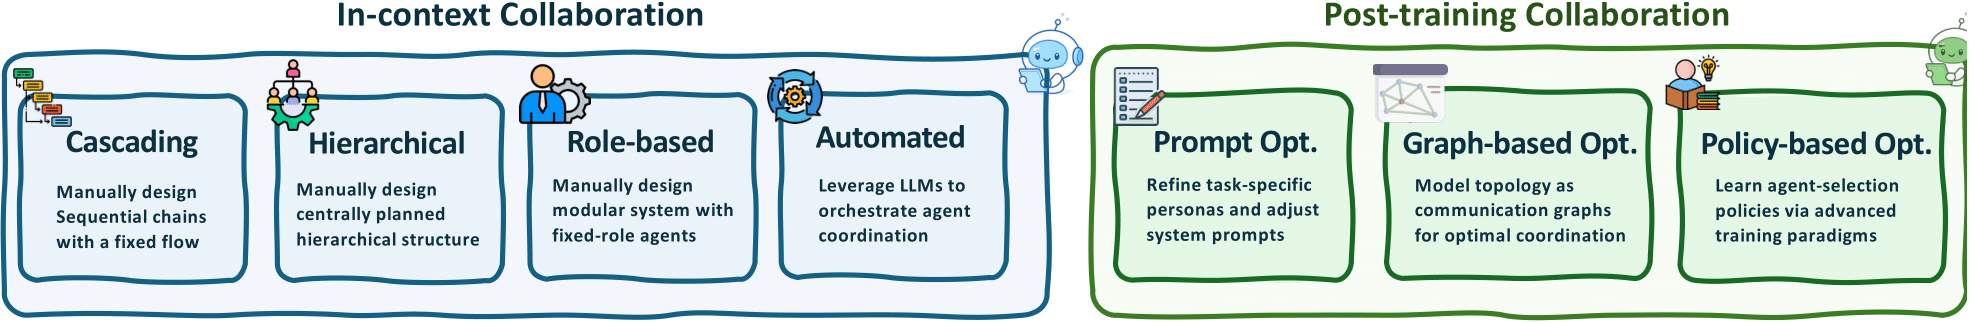
In-context Collaboration
Manually Crafted Pipelines
LLM-Driven Pipelines
Theory-of-Mind-Augmented Collaboration
Post-training Collaboration
Multi-agent Prompt Optimization
Graph-based Topology Generation
Policy-based Topology Generation
🌱 Multi-Agent Memory and Evolution
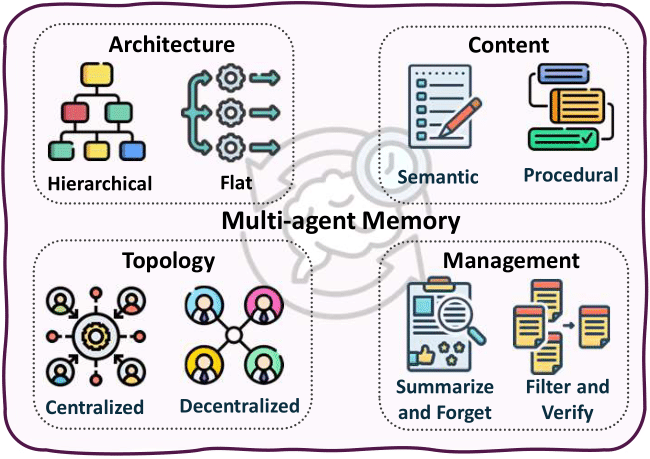
From Single-Agent Evolution to Multi-Agent Evolution
Intra-test-time Evolution
Inter-test-time Evolution
Multi-agent Evolution
Multi-agent Memory Management for Evolution
Training Multi-agent to Evolve
🎨 Applications
💻 Math Exploration & Vibe Coding Agents
Foundational Agentic Reasoning
Self-evolving Agentic Reasoning
Collective Multi-agent Reasoning
🔬 Scientific Discovery Agents
Here are the extracted citation tables grouped by their respective sections.
Foundational Agentic Reasoning
Self-evolving Agentic Reasoning
Collective multi-agent reasoning
🤖 Embodied Agents
Foundational Agentic Reasoning
Self-evolving Agentic Reasoning
Collective multi-agent reasoning
🏥 Healthcare & Medicine Agents
Foundational agentic reasoning
Self-evolving agentic reasoning
Collective multi-agent reasoning
🌐 Autonomous Web Exploration & Research Agents
Foundational agentic reasoning
Self-evolving agentic reasoning
Collective multi-agent reasoning
📊 Benchmarks
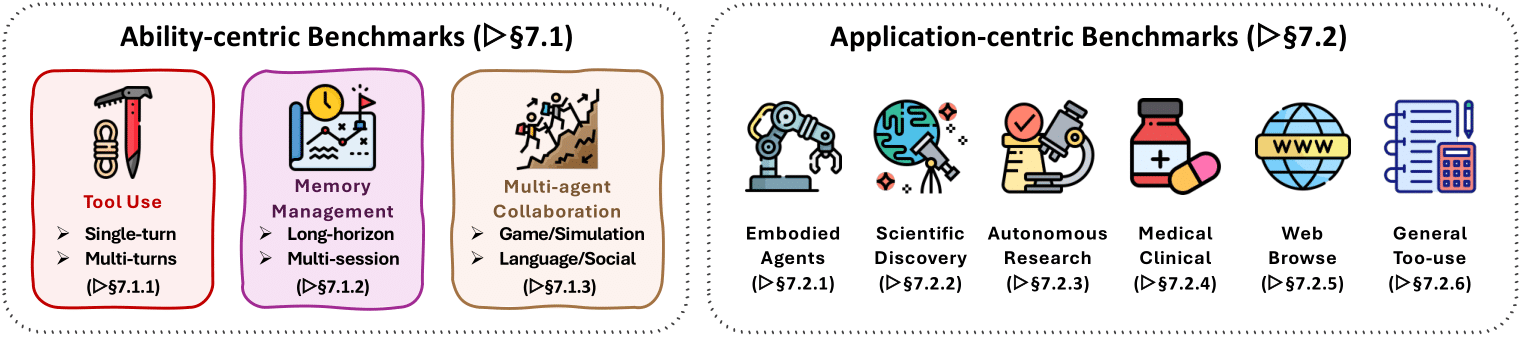
⚙️ Core Mechanisms of Agentic Reasoning
Tool Use
Single-Turn Tool Use
Multi-Turn Tool Use
Search
Memory and Planning
Long-Horizon Episodic Memory
Multi-session Recall
Planning and Feedback
Multi-Agent System
Game-based reinforcement learning evaluation
Simulation-centric real-world assessment
Language, Communication, and Social Reasoning
🎯 Applications of Agentic Reasoning
Embodied Agents
Scientific Discovery Agents
Autonomous Research Agents
Medical and Clinical Agents
Web Agents
General Tool-Use Agents
License
This repository is licensed under the MIT License.
Star History
Contributors


Similar repos


A curated list of papers and resources based on the survey "Agentic Reasoning for Large Language Models"
See the codeREADME
Awesome Agentic Reasoning Papers
This repository organizes research by thematic areas that integrate reasoning with action, including planning, tool use, search, self-evolution and recursive self-improvement (RSI) through memory and feedback, collective intelligence in multi-agent systems, and real-world applications and benchmarks.
📄 Based on the survey: Agentic Reasoning for Large Language Models: A Survey
🔔 News
[09/19/26] 🎉 Our survey, A Survey of Agentic Reasoning for Large Language Models: Towards Recursively Self-Improving and Collective Agents, has been accepted to Transactions on Machine Learning Research (TMLR)!
[03/09/26] 📊 Slides are now available to provide a clearer overview of the survey and highlight key insights. We will continue updating the paper with further improvements.
[01/21/26] 🚀 We have released a comprehensive survey, A Survey of Agentic Reasoning for Large Language Models: Towards Recursively Self-Improving and Collective Agents! The paper is now available on arxiv and HuggingFace. We welcome contributions from the community to help expand and improve our survey 🤗!
📋 Table of Contents
- 🔔 News
- 📋 Table of Contents
- 🌟 Introduction
- 🤝 Contributing
- 📝 Citation
- 🏗️ Foundational Agentic Reasoning
- 🧬 Self-evolving Agentic Reasoning
- 👥 Collective Multi-agent Reasoning
- 🎨 Applications
- 📊 Benchmarks
🌟 Introduction
Bridging thought and action through autonomous agents that reason, act, and learn via continual interaction with their environments. The goal is to enhance agent capabilities by grounding reasoning in action.
We organize agentic reasoning into three layers, each corresponding to a distinct reasoning paradigm under different environmental dynamics:
🔹 Foundational Reasoning. Core single-agent abilities (planning, tool-use, search) in environments
🔹 Self-Evolving Reasoning. Adaptation through feedback, memory, and learning in dynamic settings
🔹 Collective Reasoning. Multi-agent coordination, role specialization, and collaborative intelligence
Across these layers, we further identify complementary reasoning paradigms defined by their optimization settings.
🔸 In-Context Reasoning. Test-time scaling through structured orchestration and adaptive workflows
🔸 Post-Training Reasoning. Behavior optimization via RL and supervised fine-tuning
🤝 Contributing
This collection is an ongoing effort. We are actively expanding and refining its coverage, and welcome contributions from the community. You can:
- Submit a pull request to add papers or resources
- Open an issue to suggest additional papers or resources
- Email us at twei10@illinois.edu, twli@illinois.edu, liu326@illinois.edu
We regularly update the repository to include new research works on agentic reasoning.
📝 Citation
If you find this repository or paper useful, please consider citing the survey paper:
@article{wei2026agentic,
  title={Agentic Reasoning for Large Language Models},
  author={Wei, Tianxin and Li, Ting-Wei and Liu, Zhining and Ning, Xuying and Yang, Ze and Zou, Jiaru and Zeng, Zhichen and Qiu, Ruizhong and Lin, Xiao and Fu, Dongqi and others},
  journal={arXiv preprint arXiv:2601.12538},
  year={2026}
}
🏗️ Foundational Agentic Reasoning
🗺️ Planning Reasoning
In-context Planning
Workflow Design
Tree Search / Algorithm Simulation
Process Formalization
Decoupling / Decomposition
External Aid / Tool Use
Post-training Planning
🛠️ Tool-Use Optimization
In-Context Tool-Integration
Interleaving Reasoning and Tool Use
Optimizing Context for Tool Interaction
Post-training Tool-Integration
Bootstrapping of Tool Use via SFT
Mastery of Tool Use via RL
Orchestration-based Tool-Integration
Agentic Pipelines for Tool Orchestration
Tool Representations for Orchestration
Practical Tools and Infrastructure
| Resource | Year |
|---|---|
| Agentic Reasoning Protocol (reasoning.json) [code] | 2026 |
| OpenClaw Monitor | 2025 |
🔍 Agentic Search
In-Context Search
Interleaving Reasoning and Search
Structure-Enhanced Search
Post-Training Search
SFT-Based Agentic Search
RL-Based Agentic Search
🧬 Self-evolving Agentic Reasoning
🔄 Agentic Feedback Mechanisms
Reflective Feedback
Parametric Adaptation
Validator-Driven Feedback
🧠 Agentic Memory
Agentic Use of Flat Memory
Factual Memory
Experience Memory
Structured Use of Memory
Post-training Memory Control
🚀 Evolving Foundational Agentic Capabilities
Self-evolving Planning
Self-evolving Tool-use
Self-evolving Search for Memory Retrieval
👥 Collective Multi-agent Reasoning
🤝 Collaboration and Division of Labor
In-context Collaboration
Manually Crafted Pipelines
LLM-Driven Pipelines
Theory-of-Mind-Augmented Collaboration
Post-training Collaboration
Multi-agent Prompt Optimization
Graph-based Topology Generation
Policy-based Topology Generation
🌱 Multi-Agent Memory and Evolution
From Single-Agent Evolution to Multi-Agent Evolution
Intra-test-time Evolution
Inter-test-time Evolution
Multi-agent Evolution
Multi-agent Memory Management for Evolution
Training Multi-agent to Evolve
🎨 Applications
💻 Math Exploration & Vibe Coding Agents
Foundational Agentic Reasoning
Self-evolving Agentic Reasoning
Collective Multi-agent Reasoning
🔬 Scientific Discovery Agents
Here are the extracted citation tables grouped by their respective sections.
Foundational Agentic Reasoning
Self-evolving Agentic Reasoning
Collective multi-agent reasoning
🤖 Embodied Agents
Foundational Agentic Reasoning
Self-evolving Agentic Reasoning
Collective multi-agent reasoning
🏥 Healthcare & Medicine Agents
Foundational agentic reasoning
Self-evolving agentic reasoning
Collective multi-agent reasoning
🌐 Autonomous Web Exploration & Research Agents
Foundational agentic reasoning
Self-evolving agentic reasoning
Collective multi-agent reasoning
📊 Benchmarks
⚙️ Core Mechanisms of Agentic Reasoning
Tool Use
Single-Turn Tool Use
Multi-Turn Tool Use
Search
Memory and Planning
Long-Horizon Episodic Memory
Multi-session Recall
Planning and Feedback
Multi-Agent System
Game-based reinforcement learning evaluation
Simulation-centric real-world assessment
Language, Communication, and Social Reasoning
🎯 Applications of Agentic Reasoning
Embodied Agents
Scientific Discovery Agents
Autonomous Research Agents
Medical and Clinical Agents
Web Agents
General Tool-Use Agents
License
This repository is licensed under the MIT License.