World Action Model, VLA failure detection/correction, Efficient VLA
Python
21
143 commits
updated Oct 19, 2026
Vision-Language-Action · World Action Models · Agentic Robotics
A curated, quality-gated reading list for embodied intelligence.

Explore the papers · Start with surveys · Contribute
|
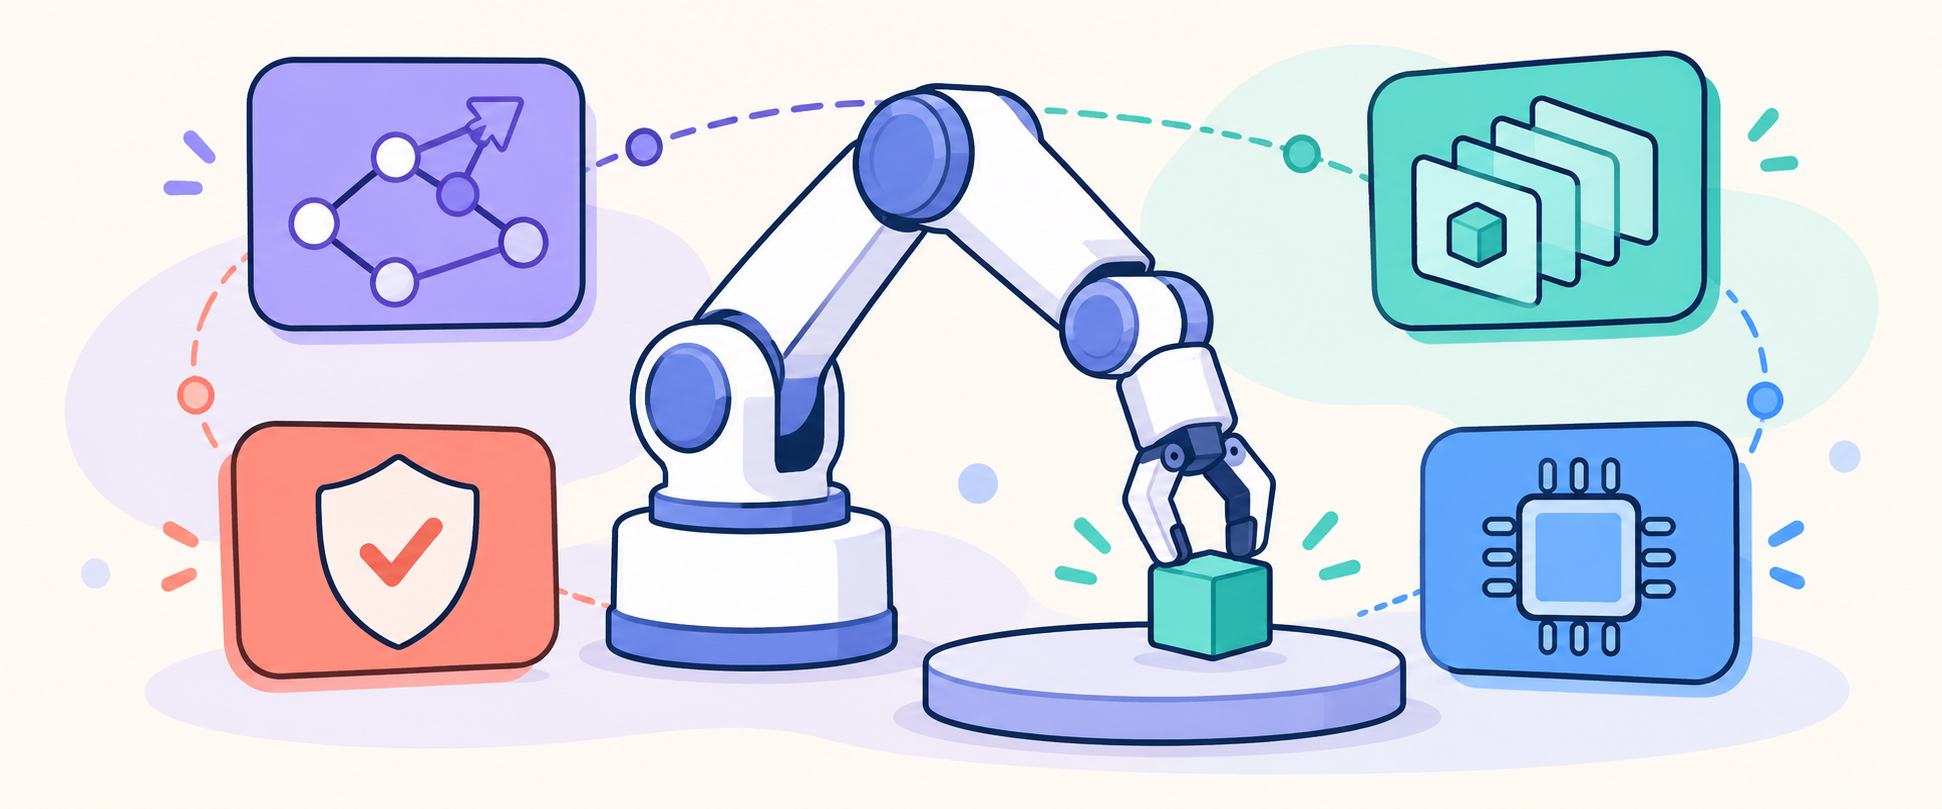
01 · Agentic RoboticsLong-horizon embodied agents, planning, memory, tools, and skill orchestration. |
02 · World Action ModelsVideo foresight, vision-language models, and predictive latent dynamics. |
|
03 · Failure Detection & CorrectionFeedback, verification, recovery, and online adaptation for reliable VLA systems. |
04 · Efficient VLACompression, adaptation, action tokenization, and efficient deployment. |
Reference shelf · Surveys & Definitions · Benchmarks & Evaluation
Reading guide · Core lists keep the 10 newest qualifying papers; linked archives retain the longer history. Reference sections may be shorter.
Relevance · ⭐⭐⭐ direct fit · ⭐⭐ adjacent/supporting · ⭐ background/context.
Core lists: Every primary paper table or subsection in this README keeps exactly the 10 newest qualifying papers, ordered by available arXiv date or identifier. The linked archive documents retain the longer historical lists.
Reference lists: Surveys and Definitions, and Benchmarks for Robustness and Evaluation, are compact reference sections and may contain fewer than 10 entries when fewer items are retained.
Relevance: ⭐⭐⭐ direct fit · ⭐⭐ adjacent/supporting · ⭐ background/context.
The agentic robotics section requires an explicit embodied-agent layer that coordinates multi-step physical execution through high-level planning, memory, tool or skill discovery and composition, VLA/VLM or policy orchestration, recovery, or online policy self-improvement. Pure navigation or VLN policies without another agentic robotics capability are out of scope. Standalone prompt optimization, generic exploration, or low-level VLA improvements without this agent-level role are also out of scope. The failure detection/correction section is not a one-to-one heading in the source repository; it groups papers that are closely related through environment feedback, self-improvement, verification, closed-loop learning, preference alignment, online planning, or robustness evaluation.
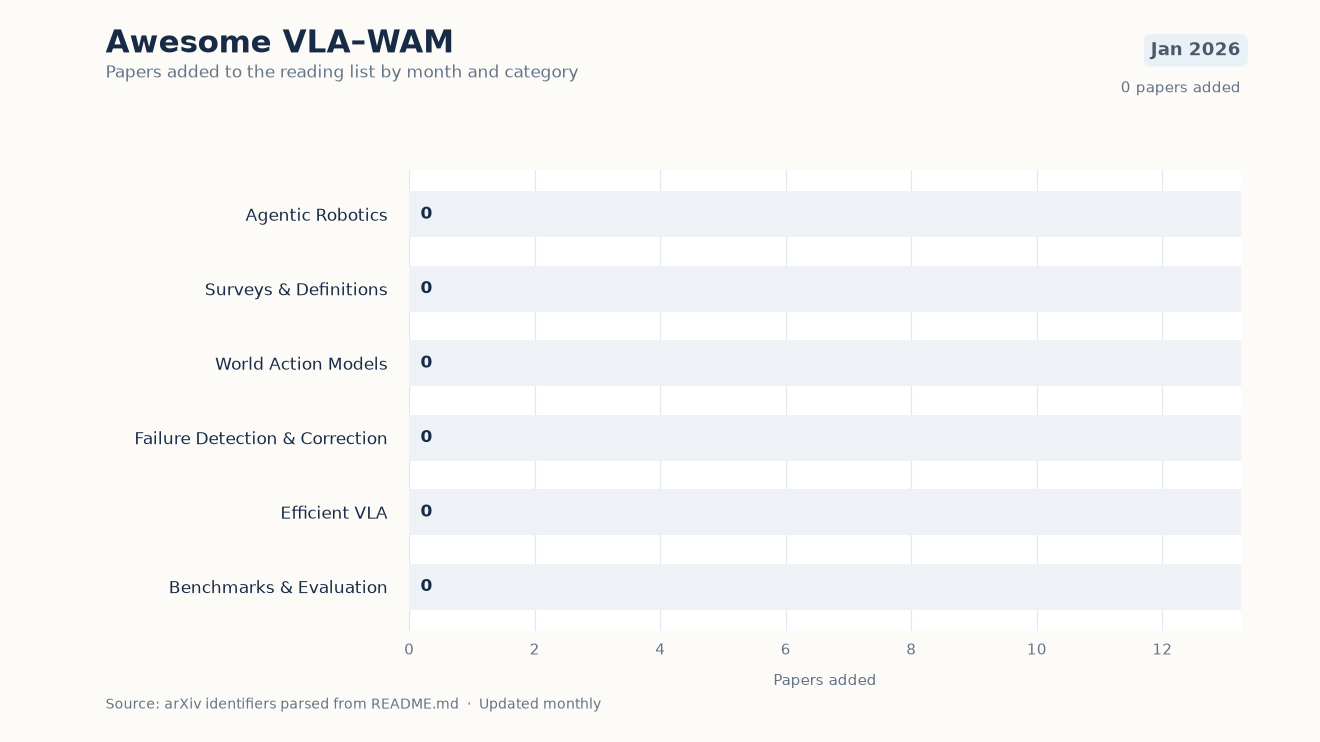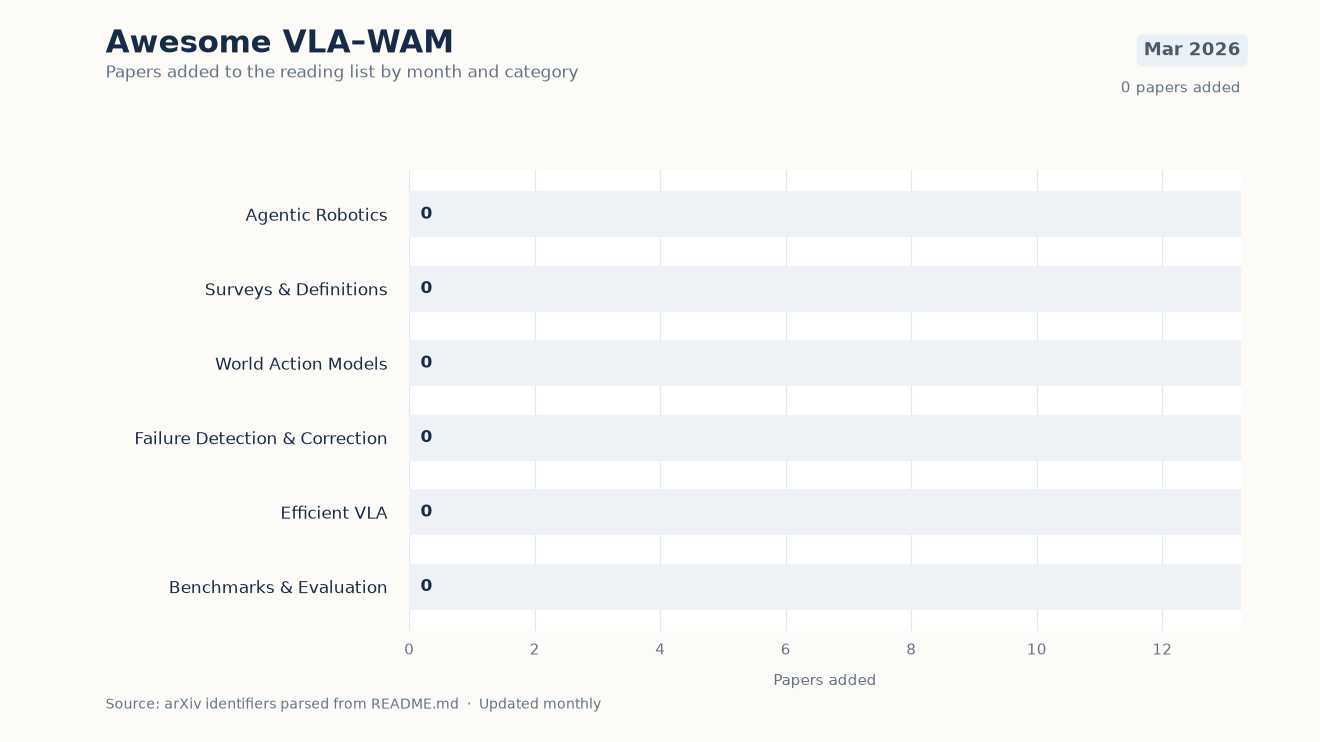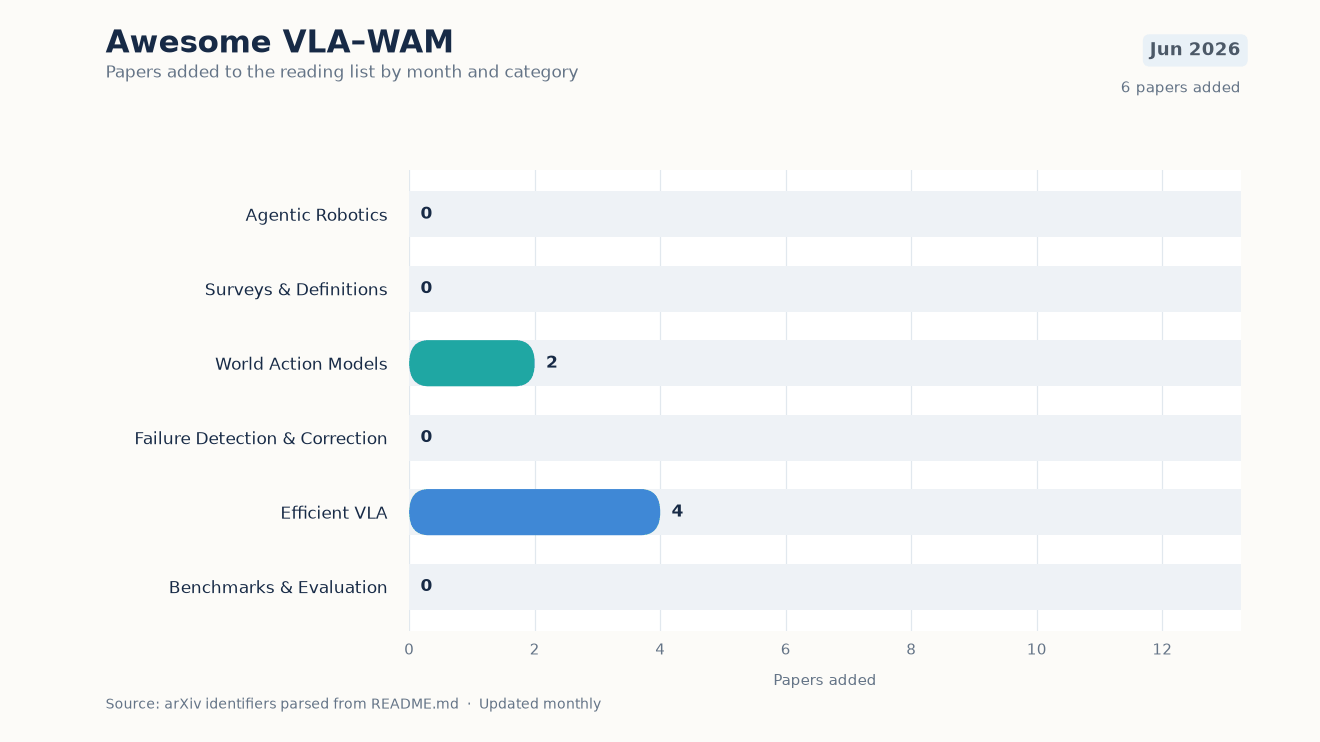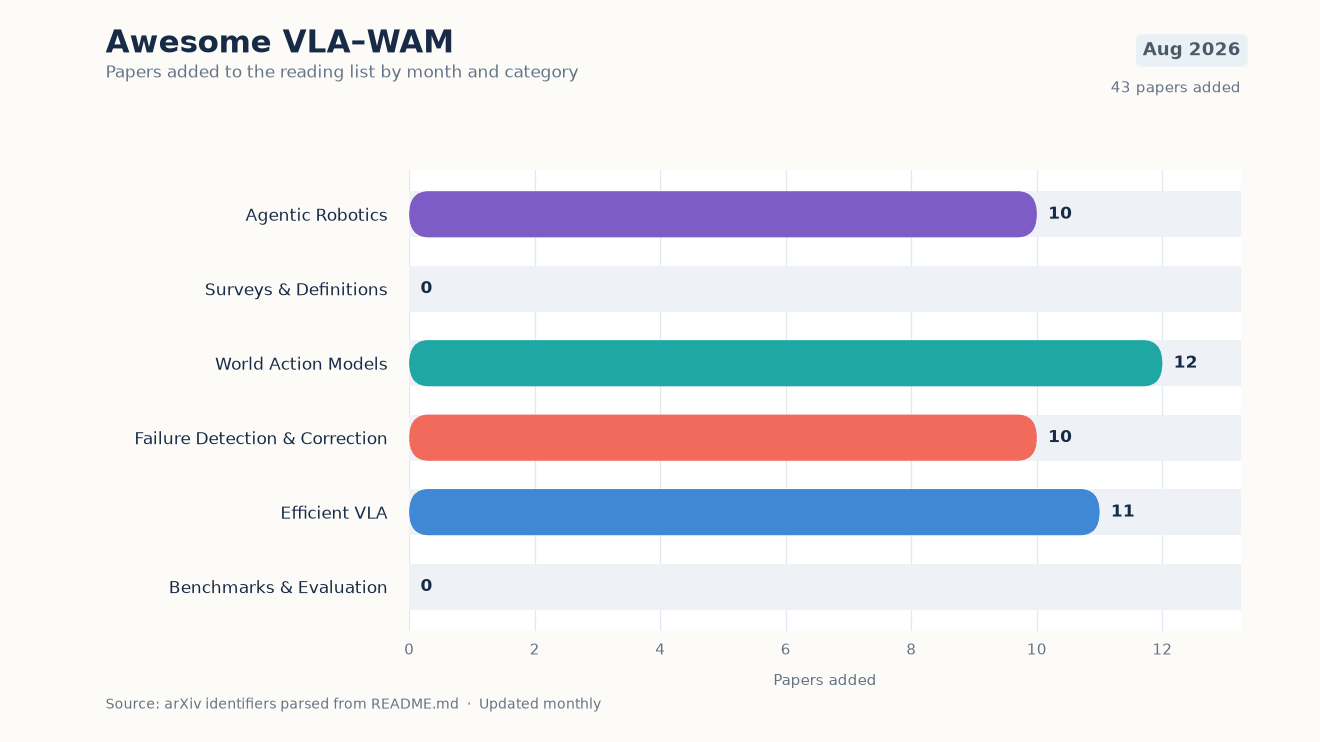
The animation tracks papers added since January 2026. It is regenerated from
the arXiv identifiers in this README with
scripts/generate_monthly_paper_chart.py.
This emerging line treats robot foundation models as components inside a broader embodied-agent loop. Papers belong here only when the agent layer is central to coordinating physical multi-step execution through planning, memory, tool or skill composition, policy orchestration, recovery, or online self-improvement; pure navigation-only or VLN policies are out of scope.
| Paper | Title | Links | Relevance |
|---|---|---|---|
| LAW | LAW: Unifying Language, Action, and World Modeling for Agentic Physical Intelligence. | arXiv | ⭐⭐⭐ |
| Value as Memory | Value as Memory: Online Value-Guided Post-training for General Robot Policies. | arXiv | ⭐⭐⭐ |
| AdaRSI | AdaRSI: On-Demand Recursive Self-Improvement for Embodied Agents. | arXiv | ⭐⭐⭐ |
| BT-Agent | BT-Agent: Deploying Onboard Robot Agents with Behavior Trees and Multi-Fidelity Evaluation. | arXiv | ⭐⭐⭐ |
| SpatialHarness | SpatialHarness: Test-Time Spatial Scaffolding for Fine Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
| SuperNav | SuperNav: An Agentic Navigation System for Any Task in Any Scene. | arXiv · Project | ⭐⭐⭐ |
| Agentic RSR | Agentic RSR: Real-to-Sim-to-Real through Scene Reconstruction and Execution-Grounded Robot Policies. | arXiv | ⭐⭐⭐ |
| OntoPlan | OntoPlan: An Ontology-Grounded Scene Representation and Agentic Framework for Scalable Robot Task Planning. | arXiv | ⭐⭐⭐ |
| RV-ICL | Recursive Video In-Context Learning for Agentic Robot. | arXiv | ⭐⭐⭐ |
| MobiAgent | MobiAgent: Dual-Loop Recursive Policy Self-Improvement for Long-Horizon Mobile Manipulation. | arXiv · Project | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| Embodied Brains Roadmap | From World Action Models to Embodied Brains: A Roadmap for Open-World Physical Intelligence. | arXiv | ⭐⭐⭐ |
| VLA Review: UAV and Bimanual | Vision Language Action (VLA) Models for Unmanned Aerial Robotics and Bimanual Manipulation: A Review. | arXiv | ⭐⭐⭐ |
| World Action Models Tutorial | From World Models to World Action Models: A Concise Tutorial for Robotics. | arXiv · Website · Code | ⭐⭐⭐ |
| World Model for Robot Learning | World Model for Robot Learning: A Comprehensive Survey. | arXiv · Website · Code | ⭐⭐⭐ |
| Embodied Agentic AI | Towards Embodied Agentic AI: Review and Classification of LLM- and VLM-Driven Robot Autonomy and Interaction. | arXiv | ⭐⭐⭐ |
Jump to: Robustness & Security · Video Generation · VLM-Based · Efficient Inference · Latent Dynamics
| Paper | Title | Links | Relevance |
|---|---|---|---|
| TAPDreamer | TAPDreamer: Transferable Adversarial Patches for World Action Models. | arXiv · Project | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| Rolling-WAM | Rolling-WAM: World Action Models with Rolling Imagination. | arXiv · Project | ⭐⭐⭐ |
| CLAP | CLAP: Cross-Embodiment Video World Models are Zero-Shot Physical Simulators. | arXiv · Project | ⭐⭐⭐ |
| TacPAC | TacPAC: Tactile Prediction and Real-Time Action Correction in World-Action Models for Contact-Rich Manipulation. | arXiv · Code | ⭐⭐⭐ |
| SV-WAM | SV-WAM: An Efficient Surround-View World-Action Model for End-to-End Autonomous Driving. | arXiv | ⭐⭐⭐ |
| SA-WAM | Spatially Aware World Action Model via Geometric Latent Diffusion. | arXiv | ⭐⭐⭐ |
| IMPACT | IMPACT: Attention Is the Interaction Map for Scalable Interaction-Aware World Model Training. | arXiv | ⭐⭐⭐ |
| AcrossVAM1.0 | AcrossVAM1.0: Particle World Modeling for Text-Assisted Robot Video Prediction. | arXiv | ⭐⭐⭐ |
| Zero-WAM | Zero-WAM: In-Context World-Action Modeling from Human Videos for Open-Ended Task Generalization. | arXiv · Project | ⭐⭐⭐ |
| WorldSync | Do Robotic World Models Really Follow Actions? Diagnosing and Aligning Action-Conditioned Generation for Policy Learning. | arXiv | ⭐⭐⭐ |
| Surgical WAM | Surgical WAM: A World-Action Model for Data-Efficient Surgical Robot Learning. | arXiv | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| ForeTime-VLA | ForeTime-VLA: Causal Future-Token Distillation from a World Action Model for Conveyor-Belt Manipulation. | arXiv | ⭐⭐⭐ |
| HyWorldVLA | HyWorldVLA: A Vision-Language-Action Model with Hybrid World Modeling for Autonomous Driving. | arXiv | ⭐⭐⭐ |
| DSWAM | DSWAM: A Dual-System World Action Foundation Model for Fine-Grained Robot Manipulation. | arXiv | ⭐⭐⭐ |
| FutureNav | FutureNav: Unified World-Action Modeling for Vision-and-Language Navigation. | arXiv | ⭐⭐⭐ |
| WLA | World-Language-Action Model for Unified World Modeling, Language Reasoning, and Action Synthesis. | arXiv · Website | ⭐⭐⭐ |
| CKT-WAM | CKT-WAM: Parameter-Efficient Context Knowledge Transfer Between World Action Models. | arXiv · Website | ⭐⭐ |
| World-Value-Action Model | World-Value-Action Model: Implicit Planning for Vision-Language-Action Systems. | arXiv | ⭐⭐⭐ |
| WoG | World Guidance World Modeling in Condition Space for Action Generation. | arXiv · Website | ⭐⭐ |
| VLAW | VLAW: Iterative Co-Improvement of Vision-Language-Action Policy and World Model. | arXiv · Website | ⭐⭐⭐ |
| VLA-JEPA | VLA-JEPA: Enhancing Vision-Language-Action Model with Latent World Model. | arXiv · Website | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| CF-Prune | Complementary Future Token Pruning for World Action Models. | arXiv | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| AWAM | AWAM: Active Trajectory-Conditioned View Imagination for Robust Robot Manipulation. | arXiv | ⭐⭐⭐ |
| P³-WAM | Perceive, Predict, and Plan: a Unified World Action Model for Egocentric Dexterous Manipulation. | arXiv · Project | ⭐⭐⭐ |
| SmolWAM | SmolWAM: A Latent World-Action Model for Robotic Manipulation on Edge Devices. | arXiv · Project · Code | ⭐⭐⭐ |
| DreamTrue | DreamTrue: Action-Faithful Robot World Model with Counterfactual Post-Training. | arXiv · Project | ⭐⭐⭐ |
| LeWAM | LeWAM: A JEPA World Action Model with Diffusion-Steering-Based MPC. | arXiv | ⭐⭐⭐ |
| PLaW-VLA | PLaW-VLA: Predictive Latent World Modeling for Vision-Language-Action Policies. | arXiv | ⭐⭐⭐ |
| OpenWAM | OpenWAM: An Open Framework for Composable World-Action Models. | arXiv · Project · Code | ⭐⭐⭐ |
| XGenAct | XGenAct: Geometry-Enhanced World Action Models through Cross-Task Generation. | arXiv | ⭐⭐⭐ |
| Ego4WAM | Ego4WAM: What Matters When Scaling Egocentric Human Data for Robot Learning? | arXiv | ⭐⭐⭐ |
| MVG-WAM | MVG-WAM: Multiple View Geometry-Aware World-Action Modeling for Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
These papers are useful entry points for failure-aware VLA systems, especially when the method uses feedback, online adaptation, closed-loop correction, self-evaluation, or policy/world-model co-improvement.
| Paper | Title | Links | Relevance |
|---|---|---|---|
| Look Before You Act | Look Before You Act: Bridging Active Perception and Vision-Language-Action Models via Observation-Aligned Data Adaptation. | arXiv | ⭐⭐⭐ |
| VeriVLA | VeriVLA: Adaptive Test-Time Verification for Flow-Based VLAs with Latent World Models. | arXiv | ⭐⭐⭐ |
| SafeDriveVLA | SafeDriveVLA: Navigation-Conditioned World Model Dreaming for Conflict-Aware End-to-End Autonomous Driving. | arXiv · Project | ⭐⭐⭐ |
| RARA | RARA: Robust Policy Fine-Tuning through Retrieval-Anchored Representation Alignment for Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
| Reflect-VLA | Reflect-VLA: Internalizing Reflective Guidance via Dual-Path On-Policy Self-Distillation for Autonomous Driving. | arXiv | ⭐⭐⭐ |
| OGPO | OGPO: Offline Goal-conditioned Policy Optimization for Recoverable Vision-Language-Action Models. | arXiv | ⭐⭐⭐ |
| VersaCamVLA | VersaCamVLA: Camera-Configurable VLA Policies for Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
| RESETTLE | RESETTLE: Robotic Recovery through Disagreement-Triggered Retrieval and Efficient Corrective Control. | arXiv · Code | ⭐⭐⭐ |
| RoboPrompt | RoboPrompt: Intuitive Robot Policy Steering with Sparse Human Input. | arXiv | ⭐⭐⭐ |
| SALT | Adapting Vision-Language-Action Models to Unknown Visual Disruptions During Execution. | arXiv | ⭐⭐⭐ |
Jump to: Compression & Adaptation · Tokenization & Deployment
| Paper | Title | Links | Relevance |
|---|---|---|---|
| MambaAct | MambaAct: Efficient Mamba Action Experts for Flow-Matching Vision-Language-Action Models. | arXiv · Code | ⭐⭐⭐ |
| REKI | REKI: Registering Knowledge in VLAs. | arXiv · Code | ⭐⭐⭐ |
| NSL | Noise Space Learning for VLA Adaptation. | arXiv | ⭐⭐⭐ |
| ActTune | ActTune: Action-Aware Precision and GPU Operating-Point Adaptation for Energy-Efficient Vision-Language-Action Inference. | arXiv | ⭐⭐⭐ |
| VLA-ZO | VLA-ZO: Fast Zeroth-Order Adaptation for Vision-Language-Action Models. | arXiv | ⭐⭐⭐ |
| Rho | Rho: A Foundation for Efficiently Adaptable VLA Models. | arXiv | ⭐⭐⭐ |
| FRAM | FRAM: Trajectory-Guided Visual Feature Selection for Compact Language-Conditioned Robot Manipulation. | arXiv | ⭐⭐⭐ |
| ε4P | Imperfection for Precision: Upcycling Imperfect Data for High-Precision Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
| AdaDE | Dense to MoE Adaptation for Compact Vision Language Action Policies. | arXiv | ⭐⭐⭐ |
| Beyond Data Scaling | Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models. | arXiv · Project | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| Discrete Actions | When Do Discrete Actions Make Good Continuous Controllers? | arXiv · Project | ⭐⭐⭐ |
| PLaW-VLA | PLaW-VLA: Predictive Latent World Modeling for Vision-Language-Action Policies. | arXiv | ⭐⭐⭐ |
| FastOPD | FastOPD: On-Policy Distillation for Lightweight VLA Deployment. | arXiv · Project | ⭐⭐⭐ |
| Discrete Forcing | Discrete Forcing: Infusing Discrete Guidance into Continuous Denoising for Few-Step Action Experts. | arXiv | ⭐⭐⭐ |
| Decoupled Early Exits | Decoupled Early Exits for Task-Dependent Compute Allocation in Flow-Matching VLAs. | arXiv | ⭐⭐⭐ |
| Think Like a World Model | Think Like a World Model, Act Like a VLA: Distilling World-Model Representations into Compact Robot Policies. | arXiv · Project | ⭐⭐⭐ |
| Coda | Fewer Steps, Better Actions: Rethinking Flow-Matching Inference for VLA Policies. | arXiv | ⭐⭐⭐ |
| GeoAAC | GeoAAC: Geometry-Based Adaptive Action Chunking from Denoising Trajectories in VLA Policies. | arXiv | ⭐⭐⭐ |
| rMuscle | rMuscle: Robotic Muscle Memory for Efficient Vision-Language-Action Model Inference. | arXiv | ⭐⭐⭐ |
| DiffAdapterVLA | Planning in the Backbone: DiffAdapterVLA for Native Continuous Trajectory Generation with Driving VLMs. | arXiv | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| WorldArena | WorldArena: A Unified Benchmark for Evaluating Perception and Functional Utility of Embodied World Models. | arXiv · Website | ⭐⭐ |
| LIBERO-Plus | LIBERO-Plus: In-depth Robustness Analysis of Vision-Language-Action Models. | arXiv · Website | ⭐⭐⭐ |
| RoboArena | RoboArena: Distributed Real-World Evaluation of Generalist Robot Policies. | arXiv · Website | ⭐ |
| RoboTwin 2.0 | RoboTwin 2.0: A Scalable Data Generator and Benchmark with Strong Domain Randomization for Robust Bimanual Robotic Manipulation. | arXiv · Website | ⭐⭐ |
| SimplerEnv | Evaluating Real-World Robot Manipulation Policies in Simulation. | arXiv · Website | ⭐ |
| LIBERO | LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning. | arXiv · Website | ⭐ |
Pull requests are welcome. A good entry should include:
For every curated update, keep the primary Codex author and add
Co-authored-by: wangskyone <[email protected]> to the
commit message.
Initial paper entries were reorganized from DravenALG/awesome-vla-wam.
Awesome VLA–WAM
A curated reading list for embodied intelligence.
Back to top ↑ · Explore the papers
World Action Model, VLA failure detection/correction, Efficient VLA
Python
21
143 commits
updated Oct 19, 2026
Vision-Language-Action · World Action Models · Agentic Robotics
A curated, quality-gated reading list for embodied intelligence.
Explore the papers · Start with surveys · Contribute
|
01 · Agentic RoboticsLong-horizon embodied agents, planning, memory, tools, and skill orchestration. |
02 · World Action ModelsVideo foresight, vision-language models, and predictive latent dynamics. |
|
03 · Failure Detection & CorrectionFeedback, verification, recovery, and online adaptation for reliable VLA systems. |
04 · Efficient VLACompression, adaptation, action tokenization, and efficient deployment. |
Reference shelf · Surveys & Definitions · Benchmarks & Evaluation
Reading guide · Core lists keep the 10 newest qualifying papers; linked archives retain the longer history. Reference sections may be shorter.
Relevance · ⭐⭐⭐ direct fit · ⭐⭐ adjacent/supporting · ⭐ background/context.
Core lists: Every primary paper table or subsection in this README keeps exactly the 10 newest qualifying papers, ordered by available arXiv date or identifier. The linked archive documents retain the longer historical lists.
Reference lists: Surveys and Definitions, and Benchmarks for Robustness and Evaluation, are compact reference sections and may contain fewer than 10 entries when fewer items are retained.
Relevance: ⭐⭐⭐ direct fit · ⭐⭐ adjacent/supporting · ⭐ background/context.
The agentic robotics section requires an explicit embodied-agent layer that coordinates multi-step physical execution through high-level planning, memory, tool or skill discovery and composition, VLA/VLM or policy orchestration, recovery, or online policy self-improvement. Pure navigation or VLN policies without another agentic robotics capability are out of scope. Standalone prompt optimization, generic exploration, or low-level VLA improvements without this agent-level role are also out of scope. The failure detection/correction section is not a one-to-one heading in the source repository; it groups papers that are closely related through environment feedback, self-improvement, verification, closed-loop learning, preference alignment, online planning, or robustness evaluation.
The animation tracks papers added since January 2026. It is regenerated from
the arXiv identifiers in this README with
scripts/generate_monthly_paper_chart.py.
This emerging line treats robot foundation models as components inside a broader embodied-agent loop. Papers belong here only when the agent layer is central to coordinating physical multi-step execution through planning, memory, tool or skill composition, policy orchestration, recovery, or online self-improvement; pure navigation-only or VLN policies are out of scope.
| Paper | Title | Links | Relevance |
|---|---|---|---|
| LAW | LAW: Unifying Language, Action, and World Modeling for Agentic Physical Intelligence. | arXiv | ⭐⭐⭐ |
| Value as Memory | Value as Memory: Online Value-Guided Post-training for General Robot Policies. | arXiv | ⭐⭐⭐ |
| AdaRSI | AdaRSI: On-Demand Recursive Self-Improvement for Embodied Agents. | arXiv | ⭐⭐⭐ |
| BT-Agent | BT-Agent: Deploying Onboard Robot Agents with Behavior Trees and Multi-Fidelity Evaluation. | arXiv | ⭐⭐⭐ |
| SpatialHarness | SpatialHarness: Test-Time Spatial Scaffolding for Fine Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
| SuperNav | SuperNav: An Agentic Navigation System for Any Task in Any Scene. | arXiv · Project | ⭐⭐⭐ |
| Agentic RSR | Agentic RSR: Real-to-Sim-to-Real through Scene Reconstruction and Execution-Grounded Robot Policies. | arXiv | ⭐⭐⭐ |
| OntoPlan | OntoPlan: An Ontology-Grounded Scene Representation and Agentic Framework for Scalable Robot Task Planning. | arXiv | ⭐⭐⭐ |
| RV-ICL | Recursive Video In-Context Learning for Agentic Robot. | arXiv | ⭐⭐⭐ |
| MobiAgent | MobiAgent: Dual-Loop Recursive Policy Self-Improvement for Long-Horizon Mobile Manipulation. | arXiv · Project | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| Embodied Brains Roadmap | From World Action Models to Embodied Brains: A Roadmap for Open-World Physical Intelligence. | arXiv | ⭐⭐⭐ |
| VLA Review: UAV and Bimanual | Vision Language Action (VLA) Models for Unmanned Aerial Robotics and Bimanual Manipulation: A Review. | arXiv | ⭐⭐⭐ |
| World Action Models Tutorial | From World Models to World Action Models: A Concise Tutorial for Robotics. | arXiv · Website · Code | ⭐⭐⭐ |
| World Model for Robot Learning | World Model for Robot Learning: A Comprehensive Survey. | arXiv · Website · Code | ⭐⭐⭐ |
| Embodied Agentic AI | Towards Embodied Agentic AI: Review and Classification of LLM- and VLM-Driven Robot Autonomy and Interaction. | arXiv | ⭐⭐⭐ |
Jump to: Robustness & Security · Video Generation · VLM-Based · Efficient Inference · Latent Dynamics
| Paper | Title | Links | Relevance |
|---|---|---|---|
| TAPDreamer | TAPDreamer: Transferable Adversarial Patches for World Action Models. | arXiv · Project | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| Rolling-WAM | Rolling-WAM: World Action Models with Rolling Imagination. | arXiv · Project | ⭐⭐⭐ |
| CLAP | CLAP: Cross-Embodiment Video World Models are Zero-Shot Physical Simulators. | arXiv · Project | ⭐⭐⭐ |
| TacPAC | TacPAC: Tactile Prediction and Real-Time Action Correction in World-Action Models for Contact-Rich Manipulation. | arXiv · Code | ⭐⭐⭐ |
| SV-WAM | SV-WAM: An Efficient Surround-View World-Action Model for End-to-End Autonomous Driving. | arXiv | ⭐⭐⭐ |
| SA-WAM | Spatially Aware World Action Model via Geometric Latent Diffusion. | arXiv | ⭐⭐⭐ |
| IMPACT | IMPACT: Attention Is the Interaction Map for Scalable Interaction-Aware World Model Training. | arXiv | ⭐⭐⭐ |
| AcrossVAM1.0 | AcrossVAM1.0: Particle World Modeling for Text-Assisted Robot Video Prediction. | arXiv | ⭐⭐⭐ |
| Zero-WAM | Zero-WAM: In-Context World-Action Modeling from Human Videos for Open-Ended Task Generalization. | arXiv · Project | ⭐⭐⭐ |
| WorldSync | Do Robotic World Models Really Follow Actions? Diagnosing and Aligning Action-Conditioned Generation for Policy Learning. | arXiv | ⭐⭐⭐ |
| Surgical WAM | Surgical WAM: A World-Action Model for Data-Efficient Surgical Robot Learning. | arXiv | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| ForeTime-VLA | ForeTime-VLA: Causal Future-Token Distillation from a World Action Model for Conveyor-Belt Manipulation. | arXiv | ⭐⭐⭐ |
| HyWorldVLA | HyWorldVLA: A Vision-Language-Action Model with Hybrid World Modeling for Autonomous Driving. | arXiv | ⭐⭐⭐ |
| DSWAM | DSWAM: A Dual-System World Action Foundation Model for Fine-Grained Robot Manipulation. | arXiv | ⭐⭐⭐ |
| FutureNav | FutureNav: Unified World-Action Modeling for Vision-and-Language Navigation. | arXiv | ⭐⭐⭐ |
| WLA | World-Language-Action Model for Unified World Modeling, Language Reasoning, and Action Synthesis. | arXiv · Website | ⭐⭐⭐ |
| CKT-WAM | CKT-WAM: Parameter-Efficient Context Knowledge Transfer Between World Action Models. | arXiv · Website | ⭐⭐ |
| World-Value-Action Model | World-Value-Action Model: Implicit Planning for Vision-Language-Action Systems. | arXiv | ⭐⭐⭐ |
| WoG | World Guidance World Modeling in Condition Space for Action Generation. | arXiv · Website | ⭐⭐ |
| VLAW | VLAW: Iterative Co-Improvement of Vision-Language-Action Policy and World Model. | arXiv · Website | ⭐⭐⭐ |
| VLA-JEPA | VLA-JEPA: Enhancing Vision-Language-Action Model with Latent World Model. | arXiv · Website | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| CF-Prune | Complementary Future Token Pruning for World Action Models. | arXiv | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| AWAM | AWAM: Active Trajectory-Conditioned View Imagination for Robust Robot Manipulation. | arXiv | ⭐⭐⭐ |
| P³-WAM | Perceive, Predict, and Plan: a Unified World Action Model for Egocentric Dexterous Manipulation. | arXiv · Project | ⭐⭐⭐ |
| SmolWAM | SmolWAM: A Latent World-Action Model for Robotic Manipulation on Edge Devices. | arXiv · Project · Code | ⭐⭐⭐ |
| DreamTrue | DreamTrue: Action-Faithful Robot World Model with Counterfactual Post-Training. | arXiv · Project | ⭐⭐⭐ |
| LeWAM | LeWAM: A JEPA World Action Model with Diffusion-Steering-Based MPC. | arXiv | ⭐⭐⭐ |
| PLaW-VLA | PLaW-VLA: Predictive Latent World Modeling for Vision-Language-Action Policies. | arXiv | ⭐⭐⭐ |
| OpenWAM | OpenWAM: An Open Framework for Composable World-Action Models. | arXiv · Project · Code | ⭐⭐⭐ |
| XGenAct | XGenAct: Geometry-Enhanced World Action Models through Cross-Task Generation. | arXiv | ⭐⭐⭐ |
| Ego4WAM | Ego4WAM: What Matters When Scaling Egocentric Human Data for Robot Learning? | arXiv | ⭐⭐⭐ |
| MVG-WAM | MVG-WAM: Multiple View Geometry-Aware World-Action Modeling for Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
These papers are useful entry points for failure-aware VLA systems, especially when the method uses feedback, online adaptation, closed-loop correction, self-evaluation, or policy/world-model co-improvement.
| Paper | Title | Links | Relevance |
|---|---|---|---|
| Look Before You Act | Look Before You Act: Bridging Active Perception and Vision-Language-Action Models via Observation-Aligned Data Adaptation. | arXiv | ⭐⭐⭐ |
| VeriVLA | VeriVLA: Adaptive Test-Time Verification for Flow-Based VLAs with Latent World Models. | arXiv | ⭐⭐⭐ |
| SafeDriveVLA | SafeDriveVLA: Navigation-Conditioned World Model Dreaming for Conflict-Aware End-to-End Autonomous Driving. | arXiv · Project | ⭐⭐⭐ |
| RARA | RARA: Robust Policy Fine-Tuning through Retrieval-Anchored Representation Alignment for Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
| Reflect-VLA | Reflect-VLA: Internalizing Reflective Guidance via Dual-Path On-Policy Self-Distillation for Autonomous Driving. | arXiv | ⭐⭐⭐ |
| OGPO | OGPO: Offline Goal-conditioned Policy Optimization for Recoverable Vision-Language-Action Models. | arXiv | ⭐⭐⭐ |
| VersaCamVLA | VersaCamVLA: Camera-Configurable VLA Policies for Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
| RESETTLE | RESETTLE: Robotic Recovery through Disagreement-Triggered Retrieval and Efficient Corrective Control. | arXiv · Code | ⭐⭐⭐ |
| RoboPrompt | RoboPrompt: Intuitive Robot Policy Steering with Sparse Human Input. | arXiv | ⭐⭐⭐ |
| SALT | Adapting Vision-Language-Action Models to Unknown Visual Disruptions During Execution. | arXiv | ⭐⭐⭐ |
Jump to: Compression & Adaptation · Tokenization & Deployment
| Paper | Title | Links | Relevance |
|---|---|---|---|
| MambaAct | MambaAct: Efficient Mamba Action Experts for Flow-Matching Vision-Language-Action Models. | arXiv · Code | ⭐⭐⭐ |
| REKI | REKI: Registering Knowledge in VLAs. | arXiv · Code | ⭐⭐⭐ |
| NSL | Noise Space Learning for VLA Adaptation. | arXiv | ⭐⭐⭐ |
| ActTune | ActTune: Action-Aware Precision and GPU Operating-Point Adaptation for Energy-Efficient Vision-Language-Action Inference. | arXiv | ⭐⭐⭐ |
| VLA-ZO | VLA-ZO: Fast Zeroth-Order Adaptation for Vision-Language-Action Models. | arXiv | ⭐⭐⭐ |
| Rho | Rho: A Foundation for Efficiently Adaptable VLA Models. | arXiv | ⭐⭐⭐ |
| FRAM | FRAM: Trajectory-Guided Visual Feature Selection for Compact Language-Conditioned Robot Manipulation. | arXiv | ⭐⭐⭐ |
| ε4P | Imperfection for Precision: Upcycling Imperfect Data for High-Precision Robotic Manipulation. | arXiv · Project | ⭐⭐⭐ |
| AdaDE | Dense to MoE Adaptation for Compact Vision Language Action Policies. | arXiv | ⭐⭐⭐ |
| Beyond Data Scaling | Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models. | arXiv · Project | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| Discrete Actions | When Do Discrete Actions Make Good Continuous Controllers? | arXiv · Project | ⭐⭐⭐ |
| PLaW-VLA | PLaW-VLA: Predictive Latent World Modeling for Vision-Language-Action Policies. | arXiv | ⭐⭐⭐ |
| FastOPD | FastOPD: On-Policy Distillation for Lightweight VLA Deployment. | arXiv · Project | ⭐⭐⭐ |
| Discrete Forcing | Discrete Forcing: Infusing Discrete Guidance into Continuous Denoising for Few-Step Action Experts. | arXiv | ⭐⭐⭐ |
| Decoupled Early Exits | Decoupled Early Exits for Task-Dependent Compute Allocation in Flow-Matching VLAs. | arXiv | ⭐⭐⭐ |
| Think Like a World Model | Think Like a World Model, Act Like a VLA: Distilling World-Model Representations into Compact Robot Policies. | arXiv · Project | ⭐⭐⭐ |
| Coda | Fewer Steps, Better Actions: Rethinking Flow-Matching Inference for VLA Policies. | arXiv | ⭐⭐⭐ |
| GeoAAC | GeoAAC: Geometry-Based Adaptive Action Chunking from Denoising Trajectories in VLA Policies. | arXiv | ⭐⭐⭐ |
| rMuscle | rMuscle: Robotic Muscle Memory for Efficient Vision-Language-Action Model Inference. | arXiv | ⭐⭐⭐ |
| DiffAdapterVLA | Planning in the Backbone: DiffAdapterVLA for Native Continuous Trajectory Generation with Driving VLMs. | arXiv | ⭐⭐⭐ |
| Paper | Title | Links | Relevance |
|---|---|---|---|
| WorldArena | WorldArena: A Unified Benchmark for Evaluating Perception and Functional Utility of Embodied World Models. | arXiv · Website | ⭐⭐ |
| LIBERO-Plus | LIBERO-Plus: In-depth Robustness Analysis of Vision-Language-Action Models. | arXiv · Website | ⭐⭐⭐ |
| RoboArena | RoboArena: Distributed Real-World Evaluation of Generalist Robot Policies. | arXiv · Website | ⭐ |
| RoboTwin 2.0 | RoboTwin 2.0: A Scalable Data Generator and Benchmark with Strong Domain Randomization for Robust Bimanual Robotic Manipulation. | arXiv · Website | ⭐⭐ |
| SimplerEnv | Evaluating Real-World Robot Manipulation Policies in Simulation. | arXiv · Website | ⭐ |
| LIBERO | LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning. | arXiv · Website | ⭐ |
Pull requests are welcome. A good entry should include:
For every curated update, keep the primary Codex author and add
Co-authored-by: wangskyone <[email protected]> to the
commit message.
Initial paper entries were reorganized from DravenALG/awesome-vla-wam.
Awesome VLA–WAM
A curated reading list for embodied intelligence.
Back to top ↑ · Explore the papers