🚀 Agent RAG haute performance fonctionnant 100% en local sur CPU.
Python
0
33 commits
updated Dec 13, 2025
pip install -r requirements.txtpython src/retrieval/reranker_installer.pypython models/llm/llm_model_installer.pystreamlit run app.pypython clear_cache.pypython monitoring/verify_paths.py
Agent RAG (Retrieval-Augmented Generation) haute performance fonctionnant 100% en local sur CPU.


VEV RAG est un système de recherche documentaire intelligent qui combine :
Le projet fonctionne entièrement en local, sans dépendance cloud, garantissant confidentialité et autonomie.
graph TB
    A[Documents PDF/DOCX/TXT/Web] --> B[Ingestion & Nettoyage]
    B --> C[Chunking Sémantique]
    C --> D[Embeddings BGE-M3]
    D --> E[LanceDB Vectorielle]
    F[Question Utilisateur] --> G[Query Expansion HyDE]
    G --> H[Recherche Hybride]
    E --> H
    H --> I[Reranking MXBai]
    I --> J[LLM Qwen3-4B]
    J --> K[Réponse Générée]
    L[GPTCache] -.-> H
# Cloner le dépôt
git clone https://github.com/user257814938/VEV_RAG.git
cd VEV_RAG

# Créer un environnement virtuel
python -m venv venv
source venv/bin/activate  # Sur Windows: venv\Scripts\activate

# Installer les dépendances
pip install -r requirements.txt

# Télécharger les modèles
python src/scripts/download_reranker.py
Créez un fichier .env à la racine (optionnel) :
# Chemins personnalisés (optionnel)
DATA_DIR=./data
MODELS_DIR=./models
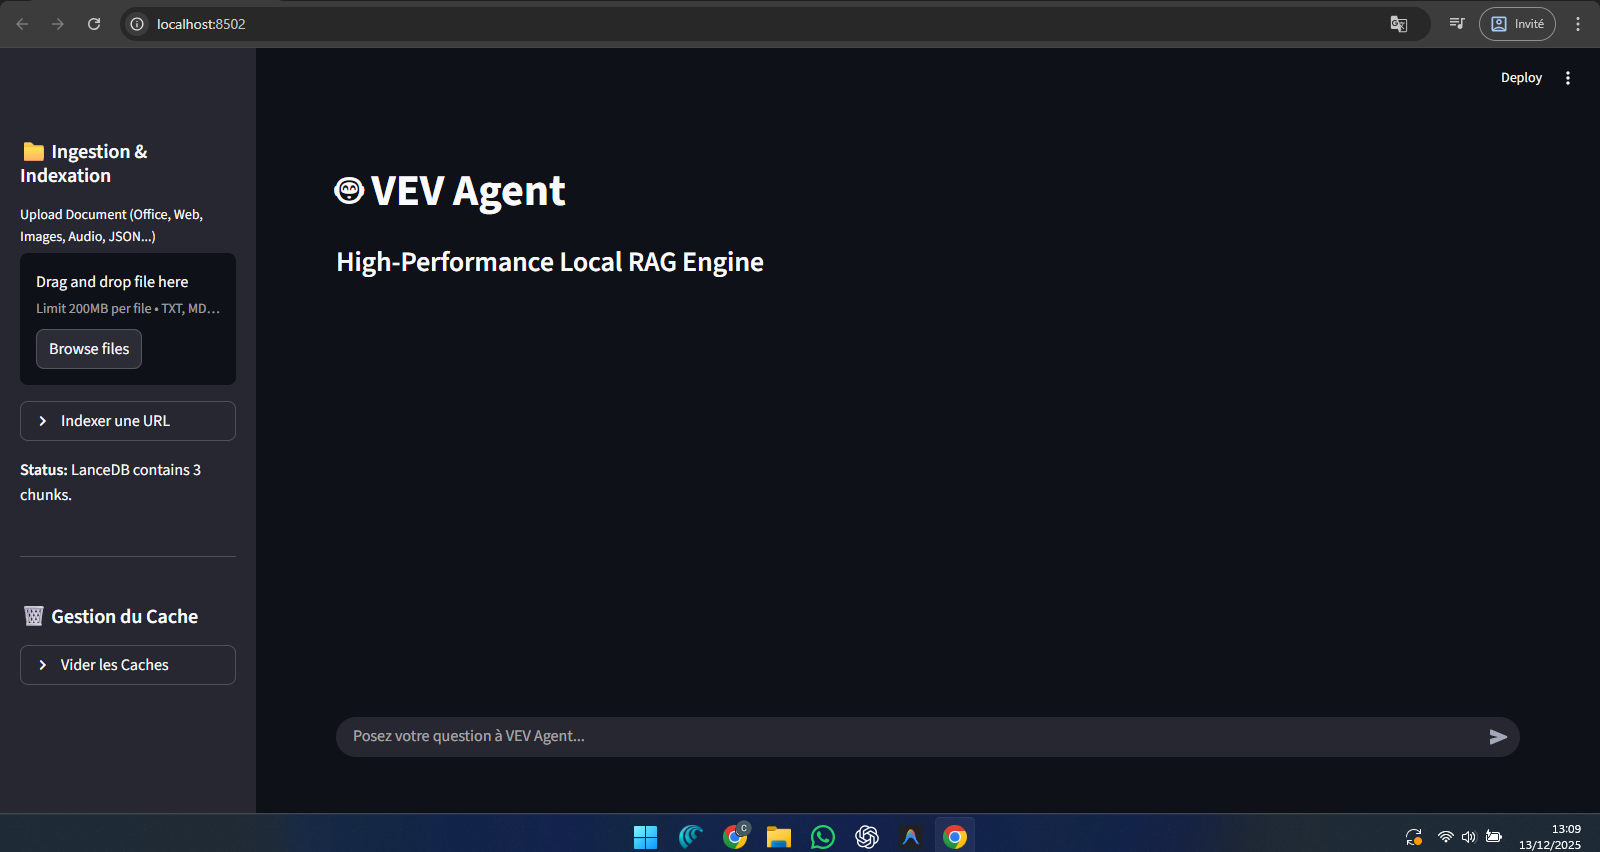
streamlit run app.py
Ouvrez votre navigateur à http://localhost:8501
from main import VEVRAGAgent

# Initialiser l'agent
agent = VEVRAGAgent()

# Ingérer des documents
agent.ingest_documents(["document.pdf", "article.docx"])

# Poser une question
response = agent.query("Quelle est la définition de l'IA ?")
print(response)
# Lancer les tests
pytest tests/

# Test d'ingestion
python tests/test_ingestion.py

# Test de recherche
python tests/test_retrieval.py
VEV_RAG/
├── 📄 app.py                    # Interface Streamlit
├── 📄 main.py                   # Orchestration principale (VEVRAGAgent)
├── 📄 requirements.txt          # Dépendances Python
├── 📂 src/
│   ├── 📂 core/
│   │   ├── config.py           # Configuration & variables d'environnement
│   │   └── schemas.py          # Structures de données (Pydantic)
│   ├── 📂 ingestion/
│   │   ├── loader_doc.py       # Chargement PDF/DOCX (Docling)
│   │   ├── loader_web.py       # Extraction web (Trafilatura)
│   │   └── cleaner.py          # Nettoyage texte (ftfy, Spacy)
│   ├── 📂 indexing/
│   │   ├── chunker.py          # Chunking sémantique
│   │   ├── embedder.py         # Embeddings (FastEmbed + BGE-M3)
│   │   └── vector_store.py     # Base vectorielle (LanceDB)
│   ├── 📂 retrieval/
│   │   ├── cache.py            # Cache sémantique (GPTCache)
│   │   ├── query_expansion.py  # Amélioration requêtes (HyDE)
│   │   └── reranker.py         # Reranking (MXBai)
│   ├── 📂 generation/
│   │   ├── llm_engine.py       # Moteur LLM (Qwen3-4B GGUF)
│   │   └── system_prompts.py   # Prompts système
│   ├── 📂 evaluation/
│   │   └── ragas_eval.py       # Évaluation qualité (RAGAS)
│   └── 📂 scripts/
│       ├── download_reranker.py # Téléchargement modèles
│       └── verify_paths.py      # Vérification structure
├── 📂 data/
│   ├── raw/                    # Documents bruts
│   ├── processed/              # Documents traités
│   └── lancedb/                # Base vectorielle
├── 📂 models/
│   ├── llm/                    # Modèles LLM (GGUF)
│   └── embeddings/             # Modèles embeddings
└── 📂 tests/
    ├── test_ingestion.py       # Tests ingestion
    └── test_retrieval.py       # Tests recherche
| Catégorie | Format | Extension | Moteur | Statut |
|---|---|---|---|---|
| Documents Office | .pdf | Docling (v2) | ✅ Supporté (avec OCR & Tableaux) | |
| Microsoft Word | .docx | Docling (v2) | ✅ Supporté | |
| Microsoft Excel | .xlsx | Docling (v2) | ✅ Supporté (Conversion Markdown) | |
| Microsoft PowerPoint | .pptx | Docling (v2) | ✅ Supporté | |
| Texte & Web | Texte Brut | .txt | Python Natif | ✅ Supporté (Ultra-rapide) |
| Markdown | .md | Python Natif | ✅ Supporté (Ultra-rapide) | |
| HTML / XHTML | .html, .htm | Docling (v2) | ✅ Supporté | |
| XML / AsciiDoc | .xml, .adoc | Docling (v2) | ✅ Supporté | |
| WebVTT | .vtt | Docling (v2) | ✅ Supporté (Sous-titres) | |
| Images (OCR) | Images | .png, .jpg, .tiff, .bmp, .webp | Docling (OCR) | ✅ Supporté |
| Audio (IA) | Audio | .mp3, .wav | Whisper Turbo | ✅ Supporté (Transcription) |
| Spécialisé | JATS/USPTO XML | .xml | Docling (v2) | ✅ Supporté |
| Docling JSON | .json | Docling (v2) | ✅ Supporté |
| Composant | Technologie | Année | Rôle |
|---|---|---|---|
| Ingestion | Docling (IBM) | 2024 | Conversion PDF/DOCX → Markdown |
| Web Scraping | Trafilatura | 2019 | Extraction contenu web |
| Nettoyage | ftfy, clean-text, Spacy | 2012-2019 | Normalisation texte |
| Chunking | Semantic Chunking | 2023 | Segmentation intelligente |
| Embeddings | FastEmbed + BGE-M3 | 2023-2024 | Vectorisation ONNX |
| Base Vectorielle | LanceDB | 2023 | Stockage hybride (FTS + Vector) |
| Cache | GPTCache | 2023 | Accélération requêtes |
| Query Expansion | HyDE | 2022 | Amélioration requêtes |
| Reranking | MXBai Rerank v2 | 2024 | Affinage résultats |
| LLM | Qwen3-4B (GGUF Q4) | 2025 | Génération réponses |
| Évaluation | RAGAS | 2023 | Métriques qualité |
| Interface | Streamlit | 2019 | UI interactive |
docling>=2.0.0
trafilatura>=1.12.0
ftfy>=6.2.0
spacy>=3.7.0
fastembed>=0.3.0
lancedb>=0.13.0
gptcache>=0.1.43
llama-cpp-python>=0.2.0
ragas>=0.1.0
streamlit>=1.35.0
Les contributions sont les bienvenues ! Pour contribuer :
git checkout -b feature/amelioration)git commit -m 'Ajout fonctionnalité')git push origin feature/amelioration)Ce projet est sous licence MIT. Voir le fichier LICENSE pour plus de détails.
Pour toute question ou suggestion, n'hésitez pas à ouvrir une issue.
Fait avec ❤️ pour la communauté IA locale
⭐ Si ce projet vous est utile, n'hésitez pas à lui donner une étoile !
🚀 Agent RAG haute performance fonctionnant 100% en local sur CPU.
Python
0
33 commits
updated Dec 13, 2025
pip install -r requirements.txtpython src/retrieval/reranker_installer.pypython models/llm/llm_model_installer.pystreamlit run app.pypython clear_cache.pypython monitoring/verify_paths.py
Agent RAG (Retrieval-Augmented Generation) haute performance fonctionnant 100% en local sur CPU.
VEV RAG est un système de recherche documentaire intelligent qui combine :
Le projet fonctionne entièrement en local, sans dépendance cloud, garantissant confidentialité et autonomie.
graph TB
    A[Documents PDF/DOCX/TXT/Web] --> B[Ingestion & Nettoyage]
    B --> C[Chunking Sémantique]
    C --> D[Embeddings BGE-M3]
    D --> E[LanceDB Vectorielle]
    F[Question Utilisateur] --> G[Query Expansion HyDE]
    G --> H[Recherche Hybride]
    E --> H
    H --> I[Reranking MXBai]
    I --> J[LLM Qwen3-4B]
    J --> K[Réponse Générée]
    L[GPTCache] -.-> H
# Cloner le dépôt
git clone https://github.com/user257814938/VEV_RAG.git
cd VEV_RAG

# Créer un environnement virtuel
python -m venv venv
source venv/bin/activate  # Sur Windows: venv\Scripts\activate

# Installer les dépendances
pip install -r requirements.txt

# Télécharger les modèles
python src/scripts/download_reranker.py
Créez un fichier .env à la racine (optionnel) :
# Chemins personnalisés (optionnel)
DATA_DIR=./data
MODELS_DIR=./models
streamlit run app.py
Ouvrez votre navigateur à http://localhost:8501
from main import VEVRAGAgent

# Initialiser l'agent
agent = VEVRAGAgent()

# Ingérer des documents
agent.ingest_documents(["document.pdf", "article.docx"])

# Poser une question
response = agent.query("Quelle est la définition de l'IA ?")
print(response)
# Lancer les tests
pytest tests/

# Test d'ingestion
python tests/test_ingestion.py

# Test de recherche
python tests/test_retrieval.py
VEV_RAG/
├── 📄 app.py                    # Interface Streamlit
├── 📄 main.py                   # Orchestration principale (VEVRAGAgent)
├── 📄 requirements.txt          # Dépendances Python
├── 📂 src/
│   ├── 📂 core/
│   │   ├── config.py           # Configuration & variables d'environnement
│   │   └── schemas.py          # Structures de données (Pydantic)
│   ├── 📂 ingestion/
│   │   ├── loader_doc.py       # Chargement PDF/DOCX (Docling)
│   │   ├── loader_web.py       # Extraction web (Trafilatura)
│   │   └── cleaner.py          # Nettoyage texte (ftfy, Spacy)
│   ├── 📂 indexing/
│   │   ├── chunker.py          # Chunking sémantique
│   │   ├── embedder.py         # Embeddings (FastEmbed + BGE-M3)
│   │   └── vector_store.py     # Base vectorielle (LanceDB)
│   ├── 📂 retrieval/
│   │   ├── cache.py            # Cache sémantique (GPTCache)
│   │   ├── query_expansion.py  # Amélioration requêtes (HyDE)
│   │   └── reranker.py         # Reranking (MXBai)
│   ├── 📂 generation/
│   │   ├── llm_engine.py       # Moteur LLM (Qwen3-4B GGUF)
│   │   └── system_prompts.py   # Prompts système
│   ├── 📂 evaluation/
│   │   └── ragas_eval.py       # Évaluation qualité (RAGAS)
│   └── 📂 scripts/
│       ├── download_reranker.py # Téléchargement modèles
│       └── verify_paths.py      # Vérification structure
├── 📂 data/
│   ├── raw/                    # Documents bruts
│   ├── processed/              # Documents traités
│   └── lancedb/                # Base vectorielle
├── 📂 models/
│   ├── llm/                    # Modèles LLM (GGUF)
│   └── embeddings/             # Modèles embeddings
└── 📂 tests/
    ├── test_ingestion.py       # Tests ingestion
    └── test_retrieval.py       # Tests recherche
| Catégorie | Format | Extension | Moteur | Statut |
|---|---|---|---|---|
| Documents Office | .pdf | Docling (v2) | ✅ Supporté (avec OCR & Tableaux) | |
| Microsoft Word | .docx | Docling (v2) | ✅ Supporté | |
| Microsoft Excel | .xlsx | Docling (v2) | ✅ Supporté (Conversion Markdown) | |
| Microsoft PowerPoint | .pptx | Docling (v2) | ✅ Supporté | |
| Texte & Web | Texte Brut | .txt | Python Natif | ✅ Supporté (Ultra-rapide) |
| Markdown | .md | Python Natif | ✅ Supporté (Ultra-rapide) | |
| HTML / XHTML | .html, .htm | Docling (v2) | ✅ Supporté | |
| XML / AsciiDoc | .xml, .adoc | Docling (v2) | ✅ Supporté | |
| WebVTT | .vtt | Docling (v2) | ✅ Supporté (Sous-titres) | |
| Images (OCR) | Images | .png, .jpg, .tiff, .bmp, .webp | Docling (OCR) | ✅ Supporté |
| Audio (IA) | Audio | .mp3, .wav | Whisper Turbo | ✅ Supporté (Transcription) |
| Spécialisé | JATS/USPTO XML | .xml | Docling (v2) | ✅ Supporté |
| Docling JSON | .json | Docling (v2) | ✅ Supporté |
| Composant | Technologie | Année | Rôle |
|---|---|---|---|
| Ingestion | Docling (IBM) | 2024 | Conversion PDF/DOCX → Markdown |
| Web Scraping | Trafilatura | 2019 | Extraction contenu web |
| Nettoyage | ftfy, clean-text, Spacy | 2012-2019 | Normalisation texte |
| Chunking | Semantic Chunking | 2023 | Segmentation intelligente |
| Embeddings | FastEmbed + BGE-M3 | 2023-2024 | Vectorisation ONNX |
| Base Vectorielle | LanceDB | 2023 | Stockage hybride (FTS + Vector) |
| Cache | GPTCache | 2023 | Accélération requêtes |
| Query Expansion | HyDE | 2022 | Amélioration requêtes |
| Reranking | MXBai Rerank v2 | 2024 | Affinage résultats |
| LLM | Qwen3-4B (GGUF Q4) | 2025 | Génération réponses |
| Évaluation | RAGAS | 2023 | Métriques qualité |
| Interface | Streamlit | 2019 | UI interactive |
docling>=2.0.0
trafilatura>=1.12.0
ftfy>=6.2.0
spacy>=3.7.0
fastembed>=0.3.0
lancedb>=0.13.0
gptcache>=0.1.43
llama-cpp-python>=0.2.0
ragas>=0.1.0
streamlit>=1.35.0
Les contributions sont les bienvenues ! Pour contribuer :
git checkout -b feature/amelioration)git commit -m 'Ajout fonctionnalité')git push origin feature/amelioration)Ce projet est sous licence MIT. Voir le fichier LICENSE pour plus de détails.
Pour toute question ou suggestion, n'hésitez pas à ouvrir une issue.
Fait avec ❤️ pour la communauté IA locale
⭐ Si ce projet vous est utile, n'hésitez pas à lui donner une étoile !



