
Private AI chats in your browser
1
stars
192
commits
TypeScript
primary language
Sep 14, 2026
updated
README
llame is a fully client-side chat app for running ONNX language and vision models with WebGPU. No backend, no API key, and no hosted inference.
Pick a model, wait for the browser download, and chat locally on your device. Chat-tuned models use their tokenizer chat template when available. Base causal language models such as GPT-2 run as text-completion models with plain continuation prompts.
Install
git clone https://github.com/tsilva/llame.git
cd llame
pnpm install
pnpm dev
Open http://localhost:3000.
Commands
pnpm dev      # start local dev server
pnpm build    # build static export
pnpm lint     # run ESLint
pnpm test     # run unit tests
pnpm run check:verified-model-sitemap
Notes
- This repo enforces pnpm for installs.
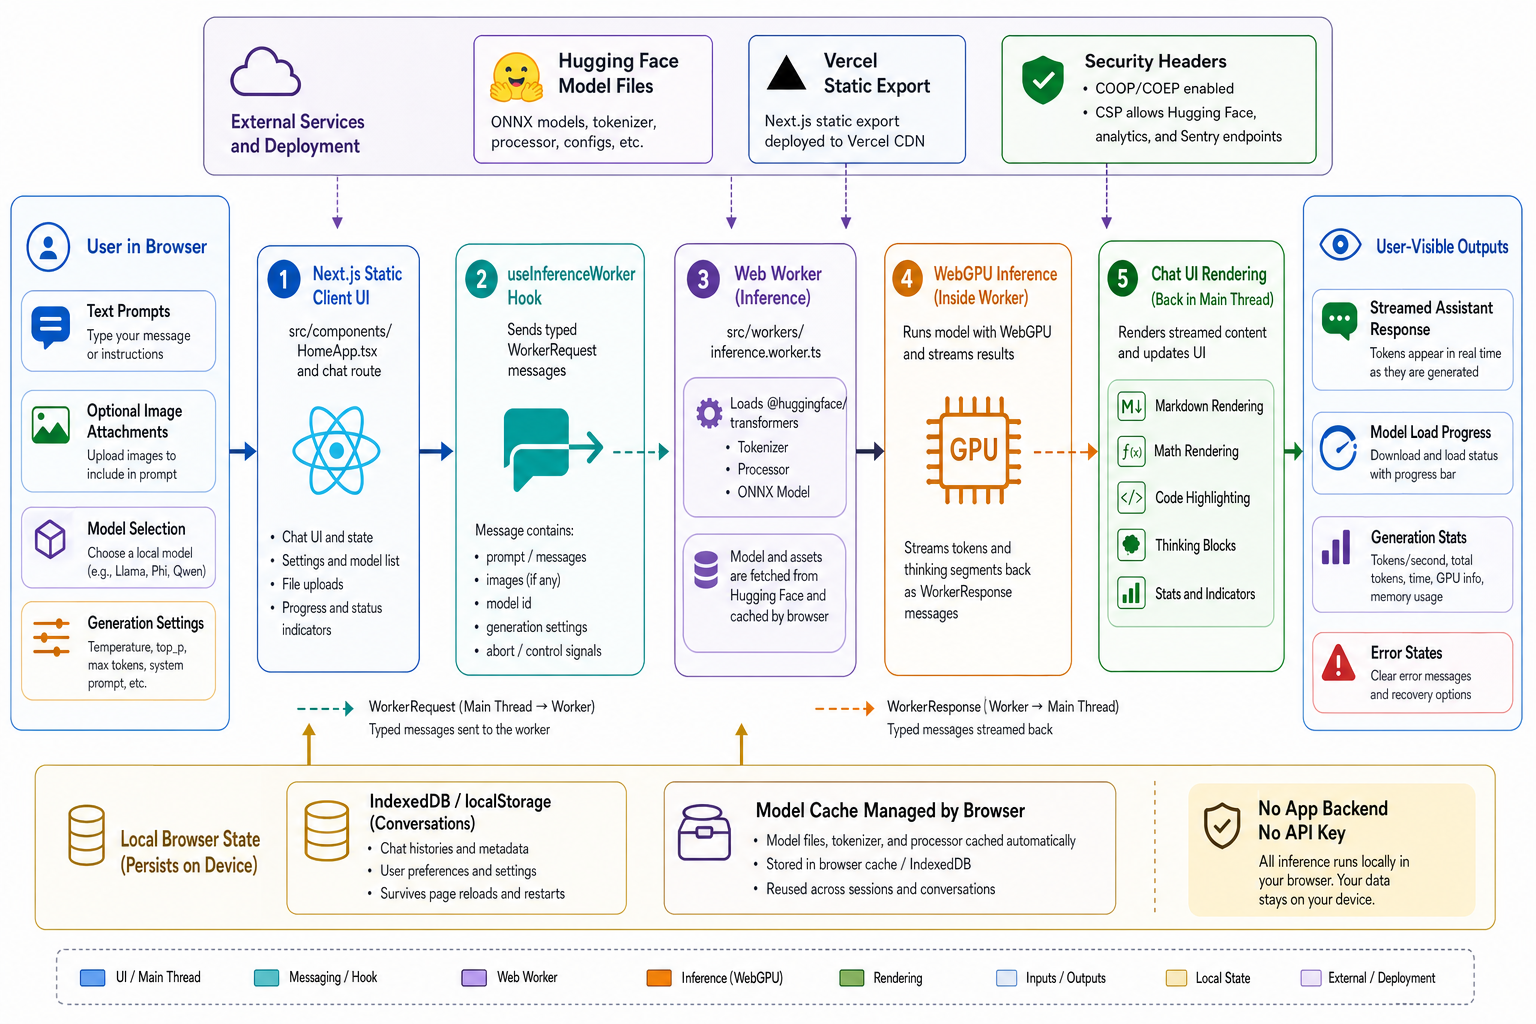
pnpm installconfigures the repo-managed pre-commit hook ingithooks/.- Models are downloaded from Hugging Face into the browser.
- Browser-tested model status lives in
src/config/verifiedModels.ts; models that load and answer plausibly are marked verified, while known failing presets are marked broken with a reason. - WebGPU is the supported inference device.
- Tokenization view can colorize the prompt input and visible chat messages after the selected model is loaded, using that model's tokenizer in the inference worker.
- Conversations, including uploaded images, are stored in IndexedDB, with
llame-localStorage keys for settings and migration state. - The Vercel deployment serves a static export with COOP/COEP and CSP headers for browser inference.
Local credentials
Private local values declared in .keyenv.toml live in macOS Keychain. Run
keyenv doctor to verify them and launch credential-dependent commands with
keyenv run -- <command>. Python, Node, and their child processes receive the
values through their normal environment APIs. Keep only public or non-secret
configuration in dotenv files.
Architecture
License
Contributors

189 commits

3 commits
Similar repos




Languages
TypeScript
79.0%
JavaScript
14.6%
Python
3.9%
CSS
2.1%
Private AI chats in your browser
1
stars
192
commits
TypeScript
primary language
Sep 14, 2026
updated
README
llame is a fully client-side chat app for running ONNX language and vision models with WebGPU. No backend, no API key, and no hosted inference.
Pick a model, wait for the browser download, and chat locally on your device. Chat-tuned models use their tokenizer chat template when available. Base causal language models such as GPT-2 run as text-completion models with plain continuation prompts.
Install
git clone https://github.com/tsilva/llame.git
cd llame
pnpm install
pnpm dev
Open http://localhost:3000.
Commands
pnpm dev      # start local dev server
pnpm build    # build static export
pnpm lint     # run ESLint
pnpm test     # run unit tests
pnpm run check:verified-model-sitemap
Notes
- This repo enforces pnpm for installs.
pnpm installconfigures the repo-managed pre-commit hook ingithooks/.- Models are downloaded from Hugging Face into the browser.
- Browser-tested model status lives in
src/config/verifiedModels.ts; models that load and answer plausibly are marked verified, while known failing presets are marked broken with a reason. - WebGPU is the supported inference device.
- Tokenization view can colorize the prompt input and visible chat messages after the selected model is loaded, using that model's tokenizer in the inference worker.
- Conversations, including uploaded images, are stored in IndexedDB, with
llame-localStorage keys for settings and migration state. - The Vercel deployment serves a static export with COOP/COEP and CSP headers for browser inference.
Local credentials
Private local values declared in .keyenv.toml live in macOS Keychain. Run
keyenv doctor to verify them and launch credential-dependent commands with
keyenv run -- <command>. Python, Node, and their child processes receive the
values through their normal environment APIs. Keep only public or non-secret
configuration in dotenv files.
Architecture
License
Similar repos
Contributors
189 commits
3 commits
Languages
TypeScript
79.0%
JavaScript
14.6%
Python
3.9%
CSS
2.1%