
README
Arabic LLM Benchmarks
A comprehensive repository of Arabic LLMs benchmarks and evaluation benchmarks, curated from systematic research on evaluating Arabic Large Language Models.
📚 Survey paper: Evaluating Arabic Large Language Models: A Survey of Benchmarks, Methods, and Gaps
Table of Contents
📋 Overview
This survey provides the first systematic review of Arabic LLM benchmarks, analyzing 40+ evaluation benchmarks across NLP tasks, knowledge domains, cultural understanding, and specialized capabilities. We propose a taxonomy organizing benchmarks into four categories: Knowledge and STEM, NLP Tasks, Culture and Dialects, and Target-Specific evaluations. Our analysis reveals significant progress in benchmark diversity while identifying critical gaps: limited temporal evaluation, insufficient multi-turn dialogue assessment, and cultural misalignment in translated datasets. We examine three primary approaches: native collection, translation, and synthetic generation discussing their trade-offs regarding authenticity, scale, and cost. This work serves as a comprehensive reference for Arabic NLP researchers, providing insights into benchmark methodologies, reproducibility standards, and evaluation metrics while offering recommendations for future development.
🗂️ Taxonomy
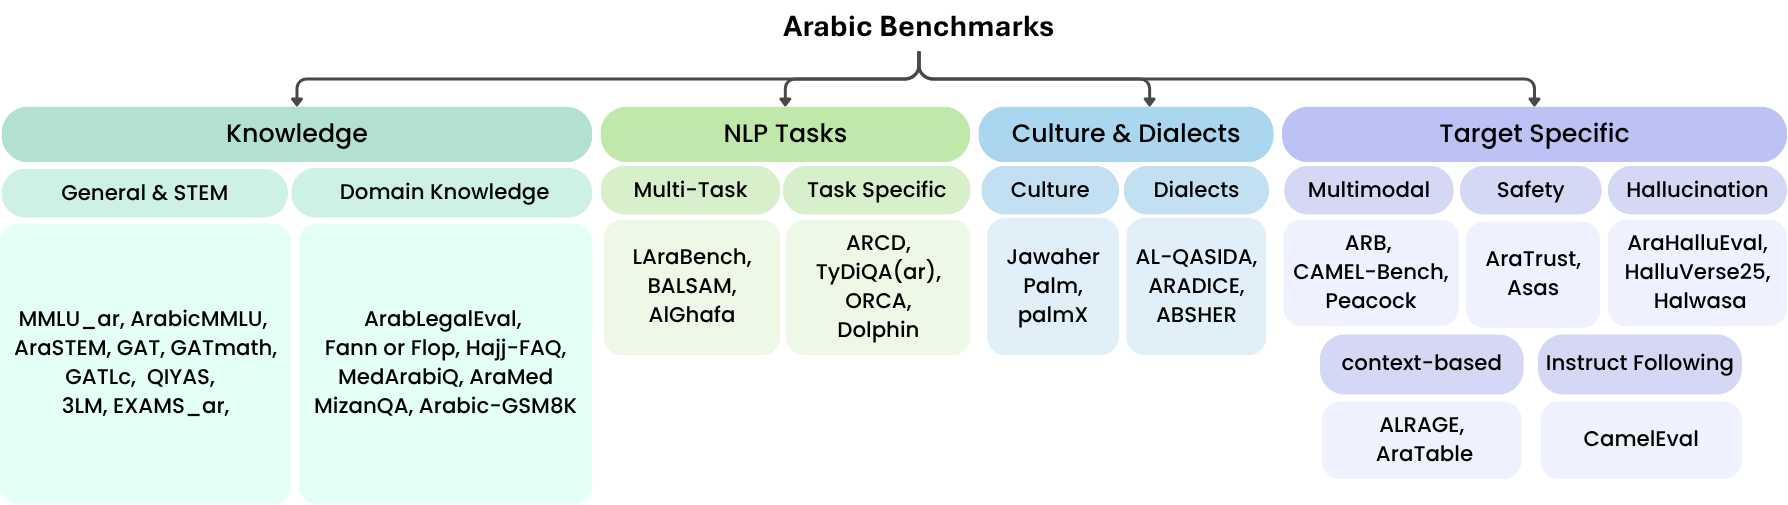 The taxonomy formed based on existing work/benchmarks is depicted above. Each of the categories is defined below:
- Knowledge includes benchmarks evaluating acquired knowledge and reasoning capabilities, along with domain-specific benchmarks in fields such as law and medicine.
- Natural Language Processing (NLP) encompasses early task-specific benchmarks and comprehensive multi-task benchmarks, reflecting the evolution from narrow task evaluation to unified assessment across diverse dialects and domains.
- Culture and Dialects groups benchmarks assessing cultural knowledge and dialect understanding, addressing the essential property of cultural awareness in Arabic LLMs.
- Target-Specific covers benchmarks designed to assess particular LLM properties such as safety, hallucination detection, instruction-following, and vision capabilities.
🔬 Knowledge
⚙️ General Knowledge & STEM
| Name | Paper/Benchmark | Links | Access |
|---|---|---|---|
| MMLU | Measuring Massive Multitask Language Understanding | paper • data • lighteval | Public |
| EXAMS | EXAMS: A Multi-Subject High School Examinations Dataset for Cross-Lingual and Multilingual Question Answering | paper • data • lighteval | Public |
| ArabicMMLU | ArabicMMLU: Assessing Massive Multitask Language Understanding in Arabic | paper • data • repo | Public |
| AraSTEM | AraSTEM: A Native Arabic Multiple Choice Question Benchmark for Evaluating LLMs Knowledge In STEM Subjects | paper | Private |
| GAT | A bilingual benchmark for evaluating large language models | paper | Private |
| Qiyas | The Qiyas Benchmark: Measuring ChatGPT Mathematical and Language Understanding in Arabic | paper | Private |
| GATmath & GATLc | GATmath and GATLc: Comprehensive benchmarks for evaluating Arabic large language models | paper • data | Public |
| 3LM | 3LM: Bridging Arabic, STEM, and Code through Benchmarking | paper • data • repo | Public |
🏛️ Domain Knowledge
| Name | Paper/Benchmark | Topic | Links | Access |
|---|---|---|---|---|
| ArabLegalEval | ArabLegalEval: A Multitask Benchmark for Assessing Arabic Legal Knowledge in Large Language Models | Law | paper • repo | Public |
| AraMed | AraMed: Arabic Medical Question Answering using Pretrained Transformer Language Models | Medical | paper • repo | Public |
| MizanQA | MizanQA: Benchmarking Large Language Models on Moroccan Legal Question Answering | Law | paper • data | Public |
| Fann or Flop | Fann or Flop: A Multigenre, Multiera Benchmark for Arabic Poetry Understanding in LLMs | Poetry | paper • data • repo | Public |
| MedArabiQ | MedArabiQ: Benchmarking Large Language Models on Arabic Medical Tasks | Medical | paper • repo | Public |
| Arabic-Gsm8k | Arabic-Gsm8k | Reasoning | data | Public |
| Hajj-FQA | Hajj-FQA: A benchmark Arabic dataset for developing question-answering systems on Hajj fatwas | Religion | paper | Private |
| MedAraBench | MedAraBench: Large-scale Arabic Medical Question Answering Dataset and Benchmark | Medical | paper • repo | Public |
💬 NLP Tasks
| Name | Paper/Benchmark | Links | Access |
|---|---|---|---|
| SOQAL | Neural Arabic Question Answering | paper • data • repo | Public |
| TyDi QA | TyDi QA: A Benchmark for Information-Seeking Question Answering in Typologically Diverse Languages | paper • repo | Public |
| ORCA | ORCA: A Challenging Benchmark for Arabic Language Understanding | paper • data | Public |
| Dolphin | Dolphin: A Challenging and Diverse Benchmark for Arabic NLG | paper | Private |
| LAraBench | LAraBench: Benchmarking Arabic AI with Large Language Models | paper • repo | Public |
| BALSAM | BALSAM: A Platform for Benchmarking Arabic Large Language Models | paper • website | Public |
| AlGhafa | AlGhafa Evaluation Benchmark for Arabic Language Models | paper • data • repo | Public |
🌍 Culture & Dialects
| Name | Paper/Benchmark | Links | Access |
|---|---|---|---|
| Jawaher | Jawaher: A Multidialectal Dataset of Arabic Proverbs for LLM Benchmarking | paper • data | Public |
| Palm | Palm: A Culturally Inclusive and Linguistically Diverse Dataset for Arabic LLMs | paper • data • repo | Public |
| PalmX | PalmX 2025: The First Shared Task on Benchmarking LLMs on Arabic and Islamic Culture | paper • data • data • website | Public |
| ArabCulture | Commonsense Reasoning in Arab Culture | paper • data • lm-eval | Public |
| AraDiCE | AraDiCE: Benchmarks for Dialectal and Cultural Capabilities in LLMs | paper • data • lm-eval | Public |
| AL-QASIDA | AL-QASIDA: Analyzing LLM Quality and Accuracy Systematically in Dialectal Arabic | paper • repo | Public |
| Absher | Absher: A Benchmark for Evaluating Large Language Models Understanding of Saudi Dialects | paper | Private |
| ADAB | ADAB: Arabic Dataset for Automated Politeness Benchmarking -- A Large-Scale Resource for Computational Sociopragmatics | paper | Private |
| DialectalArabicMMLU | DialectalArabicMMLU: Benchmarking Dialectal Capabilities in Arabic and Multilingual Language Models | paper • data | Public |
🎯 Specific-Targets
| Name | Paper/Benchmark | Topic | Links | Access |
|---|---|---|---|---|
| CamelEval | CamelEval: Advancing Culturally Aligned Arabic Language Models and Benchmarks | Instruction-following | paper | Private |
| Halwasa | Halwasa: Quantify and Analyze Hallucinations in Large Language Models: Arabic as a Case Study | Hallucination | paper | Private |
| Peacock | Peacock: A Family of Arabic Multimodal Large Language Models and Benchmarks | Multimodal | paper • data • repo | Public |
| CAMEL-Bench | CAMEL-Bench: A Comprehensive Arabic LMM Benchmark | Multimodal | paper • data • repo | Public |
| AraTrust | AraTrust: An Evaluation of Trustworthiness for LLMs in Arabic | Safety | paper • data | Public |
| Arabic Safety Dataset | Arabic Dataset for LLM Safeguard Evaluation | Safety | paper • repo | Public |
| ALRAGE | ALRAGE | Context-Based (RAG) | data | Public |
| AraTable | AraTable: Benchmarking LLMs' Reasoning and Understanding of Arabic Tabular Data | Context-Based (Tabular) | paper • repo | Public |
| AraHalluEval | AraHalluEval: A Fine-grained Hallucination Evaluation Framework for Arabic LLMs | Hallucination | paper • repo | Public |
| HalluVerse25 | HalluVerse25: Fine-grained Multilingual Benchmark Dataset for LLM Hallucinations | Poetry | paper | Private |
| ARB | ARB: A Comprehensive Arabic Multimodal Reasoning Benchmark | Multimodal | paper • data • repo | Public |
| ASAS | Redteaming Frontier LLMs with AI Astrolabe Arabic Safety Index (ASAS - أساس) | Safety | blog | Public |
🤝 Contributing
We welcome contributions! If you'd like to add new benchmarks or improve existing information, please feel free to submit issues or pull requests.
📖 Citation
If you use this repository or find the survey helpful, please cite:
@misc{alzubaidi2025evaluatingarabiclargelanguage,
      title={Evaluating Arabic Large Language Models: A Survey of Benchmarks, Methods, and Gaps},
      author={Ahmed Alzubaidi and Shaikha Alsuwaidi and Basma El Amel Boussaha and Leen AlQadi and Omar Alkaabi and Mohammed Alyafeai and Hamza Alobeidli and Hakim Hacid},
      year={2025},
      eprint={2510.13430},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2510.13430},
}
Similar repos





README
Arabic LLM Benchmarks
A comprehensive repository of Arabic LLMs benchmarks and evaluation benchmarks, curated from systematic research on evaluating Arabic Large Language Models.
📚 Survey paper: Evaluating Arabic Large Language Models: A Survey of Benchmarks, Methods, and Gaps
Table of Contents
📋 Overview
This survey provides the first systematic review of Arabic LLM benchmarks, analyzing 40+ evaluation benchmarks across NLP tasks, knowledge domains, cultural understanding, and specialized capabilities. We propose a taxonomy organizing benchmarks into four categories: Knowledge and STEM, NLP Tasks, Culture and Dialects, and Target-Specific evaluations. Our analysis reveals significant progress in benchmark diversity while identifying critical gaps: limited temporal evaluation, insufficient multi-turn dialogue assessment, and cultural misalignment in translated datasets. We examine three primary approaches: native collection, translation, and synthetic generation discussing their trade-offs regarding authenticity, scale, and cost. This work serves as a comprehensive reference for Arabic NLP researchers, providing insights into benchmark methodologies, reproducibility standards, and evaluation metrics while offering recommendations for future development.
🗂️ Taxonomy
The taxonomy formed based on existing work/benchmarks is depicted above. Each of the categories is defined below:
- Knowledge includes benchmarks evaluating acquired knowledge and reasoning capabilities, along with domain-specific benchmarks in fields such as law and medicine.
- Natural Language Processing (NLP) encompasses early task-specific benchmarks and comprehensive multi-task benchmarks, reflecting the evolution from narrow task evaluation to unified assessment across diverse dialects and domains.
- Culture and Dialects groups benchmarks assessing cultural knowledge and dialect understanding, addressing the essential property of cultural awareness in Arabic LLMs.
- Target-Specific covers benchmarks designed to assess particular LLM properties such as safety, hallucination detection, instruction-following, and vision capabilities.
🔬 Knowledge
⚙️ General Knowledge & STEM
| Name | Paper/Benchmark | Links | Access |
|---|---|---|---|
| MMLU | Measuring Massive Multitask Language Understanding | paper • data • lighteval | Public |
| EXAMS | EXAMS: A Multi-Subject High School Examinations Dataset for Cross-Lingual and Multilingual Question Answering | paper • data • lighteval | Public |
| ArabicMMLU | ArabicMMLU: Assessing Massive Multitask Language Understanding in Arabic | paper • data • repo | Public |
| AraSTEM | AraSTEM: A Native Arabic Multiple Choice Question Benchmark for Evaluating LLMs Knowledge In STEM Subjects | paper | Private |
| GAT | A bilingual benchmark for evaluating large language models | paper | Private |
| Qiyas | The Qiyas Benchmark: Measuring ChatGPT Mathematical and Language Understanding in Arabic | paper | Private |
| GATmath & GATLc | GATmath and GATLc: Comprehensive benchmarks for evaluating Arabic large language models | paper • data | Public |
| 3LM | 3LM: Bridging Arabic, STEM, and Code through Benchmarking | paper • data • repo | Public |
🏛️ Domain Knowledge
| Name | Paper/Benchmark | Topic | Links | Access |
|---|---|---|---|---|
| ArabLegalEval | ArabLegalEval: A Multitask Benchmark for Assessing Arabic Legal Knowledge in Large Language Models | Law | paper • repo | Public |
| AraMed | AraMed: Arabic Medical Question Answering using Pretrained Transformer Language Models | Medical | paper • repo | Public |
| MizanQA | MizanQA: Benchmarking Large Language Models on Moroccan Legal Question Answering | Law | paper • data | Public |
| Fann or Flop | Fann or Flop: A Multigenre, Multiera Benchmark for Arabic Poetry Understanding in LLMs | Poetry | paper • data • repo | Public |
| MedArabiQ | MedArabiQ: Benchmarking Large Language Models on Arabic Medical Tasks | Medical | paper • repo | Public |
| Arabic-Gsm8k | Arabic-Gsm8k | Reasoning | data | Public |
| Hajj-FQA | Hajj-FQA: A benchmark Arabic dataset for developing question-answering systems on Hajj fatwas | Religion | paper | Private |
| MedAraBench | MedAraBench: Large-scale Arabic Medical Question Answering Dataset and Benchmark | Medical | paper • repo | Public |
💬 NLP Tasks
| Name | Paper/Benchmark | Links | Access |
|---|---|---|---|
| SOQAL | Neural Arabic Question Answering | paper • data • repo | Public |
| TyDi QA | TyDi QA: A Benchmark for Information-Seeking Question Answering in Typologically Diverse Languages | paper • repo | Public |
| ORCA | ORCA: A Challenging Benchmark for Arabic Language Understanding | paper • data | Public |
| Dolphin | Dolphin: A Challenging and Diverse Benchmark for Arabic NLG | paper | Private |
| LAraBench | LAraBench: Benchmarking Arabic AI with Large Language Models | paper • repo | Public |
| BALSAM | BALSAM: A Platform for Benchmarking Arabic Large Language Models | paper • website | Public |
| AlGhafa | AlGhafa Evaluation Benchmark for Arabic Language Models | paper • data • repo | Public |
🌍 Culture & Dialects
| Name | Paper/Benchmark | Links | Access |
|---|---|---|---|
| Jawaher | Jawaher: A Multidialectal Dataset of Arabic Proverbs for LLM Benchmarking | paper • data | Public |
| Palm | Palm: A Culturally Inclusive and Linguistically Diverse Dataset for Arabic LLMs | paper • data • repo | Public |
| PalmX | PalmX 2025: The First Shared Task on Benchmarking LLMs on Arabic and Islamic Culture | paper • data • data • website | Public |
| ArabCulture | Commonsense Reasoning in Arab Culture | paper • data • lm-eval | Public |
| AraDiCE | AraDiCE: Benchmarks for Dialectal and Cultural Capabilities in LLMs | paper • data • lm-eval | Public |
| AL-QASIDA | AL-QASIDA: Analyzing LLM Quality and Accuracy Systematically in Dialectal Arabic | paper • repo | Public |
| Absher | Absher: A Benchmark for Evaluating Large Language Models Understanding of Saudi Dialects | paper | Private |
| ADAB | ADAB: Arabic Dataset for Automated Politeness Benchmarking -- A Large-Scale Resource for Computational Sociopragmatics | paper | Private |
| DialectalArabicMMLU | DialectalArabicMMLU: Benchmarking Dialectal Capabilities in Arabic and Multilingual Language Models | paper • data | Public |
🎯 Specific-Targets
| Name | Paper/Benchmark | Topic | Links | Access |
|---|---|---|---|---|
| CamelEval | CamelEval: Advancing Culturally Aligned Arabic Language Models and Benchmarks | Instruction-following | paper | Private |
| Halwasa | Halwasa: Quantify and Analyze Hallucinations in Large Language Models: Arabic as a Case Study | Hallucination | paper | Private |
| Peacock | Peacock: A Family of Arabic Multimodal Large Language Models and Benchmarks | Multimodal | paper • data • repo | Public |
| CAMEL-Bench | CAMEL-Bench: A Comprehensive Arabic LMM Benchmark | Multimodal | paper • data • repo | Public |
| AraTrust | AraTrust: An Evaluation of Trustworthiness for LLMs in Arabic | Safety | paper • data | Public |
| Arabic Safety Dataset | Arabic Dataset for LLM Safeguard Evaluation | Safety | paper • repo | Public |
| ALRAGE | ALRAGE | Context-Based (RAG) | data | Public |
| AraTable | AraTable: Benchmarking LLMs' Reasoning and Understanding of Arabic Tabular Data | Context-Based (Tabular) | paper • repo | Public |
| AraHalluEval | AraHalluEval: A Fine-grained Hallucination Evaluation Framework for Arabic LLMs | Hallucination | paper • repo | Public |
| HalluVerse25 | HalluVerse25: Fine-grained Multilingual Benchmark Dataset for LLM Hallucinations | Poetry | paper | Private |
| ARB | ARB: A Comprehensive Arabic Multimodal Reasoning Benchmark | Multimodal | paper • data • repo | Public |
| ASAS | Redteaming Frontier LLMs with AI Astrolabe Arabic Safety Index (ASAS - أساس) | Safety | blog | Public |
🤝 Contributing
We welcome contributions! If you'd like to add new benchmarks or improve existing information, please feel free to submit issues or pull requests.
📖 Citation
If you use this repository or find the survey helpful, please cite:
@misc{alzubaidi2025evaluatingarabiclargelanguage,
      title={Evaluating Arabic Large Language Models: A Survey of Benchmarks, Methods, and Gaps},
      author={Ahmed Alzubaidi and Shaikha Alsuwaidi and Basma El Amel Boussaha and Leen AlQadi and Omar Alkaabi and Mohammed Alyafeai and Hamza Alobeidli and Hakim Hacid},
      year={2025},
      eprint={2510.13430},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2510.13430},
}