Code and models for the paper: Hybrid Linear Attention Done Right: Efficient Distillation and Effective Architectures for Extremely Long Contexts
Python
44
18 commits
updated Oct 14, 2026
Code and models for the paper: Hybrid Linear Attention Done Right: Efficient Distillation and Effective Architectures for Extremely Long Contexts by Yingfa Chen, Zhen Leng Thai, Zihan Zhou, Zhu Zhang, Xingyu Shen, Shuo Wang, Chaojun Xiao, Xu Han, and Zhiyuan Liu.
Links:
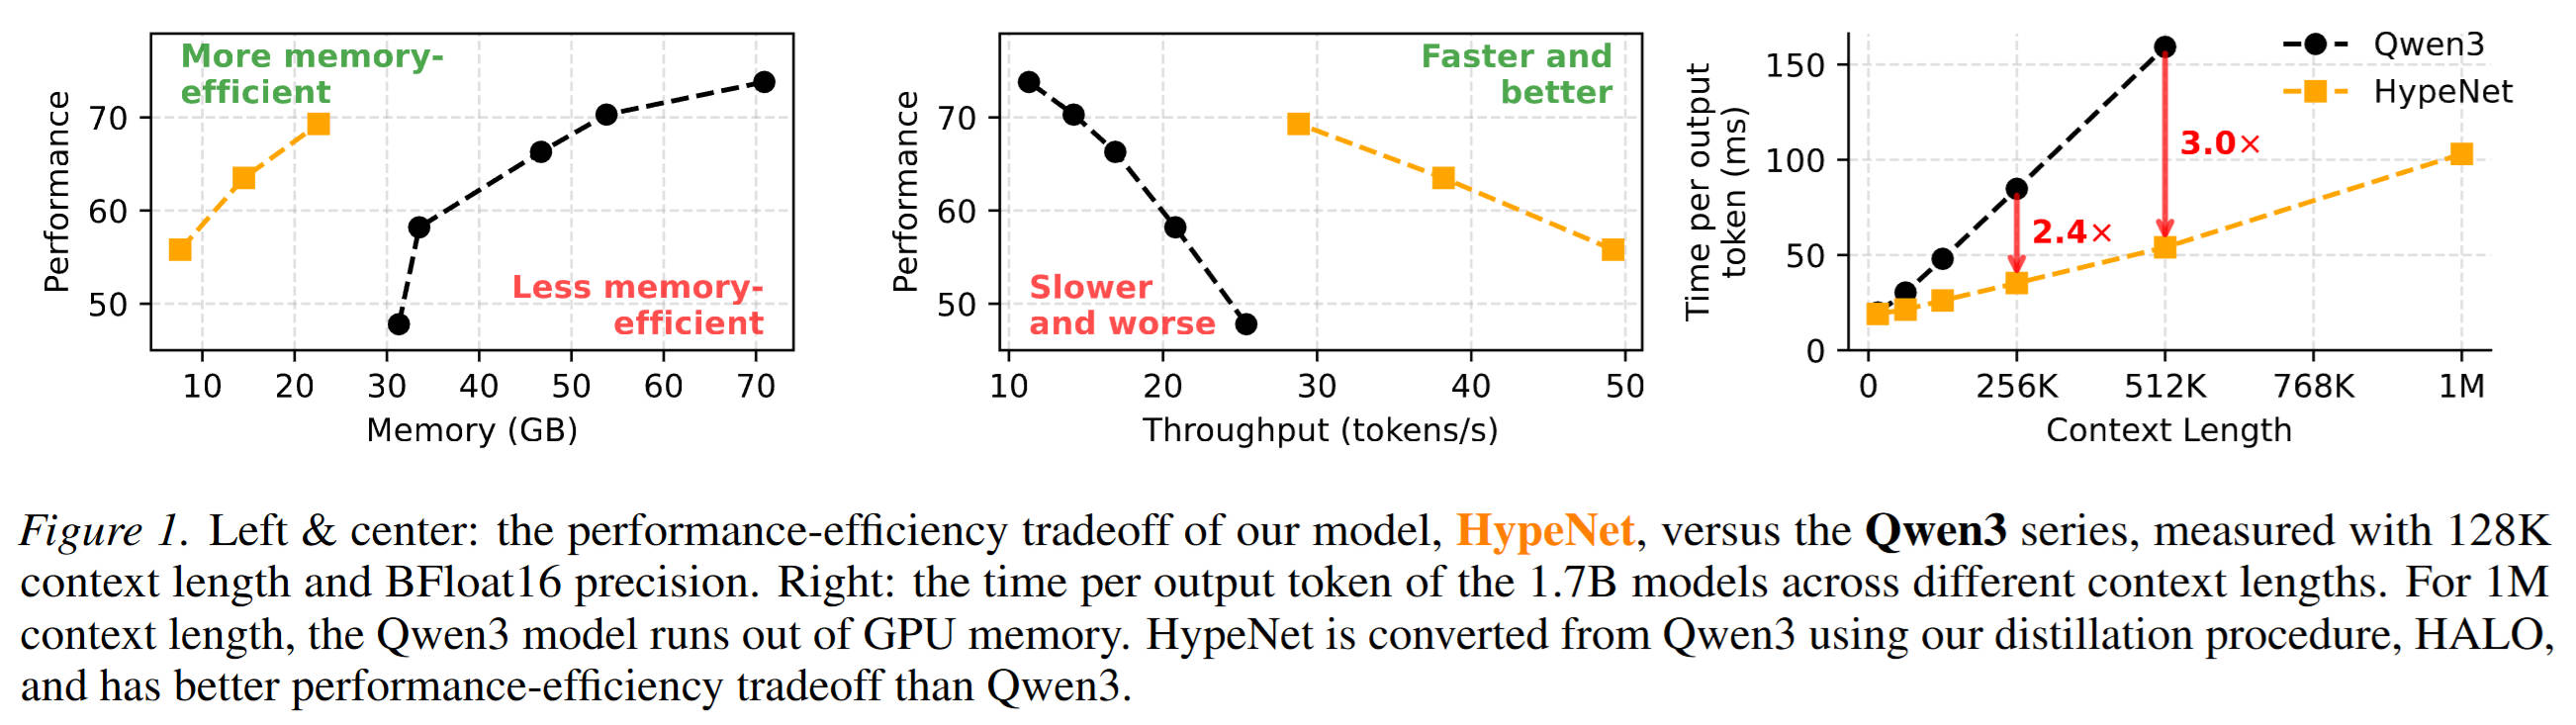
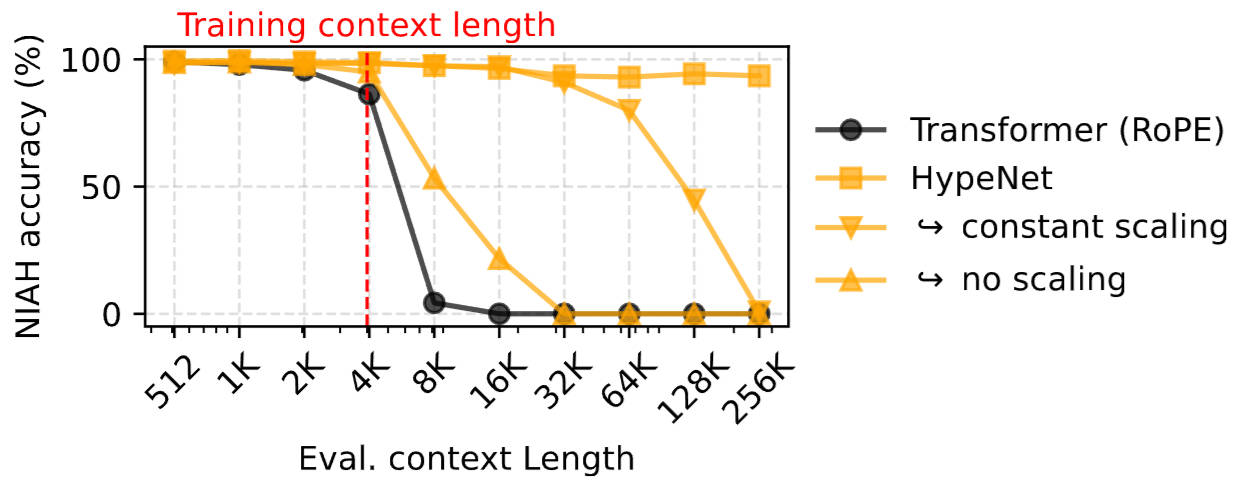
The main contributions of the paper is:
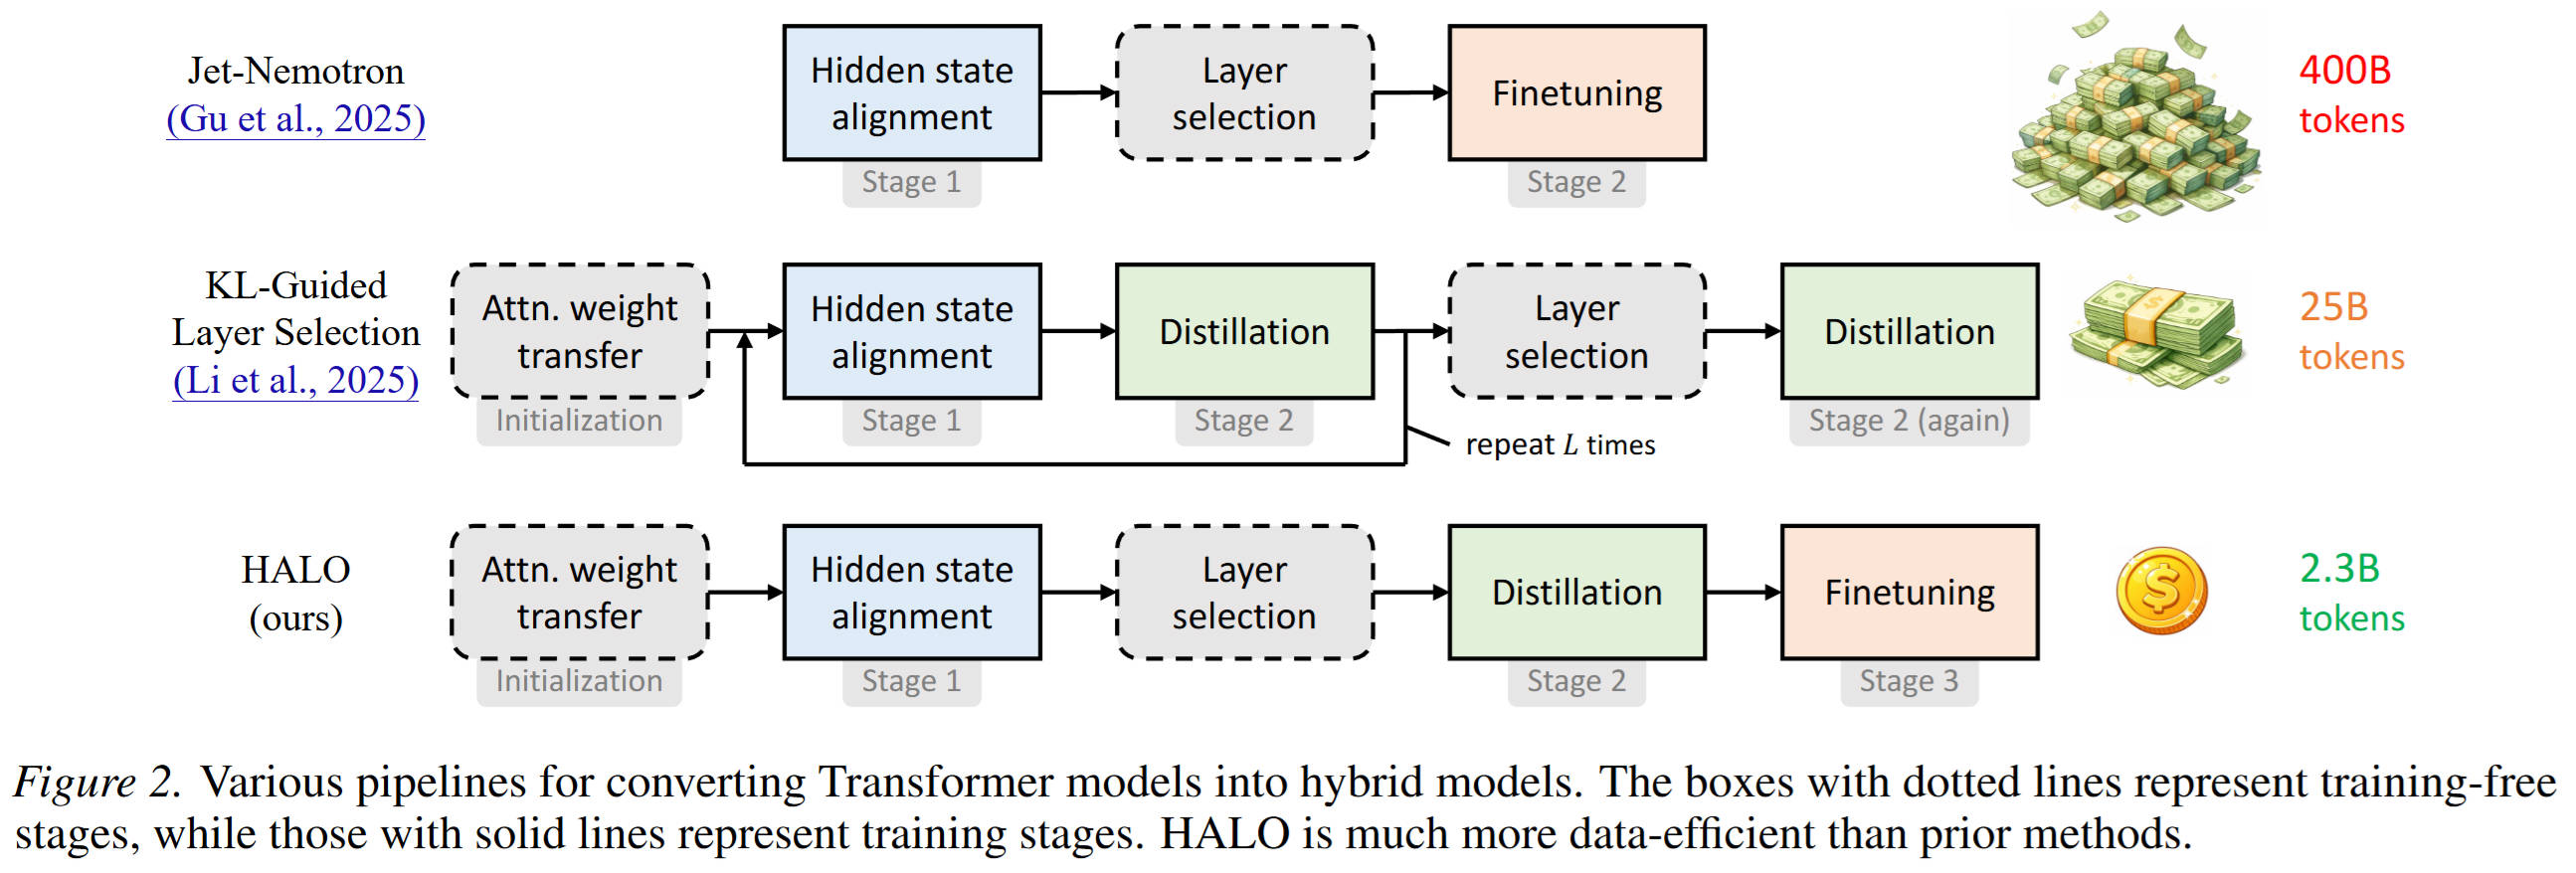
The distillation procedure, HALO, is as follows.
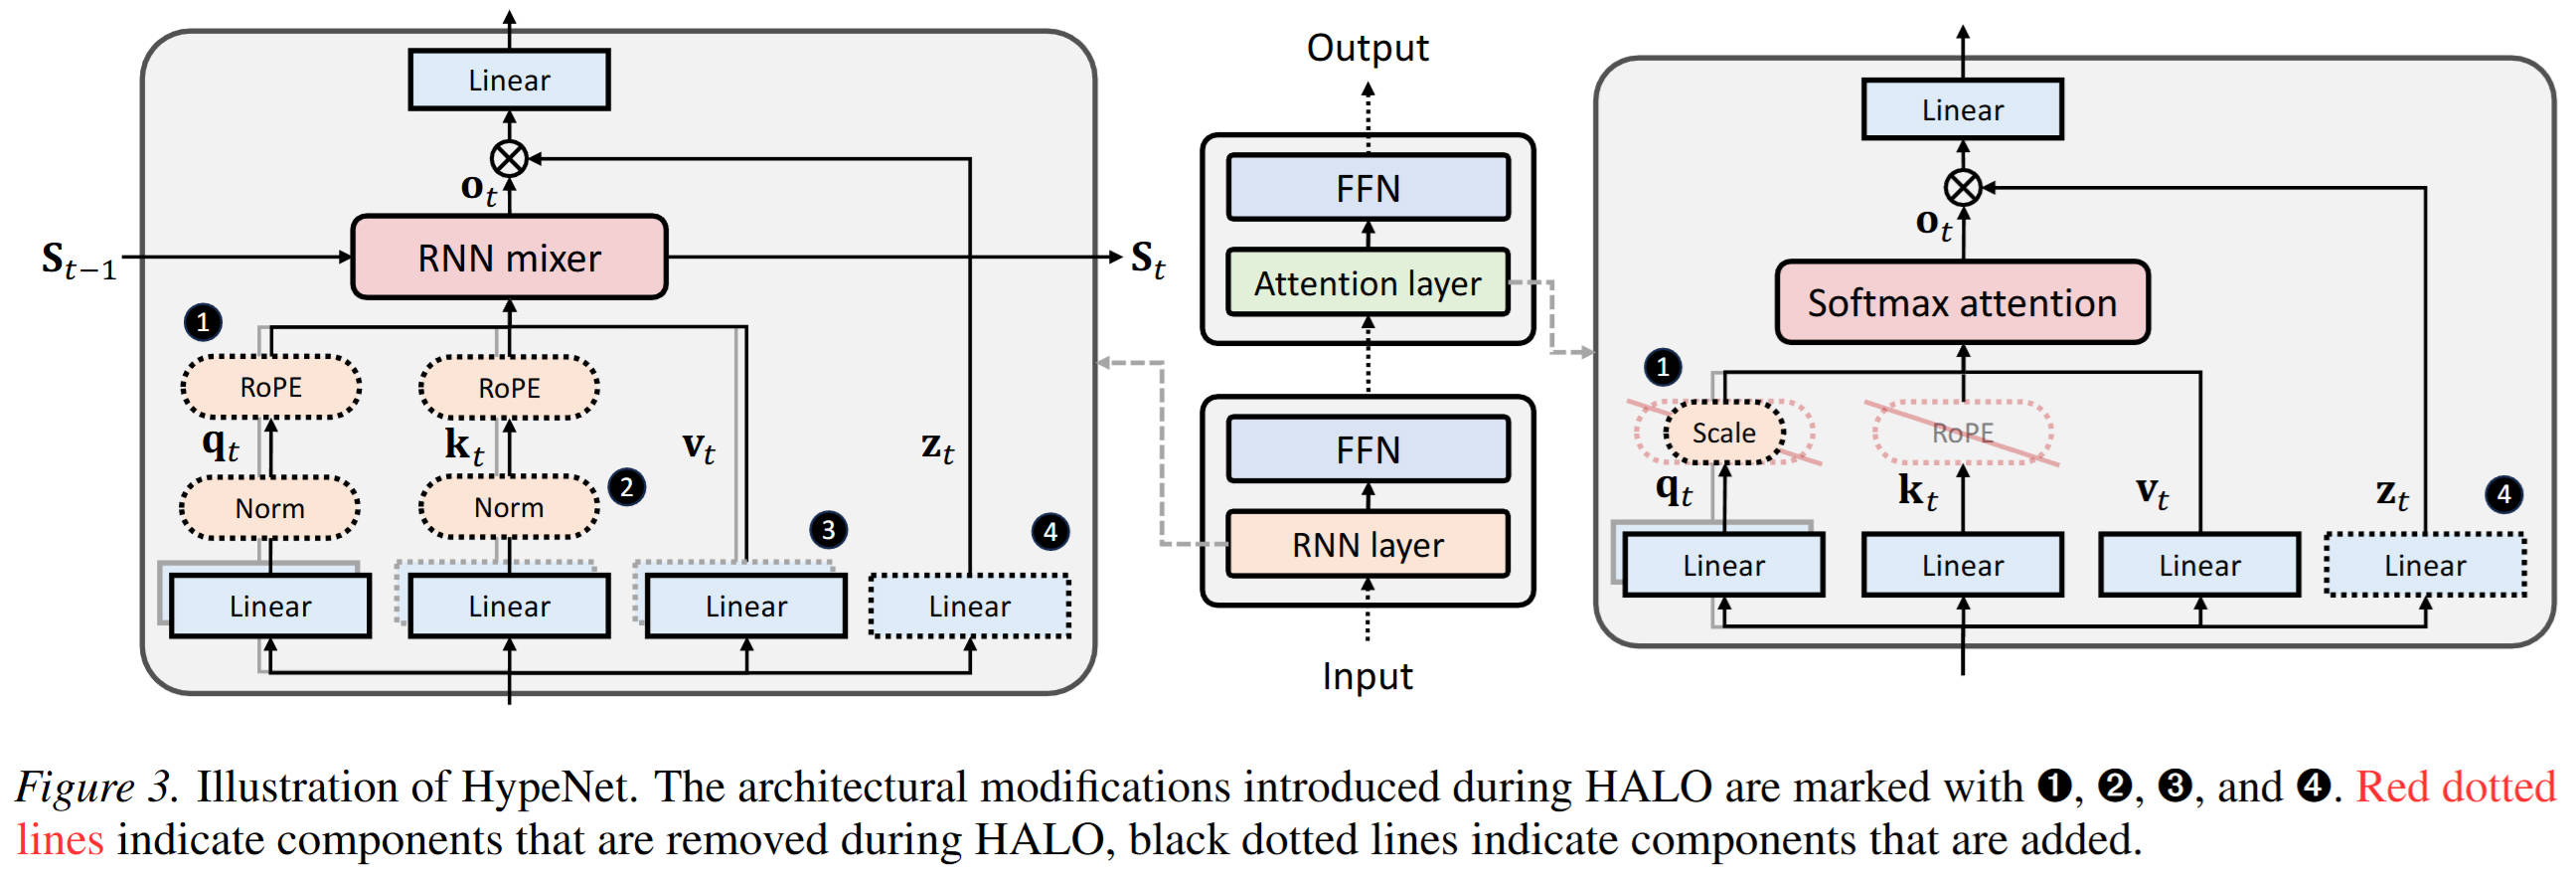
The model architecture of HypeNet is as follows.
The following is the BibTex for citing us.
@misc{hybrid-linear-attention-done-right,
      title={Hybrid Linear Attention Done Right: Efficient Distillation and Effective Architectures for Extremely Long Contexts},
      author={Yingfa Chen and Zhen Leng Thai and Zihan Zhou and Zhu Zhang and Xingyu Shen and Shuo Wang and Chaojun Xiao and Xu Han and Zhiyuan Liu},
      year={2026},
      eprint={2601.22156},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.22156},
}
Code and models for the paper: Hybrid Linear Attention Done Right: Efficient Distillation and Effective Architectures for Extremely Long Contexts
Python
44
18 commits
updated Oct 14, 2026
Code and models for the paper: Hybrid Linear Attention Done Right: Efficient Distillation and Effective Architectures for Extremely Long Contexts by Yingfa Chen, Zhen Leng Thai, Zihan Zhou, Zhu Zhang, Xingyu Shen, Shuo Wang, Chaojun Xiao, Xu Han, and Zhiyuan Liu.
Links:
The main contributions of the paper is:
The distillation procedure, HALO, is as follows.
The model architecture of HypeNet is as follows.
The following is the BibTex for citing us.
@misc{hybrid-linear-attention-done-right,
      title={Hybrid Linear Attention Done Right: Efficient Distillation and Effective Architectures for Extremely Long Contexts},
      author={Yingfa Chen and Zhen Leng Thai and Zihan Zhou and Zhu Zhang and Xingyu Shen and Shuo Wang and Chaojun Xiao and Xu Han and Zhiyuan Liu},
      year={2026},
      eprint={2601.22156},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.22156},
}





