Implementation of plug in and play Attention from "LongNet: Scaling Transformers to 1,000,000,000 Tokens"
See the code
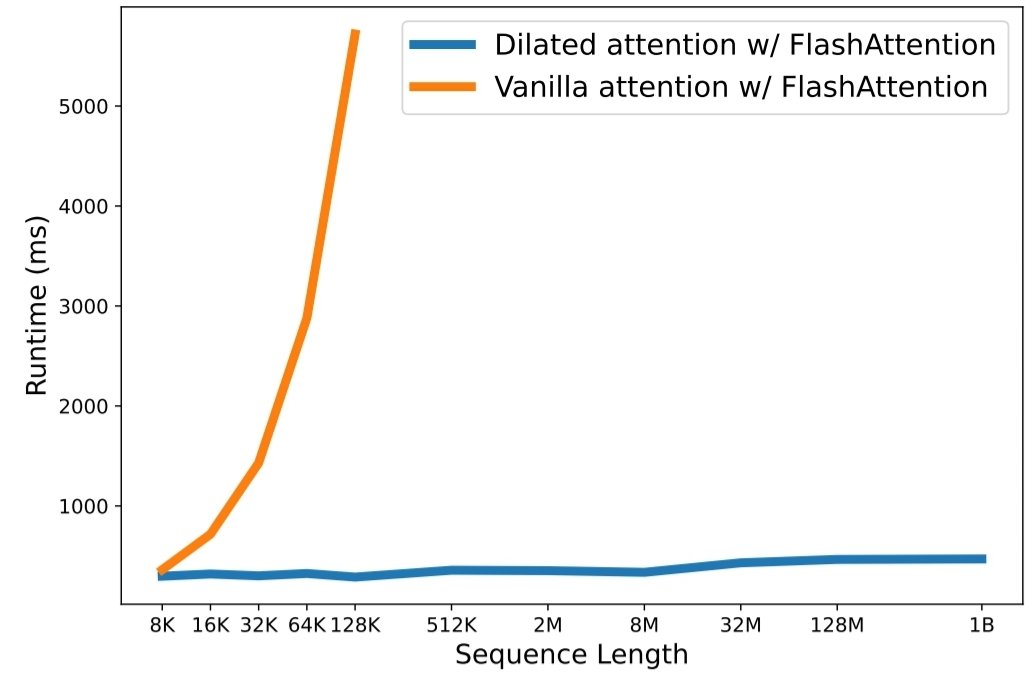




This is an open source implementation for the paper LongNet: Scaling Transformers to 1,000,000,000 Tokens by Jiayu Ding, Shuming Ma, Li Dong, Xingxing Zhang, Shaohan Huang, Wenhui Wang, Furu Wei. The LongNet is a Transformer variant designed to scale sequence length up to more than 1 billion tokens without sacrificing performance on shorter sequences.
pip install longnet
Once you have installed LongNet, you can use the DilatedAttention class as follows:
import torch
from long_net import DilatedAttention


# model config
dim = 512
heads = 8
dilation_rate = 2
segment_size = 64

# input data
batch_size = 32
seq_len = 8192


# create model and data
model = DilatedAttention(dim, heads, dilation_rate, segment_size, qk_norm=True)
x = torch.randn((batch_size, seq_len, dim))

output = model(x)
print(output)
LongNetTransformerA fully ready to train transformer model with dilated transformer blocks with Feedforwards with layernorm, SWIGLU, and a parallel transformer block
import torch
from long_net.model import LongNetTransformer

longnet = LongNetTransformer(
    num_tokens=20000,
    dim=512,
    depth=6,
    dim_head=64,
    heads=8,
    ff_mult=4,
)

tokens = torch.randint(0, 20000, (1, 512))
logits = longnet(tokens)
print(logits)
python3 train.pyScaling sequence length has become a critical bottleneck in the era of large language models. However, existing methods struggle with either computational complexity or model expressivity, rendering the maximum sequence length restricted. In this paper, they introduce LongNet, a Transformer variant that can scale sequence length to more than 1 billion tokens, without sacrificing the performance on shorter sequences. Specifically, they propose dilated attention, which expands the attentive field exponentially as the distance grows.
LongNet has significant advantages:
Experiment results demonstrate that LongNet yields strong performance on both long-sequence modeling and general language tasks. Their work opens up new possibilities for modeling very long sequences, e.g., treating a whole corpus or even the entire Internet as a sequence.
@inproceedings{ding2023longnet,
  title={LongNet: Scaling Transformers to 1,000,000,000 Tokens},
  author={Ding, Jiayu and Ma, Shuming and Dong, Li and Zhang, Xingxing and Huang, Shaohan and Wang, Wenhui and Wei, Furu},
  booktitle={Proceedings of the 10th International Conference on Learning Representations},
  year={2023}
}
342 followers · starred Jul 2023
55 followers · starred Jul 2023
543 followers · starred Sep 2026
81 followers · starred Nov 2024
Implementation of plug in and play Attention from "LongNet: Scaling Transformers to 1,000,000,000 Tokens"
See the code
This is an open source implementation for the paper LongNet: Scaling Transformers to 1,000,000,000 Tokens by Jiayu Ding, Shuming Ma, Li Dong, Xingxing Zhang, Shaohan Huang, Wenhui Wang, Furu Wei. The LongNet is a Transformer variant designed to scale sequence length up to more than 1 billion tokens without sacrificing performance on shorter sequences.
pip install longnet
Once you have installed LongNet, you can use the DilatedAttention class as follows:
import torch
from long_net import DilatedAttention


# model config
dim = 512
heads = 8
dilation_rate = 2
segment_size = 64

# input data
batch_size = 32
seq_len = 8192


# create model and data
model = DilatedAttention(dim, heads, dilation_rate, segment_size, qk_norm=True)
x = torch.randn((batch_size, seq_len, dim))

output = model(x)
print(output)
LongNetTransformerA fully ready to train transformer model with dilated transformer blocks with Feedforwards with layernorm, SWIGLU, and a parallel transformer block
import torch
from long_net.model import LongNetTransformer

longnet = LongNetTransformer(
    num_tokens=20000,
    dim=512,
    depth=6,
    dim_head=64,
    heads=8,
    ff_mult=4,
)

tokens = torch.randint(0, 20000, (1, 512))
logits = longnet(tokens)
print(logits)
python3 train.pyScaling sequence length has become a critical bottleneck in the era of large language models. However, existing methods struggle with either computational complexity or model expressivity, rendering the maximum sequence length restricted. In this paper, they introduce LongNet, a Transformer variant that can scale sequence length to more than 1 billion tokens, without sacrificing the performance on shorter sequences. Specifically, they propose dilated attention, which expands the attentive field exponentially as the distance grows.
LongNet has significant advantages:
Experiment results demonstrate that LongNet yields strong performance on both long-sequence modeling and general language tasks. Their work opens up new possibilities for modeling very long sequences, e.g., treating a whole corpus or even the entire Internet as a sequence.
@inproceedings{ding2023longnet,
  title={LongNet: Scaling Transformers to 1,000,000,000 Tokens},
  author={Ding, Jiayu and Ma, Shuming and Dong, Li and Zhang, Xingxing and Huang, Shaohan and Wang, Wenhui and Wei, Furu},
  booktitle={Proceedings of the 10th International Conference on Learning Representations},
  year={2023}
}
342 followers · starred Jul 2023
55 followers · starred Jul 2023
543 followers · starred Sep 2026
81 followers · starred Nov 2024