Help individuals and teams understand their prompting habits and improve how they work with AI coding agents. Get specific insights into prompt clarity, context, rework, outcomes and wasted effort, plus security flags. Bring your own LLM, no SaaS.
See the code


Understand your prompting habits and get specific insights to improve how you work with AI coding agents. Session Intelligence helps individuals and teams see where prompts lack context, why sessions need repeated corrections, what went well, and where time or tokens were wasted. It also flags exposed secrets and personal data. Bring your own LLM; no Session Intelligence SaaS or account is required.
Choose your path:
The workflow is collect → analyze → review → improve. Pair this engine with Agent Desk to browse your local sessions and use its local-session-extractor package to extract them into a common format. Agent Desk collects and displays sessions; Session Intelligence analyzes them.
For analysis you need Go 1.25 or newer, Docker, and a Gemini API key. To collect local transcripts with the companion extractor, you also need macOS and Node 24 or newer. If you already have a transcript in the engine's format, skip step 2. You can also try the sample offline without a key or Docker.
git clone https://github.com/tetriz-ai/session-intelligence.git
cd session-intelligence
You do not need to find each tool's hidden session files yourself. Once Agent Desk's local-session-extractor v0.1.0 release is published with its local-session-extractor-0.1.0.tgz asset, install that release tarball, scan, and list the sessions it found. The commands below require that release asset to be available; if it is not yet published, use the offline sample or supply an existing transcript in the engine's format.
npm install --prefix /tmp/session-intelligence-extractor "https://github.com/tetriz-ai/agent-desk/releases/download/local-session-extractor-v0.1.0/local-session-extractor-0.1.0.tgz"
/tmp/session-intelligence-extractor/node_modules/.bin/local-session-extractor scan
/tmp/session-intelligence-extractor/node_modules/.bin/local-session-extractor list
If Agent Desk is private, sign in with gh auth login using an account with repository access, then download and install the release asset locally:
gh release download local-session-extractor-v0.1.0 --repo tetriz-ai/agent-desk \
  --pattern 'local-session-extractor-0.1.0.tgz' --dir /tmp/session-intelligence-extractor-release
npm install --prefix /tmp/session-intelligence-extractor /tmp/session-intelligence-extractor-release/local-session-extractor-0.1.0.tgz
Then run the same scan and list commands above.
Pick a source and session ID from the list. For example, replace YOUR_SESSION_ID with a Codex session ID:
/tmp/session-intelligence-extractor/node_modules/.bin/local-session-extractor show codex -- YOUR_SESSION_ID > extracted-session.json
No conversion needed. The engine reads the extractor's record as it is — what local-session-extractor show prints, one line of its export, or one of its store rows — and keeps every message with its metadata, the session metadata, and the session events and their coverage. Pass the extracted file straight to the analysis CLI with no adapter step. A multi-session export --out sessions.jsonl has one record per line; pass one line at a time, not the whole JSONL file.
For Claude Code, use show claude-code -- YOUR_SESSION_ID; the -- also handles IDs starting with a dash. Other source names are cursor, copilot, kiro and antigravity. To browse visually, install Agent Desk. The commands here use the standalone extractor and its own store, so they work without the desktop app.
Already have a transcript? Use examples/transcript.sample.json as the input template, with ordered user and assistant messages from your real session. Save it as transcript.json. Native Claude/Codex JSONL files, Cursor databases, and plain-text chat exports need conversion first.
The bundled reference-llm service uses Gemini. Replace your-gemini-api-key with your own key:
GEMINI_API_KEY=your-gemini-api-key docker compose up -d --build --wait
The Go CLI sends the transcript to your local service, which sends it to Gemini for analysis. Using your own key does not make Gemini inference offline. To use another model, see Use a different model.
The Compose stack also starts Postgres, although the single-session CLI does not use it. If host port 5432 or 8000 is already in use, remap it with a docker-compose.override.yml.
go run ./cmd/analyze-real --url http://localhost:8000 extracted-session.json > analysis.json
Open analysis.json to read the verdict, turn and phase judgments, measured usage, and security flags. To check the setup with the bundled sample instead:
go run ./cmd/analyze-real --url http://localhost:8000 examples/transcript.sample.json > sample-analysis.json
Run docker compose down when you are done. Each analysis makes calls using your key and incurs your provider's usage charges.
The output is a single analyze.Analysis JSON object. A trimmed example — a session verdict, one phase with a went_wrong and a friction_cause, one judged turn, and one security flag — is in examples/analysis.sample.json:
{
  "session_id": "sample-session",
  "ide_type": "CLAUDE_CODE",
  "disposition": "PRODUCED",
  "verdict": {
    "underlying_goal": "Configure and wire payments client to provider API using environment secrets and preserved backoff retries.",
    "goal_is_coding_work": true,
    "goal_achieved": "SOMEWHAT",
    "smoothness": "ROUGH",
    "friction_cause": "PROMPT",
    "score_overall": 3,
    "score_clarity": 4
  },
  "phases": [
    {
      "ordinal": 0,
      "theme": "CREATION",
      "objective_met": "PARTIALLY_MET",
      "friction_cause": "PROMPT",
      "went_well": ["Agent asked clarifying questions when info was missing"],
      "went_wrong": ["Prompt 1 leaked live API credentials directly in chat", "Agent hardcoded credentials and broke existing backoff logic, needing a correction round-trip"]
    }
  ],
  "turns": [
    {
      "prompt_index": 1,
      "prompt_type": "CREATION",
      "security_issues": [
        { "type": "api-key-leak", "severity": "CRITICAL", "note": "Live API key pasted directly into prompt." }
      ]
    }
  ],
  "security_flags": [
    { "type": "api-key-leak", "severity": "critical", "occurrences": ["Live API key pasted directly into prompt."] }
  ]
}
Enum-valued fields render as their short upper-snake names (an unresolved signal is the empty string); the sample file carries the full field set.
The engine analyzes the normalized Conversation format, rather than reading vendor files directly. Source support comes from Agent Desk v0.1.0 / local-session-extractor v0.1.0, on macOS:
| Tool (extractor reader version) | CLI / IDE / desktop surfaces read by the companion extractor | Formats covered |
|---|---|---|
| Codex (v2) | CLI, VS Code extension, Codex desktop app | Shared .codex rollout JSONL and state_5.sqlite; the reader documents the v0.118+ rollout shape and skips legacy files without a type envelope |
| Claude (v1) | Claude Code CLI, VS Code and desktop entry points; Claude desktop Cowork agent mode | .claude/projects JSONL and Cowork audit.jsonl stores |
| Kiro (v1) | CLI and IDE/desktop | CLI session.json + messages.jsonl, current IDE session format, and legacy desktop JSON history |
| Cursor (v2) | Desktop IDE and cursor-agent CLI | IDE conversation databases/transcripts and CLI ~/.cursor/chats store.db + meta.json |
| GitHub Copilot (v2) | CLI, VS Code / VS Code Insiders, JetBrains IDEs | CLI events.jsonl, VS Code JSONL and legacy JSON chat sessions, JetBrains Nitrite/H2 chat databases |
| Antigravity (v1) | Desktop IDE | Local session artifacts; full conversations depend on the running local server |
Vendor release ranges are not certified. Except for the Codex format observation above, the companion project does not publish minimum/maximum supported vendor releases. The version beside each tool is the extractor's own reader code version, not a vendor app version. These readers cover the listed file layouts; a newer vendor release can change them. Ordinary Claude desktop chat is not the Cowork/Claude Code agent transcript covered here.
Check the installed extractor with local-session-extractor capabilities. For source locations, see its reference; the source readers define the formats covered. This engine does not require you to install or run the originating IDE once you have a normalized transcript.
Use the analysis to choose a concrete change for your next session:
| Look at | What you can learn | What to try next |
|---|---|---|
verdict.score_clarity, score_specificity, score_context_provision, score_completeness | Whether your prompts explain the goal, constraints and context clearly | Include the relevant files, expected behavior and acceptance criteria in your opening prompt |
turns[].prompt_objective_met, failure_class, waste_cause | Which exchanges missed their objective and where rework arose | Find the affected prompt and supply the missing constraint or split the task into smaller steps |
phases[].went_well, went_wrong, friction_cause | Specific strengths and problems at each stage of the work | Repeat the approaches that worked and change the instructions at the stage that stalled |
verdict.goal_achieved, smoothness, token_efficiency; measured | Whether the session reached its goal and how much effort it took | Compare similar tasks over time to see whether your changes help |
security_flags and per-turn security_issues | Exposed API keys, database credentials or personal data | Locate the affected exchange and address the exposure |
The CLI returns structured JSON; it does not provide a dashboard or automatically track habits across sessions. Review several analyses to spot recurring patterns. Scores are model judgments, and usage metrics depend on what the transcript contains. Optional round-trip fault scoring requires a custom detector; the bundled placeholder is off by default. See Limitations for the exact boundaries.
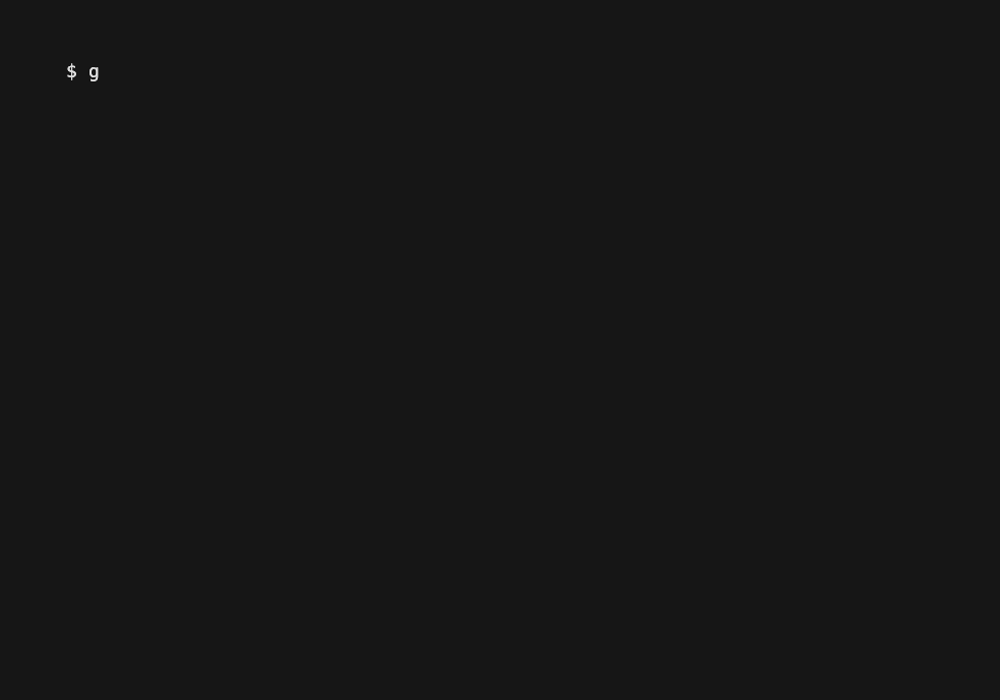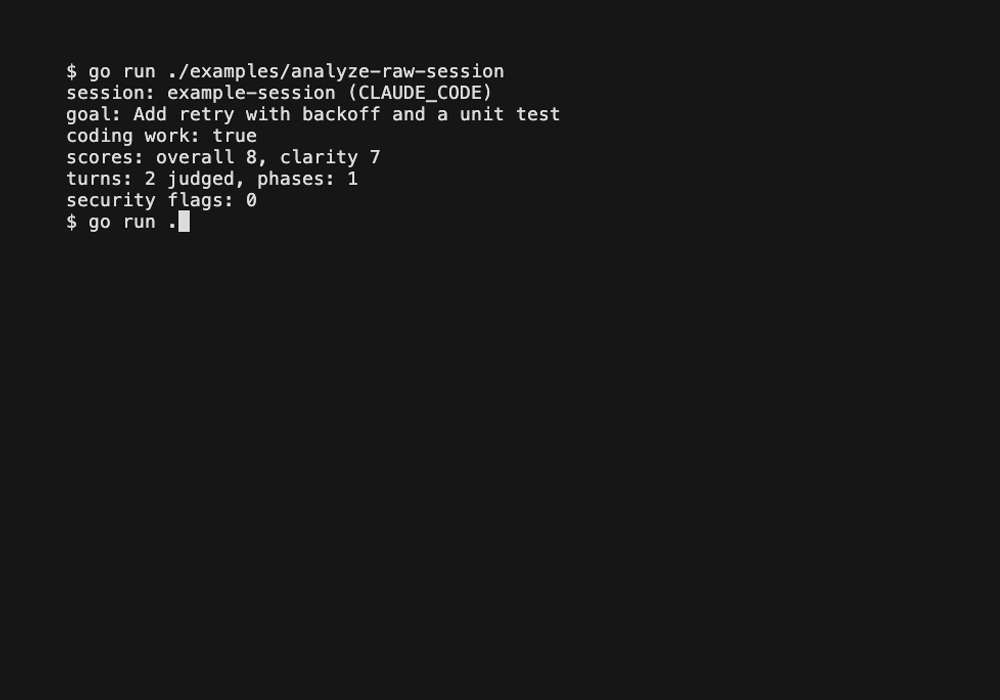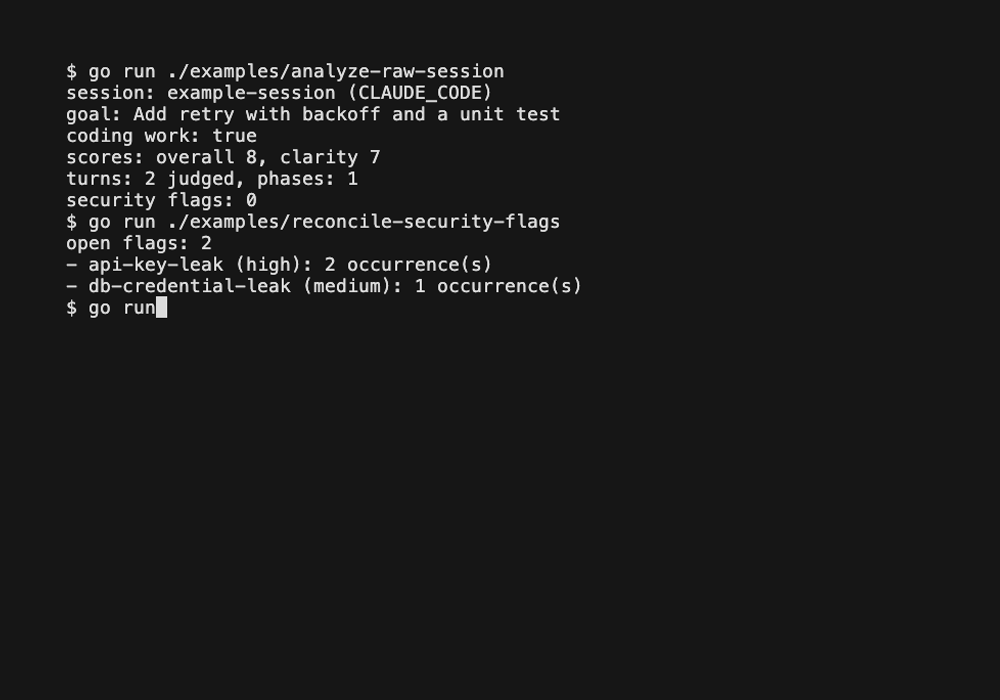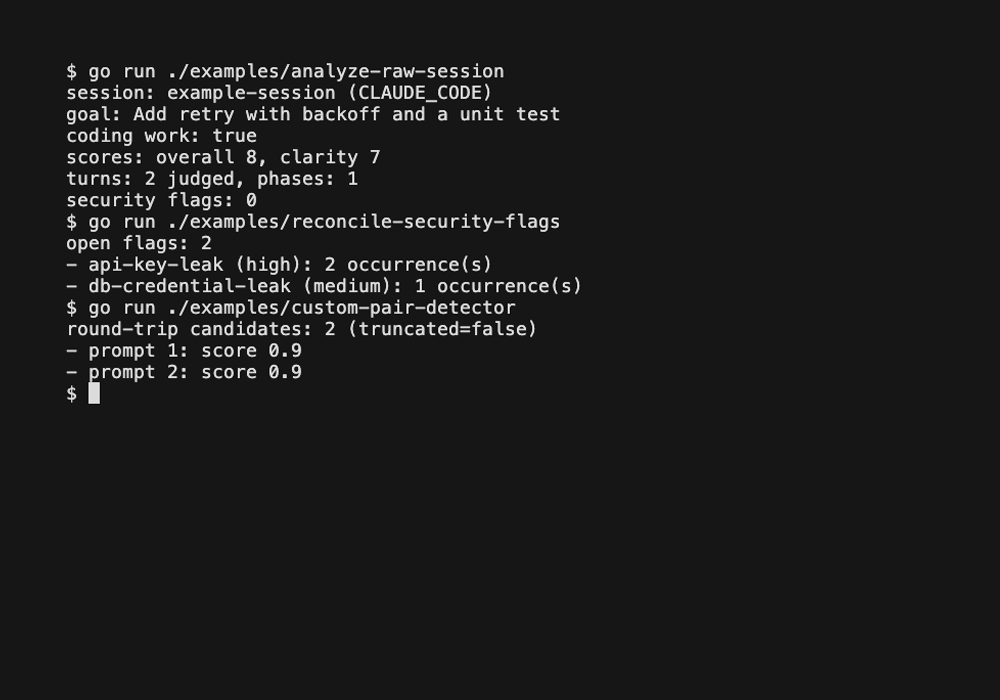
One example analyzes a built-in session with a fake model, so it needs no key and no Docker:
go run ./examples/analyze-raw-session
session: example-session (CLAUDE_CODE)
goal: Add retry with backoff and a unit test
coding work: true
scores: overall 8, clarity 7
turns: 2 judged, phases: 1
security flags: 0
To compile everything and run the offline suite:
go build ./...     # compile every package
go test ./...      # unit suites run offline; DAO/e2e tests skip without POSTGRES_TEST_DSN
This uses a fake model to demonstrate the output; it does not evaluate your own prompting. Every runnable example is listed in examples/README.md.
Use this path when you want structured session analysis in your own application. The packages accept your model and storage dependencies explicitly.
To embed Session Intelligence in your own product, pick the entry point that matches what you have.
| You have | Use | Example |
|---|---|---|
| one transcript and your own key, and want its analysis | analyze.AnalyzeSession | analyze-raw-session |
| detected security issues to turn into flags | security.Reconciler.ReconcileOpenFlags | reconcile-security-flags |
| your own round-trip scoring to plug in | analyze.RoundTripDetector | custom-pair-detector |
| a backlog of raw records to run end-to-end | SessionAnalysisProcessor.ProcessFlat | Running the full pipeline |
Every entry point is package-level Go, and each dependency is passed in as an interface. Importing the engine has no global side effects: it logs through a no-op logger until you call analyze.SetLogger, and registers no Prometheus metrics until you call analyze.RegisterMetrics.
These are the supported public import paths — the API contract:
| Import path | What it gives you |
|---|---|
github.com/tetriz-ai/session-intelligence/analyze | the main entry: AnalyzeSession, ParseConversation, the Provider and RoundTripDetector interfaces, and the Err* sentinels |
github.com/tetriz-ai/session-intelligence/security | Reconciler and the FlagStore interface for turning detected issues into open security flags |
github.com/tetriz-ai/session-intelligence/dao/model | the flag and record types (SecurityFlag, …) that security reads and writes |
github.com/tetriz-ai/session-intelligence/gen/sessionintelligence/v1 | the generated Conversation proto and its companions |
Everything under github.com/tetriz-ai/session-intelligence/internal/ is implementation detail — not part of the API contract, and may change without notice. Do not import it.
When: you have a single transcript and want its structured analysis without standing up Postgres or the batch pipeline. AnalyzeSession runs the spine, then the read, evidence and discard passes, over one in-memory Conversation, and returns a clean Analysis. It does no database or S3 access, so the only I/O is your Provider's LLM calls.
conv, err := analyze.ParseConversation(transcriptJSON) // or build *analyze.Conversation directly
if err != nil { /* ... */ }

analysis, err := analyze.AnalyzeSession(ctx, conv, analyze.Options{
    Provider: analyze.NewReferenceLLMProvider("http://localhost:8000"), // or your own Provider
})
if err != nil { /* ... */ }

fmt.Println(analysis.Verdict.UnderlyingGoal, len(analysis.Turns), len(analysis.SecurityFlags))
The analyze-raw-session example runs this end-to-end offline with a fake Provider. The input Conversation is the protojson encoding of sessionintelligence.v1.Conversation — an object with ide_type, prompts and optional session_events — documented in proto/sessionintelligence/v1/conversation.proto, with a ready sample at examples/transcript.sample.json.
Remember: the call is all-or-nothing, so a failed evidence or discard pass fails the whole call rather than returning a partial verdict. See Reference for the inputs it rejects before any provider call.
The engine is not tied to Gemini. The bundled reference service calls Gemini through the google-genai SDK, in reference-llm/app/llm/providers/gemini.py. You can run against any provider in one of two ways.
analyze.Provider — one GenerateContent method — and pass it in Options. The engine then calls your model directly, with no reference-llm at all.reference-llm/app/llm/providers/: implement the LLMProvider base class from base.py, then wire it into TenantProviderFactory in tenant_provider_factory.py beside the Gemini one.When: a pass found security-layer issues on a record and you want the open flags for it. The complete program is in reconcile-security-flags, and runs offline:
go run ./examples/reconcile-security-flags
open flags: 2
- api-key-leak (high): 2 occurrence(s)
- db-credential-leak (medium): 1 occurrence(s)
Remember: a non-security slug is ignored rather than flagged, and each excerpt is masked as a backstop, not as redaction.
When: you want your own round-trip scoring in place of the bundled placeholder. The complete program is in custom-pair-detector: it implements analyze.RoundTripDetector and passes it through Options. It runs offline:
go run ./examples/custom-pair-detector
round-trip candidates: 2 (truncated=false)
- prompt 1: score 0.9
- prompt 2: score 0.9
Remember: return a non-nil empty result when no pairs are supplied, and set Truncated when the pairs overflow the ceiling.
The full engine reads raw records and persists analyses, so it needs Postgres. Two runs exercise it. The first is the CI acceptance gate and needs no key or Docker: it feeds a recorded fixture through a fake LLMProducer and a placeholder detector, and asserts it persists the session analysis with its turn, phase and state rows plus any security_flags.
createdb session_intelligence_test
psql -d session_intelligence_test -f migrations/latest.sql
# Or, against the docker-compose Postgres:
#   POSTGRES_TEST_DSN="postgres://postgres:postgres@localhost:5432/session_intelligence"
POSTGRES_TEST_DSN="host=localhost port=5432 dbname=session_intelligence_test sslmode=disable" \
  go test ./... -run TestFullStackSessionAnalysisE2E -count=1
The second runs the same pipeline with real LLM calls, against Postgres and the bundled reference reference-llm brought up by docker-compose. The provider key is read only from the environment.
GEMINI_API_KEY=... ./scripts/e2e-real.sh
See the full API on pkg.go.dev and every runnable example in examples/README.md.
Under the hood it runs a deterministic spine over the transcript, then a three-pass LLM pipeline — a read pass, an evidence pass and a discard pass.
flowchart LR
  CONV[Conversation<br/>one transcript] --> SPINE
  subgraph ENGINE["analyze.AnalyzeSession"]
    direction LR
    SPINE[Spine<br/>parse · telemetry<br/>· round-trip pairs<br/>· phases] --> R[R — read<br/>turns + phases]
    R --> E[E — evidence]
    E --> D[D — discard]
    D --> OUT[Analysis]
  end
  R -.->|Provider| LLM[[your LLM<br/>or reference-llm]]
  E -.->|Provider| LLM
  D -.->|Provider| LLM
  SPINE -.->|RoundTripDetector| PD[[round-trip detector<br/>optional]]
dao package carries the batch pipeline's persistence and reference readers, with nothing aggregating on top.GEMINI_API_KEY from the environment at run time.AnalyzeSessionanalyze.ErrTranscriptTooLarge, and an empty or assistant-only one returns analyze.ErrNoTaggableTurns, both before any provider call.Analysis.SecurityFlags are reconciled to one flag per type at the highest severity, each excerpt masked. The per-turn Turns[].SecurityIssues are the raw readout, redacted but not deduped.ProcessFlatReconcileOpenFlagsapi-key-leak, db-credential-leak and pii-injection become flags. Any other slug is ignored.publishEvidence is true.RoundTripDetectorDetect returns an empty, non-nil result.Truncated is true when the pairs overflow the ceiling.Plain definitions of the terms this README uses.
| Term | What it means |
|---|---|
| Session (transcript) | One coding-agent conversation — an ordered list of the person's and the agent's messages. It is the engine's unit of analysis, encoded as a Conversation. |
| Spine | The deterministic first pass. Before any LLM call it parses the transcript, computes telemetry, finds round-trip pairs and segments phases. |
| Turn | One judged exchange — a prompt and the agent's response — scored for things like whether its objective was met and how helpful the agent was. |
| Phase | A group of turns that make up one stage of the work. |
| Verdict | The session-level judgment: the underlying goal, whether it was coding work, quality scores, and outcome signals like smoothness and speed. |
| Outcome | Whether the session reached its goal. |
| Round-trip | A back-and-forth where the person had to re-engage the agent on the same thing — a correction or a repeat, which signals rework. |
| Round-trip detector | The optional seam (analyze.RoundTripDetector) that scores round-trip pairs. A transparent placeholder ships, off by default. |
| Security flag | Sensitive data that leaked into the session: a leaked API key, a database credential, or personal data (PII). One of three types, each with a severity from low to critical. |
| Read / Evidence / Discard | The three LLM passes after the spine. Read judges the turns, phases and verdict. Evidence judges artifacts and round-trip fault. Discard judges wasted effort. |
| Provider | The seam that makes the LLM calls (analyze.Provider). The bundled reference uses Gemini, and you can supply your own. |
| Disposition | Whether the analysis is complete (PRODUCED) or partial (PARTIAL). |
Check these before you run the engine on data that matters. Each is pinned by a test.
TestReconcileMasksKnownSecretShapesInExcerpt. Sanitizing a finding is the finding's author's job, and a novel secret shape in a note will still be stored. Do not rely on this layer for redaction.security_flags, never silently dropped, and an unspecified severity is published at "medium". Pinned by security/reconcile_test.go.security/reconcile_test.go.ML_MODEL_INFERENCE__DETECTOR_ENABLED=false). With it on, the scores are not fitted, and the corpus-fitted model is not distributed.This is v0.1.0, a pre-1.0 release: the public API and the proto package path may change before v1.0. The project follows semantic versioning, and a change to an exported signature is breaking. The toolchain floor is Go 1.25.0.
go test ./... runs the unit suites offline. The DAO and pipeline end-to-end tests need Postgres and skip without POSTGRES_TEST_DSN. CONTRIBUTING.md shows the setup. Every example runs in CI through scripts/run-examples.sh.
Latest release
Releases this year
Help individuals and teams understand their prompting habits and improve how they work with AI coding agents. Get specific insights into prompt clarity, context, rework, outcomes and wasted effort, plus security flags. Bring your own LLM, no SaaS.
See the code
Understand your prompting habits and get specific insights to improve how you work with AI coding agents. Session Intelligence helps individuals and teams see where prompts lack context, why sessions need repeated corrections, what went well, and where time or tokens were wasted. It also flags exposed secrets and personal data. Bring your own LLM; no Session Intelligence SaaS or account is required.
Choose your path:
The workflow is collect → analyze → review → improve. Pair this engine with Agent Desk to browse your local sessions and use its local-session-extractor package to extract them into a common format. Agent Desk collects and displays sessions; Session Intelligence analyzes them.
For analysis you need Go 1.25 or newer, Docker, and a Gemini API key. To collect local transcripts with the companion extractor, you also need macOS and Node 24 or newer. If you already have a transcript in the engine's format, skip step 2. You can also try the sample offline without a key or Docker.
git clone https://github.com/tetriz-ai/session-intelligence.git
cd session-intelligence
You do not need to find each tool's hidden session files yourself. Once Agent Desk's local-session-extractor v0.1.0 release is published with its local-session-extractor-0.1.0.tgz asset, install that release tarball, scan, and list the sessions it found. The commands below require that release asset to be available; if it is not yet published, use the offline sample or supply an existing transcript in the engine's format.
npm install --prefix /tmp/session-intelligence-extractor "https://github.com/tetriz-ai/agent-desk/releases/download/local-session-extractor-v0.1.0/local-session-extractor-0.1.0.tgz"
/tmp/session-intelligence-extractor/node_modules/.bin/local-session-extractor scan
/tmp/session-intelligence-extractor/node_modules/.bin/local-session-extractor list
If Agent Desk is private, sign in with gh auth login using an account with repository access, then download and install the release asset locally:
gh release download local-session-extractor-v0.1.0 --repo tetriz-ai/agent-desk \
  --pattern 'local-session-extractor-0.1.0.tgz' --dir /tmp/session-intelligence-extractor-release
npm install --prefix /tmp/session-intelligence-extractor /tmp/session-intelligence-extractor-release/local-session-extractor-0.1.0.tgz
Then run the same scan and list commands above.
Pick a source and session ID from the list. For example, replace YOUR_SESSION_ID with a Codex session ID:
/tmp/session-intelligence-extractor/node_modules/.bin/local-session-extractor show codex -- YOUR_SESSION_ID > extracted-session.json
No conversion needed. The engine reads the extractor's record as it is — what local-session-extractor show prints, one line of its export, or one of its store rows — and keeps every message with its metadata, the session metadata, and the session events and their coverage. Pass the extracted file straight to the analysis CLI with no adapter step. A multi-session export --out sessions.jsonl has one record per line; pass one line at a time, not the whole JSONL file.
For Claude Code, use show claude-code -- YOUR_SESSION_ID; the -- also handles IDs starting with a dash. Other source names are cursor, copilot, kiro and antigravity. To browse visually, install Agent Desk. The commands here use the standalone extractor and its own store, so they work without the desktop app.
Already have a transcript? Use examples/transcript.sample.json as the input template, with ordered user and assistant messages from your real session. Save it as transcript.json. Native Claude/Codex JSONL files, Cursor databases, and plain-text chat exports need conversion first.
The bundled reference-llm service uses Gemini. Replace your-gemini-api-key with your own key:
GEMINI_API_KEY=your-gemini-api-key docker compose up -d --build --wait
The Go CLI sends the transcript to your local service, which sends it to Gemini for analysis. Using your own key does not make Gemini inference offline. To use another model, see Use a different model.
The Compose stack also starts Postgres, although the single-session CLI does not use it. If host port 5432 or 8000 is already in use, remap it with a docker-compose.override.yml.
go run ./cmd/analyze-real --url http://localhost:8000 extracted-session.json > analysis.json
Open analysis.json to read the verdict, turn and phase judgments, measured usage, and security flags. To check the setup with the bundled sample instead:
go run ./cmd/analyze-real --url http://localhost:8000 examples/transcript.sample.json > sample-analysis.json
Run docker compose down when you are done. Each analysis makes calls using your key and incurs your provider's usage charges.
The output is a single analyze.Analysis JSON object. A trimmed example — a session verdict, one phase with a went_wrong and a friction_cause, one judged turn, and one security flag — is in examples/analysis.sample.json:
{
  "session_id": "sample-session",
  "ide_type": "CLAUDE_CODE",
  "disposition": "PRODUCED",
  "verdict": {
    "underlying_goal": "Configure and wire payments client to provider API using environment secrets and preserved backoff retries.",
    "goal_is_coding_work": true,
    "goal_achieved": "SOMEWHAT",
    "smoothness": "ROUGH",
    "friction_cause": "PROMPT",
    "score_overall": 3,
    "score_clarity": 4
  },
  "phases": [
    {
      "ordinal": 0,
      "theme": "CREATION",
      "objective_met": "PARTIALLY_MET",
      "friction_cause": "PROMPT",
      "went_well": ["Agent asked clarifying questions when info was missing"],
      "went_wrong": ["Prompt 1 leaked live API credentials directly in chat", "Agent hardcoded credentials and broke existing backoff logic, needing a correction round-trip"]
    }
  ],
  "turns": [
    {
      "prompt_index": 1,
      "prompt_type": "CREATION",
      "security_issues": [
        { "type": "api-key-leak", "severity": "CRITICAL", "note": "Live API key pasted directly into prompt." }
      ]
    }
  ],
  "security_flags": [
    { "type": "api-key-leak", "severity": "critical", "occurrences": ["Live API key pasted directly into prompt."] }
  ]
}
Enum-valued fields render as their short upper-snake names (an unresolved signal is the empty string); the sample file carries the full field set.
The engine analyzes the normalized Conversation format, rather than reading vendor files directly. Source support comes from Agent Desk v0.1.0 / local-session-extractor v0.1.0, on macOS:
| Tool (extractor reader version) | CLI / IDE / desktop surfaces read by the companion extractor | Formats covered |
|---|---|---|
| Codex (v2) | CLI, VS Code extension, Codex desktop app | Shared .codex rollout JSONL and state_5.sqlite; the reader documents the v0.118+ rollout shape and skips legacy files without a type envelope |
| Claude (v1) | Claude Code CLI, VS Code and desktop entry points; Claude desktop Cowork agent mode | .claude/projects JSONL and Cowork audit.jsonl stores |
| Kiro (v1) | CLI and IDE/desktop | CLI session.json + messages.jsonl, current IDE session format, and legacy desktop JSON history |
| Cursor (v2) | Desktop IDE and cursor-agent CLI | IDE conversation databases/transcripts and CLI ~/.cursor/chats store.db + meta.json |
| GitHub Copilot (v2) | CLI, VS Code / VS Code Insiders, JetBrains IDEs | CLI events.jsonl, VS Code JSONL and legacy JSON chat sessions, JetBrains Nitrite/H2 chat databases |
| Antigravity (v1) | Desktop IDE | Local session artifacts; full conversations depend on the running local server |
Vendor release ranges are not certified. Except for the Codex format observation above, the companion project does not publish minimum/maximum supported vendor releases. The version beside each tool is the extractor's own reader code version, not a vendor app version. These readers cover the listed file layouts; a newer vendor release can change them. Ordinary Claude desktop chat is not the Cowork/Claude Code agent transcript covered here.
Check the installed extractor with local-session-extractor capabilities. For source locations, see its reference; the source readers define the formats covered. This engine does not require you to install or run the originating IDE once you have a normalized transcript.
Use the analysis to choose a concrete change for your next session:
| Look at | What you can learn | What to try next |
|---|---|---|
verdict.score_clarity, score_specificity, score_context_provision, score_completeness | Whether your prompts explain the goal, constraints and context clearly | Include the relevant files, expected behavior and acceptance criteria in your opening prompt |
turns[].prompt_objective_met, failure_class, waste_cause | Which exchanges missed their objective and where rework arose | Find the affected prompt and supply the missing constraint or split the task into smaller steps |
phases[].went_well, went_wrong, friction_cause | Specific strengths and problems at each stage of the work | Repeat the approaches that worked and change the instructions at the stage that stalled |
verdict.goal_achieved, smoothness, token_efficiency; measured | Whether the session reached its goal and how much effort it took | Compare similar tasks over time to see whether your changes help |
security_flags and per-turn security_issues | Exposed API keys, database credentials or personal data | Locate the affected exchange and address the exposure |
The CLI returns structured JSON; it does not provide a dashboard or automatically track habits across sessions. Review several analyses to spot recurring patterns. Scores are model judgments, and usage metrics depend on what the transcript contains. Optional round-trip fault scoring requires a custom detector; the bundled placeholder is off by default. See Limitations for the exact boundaries.
One example analyzes a built-in session with a fake model, so it needs no key and no Docker:
go run ./examples/analyze-raw-session
session: example-session (CLAUDE_CODE)
goal: Add retry with backoff and a unit test
coding work: true
scores: overall 8, clarity 7
turns: 2 judged, phases: 1
security flags: 0
To compile everything and run the offline suite:
go build ./...     # compile every package
go test ./...      # unit suites run offline; DAO/e2e tests skip without POSTGRES_TEST_DSN
This uses a fake model to demonstrate the output; it does not evaluate your own prompting. Every runnable example is listed in examples/README.md.
Use this path when you want structured session analysis in your own application. The packages accept your model and storage dependencies explicitly.
To embed Session Intelligence in your own product, pick the entry point that matches what you have.
| You have | Use | Example |
|---|---|---|
| one transcript and your own key, and want its analysis | analyze.AnalyzeSession | analyze-raw-session |
| detected security issues to turn into flags | security.Reconciler.ReconcileOpenFlags | reconcile-security-flags |
| your own round-trip scoring to plug in | analyze.RoundTripDetector | custom-pair-detector |
| a backlog of raw records to run end-to-end | SessionAnalysisProcessor.ProcessFlat | Running the full pipeline |
Every entry point is package-level Go, and each dependency is passed in as an interface. Importing the engine has no global side effects: it logs through a no-op logger until you call analyze.SetLogger, and registers no Prometheus metrics until you call analyze.RegisterMetrics.
These are the supported public import paths — the API contract:
| Import path | What it gives you |
|---|---|
github.com/tetriz-ai/session-intelligence/analyze | the main entry: AnalyzeSession, ParseConversation, the Provider and RoundTripDetector interfaces, and the Err* sentinels |
github.com/tetriz-ai/session-intelligence/security | Reconciler and the FlagStore interface for turning detected issues into open security flags |
github.com/tetriz-ai/session-intelligence/dao/model | the flag and record types (SecurityFlag, …) that security reads and writes |
github.com/tetriz-ai/session-intelligence/gen/sessionintelligence/v1 | the generated Conversation proto and its companions |
Everything under github.com/tetriz-ai/session-intelligence/internal/ is implementation detail — not part of the API contract, and may change without notice. Do not import it.
When: you have a single transcript and want its structured analysis without standing up Postgres or the batch pipeline. AnalyzeSession runs the spine, then the read, evidence and discard passes, over one in-memory Conversation, and returns a clean Analysis. It does no database or S3 access, so the only I/O is your Provider's LLM calls.
conv, err := analyze.ParseConversation(transcriptJSON) // or build *analyze.Conversation directly
if err != nil { /* ... */ }

analysis, err := analyze.AnalyzeSession(ctx, conv, analyze.Options{
    Provider: analyze.NewReferenceLLMProvider("http://localhost:8000"), // or your own Provider
})
if err != nil { /* ... */ }

fmt.Println(analysis.Verdict.UnderlyingGoal, len(analysis.Turns), len(analysis.SecurityFlags))
The analyze-raw-session example runs this end-to-end offline with a fake Provider. The input Conversation is the protojson encoding of sessionintelligence.v1.Conversation — an object with ide_type, prompts and optional session_events — documented in proto/sessionintelligence/v1/conversation.proto, with a ready sample at examples/transcript.sample.json.
Remember: the call is all-or-nothing, so a failed evidence or discard pass fails the whole call rather than returning a partial verdict. See Reference for the inputs it rejects before any provider call.
The engine is not tied to Gemini. The bundled reference service calls Gemini through the google-genai SDK, in reference-llm/app/llm/providers/gemini.py. You can run against any provider in one of two ways.
analyze.Provider — one GenerateContent method — and pass it in Options. The engine then calls your model directly, with no reference-llm at all.reference-llm/app/llm/providers/: implement the LLMProvider base class from base.py, then wire it into TenantProviderFactory in tenant_provider_factory.py beside the Gemini one.When: a pass found security-layer issues on a record and you want the open flags for it. The complete program is in reconcile-security-flags, and runs offline:
go run ./examples/reconcile-security-flags
open flags: 2
- api-key-leak (high): 2 occurrence(s)
- db-credential-leak (medium): 1 occurrence(s)
Remember: a non-security slug is ignored rather than flagged, and each excerpt is masked as a backstop, not as redaction.
When: you want your own round-trip scoring in place of the bundled placeholder. The complete program is in custom-pair-detector: it implements analyze.RoundTripDetector and passes it through Options. It runs offline:
go run ./examples/custom-pair-detector
round-trip candidates: 2 (truncated=false)
- prompt 1: score 0.9
- prompt 2: score 0.9
Remember: return a non-nil empty result when no pairs are supplied, and set Truncated when the pairs overflow the ceiling.
The full engine reads raw records and persists analyses, so it needs Postgres. Two runs exercise it. The first is the CI acceptance gate and needs no key or Docker: it feeds a recorded fixture through a fake LLMProducer and a placeholder detector, and asserts it persists the session analysis with its turn, phase and state rows plus any security_flags.
createdb session_intelligence_test
psql -d session_intelligence_test -f migrations/latest.sql
# Or, against the docker-compose Postgres:
#   POSTGRES_TEST_DSN="postgres://postgres:postgres@localhost:5432/session_intelligence"
POSTGRES_TEST_DSN="host=localhost port=5432 dbname=session_intelligence_test sslmode=disable" \
  go test ./... -run TestFullStackSessionAnalysisE2E -count=1
The second runs the same pipeline with real LLM calls, against Postgres and the bundled reference reference-llm brought up by docker-compose. The provider key is read only from the environment.
GEMINI_API_KEY=... ./scripts/e2e-real.sh
See the full API on pkg.go.dev and every runnable example in examples/README.md.
Under the hood it runs a deterministic spine over the transcript, then a three-pass LLM pipeline — a read pass, an evidence pass and a discard pass.
flowchart LR
  CONV[Conversation<br/>one transcript] --> SPINE
  subgraph ENGINE["analyze.AnalyzeSession"]
    direction LR
    SPINE[Spine<br/>parse · telemetry<br/>· round-trip pairs<br/>· phases] --> R[R — read<br/>turns + phases]
    R --> E[E — evidence]
    E --> D[D — discard]
    D --> OUT[Analysis]
  end
  R -.->|Provider| LLM[[your LLM<br/>or reference-llm]]
  E -.->|Provider| LLM
  D -.->|Provider| LLM
  SPINE -.->|RoundTripDetector| PD[[round-trip detector<br/>optional]]
dao package carries the batch pipeline's persistence and reference readers, with nothing aggregating on top.GEMINI_API_KEY from the environment at run time.AnalyzeSessionanalyze.ErrTranscriptTooLarge, and an empty or assistant-only one returns analyze.ErrNoTaggableTurns, both before any provider call.Analysis.SecurityFlags are reconciled to one flag per type at the highest severity, each excerpt masked. The per-turn Turns[].SecurityIssues are the raw readout, redacted but not deduped.ProcessFlatReconcileOpenFlagsapi-key-leak, db-credential-leak and pii-injection become flags. Any other slug is ignored.publishEvidence is true.RoundTripDetectorDetect returns an empty, non-nil result.Truncated is true when the pairs overflow the ceiling.Plain definitions of the terms this README uses.
| Term | What it means |
|---|---|
| Session (transcript) | One coding-agent conversation — an ordered list of the person's and the agent's messages. It is the engine's unit of analysis, encoded as a Conversation. |
| Spine | The deterministic first pass. Before any LLM call it parses the transcript, computes telemetry, finds round-trip pairs and segments phases. |
| Turn | One judged exchange — a prompt and the agent's response — scored for things like whether its objective was met and how helpful the agent was. |
| Phase | A group of turns that make up one stage of the work. |
| Verdict | The session-level judgment: the underlying goal, whether it was coding work, quality scores, and outcome signals like smoothness and speed. |
| Outcome | Whether the session reached its goal. |
| Round-trip | A back-and-forth where the person had to re-engage the agent on the same thing — a correction or a repeat, which signals rework. |
| Round-trip detector | The optional seam (analyze.RoundTripDetector) that scores round-trip pairs. A transparent placeholder ships, off by default. |
| Security flag | Sensitive data that leaked into the session: a leaked API key, a database credential, or personal data (PII). One of three types, each with a severity from low to critical. |
| Read / Evidence / Discard | The three LLM passes after the spine. Read judges the turns, phases and verdict. Evidence judges artifacts and round-trip fault. Discard judges wasted effort. |
| Provider | The seam that makes the LLM calls (analyze.Provider). The bundled reference uses Gemini, and you can supply your own. |
| Disposition | Whether the analysis is complete (PRODUCED) or partial (PARTIAL). |
Check these before you run the engine on data that matters. Each is pinned by a test.
TestReconcileMasksKnownSecretShapesInExcerpt. Sanitizing a finding is the finding's author's job, and a novel secret shape in a note will still be stored. Do not rely on this layer for redaction.security_flags, never silently dropped, and an unspecified severity is published at "medium". Pinned by security/reconcile_test.go.security/reconcile_test.go.ML_MODEL_INFERENCE__DETECTOR_ENABLED=false). With it on, the scores are not fitted, and the corpus-fitted model is not distributed.This is v0.1.0, a pre-1.0 release: the public API and the proto package path may change before v1.0. The project follows semantic versioning, and a change to an exported signature is breaking. The toolchain floor is Go 1.25.0.
go test ./... runs the unit suites offline. The DAO and pipeline end-to-end tests need Postgres and skip without POSTGRES_TEST_DSN. CONTRIBUTING.md shows the setup. Every example runs in CI through scripts/run-examples.sh.
Latest release
Releases this year



