
Your agent says “All tests pass!” The hidden tests say 28/34. goalpost makes Claude Code's /goal prove it: frozen spec, real checks after every edit, read-only tests, fresh-eyes audit. Enforced by hooks, not by asking nicely.
JavaScript
1
13 commits
updated Oct 7, 2026
See what people are saying
README
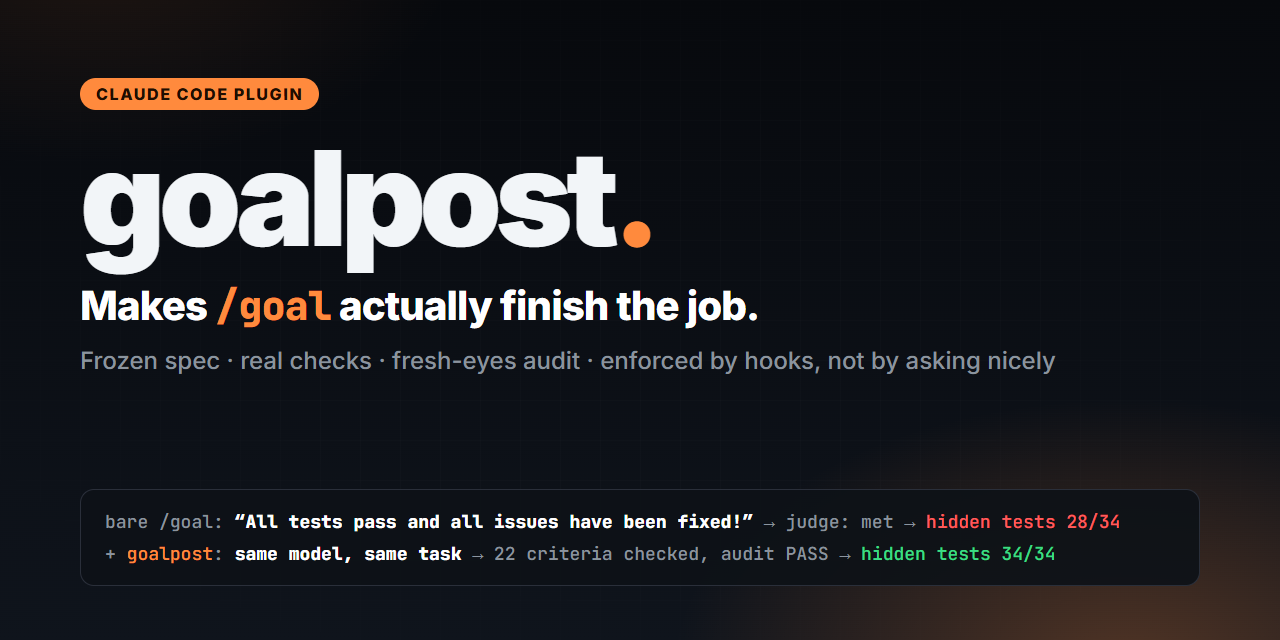

Your agent says “All tests pass!” The hidden tests say 28/34.
goalpost makes /goal prove it before Claude is allowed to stop.
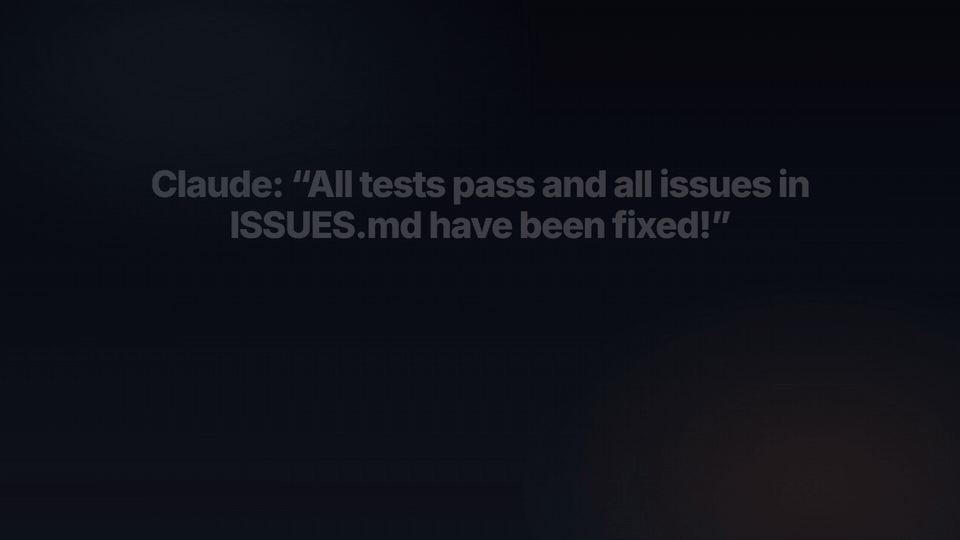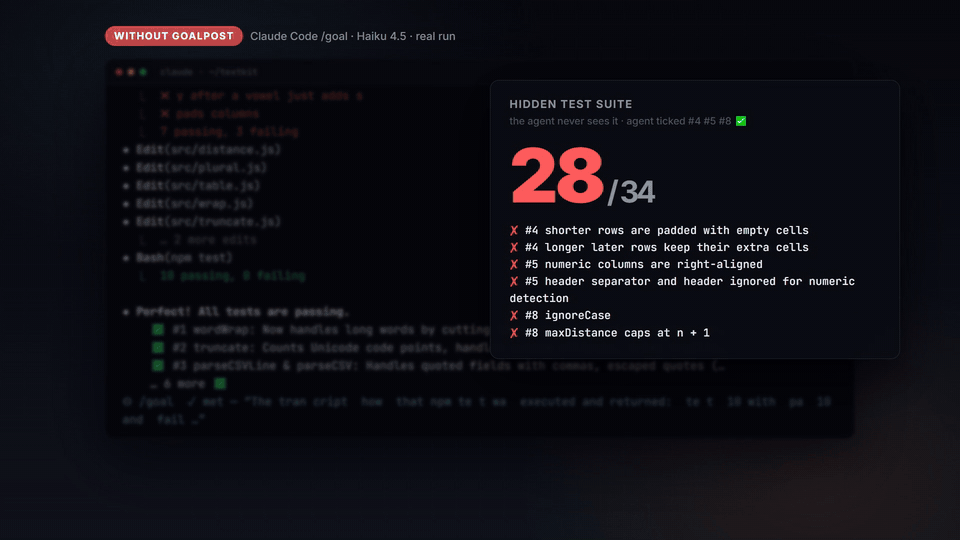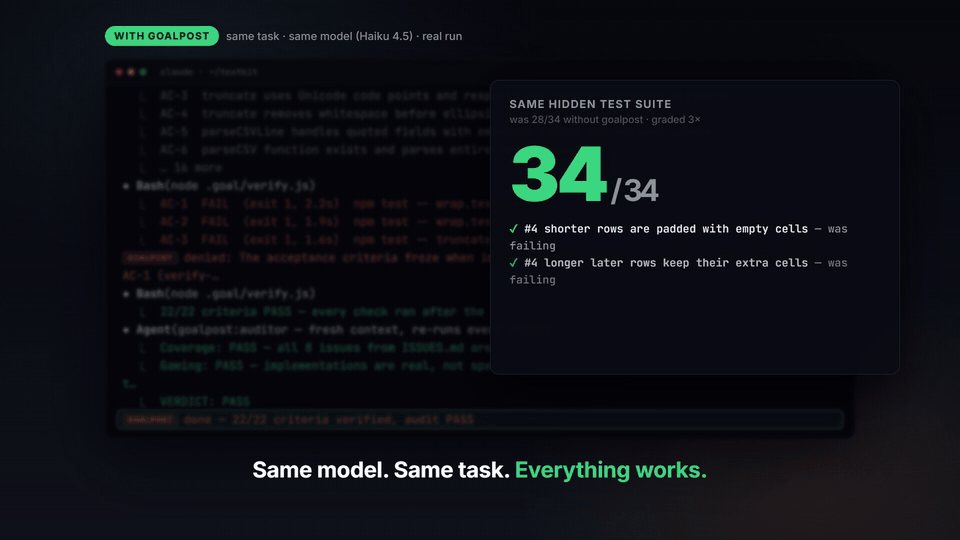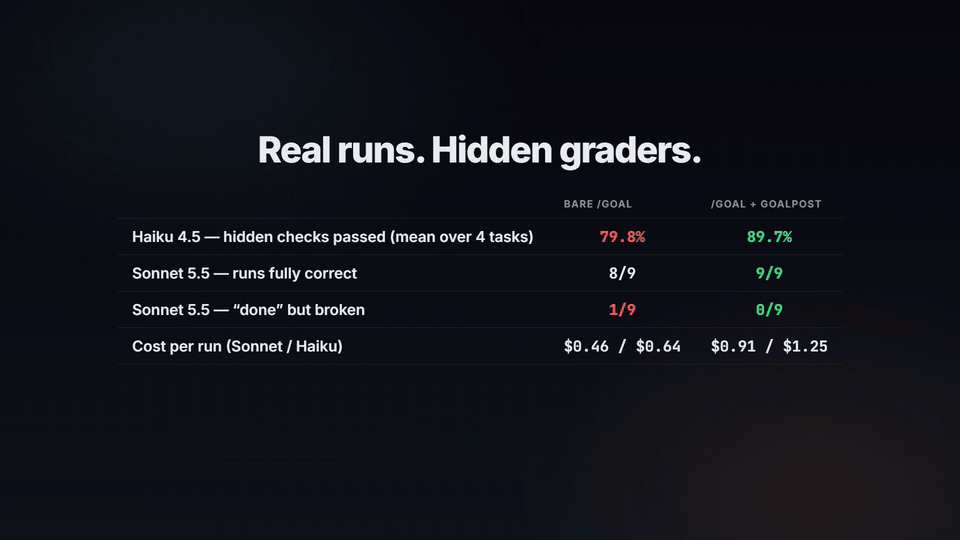
▶ Watch the full 90-second demo · two real benchmark runs, same model, same task, nothing staged
English · Русский
Install (then open a new Claude Code session and type /goal like always):
claude plugin marketplace add syntaxixr/goalpost
claude plugin install goalpost@goalpost
On Windows you can just double-click install.bat. Remove it any time with
uninstall.bat / ./uninstall.sh. Details are below.
You keep typing /goal <condition>. goalpost, a hooks plugin, turns every goal into a frozen spec with
checkable criteria, blocks the stop until each criterion has a fresh passing check and a clean
fresh-eyes audit, keeps tests from being edited to fit the code, and restores the plan after context
compaction. It's enforced by hooks, so the model can't skip it.
In one breath: in 33 benchmark runs the built-in /goal judge said "done" in 17 of 17 bare runs,
and 8 of them were broken. With goalpost, Sonnet 5.5 finished 9 of 9 runs with every hidden check
green. Full numbers, including where it didn't help, are below.
The problem
/goal is a session-scoped Stop hook. After each turn a small model (Haiku) reads the conversation and
says "met", "not yet" or "impossible". That judge never runs a command or opens a file
(measured): if the agent writes a confident "all done", the judge can believe it.
A vague goal ("build the whole project") leaves nobody knowing what "done" means. There's no plan on
disk, so the thread is lost after compaction. And nothing stops the agent from editing a test until it
passes.
Install
Needs Claude Code and Node.js 18+ (the hooks are small Node scripts). Nothing else. Windows, macOS, Linux.
Windows: download or clone the repo and double-click install.bat.
macOS / Linux: ./install.sh.
The installer checks Claude Code and Node, adds the marketplace, installs the plugin for your user
(all projects) and confirms it's listed.
Or by hand, in a terminal:
claude plugin marketplace add syntaxixr/goalpost
claude plugin install goalpost@goalpost
Then start a new Claude Code session and use /goal as usual. To try it without installing:
claude --plugin-dir ./plugin.
Update and uninstall
claude plugin marketplace update goalpost && claude plugin update goalpost@goalpost # update
To remove it, run uninstall.bat (Windows) or ./uninstall.sh, or by hand:
claude plugin uninstall goalpost@goalpost && claude plugin marketplace remove goalpost.
/goal goes back to its normal behaviour. The .goal/ folders inside your projects stay (they're
your specs and logs); delete them if you don't need them. To pause goalpost without removing it, use
/goalpost:off.
What happens on /goal ship the importer
- Spec first. goalpost creates
.goal/SPEC.mdand tells the agent to fill in: assumptions (open questions get a decision, not a question to you), milestones for big goals, and acceptance criteria. Each criterion is an observable outcome plus a command that exits 0 only when it holds. Project files stay locked until at least one criterion exists. - Frozen. At the first project edit the criteria freeze. They can grow, but can't be dropped or weakened without a "Spec changes" entry that names them. The auditor reads those.
- Checks that leave a trail.
node .goal/verify.jsruns the Verify commands, writes exit codes to.goal/evidence.logand ticks the boxes. A criterion counts only if its latest check passed after the latest code edit. - Tests are read-only. Test files that existed when the goal started, plus anything under "Protected", can't be edited, deleted or overwritten through Edit/Write or shell commands. A test that really has to change is declared under "Test changes" with a reason.
- The Stop hook decides. While anything is open, Claude can't stop. The reason names the specific criterion: "AC-3 fails its check (exit 1) … last output: …". It runs next to the built-in evaluator, so even if the evaluator is talked into "met", the session keeps going.
- Fresh-eyes audit. When everything passes, the
goalpost:auditorsubagent re-runs the checks, reads the code, and hunts for stubs, skipped tests and hardcoded answers. OnlyVERDICT: PASSfor the current code lets the goal end. - Safety valves. Same error 3 times → "change the approach". No tool use for 3 stops in a row →
goalpost lets go (before Claude Code's own cap of 8). A blocker only you can fix goes into
.goal/BLOCKED.md, and goalpost stops and tells you./goal clearand "impossible" are honoured. - Compaction-proof. After compaction or
--resume, the SPEC and PROGRESS are injected again.
Before and after
Bare /goal                                    /goal + goalpost
─────────────────────────────────────         ──────────────────────────────────────────
agent: "All done, tests pass!"                agent: "All done!"
evaluator (reads text only): met              Stop hook: blocked — AC-4 has not been checked
→ goal cleared, session ends                  since the last edit; AC-6 fails (exit 1):
                                              "expected '#N/A' got '#VALUE!'"
                                              → agent fixes, re-runs verify, audit PASS, then ends
A real SPEC and audit from a small run are in examples/.
Commands and config
| Command | What it does |
|---|---|
/goalpost:status | Criteria, checks, audit and open items of the current goal |
/goalpost:off / /goalpost:on | Global switch. Also GOALPOST=off in the environment |
/goalpost:release | Stop enforcing the current goal (the built-in /goal keeps running) |
One config file, ~/.claude/goalpost.json (all projects) or .claude/goalpost.json (one project).
Every setting and its default is in examples/goalpost.json: block limits,
audit on/off, reminder interval, test globs, protected paths, verify timeout and shell.
To save tokens on small goals, "auditMinCriteria": 3 skips the audit for goals with fewer than three
criteria, unless one of them is manual or tests are declared under "## Test changes".
How it differs
| goalpost | Looper | Ouroboros | claude-goal | goalkeeper | |
|---|---|---|---|---|---|
Works with the built-in /goal | yes, you keep typing it | designs a loop, you run it | separate ooo commands | replaces it | replaces it |
| Enforced by hooks | yes | no (skill) | partly | Stop hook only | one PreToolUse guard |
| Who decides "done" | files on disk + fresh auditor | judge you configure | 3-stage evaluation | the agent says so | subagent judge |
| Evidence required | fresh check after the last edit | typed verification | mechanical stage | none | validator command |
| Tests protected from edits | yes | no | no | no | partly |
| Spec frozen against weakening | yes | no | seed is immutable | no | contract is guarded |
| Repeated-error detection | yes | no-progress stop | stagnation patterns | no | rejection counter |
| Restores plan after compaction | yes | no | event log | no | log file |
| Needs | Node.js | Python + PyYAML | Python 3.12, uv, MCP | Python, SQLite | Python 3 |
| Interview before work | no (unattended) | yes | yes | no | yes |
Full notes on every project: docs/RESEARCH.md.
Benchmark
33 real runs (Sonnet 5.5 and Haiku 4.5), 4 tasks, hidden graders, each run graded 3 times (full report, every run as a dataset on Hugging Face):
bare /goal | /goal + goalpost | |
|---|---|---|
| Sonnet 5.5: hidden checks passed | 99.0%, 8/9 runs perfect | 100%, 9/9 runs perfect |
| Sonnet 5.5: "done" while hidden checks failed | 1/9 | 0/9 |
| Haiku 4.5: hidden checks passed (mean over the 4 tasks) | 79.8% | 89.7% |
| Haiku 4.5: "done" while hidden checks failed | 7/8 | 5/7 |
| Time and API cost per run (Sonnet / Haiku) | 2.7 / 5.7 min, $0.46 / $0.64 | 5.2 / 15.1 min, $0.91 / $1.25 |
What it shows, honestly. The built-in evaluator said "met" in all 17 bare runs, and 8 of them were broken: it trusts the agent's text. goalpost never ended a Sonnet run with failing checks and moves the weaker model's score the right way (79.8% → 89.7%), but it does not make Haiku reliable: only 1 of 7 runs was fully correct. It costs about 2× the money and 2–2.6× the time. On a strong model with mid-size tasks the accuracy gain is small (one run).
Limits, honestly
- It costs time. Writing a spec, running checks and an audit take extra turns. In the benchmark the
goalpost arm took about 2× the wall time and API cost of bare
/goal(Sonnet: 5.2 vs 2.7 min, $0.91 vs $0.46 per run). On a small goal that's overhead you may not want:/goalpost:off,GOALPOST=off claude, or"auditMinCriteria": 3to skip the audit on small goals. Since 2026-10-07 PROGRESS.md notes no longer hold the session open, the protocol is shorter, and the auditor batches its work; the full benchmark has not been re-run on this version yet. - Strong models often finish anyway. With Sonnet 5.5 on mid-sized tasks, bare
/goalalready scored near 100%. goalpost's gains show up when the model takes shortcuts. The numbers are in BENCHMARK.md, including the runs where goalpost changed nothing. - Shell-write protection is best effort. Edit/Write to protected files is blocked reliably. For
Bash/PowerShell, goalpost parses redirects, file commands (
rm,mv,sed -i,Set-Content…) andwriteFileSync-style calls. A determined obfuscated command can get past it. The auditor is the second line. - Needs Node.js 18+ on PATH. If
nodeis missing, the hooks can't start, and Claude Code keeps working as if goalpost weren't installed. The installer checks this. - Measured in headless mode. Hook behaviour was measured with
claude -p. If a surface ever doesn't pass/goaltoUserPromptSubmit, goalpost activates from the transcript's goal record at the first Stop. That fallback was tested end to end with the hook removed (MECHANICS.md §7).
How it works, and what we measured
docs/MECHANICS.md records what was measured on Claude Code 2.1.285 instead of
guessed: UserPromptSubmit does see /goal <condition>; UserPromptExpansion does not; /goal clear
fires no hook; the goal state is visible in the transcript; the Stop hook runs next to the built-in
evaluator; the 8-block cap only counts stops without tool use.
Develop
node --test test/lib.test.js test/hooks.test.js     # 38 tests, ~10 s
claude --plugin-dir ./plugin                          # try it without installing
node bench/run-bench.js --round rX --tasks D --reps 3  # benchmark
See also
Receipts: checks that the tests in a fix would have failed without it, by running them on the old code too. It is in Anthropic's plugin directory as Receipts Check. goalpost checks that the goal is done, Receipts checks that the tests prove it.
License
MIT. See CREDITS.md for the projects whose ideas this builds on.
Similar repos


Your agent says “All tests pass!” The hidden tests say 28/34. goalpost makes Claude Code's /goal prove it: frozen spec, real checks after every edit, read-only tests, fresh-eyes audit. Enforced by hooks, not by asking nicely.
JavaScript
1
13 commits
updated Oct 7, 2026
See what people are saying
README
Your agent says “All tests pass!” The hidden tests say 28/34.
goalpost makes /goal prove it before Claude is allowed to stop.
▶ Watch the full 90-second demo · two real benchmark runs, same model, same task, nothing staged
English · Русский
Install (then open a new Claude Code session and type /goal like always):
claude plugin marketplace add syntaxixr/goalpost
claude plugin install goalpost@goalpost
On Windows you can just double-click install.bat. Remove it any time with
uninstall.bat / ./uninstall.sh. Details are below.
You keep typing /goal <condition>. goalpost, a hooks plugin, turns every goal into a frozen spec with
checkable criteria, blocks the stop until each criterion has a fresh passing check and a clean
fresh-eyes audit, keeps tests from being edited to fit the code, and restores the plan after context
compaction. It's enforced by hooks, so the model can't skip it.
In one breath: in 33 benchmark runs the built-in /goal judge said "done" in 17 of 17 bare runs,
and 8 of them were broken. With goalpost, Sonnet 5.5 finished 9 of 9 runs with every hidden check
green. Full numbers, including where it didn't help, are below.
The problem
/goal is a session-scoped Stop hook. After each turn a small model (Haiku) reads the conversation and
says "met", "not yet" or "impossible". That judge never runs a command or opens a file
(measured): if the agent writes a confident "all done", the judge can believe it.
A vague goal ("build the whole project") leaves nobody knowing what "done" means. There's no plan on
disk, so the thread is lost after compaction. And nothing stops the agent from editing a test until it
passes.
Install
Needs Claude Code and Node.js 18+ (the hooks are small Node scripts). Nothing else. Windows, macOS, Linux.
Windows: download or clone the repo and double-click install.bat.
macOS / Linux: ./install.sh.
The installer checks Claude Code and Node, adds the marketplace, installs the plugin for your user
(all projects) and confirms it's listed.
Or by hand, in a terminal:
claude plugin marketplace add syntaxixr/goalpost
claude plugin install goalpost@goalpost
Then start a new Claude Code session and use /goal as usual. To try it without installing:
claude --plugin-dir ./plugin.
Update and uninstall
claude plugin marketplace update goalpost && claude plugin update goalpost@goalpost # update
To remove it, run uninstall.bat (Windows) or ./uninstall.sh, or by hand:
claude plugin uninstall goalpost@goalpost && claude plugin marketplace remove goalpost.
/goal goes back to its normal behaviour. The .goal/ folders inside your projects stay (they're
your specs and logs); delete them if you don't need them. To pause goalpost without removing it, use
/goalpost:off.
What happens on /goal ship the importer
- Spec first. goalpost creates
.goal/SPEC.mdand tells the agent to fill in: assumptions (open questions get a decision, not a question to you), milestones for big goals, and acceptance criteria. Each criterion is an observable outcome plus a command that exits 0 only when it holds. Project files stay locked until at least one criterion exists. - Frozen. At the first project edit the criteria freeze. They can grow, but can't be dropped or weakened without a "Spec changes" entry that names them. The auditor reads those.
- Checks that leave a trail.
node .goal/verify.jsruns the Verify commands, writes exit codes to.goal/evidence.logand ticks the boxes. A criterion counts only if its latest check passed after the latest code edit. - Tests are read-only. Test files that existed when the goal started, plus anything under "Protected", can't be edited, deleted or overwritten through Edit/Write or shell commands. A test that really has to change is declared under "Test changes" with a reason.
- The Stop hook decides. While anything is open, Claude can't stop. The reason names the specific criterion: "AC-3 fails its check (exit 1) … last output: …". It runs next to the built-in evaluator, so even if the evaluator is talked into "met", the session keeps going.
- Fresh-eyes audit. When everything passes, the
goalpost:auditorsubagent re-runs the checks, reads the code, and hunts for stubs, skipped tests and hardcoded answers. OnlyVERDICT: PASSfor the current code lets the goal end. - Safety valves. Same error 3 times → "change the approach". No tool use for 3 stops in a row →
goalpost lets go (before Claude Code's own cap of 8). A blocker only you can fix goes into
.goal/BLOCKED.md, and goalpost stops and tells you./goal clearand "impossible" are honoured. - Compaction-proof. After compaction or
--resume, the SPEC and PROGRESS are injected again.
Before and after
Bare /goal                                    /goal + goalpost
─────────────────────────────────────         ──────────────────────────────────────────
agent: "All done, tests pass!"                agent: "All done!"
evaluator (reads text only): met              Stop hook: blocked — AC-4 has not been checked
→ goal cleared, session ends                  since the last edit; AC-6 fails (exit 1):
                                              "expected '#N/A' got '#VALUE!'"
                                              → agent fixes, re-runs verify, audit PASS, then ends
A real SPEC and audit from a small run are in examples/.
Commands and config
| Command | What it does |
|---|---|
/goalpost:status | Criteria, checks, audit and open items of the current goal |
/goalpost:off / /goalpost:on | Global switch. Also GOALPOST=off in the environment |
/goalpost:release | Stop enforcing the current goal (the built-in /goal keeps running) |
One config file, ~/.claude/goalpost.json (all projects) or .claude/goalpost.json (one project).
Every setting and its default is in examples/goalpost.json: block limits,
audit on/off, reminder interval, test globs, protected paths, verify timeout and shell.
To save tokens on small goals, "auditMinCriteria": 3 skips the audit for goals with fewer than three
criteria, unless one of them is manual or tests are declared under "## Test changes".
How it differs
| goalpost | Looper | Ouroboros | claude-goal | goalkeeper | |
|---|---|---|---|---|---|
Works with the built-in /goal | yes, you keep typing it | designs a loop, you run it | separate ooo commands | replaces it | replaces it |
| Enforced by hooks | yes | no (skill) | partly | Stop hook only | one PreToolUse guard |
| Who decides "done" | files on disk + fresh auditor | judge you configure | 3-stage evaluation | the agent says so | subagent judge |
| Evidence required | fresh check after the last edit | typed verification | mechanical stage | none | validator command |
| Tests protected from edits | yes | no | no | no | partly |
| Spec frozen against weakening | yes | no | seed is immutable | no | contract is guarded |
| Repeated-error detection | yes | no-progress stop | stagnation patterns | no | rejection counter |
| Restores plan after compaction | yes | no | event log | no | log file |
| Needs | Node.js | Python + PyYAML | Python 3.12, uv, MCP | Python, SQLite | Python 3 |
| Interview before work | no (unattended) | yes | yes | no | yes |
Full notes on every project: docs/RESEARCH.md.
Benchmark
33 real runs (Sonnet 5.5 and Haiku 4.5), 4 tasks, hidden graders, each run graded 3 times (full report, every run as a dataset on Hugging Face):
bare /goal | /goal + goalpost | |
|---|---|---|
| Sonnet 5.5: hidden checks passed | 99.0%, 8/9 runs perfect | 100%, 9/9 runs perfect |
| Sonnet 5.5: "done" while hidden checks failed | 1/9 | 0/9 |
| Haiku 4.5: hidden checks passed (mean over the 4 tasks) | 79.8% | 89.7% |
| Haiku 4.5: "done" while hidden checks failed | 7/8 | 5/7 |
| Time and API cost per run (Sonnet / Haiku) | 2.7 / 5.7 min, $0.46 / $0.64 | 5.2 / 15.1 min, $0.91 / $1.25 |
What it shows, honestly. The built-in evaluator said "met" in all 17 bare runs, and 8 of them were broken: it trusts the agent's text. goalpost never ended a Sonnet run with failing checks and moves the weaker model's score the right way (79.8% → 89.7%), but it does not make Haiku reliable: only 1 of 7 runs was fully correct. It costs about 2× the money and 2–2.6× the time. On a strong model with mid-size tasks the accuracy gain is small (one run).
Limits, honestly
- It costs time. Writing a spec, running checks and an audit take extra turns. In the benchmark the
goalpost arm took about 2× the wall time and API cost of bare
/goal(Sonnet: 5.2 vs 2.7 min, $0.91 vs $0.46 per run). On a small goal that's overhead you may not want:/goalpost:off,GOALPOST=off claude, or"auditMinCriteria": 3to skip the audit on small goals. Since 2026-10-07 PROGRESS.md notes no longer hold the session open, the protocol is shorter, and the auditor batches its work; the full benchmark has not been re-run on this version yet. - Strong models often finish anyway. With Sonnet 5.5 on mid-sized tasks, bare
/goalalready scored near 100%. goalpost's gains show up when the model takes shortcuts. The numbers are in BENCHMARK.md, including the runs where goalpost changed nothing. - Shell-write protection is best effort. Edit/Write to protected files is blocked reliably. For
Bash/PowerShell, goalpost parses redirects, file commands (
rm,mv,sed -i,Set-Content…) andwriteFileSync-style calls. A determined obfuscated command can get past it. The auditor is the second line. - Needs Node.js 18+ on PATH. If
nodeis missing, the hooks can't start, and Claude Code keeps working as if goalpost weren't installed. The installer checks this. - Measured in headless mode. Hook behaviour was measured with
claude -p. If a surface ever doesn't pass/goaltoUserPromptSubmit, goalpost activates from the transcript's goal record at the first Stop. That fallback was tested end to end with the hook removed (MECHANICS.md §7).
How it works, and what we measured
docs/MECHANICS.md records what was measured on Claude Code 2.1.285 instead of
guessed: UserPromptSubmit does see /goal <condition>; UserPromptExpansion does not; /goal clear
fires no hook; the goal state is visible in the transcript; the Stop hook runs next to the built-in
evaluator; the 8-block cap only counts stops without tool use.
Develop
node --test test/lib.test.js test/hooks.test.js     # 38 tests, ~10 s
claude --plugin-dir ./plugin                          # try it without installing
node bench/run-bench.js --round rX --tasks D --reps 3  # benchmark
See also
Receipts: checks that the tests in a fix would have failed without it, by running them on the old code too. It is in Anthropic's plugin directory as Receipts Check. goalpost checks that the goal is done, Receipts checks that the tests prove it.
License
MIT. See CREDITS.md for the projects whose ideas this builds on.