
ArcticInference: vLLM plugin for high-throughput, low-latency inference
Python
486
187 commits
updated Sep 23, 2026
README

| Documentation | Blog | Paper |
Latest news
- [2025/08] - Fast Reasoning on GPT-OSS with Speculative Decoding and Arctic Inference
- [2025/05] - Arctic Inference w. Shift Parallelism: The Fastest Open Source Inference System for Enterprise AI
- [2025/05] - Scaling vLLM for Embeddings: 16x Throughput and Cost Reduction
- [2025/05] - Fastest Speculative Decoding in vLLM with Arctic Inference and Arctic Training
- [2025/04] - Low-Latency and High-Throughput Inference for Long Context w. Sequence Parallelism (Ulysses)
Arctic Inference
Arctic Inference is an open-source vLLM plugin that brings Snowflake’s inference innovations to the community, delivering the fastest and most cost-effective open-source inference for LLMs and Embeddings.
Arctic Inference achieves high throughput and low latency through a wholistic set of inference optimizations:
Optimized LLM Inference
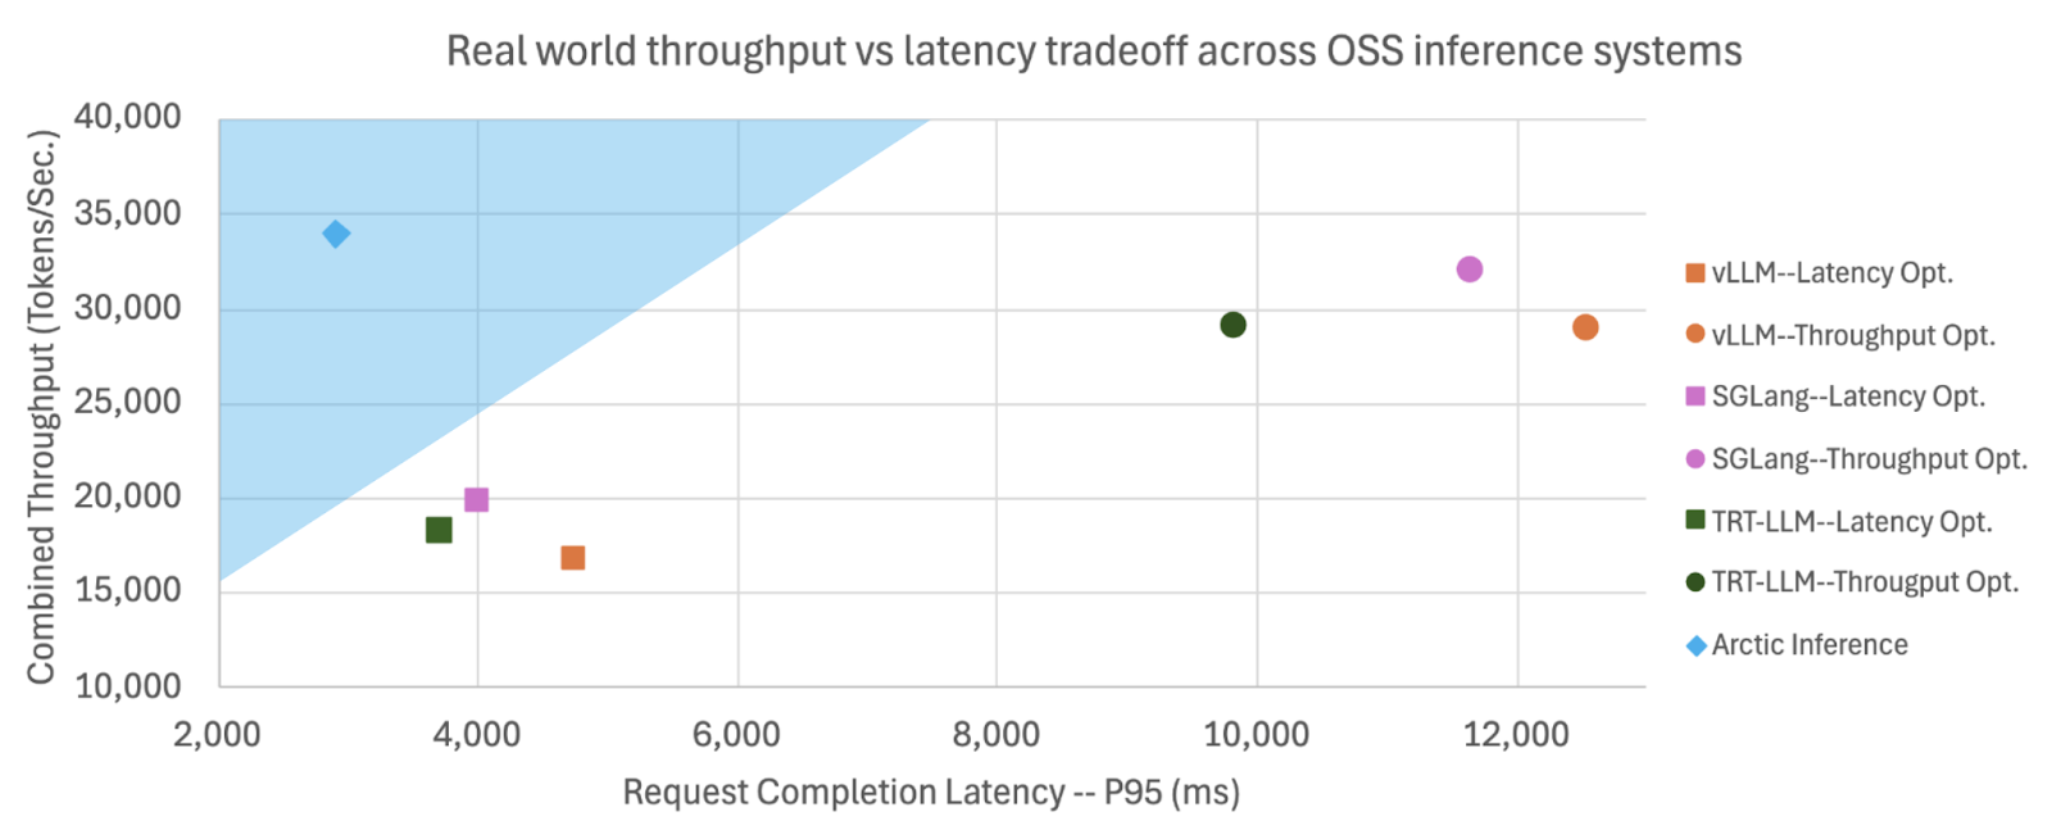
For real-world LLM workloads, a single deployment of Arctic Inference + vLLM achieves:
- 3.4x faster request completion and 1.06x higher throughput compared to the best throughput-optimized deployment (TP=1, DP=8)
- 1.7x higher throughput and 1.28x faster request completion compared to the best latency-optimized deployment (TP=8, DP=1)
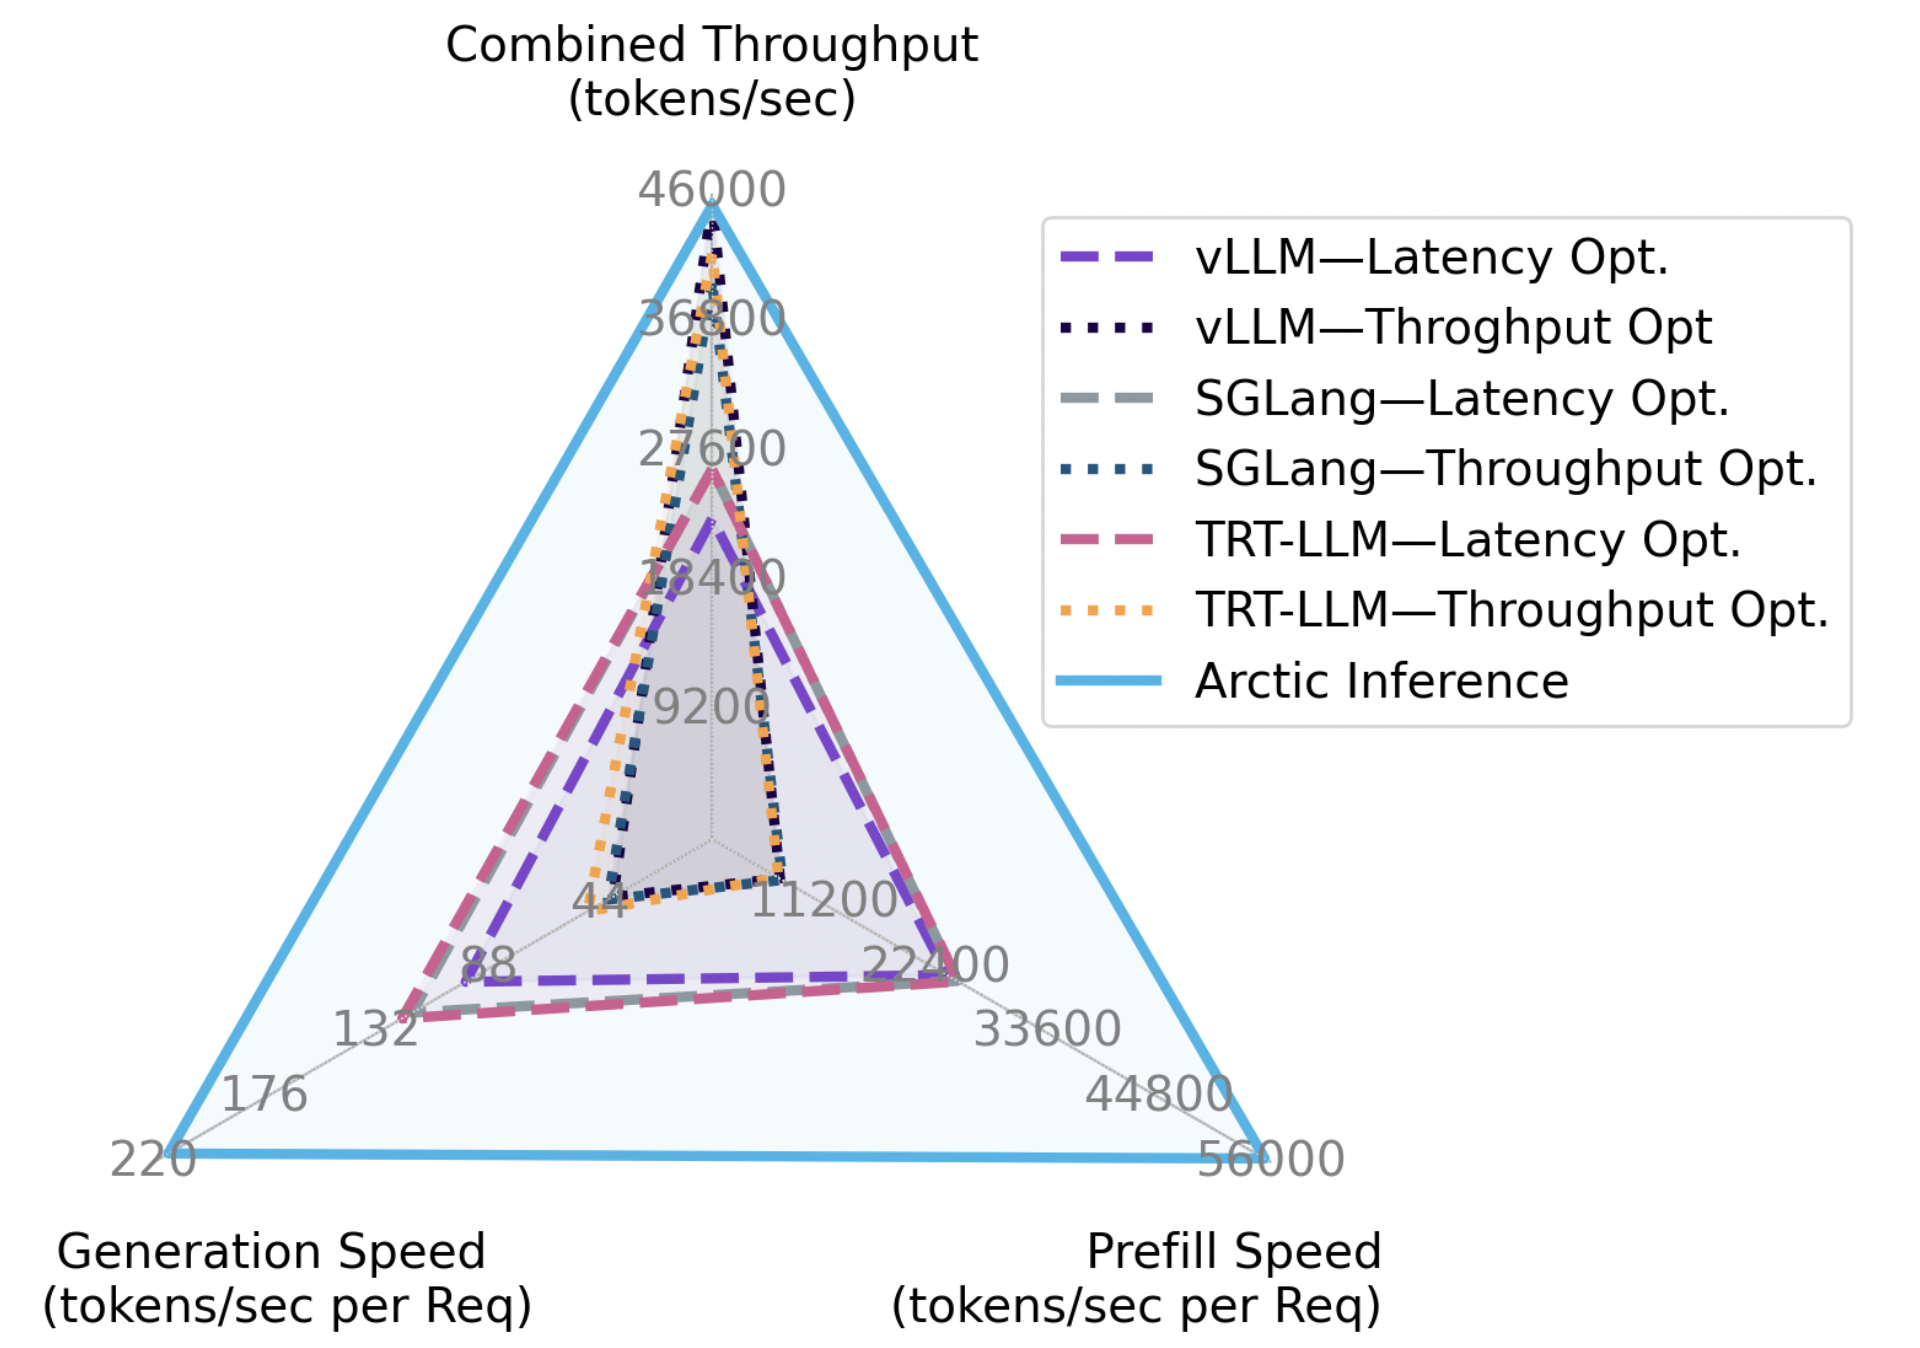
Arctic Inference + vLLM achieves the elusive "trifecta" of quicker response, higher throughput, and faster generation in a single deployment:
- 2.25x faster response time (prefill throughput per request)
- 1.75x faster generation per request
- SOTA combined throughput
Optimized Embeddings
See our blog for evaluation details.
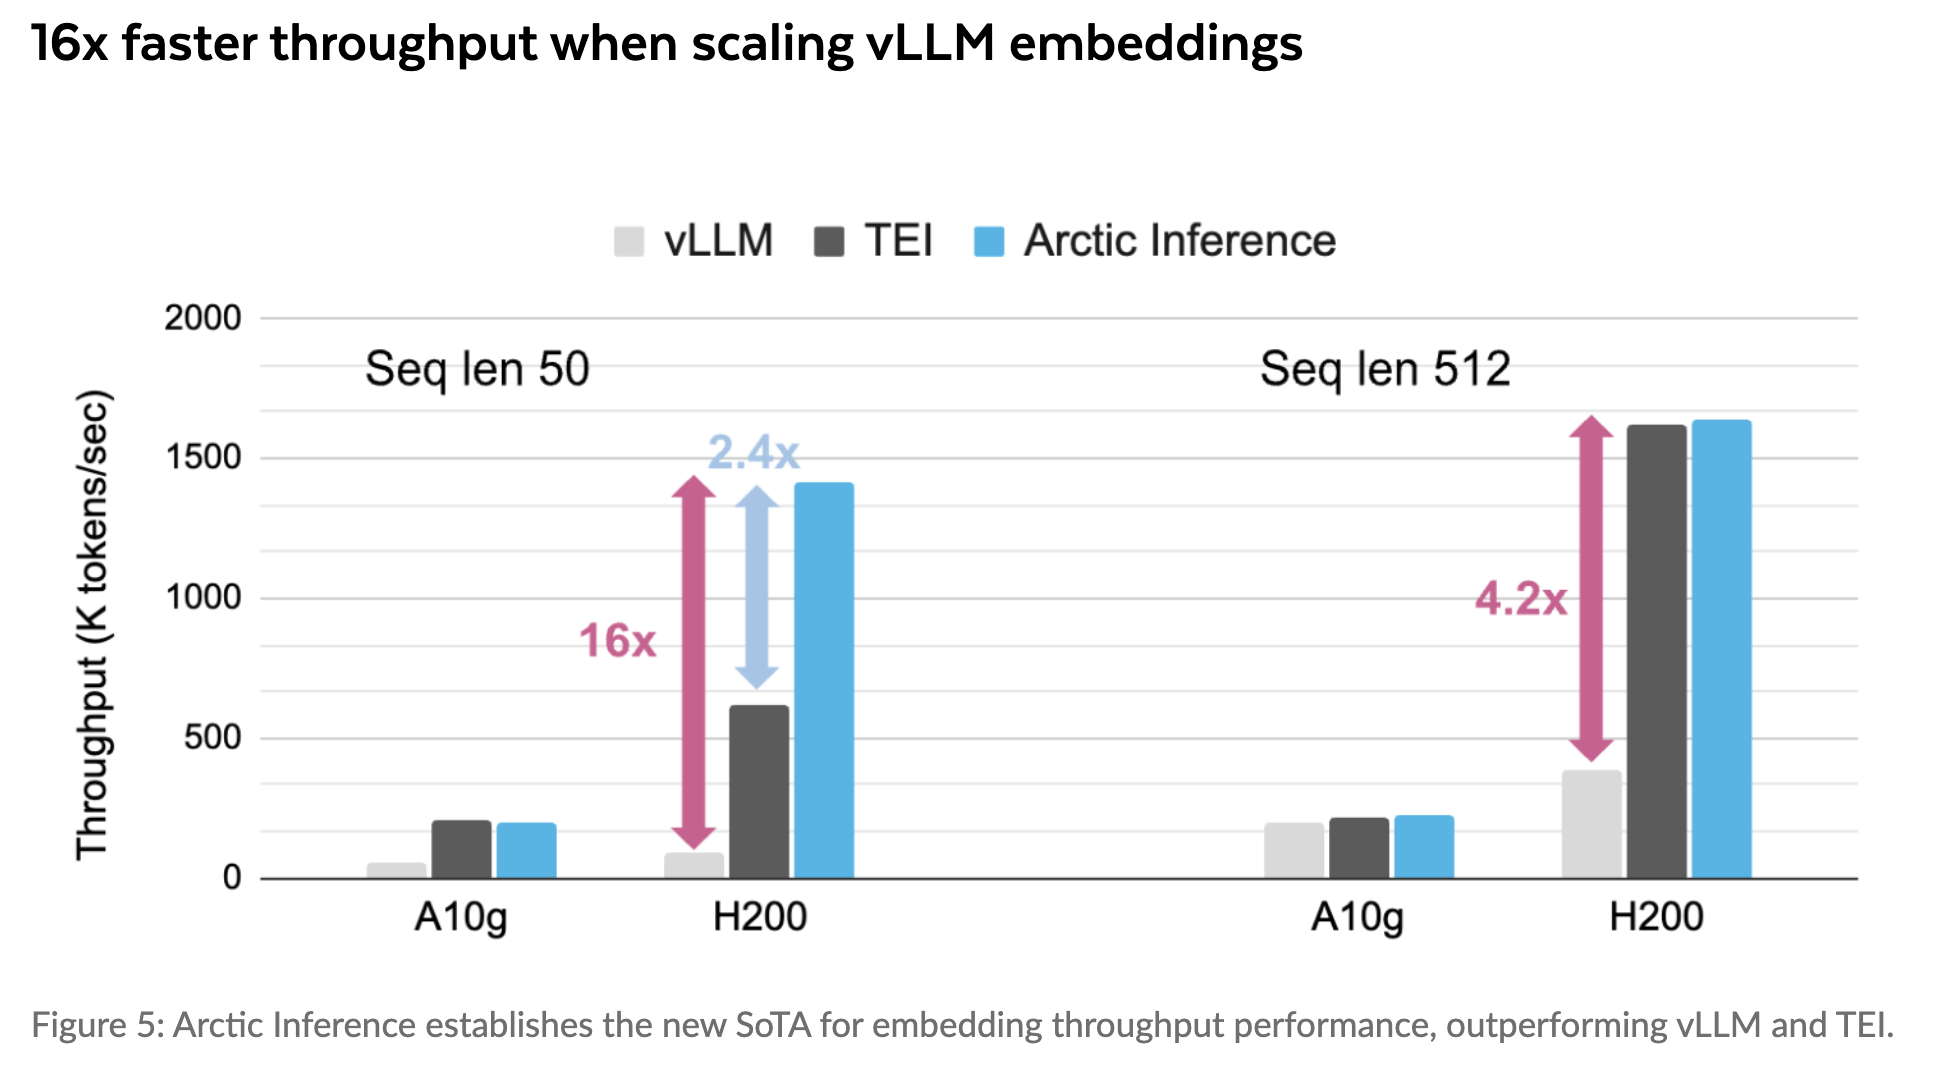
For embeddings, Arctic Inference + vLLM delivers a whopping 1.4M toks/sec per GPU:
- 16x faster than plain vLLM on short sequences and 4.2x faster on long sequences
- 2.4x faster than Text Embeddings Inference (TEI) on short sequences and at parity for long sequences
Quick Start
$ pip install arctic-inference[vllm]
Once installed, Arctic Inference automatically patches vLLM to use Arctic Inference with Shift Parallelism and other optimizations implemented in Arctic Inference, and users can continue to use their familiar vLLM APIs and CLI. It’s easy to get started!
Running Arctic Inference with vLLM
By using the examples below, you can get benefits from Shift Parallelism, Speculative Decoding, and SwiftKV all at once!
Serving
ARCTIC_INFERENCE_ENABLED=1 vllm serve Snowflake/Llama-3.1-SwiftKV-8B-Instruct \
    --quantization "fp8" \
    --tensor-parallel-size 1 \
    --ulysses-sequence-parallel-size 2 \
    --enable-shift-parallel \
    --speculative-config '{
        "method": "arctic",
        "model":"Snowflake/Arctic-LSTM-Speculator-Llama-3.1-8B-Instruct",
        "num_speculative_tokens": 3,
        "enable_suffix_decoding": true,
        "disable_by_batch_size": 64
    }'
Offline
Save the following script to arctic_example.py:
import vllm
from vllm import LLM, SamplingParams

vllm.plugins.load_general_plugins()

llm = LLM(
    model="Snowflake/Llama-3.1-SwiftKV-8B-Instruct",
    quantization="fp8",
    tensor_parallel_size=1,
    ulysses_sequence_parallel_size=2,
    enable_shift_parallel=True,
    speculative_config={
        "method": "arctic",
        "model": "Snowflake/Arctic-LSTM-Speculator-Llama-3.1-8B-Instruct",
        "num_speculative_tokens": 3,
        "enable_suffix_decoding": True,
        "disable_by_batch_size": 64,
    },
)

conversation = [
    {
        "role": "user",
        "content": "Write an essay about the importance of higher education.",
    },
]

sampling_params = SamplingParams(temperature=0.0, max_tokens=800)

outputs = llm.chat(conversation, sampling_params=sampling_params)

print(outputs[0].outputs[0].text)
Run the script with Arctic Inference enabled:
ARCTIC_INFERENCE_ENABLED=1 python arctic_example.py
Citation
@misc{arcticinference2025,
      title={Arctic Inference with Shift Parallelism: Fast and Efficient Open Source Inference System for Enterprise AI},
      author={Samyam Rajbhandari and Mert Hidayetoglu and Aurick Qiao and Ye Wang and Juncheng Yang and Jeff Rasley and Michael Wyatt and Yuxiong He},
      year={2025},
      url={https://arxiv.org/abs/2507.11830},
}
Contributors


Similar repos




Languages
Python
92.9%
Cuda
3.4%
C++
3.0%
ArcticInference: vLLM plugin for high-throughput, low-latency inference
Python
486
187 commits
updated Sep 23, 2026
README
| Documentation | Blog | Paper |
Latest news
- [2025/08] - Fast Reasoning on GPT-OSS with Speculative Decoding and Arctic Inference
- [2025/05] - Arctic Inference w. Shift Parallelism: The Fastest Open Source Inference System for Enterprise AI
- [2025/05] - Scaling vLLM for Embeddings: 16x Throughput and Cost Reduction
- [2025/05] - Fastest Speculative Decoding in vLLM with Arctic Inference and Arctic Training
- [2025/04] - Low-Latency and High-Throughput Inference for Long Context w. Sequence Parallelism (Ulysses)
Arctic Inference
Arctic Inference is an open-source vLLM plugin that brings Snowflake’s inference innovations to the community, delivering the fastest and most cost-effective open-source inference for LLMs and Embeddings.
Arctic Inference achieves high throughput and low latency through a wholistic set of inference optimizations:
Optimized LLM Inference
For real-world LLM workloads, a single deployment of Arctic Inference + vLLM achieves:
- 3.4x faster request completion and 1.06x higher throughput compared to the best throughput-optimized deployment (TP=1, DP=8)
- 1.7x higher throughput and 1.28x faster request completion compared to the best latency-optimized deployment (TP=8, DP=1)
Arctic Inference + vLLM achieves the elusive "trifecta" of quicker response, higher throughput, and faster generation in a single deployment:
- 2.25x faster response time (prefill throughput per request)
- 1.75x faster generation per request
- SOTA combined throughput
Optimized Embeddings
See our blog for evaluation details.
For embeddings, Arctic Inference + vLLM delivers a whopping 1.4M toks/sec per GPU:
- 16x faster than plain vLLM on short sequences and 4.2x faster on long sequences
- 2.4x faster than Text Embeddings Inference (TEI) on short sequences and at parity for long sequences
Quick Start
$ pip install arctic-inference[vllm]
Once installed, Arctic Inference automatically patches vLLM to use Arctic Inference with Shift Parallelism and other optimizations implemented in Arctic Inference, and users can continue to use their familiar vLLM APIs and CLI. It’s easy to get started!
Running Arctic Inference with vLLM
By using the examples below, you can get benefits from Shift Parallelism, Speculative Decoding, and SwiftKV all at once!
Serving
ARCTIC_INFERENCE_ENABLED=1 vllm serve Snowflake/Llama-3.1-SwiftKV-8B-Instruct \
    --quantization "fp8" \
    --tensor-parallel-size 1 \
    --ulysses-sequence-parallel-size 2 \
    --enable-shift-parallel \
    --speculative-config '{
        "method": "arctic",
        "model":"Snowflake/Arctic-LSTM-Speculator-Llama-3.1-8B-Instruct",
        "num_speculative_tokens": 3,
        "enable_suffix_decoding": true,
        "disable_by_batch_size": 64
    }'
Offline
Save the following script to arctic_example.py:
import vllm
from vllm import LLM, SamplingParams

vllm.plugins.load_general_plugins()

llm = LLM(
    model="Snowflake/Llama-3.1-SwiftKV-8B-Instruct",
    quantization="fp8",
    tensor_parallel_size=1,
    ulysses_sequence_parallel_size=2,
    enable_shift_parallel=True,
    speculative_config={
        "method": "arctic",
        "model": "Snowflake/Arctic-LSTM-Speculator-Llama-3.1-8B-Instruct",
        "num_speculative_tokens": 3,
        "enable_suffix_decoding": True,
        "disable_by_batch_size": 64,
    },
)

conversation = [
    {
        "role": "user",
        "content": "Write an essay about the importance of higher education.",
    },
]

sampling_params = SamplingParams(temperature=0.0, max_tokens=800)

outputs = llm.chat(conversation, sampling_params=sampling_params)

print(outputs[0].outputs[0].text)
Run the script with Arctic Inference enabled:
ARCTIC_INFERENCE_ENABLED=1 python arctic_example.py
Citation
@misc{arcticinference2025,
      title={Arctic Inference with Shift Parallelism: Fast and Efficient Open Source Inference System for Enterprise AI},
      author={Samyam Rajbhandari and Mert Hidayetoglu and Aurick Qiao and Ye Wang and Juncheng Yang and Jeff Rasley and Michael Wyatt and Yuxiong He},
      year={2025},
      url={https://arxiv.org/abs/2507.11830},
}
Similar repos
Contributors
Languages
Python
92.9%
Cuda
3.4%
C++
3.0%