
README
Awesome-LLM-Inference-Engine
Welcome to the Awesome-LLM-Inference-Engine repository!
A curated list of LLM inference engines, system architectures, and optimization techniques for efficient large language model serving. This repository complements our survey paper analyzing 25 inference engines, both open-source and commercial. It aims to provide practical insights for researchers, system designers, and engineers building LLM inference infrastructure.
Our work is based on the following paper: Survey on Inference Engines for Large Language Models: Perspectives on Optimization and Efficiency
🗂 Table of Contents
- 🧠 Overview
- 📊 Taxonomy
- 🛠 Optimization Techniques
- 🔓 Open Source Inference Engines
- 🧭 Open Source LLM Gateways and Serving Systems
- 💼 Commercial Inference Engines
- 🧮 Comparison Table
- 🔭 Future Directions
- 🤝 Contributing
- ⚖️ License
- 📝 Citation
- 🔬 Experiments
🧠 Overview
LLM services are evolving rapidly to support complex tasks such as chain-of-thought (CoT), reasoning, AI Agent workflows. These workloads significantly increase inference cost and system complexity.
This repository categorizes and compares LLM inference engines by:
- 🖧 Deployment type (single-node vs multi-node)
- ⚙️ Hardware diversity (homogeneous vs heterogeneous)
📊 Taxonomy
We classify LLM inference engines along the following dimensions:
- 🧑💻 Ease-of-Use: Assesses documentation quality and community activity. Higher scores indicate better developer experience and community support.
- ⚙️ Ease-of-Deployment: Measures the simplicity and speed of installation using tools like pip, APT, Homebrew, Conda, Docker, source builds, or prebuilt binaries.
- 🌐 General-purpose support: Reflects the range of supported LLM models and hardware platforms. Higher values indicate broader compatibility across diverse model families and execution environments.
- 🏗 Scalability: Indicates the engine’s ability to operate effectively across edge devices, servers, and multi-node deployments. Higher scores denote readiness for large-scale or distributed workloads.
- 📈 Throughput-aware: Captures the presence of optimization techniques focused on maximizing throughput, such as continuous batching, parallelism, and cache reuse.
- ⚡ Latency-aware: Captures support for techniques targeting low latency, including stall-free scheduling, chunked prefill, and priority-aware execution.
🔓 Open Source Inference Engines
- bitnet.cpp
- deepseek-v4-flash-0731-in-c
- DeepSpeed-FastGen 🌐 Webpage 📄 Paper
- DistServe 📄 Paper
- EIE - Elyne Inference Engine
- Higgs
- LightLLM 🌐 Webpage
- LitGPT 🌐 Webpage
- LMDeploy 🌐 Webpage
- llama2.c
- llama.cpp
- MAX 🌐 Webpage
- MLC LLM 🌐 Webpage
- NanoFlow 📄 Paper
- Ollama 🌐 Webpage
- OpenLLM 🌐 Webpage
- PowerInfer
- Project Zero 📄 Paper1, 📄 Paper2
- Sarathi-Serve 📄 Paper
- SGLang 🌐 Webpage 📄 Paper
- TensorRT-LLM 🌐 Webpage
- TGI (Text Generation Inference) 🌐 Webpage
- Unsloth 🌐 Webpage
- vAttention 📄 Paper
- vLLM 🌐 Webpage 📄 Paper
- XTLLM
- PrefillOnly 📄 Paper
- Colossal-AI 🌐 Webpage
🧭 Open Source LLM Gateways and Serving Systems
- Ferro Labs AI Gateway
- KV Cache Store - Hosted KV-cache artifact registry and open-source Rust CLI for precomputing, quantizing, verifying, and sharing attention-state artifacts across self-hosted LLM inference. (CLI source)
💼 Commercial Inference Engines
📋 Overview of LLM Inference Engines
The following table compares 26 open-source and commercial LLM inference engines along multiple dimensions including organization, release status, GitHub trends, documentation maturity, model support, and community presence.
| Framework | Organization | Release Date | Open Source | GitHub Stars | Docs | SNS | Forum | Meetup |
|---|---|---|---|---|---|---|---|---|
| Ollama | Community (Ollama) | Jun. 2023 | ✅ | 136K | 🟠 | ✅ | ❌ | ✅ |
| llama.cpp | Community (ggml.ai) | Mar. 2023 | ✅ | 77.6K | 🟡 | ❌ | ❌ | ❌ |
| vLLM | Academic (vLLM Team) | Feb. 2023 | ✅ | 43.4K | ✅ | ✅ | ✅ | ✅ |
| DeepSpeed-FastGen | Big Tech (Microsoft) | Nov. 2023 | ✅ | 37.7K | ✅ | ❌ | ❌ | ✅ |
| Unsloth | Startup (Unsloth AI) | Nov. 2023 | 🔷 | 36.5K | 🟡 | ✅ | ✅ | ❌ |
| MAX | Startup (Modular Inc.) | Apr. 2023 | 🔷 | 23.8K | 🟠 | ✅ | ✅ | ✅ |
| MLC LLM | Community (MLC-AI) | Apr. 2023 | ✅ | 20.3K | 🟠 | ✅ | ❌ | ❌ |
| llama2.c | Community (Andrej Karpathy) | Jul. 2023 | ✅ | 18.3K | ❌ | ✅ | ❌ | ❌ |
| bitnet.cpp | Big Tech (Microsoft) | Oct. 2024 | ✅ | 13.6K | ❌ | ❌ | ❌ | ❌ |
| SGLang | Academic (SGLang Team) | Jan. 2024 | ✅ | 12.8K | 🟠 | ✅ | ❌ | ✅ |
| LitGPT | Startup (Lightning AI) | Jun. 2024 | ✅ | 12.0K | 🟡 | ✅ | ❌ | ✅ |
| OpenLLM | Startup (BentoML) | Apr. 2023 | 🔷 | 11.1K | ❌ | ✅ | ❌ | ❌ |
| TensorRT-LLM | Big Tech (NVIDIA) | Aug. 2023 | 🔷 | 10.1K | ✅ | ❌ | ✅ | ✅ |
| TGI | Startup (Hugging Face) | Oct. 2022 | ✅ | 10.0K | 🟠 | ❌ | ✅ | ❌ |
| PowerInfer | Academic (SJTU-IPADS) | Dec. 2023 | ✅ | 8.2K | ❌ | ❌ | ❌ | ❌ |
| LMDeploy | Startup (MMDeploy) | Jun. 2023 | ✅ | 6.0K | 🟠 | ✅ | ❌ | ❌ |
| LightLLM | Academic (Lightllm Team) | Jul. 2023 | ✅ | 3.1K | 🟠 | ✅ | ❌ | ❌ |
| NanoFlow | Academic (UW Efeslab) | Aug. 2024 | ✅ | 0.7K | ❌ | ❌ | ❌ | ❌ |
| DistServe | Academic (PKU) | Jan. 2024 | ✅ | 0.5K | ❌ | ❌ | ❌ | ❌ |
| vAttention | Big Tech (Microsoft) | May. 2024 | ✅ | 0.3K | ❌ | ❌ | ❌ | ❌ |
| Sarathi-Serve | Big Tech (Microsoft) | Nov. 2023 | ✅ | 0.3K | ❌ | ❌ | ❌ | ❌ |
| EIE | Startup (Elyne Corp) | Apr. 2026 | ✅ | 4 | 🟠 | ❌ | ❌ | ❌ |
| Friendli Inference | Startup (FriendliAI Inc.) | Nov. 2023 | ❌ | -- | 🟡 | ❌ | ❌ | ✅ |
| Fireworks AI | Startup (Fireworks AI Inc.) | Jul. 2023 | ❌ | -- | 🟡 | ✅ | ❌ | ❌ |
| GroqCloud | Startup (Groq Inc.) | Feb. 2024 | ❌ | -- | ❌ | ✅ | ❌ | ✅ |
| Together Inference | Startup (together.ai) | Nov. 2023 | ❌ | -- | 🟡 | ✅ | ❌ | ❌ |
Legend:
- Open Source: ✅ = yes, 🔷 = partial, ❌ = closed
- Docs: ✅ = detailed, 🟠 = moderate, 🟡 = simple, ❌ = missing
- SNS / Forum / Meetup: presence of Discord/Slack, forum, or events
🛠 Optimization Techniques
We classify LLM inference optimization techniques into several major categories based on their target performance metrics, including latency, throughput, memory, and scalability. Each category includes representative methods and corresponding research publications.
🧩 Batch Optimization
| Technique | Description | References |
|---|---|---|
| Dynamic Batching | Collects user requests over a short time window to process them together, improving hardware efficiency | Crankshaw et al. (2017), Ali et al. (2020) |
| Continuous Batching | Forms batches incrementally based on arrival time to minimize latency | Yu et al. (2022), He et al. (2024) |
| Nano Batching | Extremely fine-grained batching for ultra-low latency inference | Zhu et al. (2024) |
| Chunked-prefills | Splits prefill into chunks for parallel decoding | Agrawal et al. (2023) |
- SuperCompress - Learned prompt compression that reduces inference tokens by ~65%. ~5K-parameter CPU policy (~60ms latency) with 100% oracle recall. Pre-processes prompts before inference.
🕸 Parallelism
| Technique | Description | References |
|---|---|---|
| Data Parallelism (DP) | Copies the same model to multiple GPUs and splits input data for parallel execution | Rajbhandari et al. (2020) |
| Fully Shared Data Parallelism (FSDP) | Shards model parameters across GPUs for memory-efficient training | Zhao et al. (2023) |
| Tensor Parallelism (TP) | Splits model tensors across devices for parallel computation | Stojkovic et al. (2024), Prabhakar et al. (2024) |
| Pipeline Parallelism (PP) | Divides model layers across devices and executes micro-batches sequentially | Agrawal et al. (2023), Hu et al. (2021), Ma et al. (2024), Yu et al. (2024) |
📦 Compression
Quantization
- OneComp vLLM plugin — Official vLLM plugin (DBF, Mixed-GPTQ) for serving OneComp-quantized LLMs. Paper.
| Technique | Description | References |
|---|---|---|
| PTQ | Applies quantization after training | Li et al. (2023) |
| QAT | Retrains with quantization awareness | Chen et al. (2024), Liu et al. (2023) |
| AQLM | Maintains performance at extremely low precision | Egiazarian et al. (2024) |
| SmoothQuant | Uses scale folding for normalization | Xiao et al. (2023) |
| KV Cache Quantization | Quantizes KV cache to reduce memory usage | Hooper et al. (2024), Liu et al. (2024) |
| EXL2 | Implements efficient quantization format | EXL2 |
| EETQ | Inference-friendly quantization method | EETQ |
| LLM Compressor | Unified framework for quantization and pruning | LLM Compressor |
| GPTQ | Hessian-aware quantization minimizing accuracy loss | Frantar et al. (2022) |
| Marlin | Fused quantization kernels for performance | Frantar et al. (2025) |
| Microscaling Format | Compact format for fine-grained quantization | Rouhani et al. (2023) |
Pruning
| Technique | Description | References |
|---|---|---|
| cuSPARSE | NVIDIA-optimized sparse matrix library | NVIDIA cuSPARSE |
| Wanda | Importance-based weight pruning | Sun et al. (2023) |
| Mini-GPTs | Efficient inference with reduced compute | Valicenti et al. (2023) |
| Token pruning | Skips decoding of unimportant tokens | Fu et al. (2024) |
| Post-Training Pruning | Prunes weights based on importance after training | Zhao et al. (2024) |
Sparsity Optimization
| Technique | Description | References |
|---|---|---|
| Structured Sparsity | Removes weights in fixed patterns | Zheng et al. (2024), Dong et al. (2023) |
| Dynamic Sparsity | Applies sparsity dynamically at runtime | Zhang et al. (2023) |
| Kernel-level Sparsity | Optimizations at CUDA kernel level | Xia et al. (2023), Borstnik et al. (2014), xFormers (2022), Xiang et al. (2025) |
| Block Sparsity | Removes weights in block structures | Gao et al. (2024) |
| N:M Sparsity | Maintains sparsity in fixed N:M ratios | Zhang et al. (2022) |
| MoE / Sparse MoE | Activates only a subset of experts | Cai et al. (2024), Fedus et al. (2022), Du et al. (2022) |
| Dynamic Token Sparsity | Prunes tokens based on dynamic importance | Yang et al. (2024), Fu et al. (2024) |
| Contextual Sparsity | Applies sparsity based on context | Liu et al. (2023), Akhauri et al. (2024) |
- SuperCompress - Learned prompt compression that reduces inference tokens by ~65%. ~5K-parameter CPU policy (~60ms latency) with 100% oracle recall. Pre-processes prompts before inference.
🛠 Fine-Tuning
| Technique | Description | References |
|---|---|---|
| Full-Parameter Tuning | Updates all model parameters | Lv et al. (2023) |
| LoRA | Injects low-rank matrices for efficient updates | Hu et al. (2022), Sheng et al. (2023) |
| QLoRA | Combines LoRA with quantized weights | Dettmers et al. (2023), Zhang et al. (2023) |
💾 Caching
| Technique | Description | References |
|---|---|---|
| Prompt Caching | Caches responses to identical prompts | Zhu et al. (2024) |
| Prefix Caching | Reuses common prefix computations | Liu et al. (2024), Pan et al. (2024) |
| KV Caching | Stores KV pairs for reuse in decoding | Pope et al. (2023) |
🔍 Attention Optimization
| Technique | Description | References |
|---|---|---|
| PagedAttention | Partitions KV cache into memory-efficient pages | Kwon et al. (2023) |
| TokenAttention | Selects tokens dynamically for attention | LightLLM |
| ChunkedAttention | Divides attention into chunks for better scheduling | Ye et al. (2024) |
| FlashAttention | High-speed kernel for attention | Dao et al. (2022),Dao et al. (2023), Shah et al. (2024) |
| RadixAttention | Merges tokens to reuse KV cache | Zheng et al. (2024) |
| FlexAttention | Configurable attention via DSL | Dong et al. (2024) |
| FireAttention | Optimized for MQA and fused heads | Fireworks AI |
🎲 Sampling Optimization
| Technique | Description | References |
|---|---|---|
| EAGLE | Multi-token speculative decoding | Li et al. (2024a), Li et al. (2024b), Li et al. (2025) |
| Medusa | Tree-based multi-head decoding | Cai et al. (2024) |
| ReDrafter | Regenerates output based on long-range context | Cheng et al. (2024) |
| MineDraft | Batch parallel speculative decoding overlapping drafting and verification (vLLM plugin) | Tang et al. (2026) |
- SuperCompress - Learned prompt compression that reduces inference tokens by ~65%. ~5K-parameter CPU policy (~60ms latency) with 100% oracle recall. Pre-processes prompts before inference.
🧾 Structured Outputs
| Technique | Description | References |
|---|---|---|
| FSM / CFG | Rule-based decoding constraints | Willard et al. (2023), Geng et al. (2023), Barke et al. (2024) |
| Outlines / XGrammar | Token-level structural constraints | Wilard et al. (2023), Dong et al. (2024) |
| LM Format Enforcer | Enforces output to follow JSON schemas | LM Format Enforcer |
| llguidance / GBNF | Lightweight grammar-based decoding | GBNF, llguidance |
| OpenAI Structured Outputs | API-supported structured outputs | OpenAI |
| JSONSchemaBench | Benchmark for structured decoding | Geng et al. (2025) |
| StructEval | Benchmarks structured generation and conversion across 18 text and visual formats | Yang et al. (2026), Code |
| StructTest / SoEval | Tools for structured output validation | Chen et al. (2024), Liu et al. (2024) |
📚 Comparison Table
⚠️ Due to GitHub Markdown limitations, only a summarized Markdown version is available here. Please refer to the LaTeX version in the survey paper for full detail.
💻 Hardware Support Matrix
| Framework | Linux | Windows | macOS | Web/API | x86-64 | ARM64/Apple Silicon | NVIDIA GPU (CUDA) | AMD GPU (ROCm/HIP) | Intel GPU (SYCL) | Google TPU | AMD Instinct | Intel Gaudi | Huawei Ascend | AWS Inferentia | Mobile / Edge | ETC |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Ollama | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ (NVIDIA Jetson) | ❌ |
| LLaMA.cpp | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ (Qualcomm Adreno) | Moore Threads MTT |
| vLLM | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ (NVIDIA Jetson) | ❌ |
| DeepSpeed-FastGen | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | Tecorigin SDAA |
| unsloth | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| MAX | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| MLC-LLM | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ (Qualcomm Adreno, ARM Mali, Apple) | ❌ |
| llama2.c | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| bitnet.cpp | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| SGLang | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ✅ (NVIDIA Jetson) | ❌ |
| LitGPT | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| OpenLLM | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| TensorRT-LLM | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ (NVIDIA Jetson) | ❌ |
| TGI | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ |
| PowerInfer | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ (Qualcomm Snapdragon 8) | ❌ |
| LMDeploy | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ (NVIDIA Jetson) | ❌ |
| LightLLM | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| NanoFlow | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| DistServe | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| vAttention | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Sarathi-Serve | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| EIE | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Friendli Inference | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Fireworks AI | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| GroqCloud | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | Groq LPU |
| Together Inference | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
- NVIDIA GPU: NVIDIA A100, NVIDIA H100, NVIDIA H200 etc.
- AMD GPU: AMD Radeon, etc.
- Intel GPU: Intel Arc, etc.
- Google TPU: TPU v4, TPU v5e, TPU v5p, etc.
- AMD Instinct: Instinct MI200, Instinct MI300X, etc.
- Intel Gaudi: Intel Gaudi 2, Intel Gaudi 3
- Huawei Ascend: Ascend series
- AWS Inferentia: Inferentia, Inferentia 2
- Mobile/Edge: NVIDIA Jetson, Qualcomm Snapdragon, etc.
- ETC: Moore Threads MTT, Tecorigin SDAA, Groq LPU
🧭 Deployment Scalability vs. Hardware Diversity
| 🧩 Heterogeneous Devices | ⚙️ Homogeneous Devices | |
|---|---|---|
| 🖥 Single-Node | EIE, llama.cpp, MAX, MLC LLM, Ollama, PowerInfer, TGI | bitnet.cpp, LightLLM, llama2.c, NanoFlow, OpenLLM, Sarathi-Serve, Unsloth, vAttention, Friendli Inference |
| 🖧 Multi-Node | DeepSpeed-FastGen, LitGPT, LMDeploy, SGLang, vLLM, Fireworks AI, Together Inference | DistServe, TensorRT-LLM, GroqCloud |
Legend:
- 🖥 Single-Node: Designed for single-device execution
- 🖧 Multi-Node: Supports distributed or multi-host serving
- 🧩 Heterogeneous Devices: Supports diverse hardware (CPU, GPU, accelerators)
- ⚙️ Homogeneous Devices: Optimized for a single hardware class
📌 Optimization Coverage Matrix
| Framework | Dynamic Batching | Continuous Batching | Nano Batching | Chunked-prefills | Data Parallelism | FSDP | Tensor Parallelism | Pipeline Parallelism | Quantization | Pruning | Sparsity | LoRA | Prompt Caching | Prefix Caching | KV Caching | PagedAttention | vAttention | FlashAttention | RadixAttention | FlexAttention | FireAttention | Speculative Decoding | Guided Decoding |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Ollama | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| LLaMA.cpp | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| vLLM | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| DeepSpeed-FastGen | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| unsloth | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ |
| MAX | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| MLC-LLM | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ |
| llama2.c | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| bitnet.cpp | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| SGLang | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ |
| LitGPT | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ |
| OpenLLM | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| TensorRT-LLM | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ |
| TGI | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ |
| PowerInfer | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ |
| LMDeploy | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ |
| LightLLM | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| NanoFlow | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| DistServe | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| vAttention | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Sarathi-Serve | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| EIE | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Friendli Inference | - | ✅ | - | - | - | - | ✅ | ✅ | ✅ | - | ✅ | ✅ | - | - | - | - | ❌ | - | - | ❌ | ✅ | ✅ | ✅ |
| Fireworks AI | - | ✅ | - | - | - | - | - | - | ✅ | ✅ | ✅ | ✅ | ✅ | - | ✅ | - | ❌ | - | - | ❌ | ✅ | ✅ | ✅ |
| GroqCloud | - | - | - | - | ✅ | - | ✅ | ✅ | ✅ | ✅ | ✅ | - | - | - | - | - | ❌ | - | - | ❌ | ✅ | ✅ | ✅ |
| Together Inference | - | - | - | - | - | ✅ | - | - | ✅ | - | ✅ | ✅ | ✅ | - | - | - | ❌ | ✅ | - | ❌ | ✅ | ✅ | ✅ |
🧮 Numeric Precision Support Matrix
| Framework | FP32 | FP16 | FP8 | FP4 | NF4 | BF16 | INT8 | INT4 | MXFP8 | MXFP6 | MXFP4 | MXINT8 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Ollama | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| LLaMA.cpp | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| vLLM | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| DeepSpeed-FastGen | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| unsloth | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| MAX | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| MLC-LLM | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| llama2.c | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| bitnet.cpp | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| SGLang | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| LitGPT | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| OpenLLM | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| TensorRT-LLM | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ |
| TGI | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| PowerInfer | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| LMDeploy | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| LightLLM | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| NanoFlow | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| DistServe | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| vAttention | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| Sarathi-Serve | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| EIE | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| Friendli Inference | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| Fireworks AI | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| GroqCloud | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Together Inference | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ |
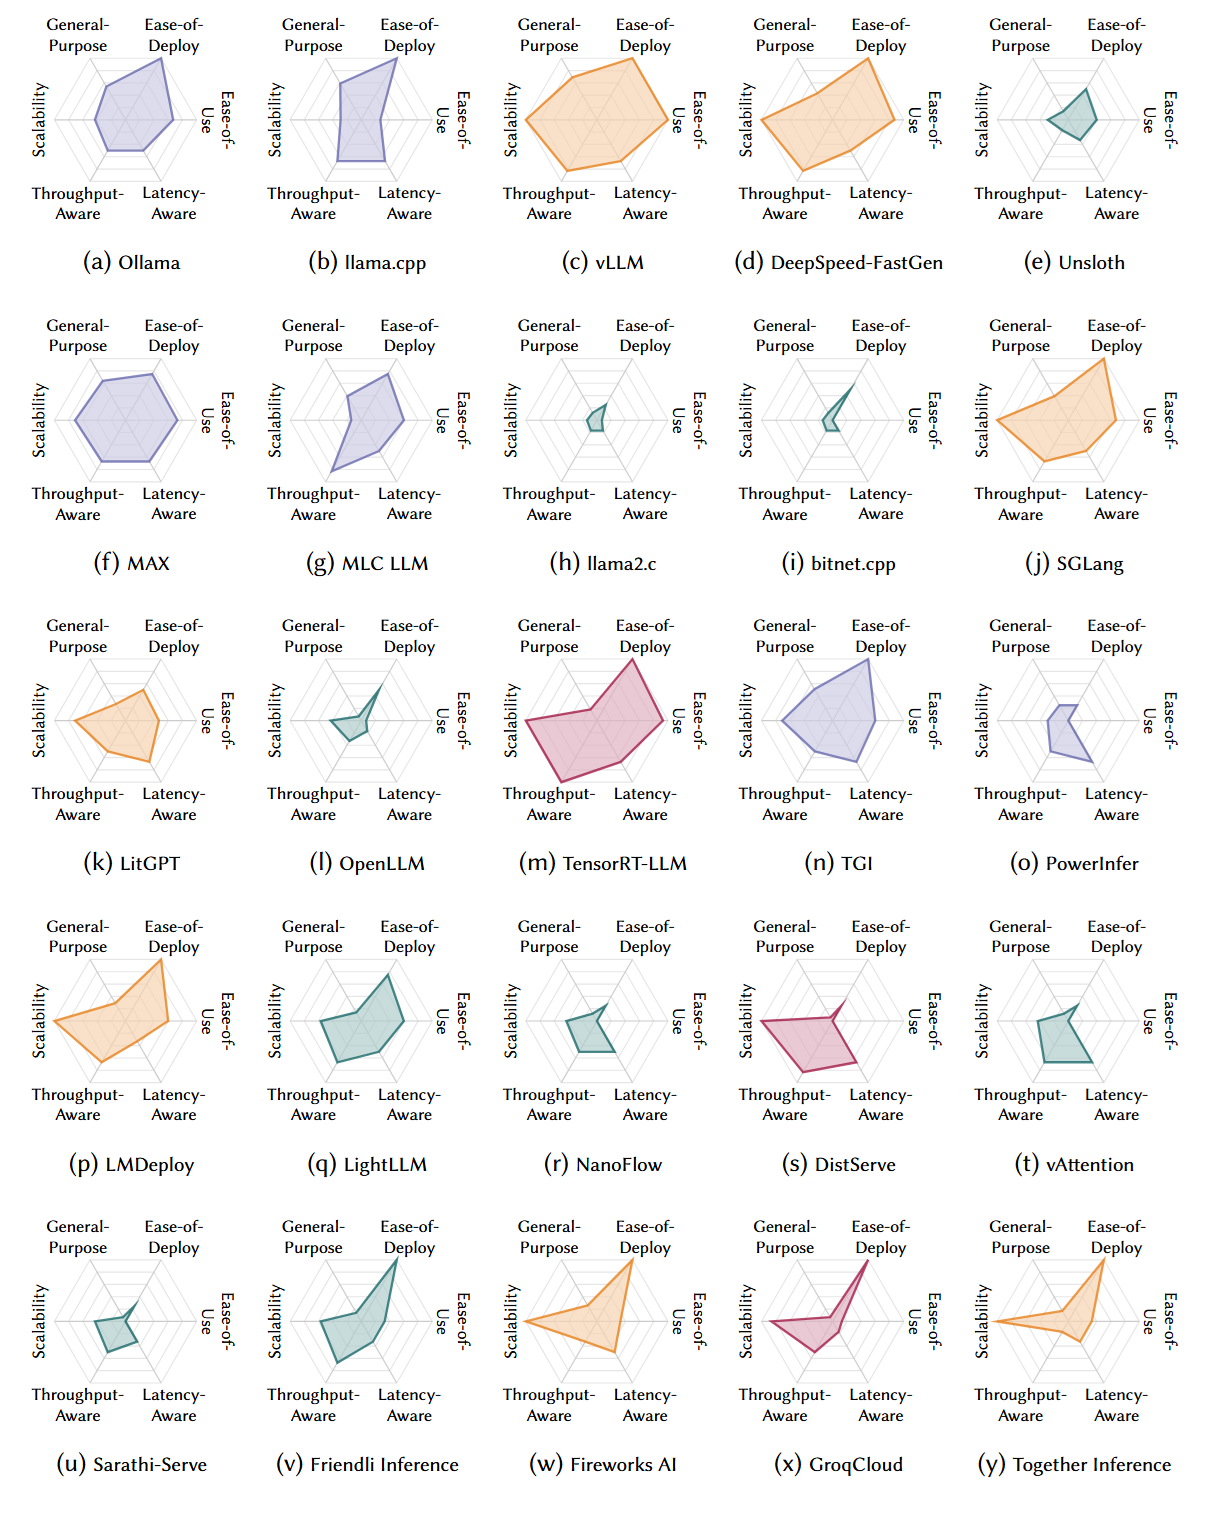
🧭 Radar Chart: Multi-Dimensional Evaluation of LLM Inference Engines
This radar chart compares 25 inference engines across six key dimensions: general-purpose support, ease of use, ease of deployment, latency awareness, throughput awareness, and scalability.
📈 Commercial Inference Engine Performance Comparison
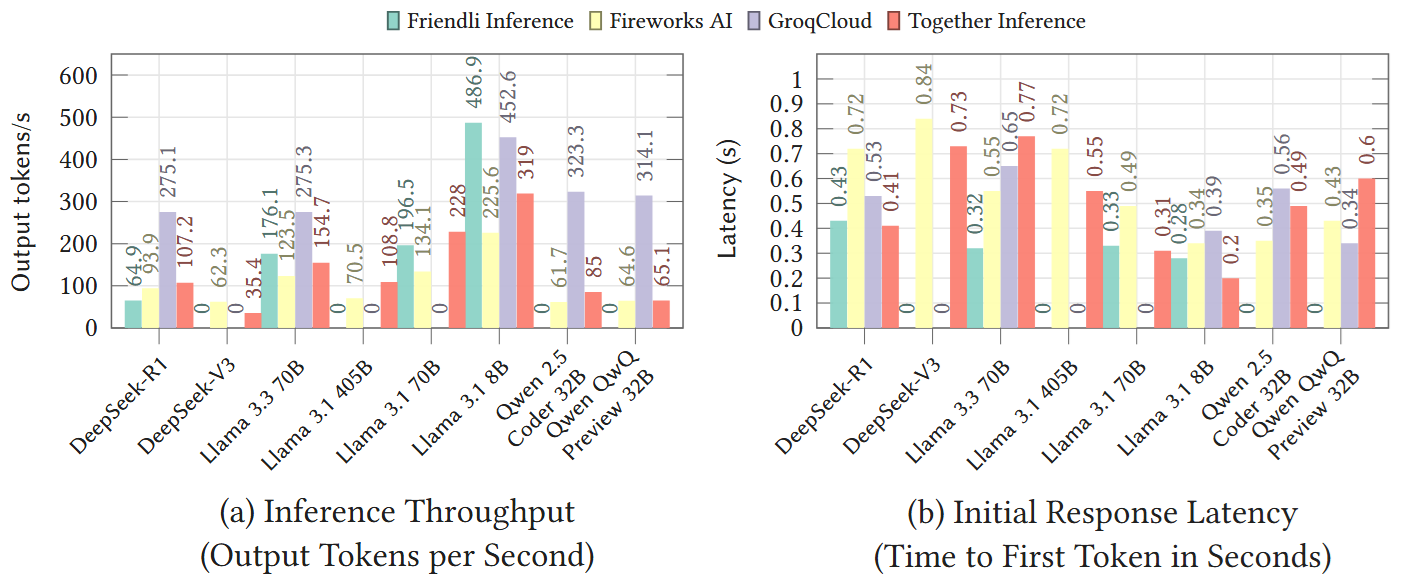
- Source: Artificial Analysis
💲 Commercial Inference Engine Pricing by Model (USD per 1M tokens)
| Model | Friendli AI† | Fireworks AI | GroqCloud | Together AI‡ |
|---|---|---|---|---|
| DeepSeek-R1 | 3.00 / 7.00 | 3.00 / 8.00 | 0.75* / 0.99* | 3.00 / 7.00 |
| DeepSeek-V3 | - / - | 0.90 / 0.90 | - / - | 1.25 / 1.25 |
| Llama 3.3 70B | 0.60 / 0.60 | - / - | 0.59 / 0.79 | 0.88 / 0.88 |
| Llama 3.1 405B | - / - | 3.00 / 3.00 | - / - | 3.50 / 3.50 |
| Llama 3.1 70B | 0.60 / 0.60 | - / - | - / - | 0.88 / 0.88 |
| Llama 3.1 8B | 0.10 / 0.10 | - / - | 0.05 / 0.08 | 0.18 / 0.18 |
| Qwen 2.5 Coder 32B | - / - | - / - | 0.79 / 0.79 | 0.80 / 0.80 |
| Qwen QwQ Preview 32B | - / - | - / - | 0.29 / 0.39 | 1.20 / 1.20 |
- † Llama is Instruct model
- ‡ Turbo mode price
- * DeepSeek-R1 Distill Llama 70B
💲 Commercial Inference Engine Pricing by Hardware Type (USD per hour per device)
| Hardware | Friendli AI | Fireworks AI | GroqCloud | Together AI |
|---|---|---|---|---|
| NVIDIA A100 80GB | 2.9 | 2.9 | - | 2.56 |
| NVIDIA H100 80GB | 5.6 | 5.8 | - | 3.36 |
| NVIDIA H200 141GB | - | 9.99 | - | 4.99 |
| AMD MI300X | - | 4.99 | - | - |
| Groq LPU | - | - | - | - |
- SuperCompress - Learned prompt compression that reduces inference tokens by ~65%. ~5K-parameter CPU policy (~60ms latency) with 100% oracle recall. Pre-processes prompts before inference.
🔬 Experiments
This section presents an empirical study of 21 open-source LLM inference engines across both server-class GPUs and edge devices. All benchmarks were executed through a unified OpenAI-compatible interface, and GuideLLM (https://github.com/vllm-project/guidellm) was used to generate load, measure latency, and ensure reproducible evaluation across engines.
⚙️ Experimental Setup
Hardware
- Server A (High-End): 8× NVIDIA H100
- Server B (Mid-Range): 6× NVIDIA RTX A6000
- Edge Device: NVIDIA Jetson Orin AGX 32GB
Engine Installation Notes
All 21 engines were installed and tested individually.
- Easy: pip/uv-based engines (Ollama, LLaMA.cpp, vLLM, etc.)
- Medium: container-based engines (TGI, TensorRT-LLM, MAX)
- Hard: engines requiring extra build steps or patches (MLC LLM, DistServe, NanoFlow)
Model Execution Feasibility
Not all engines supported the same models across devices. Some engines:
- ran on A6000 but not H100 (kernel/runtime mismatch)
- failed on multinode-only configurations
- lacked Jetson/ARM builds
Only Ollama and LLaMA.cpp ran reliably on Jetson.
📏 Evaluation Methodology
All requests were issued using GuideLLM, with a consistent API schema for fair comparison.
Metrics:
- TTFT (Time To First Token)
- TBT (Time Between Tokens)
- Requests/s
- Token Throughput
- End-to-End Latency
- Success Rate under concurrency
Workload design:
- Varying prompt lengths → TTFT
- Varying output lengths → TBT
- Increasing concurrency → throughput, stability
- Server tests: 30-second runs
- Edge tests: 240-second runs
- All engines evaluated using default settings (no manual tuning)
🔢 Quantized Model Results (Server)
Evaluated primarily on Ollama, LLaMA.cpp, and MLC LLM with 4-bit models.
TTFT
- TTFT increases linearly with prompt length across engines.
- LLaMA.cpp on H100 had competitive TTFT but occasionally unstable.
- MLC LLM showed fast TTFT in some cases but poor overall reliability.
TBT
- H100 delivered 2× faster decoding than A6000.
- For larger models (e.g., Qwen3-32B), several engines failed as output length increased.
Throughput Under Concurrency
- Small models → similar throughput across engines
- Medium models → Ollama (H100) consistently highest and most stable
- LLaMA.cpp → good decoding speed but high failure rate at concurrency ≥ 8
Token Throughput Meta-Llama-3.1-8B:
- Ollama (H100): ~588 tok/s
- LLaMA.cpp (H100): ~431 tok/s
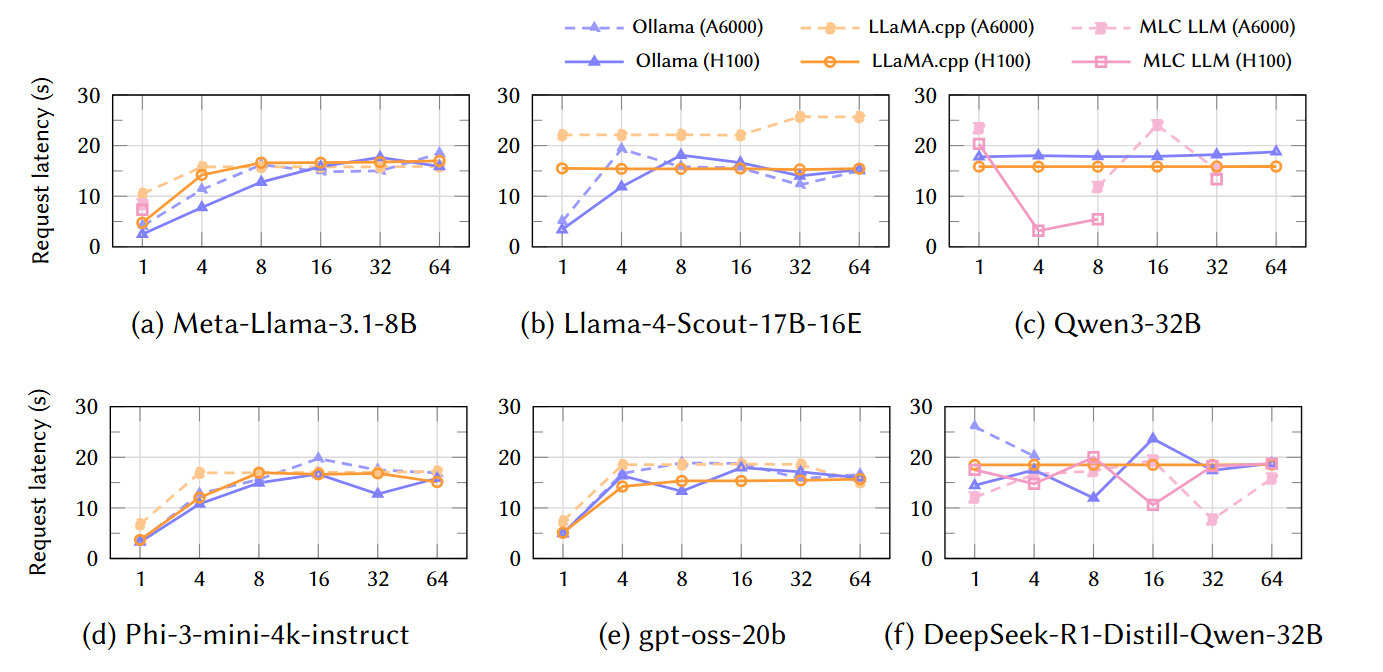
End-to-End Latency
Most engines converge around 15–17 seconds at concurrency 16.
Stability
- Medium/large models break down quickly at higher concurrency (1–10% success at ≥16).
- MLC LLM becomes unusable beyond concurrency 4.
💡 Full-Precision Model Results (Server)
Focus on high-performance engines: TensorRT-LLM, vLLM, LMDeploy, TGI.
TTFT
- TensorRT-LLM consistently lowest TTFT.
- vLLM, LMDeploy, TGI stable across all prompts/models.
TBT
- TensorRT-LLM fastest due to fused kernels and optimized attention.
- Others show moderate, predictable scaling.
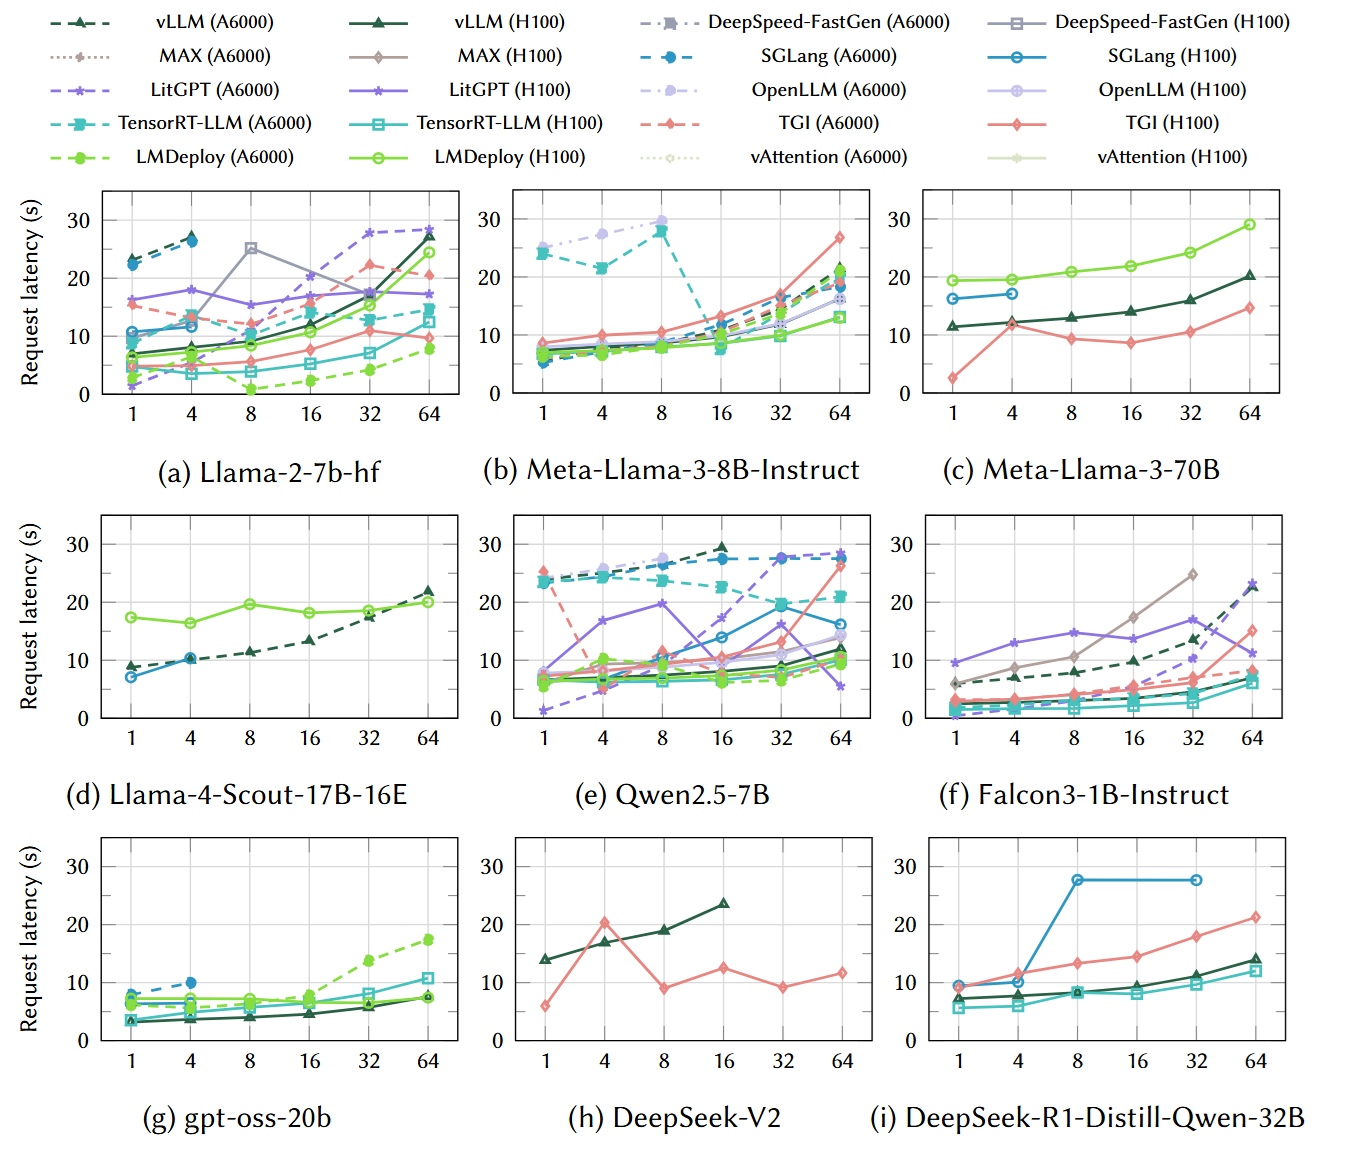
Requests/s (Llama-2-7B) Concurrency 64:
- TensorRT-LLM: 3.68 req/s
- LMDeploy: 2.57 req/s
- vLLM: 2.00 req/s
- TGI: 2.37 req/s
Token Throughput (Llama-2-7B, concurrency 64)
- TensorRT-LLM: 7,535 tok/s
- LMDeploy: 4,246 tok/s
- vLLM: 4,107 tok/s
- TGI: 3,058 tok/s
Some models (e.g., Qwen2.5) favor LMDeploy or vLLM due to kernel specialization.
Latency & Stability
- TensorRT-LLM lowest latency, vLLM/LMDeploy/TGI close behind.
- Most other engines failed to maintain concurrency stability.
📱 Edge Device Results (Jetson Orin)
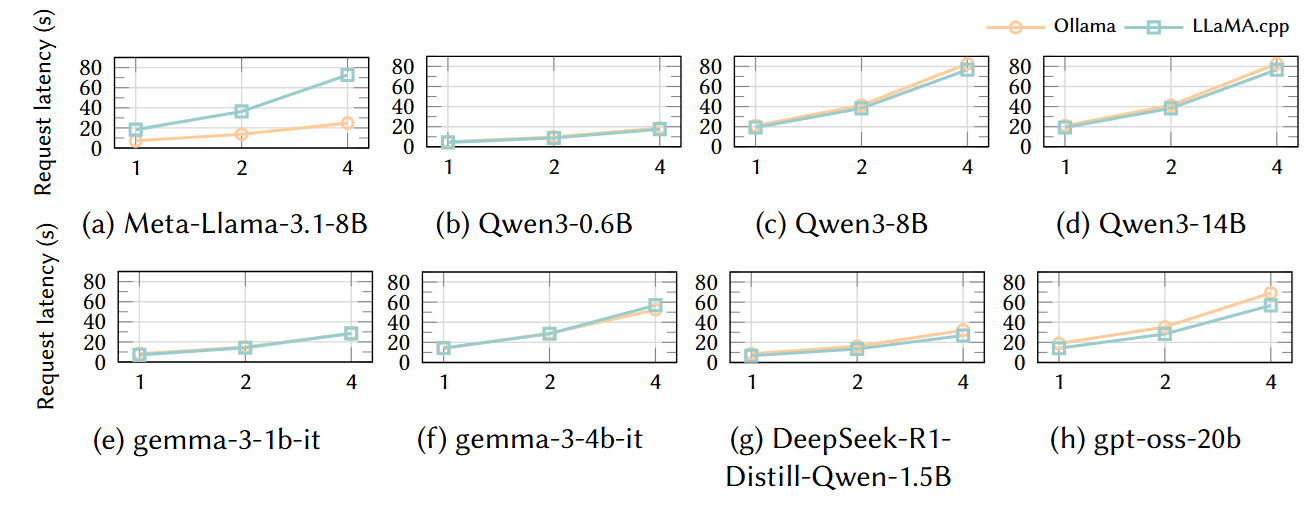
Only Ollama and LLaMA.cpp passed all tests.
TTFT
Llama-3.1-8B:
- Ollama is 2.5–3.5× faster than LLaMA.cpp
Small models (<1B–2B):
- LLaMA.cpp is faster
8B+ models: TTFT grows to 30–40s → impractical.
TBT
- Small models → LLaMA.cpp wins
- Medium models → Ollama wins
- Differences smaller than TTFT gap
Throughput
8B models:
- Ollama: ~0.15 req/s
- LLaMA.cpp: ~0.05 req/s
14B models:
- ~0.07 req/s → not usable
Latency Concurrency 4:
- 8B models: 25–70s
- 14B models: >130s
Edge-viable range: 1B–4B models, concurrency 1–2
🧭 Overall Findings
Server
- Top performance: TensorRT-LLM
- Best all-rounders: vLLM, LMDeploy, TGI
- Unstable under load: SGLang, LitGPT, DeepSpeed-FastGen (without tuning)
- Large models still unstable under high concurrency on a single node
Edge
- 8B+ models not suitable
- Practical range is 1B–4B models
- Ollama better for interactive use
- LLaMA.cpp better for small-model, high-locality workloads
Key Takeaways
- Engine performance varies significantly by model type, hardware, and concurrency.
- Many engines fail silently at scale; stability is as important as raw throughput.
- TensorRT-LLM dominates optimized full-precision inference, while vLLM/LMDeploy/TGI provide balanced performance without special builds.
- Edge inference remains heavily constrained by memory and latency.
🔭 Future Directions
LLM inference engines are rapidly evolving, but several important challenges remain open. Below we summarize key future directions and how they relate to system and model design.
1. Long-context Inference and Memory Management
Modern LLMs are pushing context windows from tens of thousands to millions of tokens, which causes KV cache size and memory usage to grow dramatically. This trend raises several needs:
- KV cache optimization: Techniques like paged KV management, hierarchical caching, CPU offloading, and memory-efficient attention (e.g., paged attention, chunked prefill) aim to reduce internal fragmentation and improve time-to-first-token (TTFT).
- Context compression: Methods such as coarse-to-fine context compression and budget-controlled token selection can shrink prompts by up to tens of times without major performance loss, though they must carefully avoid semantic drift.
- Streaming and unbounded inputs: Real-world services rely on multi-turn dialogue and streaming generation, effectively requiring unbounded input handling. Sliding windows and streaming attention approaches with relative position encodings (e.g., RoPE, ALiBi) enable infinite-length streams without retraining, but still struggle with tasks that require very long-range dependencies.
- Chunk-based aggregation: Some engines (e.g., vLLM) split long sequences into chunks, pool each chunk into embeddings, and then average them. This is simple and efficient but limits cross-chunk interaction and global reasoning.
Overall, long-context support requires combining cache management, context compression, and streaming attention rather than relying on a single technique.
2. Complex Logical Reasoning and CoT-friendly Inference
LLMs are increasingly used for complex reasoning tasks, such as multi-step problem solving, autonomous chain-of-thought (CoT) generation, and tool-based workflows:
- CoT explosion: CoT and multi-turn refinement can dramatically increase token usage in the decode phase, causing quasi-linear growth in FLOPs and memory traffic. KV cache capacity and bandwidth become critical bottlenecks.
- KV optimization for reasoning: Low-rank and sparse KV caching (e.g., keeping Keys in compressed form and reconstructing Values on demand) can mitigate memory pressure and bandwidth costs in long reasoning chains.
- Queue interference: Long CoT requests can cause head-of-line blocking, degrading TTFT for short, interactive requests. Splitting prefill and decode across heterogeneous devices and batching them separately helps reduce interference and maintain responsiveness.
- Conciseness vs. verbosity: Overly verbose CoT does not always improve answer quality and can lead to bloated responses. Metrics such as “correct-and-concise” and reward shaping that penalize unnecessary tokens are important for practical deployments.
- Session continuity: Engines must support streaming outputs, multi-turn session management, and stable handling of long reasoning flows as first-class concerns.
3. Application-driven Engine Design and Low-rank Decomposition
Inference engines must balance application requirements against system constraints:
- Latency vs. throughput: Interactive applications (chatbots, translators, copilots) prioritize latency, while batch workloads (e.g., offline translation or summarization) prioritize throughput. Engines should expose tunable profiles and scheduling policies for different scenarios.
- Model-level compression with low-rank decomposition: LLMs exhibit relatively low computational density for their parameter scale, making pure quantization/pruning insufficient. Low-rank decomposition bridges this gap by:
- Factorizing weight matrices/tensors into low-rank components using SVD or tensor techniques (Tensor Train, Tensor Ring, Tucker).
- Applying rank-constrained training or post-hoc decomposition to control the latency–accuracy trade-off.
- Two stages of application: Low-rank structure can be imposed:
- During pre-training, by parameterizing layers directly in low-rank form.
- As post-training compression, where layer-wise ranks are tuned to match hardware and latency targets.
- Hardware-aware co-design: To unlock full benefits:
- Ranks and decomposition dimensions must consider warp size, memory bank layout, shared memory capacity, and tensor core block sizes.
- Multiple small matrix multiplications should be fused into single kernels or reorganized into tensor-core-friendly blocks to avoid kernel launch overhead and global memory thrashing.
- Schedulers should reorder the computation graph so low-reuse regions stay in faster memories (registers/shared memory), alleviating bandwidth bottlenecks.
Low-rank decomposition thus complements engine-level optimization. Engines that already support post-training quantization (e.g., via libraries like Unsloth) can further improve efficiency by adding low-rank modules, enabling personal and edge deployment of larger models.
4. LLM Alignment at Training and Inference Time
As LLMs spread across domains, alignment (usefulness, safety, policy compliance, tone) becomes as important as raw task accuracy:
- Alignment methods:
- SFT → RLHF: Supervised fine-tuning followed by reinforcement learning from human feedback with reward models and PPO.
- RLAIF / Constitutional AI: Replacing human feedback with AI judges, guided by constitutions or policies.
- DPO and related methods: Directly optimizing the policy from preference pairs without explicit reward models or PPO.
- Frameworks and tooling: Large-scale alignment frameworks (Verl, LlamaRL, TRL, OpenRLHF, DeepSpeed-Chat) combine RLHF, DPO, and AI feedback in scalable pipelines.
- Impact on inference: Well-aligned models:
- Reduce retries and downstream filtering by matching user intent and policies more reliably.
- Produce more stable output formats and lengths, simplifying batch scheduling and response shaping.
Alignment does not reduce parameter counts, so engines must still combine alignment-aware models with quantization, KV caching, and smart batching to meet real-time service goals.
5. Hardware-aware Fusion and Mixed-precision Kernels
Generative AI workloads based on Transformers and diffusion models demand more sophisticated kernel design:
- Advanced fusion: Beyond simple operator fusion, kernels like FlashAttention-3 use hardware-conscious tiling and memory layouts tuned to GPUs such as NVIDIA H100.
- Microscaling datatypes: Emerging low-precision formats (FP4, MXFP4, NVFP4) enable:
- Faster GEMM operations and lower memory footprint.
- Competitive training and inference accuracy when combined with robust scaling, gradient estimation, and outlier handling (e.g., Random Hadamard transforms).
- MoE-friendly quantization: For mixture-of-experts (MoE) models, quantizing expert weights into FP4/MXFP4 can dramatically reduce memory usage, storing parameters effectively at around four bits while preserving utility.
- Engine requirements: To deploy these formats in production, inference engines must:
- Provide FP4/MXFP4-aware kernels and cache layouts.
- Integrate with hardware-specific features of modern accelerators (e.g., Blackwell, H100) to maximize utilization.
- Support mixed-precision pipelines that combine ultra-low precision weights with higher-precision activations or accumulators where needed.
6. On-device Inference and Knowledge Distillation
The demand for on-device and on-premise inference is growing due to privacy, latency, and offline requirements:
- From LLMs to SLMs: Compact models (e.g., Llama 3.2, Gemma, Phi-3, Pythia) enable LLM-style capabilities on embedded systems, mobile devices, IoT endpoints, and single-GPU setups.
- Edge-specific optimizations:
- Tolerance-aware compression, I/O recomputation pipelines, and chunk lifecycle management for mobile hardware.
- Collaborative inference across multiple edge devices to share computational workloads.
- 4-bit quantization and offloading of model weights, activations, and KV caches between GPU, CPU, and disk for resource-constrained environments.
- Knowledge distillation (KD):
- KD compresses large “teacher” models into smaller “student” models while maintaining accuracy.
- Different knowledge sources include labels, probability distributions, intermediate features, curated synthetic data, feedback signals, and self-filtered outputs.
- Distillation can be applied during fine-tuning or over the full pre-training pipeline, via supervised learning, divergence-based losses, or RL-style optimization.
- White-box KD leverages teacher logits and internal states for fine-grained alignment, while black-box KD (e.g., via APIs) relies only on final outputs and tends to be less sample-efficient.
Engines that support training loops can integrate KD directly; otherwise, they can still support light-weight distillation via student generation from teacher outputs.
7. Heterogeneous Hardware and Accelerator Support
LLM inference is no longer GPU-only. TPUs, NPUs, FPGAs, ASICs, and PIM/NDP platforms are increasingly relevant:
- Diverse accelerators: AWS Inferentia, Google TPU, AMD Instinct MI300X, Furiosa, Cerebras, and others offer varied architectures and memory systems.
- Hardware-specific strategies:
- Optimal partitioning of prefill and decode phases.
- Hardware-aware quantization, sparsity, and speculative decoding strategies that behave differently depending on batch size and memory hierarchy.
- Software stacks:
- TPUs typically rely on XLA and JAX.
- Other accelerators provide dedicated stacks (e.g., GroqWare/GroqFlow).
- Some engines (e.g., vLLM) are starting to support multiple backends (TPU, AMD, Ascend, etc.), but full official integration is still limited.
- Vendor-driven integration: Because adapting engines to new hardware often requires deep modifications (runtime, compiler, kernel libraries), hardware vendors increasingly provide their own wrappers and forks tailored to their accelerators.
Broad heterogeneous support requires careful co-design across engines, compilers, runtimes, and hardware vendors.
8. Multimodal LLM Inference
Most existing inference engines are text-centric, but real-world intelligence requires multimodal capabilities:
- Multimodal models: Architectures like Qwen2-VL and LLaVA-1.5 process images, text, and potentially audio/video, requiring:
- Efficient multimodal preprocessing pipelines.
- Multi-stream parallel execution across different modalities.
- Modality-aware compression:
- Standard quantization must be adapted so that modality-specific features are preserved.
- Compression schemes should minimize information loss in visual/audio channels while still reducing memory and compute.
- Hardware-accelerated multimodal decoding:
- Speculative decoding and other fast-decoding techniques should be extended to multimodal inputs.
- Multimodal Rotary Position Embedding (M-RoPE) extends positional encodings to better capture relationships across modalities and sequences.
Inference engines must evolve beyond text-only assumptions to support these heterogeneous inputs and computations.
9. Alternative Architectures Beyond Transformers
Although Transformers still dominate, alternative and hybrid architectures are rapidly emerging:
- Selective State Space Models (SSMs): RetNet, RWKV, and Mamba replace or augment attention with state-space layers, enabling:
- Linear-time processing of long sequences.
- More memory-friendly scaling for long-context tasks.
- Hybrid and MoE architectures:
- Jamba combines Mamba and Transformers with MoE to increase capacity while keeping active parameters manageable during inference.
- IBM Granite 4.0 integrates Mamba-based and Transformer-based components to reduce memory usage by over 70% while maintaining competitive accuracy, and operates across various hardware (e.g., GPUs, NPUs).
- Engine implications: Future inference systems must:
- Support non-Transformer primitives (state-space layers, different update rules, etc.).
- Be flexible enough to incorporate hybrid graphs that mix attention, MoE, and SSM blocks.
- Expose scheduling and memory policies that work for both standard Transformers and emerging architectures.
10. Security and Robustness in Inference
LLM inference introduces new security risks:
- Threats:
- Prompt injection and jailbreak attempts that override system instructions.
- Data leakage in sensitive domains such as finance and healthcare.
- Generation of harmful, misleading, or malicious content.
- Mitigation strategies:
- Robust training (e.g., adversarial training) to harden models against malicious inputs.
- Runtime safeguards: content moderation, instruction guarding, and input sanitization to block or neutralize high-risk queries.
- Service-level controls: role-based access control (RBAC), multi-factor authentication (MFA), short-lived access tokens, and strict logging/auditing policies.
- Engine role: Most engines currently focus on performance but rely on upstream or downstream filters and policies for security. A future direction is to treat security and robustness as first-class concerns within the engine itself (e.g., integrating moderation hooks and policy-aware routing).
11. Cloud Orchestration and Multi-node / Multi-agent Serving
Large-scale LLM services require robust orchestration and serving platforms:
- Cloud-native deployment:
- Kubernetes for container orchestration and autoscaling.
- Prometheus and Grafana for resource monitoring and visualization.
- Ray, Triton, Hugging Face Spaces, and other frameworks for distributed serving and scheduling.
- MoE and multi-agent scaling:
- As MoE and multi-agent workloads grow, serving moves from single device/node setups to multi-device, multi-node clusters.
- Disaggregating attention and FFN modules, and overlapping them via ping-pong pipeline parallelism, can significantly increase GPU utilization and throughput for MoE models.
- KV cache sharing and communication:
- KV cache reuse across models or agents (e.g., via offset-based reuse or cache projection and fusion) reduces redundant prefill computation and inter-model communication.
- Enhanced collective communication libraries (beyond standard NCCL) with zero-copy transports, fault-tolerant All-Reduce, and optimized AllToAll-like primitives improve performance in large multi-node environments.
As LLM services scale to tens or thousands of GPUs and multiple agents, inference engines must incorporate capabilities like distributed expert placement, KV cache sharing, and high-performance communication to meet real-world service-level objectives.
In summary, future LLM inference engines must evolve from “fast Transformer executors” into general-purpose, alignment-aware, secure, and hardware-conscious platforms that can:
- Handle extremely long contexts and complex reasoning.
- Support multimodal and alternative model architectures.
- Run efficiently on heterogeneous hardware and edge devices.
- Integrate alignment, security, and cloud orchestration as first-class features.
This holistic view of optimization—across models, engines, hardware, and serving platforms—will be crucial for building robust, scalable LLM systems.
🤝 Contributing
We welcome community contributions! Feel free to:
- Add new inference engines, serving gateways, or papers
- Update benchmarks or hardware support
- Submit PRs for engine usage examples or tutorials
⚖️ License
MIT License. See LICENSE for details.
📝 Citation
@misc{awesome_inference_engine,
  author       = {Sihyeong Park, Sungryeol Jeon, Chaelyn Lee, Seokhun Jeon, Byung-Soo Kim, and Jemin Lee},
  title        = {{Awesome-LLM-Inference-Engine}},
  howpublished = {\url{https://github.com/sihyeong/Awesome-LLM-Inference-Engine}},
  year         = {2025}
}
@article{10.1145/3803798,
author = {Park, Sihyeong and Jeon, Sungryeol and Lee, Chaelyn and Jeon, Seokhun and Kim, Byung-Soo and Lee, Jemin},
title = {A Survey on Inference Engines for Large Language Models: Perspectives on Optimization and Efficiency},
year = {2026},
publisher = {Association for Computing Machinery},
address = {New York, NY, USA},
issn = {2157-6904},
url = {https://doi.org/10.1145/3803798},
doi = {10.1145/3803798},
note = {Just Accepted},
journal = {ACM Trans. Intell. Syst. Technol.},
month = mar,
keywords = {Large Language Model, Transformer, Inference Engine, Framework, Optimization}
}
Contributors


Similar repos


README
Awesome-LLM-Inference-Engine
Welcome to the Awesome-LLM-Inference-Engine repository!
A curated list of LLM inference engines, system architectures, and optimization techniques for efficient large language model serving. This repository complements our survey paper analyzing 25 inference engines, both open-source and commercial. It aims to provide practical insights for researchers, system designers, and engineers building LLM inference infrastructure.
Our work is based on the following paper: Survey on Inference Engines for Large Language Models: Perspectives on Optimization and Efficiency
🗂 Table of Contents
- 🧠 Overview
- 📊 Taxonomy
- 🛠 Optimization Techniques
- 🔓 Open Source Inference Engines
- 🧭 Open Source LLM Gateways and Serving Systems
- 💼 Commercial Inference Engines
- 🧮 Comparison Table
- 🔭 Future Directions
- 🤝 Contributing
- ⚖️ License
- 📝 Citation
- 🔬 Experiments
🧠 Overview
LLM services are evolving rapidly to support complex tasks such as chain-of-thought (CoT), reasoning, AI Agent workflows. These workloads significantly increase inference cost and system complexity.
This repository categorizes and compares LLM inference engines by:
- 🖧 Deployment type (single-node vs multi-node)
- ⚙️ Hardware diversity (homogeneous vs heterogeneous)
📊 Taxonomy
We classify LLM inference engines along the following dimensions:
- 🧑💻 Ease-of-Use: Assesses documentation quality and community activity. Higher scores indicate better developer experience and community support.
- ⚙️ Ease-of-Deployment: Measures the simplicity and speed of installation using tools like pip, APT, Homebrew, Conda, Docker, source builds, or prebuilt binaries.
- 🌐 General-purpose support: Reflects the range of supported LLM models and hardware platforms. Higher values indicate broader compatibility across diverse model families and execution environments.
- 🏗 Scalability: Indicates the engine’s ability to operate effectively across edge devices, servers, and multi-node deployments. Higher scores denote readiness for large-scale or distributed workloads.
- 📈 Throughput-aware: Captures the presence of optimization techniques focused on maximizing throughput, such as continuous batching, parallelism, and cache reuse.
- ⚡ Latency-aware: Captures support for techniques targeting low latency, including stall-free scheduling, chunked prefill, and priority-aware execution.
🔓 Open Source Inference Engines
- bitnet.cpp
- deepseek-v4-flash-0731-in-c
- DeepSpeed-FastGen 🌐 Webpage 📄 Paper
- DistServe 📄 Paper
- EIE - Elyne Inference Engine
- Higgs
- LightLLM 🌐 Webpage
- LitGPT 🌐 Webpage
- LMDeploy 🌐 Webpage
- llama2.c
- llama.cpp
- MAX 🌐 Webpage
- MLC LLM 🌐 Webpage
- NanoFlow 📄 Paper
- Ollama 🌐 Webpage
- OpenLLM 🌐 Webpage
- PowerInfer
- Project Zero 📄 Paper1, 📄 Paper2
- Sarathi-Serve 📄 Paper
- SGLang 🌐 Webpage 📄 Paper
- TensorRT-LLM 🌐 Webpage
- TGI (Text Generation Inference) 🌐 Webpage
- Unsloth 🌐 Webpage
- vAttention 📄 Paper
- vLLM 🌐 Webpage 📄 Paper
- XTLLM
- PrefillOnly 📄 Paper
- Colossal-AI 🌐 Webpage
🧭 Open Source LLM Gateways and Serving Systems
- Ferro Labs AI Gateway
- KV Cache Store - Hosted KV-cache artifact registry and open-source Rust CLI for precomputing, quantizing, verifying, and sharing attention-state artifacts across self-hosted LLM inference. (CLI source)
💼 Commercial Inference Engines
📋 Overview of LLM Inference Engines
The following table compares 26 open-source and commercial LLM inference engines along multiple dimensions including organization, release status, GitHub trends, documentation maturity, model support, and community presence.
| Framework | Organization | Release Date | Open Source | GitHub Stars | Docs | SNS | Forum | Meetup |
|---|---|---|---|---|---|---|---|---|
| Ollama | Community (Ollama) | Jun. 2023 | ✅ | 136K | 🟠 | ✅ | ❌ | ✅ |
| llama.cpp | Community (ggml.ai) | Mar. 2023 | ✅ | 77.6K | 🟡 | ❌ | ❌ | ❌ |
| vLLM | Academic (vLLM Team) | Feb. 2023 | ✅ | 43.4K | ✅ | ✅ | ✅ | ✅ |
| DeepSpeed-FastGen | Big Tech (Microsoft) | Nov. 2023 | ✅ | 37.7K | ✅ | ❌ | ❌ | ✅ |
| Unsloth | Startup (Unsloth AI) | Nov. 2023 | 🔷 | 36.5K | 🟡 | ✅ | ✅ | ❌ |
| MAX | Startup (Modular Inc.) | Apr. 2023 | 🔷 | 23.8K | 🟠 | ✅ | ✅ | ✅ |
| MLC LLM | Community (MLC-AI) | Apr. 2023 | ✅ | 20.3K | 🟠 | ✅ | ❌ | ❌ |
| llama2.c | Community (Andrej Karpathy) | Jul. 2023 | ✅ | 18.3K | ❌ | ✅ | ❌ | ❌ |
| bitnet.cpp | Big Tech (Microsoft) | Oct. 2024 | ✅ | 13.6K | ❌ | ❌ | ❌ | ❌ |
| SGLang | Academic (SGLang Team) | Jan. 2024 | ✅ | 12.8K | 🟠 | ✅ | ❌ | ✅ |
| LitGPT | Startup (Lightning AI) | Jun. 2024 | ✅ | 12.0K | 🟡 | ✅ | ❌ | ✅ |
| OpenLLM | Startup (BentoML) | Apr. 2023 | 🔷 | 11.1K | ❌ | ✅ | ❌ | ❌ |
| TensorRT-LLM | Big Tech (NVIDIA) | Aug. 2023 | 🔷 | 10.1K | ✅ | ❌ | ✅ | ✅ |
| TGI | Startup (Hugging Face) | Oct. 2022 | ✅ | 10.0K | 🟠 | ❌ | ✅ | ❌ |
| PowerInfer | Academic (SJTU-IPADS) | Dec. 2023 | ✅ | 8.2K | ❌ | ❌ | ❌ | ❌ |
| LMDeploy | Startup (MMDeploy) | Jun. 2023 | ✅ | 6.0K | 🟠 | ✅ | ❌ | ❌ |
| LightLLM | Academic (Lightllm Team) | Jul. 2023 | ✅ | 3.1K | 🟠 | ✅ | ❌ | ❌ |
| NanoFlow | Academic (UW Efeslab) | Aug. 2024 | ✅ | 0.7K | ❌ | ❌ | ❌ | ❌ |
| DistServe | Academic (PKU) | Jan. 2024 | ✅ | 0.5K | ❌ | ❌ | ❌ | ❌ |
| vAttention | Big Tech (Microsoft) | May. 2024 | ✅ | 0.3K | ❌ | ❌ | ❌ | ❌ |
| Sarathi-Serve | Big Tech (Microsoft) | Nov. 2023 | ✅ | 0.3K | ❌ | ❌ | ❌ | ❌ |
| EIE | Startup (Elyne Corp) | Apr. 2026 | ✅ | 4 | 🟠 | ❌ | ❌ | ❌ |
| Friendli Inference | Startup (FriendliAI Inc.) | Nov. 2023 | ❌ | -- | 🟡 | ❌ | ❌ | ✅ |
| Fireworks AI | Startup (Fireworks AI Inc.) | Jul. 2023 | ❌ | -- | 🟡 | ✅ | ❌ | ❌ |
| GroqCloud | Startup (Groq Inc.) | Feb. 2024 | ❌ | -- | ❌ | ✅ | ❌ | ✅ |
| Together Inference | Startup (together.ai) | Nov. 2023 | ❌ | -- | 🟡 | ✅ | ❌ | ❌ |
Legend:
- Open Source: ✅ = yes, 🔷 = partial, ❌ = closed
- Docs: ✅ = detailed, 🟠 = moderate, 🟡 = simple, ❌ = missing
- SNS / Forum / Meetup: presence of Discord/Slack, forum, or events
🛠 Optimization Techniques
We classify LLM inference optimization techniques into several major categories based on their target performance metrics, including latency, throughput, memory, and scalability. Each category includes representative methods and corresponding research publications.
🧩 Batch Optimization
| Technique | Description | References |
|---|---|---|
| Dynamic Batching | Collects user requests over a short time window to process them together, improving hardware efficiency | Crankshaw et al. (2017), Ali et al. (2020) |
| Continuous Batching | Forms batches incrementally based on arrival time to minimize latency | Yu et al. (2022), He et al. (2024) |
| Nano Batching | Extremely fine-grained batching for ultra-low latency inference | Zhu et al. (2024) |
| Chunked-prefills | Splits prefill into chunks for parallel decoding | Agrawal et al. (2023) |
- SuperCompress - Learned prompt compression that reduces inference tokens by ~65%. ~5K-parameter CPU policy (~60ms latency) with 100% oracle recall. Pre-processes prompts before inference.
🕸 Parallelism
| Technique | Description | References |
|---|---|---|
| Data Parallelism (DP) | Copies the same model to multiple GPUs and splits input data for parallel execution | Rajbhandari et al. (2020) |
| Fully Shared Data Parallelism (FSDP) | Shards model parameters across GPUs for memory-efficient training | Zhao et al. (2023) |
| Tensor Parallelism (TP) | Splits model tensors across devices for parallel computation | Stojkovic et al. (2024), Prabhakar et al. (2024) |
| Pipeline Parallelism (PP) | Divides model layers across devices and executes micro-batches sequentially | Agrawal et al. (2023), Hu et al. (2021), Ma et al. (2024), Yu et al. (2024) |
📦 Compression
Quantization
- OneComp vLLM plugin — Official vLLM plugin (DBF, Mixed-GPTQ) for serving OneComp-quantized LLMs. Paper.
| Technique | Description | References |
|---|---|---|
| PTQ | Applies quantization after training | Li et al. (2023) |
| QAT | Retrains with quantization awareness | Chen et al. (2024), Liu et al. (2023) |
| AQLM | Maintains performance at extremely low precision | Egiazarian et al. (2024) |
| SmoothQuant | Uses scale folding for normalization | Xiao et al. (2023) |
| KV Cache Quantization | Quantizes KV cache to reduce memory usage | Hooper et al. (2024), Liu et al. (2024) |
| EXL2 | Implements efficient quantization format | EXL2 |
| EETQ | Inference-friendly quantization method | EETQ |
| LLM Compressor | Unified framework for quantization and pruning | LLM Compressor |
| GPTQ | Hessian-aware quantization minimizing accuracy loss | Frantar et al. (2022) |
| Marlin | Fused quantization kernels for performance | Frantar et al. (2025) |
| Microscaling Format | Compact format for fine-grained quantization | Rouhani et al. (2023) |
Pruning
| Technique | Description | References |
|---|---|---|
| cuSPARSE | NVIDIA-optimized sparse matrix library | NVIDIA cuSPARSE |
| Wanda | Importance-based weight pruning | Sun et al. (2023) |
| Mini-GPTs | Efficient inference with reduced compute | Valicenti et al. (2023) |
| Token pruning | Skips decoding of unimportant tokens | Fu et al. (2024) |
| Post-Training Pruning | Prunes weights based on importance after training | Zhao et al. (2024) |
Sparsity Optimization
| Technique | Description | References |
|---|---|---|
| Structured Sparsity | Removes weights in fixed patterns | Zheng et al. (2024), Dong et al. (2023) |
| Dynamic Sparsity | Applies sparsity dynamically at runtime | Zhang et al. (2023) |
| Kernel-level Sparsity | Optimizations at CUDA kernel level | Xia et al. (2023), Borstnik et al. (2014), xFormers (2022), Xiang et al. (2025) |
| Block Sparsity | Removes weights in block structures | Gao et al. (2024) |
| N:M Sparsity | Maintains sparsity in fixed N:M ratios | Zhang et al. (2022) |
| MoE / Sparse MoE | Activates only a subset of experts | Cai et al. (2024), Fedus et al. (2022), Du et al. (2022) |
| Dynamic Token Sparsity | Prunes tokens based on dynamic importance | Yang et al. (2024), Fu et al. (2024) |
| Contextual Sparsity | Applies sparsity based on context | Liu et al. (2023), Akhauri et al. (2024) |
- SuperCompress - Learned prompt compression that reduces inference tokens by ~65%. ~5K-parameter CPU policy (~60ms latency) with 100% oracle recall. Pre-processes prompts before inference.
🛠 Fine-Tuning
| Technique | Description | References |
|---|---|---|
| Full-Parameter Tuning | Updates all model parameters | Lv et al. (2023) |
| LoRA | Injects low-rank matrices for efficient updates | Hu et al. (2022), Sheng et al. (2023) |
| QLoRA | Combines LoRA with quantized weights | Dettmers et al. (2023), Zhang et al. (2023) |
💾 Caching
| Technique | Description | References |
|---|---|---|
| Prompt Caching | Caches responses to identical prompts | Zhu et al. (2024) |
| Prefix Caching | Reuses common prefix computations | Liu et al. (2024), Pan et al. (2024) |
| KV Caching | Stores KV pairs for reuse in decoding | Pope et al. (2023) |
🔍 Attention Optimization
| Technique | Description | References |
|---|---|---|
| PagedAttention | Partitions KV cache into memory-efficient pages | Kwon et al. (2023) |
| TokenAttention | Selects tokens dynamically for attention | LightLLM |
| ChunkedAttention | Divides attention into chunks for better scheduling | Ye et al. (2024) |
| FlashAttention | High-speed kernel for attention | Dao et al. (2022),Dao et al. (2023), Shah et al. (2024) |
| RadixAttention | Merges tokens to reuse KV cache | Zheng et al. (2024) |
| FlexAttention | Configurable attention via DSL | Dong et al. (2024) |
| FireAttention | Optimized for MQA and fused heads | Fireworks AI |
🎲 Sampling Optimization
| Technique | Description | References |
|---|---|---|
| EAGLE | Multi-token speculative decoding | Li et al. (2024a), Li et al. (2024b), Li et al. (2025) |
| Medusa | Tree-based multi-head decoding | Cai et al. (2024) |
| ReDrafter | Regenerates output based on long-range context | Cheng et al. (2024) |
| MineDraft | Batch parallel speculative decoding overlapping drafting and verification (vLLM plugin) | Tang et al. (2026) |
- SuperCompress - Learned prompt compression that reduces inference tokens by ~65%. ~5K-parameter CPU policy (~60ms latency) with 100% oracle recall. Pre-processes prompts before inference.
🧾 Structured Outputs
| Technique | Description | References |
|---|---|---|
| FSM / CFG | Rule-based decoding constraints | Willard et al. (2023), Geng et al. (2023), Barke et al. (2024) |
| Outlines / XGrammar | Token-level structural constraints | Wilard et al. (2023), Dong et al. (2024) |
| LM Format Enforcer | Enforces output to follow JSON schemas | LM Format Enforcer |
| llguidance / GBNF | Lightweight grammar-based decoding | GBNF, llguidance |
| OpenAI Structured Outputs | API-supported structured outputs | OpenAI |
| JSONSchemaBench | Benchmark for structured decoding | Geng et al. (2025) |
| StructEval | Benchmarks structured generation and conversion across 18 text and visual formats | Yang et al. (2026), Code |
| StructTest / SoEval | Tools for structured output validation | Chen et al. (2024), Liu et al. (2024) |
📚 Comparison Table
⚠️ Due to GitHub Markdown limitations, only a summarized Markdown version is available here. Please refer to the LaTeX version in the survey paper for full detail.
💻 Hardware Support Matrix
| Framework | Linux | Windows | macOS | Web/API | x86-64 | ARM64/Apple Silicon | NVIDIA GPU (CUDA) | AMD GPU (ROCm/HIP) | Intel GPU (SYCL) | Google TPU | AMD Instinct | Intel Gaudi | Huawei Ascend | AWS Inferentia | Mobile / Edge | ETC |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Ollama | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ (NVIDIA Jetson) | ❌ |
| LLaMA.cpp | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ (Qualcomm Adreno) | Moore Threads MTT |
| vLLM | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ (NVIDIA Jetson) | ❌ |
| DeepSpeed-FastGen | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | Tecorigin SDAA |
| unsloth | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| MAX | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| MLC-LLM | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ (Qualcomm Adreno, ARM Mali, Apple) | ❌ |
| llama2.c | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| bitnet.cpp | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| SGLang | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ✅ (NVIDIA Jetson) | ❌ |
| LitGPT | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| OpenLLM | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| TensorRT-LLM | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ (NVIDIA Jetson) | ❌ |
| TGI | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ |
| PowerInfer | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ (Qualcomm Snapdragon 8) | ❌ |
| LMDeploy | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ (NVIDIA Jetson) | ❌ |
| LightLLM | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| NanoFlow | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| DistServe | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| vAttention | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Sarathi-Serve | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| EIE | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Friendli Inference | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Fireworks AI | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| GroqCloud | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | Groq LPU |
| Together Inference | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
- NVIDIA GPU: NVIDIA A100, NVIDIA H100, NVIDIA H200 etc.
- AMD GPU: AMD Radeon, etc.
- Intel GPU: Intel Arc, etc.
- Google TPU: TPU v4, TPU v5e, TPU v5p, etc.
- AMD Instinct: Instinct MI200, Instinct MI300X, etc.
- Intel Gaudi: Intel Gaudi 2, Intel Gaudi 3
- Huawei Ascend: Ascend series
- AWS Inferentia: Inferentia, Inferentia 2
- Mobile/Edge: NVIDIA Jetson, Qualcomm Snapdragon, etc.
- ETC: Moore Threads MTT, Tecorigin SDAA, Groq LPU
🧭 Deployment Scalability vs. Hardware Diversity
| 🧩 Heterogeneous Devices | ⚙️ Homogeneous Devices | |
|---|---|---|
| 🖥 Single-Node | EIE, llama.cpp, MAX, MLC LLM, Ollama, PowerInfer, TGI | bitnet.cpp, LightLLM, llama2.c, NanoFlow, OpenLLM, Sarathi-Serve, Unsloth, vAttention, Friendli Inference |
| 🖧 Multi-Node | DeepSpeed-FastGen, LitGPT, LMDeploy, SGLang, vLLM, Fireworks AI, Together Inference | DistServe, TensorRT-LLM, GroqCloud |
Legend:
- 🖥 Single-Node: Designed for single-device execution
- 🖧 Multi-Node: Supports distributed or multi-host serving
- 🧩 Heterogeneous Devices: Supports diverse hardware (CPU, GPU, accelerators)
- ⚙️ Homogeneous Devices: Optimized for a single hardware class
📌 Optimization Coverage Matrix
| Framework | Dynamic Batching | Continuous Batching | Nano Batching | Chunked-prefills | Data Parallelism | FSDP | Tensor Parallelism | Pipeline Parallelism | Quantization | Pruning | Sparsity | LoRA | Prompt Caching | Prefix Caching | KV Caching | PagedAttention | vAttention | FlashAttention | RadixAttention | FlexAttention | FireAttention | Speculative Decoding | Guided Decoding |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Ollama | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| LLaMA.cpp | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| vLLM | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| DeepSpeed-FastGen | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| unsloth | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ |
| MAX | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| MLC-LLM | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ |
| llama2.c | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| bitnet.cpp | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| SGLang | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ |
| LitGPT | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ |
| OpenLLM | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| TensorRT-LLM | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ |
| TGI | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ |
| PowerInfer | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ |
| LMDeploy | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ |
| LightLLM | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ |
| NanoFlow | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| DistServe | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| vAttention | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Sarathi-Serve | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| EIE | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Friendli Inference | - | ✅ | - | - | - | - | ✅ | ✅ | ✅ | - | ✅ | ✅ | - | - | - | - | ❌ | - | - | ❌ | ✅ | ✅ | ✅ |
| Fireworks AI | - | ✅ | - | - | - | - | - | - | ✅ | ✅ | ✅ | ✅ | ✅ | - | ✅ | - | ❌ | - | - | ❌ | ✅ | ✅ | ✅ |
| GroqCloud | - | - | - | - | ✅ | - | ✅ | ✅ | ✅ | ✅ | ✅ | - | - | - | - | - | ❌ | - | - | ❌ | ✅ | ✅ | ✅ |
| Together Inference | - | - | - | - | - | ✅ | - | - | ✅ | - | ✅ | ✅ | ✅ | - | - | - | ❌ | ✅ | - | ❌ | ✅ | ✅ | ✅ |
🧮 Numeric Precision Support Matrix
| Framework | FP32 | FP16 | FP8 | FP4 | NF4 | BF16 | INT8 | INT4 | MXFP8 | MXFP6 | MXFP4 | MXINT8 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Ollama | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| LLaMA.cpp | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| vLLM | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| DeepSpeed-FastGen | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| unsloth | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| MAX | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| MLC-LLM | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| llama2.c | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| bitnet.cpp | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| SGLang | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| LitGPT | ✅ | ✅ | ❌ | ✅ | ✅ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| OpenLLM | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| TensorRT-LLM | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ |
| TGI | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| PowerInfer | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| LMDeploy | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| LightLLM | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| NanoFlow | ❌ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| DistServe | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| vAttention | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| Sarathi-Serve | ✅ | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| EIE | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| Friendli Inference | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| Fireworks AI | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| GroqCloud | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Together Inference | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ | ❌ |
🧭 Radar Chart: Multi-Dimensional Evaluation of LLM Inference Engines
This radar chart compares 25 inference engines across six key dimensions: general-purpose support, ease of use, ease of deployment, latency awareness, throughput awareness, and scalability.
📈 Commercial Inference Engine Performance Comparison
- Source: Artificial Analysis
💲 Commercial Inference Engine Pricing by Model (USD per 1M tokens)
| Model | Friendli AI† | Fireworks AI | GroqCloud | Together AI‡ |
|---|---|---|---|---|
| DeepSeek-R1 | 3.00 / 7.00 | 3.00 / 8.00 | 0.75* / 0.99* | 3.00 / 7.00 |
| DeepSeek-V3 | - / - | 0.90 / 0.90 | - / - | 1.25 / 1.25 |
| Llama 3.3 70B | 0.60 / 0.60 | - / - | 0.59 / 0.79 | 0.88 / 0.88 |
| Llama 3.1 405B | - / - | 3.00 / 3.00 | - / - | 3.50 / 3.50 |
| Llama 3.1 70B | 0.60 / 0.60 | - / - | - / - | 0.88 / 0.88 |
| Llama 3.1 8B | 0.10 / 0.10 | - / - | 0.05 / 0.08 | 0.18 / 0.18 |
| Qwen 2.5 Coder 32B | - / - | - / - | 0.79 / 0.79 | 0.80 / 0.80 |
| Qwen QwQ Preview 32B | - / - | - / - | 0.29 / 0.39 | 1.20 / 1.20 |
- † Llama is Instruct model
- ‡ Turbo mode price
- * DeepSeek-R1 Distill Llama 70B
💲 Commercial Inference Engine Pricing by Hardware Type (USD per hour per device)
| Hardware | Friendli AI | Fireworks AI | GroqCloud | Together AI |
|---|---|---|---|---|
| NVIDIA A100 80GB | 2.9 | 2.9 | - | 2.56 |
| NVIDIA H100 80GB | 5.6 | 5.8 | - | 3.36 |
| NVIDIA H200 141GB | - | 9.99 | - | 4.99 |
| AMD MI300X | - | 4.99 | - | - |
| Groq LPU | - | - | - | - |
- SuperCompress - Learned prompt compression that reduces inference tokens by ~65%. ~5K-parameter CPU policy (~60ms latency) with 100% oracle recall. Pre-processes prompts before inference.
🔬 Experiments
This section presents an empirical study of 21 open-source LLM inference engines across both server-class GPUs and edge devices. All benchmarks were executed through a unified OpenAI-compatible interface, and GuideLLM (https://github.com/vllm-project/guidellm) was used to generate load, measure latency, and ensure reproducible evaluation across engines.
⚙️ Experimental Setup
Hardware
- Server A (High-End): 8× NVIDIA H100
- Server B (Mid-Range): 6× NVIDIA RTX A6000
- Edge Device: NVIDIA Jetson Orin AGX 32GB
Engine Installation Notes
All 21 engines were installed and tested individually.
- Easy: pip/uv-based engines (Ollama, LLaMA.cpp, vLLM, etc.)
- Medium: container-based engines (TGI, TensorRT-LLM, MAX)
- Hard: engines requiring extra build steps or patches (MLC LLM, DistServe, NanoFlow)
Model Execution Feasibility
Not all engines supported the same models across devices. Some engines:
- ran on A6000 but not H100 (kernel/runtime mismatch)
- failed on multinode-only configurations
- lacked Jetson/ARM builds
Only Ollama and LLaMA.cpp ran reliably on Jetson.
📏 Evaluation Methodology
All requests were issued using GuideLLM, with a consistent API schema for fair comparison.
Metrics:
- TTFT (Time To First Token)
- TBT (Time Between Tokens)
- Requests/s
- Token Throughput
- End-to-End Latency
- Success Rate under concurrency
Workload design:
- Varying prompt lengths → TTFT
- Varying output lengths → TBT
- Increasing concurrency → throughput, stability
- Server tests: 30-second runs
- Edge tests: 240-second runs
- All engines evaluated using default settings (no manual tuning)
🔢 Quantized Model Results (Server)
Evaluated primarily on Ollama, LLaMA.cpp, and MLC LLM with 4-bit models.
TTFT
- TTFT increases linearly with prompt length across engines.
- LLaMA.cpp on H100 had competitive TTFT but occasionally unstable.
- MLC LLM showed fast TTFT in some cases but poor overall reliability.
TBT
- H100 delivered 2× faster decoding than A6000.
- For larger models (e.g., Qwen3-32B), several engines failed as output length increased.
Throughput Under Concurrency
- Small models → similar throughput across engines
- Medium models → Ollama (H100) consistently highest and most stable
- LLaMA.cpp → good decoding speed but high failure rate at concurrency ≥ 8
Token Throughput Meta-Llama-3.1-8B:
- Ollama (H100): ~588 tok/s
- LLaMA.cpp (H100): ~431 tok/s
End-to-End Latency
Most engines converge around 15–17 seconds at concurrency 16.
Stability
- Medium/large models break down quickly at higher concurrency (1–10% success at ≥16).
- MLC LLM becomes unusable beyond concurrency 4.
💡 Full-Precision Model Results (Server)
Focus on high-performance engines: TensorRT-LLM, vLLM, LMDeploy, TGI.
TTFT
- TensorRT-LLM consistently lowest TTFT.
- vLLM, LMDeploy, TGI stable across all prompts/models.
TBT
- TensorRT-LLM fastest due to fused kernels and optimized attention.
- Others show moderate, predictable scaling.
Requests/s (Llama-2-7B) Concurrency 64:
- TensorRT-LLM: 3.68 req/s
- LMDeploy: 2.57 req/s
- vLLM: 2.00 req/s
- TGI: 2.37 req/s
Token Throughput (Llama-2-7B, concurrency 64)
- TensorRT-LLM: 7,535 tok/s
- LMDeploy: 4,246 tok/s
- vLLM: 4,107 tok/s
- TGI: 3,058 tok/s
Some models (e.g., Qwen2.5) favor LMDeploy or vLLM due to kernel specialization.
Latency & Stability
- TensorRT-LLM lowest latency, vLLM/LMDeploy/TGI close behind.
- Most other engines failed to maintain concurrency stability.
📱 Edge Device Results (Jetson Orin)
Only Ollama and LLaMA.cpp passed all tests.
TTFT
Llama-3.1-8B:
- Ollama is 2.5–3.5× faster than LLaMA.cpp
Small models (<1B–2B):
- LLaMA.cpp is faster
8B+ models: TTFT grows to 30–40s → impractical.
TBT
- Small models → LLaMA.cpp wins
- Medium models → Ollama wins
- Differences smaller than TTFT gap
Throughput
8B models:
- Ollama: ~0.15 req/s
- LLaMA.cpp: ~0.05 req/s
14B models:
- ~0.07 req/s → not usable
Latency Concurrency 4:
- 8B models: 25–70s
- 14B models: >130s
Edge-viable range: 1B–4B models, concurrency 1–2
🧭 Overall Findings
Server
- Top performance: TensorRT-LLM
- Best all-rounders: vLLM, LMDeploy, TGI
- Unstable under load: SGLang, LitGPT, DeepSpeed-FastGen (without tuning)
- Large models still unstable under high concurrency on a single node
Edge
- 8B+ models not suitable
- Practical range is 1B–4B models
- Ollama better for interactive use
- LLaMA.cpp better for small-model, high-locality workloads
Key Takeaways
- Engine performance varies significantly by model type, hardware, and concurrency.
- Many engines fail silently at scale; stability is as important as raw throughput.
- TensorRT-LLM dominates optimized full-precision inference, while vLLM/LMDeploy/TGI provide balanced performance without special builds.
- Edge inference remains heavily constrained by memory and latency.
🔭 Future Directions
LLM inference engines are rapidly evolving, but several important challenges remain open. Below we summarize key future directions and how they relate to system and model design.
1. Long-context Inference and Memory Management
Modern LLMs are pushing context windows from tens of thousands to millions of tokens, which causes KV cache size and memory usage to grow dramatically. This trend raises several needs:
- KV cache optimization: Techniques like paged KV management, hierarchical caching, CPU offloading, and memory-efficient attention (e.g., paged attention, chunked prefill) aim to reduce internal fragmentation and improve time-to-first-token (TTFT).
- Context compression: Methods such as coarse-to-fine context compression and budget-controlled token selection can shrink prompts by up to tens of times without major performance loss, though they must carefully avoid semantic drift.
- Streaming and unbounded inputs: Real-world services rely on multi-turn dialogue and streaming generation, effectively requiring unbounded input handling. Sliding windows and streaming attention approaches with relative position encodings (e.g., RoPE, ALiBi) enable infinite-length streams without retraining, but still struggle with tasks that require very long-range dependencies.
- Chunk-based aggregation: Some engines (e.g., vLLM) split long sequences into chunks, pool each chunk into embeddings, and then average them. This is simple and efficient but limits cross-chunk interaction and global reasoning.
Overall, long-context support requires combining cache management, context compression, and streaming attention rather than relying on a single technique.
2. Complex Logical Reasoning and CoT-friendly Inference
LLMs are increasingly used for complex reasoning tasks, such as multi-step problem solving, autonomous chain-of-thought (CoT) generation, and tool-based workflows:
- CoT explosion: CoT and multi-turn refinement can dramatically increase token usage in the decode phase, causing quasi-linear growth in FLOPs and memory traffic. KV cache capacity and bandwidth become critical bottlenecks.
- KV optimization for reasoning: Low-rank and sparse KV caching (e.g., keeping Keys in compressed form and reconstructing Values on demand) can mitigate memory pressure and bandwidth costs in long reasoning chains.
- Queue interference: Long CoT requests can cause head-of-line blocking, degrading TTFT for short, interactive requests. Splitting prefill and decode across heterogeneous devices and batching them separately helps reduce interference and maintain responsiveness.
- Conciseness vs. verbosity: Overly verbose CoT does not always improve answer quality and can lead to bloated responses. Metrics such as “correct-and-concise” and reward shaping that penalize unnecessary tokens are important for practical deployments.
- Session continuity: Engines must support streaming outputs, multi-turn session management, and stable handling of long reasoning flows as first-class concerns.
3. Application-driven Engine Design and Low-rank Decomposition
Inference engines must balance application requirements against system constraints:
- Latency vs. throughput: Interactive applications (chatbots, translators, copilots) prioritize latency, while batch workloads (e.g., offline translation or summarization) prioritize throughput. Engines should expose tunable profiles and scheduling policies for different scenarios.
- Model-level compression with low-rank decomposition: LLMs exhibit relatively low computational density for their parameter scale, making pure quantization/pruning insufficient. Low-rank decomposition bridges this gap by:
- Factorizing weight matrices/tensors into low-rank components using SVD or tensor techniques (Tensor Train, Tensor Ring, Tucker).
- Applying rank-constrained training or post-hoc decomposition to control the latency–accuracy trade-off.
- Two stages of application: Low-rank structure can be imposed:
- During pre-training, by parameterizing layers directly in low-rank form.
- As post-training compression, where layer-wise ranks are tuned to match hardware and latency targets.
- Hardware-aware co-design: To unlock full benefits:
- Ranks and decomposition dimensions must consider warp size, memory bank layout, shared memory capacity, and tensor core block sizes.
- Multiple small matrix multiplications should be fused into single kernels or reorganized into tensor-core-friendly blocks to avoid kernel launch overhead and global memory thrashing.
- Schedulers should reorder the computation graph so low-reuse regions stay in faster memories (registers/shared memory), alleviating bandwidth bottlenecks.
Low-rank decomposition thus complements engine-level optimization. Engines that already support post-training quantization (e.g., via libraries like Unsloth) can further improve efficiency by adding low-rank modules, enabling personal and edge deployment of larger models.
4. LLM Alignment at Training and Inference Time
As LLMs spread across domains, alignment (usefulness, safety, policy compliance, tone) becomes as important as raw task accuracy:
- Alignment methods:
- SFT → RLHF: Supervised fine-tuning followed by reinforcement learning from human feedback with reward models and PPO.
- RLAIF / Constitutional AI: Replacing human feedback with AI judges, guided by constitutions or policies.
- DPO and related methods: Directly optimizing the policy from preference pairs without explicit reward models or PPO.
- Frameworks and tooling: Large-scale alignment frameworks (Verl, LlamaRL, TRL, OpenRLHF, DeepSpeed-Chat) combine RLHF, DPO, and AI feedback in scalable pipelines.
- Impact on inference: Well-aligned models:
- Reduce retries and downstream filtering by matching user intent and policies more reliably.
- Produce more stable output formats and lengths, simplifying batch scheduling and response shaping.
Alignment does not reduce parameter counts, so engines must still combine alignment-aware models with quantization, KV caching, and smart batching to meet real-time service goals.
5. Hardware-aware Fusion and Mixed-precision Kernels
Generative AI workloads based on Transformers and diffusion models demand more sophisticated kernel design:
- Advanced fusion: Beyond simple operator fusion, kernels like FlashAttention-3 use hardware-conscious tiling and memory layouts tuned to GPUs such as NVIDIA H100.
- Microscaling datatypes: Emerging low-precision formats (FP4, MXFP4, NVFP4) enable:
- Faster GEMM operations and lower memory footprint.
- Competitive training and inference accuracy when combined with robust scaling, gradient estimation, and outlier handling (e.g., Random Hadamard transforms).
- MoE-friendly quantization: For mixture-of-experts (MoE) models, quantizing expert weights into FP4/MXFP4 can dramatically reduce memory usage, storing parameters effectively at around four bits while preserving utility.
- Engine requirements: To deploy these formats in production, inference engines must:
- Provide FP4/MXFP4-aware kernels and cache layouts.
- Integrate with hardware-specific features of modern accelerators (e.g., Blackwell, H100) to maximize utilization.
- Support mixed-precision pipelines that combine ultra-low precision weights with higher-precision activations or accumulators where needed.
6. On-device Inference and Knowledge Distillation
The demand for on-device and on-premise inference is growing due to privacy, latency, and offline requirements:
- From LLMs to SLMs: Compact models (e.g., Llama 3.2, Gemma, Phi-3, Pythia) enable LLM-style capabilities on embedded systems, mobile devices, IoT endpoints, and single-GPU setups.
- Edge-specific optimizations:
- Tolerance-aware compression, I/O recomputation pipelines, and chunk lifecycle management for mobile hardware.
- Collaborative inference across multiple edge devices to share computational workloads.
- 4-bit quantization and offloading of model weights, activations, and KV caches between GPU, CPU, and disk for resource-constrained environments.
- Knowledge distillation (KD):
- KD compresses large “teacher” models into smaller “student” models while maintaining accuracy.
- Different knowledge sources include labels, probability distributions, intermediate features, curated synthetic data, feedback signals, and self-filtered outputs.
- Distillation can be applied during fine-tuning or over the full pre-training pipeline, via supervised learning, divergence-based losses, or RL-style optimization.
- White-box KD leverages teacher logits and internal states for fine-grained alignment, while black-box KD (e.g., via APIs) relies only on final outputs and tends to be less sample-efficient.
Engines that support training loops can integrate KD directly; otherwise, they can still support light-weight distillation via student generation from teacher outputs.
7. Heterogeneous Hardware and Accelerator Support
LLM inference is no longer GPU-only. TPUs, NPUs, FPGAs, ASICs, and PIM/NDP platforms are increasingly relevant:
- Diverse accelerators: AWS Inferentia, Google TPU, AMD Instinct MI300X, Furiosa, Cerebras, and others offer varied architectures and memory systems.
- Hardware-specific strategies:
- Optimal partitioning of prefill and decode phases.
- Hardware-aware quantization, sparsity, and speculative decoding strategies that behave differently depending on batch size and memory hierarchy.
- Software stacks:
- TPUs typically rely on XLA and JAX.
- Other accelerators provide dedicated stacks (e.g., GroqWare/GroqFlow).
- Some engines (e.g., vLLM) are starting to support multiple backends (TPU, AMD, Ascend, etc.), but full official integration is still limited.
- Vendor-driven integration: Because adapting engines to new hardware often requires deep modifications (runtime, compiler, kernel libraries), hardware vendors increasingly provide their own wrappers and forks tailored to their accelerators.
Broad heterogeneous support requires careful co-design across engines, compilers, runtimes, and hardware vendors.
8. Multimodal LLM Inference
Most existing inference engines are text-centric, but real-world intelligence requires multimodal capabilities:
- Multimodal models: Architectures like Qwen2-VL and LLaVA-1.5 process images, text, and potentially audio/video, requiring:
- Efficient multimodal preprocessing pipelines.
- Multi-stream parallel execution across different modalities.
- Modality-aware compression:
- Standard quantization must be adapted so that modality-specific features are preserved.
- Compression schemes should minimize information loss in visual/audio channels while still reducing memory and compute.
- Hardware-accelerated multimodal decoding:
- Speculative decoding and other fast-decoding techniques should be extended to multimodal inputs.
- Multimodal Rotary Position Embedding (M-RoPE) extends positional encodings to better capture relationships across modalities and sequences.
Inference engines must evolve beyond text-only assumptions to support these heterogeneous inputs and computations.
9. Alternative Architectures Beyond Transformers
Although Transformers still dominate, alternative and hybrid architectures are rapidly emerging:
- Selective State Space Models (SSMs): RetNet, RWKV, and Mamba replace or augment attention with state-space layers, enabling:
- Linear-time processing of long sequences.
- More memory-friendly scaling for long-context tasks.
- Hybrid and MoE architectures:
- Jamba combines Mamba and Transformers with MoE to increase capacity while keeping active parameters manageable during inference.
- IBM Granite 4.0 integrates Mamba-based and Transformer-based components to reduce memory usage by over 70% while maintaining competitive accuracy, and operates across various hardware (e.g., GPUs, NPUs).
- Engine implications: Future inference systems must:
- Support non-Transformer primitives (state-space layers, different update rules, etc.).
- Be flexible enough to incorporate hybrid graphs that mix attention, MoE, and SSM blocks.
- Expose scheduling and memory policies that work for both standard Transformers and emerging architectures.
10. Security and Robustness in Inference
LLM inference introduces new security risks:
- Threats:
- Prompt injection and jailbreak attempts that override system instructions.
- Data leakage in sensitive domains such as finance and healthcare.
- Generation of harmful, misleading, or malicious content.
- Mitigation strategies:
- Robust training (e.g., adversarial training) to harden models against malicious inputs.
- Runtime safeguards: content moderation, instruction guarding, and input sanitization to block or neutralize high-risk queries.
- Service-level controls: role-based access control (RBAC), multi-factor authentication (MFA), short-lived access tokens, and strict logging/auditing policies.
- Engine role: Most engines currently focus on performance but rely on upstream or downstream filters and policies for security. A future direction is to treat security and robustness as first-class concerns within the engine itself (e.g., integrating moderation hooks and policy-aware routing).
11. Cloud Orchestration and Multi-node / Multi-agent Serving
Large-scale LLM services require robust orchestration and serving platforms:
- Cloud-native deployment:
- Kubernetes for container orchestration and autoscaling.
- Prometheus and Grafana for resource monitoring and visualization.
- Ray, Triton, Hugging Face Spaces, and other frameworks for distributed serving and scheduling.
- MoE and multi-agent scaling:
- As MoE and multi-agent workloads grow, serving moves from single device/node setups to multi-device, multi-node clusters.
- Disaggregating attention and FFN modules, and overlapping them via ping-pong pipeline parallelism, can significantly increase GPU utilization and throughput for MoE models.
- KV cache sharing and communication:
- KV cache reuse across models or agents (e.g., via offset-based reuse or cache projection and fusion) reduces redundant prefill computation and inter-model communication.
- Enhanced collective communication libraries (beyond standard NCCL) with zero-copy transports, fault-tolerant All-Reduce, and optimized AllToAll-like primitives improve performance in large multi-node environments.
As LLM services scale to tens or thousands of GPUs and multiple agents, inference engines must incorporate capabilities like distributed expert placement, KV cache sharing, and high-performance communication to meet real-world service-level objectives.
In summary, future LLM inference engines must evolve from “fast Transformer executors” into general-purpose, alignment-aware, secure, and hardware-conscious platforms that can:
- Handle extremely long contexts and complex reasoning.
- Support multimodal and alternative model architectures.
- Run efficiently on heterogeneous hardware and edge devices.
- Integrate alignment, security, and cloud orchestration as first-class features.
This holistic view of optimization—across models, engines, hardware, and serving platforms—will be crucial for building robust, scalable LLM systems.
🤝 Contributing
We welcome community contributions! Feel free to:
- Add new inference engines, serving gateways, or papers
- Update benchmarks or hardware support
- Submit PRs for engine usage examples or tutorials
⚖️ License
MIT License. See LICENSE for details.
📝 Citation
@misc{awesome_inference_engine,
  author       = {Sihyeong Park, Sungryeol Jeon, Chaelyn Lee, Seokhun Jeon, Byung-Soo Kim, and Jemin Lee},
  title        = {{Awesome-LLM-Inference-Engine}},
  howpublished = {\url{https://github.com/sihyeong/Awesome-LLM-Inference-Engine}},
  year         = {2025}
}
@article{10.1145/3803798,
author = {Park, Sihyeong and Jeon, Sungryeol and Lee, Chaelyn and Jeon, Seokhun and Kim, Byung-Soo and Lee, Jemin},
title = {A Survey on Inference Engines for Large Language Models: Perspectives on Optimization and Efficiency},
year = {2026},
publisher = {Association for Computing Machinery},
address = {New York, NY, USA},
issn = {2157-6904},
url = {https://doi.org/10.1145/3803798},
doi = {10.1145/3803798},
note = {Just Accepted},
journal = {ACM Trans. Intell. Syst. Technol.},
month = mar,
keywords = {Large Language Model, Transformer, Inference Engine, Framework, Optimization}
}