
Awesome LLM compression research papers and tools.
1,876
1,035 commits
updated Aug 27, 2026
README
Awesome LLM Compression


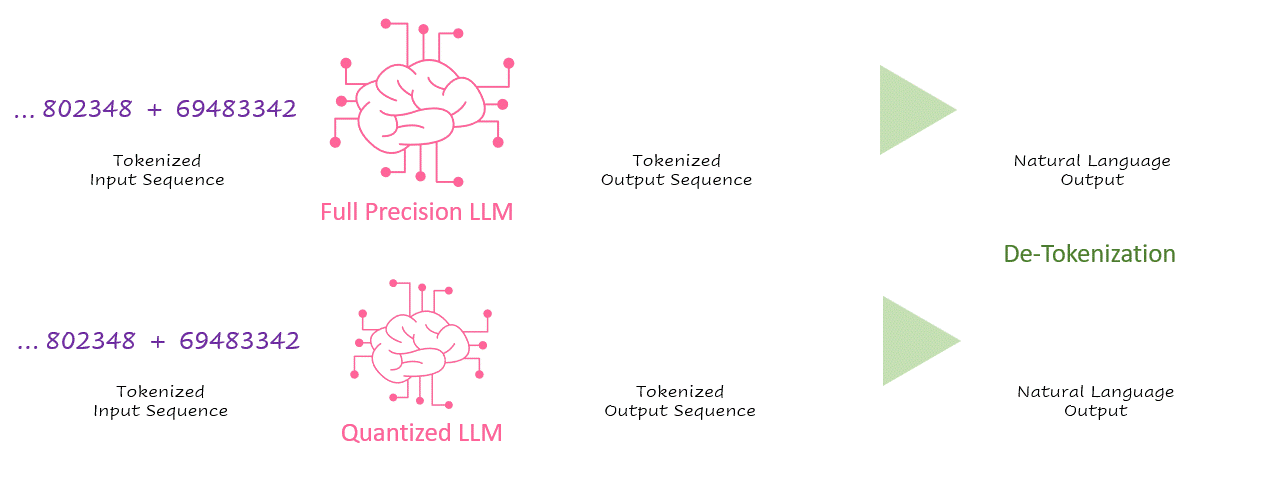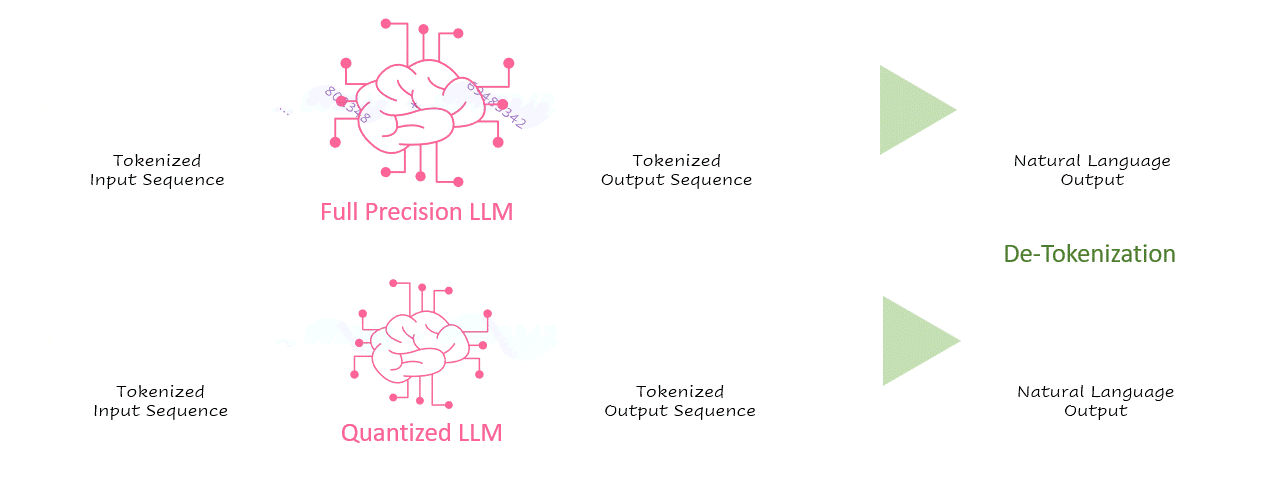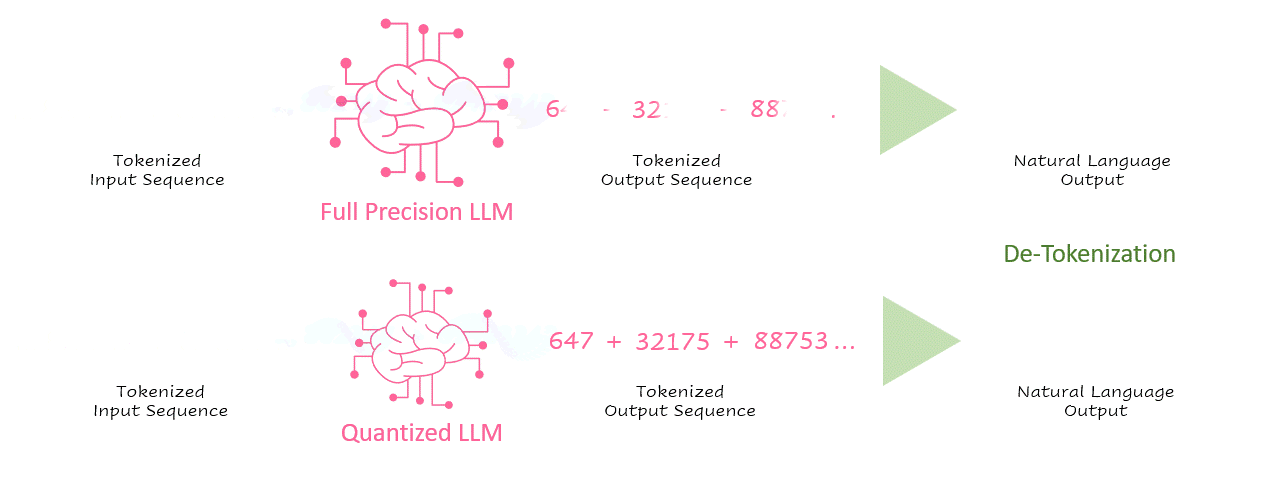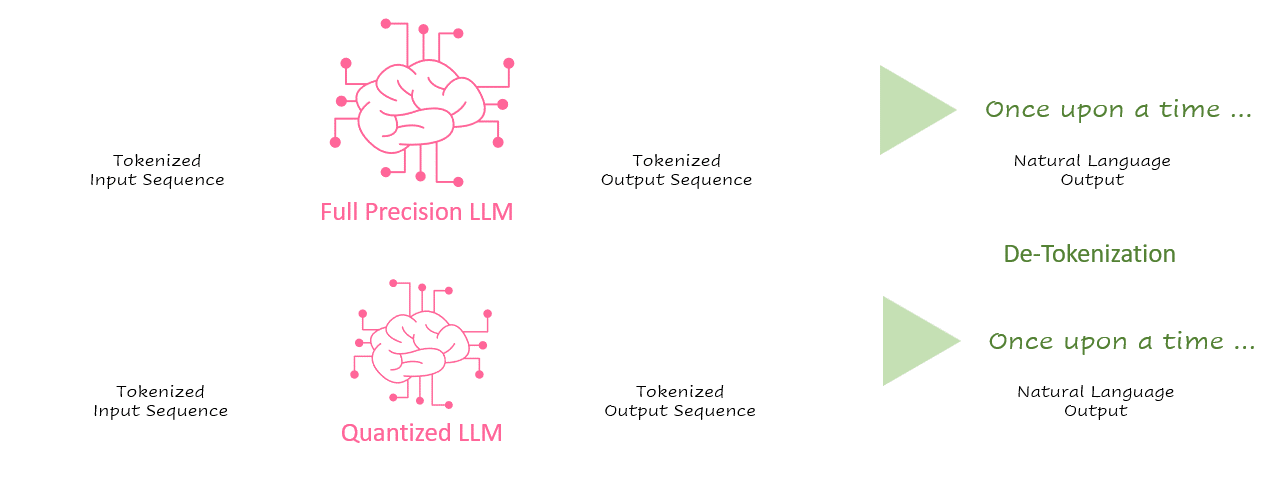
Awesome LLM compression research papers and tools to accelerate LLM training and inference.
Papers in each category are grouped by year in collapsible blocks, newest first — click a year to expand it. The current year is expanded by default.
Contents
Papers
Survey
2026 · 6 papers
-
Dynamic Model Routing and Cascading for Efficient LLM Inference: A Survey
Arxiv 2026 [Paper] -
A Survey of On-Policy Distillation for Large Language Models
Arxiv 2026 [Paper] -
Unifying Data, Memory, and Compute Efficiency in LLM training: A Survey
TAI 2026 [Paper] -
From Tensor Buffer to Distributed Memory Hierarchy: A Survey of KV Cache Management for LLM Serving
Arxiv 2026 [Paper] -
Towards Efficient Large Language Model Serving: A Survey on System-Aware KV Cache Optimization
ACL Findings 2026 [Paper] -
Accelerating Masked Diffusion Large Language Models: A Survey of Efficient Inference Techniques
IJCAI-ECAI 2026 (Survey Track) [Paper]
2025 · 14 papers
-
Compressed but Compromised? A Study of Jailbreaking in Compressed LLMs
NeurIPS Lock-LLM Workshop 2025 [Paper] [Blog] -
Scaling Down, Serving Fast: Compressing and Deploying Efficient LLMs for Recommendation Systems
EMNLP 2025 [Paper] -
Key, Value, Compress: A Systematic Exploration of KV Cache Compression Techniques
CICC 2025 [Paper] -
Are We There Yet? A Measurement Study of Efficiency for LLM Applications on Mobile Devices
Arxiv 2025 [Paper] -
Knowledge Distillation and Dataset Distillation of Large Language Models: Emerging Trends, Challenges, and Future Directions
Arxiv 2025 [Paper] -
An Empirical Study on Prompt Compression for Large Language Models
Building Trust Workshop @ ICLR 2025 2025 [Paper] [PCToolkit] -
Low-Precision Training of Large Language Models: Methods, Challenges, and Opportunities
Arxiv 2025 [Paper] [GitHub Page] -
Optimizing LLMs for Resource-Constrained Environments: A Survey of Model Compression Techniques
COMPSAC 2025 [Paper] -
A Survey on Inference Engines for Large Language Models: Perspectives on Optimization and Efficiency
Arxiv 2025 [Paper] [GitHub Page] -
EfficientLLM: Efficiency in Large Language Models
Arxiv 2025 [Paper] [Homepage] [Huggingface Page] -
KV Cache Compression for Inference Efficiency in LLMs: A Review
Arxiv 2025 [Paper] -
A Survey on Parallel Text Generation: From Parallel Decoding to Diffusion Language Models
Arxiv 2025 [Paper] [Code] -
A Survey on Collaborating Small and Large Language Models for Performance, Cost-effectiveness, Cloud-edge Privacy, and Trustworthiness
Arxiv 2025 [Paper] [Code] -
A Survey on Efficient Large Language Model Training: From Data-centric Perspectives
ACL 2025 [Paper] [Code]


2024 · 17 papers
-
Understanding LLMs: A Comprehensive Overview from Training to Inference
Arxiv 2024 [Paper] -
Faster and Lighter LLMs: A Survey on Current Challenges and Way Forward
IJCAI 2024 (Survey Track) [Paper] [GitHub Page] -
A Survey of Resource-efficient LLM and Multimodal Foundation Models
Arxiv 2024 [Paper] -
A Survey on Hardware Accelerators for Large Language Models
Arxiv 2024 [Paper] -
A Comprehensive Survey of Compression Algorithms for Language Models
Arxiv 2024 [Paper] -
A Survey on Transformer Compression
Arxiv 2024 [Paper] -
Model Compression and Efficient Inference for Large Language Models: A Survey
Arxiv 2024 [Paper] -
LLM Inference Unveiled: Survey and Roofline Model Insights
Arxiv 2024 [Paper] -
A Survey on Knowledge Distillation of Large Language Models
Arxiv 2024 [Paper] [GitHub Page] -
Efficient Prompting Methods for Large Language Models: A Survey
Arxiv 2024 [Paper] -
Survey on Knowledge Distillation for Large Language Models: Methods, Evaluation, and Application
Arxiv 2024 [Paper] -
On-Device Language Models: A Comprehensive Review
Arxiv 2024 [Paper] [Download On-device LLMs] -
A Survey of Low-bit Large Language Models: Basics, Systems, and Algorithms
Arxiv 2024 [Paper] -
Contextual Compression in Retrieval-Augmented Generation for Large Language Models: A Survey
Arxiv 2024 [Paper] -
Prompt Compression for Large Language Models: A Survey
Arxiv 2024 [Paper] -
A Comprehensive Study on Quantization Techniques for Large Language Models
Arxiv 2024 [Paper] -
A Survey on Large Language Model Acceleration based on KV Cache Management
TMLR 2025 [Paper]
2023 · 5 papers
-
A Survey on Model Compression for Large Language Models
TACL [Paper] -
The Cost of Compression: Investigating the Impact of Compression on Parametric Knowledge in Language Models
EMNLP 2023 [Paper] [Code] -
The Efficiency Spectrum of Large Language Models: An Algorithmic Survey
Arxiv 2023 [Paper] -
Efficient Large Language Models: A Survey
TMLR [Paper] [GitHub Page] -
Towards Efficient Generative Large Language Model Serving: A Survey from Algorithms to Systems
ICML 2024 Tutorial [Paper] [Tutorial]

Quantization
2026 · 56 papers
-
Can Large Language Models Still Explain Themselves? Investigating the Impact of Quantization on Self-Explanations
EMNLP Findings 2026 [Paper] -
QSLM: A Performance- and Memory-aware Quantization Framework with Tiered Search Strategy for Spike-driven Language Models
DATE 2026 [Paper] -
HAS-VQ: Hessian-Adaptive Sparse Vector Quantization for High-Fidelity LLM Compression
Arxiv 2026 [Paper] [Code] -
ARCQuant: Boosting NVFP4 Quantization with Augmented Residual Channels for LLMs
ACL 2026 [Paper] -
Sherry: Hardware-Efficient 1.25-Bit Ternary Quantization via Fine-grained Sparsification
Arxiv 2026 [Paper] [Code] -
Calibrating Beyond English: Language Diversity for Better Quantized Multilingual LLM
EACL 2026 [Paper] -
M2XFP: A Metadata-Augmented Microscaling Data Format for Efficient Low-bit Quantization
ASPLOS 2026 [Paper] -
Quartet II: Accurate LLM Pre-Training in NVFP4 by Improved Unbiased Gradient Estimation
Arxiv 2026 [Paper] [Code] -
Two-Stage Grid Optimization for Group-wise Quantization of LLMs
ICASSP 2026 [Paper] -
Quantized Evolution Strategies: High-precision Fine-tuning of Quantized LLMs at Low-precision Cost
Arxiv 2026 [Paper] [Code] -
QVLA: Not All Channels Are Equal in Vision-Language-Action Model's Quantization
ICLR 2026 [Paper] -
TurboBoA: Faster and Exact Attention-aware Quantization without Backpropagation
ICLR 2026 [Paper] -
RaBiT: Residual-Aware Binarization Training for Accurate and Efficient LLMs
ICML 2026 [Paper] -
NanoQuant: Efficient Sub-1-Bit Quantization of Large Language Models
ICML 2026 [Paper] -
On the Importance of a Multi-Scale Calibration for Quantization
ICASSP 2026 [Paper] -
QTALE: Quantization-Robust Token-Adaptive Layer Execution for LLMs
ICML 2026 [Paper] -
QuRL: Efficient Reinforcement Learning with Quantized Rollout
ICLR 2026 [Paper] -
SPQ: An Ensemble Technique for Large Language Model Compression
LREC 2026 [Paper] [Code] -
Quant Experts: Token-aware Adaptive Error Reconstruction with Mixture of Experts for Large Vision-Language Models Quantization
CVPR 2026 [Paper] -
MASQuant: Modality-Aware Smoothing Quantization for Multimodal Large Language Models
CVPR 2026 [Paper] -
SliderQuant: Accurate Post-Training Quantization for LLMs
ICLR 2026 [Paper] [Code] -
OneComp: One-Line Revolution for Generative AI Model Compression
Arxiv 2026 [Paper] [Code] -
Fast NF4 Dequantization Kernels for Large Language Model Inference
ASPLOS 2026 Workshop [Paper] -
RUQuant: Towards Refining Uniform Quantization for Large Language Models
KDD 2026 [Paper] -
SEPTQ: A Simple and Effective Post-Training Quantization Paradigm for Large Language Models
KDD 2025 [Paper] -
ReSpinQuant: Efficient Layer-Wise LLM Quantization via Subspace Residual Rotation Approximation
ICML 2026 [Paper] -
Robust Ultra Low-Bit Post-Training Quantization via Stable Diagonal Curvature Estimate
MLSys 2026 [Paper] -
AQPIM: Breaking the PIM Capacity Wall for LLMs with In-Memory Activation Quantization
HPCA 2026 [Paper] -
From Signal Degradation to Computation Collapse: Uncovering the Two Failure Modes of LLM Quantization
ACL Findings 2026 [Paper] -
Statistically-Lossless Quantization of Large Language Models
Arxiv 2026 [Paper] [Code] -
EdgeRazor: A Lightweight Framework for Large Language Models via Mixed-Precision Quantization-Aware Distillation
Arxiv 2026 [Paper] [Code] [Model] [Playground] -
OSAQ: Outlier Self-Absorption for Accurate Low-bit LLM Quantization
ICML 2026 [Paper] -
Normalized Architectures are Natively 4-Bit
Arxiv 2026 [Paper] [Code] -
RQ-MoE: Residual Quantization via Mixture of Experts for Efficient Input-Dependent Vector Compression
ICML 2026 [Paper] -
XFP: Quality-Targeted Adaptive Codebook Quantization with Sparse Outlier Separation for LLM Inference
Arxiv 2026 [Paper] [Code] -
GEMQ: Global Expert-Level Mixed-Precision Quantization for MoE LLMs
ICML 2026 [Paper] [Code] -
EVA: Accelerating LLM Decoding via an Efficient Vector Quantization Architecture
ISCA 2026 [Paper] -
Influence-Inspired Spectral Rotations for Extreme Low-Bit LLM Quantization
Arxiv 2026 [Paper] [Code] -
InfoQuant: Shaping Activation Distributions for Low-Bit LLM Quantization
Arxiv 2026 [Paper] [Code] -
LFQ: Logit-aware Final-block Quantization for Boosting the Generation Quality of Low-Bit Quantized LLMs
ICML 2026 [Paper] -
LiftQuant: Continuous Bit-Width LLM via Dimensional Lifting and Projection
ICML 2026 [Paper] -
UniSVQ: 2-bit Unified Scalar-Vector Quantization
ICML 2026 [Paper] -
LC-QAT: Data-Efficient 2-Bit QAT for LLMs via Linear-Constrained Vector Quantization
ICML 2026 [Paper] -
TWLA: Achieving Ternary Weights and Low-Bit Activations for LLMs via Post-Training Quantization
ICML 2026 [Paper] -
CAT-Q: Cost-efficient and Accurate Ternary Quantization for LLMs
ICML 2026 [Paper] [Code] -
Quantize the Target, Quantize the Drafter: Efficient Inference with Qwen3.5-4B
Arxiv 2026 [Paper] [Code] -
KronQ: LLM Quantization via Kronecker-Factored Hessian
COLM 2026 [Paper] -
Rethinking Small VLM Quantization: From Component-Wise Analysis to Hardware-Aware Edge Deployment
ICML 2026 Workshop [Paper] -
Reliability Scaling Laws for Quantized Large Language Models
TMLR 2026 [Paper] -
PolyQ: Codesigning End-to-End Quantization Framework for Scalable Edge CPU LLM Inference
ICCAD 2026 [Paper] -
ExaGEMM: Exploration Framework for CPU-Driven ML Inference via Associative In-Register Computing for Low-Bit GEMM
ICCAD 2026 [Paper] -
GyRot: Leveraging Hidden Synergy between Rotation and Fine-grained Group Quantization for Low-bit LLM Inference
HPCA 2026 [Paper] -
Attend to Your Own Thoughts: Breaking the Barrier for Post-Training Quantization of Reasoning LLMs through the Lens of 1.58-Bit Quantization
Arxiv 2026 [Paper] [Code] -
ARCHead: Activation-Metric Residual Correction for Large Language Model Output Heads
Arxiv 2026 [Paper] [Code] -
Compress and Forget: bitsandbytes Quantization Amplifies Proactive Interference in LLMs
Arxiv 2026 [Paper] [Code] -
Jacobian-guided Noise Injection for Quantization Robustness in Large Language Models
ICML 2026 [Paper]


2025 · 118 papers
-
HALO: Hadamard-Assisted Lower-Precision Optimization for LLMs
Arxiv 2025 [Paper] -
RaZeR: Pushing the Limits of NVFP4 Quantization with Redundant Zero Remapping
Arxiv 2025 [Paper] -
FlexQuant: Elastic Quantization Framework for Locally Hosted LLM on Edge Devices
Arxiv 2025 [Paper] -
Rethinking Post-Training Quantization: Introducing a Statistical Pre-Calibration Approach
Arxiv 2025 [Paper] -
Qrazor: Reliable and effortless 4-bit llm quantization by significant data razoring
Arxiv 2025 [Paper] -
OstQuant: Refining Large Language Model Quantization with Orthogonal and Scaling Transformations for Better Distribution Fitting
ICLR 2025 [Paper] [Code] -
SwiftPrune: Hessian-Free Weight Pruning for Large Language Models
Arxiv 2025 [Paper] -
Progressive Binarization with Semi-Structured Pruning for LLMs
Arxiv 2025 [Paper] [Code] -
Physics-Inspired Binary Neural Networks: Interpretable Compression with Theoretical Guarantees
Arxiv 2025 [Paper] -
QuEST: Stable Training of LLMs with 1-Bit Weights and Activations
Arxiv 2025 [Paper] -
ParetoQ: Scaling Laws in Extremely Low-bit LLM Quantization
NeurIPS 2025 [Paper] -
Systematic Outliers in Large Language Models
ICLR 2025 [Paper] [Code] -
Can Post-Training Quantization Benefit from an Additional QLoRA Integration?
NAACL 2025 [Paper] -
1bit-Merging: Dynamic Quantized Merging for Large Language Models
Arxiv 2025 [Paper] -
Towards Efficient Pre-training: Exploring FP4 Precision in Large Language Models
Arxiv 2025 [Paper] -
Continual Quantization-Aware Pre-Training: When to transition from 16-bit to 1.58-bit pre-training for BitNet language models?
Arxiv 2025 [Paper] -
QuZO: Quantized Zeroth-Order Fine-Tuning for Large Language Models
Arxiv 2025 [Paper] -
Benchmarking Post-Training Quantization in LLMs: Comprehensive Taxonomy, Unified Evaluation, and Comparative Analysis
Arxiv 2025 [Paper] -
Compression Scaling Laws:Unifying Sparsity and Quantization
Arxiv 2025 [Paper] -
M-ANT: Efficient Low-bit Group Quantization for LLMs via Mathematically Adaptive Numerical Type
Arxiv 2025 [Paper] -
Identifying Sensitive Weights via Post-quantization Integral
Arxiv 2025 [Paper] -
RSQ: Learning from Important Tokens Leads to Better Quantized LLMs
Arxiv 2025 [Paper] [Code] -
VQ-LLM: High-performance Code Generation for Vector Quantization Augmented LLM Inference
HPCA 2025 [Paper] -
Universality of Layer-Level Entropy-Weighted Quantization Beyond Model Architecture and Size
Arxiv 2025 [Paper] -
Towards Superior Quantization Accuracy: A Layer-sensitive Approach
Arxiv 2025 [Paper] -
MergeQuant: Accurate 4-bit Static Quantization of Large Language Models by Channel-wise Calibration
Arxiv 2025 [Paper] -
ClusComp: A Simple Paradigm for Model Compression and Efficient Finetuning
Arxiv 2025 [Paper] -
DynaMo: Runtime Switchable Quantization for MoE with Cross-Dataset Adaptation
DATE 2026 [Paper] -
Cocktail: Chunk-Adaptive Mixed-Precision Quantization for Long-Context LLM Inference
DATE 2025 [Paper] -
GPTQv2: Efficient Finetuning-Free Quantization for Asymmetric Calibration
ICML 2025 [Paper] [Code] -
Task-Circuit Quantization: Leveraging Knowledge Localization and Interpretability for Compression
COLM 2025 [Paper] [Code] -
Quantization Error Propagation: Revisiting Layer-Wise Post-Training Quantization
NeurIPS 2025 [Paper] [Code] -
RaanA: A Fast, Flexible, and Data-Efficient Post-Training Quantization Algorithm
Arxiv 2025 [Paper] [Code] -
Achieving binary weight and activation for LLMs using Post-Training Quantization
Arxiv 2025 [Paper] -
DL-QAT: Weight-Decomposed Low-Rank Quantization-Aware Training for Large Language Models
EMNLP 2024 [Paper] -
Gradual Binary Search and Dimension Expansion : A general method for activation quantization in LLMs
Arxiv 2025 [Paper] -
FGMP: Fine-Grained Mixed-Precision Weight and Activation Quantization for Hardware-Accelerated LLM Inference
Arxiv 2025 [Paper] -
BitNet v2: Native 4-bit Activations with Hadamard Transformation for 1-bit LLMs
Arxiv 2025 [Paper] -
FineQ: Software-Hardware Co-Design for Low-Bit Fine-Grained Mixed-Precision Quantization of LLMs
DATE 2025 [Paper] -
Precision Where It Matters: A Novel Spike Aware Mixed-Precision Quantization Strategy for LLaMA-based Language Models
Arxiv 2025 [Paper] -
ICQuant: Index Coding enables Low-bit LLM Quantization
Arxiv 2025 [Paper] -
Radio: Rate-Distortion Optimization for Large Language Model Compression
ICML 2025 [Paper] -
Balancing Fidelity and Plasticity: Aligning Mixed-Precision Fine-Tuning with Linguistic Hierarchies
Arxiv 2025 [Paper] -
MoEQuant: Enhancing Quantization for Mixture-of-Experts Large Language Models via Expert-Balanced Sampling and Affinity Guidance
ICML 2025 [Paper] -
Grouped Sequency-arranged Rotation: Optimizing Rotation Transformation for Quantization for Free
Arxiv 2025 [Paper] -
Improving Block-Wise LLM Quantization by 4-bit Block-Wise Optimal Float (BOF4): Analysis and Variations
Arxiv 2025 [Paper] -
GuidedQuant: Large Language Model Quantization via Exploiting End Loss Guidance
ICML 2025 [Paper] [Code] -
QuantX: A Framework for Hardware-Aware Quantization of Generative AI Workloads
Arxiv 2025 [Paper] -
An Extra RMSNorm is All You Need for Fine Tuning to 1.58 Bits
Arxiv 2025 [Paper] -
ITERA-LLM: Boosting Sub-8-Bit Large Language Model Inference via Iterative Tensor Decomposition
Arxiv 2025 [Paper] -
Fine-tuning Quantized Neural Networks with Zeroth-order Optimization
ICLR 2026 [Paper] -
Scaling Law for Quantization-Aware Training
Arxiv 2025 [Paper] -
Quaff: Quantized Parameter-Efficient Fine-Tuning under Outlier Spatial Stability Hypothesis
ACL 2025 [Paper] [Code] -
Is (Selective) Round-To-Nearest Quantization All You Need?
Arxiv 2025 [Paper] -
NeUQI: Near-Optimal Uniform Quantization Parameter Initialization
ICML 2026 [Paper] -
LoTA-QAF: Lossless Ternary Adaptation for Quantization-Aware Fine-Tuning
Arxiv 2025 [Paper] [Code] -
FP4 All the Way: Fully Quantized Training of LLMs
Arxiv 2025 [Paper] [Code] -
FireQ: Fast INT4-FP8 Kernel and RoPE-aware Quantization for LLM Inference Acceleration
Arxiv 2025 [Paper] -
Rethinking the Outlier Distribution in Large Language Models: An In-depth Study
Arxiv 2025 [Paper] -
Assigning Distinct Roles to Quantized and Low-Rank Matrices Toward Optimal Weight Decomposition
ACL Findings 2025 [Paper] -
Unifying Uniform and Binary-coding Quantization for Accurate Compression of Large Language Models
ACL 2025 [Paper] -
FPTQuant: Function-Preserving Transforms for LLM Quantization
ICML 2026 [Paper] -
BAQ: Efficient Bit Allocation Quantization for Large Language Models
Arxiv 2025 [Paper] [Code] -
MoQAE: Mixed-Precision Quantization for Long-Context LLM Inference via Mixture of Quantization-Aware Experts
ACL 2025 [Paper] -
Unifying Block-wise PTQ and Distillation-based QAT for Progressive Quantization toward 2-bit Instruction-Tuned LLMs
Arxiv 2025 [Paper] -
Boost Post-Training Quantization via Null Space Optimization for Large Language Models
Arxiv 2025 [Paper] [Code] -
FlexQuant: A Flexible and Efficient Dynamic Precision Switching Framework for LLM Quantization
Arxiv 2025 [Paper] -
BTC-LLM: Efficient Sub-1-Bit LLM Quantization via Learnable Transformation and Binary Codebook
Arxiv 2025 [Paper] -
ROSAQ: Rotation-based Saliency-Aware Weight Quantization for Efficiently Compressing Large Language Models
Arxiv 2025 [Paper] -
LittleBit: Ultra Low-Bit Quantization via Latent Factorization
NeurIPS 2025 [Paper] -
BASE-Q: Bias and Asymmetric Scaling Enhanced Rotational Quantization for Large Language Models
Arxiv 2025 [Paper] [Code] -
UltraSketchLLM: Sub-1-Bit LLM Compression via Sketch and Hardware-Friendly Operators
DAC 2026 [Paper] -
DBellQuant: Breaking the Bell with Double-Bell Transformation for LLMs Post Training Binarization
Arxiv 2025 [Paper] -
any4: Learned 4-bit Numeric Representation for LLMs
ICML 2025 [Paper] -
CCQ: Convolutional Code for Extreme Low-bit Quantization in LLMs
Arxiv 2025 [Paper] -
First-Order Error Matters: Accurate Compensation for Quantized Large Language Models
AAAI 2026 [Paper] -
PoTPTQ: A Two-step Power-of-Two Post-training for LLMs
ECAI 2025 [Paper] -
EAC-MoE: Expert-Selection Aware Compressor for Mixture-of-Experts Large Language Models
ACL 2025 [Paper] -
MicroMix: Efficient Mixed-Precision Quantization with Microscaling Formats for Large Language Models
Arxiv 2025 [Paper] [Code] -
VLMQ: Token Saliency-Driven Post-Training Quantization for Vision-language Models
Arxiv 2025 [Paper] -
FlashCommunication V2: Bit Splitting and Spike Reserving for Any Bit Communication
Arxiv 2025 [Paper] -
FlexQ: Efficient Post-training INT6 Quantization for LLM Serving via Algorithm-System Co-Design
Arxiv 2025 [Paper] [Code] -
Provable Post-Training Quantization: Theoretical Analysis of OPTQ and Qronos
Arxiv 2025 [Paper] -
iFairy: the First 2-bit Complex LLM with All Parameters in ${\pm1, \pm i}$
Arxiv 2025 [Paper] -
Pushing the Envelope of LLM Inference on AI-PC and Intel GPUs
Arxiv 2025 [Paper] -
Rethinking 1-bit Optimization Leveraging Pre-trained Large Language Models
Arxiv 2025 [Paper] -
Efficient Edge LLMs Deployment via HessianAware Quantization and CPU GPU Collaborative
Arxiv 2025 [Paper] -
Profiling Large Language Model Inference on Apple Silicon: A Quantization Perspective
Arxiv 2025 [Paper] -
LLM Compression: How Far Can We Go in Balancing Size and Performance?
RANLP 2025 [Paper] -
DLLMQuant: Quantizing Diffusion-based Large Language Models
Arxiv 2025 [Paper] -
Quantization Meets dLLMs: A Systematic Study of Post-training Quantization for Diffusion LLMs
Machine Intelligence Research 2025 [Paper] -
Systematic Characterization of LLM Quantization: A Performance, Energy, and Quality Perspective
Arxiv 2025 [Paper] -
Interpreting the Effects of Quantization on LLMs
AACL 2025 [Paper] -
Task-Stratified Knowledge Scaling Laws for Post-Training Quantized Large Language Models
ACL Findings 2026 [Paper] -
APT-LLM: Exploiting Arbitrary-Precision Tensor Core Computing for LLM Acceleration
TCAD 2025 [Paper] -
Quantized but Deceptive? A Multi-Dimensional Truthfulness Evaluation of Quantized LLMs
EMNLP 2025 [Paper] -
The Uneven Impact of Post-Training Quantization in Machine Translation
Arxiv 2025 [Paper] -
BitROM: Weight Reload-Free CiROM Architecture Towards Billion-Parameter 1.58-bit LLM Inference
ASP-DAC 2026 [Paper] -
AMQ: Enabling AutoML for Mixed-precision Weight-Only Quantization of Large Language Models
EMNLP 2025 [Paper] -
Fair-GPTQ: Bias-Aware Quantization for Large Language Models
Arxiv 2025 [Paper] -
QWHA: Quantization-Aware Walsh-Hadamard Adaptation for Parameter-Efficient Fine-Tuning on Large Language Models
ICLR 2026 [Paper] -
Q-Palette: Fractional-Bit Quantizers Toward Optimal Bit Allocation for Efficient LLM Deployment
NeurIPS 2025 [Paper] -
AnyBCQ: Hardware Efficient Flexible Binary-Coded Quantization for Multi-Precision LLMs
ICLR 2026 [Paper] -
QeRL: Beyond Efficiency -- Quantization-enhanced Reinforcement Learning for LLMs
Arxiv 2025 [Paper] [Code] -
F-BFQ: Flexible Block Floating-Point Quantization Accelerator for LLMs
ISCA 2025 Workshop [Paper] -
Learning Grouped Lattice Vector Quantizers for Low-Bit LLM Compression
NeurIPS 2025 [Paper] -
A Convergence Analysis of Adaptive Optimizers under Floating-point Quantization
ICLR 2026 [Paper] -
FALQON: Accelerating LoRA Fine-tuning with Low-Bit Floating-Point Arithmetic
NeurIPS 2025 [Paper] -
TetraJet-v2: Accurate NVFP4 Training for Large Language Models with Oscillation Suppression and Outlier Control
ICML 2026 [Paper] -
DartQuant: Efficient Rotational Distribution Calibration for LLM Quantization
NeurIPS 2025 [Paper] -
You Had One Job: Per-Task Quantization Using LLMs' Hidden Representations
ICML 2026 Workshop [Paper] -
P3-LLM: An Integrated NPU-PIM Accelerator for Edge LLM Inference Using Hybrid Numerical Formats
ISCA 2026 [Paper] -
ParoQuant: Pairwise Rotation Quantization for Efficient Reasoning LLM Inference
ICLR 2026 [Paper] [Code] -
SpecQuant: Spectral Decomposition and Adaptive Truncation for Ultra-Low-Bit LLMs Quantization
AAAI 2026 [Paper] -
T-SAR: A Full-Stack Co-design for CPU-Only Ternary LLM Inference via In-Place SIMD ALU Reorganization
DATE 2026 [Paper] -
Enhancing Trustworthiness with Mixed Precision: Benchmarks, Opportunities, and Challenges
ASP-DAC 2026 [Paper] -
SignRoundV2: Toward Closing the Performance Gap in Extremely Low-Bit Post-Training Quantization for LLMs
Arxiv 2025 [Paper] [Code] -
CodeGEMM: A Codebook-Centric Approach to Efficient GEMM in Quantized LLMs
NeurIPS 2025 [Paper]


2024 · 162 papers
-
FlightLLM: Efficient Large Language Model Inference with a Complete Mapping Flow on FPGA
FPGA 2024 [Paper] -
Extreme Compression of Large Language Models via Additive Quantization
ICML 2024 [Paper] [Code] -
Quantized Side Tuning: Fast and Memory-Efficient Tuning of Quantized Large Language Models
Arxiv 2024 [Paper] -
Inferflow: an Efficient and Highly Configurable Inference Engine for Large Language Models
Arxiv 2024 [Paper] -
FP6-LLM: Efficiently Serving Large Language Models Through FP6-Centric Algorithm-System Co-Design
USENIX ATC 2024 [Paper] -
Can Large Language Models Understand Context?
EACL Findings 2024 [Paper] -
Squat: Quant Small Language Models on the Edge
ICCAD 2025 [Paper] [Code] -
LQER: Low-Rank Quantization Error Reconstruction for LLMs
ICML 2024 [Paper] -
BiLLM: Pushing the Limit of Post-Training Quantization for LLMs
Arxiv 2024 [Paper] [Code] -
QuIP#: Even Better LLM Quantization with Hadamard Incoherence and Lattice Codebooks
ICML 2024 [Paper] [Code] -
L4Q: Parameter Efficient Quantization-Aware Training on Large Language Models via LoRA-wise LSQ
Arxiv 2024 [Paper] -
TP-Aware Dequantization
Arxiv 2024 [Paper] -
ApiQ: Finetuning of 2-Bit Quantized Large Language Model
EMNLP 2024 [Paper] -
Accurate LoRA-Finetuning Quantization of LLMs via Information Retention
Arxiv 2024 [Paper] [Code] -
BitDelta: Your Fine-Tune May Only Be Worth One Bit
NeurIPS 2024 [Paper] [Code] -
QDyLoRA: Quantized Dynamic Low-Rank Adaptation for Efficient Large Language Model Tuning
EMNLP 2024 Industry Track [Paper] -
Any-Precision LLM: Low-Cost Deployment of Multiple, Different-Sized LLMs
ICML 2024 [Paper] -
BitDistiller: Unleashing the Potential of Sub-4-Bit LLMs via Self-Distillation
ACL 2024 [Paper] [Code] -
OneBit: Towards Extremely Low-bit Large Language Models
NeurIPS 2024 [Paper] -
DB-LLM: Accurate Dual-Binarization for Efficient LLMs
ACL Findings 2024 [Paper] -
WKVQuant: Quantizing Weight and Key/Value Cache for Large Language Models Gains More
Arxiv 2024 [Paper] -
GPTVQ: The Blessing of Dimensionality for LLM Quantization
Arxiv 2024 [Paper] [Code] -
APTQ: Attention-aware Post-Training Mixed-Precision Quantization for Large Language Models
DAC 2024 [Paper] -
A Comprehensive Evaluation of Quantization Strategies for Large Language Models
ACL Findings 2024 [Paper] -
Evaluating Quantized Large Language Models
Arxiv 2024 [Paper] -
FlattenQuant: Breaking Through the Inference Compute-bound for Large Language Models with Per-tensor Quantization
Arxiv 2024 [Paper] -
LLM-PQ: Serving LLM on Heterogeneous Clusters with Phase-Aware Partition and Adaptive Quantization
Arxiv 2024 [Paper] -
IntactKV: Improving Large Languagze Model Quantization by Keeping Pivot Tokens Intact
ACL Findings 2024 [Paper] [Code] -
On the Compressibility of Quantized Large Language Models
Arxiv 2024 [Paper] -
EasyQuant: An Efficient Data-free Quantization Algorithm for LLMs
Arxiv 2024 [Paper] -
What Makes Quantization for Large Language Models Hard? An Empirical Study from the Lens of Perturbation
Arxiv 2024 [Paper] -
AffineQuant: Affine Transformation Quantization for Large Language Models
ICLR 2024 [Paper] [Code] -
Oh! We Freeze: Improving Quantized Knowledge Distillation via Signal Propagation Analysis for Large Language Models
ICLR Practical ML for Low Resource Settings Workshop 2024 [Paper] -
Accurate Block Quantization in LLMs with Outliers
Arxiv 2024 [Paper] -
QuaRot: Outlier-Free 4-Bit Inference in Rotated LLMs
Arxiv 2024 [Paper] [Code] -
Minimize Quantization Output Error with Bias Compensation
Arxiv 2024 [Paper] [Code] -
Cherry on Top: Parameter Heterogeneity and Quantization in Large Language Models
Arxiv 2024 [Paper] -
Fine-Tuning, Quantization, and LLMs: Navigating Unintended Outcomes
Arxiv 2024 [Paper] -
Quantization of Large Language Models with an Overdetermined Basis
Arxiv 2024 [Paper] -
An empirical study of LLaMA3 quantization: from LLMs to MLLMs
Arxiv 2024 [Paper] [Code] -
How to Parameterize Asymmetric Quantization Ranges for Quantization-Aware Training
Arxiv 2024 [Paper] -
Mitigating the Impact of Outlier Channels for Language Model Quantization with Activation Regularization
Arxiv 2024 [Paper] [Code] -
When Quantization Affects Confidence of Large Language Models?
NAACL 2024 [Paper] -
QServe: W4A8KV4 Quantization and System Co-design for Efficient LLM Serving
Arxiv 2024 [Paper] [Code] -
Learning from Students: Applying t-Distributions to Explore Accurate and Efficient Formats for LLMs
ICML 2024 [Paper] -
LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit
EMNLP 2024 [Paper] [Code] -
SKVQ: Sliding-window Key and Value Cache Quantization for Large Language Models
Arxiv 2024 [Paper] -
Post Training Quantization of Large Language Models with Microscaling Formats
Arxiv 2024 [Paper] -
Edge Intelligence Optimization for Large Language Model Inference with Batching and Quantization
Arxiv 2024 [Paper] -
SliM-LLM: Salience-Driven Mixed-Precision Quantization for Large Language Models
Arxiv 2024 [Paper] [Code] -
OAC: Output-adaptive Calibration for Accurate Post-training Quantization
Arxiv 2024 [Paper] -
PV-Tuning: Beyond Straight-Through Estimation for Extreme LLM Compression
Arxiv 2024 [Paper] -
SpinQuant -- LLM quantization with learned rotations
ICLR 2025 [Paper] -
Compressing Large Language Models using Low Rank and Low Precision Decomposition
NeurIPS 2024 [Paper] [Code] -
Athena: Efficient Block-Wise Post-Training Quantization for Large Language Models Using Second-Order Matrix Derivative Information
Arxiv 2024 [Paper] -
Exploiting LLM Quantization
Arxiv 2024 [Paper] -
One QuantLLM for ALL: Fine-tuning Quantized LLMs Once for Efficient Deployments
Arxiv 2024 [Paper] -
LCQ: Low-Rank Codebook based Quantization for Large Language Models
Arxiv 2024 [Paper] -
LoQT: Low Rank Adapters for Quantized Training
Arxiv 2024 [Paper] [Code] -
CLAQ: Pushing the Limits of Low-Bit Post-Training Quantization for LLMs
Arxiv 2024 [Paper] -
I-LLM: Efficient Integer-Only Inference for Fully-Quantized Low-Bit Large Language Models
Arxiv 2024 [Paper] -
Outliers and Calibration Sets have Diminishing Effect on Quantization of Modern LLMs
Arxiv 2024 [Paper] -
DuQuant: Distributing Outliers via Dual Transformation Makes Stronger Quantized LLMs
NeurIPS 2024 [Paper] [Code] -
ShiftAddLLM: Accelerating Pretrained LLMs via Post-Training Multiplication-Less Reparameterization
NeurIPS 2024 [Paper] [Code] -
Low-Rank Quantization-Aware Training for LLMs
Arxiv 2024 [Paper] -
TernaryLLM: Ternarized Large Language Model
Arxiv 2024 [Paper] -
Examining Post-Training Quantization for Mixture-of-Experts: A Benchmark
Arxiv 2024 [Paper] [Code] -
Delta-CoMe: Training-Free Delta-Compression with Mixed-Precision for Large Language Models
NeurIPS 2024 [Paper] -
QQQ: Quality Quattuor-Bit Quantization for Large Language Models
Arxiv 2024 [Paper] [Code] -
QTIP: Quantization with Trellises and Incoherence Processing
NeurIPS 2024 [Paper] [Code] -
Prefixing Attention Sinks can Mitigate Activation Outliers for Large Language Model Quantization
EMNLP 2024 [Paper] -
Mixture of Scales: Memory-Efficient Token-Adaptive Binarization for Large Language Models
NeurIPS 2024 [Paper] -
Tender: Accelerating Large Language Models via Tensor Decomposition and Runtime Requantization
ISCA 2024 [Paper] -
SDQ: Sparse Decomposed Quantization for LLM Inference
Arxiv 2024 [Paper] -
Attention-aware Post-training Quantization without Backpropagation
ICML 2025 [Paper] -
EDGE-LLM: Enabling Efficient Large Language Model Adaptation on Edge Devices via Layerwise Unified Compression and Adaptive Layer Tuning and Voting
Arxiv 2024 [Paper] [Code] -
Compensate Quantization Errors: Make Weights Hierarchical to Compensate Each Other
Arxiv 2024 [Paper] -
Layer-Wise Quantization: A Pragmatic and Effective Method for Quantizing LLMs Beyond Integer Bit-Levels
Arxiv 2024 [Paper] [Code] -
CDQuant: Greedy Coordinate Descent for Accurate LLM Quantization
Arxiv 2024 [Paper] -
OutlierTune: Efficient Channel-Wise Quantization for Large Language Models
Arxiv 2024 [Paper] -
T-MAC: CPU Renaissance via Table Lookup for Low-Bit LLM Deployment on Edge
EuroSys 2025 [Paper] [Code] -
GPTQT: Quantize Large Language Models Twice to Push the Efficiency
ICORIS 2024 [Paper] -
Improving Conversational Abilities of Quantized Large Language Models via Direct Preference Alignment
ACL 2024 [Paper] -
How Does Quantization Affect Multilingual LLMs?
EMNLP Findings 2024 [Paper] -
RoLoRA: Fine-tuning Rotated Outlier-free LLMs for Effective Weight-Activation Quantization
EMNLP Findings 2024 [Paper] [Code] -
Q-GaLore: Quantized GaLore with INT4 Projection and Layer-Adaptive Low-Rank Gradients
Arxiv 2024 [Paper] [Code] -
FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision
Arxiv 2024 [Paper] [Code] -
Accuracy is Not All You Need
Arxiv 2024 [Paper] -
BitNet b1.58 Reloaded: State-of-the-art Performance Also on Smaller Networks
Arxiv 2024 [Paper] -
LeanQuant: Accurate Large Language Model Quantization with Loss-Error-Aware Grid
ICLR 2025 [Paper] -
Fast Matrix Multiplications for Lookup Table-Quantized LLMs
EMNLP Findings 2024 [Paper] [Code] -
EfficientQAT: Efficient Quantization-Aware Training for Large Language Models
ACL 2025 [Paper] [Code] -
LRQ: Optimizing Post-Training Quantization for Large Language Models by Learning Low-Rank Weight-Scaling Matrices
NAACL 2025 [Paper] -
Exploring Quantization for Efficient Pre-Training of Transformer Language Models
EMNLP Findings 2024 [Paper] [Code] -
Spectra: Surprising Effectiveness of Pretraining Ternary Language Models at Scale
Arxiv 2024 [Paper] [Code] -
Mamba-PTQ: Outlier Channels in Recurrent Large Language Models
Efficient Systems for Foundation Models Workshop @ ICML 2024 [Paper] -
Compensate Quantization Errors+: Quantized Models Are Inquisitive Learners
Arxiv 2024 [Paper] -
Accurate and Efficient Fine-Tuning of Quantized Large Language Models Through Optimal Balance
Arxiv 2024 [Paper] [Code] -
STBLLM: Breaking the 1-Bit Barrier with Structured Binary LLMs
Arxiv 2024 [Paper] -
Advancing Multimodal Large Language Models with Quantization-Aware Scale Learning for Efficient Adaptation
ACM MM 2024 [Paper] -
ABQ-LLM: Arbitrary-Bit Quantized Inference Acceleration for Large Language Models
AAAI 2025 [Paper] -
MARLIN: Mixed-Precision Auto-Regressive Parallel Inference on Large Language Models
Arxiv 2024 [Paper] [Code (Marlin)] [Code (Sparse Marlin)] -
Matmul or No Matmal in the Era of 1-bit LLMs
Arxiv 2024 [Paper] -
MobileQuant: Mobile-friendly Quantization for On-device Language Models
EMNLP Findings 2024 [Paper] [Code] -
GIFT-SW: Gaussian noise Injected Fine-Tuning of Salient Weights for LLMs
Arxiv 2024 [Paper] [Code] -
Foundations of Large Language Model Compression -- Part 1: Weight Quantization
Arxiv 2024 [Paper] -
OPAL: Outlier-Preserved Microscaling Quantization A ccelerator for Generative Large Language Models
DAC 2024 [Paper] -
VPTQ: Extreme Low-bit Vector Post-Training Quantization for Large Language Models
EMNLP 2024 [Paper] [Code] -
Scaling FP8 training to trillion-token LLMs
Arxiv 2024 [Paper] -
Accumulator-Aware Post-Training Quantization
Arxiv 2024 [Paper] -
Efficient Arbitrary Precision Acceleration for Large Language Models on GPU Tensor Cores
ASP-DAC 2025 [Paper] -
Rotated Runtime Smooth: Training-Free Activation Smoother for accurate INT4 inference
Arxiv 2024 [Paper] [Code] -
EXAQ: Exponent Aware Quantization For LLMs Acceleration
Arxiv 2024 [Paper] -
ARB-LLM: Alternating Refined Binarizations for Large Language Models
Arxiv 2024 [Paper] [Code] -
PrefixQuant: Eliminating Outliers by Prefixed Tokens for Large Language Models Quantization
Arxiv 2024 [Paper] [Code] -
Sketch to Adapt: Fine-Tunable Sketches for Efficient LLM Adaptation
ICML 2025 [Paper] -
Scaling Laws For Mixed Quantization
Arxiv 2024 [Paper] -
Q-VLM: Post-training Quantization for Large Vision-Language Models
NeurIPS 2024 [Paper] [Code] -
CrossQuant: A Post-Training Quantization Method with Smaller Quantization Kernel for Precise Large Language Model Compression
Arxiv 2024 [Paper] -
FlatQuant: Flatness Matters for LLM Quantization
ICML 2025 [Paper] [Code] -
DeltaDQ: Ultra-High Delta Compression for Fine-Tuned LLMs via Group-wise Dropout and Separate Quantization
Arxiv 2024 [Paper] -
QEFT: Quantization for Efficient Fine-Tuning of LLMs
EMNLP Findings 2024 [Paper] [Code] -
Continuous Approximations for Improving Quantization Aware Training of LLMs
Arxiv 2024 [Paper] -
DAQ: Density-Aware Post-Training Weight-Only Quantization For LLMs
Arxiv 2024 [Paper] -
COMET: Towards Partical W4A4KV4 LLMs Serving
Arxiv 2024 [Paper] -
Scaling laws for post-training quantized large language models
Arxiv 2024 [Paper] -
Channel-Wise Mixed-Precision Quantization for Large Language Models
Arxiv 2024 [Paper] -
Understanding the difficulty of low-precision post-training quantization of large language models
Arxiv 2024 [Paper] -
QuAILoRA: Quantization-Aware Initialization for LoRA
NeurIPS Workshop on Efficient Natural Language and Speech Processing (ENLSP-IV) 2024 [Paper] -
SDP4Bit: Toward 4-bit Communication Quantization in Sharded Data Parallelism for LLM Training
NeurIPS 2024 [Paper] -
Pyramid Vector Quantization for LLMs
Arxiv 2024 [Paper] -
TesseraQ: Ultra Low-Bit LLM Post-Training Quantization with Block Reconstruction
Arxiv 2024 [Paper] [Code] -
COAT: Compressing Optimizer states and Activation for Memory-Efficient FP8 Training
ICLR 2025 [Paper] [Code] -
GWQ: Gradient-Aware Weight Quantization for Large Language Models
Arxiv 2024 [Paper] -
"Give Me BF16 or Give Me Death"? Accuracy-Performance Trade-Offs in LLM Quantization
ACL 2025 [Paper] -
Interactions Across Blocks in Post-Training Quantization of Large Language Models
Arxiv 2024 [Paper] -
BitNet a4.8: 4-bit Activations for 1-bit LLMs
Arxiv 2024 [Paper] -
The Super Weight in Large Language Models
Arxiv 2024 [Paper] [Code] -
ASER: Activation Smoothing and Error Reconstruction for Large Language Model Quantization
AAAI 2025 [Paper] -
Towards Low-bit Communication for Tensor Parallel LLM Inference
Arxiv 2024 [Paper] -
AMXFP4: Taming Activation Outliers with Asymmetric Microscaling Floating-Point for 4-bit LLM Inference
Arxiv 2024 [Paper] [Code] -
Scaling Laws for Precision
Arxiv 2024 [Paper] -
BitMoD: Bit-serial Mixture-of-Datatype LLM Acceleration
HPCA 2025 [Paper] [Code] -
SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization
ICML 2025 [Paper] [Code] -
AutoMixQ: Self-Adjusting Quantization for High Performance Memory-Efficient Fine-Tuning
Arxiv 2024 [Paper] -
Anda: Unlocking Efficient LLM Inference with a Variable-Length Grouped Activation Data Format
HPCA 2025 [Paper] -
MixPE: Quantization and Hardware Co-design for Efficient LLM Inference
Arxiv 2024 [Paper] -
Pushing the Limits of Large Language Model Quantization via the Linearity Theorem
Arxiv 2024 [Paper] -
Low-Bit Quantization Favors Undertrained LLMs: Scaling Laws for Quantized LLMs with 100T Training Tokens
Arxiv 2024 [Paper] [Models] -
DFRot: Achieving Outlier-Free and Massive Activation-Free for Rotated LLMs with Refined Rotation
COLM 2025 [Paper] [Code] -
RILQ: Rank-Insensitive LoRA-based Quantization Error Compensation for Boosting 2-bit Large Language Model Accuracy
AAAI 2025 [Paper] -
CPTQuant -- A Novel Mixed Precision Post-Training Quantization Techniques for Large Language Models
Arxiv 2024 [Paper] -
SKIM: Any-bit Quantization Pushing The Limits of Post-Training Quantization
Arxiv 2024 [Paper] -
Direct Quantized Training of Language Models with Stochastic Rounding
Arxiv 2024 [Paper] [Code] -
Taming Sensitive Weights : Noise Perturbation Fine-tuning for Robust LLM Quantization
Arxiv 2024 [Paper] -
Low-Rank Correction for Quantized LLMs
Arxiv 2024 [Paper] -
CRVQ: Channel-relaxed Vector Quantization for Extreme Compression of LLMs
Arxiv 2024 [Paper] -
ResQ: Mixed-Precision Quantization of Large Language Models with Low-Rank Residuals
Arxiv 2024 [Paper] [Code] -
MixLLM: LLM Quantization with Global Mixed-precision between Output-features and Highly-efficient System Design
MLSys 2026 [Paper] -
GQSA: Group Quantization and Sparsity for Accelerating Large Language Model Inference
Arxiv 2024 [Paper] -
LSAQ: Layer-Specific Adaptive Quantization for Large Language Model Deployment
Arxiv 2024 [Paper] -
DecDEC: A Systems Approach to Advancing Low-Bit LLM Quantization
OSDI 2025 [Paper]


2023 · 75 papers
-
FlexRound: Learnable Rounding based on Element-wise Division for Post-Training Quantization
ICML 2023 [Paper] [Code (DeepSpeed)] -
Understanding INT4 Quantization for Transformer Models: Latency Speedup, Composability, and Failure Cases
ICML 2023 [Paper] [Code] -
The case for 4-bit precision: k-bit Inference Scaling Laws
ICML 2023 [Paper] -
PreQuant: A Task-agnostic Quantization Approach for Pre-trained Language Models
ACL 2023 [Paper] -
Boost Transformer-based Language Models with GPU-Friendly Sparsity and Quantization
ACL 2023 [Paper] -
QLoRA: Efficient Finetuning of Quantized LLMs
NeurIPS 2023 [Paper] [Code] -
The Quantization Model of Neural Scaling
NeurIPS 2023 [Paper] -
Quantized Distributed Training of Large Models with Convergence Guarantees
ICML 2023 [Paper] -
RPTQ: Reorder-based Post-training Quantization for Large Language Models
Arxiv 2023 [Paper] [Code] -
ZeroQuant-V2: Exploring Post-training Quantization in LLMs from Comprehensive Study to Low Rank Compensation
AAAI 2024 [Paper] [Code] -
Integer or Floating Point? New Outlooks for Low-Bit Quantization on Large Language Models
ICML 2024 [Paper] -
Memory-Efficient Fine-Tuning of Compressed Large Language Models via sub-4-bit Integer Quantization
NeurIPS 2023 [Paper] -
Compress, Then Prompt: Improving Accuracy-Efficiency Trade-off of LLM Inference with Transferable Prompt
Arxiv 2023 [Paper] -
AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration
MLSys 2024 (Best Paper 🏆) [Paper] [Code] -
LLM-QAT: Data-Free Quantization Aware Training for Large Language Models
ACL Findings 2024 [Paper] [Code] -
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
ICLR 2024 [Paper] [Code] -
OWQ: Outlier-Aware Weight Quantization for Efficient Fine-Tuning and Inference of Large Language Models
AAAI 2024 [Paper] -
SqueezeLLM: Dense-and-Sparse Quantization
ICML 2024 [Paper] [Code] -
INT2.1: Towards Fine-Tunable Quantized Large Language Models with Error Correction through Low-Rank Adaptation
Arxiv 2023 [Paper] -
LQ-LoRA: Low-rank Plus Quantized Matrix Decomposition for Efficient Language Model Finetuning
ICLR 2024 [Paper] -
INT-FP-QSim: Mixed Precision and Formats For Large Language Models and Vision Transformers
Arxiv 2023 [Paper] [Code] -
QIGen: Generating Efficient Kernels for Quantized Inference on Large Language Models
Arxiv 2023 [Paper] [Code] -
Do Emergent Abilities Exist in Quantized Large Language Models: An Empirical Study
COLING 2024 [Paper] -
ZeroQuant-FP: A Leap Forward in LLMs Post-Training W4A8 Quantization Using Floating-Point Formats
Arxiv 2023 [Paper] [Code (DeepSpeed)] -
OliVe: Accelerating Large Language Models via Hardware-friendly Outlier-Victim Pair Quantization
ISCA 2023 [Paper] -
NUPES : Non-Uniform Post-Training Quantization via Power Exponent Search
Arxiv 2023 [Paper] -
GPT-Zip: Deep Compression of Finetuned Large Language Models
ICML 2023 Workshop ES-FoMO [Paper] -
Generating Efficient Kernels for Quantized Inference on Large Language Models
ICML 2023 Workshop ES-FoMO [Paper] -
Gradient-Based Post-Training Quantization: Challenging the Status Quo
Arxiv 2023 [Paper] -
FineQuant: Unlocking Efficiency with Fine-Grained Weight-Only Quantization for LLMs
Arxiv 2023 [Paper] -
OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models
ICLR 2024 [Paper] [Code] -
FPTQ: Fine-grained Post-Training Quantization for Large Language Models
Arxiv 2023 [Paper] -
eDKM: An Efficient and Accurate Train-time Weight Clustering for Large Language Models
IEEE Computer Architecture Letters 2023 [Paper] -
QuantEase: Optimization-based Quantization for Language Models -- An Efficient and Intuitive Algorithm
Arxiv 2023 [Paper] -
Norm Tweaking: High-performance Low-bit Quantization of Large Language Models
AAAI 2024 [Paper] -
Understanding the Impact of Post-Training Quantization on Large-scale Language Models
Arxiv 2023 [Paper] -
MEMORY-VQ: Compression for Tractable Internet-Scale Memory
NAACL 2024 [Paper] -
Optimize Weight Rounding via Signed Gradient Descent for the Quantization of LLMs
EMNLP Findings 2024 [Paper] [Code] -
Efficient Post-training Quantization with FP8 Formats
MLSys 2024 [Paper] [Code (Intel® Neural Compressor)] -
QA-LoRA: Quantization-Aware Low-Rank Adaptation of Large Language Models
ICLR 2024 [Paper] [Code] -
Rethinking Channel Dimensions to Isolate Outliers for Low-bit Weight Quantization of Large Language Models
ICLR 2024 [Paper] [Code] -
ModuLoRA: Finetuning 3-Bit LLMs on Consumer GPUs by Integrating with Modular Quantizers
TMLR (Featured Certification 🌟) [Paper] -
PB-LLM: Partially Binarized Large Language Models
ICLR 2024 [Paper] [Code] -
Dual Grained Quantization: Efficient Fine-Grained Quantization for LLM
Arxiv 2023 [Paper] -
QLLM: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models
ICLR 2024 [Paper] [Code] -
LoftQ: LoRA-Fine-Tuning-Aware Quantization for Large Language Models
ICLR 2024 [Paper] [Code] -
QFT: Quantized Full-parameter Tuning of LLMs with Affordable Resources
ICLR 2026 Workshop [Paper] -
TEQ: Trainable Equivalent Transformation for Quantization of LLMs
Arxiv 2023 [Paper] [Code (Intel® Neural Compressor)] -
BitNet: Scaling 1-bit Transformers for Large Language Models
Arxiv 2023 [Paper] [Code] -
FP8-LM: Training FP8 Large Language Models
Arxiv 2023 [Paper] [Code] -
QUIK: Towards End-to-End 4-Bit Inference on Generative Large Language Models
EMNLP 2024 [Paper] [Code] -
AFPQ: Asymmetric Floating Point Quantization for LLMs
ACL Findings 2024 [Paper] [Code] -
AWEQ: Post-Training Quantization with Activation-Weight Equalization for Large Language Models
Arxiv 2023 [Paper] -
Atom: Low-bit Quantization for Efficient and Accurate LLM Serving
MLSys 2024 [Paper] [Code] -
QMoE: Practical Sub-1-Bit Compression of Trillion-Parameter Models
Arxiv 2023 [Paper] -
Dissecting the Runtime Performance of the Training, Fine-tuning, and Inference of Large Language Models
Arxiv 2023 [Paper] -
On the Impact of Calibration Data in Post-training Quantization and Pruning
ACL 2024 [Paper] -
A Speed Odyssey for Deployable Quantization of LLMs
Arxiv 2023 [Paper] -
Fast and Efficient 2-bit LLM Inference on GPU: 2/4/16-bit in a Weight Matrix with Asynchronous Dequantization
Arxiv 2023 [Paper] -
Quantizable Transformers: Removing Outliers by Helping Attention Heads Do Nothing
NeurIPS 2023 [Paper] [Code] -
Efficient LLM Inference on CPUs
NeurIPS 2023 on Efficient Natural Language and Speech Processing [Paper] [Code] -
The Cost of Compression: Investigating the Impact of Compression on Parametric Knowledge in Language Models
EMNLP Findings 2023 [Paper] -
Zero-Shot Sharpness-Aware Quantization for Pre-trained Language Models
EMNLP 2023 [Paper] -
Revisiting Block-based Quantisation: What is Important for Sub-8-bit LLM Inference?
EMNLP 2023 [Paper] [Code] -
Outlier Suppression+: Accurate quantization of large language models by equivalent and optimal shifting and scaling
EMNLP 2023 [Paper] -
Watermarking LLMs with Weight Quantization
EMNLP 2023 [Paper] [Code] -
Enhancing Computation Efficiency in Large Language Models through Weight and Activation Quantization
EMNLP 2023 [Paper] -
LLM-FP4: 4-Bit Floating-Point Quantized Transformers
EMNLP 2023 [Paper] [Code] -
Agile-Quant: Activation-Guided Quantization for Faster Inference of LLMs on the Edge
AAAI 2024 [Paper] -
SmoothQuant+: Accurate and Efficient 4-bit Post-Training WeightQuantization for LLM
Arxiv 2023 [Paper] -
CBQ: Cross-Block Quantization for Large Language Models
Arxiv 2023 [Paper] -
ZeroQuant(4+2): Redefining LLMs Quantization with a New FP6-Centric Strategy for Diverse Generative Tasks
Arxiv 2023 [Paper] -
QuIP: 2-Bit Quantization of Large Language Models With Guarantees
NeurIPS 2023 [Paper] [Code] -
A Performance Evaluation of a Quantized Large Language Model on Various Smartphones
Arxiv 2023 [Paper] -
DeltaZip: Efficient Serving of Multiple Full-Model-Tuned LLMs
EuroSys 2025 [Paper] [Code]


2022 · 6 papers
-
ZeroQuant: Efficient and Affordable Post-Training Quantization for Large-Scale Transformers
NeurIPS 2022 [Paper] [Code (DeepSpeed)] -
LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale
NeurIPS 2022 [Paper] [Code] -
Outlier Suppression: Pushing the Limit of Low-bit Transformer Language Models
NeurIPS 2022 [Paper] [Code] -
LUT-GEMM: Quantized Matrix Multiplication based on LUTs for Efficient Inference in Large-Scale Generative Language Models
ICLR 2024 [Paper] -
SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models
ICML 2023 [Paper] [Code] -
GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers
ICLR 2023 [Paper] [Code]


Pruning and Sparsity
2026 · 33 papers
-
Adaptive Layer Selection for Layer-Wise Token Pruning in LLM Inference
ACL Findings 2026 [Paper] [Code] -
LLMs can Compress LLMs: Adaptive Pruning by Agents
Arxiv 2026 [Paper] -
Streaming-dLLM: Accelerating Diffusion LLMs via Suffix Pruning and Dynamic Decoding
Arxiv 2026 [Paper] [Code] -
GradPruner: Gradient-Guided Layer Pruning Enabling Efficient Fine-Tuning and Inference for LLMs
ICLR 2026 [Paper] -
FASA: Frequency-aware Sparse Attention
ICLR 2026 [Paper] -
Compressing LLMs with MoP: Mixture of Pruners
Arxiv 2026 [Paper] [Code] -
Pruning as a Cooperative Game: Surrogate-Assisted Layer Contribution Estimation for Large Language Models
ICLR 2026 [Paper] -
Sink-Aware Pruning for Diffusion Language Models
Arxiv 2026 [Paper] [Code] -
Curvature-Weighted Capacity Allocation: A Minimum Description Length Framework for Layer-Adaptive Large Language Model Optimization
UAI 2026 [Paper] [Code] -
Sparse-BitNet: 1.58-bit LLMs are Naturally Friendly to Semi-Structured Sparsity
Arxiv 2026 [Paper] [Code] -
Stem: Rethinking Causal Information Flow in Sparse Attention
ICML 2026 [Paper] -
High-Fidelity Pruning for Large Language Models
Arxiv 2026 [Paper] [Code] -
Sparser, Faster, Lighter Transformer Language Models
Arxiv 2026 [Paper] [Code] -
REAM: Merging Improves Pruning of Experts in LLMs
Arxiv 2026 [Paper] [Code] -
GRASPrune: Global Gating for Budgeted Structured Pruning of Large Language Models
ACL 2026 [Paper] -
Revisiting the Effectiveness of LLM Pruning for Test-Time Scaling
EMNLP Findings 2026 [Paper] -
Compute Where it Counts: Self Optimizing Language Models
Arxiv 2026 [Paper] [Code] -
Ghosted Layers: Unconstrained Activation Alignment for Recovering Layer-Pruned LLMs
Arxiv 2026 [Paper] [Code] -
LEAP: Learnable End-to-End Adaptive Pruning of Large Language Models
ICML 2026 Workshop [Paper] -
Efficient Long-Context Modeling in Diffusion Language Models via Block Approximate Sparse Attention
CVPR 2026 [Paper] -
Locality-Aware Redundancy Pruning for LLM Depth Compression
Arxiv 2026 [Paper] [Code] -
FlashMemory-DeepSeek-V4: Lightning Index Ultra-Long Context via Lookahead Sparse Attention
Arxiv 2026 [Paper] [Code] -
Beyond FLOPs: Benchmarking Real Inference Acceleration of LLM Pruning under a GEMM-Centric Taxonomy
Arxiv 2026 [Paper] [Code] -
Persona-Pruner: Sculpting Lightweight Models for Role-Playing
ICML 2026 [Paper] [Code] -
Dustin: Draft-Augmented Sparse Verification for Efficient Long-Context Generation with Speculative Decoding
ICML 2026 [Paper] -
EPTS: Elastic Post-Training Sparsity for Efficient Large Language Model Compression
KDD 2026 [Paper] -
Super-Tuning: From Activation-Aware Pruning to Sparse Fine-Tuning
Arxiv 2026 [Paper] [Code] -
WIDE: Boosting Adaptive LLM Inference via Token-level Dynamic Width Pruning
Arxiv 2026 [Paper] [Code] -
Celty: SpMspV GPU Kernel and SIMT Co-Design for Efficient Dual-Sparse LLM Inference
ICCAD 2026 [Paper] [Code] -
Prune Once: Retraining-Free Task-Agnostic Pruning for Vision-Language Models
ECCV 2026 [Paper] -
Router Sensitivity Under Lightweight Fine-Tuning Identifies Prunable Experts in Mixture-of-Experts Models
Arxiv 2026 [Paper] [Code] -
Reservoir of Importance: Learning Semi-Structured Sparsity with Differentiable Subset Sampling
EMNLP 2026 [Paper]


2025 · 60 papers
-
FASP: Fast and Accurate Structured Pruning of Large Language Models
Arxiv 2025 [Paper] -
MultiPruner: Balanced Structure Removal in Foundation Models
Arxiv 2025 [Paper] [Code] -
Mamba-Shedder: Post-Transformer Compression for Efficient Selective Structured State Space Models
NAACL 2025 [Paper] [Code] -
2SSP: A Two-Stage Framework for Structured Pruning of LLMs
Arxiv 2025 [Paper] [Code] -
You Only Prune Once: Designing Calibration-Free Model Compression With Policy Learning
ICLR 2025 [Paper] -
SwiftPrune: Hessian-Free Weight Pruning for Large Language Models
Arxiv 2025 [Paper] -
Pivoting Factorization: A Compact Meta Low-Rank Representation of Sparsity for Efficient Inference in Large Language Models
ICML 2025 [Paper] -
Twilight: Adaptive Attention Sparsity with Hierarchical Top-p Pruning
NeurIPS 2025 [Paper] -
Adapt-Pruner: Adaptive Structural Pruning for Efficient Small Language Model Training
Arxiv 2025 [Paper] -
Dobi-SVD: Differentiable SVD for LLM Compression and Some New Perspectives
ICLR 2025 [Paper] [Homepage] -
EfficientLLM: Scalable Pruning-Aware Pretraining for Architecture-Agnostic Edge Language Models
Arxiv 2025 [Paper] [Code] -
DarwinLM: Evolutionary Structured Pruning of Large Language Models
COLM 2026 [Paper] -
MaskPrune: Mask-based LLM Pruning for Layer-wise Uniform Structures
Arxiv 2025 [Paper] -
Determining Layer-wise Sparsity for Large Language Models Through a Theoretical Perspective
Arxiv 2025 [Paper] -
PPC-GPT: Federated Task-Specific Compression of Large Language Models via Pruning and Chain-of-Thought Distillation
Arxiv 2025 [Paper] -
Compression Scaling Laws: Unifying Sparsity and Quantization
Arxiv 2025 [Paper] -
PASER: Post-Training Data Selection for Efficient Pruned Large Language Model Recovery
ICLR 2026 [Paper] -
Týr-the-Pruner: Unlocking Accurate 50% Structural Pruning for LLMs via Global Sparsity Distribution Optimization
Arxiv 2025 [Paper] -
Thanos: A Block-wise Pruning Algorithm for Efficient Large Language Model Compression
Arxiv 2025 [Paper] -
Efficient LLMs with AMP: Attention Heads and MLP Pruning
IJCNN 2025 [Paper] -
ReplaceMe: Network Simplification via Layer Pruning and Linear Transformations
NeurIPS 2025 [Paper] [Code] -
Large Language Model Compression with Global Rank and Sparsity Optimization
Arxiv 2025 [Paper] -
TRIM: Achieving Extreme Sparsity with Targeted Row-wise Iterative Metric-driven Pruning
Arxiv 2025 [Paper] [Code] -
RAP: Runtime-Adaptive Pruning for LLM Inference
Arxiv 2025 [Paper] -
Two-Stage Regularization-Based Structured Pruning for LLMs
ACL 2026 [Paper] -
Pangu Light: Weight Re-Initialization for Pruning and Accelerating LLMs
Arxiv 2025 [Paper] -
Sparsified State-Space Models are Efficient Highway Networks
TMLR 2025 [Paper] [Code] -
SDMPrune: Self-Distillation MLP Pruning for Efficient Large Language Models
Arxiv 2025 [Paper] [Code] -
Amber Pruner: Leveraging N:M Activation Sparsity for Efficient Prefill in Large Language Models
Arxiv 2025 [Paper] -
Beyond Manually Designed Pruning Policies with Second-Level Performance Prediction: A Pruning Framework for LLMs
Arxiv 2025 [Paper] [Code] -
Pruning Large Language Models by Identifying and Preserving Functional Networks
Arxiv 2025 [Paper] [Code] -
SlimInfer: Accelerating Long-Context LLM Inference via Dynamic Token Pruning
Arxiv 2025 [Paper] [Code] -
EGGS-PTP: An Expander-Graph Guided Structured Post-training Pruning Method for Large Language Models
Arxiv 2025 [Paper] -
Z-Pruner: Post-Training Pruning of Large Language Models for Efficiency without Retraining
AICCSA 2025 [Paper] [Code] -
H2EAL: Hybrid-Bonding Architecture with Hybrid Sparse Attention for Efficient Long-Context LLM Inference
ICCAD 2025 [Paper] -
Less Is More? Examining Fairness in Pruned Large Language Models for Summarising Opinions
EMNLP 2025 [Paper] [Code] -
DualSparse-MoE: Coordinating Tensor/Neuron-Level Sparsity with Expert Partition and Reconstruction
Arxiv 2025 [Paper] -
Optimal Sparsity of Mixture-of-Experts Language Models for Reasoning Tasks
ICLR 2026 [Paper] [Code] -
Spatio-Temporal Pruning for Compressed Spiking Large Language Models
Arxiv 2025 [Paper] -
Dropping Experts, Recombining Neurons: Retraining-Free Pruning for Sparse Mixture-of-Experts LLMs
EMNLP 2025 [Paper] -
Reasoning Models Can be Accurately Pruned Via Chain-of-Thought Reconstruction
Arxiv 2025 [Paper] [Code] -
NIRVANA: Structured Pruning Reimagined for Large Language Model Compression
COLM 2026 [Paper] -
HEAPr: Hessian-based Efficient Atomic Expert Pruning in Output Space
ICLR 2026 [Paper] [Code] -
ProxyAttn: Guided Sparse Attention via Representative Heads
ICLR 2026 [Paper] -
Effective Model Pruning: Measure The Redundancy of Model Components
ICML 2026 [Paper] -
The Unseen Frontier: Pushing the Limits of LLM Sparsity with Surrogate-Free ADMM
ICLR 2026 [Paper] -
ARMOR: High-Performance Semi-Structured Pruning via Adaptive Matrix Factorization
ICLR 2026 [Paper] [Code] -
RCPU: Rotation-Constrained Error Compensation for Structured Pruning of Large Language Models
ICLR 2026 [Paper] -
Fewer Weights, More Problems: A Practical Attack on LLM Pruning
ICLR 2026 [Paper] [Code] -
From Local to Global: Revisiting Structured Pruning Paradigms for Large Language Models
ACL 2026 [Paper] -
Sparser Block-Sparse Attention via Token Permutation
ICML 2026 [Paper] [Code] -
Restoring Pruned Large Language Models via Lost Component Compensation
NeurIPS 2025 [Paper] -
When Fewer Layers Break More Chains: Layer Pruning Harms Test-Time Scaling in LLMs
Arxiv 2025 [Paper] [Code] -
1+1>2: A Synergistic Sparse and Low-Rank Compression Method for Large Language Models
EMNLP Findings 2025 [Paper] -
SpecAttn: Speculating Sparse Attention
NeurIPS 2025 Workshop [Paper] -
IG-Pruning: Input-Guided Block Pruning for Large Language Models
EMNLP 2025 [Paper] [Code] -
MACKO: Sparse Matrix-Vector Multiplication for Low Sparsity
Arxiv 2025 [Paper] [Code] -
Understanding and Harnessing Sparsity in Unified Multimodal Models
Arxiv 2025 [Paper] [Code] -
Resting Neurons, Active Insights: Robustifying Activation Sparsity in LLMs via Spontaneity
ICML 2026 [Paper] -
Fragile Knowledge, Robust Instruction-Following: The Width Pruning Dichotomy in Llama-3.2
Arxiv 2025 [Paper] [Code]


2024 · 77 papers
-
Plug-and-Play: An Efficient Post-training Pruning Method for Large Language Models
ICLR 2024 [Paper] [Code] -
Fast and Optimal Weight Update for Pruned Large Language Models
Arxiv 2024 [Paper] -
APT: Adaptive Pruning and Tuning Pretrained Language Models for Efficient Training and Inference
ICML 2024 [Paper] -
Scaling Sparse Fine-Tuning to Large Language Models
Arxiv 2024 [Paper] -
SliceGPT: Compress Large Language Models by Deleting Rows and Columns
ICLR 2024 [Paper] [Code] -
Shortened LLaMA: Depth Pruning for Large Language Models with Comparison of Retraining Methods
ICLR 2024 Workshop [Paper] -
Everybody Prune Now: Structured Pruning of LLMs with only Forward Passes
Arxiv 2024 [Paper] [Code] -
NutePrune: Efficient Progressive Pruning with Numerous Teachers for Large Language Models
Arxiv 2024 [Paper] -
LaCo: Large Language Model Pruning via Layer Collapse
EMNLP Findings 2024 [Paper] -
Why Lift so Heavy? Slimming Large Language Models by Cutting Off the Layers
Arxiv 2024 [Paper] -
EBFT: Effective and Block-Wise Fine-Tuning for Sparse LLMs
Arxiv 2024 [Paper] [Code] -
Data-free Weight Compress and Denoise for Large Language Models
Arxiv 2024 [Paper] -
Gradient-Free Adaptive Global Pruning for Pre-trained Language Models
NeurIPS 2024 [Paper] -
ShortGPT: Layers in Large Language Models are More Redundant Than You Expect
Arxiv 2024 [Paper] -
LLaVA-PruMerge: Adaptive Token Reduction for Efficient Large Multimodal Models
ICCV 2025 [Paper] [Code] -
Streamlining Redundant Layers to Compress Large Language Models
Arxiv 2024 [Paper] -
LoRAP: Transformer Sub-Layers Deserve Differentiated Structured Compression for Large Language Models
Arxiv 2024 [Paper] -
LoNAS: Elastic Low-Rank Adapters for Efficient Large Language Models
COLING 2024 [Paper] [Code] -
Shears: Unstructured Sparsity with Neural Low-rank Adapter Search
NAACL 2024 [Paper] [Code] -
Eigenpruning: an Interpretability-Inspired PEFT Method
NAACL 2024 Abstract [Paper] -
OpenBA-V2: Reaching 77.3% High Compression Ratio with Fast Multi-Stage Pruning
Arxiv 2024 [Paper] -
Pruning as a Domain-specific LLM Extractor
NAACL 2024 Findings [Paper] [Code] -
Differentiable Model Scaling using Differentiable Topk
ICML 2024 [Paper] -
COPAL: Continual Pruning in Large Language Generative Models
ICML 2024 [Paper] -
Pruner-Zero: Evolving Symbolic Pruning Metric from scratch for Large Language Models
ICML 2024 [Paper] [Code] -
Feature-based Low-Rank Compression of Large Language Models via Bayesian Optimization
ACL Findings 2024 [Paper] -
Surgical Feature-Space Decomposition of LLMs: Why, When and How?
ACL 2024 [Paper] -
Pruning Large Language Models to Intra-module Low-rank Architecture with Transitional Activations
ACL Findings 2024 [Paper] -
Light-PEFT: Lightening Parameter-Efficient Fine-Tuning via Early Pruning
ACL Findings 2024 [Paper] [Code] -
Quest: Query-Aware Sparsity for Efficient Long-Context LLM Inference
ICML 2024 [Paper] [Code] -
MoreauPruner: Robust Pruning of Large Language Models against Weight Perturbations
Arxiv 2024 [Paper] [Code] -
ALPS: Improved Optimization for Highly Sparse One-Shot Pruning for Large Language Models
Arxiv 2024 [Paper] -
A Training-free Sub-quadratic Cost Transformer Model Serving Framework With Hierarchically Pruned Attention
Arxiv 2024 [Paper] -
Bypass Back-propagation: Optimization-based Structural Pruning for Large Language Models via Policy Gradient
ACL 2025 [Paper] -
BlockPruner: Fine-grained Pruning for Large Language Models
ACL Findings 2025 [Paper] [Code] -
Rethinking Pruning Large Language Models: Benefits and Pitfalls of Reconstruction Error Minimization
EMNLP 2024 [Paper] -
RankAdaptor: Hierarchical Rank Allocation for Efficient Fine-Tuning Pruned LLMs via Performance Model
Arxiv 2024 [Paper] -
What Matters in Transformers? Not All Attention is Needed
Arxiv 2024 [Paper] [Code] -
Pruning via Merging: Compressing LLMs via Manifold Alignment Based Layer Merging
EMNLP 2024 [Paper] -
ShadowLLM: Predictor-based Contextual Sparsity for Large Language Models
EMNLP 2024 [Paper] [Code] -
Finding Transformer Circuits with Edge Pruning
NeurIPS 2024 [Paper] [Code] -
Efficient Expert Pruning for Sparse Mixture-of-Experts Language Models: Enhancing Performance and Reducing Inference Costs
Arxiv 2024 [Paper] [Code] -
MINI-LLM: Memory-Efficient Structured Pruning for Large Language Models
Arxiv 2024 [Paper] -
Reconstruct the Pruned Model without Any Retraining
Arxiv 2024 [Paper] -
A deeper look at depth pruning of LLMs
ICML TF2M Workshop 2024 [Paper] [Code] -
Greedy Output Approximation: Towards Efficient Structured Pruning for LLMs Without Retraining
Arxiv 2024 [Paper] -
Pruning Large Language Models with Semi-Structural Adaptive Sparse Training
Arxiv 2024 [Paper] -
A Convex-optimization-based Layer-wise Post-training Pruner for Large Language Models
Arxiv 2024 [Paper] -
ThinK: Thinner Key Cache by Query-Driven Pruning
ICLR 2025 [Paper] -
MoDeGPT: Modular Decomposition for Large Language Model Compression
ICLR 2025 [Paper] -
LLM-Barber: Block-Aware Rebuilder for Sparsity Mask in One-Shot for Large Language Models
ICCAD 2025 [Paper] [Code] -
LLM Pruning and Distillation in Practice: The Minitron Approach
Arxiv 2024 [Paper] [Models] -
Training-Free Activation Sparsity in Large Language Models
ICLR 2025 [Paper] -
Enhancing One-shot Pruned Pre-trained Language Models through Sparse-Dense-Sparse Mechanism
COLING 2025 [Paper] -
PAT: Pruning-Aware Tuning for Large Language Models
AAAI 2025 [Paper] [Code] -
Sirius: Contextual Sparsity with Correction for Efficient LLMs
Arxiv 2024 [Paper] [Code] -
STUN: Structured-Then-Unstructured Pruning for Scalable MoE Pruning
ACL 2025 [Paper] -
DISP-LLM: Dimension-Independent Structural Pruning for Large Language Models
NeurIPS 2024 [Paper] -
Search for Efficient Large Language Models
NeurIPS 2024 [Paper] -
SlimGPT: Layer-wise Structured Pruning for Large Language Models
NeurIPS 2024 [Paper] -
Learn To be Efficient: Build Structured Sparsity in Large Language Models
NeurIPS 2024 [Paper] -
ALS: Adaptive Layer Sparsity for Large Language Models via Activation Correlation Assessment
NeurIPS 2024 [Paper] -
Getting Free Bits Back from Rotational Symmetries in LLMs
Arxiv 2024 [Paper] -
SLiM: One-shot Quantization and Sparsity with Low-rank Approximation for LLM Weight Compression
ICML 2025 [Paper] [Code] -
Self-Data Distillation for Recovering Quality in Pruned Large Language Models
MLSys 2025 [Paper] -
EvoPress: Towards Optimal Dynamic Model Compression via Evolutionary Search
Arxiv 2024 [Paper] [Code] -
Pruning Foundation Models for High Accuracy without Retraining
EMNLP Findings 2024 [Paper] [Code] -
Beware of Calibration Data for Pruning Large Language Models
ICLR 2025 [Paper] -
SQFT: Low-cost Model Adaptation in Low-precision Sparse Foundation Models
EMNLP Findings 2024 [Paper] [Code] -
Change Is the Only Constant: Dynamic LLM Slicing based on Layer Redundancy
EMNLP Findings 2024 [Paper] [Code] -
Zeroth-Order Adaptive Neuron Alignment Based Pruning without Retraining
Arxiv 2025 [Paper] [Code] -
Scaling Law for Post-training after Model Pruning
ACL 2025 [Paper] -
LEMON: Reviving Stronger and Smaller LMs from Larger LMs with Linear Parameter Fusion
ACL 2024 [Paper] -
TrimLLM: Progressive Layer Dropping for Domain-Specific LLMs
Arxiv 2024 [Paper] -
FTP: A Fine-grained Token-wise Pruner for Large Language Models via Token Routing
Arxiv 2024 [Paper] -
Activation Sparsity Opportunities for Compressing General Large Language Models
Arxiv 2024 [Paper] -
FineGates: LLMs Finetuning with Compression using Stochastic Gates
Arxiv 2025 [Paper]


2023 · 41 papers
-
The Lazy Neuron Phenomenon: On Emergence of Activation Sparsity in Transformers
ICLR 2023 [Paper] -
Deja Vu: Contextual Sparsity for Efficient LLMs at Inference Time
ICML 2023 [Paper] [Code] -
LoSparse: Structured Compression of Large Language Models based on Low-Rank and Sparse Approximation
ICML 2023 [Paper] [Code] -
LLM-Pruner: On the Structural Pruning of Large Language Models
NeurIPS 2023 [Paper] [Code] -
ZipLM: Inference-Aware Structured Pruning of Language Models
NeurIPS 2023 [Paper] [Code] -
H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models
NeurIPS 2023 [Paper] [Code] -
The Emergence of Essential Sparsity in Large Pre-trained Models: The Weights that Matter
NeurIPS 2023 [Paper] [Code] -
Learning to Compress Prompts with Gist Tokens
NeurIPS 2023 [Paper] -
Dynamic Context Pruning for Efficient and Interpretable Autoregressive Transformers
NeurIPS 2023 [Paper] -
Prune and Tune: Improving Efficient Pruning Techniques for Massive Language Models
ICLR 2023 TinyPapers [Paper] -
SparseGPT: Massive Language Models Can Be Accurately Pruned in One-Shot
ICML 2023 [Paper] [Code] -
AdaLoRA: Adaptive Budget Allocation for Parameter-Efficient Fine-Tuning
ICLR 2023 [Paper] -
Structured Pruning for Efficient Generative Pre-trained Language Models
ACL 2023 [Paper] -
A Simple and Effective Pruning Approach for Large Language Models
ICLR 2024 [Paper] [Code] -
Pruning Meets Low-Rank Parameter-Efficient Fine-Tuning
ACL Findings 2024 [Paper] -
Structural pruning of large language models via neural architecture search
AutoML 2023 [Paper] -
Pruning Large Language Models via Accuracy Predictor
ICASSP 2024 [Paper] -
Flash-LLM: Enabling Cost-Effective and Highly-Efficient Large Generative Model Inference with Unstructured Sparsity
VLDB 2024 [Paper] [Code] -
Compressing LLMs: The Truth is Rarely Pure and Never Simple
ICLR 2024 [Paper] -
Pruning Small Pre-Trained Weights Irreversibly and Monotonically Impairs "Difficult" Downstream Tasks in LLMs
ICML 2024 [Paper] [Code] -
Compresso: Structured Pruning with Collaborative Prompting Learns Compact Large Language Models
Arxiv 2023 [Paper] [Code] -
Outlier Weighed Layerwise Sparsity (OWL): A Missing Secret Sauce for Pruning LLMs to High Sparsity
ICML 2024 [Paper] [Code] -
Sheared LLaMA: Accelerating Language Model Pre-training via Structured Pruning
Arxiv 2023 [Paper] [Code] -
Dynamic Sparse No Training: Training-Free Fine-tuning for Sparse LLMs
ICLR 2024 [Paper] [Code] -
One-Shot Sensitivity-Aware Mixed Sparsity Pruning for Large Language Models
ICASSP 2024 [Paper] -
Survival of the Most Influential Prompts: Efficient Black-Box Prompt Search via Clustering and Pruning
EMNLP Findings 2023 [Paper] -
The Cost of Compression: Investigating the Impact of Compression on Parametric Knowledge in Language Models
EMNLP Findings 2023 [Paper] -
Divergent Token Metrics: Measuring degradation to prune away LLM components -- and optimize quantization
Arxiv 2023 [Paper] -
LoRAShear: Efficient Large Language Model Structured Pruning and Knowledge Recovery
Arxiv 2023 [Paper] -
ReLU Strikes Back: Exploiting Activation Sparsity in Large Language Models
Arxiv 2023 [Paper] -
E-Sparse: Boosting the Large Language Model Inference through Entropy-based N:M Sparsity
Arxiv 2023 [Paper] -
Beyond Size: How Gradients Shape Pruning Decisions in Large Language Models
Arxiv 2023 [Paper] [Code] -
On the Impact of Calibration Data in Post-training Quantization and Pruning
ACL 2024 [Paper] -
BESA: Pruning Large Language Models with Blockwise Parameter-Efficient Sparsity Allocation
OpenReview [Paper] [Code] -
PUSHING GRADIENT TOWARDS ZERO: A NOVEL PRUNING METHOD FOR LARGE LANGUAGE MODELS
OpenReview 2023 [Paper] -
Lighter, yet More Faithful: Investigating Hallucinations in Pruned Large Language Models for Abstractive Summarization
TACL 2024 [Paper] [Code] -
Mini-GPTs: Efficient Large Language Models through Contextual Pruning
Arxiv 2023 [Paper] [Code] -
The LLM Surgeon
Arxiv 2023 [Paper] -
Fluctuation-based Adaptive Structured Pruning for Large Language Models
AAAI 2024 [Paper] -
How to Prune Your Language Model: Recovering Accuracy on the "Sparsity May Cry'' Benchmark
CPAL 2024 [Paper] -
PERP: Rethinking the Prune-Retrain Paradigm in the Era of LLMs
Arxiv 2023 [Paper]


2022 · 1 paper

Distillation
2026 · 30 papers
-
d3LLM: Ultra-Fast Diffusion LLM using Pseudo-Trajectory Distillation
ICML 2026 [Paper] -
RM-Distiller: Exploiting Generative LLM for Reward Model Distillation
ECAI 2026 [Paper] -
Self-Distilled Reasoner: On-Policy Self-Distillation for Large Language Models
Arxiv 2026 [Paper] [Code] -
Thinking Broad, Acting Fast: Latent Reasoning Distillation from Multi-Perspective Chain-of-Thought for E-Commerce Relevance
WWW 2026 [Paper] -
Exploring Knowledge Purification in Multi-Teacher Knowledge Distillation for LLMs
ICLR 2026 [Paper] -
FutureMind: Equipping Small Language Models with Strategic Thinking-Pattern Priors via Adaptive Knowledge Distillation
ICLR 2026 [Paper] -
Making Expert Reasoning Learnable with Self-Distillation
ICML 2026 [Paper] -
Pedagogically-Inspired Data Synthesis for Language Model Knowledge Distillation
ICLR 2026 [Paper] -
BRIDGE: Bridging Reasoning In Distillation Gap Elimination via Structure-Aware Masking
Arxiv 2026 [Paper] [Code] -
Surgical Post-Training: Proximal On-Policy Distillation for Reasoning with Knowledge Retention
Arxiv 2026 [Paper] [Code] -
KDFlow: A User-Friendly and Efficient Knowledge Distillation Framework for Large Language Models
Arxiv 2026 [Paper] [Code] -
Dual-Space Knowledge Distillation with Key-Query Matching for Large Language Models with Vocabulary Mismatch
ICASSP 2026 [Paper] -
Why Does Self-Distillation (Sometimes) Degrade the Reasoning Capability of LLMs?
COLM 2026 [Paper] [Code] -
Hybrid Policy Distillation for LLMs
ICML 2026 [Paper] -
Turning the TIDE: Cross-Architecture Distillation for Diffusion Large Language Models
Arxiv 2026 [Paper] [Code] -
SRA: Span Representation Alignment for Large Language Model Distillation
ACL 2026 [Paper] -
MTA: Multi-Granular Trajectory Alignment for Large Language Model Distillation
ACL 2026 [Paper] -
UniSD: Towards a Unified Self-Distillation Framework for Large Language Models
Arxiv 2026 [Paper] [Code] -
Rubric-based On-policy Distillation
Arxiv 2026 [Paper] [Code] -
Towards Resource-Efficient LLMs: End-to-End Energy Accounting of Distillation Pipelines
ICML 2026 [Paper] -
Skill-Conditioned Gated Self-Distillation for LLM Reasoning
EMNLP Findings 2026 [Paper] [Code] -
PADD: Path-Aligned Decompression Distillation for Non-Router Teacher to Guide MoE Student Learning
ICML 2026 [Paper] -
AsyncOPD: How Stale Can On-Policy Distillation Be?
Arxiv 2026 [Paper] [Code] -
Token-level Response-visual Attention Guidance for Multimodal LLMs Knowledge Distillation
ECCV 2026 [Paper] -
Answer-Conditioned Chains of Thought Degrade Verifiable-Reasoning Distillation in Large Language Models
Arxiv 2026 [Paper] [Code] -
On-Policy Self-Distillation without Any Supervision
Arxiv 2026 [Paper] [Code] -
Mismatch Matters: On-Policy Distillation Beyond Token Agreement
Arxiv 2026 [Paper] [Code] -
Thinking at the Right Size: Amortized Distillation Across Post-Trained LLMs
EMNLP Findings 2026 [Paper] -
SelFusion: Self-distillation for Diffusion Language Models
ACL 2026 [Paper] [Code]


2025 · 23 papers
-
Chunk-Distilled Language Modeling
Arxiv 2025 [Paper] -
CODI: Compressing Chain-of-Thought into Continuous Space via Self-Distillation
Arxiv 2025 [Paper] -
Every Expert Matters: Towards Effective Knowledge Distillation for Mixture-of-Experts Language Models
Arxiv 2025 [Paper] -
TinyR1-32B-Preview: Boosting Accuracy with Branch-Merge Distillation
Arxiv 2025 [Paper] -
UNDO: Understanding Distillation as Optimization
Arxiv 2025 [Paper] -
A Token is Worth over 1,000 Tokens: Efficient Knowledge Distillation through Low-Rank Clone
NeurIPS 2025 [Paper] [Code] -
SDMPrune: Self-Distillation MLP Pruning for Efficient Large Language Models
Arxiv 2025 [Paper] [Code] -
Less is More: Selective Reflection for Compatible and Efficient Knowledge Distillation in Large Language Models
Arxiv 2025 [Paper] -
Membership and Memorization in LLM Knowledge Distillation
Arxiv 2025 [Paper] -
Slow Tuning and Low-Entropy Masking for Safe Chain-of-Thought Distillation
Arxiv 2025 [Paper] -
Beyond Scaling Law: A Data-Efficient Distillation Framework for Reasoning
Arxiv 2025 [Paper] -
Can Large Models Teach Student Models to Solve Mathematical Problems Like Human Beings? A Reasoning Distillation Method via Multi-LoRA Interaction
IJCAI 2025 [Paper] -
Learning from Diverse Reasoning Paths with Routing and Collaboration
Arxiv 2025 [Paper] [Code] -
Student-Centered Distillation Narrows the Agentic Gap Between Small and Large LLMs
ICML 2026 [Paper] -
ORPO-Distill: Mixed-Policy Preference Optimization for Cross-Architecture LLM Distillation
NeurIPS 2025 Workshop [Paper] -
Distillation of Large Language Models via Concrete Score Matching
ICLR 2026 [Paper] -
SpikingMamba: Towards Energy-Efficient Large Language Models via Knowledge Distillation from Mamba
Arxiv 2025 [Paper] [Code] -
Boomerang Distillation Enables Zero-Shot Model Size Interpolation
ICLR 2026 [Paper] -
The Valley of Code Reasoning: Scaling Knowledge Distillation of Large Language Models
NeurIPS 2025 Workshop [Paper] -
AMiD: Knowledge Distillation for LLMs with $α$-mixture Assistant Distribution
ICLR 2026 [Paper] -
Few-Shot Knowledge Distillation of LLMs With Counterfactual Explanations
NeurIPS 2025 [Paper] -
Two Heads are Better than One: Distilling Large Language Model Features Into Small Models with Feature Decomposition and Mixture
AAAI 2026 [Paper] -
EM-KD: Distilling Efficient Multimodal Large Language Model with Unbalanced Vision Tokens
AAAI 2026 [Paper]


2024 · 28 papers
-
YODA: Teacher-Student Progressive Learning for Language Models
Arxiv 2023 [Paper] -
Knowledge Fusion of Large Language Models
ICLR 2024 [Paper] [Code] -
Knowledge Distillation for Closed-Source Language Models
Arxiv 2024 [Paper] -
Beyond Answers: Transferring Reasoning Capabilities to Smaller LLMs Using Multi-Teacher Knowledge Distillation
WSDM 2025 [Paper] -
Towards Cross-Tokenizer Distillation: the Universal Logit Distillation Loss for LLMs
Arxiv 2024 [Paper] -
Revisiting Knowledge Distillation for Autoregressive Language Models
ACL 2024 [Paper] -
Sinkhorn Distance Minimization for Knowledge Distillation
COLING 2024 [Paper] -
Divide-or-Conquer? Which Part Should You Distill Your LLM?
EMNLP Findings 2024 [Paper] -
Learning to Maximize Mutual Information for Chain-of-Thought Distillation
ACL 2024 Findings [Paper] -
DistiLLM: Towards Streamlined Distillation for Large Language Models
ICML 2024 [Paper] [Code] -
Efficiently Distilling LLMs for Edge Applications
NAACL 2024 [Paper] -
Rethinking Kullback-Leibler Divergence in Knowledge Distillation for Large Language Models
COLING 2025 [Paper] -
Distilling Algorithmic Reasoning from LLMs via Explaining Solution Programs
Arxiv 2024 [Paper] -
Direct Preference Knowledge Distillation for Large Language Models
Arxiv 2024 [Paper] [Code] -
Dual-Space Knowledge Distillation for Large Language Models
EMNLP 2024 [Paper] [Code] -
DDK: Distilling Domain Knowledge for Efficient Large Language Models
Arxiv 2024 [Paper] -
Compact Language Models via Pruning and Knowledge Distillation
Arxiv 2024 [Paper] [Code] -
LLM Pruning and Distillation in Practice: The Minitron Approach
Arxiv 2024 [Paper] [Models] -
The Mamba in the Llama: Distilling and Accelerating Hybrid Models
NeurIPS 2024 [Paper] -
DocKD: Knowledge Distillation from LLMs for Open-World Document Understanding Models
EMNLP 2024 [Paper] -
SWITCH: Studying with Teacher for Knowledge Distillation of Large Language Models
NAACL Findings 2025 [Paper] -
Mentor-KD: Making Small Language Models Better Multi-step Reasoners
EMNLP 2024 [Paper] [Code] -
Exploring and Enhancing the Transfer of Distribution in Knowledge Distillation for Autoregressive Language Models
Arxiv 2024 [Paper] -
LLM-Neo: Parameter Efficient Knowledge Distillation for Large Language Models
Arxiv 2024 [Paper] [Code] -
Enhancing Knowledge Distillation for LLMs with Response-Priming Prompting
Arxiv 2024 [Paper] [Code] -
Feature Alignment-Based Knowledge Distillation for Efficient Compression of Large Language Models
Arxiv 2024 [Paper] -
Lillama: Large Language Models Compression via Low-Rank Feature Distillation
NAACL 2025 [Paper] [Code] -
Multi-Level Optimal Transport for Universal Cross-Tokenizer Knowledge Distillation on Language Models
AAAI 2025 [Paper]


2023 · 20 papers
-
Lifting the Curse of Capacity Gap in Distilling Language Models
ACL 2023 [Paper] [Code] -
Symbolic Chain-of-Thought Distillation: Small Models Can Also "Think" Step-by-Step
ACL 2023 [Paper] -
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
ACL 2023 [Paper] -
SCOTT: Self-Consistent Chain-of-Thought Distillation
ACL 2023 [Paper] -
LaMini-LM: A Diverse Herd of Distilled Models from Large-Scale Instructions
EACL 2024 [Paper] [Code] -
Just CHOP: Embarrassingly Simple LLM Compression
Arxiv 2023 [Paper] -
The False Promise of Imitating Proprietary LLMs
Arxiv 2023 [Paper] -
GPT4All: Training an Assistant-style Chatbot with Large Scale Data Distillation from GPT-3.5-Turbo
Arxiv 2023 [Paper] [Code] -
PaD: Program-aided Distillation Can Teach Small Models Reasoning Better than Chain-of-thought Fine-tuning
NAACL 2024 [Paper] -
MiniLLM: Knowledge Distillation of Large Language Models
ICLR 2024 [Paper] [Code] -
On-Policy Distillation of Language Models: Learning from Self-Generated Mistakes
ICLR 2024 [Paper] -
Chain-of-Thought Prompt Distillation for Multimodal Named Entity and Multimodal Relation Extraction
Arxiv 2023 [Paper] -
Task-agnostic Distillation of Encoder-Decoder Language Models
Arxiv 2023 [Paper] -
Sci-CoT: Leveraging Large Language Models for Enhanced Knowledge Distillation in Small Models for Scientific QA
Arxiv 2023 [Paper] -
Baby Llama: knowledge distillation from an ensemble of teachers trained on a small dataset with no performance penalty
CoNLL 2023 [Paper] [Code] -
Can a student Large Language Model perform as well as it's teacher?
Arxiv 2023 [Paper] -
Multistage Collaborative Knowledge Distillation from Large Language Models
ACL 2024 [Paper] [Code] -
Lion: Adversarial Distillation of Closed-Source Large Language Model
EMNLP 2023 [Paper] [Code] -
MCC-KD: Multi-CoT Consistent Knowledge Distillation
EMNLP 2023 [Paper] -
PromptMix: A Class Boundary Augmentation Method for Large Language Model Distillation
EMNLP 2023 [Paper]


Efficient Prompting
2026 · 7 papers
-
SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents
Arxiv 2026 [Paper] [Code] -
COMI: Coarse-to-fine Context Compression via Marginal Information Gain
ICLR 2026 [Paper] -
Cross-Family Speculative Prefill: Training-Free Long-Context Compression with Small Draft Models
ICLR 2026 [Paper] -
Structured Distillation for Personalized Agent Memory: 11x Token Reduction with Retrieval Preservation
Arxiv 2026 [Paper] [Code] -
Density-aware Soft Context Compression with Semi-Dynamic Compression Ratio
Arxiv 2026 [Paper] [Code] -
LensVLM: Selective Context Expansion for Compressed Visual Representation of Text
Arxiv 2026 [Paper] -
AGORA: Adapter-Grounded Observation-Action Retention for Inference-Free Prompt Compression in LLM Agents
Arxiv 2026 [Paper] [Code]


2025 · 20 papers
-
ICPC: In-context Prompt Compression with Faster Inference
Arxiv 2025 [Paper] -
Efficient Prompt Compression with Evaluator Heads for Long-Context Transformer Inference
Arxiv 2025 [Paper] -
LCIRC: A Recurrent Compression Approach for Efficient Long-form Context and Query Dependent Modeling in LLMs
NAACL 2025 [Paper] -
TokenSkip: Controllable Chain-of-Thought Compression in LLMs
EMNLP 2025 [Paper] -
Task-agnostic Prompt Compression with Context-aware Sentence Embedding and Reward-guided Task Descriptor
Arxiv 2025 [Paper] -
LightThinker: Thinking Step-by-Step Compression
EMNLP 2025 [Paper] [Code] -
BatchGEMBA: Token-Efficient Machine Translation Evaluation with Batched Prompting and Prompt Compression
Arxiv 2025 [Paper] [Code] -
EFPC: Towards Efficient and Flexible Prompt Compression
Arxiv 2025 [Paper] -
KV-Distill: Nearly Lossless Learnable Context Compression for LLMs
Arxiv 2025 [Paper] -
Text Compression for Efficient Language Generation
NAACL Student Research Workshop (SRW) 2025 [Paper] -
Understanding and Improving Information Preservation in Prompt Compression for LLMs
EMNLP Findings 2025 [Paper] -
Dynamic Compressing Prompts for Efficient Inference of Large Language Models
Arxiv 2025 [Paper] [Code] -
PIS: Linking Importance Sampling and Attention Mechanisms for Efficient Prompt Compression
Arxiv 2025 [Paper] -
ProCut: LLM Prompt Compression via Attribution Estimation
Arxiv 2025 [Paper] -
SCOPE: A Generative Approach for LLM Prompt Compression
COLM 2026 [Paper] -
ILRe: Intermediate Layer Retrieval for Context Compression in Causal Language Models
Arxiv 2025 [Paper] -
AttnComp: Attention-Guided Adaptive Context Compression for Retrieval-Augmented Generation
EMNLP Findings 2025 [Paper] -
Distilling Many-Shot In-Context Learning into a Cheat Sheet
EMNLP Findings 2025 [Paper] -
ACON: Optimizing Context Compression for Long-horizon LLM Agents
ICML 2026 [Paper] -
Autoencoding-Free Context Compression for LLMs via Contextual Semantic Anchors
Arxiv 2025 [Paper] [Code]


2024 · 25 papers
-
The Impact of Reasoning Step Length on Large Language Models
ACL 2024 Findings [Paper] -
Learning to Compress Prompt in Natural Language Formats
Arxiv 2024 [Paper] -
Say More with Less: Understanding Prompt Learning Behaviors through Gist Compression
Arxiv 2024 [Paper] [Code] -
StreamingDialogue: Prolonged Dialogue Learning via Long Context Compression with Minimal Losses
Arxiv 2024 [Paper] -
LLMLingua-2: Data Distillation for Efficient and Faithful Task-Agnostic Prompt Compression
ACL Findings 2024 [Paper] [Code] -
PCToolkit: A Unified Plug-and-Play Prompt Compression Toolkit of Large Language Models
Arxiv 2024 [Paper] [Code] -
PROMPT-SAW: Leveraging Relation-Aware Graphs for Textual Prompt Compression
Arxiv 2024 [Paper] -
Prompts As Programs: A Structure-Aware Approach to Efficient Compile-Time Prompt Optimization
Arxiv 2024 [Paper] [Code] -
Adapting LLMs for Efficient Context Processing through Soft Prompt Compression
IPCA 2024 [Paper] -
Compressing Long Context for Enhancing RAG with AMR-based Concept Distillation
Arxiv 2024 [Paper] -
UniICL: An Efficient Unified Framework Unifying Compression, Selection, and Generation
ACL 2025 [Paper] -
SelfCP: Compressing Long Prompt to 1/12 Using the Frozen Large Language Model Itself
Arxiv 2024 [Paper] -
Fundamental Limits of Prompt Compression: A Rate-Distortion Framework for Black-Box Language Models
NeurIPS 2024 [Paper] -
QUITO: Accelerating Long-Context Reasoning through Query-Guided Context Compression
Arxiv 2024 [Paper] [Code] -
500xCompressor: Generalized Prompt Compression for Large Language Models
Arxiv 2024 [Paper] -
Enhancing and Accelerating Large Language Models via Instruction-Aware Contextual Compression
Arxiv 2024 [Paper] -
Prompt Compression with Context-Aware Sentence Encoding for Fast and Improved LLM Inference
Arxiv 2024 [Paper] [Code] -
Learning to Compress Contexts for Efficient Knowledge-based Visual Question Answering
Arxiv 2024 [Paper] -
Parse Trees Guided LLM Prompt Compression
Arxiv 2024 [Paper] -
AlphaZip: Neural Network-Enhanced Lossless Text Compression
Arxiv 2024 [Paper] -
Discovering the Gems in Early Layers: Accelerating Long-Context LLMs with 1000x Input Token Reduction
Arxiv 2024 [Paper] [Code] -
Perception Compressor:A training-free prompt compression method in long context scenarios
NAACL Findings 2025 [Paper] -
From Reading to Compressing: Exploring the Multi-document Reader for Prompt Compression
EMNLP Findings 2024 [Paper] [Code] -
Selection-p: Self-Supervised Task-Agnostic Prompt Compression for Faithfulness and Transferability
EMNLP Findings 2024 [Paper] -
Style-Compress: An LLM-Based Prompt Compression Framework Considering Task-Specific Styles
EMNLP Findings 2024 [Paper]


2023 · 17 papers
-
Did You Read the Instructions? Rethinking the Effectiveness of Task Definitions in Instruction Learning
ACL 2023 [Paper] [Code] -
Batch Prompting: Efficient Inference with Large Language Model APIs
EMNLP 2023 [Paper] [Code] -
Adapting Language Models to Compress Contexts
EMNLP 2023 [Paper] [Code] -
Compressing Context to Enhance Inference Efficiency of Large Language Models
EMNLP 2023 [Paper] [Code] -
LLMLingua: Compressing Prompts for Accelerated Inference of Large Language Models
EMNLP 2023 [Paper] [Code] -
Vector-Quantized Prompt Learning for Paraphrase Generation
EMNLP Findings 2023 [Paper] -
Efficient Prompting via Dynamic In-Context Learning
Arxiv 2023 [Paper] -
Learning to Compress Prompts with Gist Tokens
NeurIPS 2023 [Paper] [Code] -
In-context Autoencoder for Context Compression in a Large Language Model
ICLR 2024 [Paper] -
Discrete Prompt Compression with Reinforcement Learning
Arxiv 2023 [Paper] [Code] -
BatchPrompt: Accomplish more with less
Arxiv 2023 [Paper] -
Do Compressed LLMs Forget Knowledge? An Experimental Study with Practical Implications
Arxiv 2023 [Paper] -
RECOMP: Improving Retrieval-Augmented LMs with Compression and Selective Augmentation
Arxiv 2023 [Paper] [Code] -
LongLLMLingua: Accelerating and Enhancing LLMs in Long Context Scenarios via Prompt Compression
ACL 2024 [Paper] [Code] -
Extending Context Window of Large Language Models via Semantic Compression
Arxiv 2023 [Paper] -
Fewer is More: Boosting LLM Reasoning with Reinforced Context Pruning
EMNLP 2024 [Paper] [Code] -
Compressed Context Memory For Online Language Model Interaction
ICLR 2024 [Paper] [Code]


KV Cache Compression
2026 · 31 papers
-
Joint Encoding of KV-Cache Blocks for Scalable LLM Serving
Arxiv 2026 [Paper] [Code] -
OrbitFlow: SLO-Aware Long-Context LLM Serving with Fine-Grained KV Cache Reconfiguration
VLDB 2026 [Paper] -
HeteroCache: A Dynamic Retrieval Approach to Heterogeneous KV Cache Compression for Long-Context LLM Inference
ACL 2026 [Paper] -
LRAgent: Efficient KV Cache Sharing for Multi-LoRA LLM Agents
ICML 2026 [Paper] -
ForesightKV: Optimizing KV Cache Eviction for Reasoning Models by Learning Long-Term Contribution
ICML 2026 [Paper] -
ParisKV: Fast and Drift-Robust KV-Cache Retrieval for Long-Context LLMs
ICML 2026 [Paper] [Code] -
Learning to Evict from Key-Value Cache
ICML 2026 [Paper] [Code] -
KEEP: A KV-Cache-Centric Memory Management System for Efficient Embodied Planning
DAC 2026 [Paper] -
LookaheadKV: Fast and Accurate KV Cache Eviction by Glimpsing into the Future without Generation
ICLR 2026 [Paper] -
ScoutAttention: Efficient KV Cache Offloading via Layer-Ahead CPU Pre-computation for LLM Inference
DAC 2026 [Paper] -
Don't Waste Bits! Adaptive KV-Cache Quantization for Lightweight On-Device LLMs
CVPR 2026 [Paper] -
TriAttention: Efficient Long Reasoning with Trigonometric KV Compression
Arxiv 2026 [Paper] [Code] -
Latent-Condensed Transformer for Efficient Long Context Modeling
ACL 2026 [Paper] -
Open-TQ-Metal: Fused Compressed-Domain Attention for Long-Context LLM Inference on Apple Silicon
Arxiv 2026 [Paper] [Code] -
River-LLM: Large Language Model Seamless Exit Based on KV Share
ACL 2026 [Paper] -
PolyKV: A Shared Asymmetrically-Compressed KV Cache Pool for Multi-Agent LLM Inference
Arxiv 2026 [Paper] [Code] -
Rethinking KV Cache Eviction via a Unified Information-Theoretic Objective
Arxiv 2026 [Paper] [Code] -
Make Your LVLM KV Cache More Lightweight
TMLR 2026 [Paper] -
SplitZip: Ultra Fast Lossless KV Compression for Disaggregated LLM Serving
Arxiv 2026 [Paper] [Code] -
ReST-KV: Robust KV Cache Eviction with Layer-wise Output Reconstruction and Spatial-Temporal Smoothing
ICLR 2026 [Paper] [Code] -
MuKV: Multi-Grained KV Cache Compression for Long Streaming Video Question-Answering
Arxiv 2026 [Paper] [Code] -
Semantic Cache Distillation: Efficient State Transfer via Reuse and Selective Patching
ICML 2026 [Paper] -
RKSC: Reasoning-Aware KV Cache Sharing and Confident Early Exit for Multi-Step LLM Inference
ICML 2026 Workshop [Paper] -
KVEraser: Learning to Steer KV Cache for Efficient Localized Context Erasing
ICML 2026 Workshop [Paper] [Code] -
CompressKV: Semantic-Retrieval-Guided KV-Cache Compression for Resource-Efficient Long-Context LLM Inference
Arxiv 2026 [Paper] [Code] -
HARD-KV: Head-Adaptive Regularization for Decoding-time KV Compression
ICML 2026 [Paper] -
GSRQ: Gain-Shape Residual Quantization for Sub-1-bit KV Cache
ICML 2026 [Paper] -
Fractal KV-Cache Archives: Lossless Symbolic Storage with In-Place Retrieval for Long-Context LLM Inference
Arxiv 2026 [Paper] [Code] -
C$^2$KV: Compressed and Composable KV Cache Reuse for Efficient LLM Inference
KDD 2026 [Paper] -
WnW: Waxing-and-Waning KV Cache for Long-Form Speech LLMs
EMNLP 2026 [Paper] -
VisCache: Visual KV Cache Pruning for Efficient Vision Large Language Model Inference
Arxiv 2026 [Paper] [Code]


2025 · 69 papers
-
TreeKV: Smooth Key-Value Cache Compression with Tree Structures
Arxiv 2025 [Paper] -
RotateKV: Accurate and Robust 2-Bit KV Cache Quantization for LLMs via Outlier-Aware Adaptive Rotations
Arxiv 2025 [Paper] -
Cache Me If You Must: Adaptive Key-Value Quantization for Large Language Models
Arxiv 2025 [Paper] -
ChunkKV: Semantic-Preserving KV Cache Compression for Efficient Long-Context LLM Inference
NeurIPS 2025 [Paper] -
FastKV: Decoupling of Context Reduction and KV Cache Compression for Prefill-Decoding Acceleration
ACL Findings 2026 [Paper] [Code] -
Semantic Integrity Matters: Benchmarking and Preserving High-Density Reasoning in KV Cache Compression
ICML 2026 [Paper] -
PolarQuant: Quantizing KV Caches with Polar Transformation
Arxiv 2025 [Paper] -
Streaming Attention Approximation via Discrepancy Theory
Arxiv 2025 [Paper] -
Unshackling Context Length: An Efficient Selective Attention Approach through Query-Key Compression
Arxiv 2025 [Paper] -
RocketKV: Accelerating Long-Context LLM Inference via Two-Stage KV Cache Compression
ICML 2025 [Paper] -
Quantize What Counts: More for Keys, Less for Values
ACL 2026 [Paper] -
SVDq: 1.25-bit and 410x Key Cache Compression for LLM Attention
Arxiv 2025 [Paper] -
ReFreeKV: Towards Threshold-Free KV Cache Compression
ACL Findings 2026 [Paper] -
BaKlaVa -- Budgeted Allocation of KV cache for Long-context Inference
Arxiv 2025 [Paper] -
WeightedKV: Attention Scores Weighted Key-Value Cache Merging for Large Language Models
ICASSP 2025 [Paper] -
KVCrush: Key value cache size-reduction using similarity in head-behaviour
Arxiv 2025 [Paper] -
Q-Filters: Leveraging QK Geometry for Efficient KV Cache Compression
Arxiv 2025 [Paper] [Code] -
Beyond RAG: Task-Aware KV Cache Compression for Comprehensive Knowledge Reasoning
Arxiv 2025 [Paper] -
FastCache: Optimizing Multimodal LLM Serving through Lightweight KV-Cache Compression Framework
Arxiv 2025 [Paper] -
LLMs Know What to Drop: Self-Attention Guided KV Cache Eviction for Efficient Long-Context Inference
ICLR 2025 [Paper] -
ZeroMerge: Parameter-Free KV Cache Compression for Memory-Efficient Long-Context LLMs
Arxiv 2025 [Paper] [Code] -
Time and Memory Trade-off of KV-Cache Compression in Tensor Transformer Decoding
Arxiv 2025 [Paper] -
Plug-and-Play 1.x-Bit KV Cache Quantization for Video Large Language Models
Arxiv 2025 [Paper] [Code] -
OmniKV: Dynamic Context Selection for Efficient Long-Context LLMs
ICLR 2025 [Paper] -
WindowKV: Task-Adaptive Group-Wise KV Cache Window Selection for Efficient LLM Inference
Arxiv 2025 [Paper] [Code] -
xKV: Cross-Layer KV-Cache Compression via Aligned Singular Vector Extraction
ICML 2026 [Paper] [Code] -
LogQuant: Log-Distributed 2-Bit Quantization of KV Cache with Superior Accuracy Preservation
ICLR 2025 Workshop on Sparsity in LLMs (SLLM) [Paper] [Code] -
AirCache: Activating Inter-modal Relevancy KV Cache Compression for Efficient Large Vision-Language Model Inference
Arxiv 2025 [Paper] -
Rethinking Key-Value Cache Compression Techniques for Large Language Model Serving
MLSys 2025 [Paper] [Code] -
MILLION: Mastering Long-Context LLM Inference Via Outlier-Immunized KV Product Quantization
DAC 2025 [Paper] [Code] -
KeepKV: Eliminating Output Perturbation in KV Cache Compression for Efficient LLMs Inference
Arxiv 2025 [Paper] -
FreqKV: Key-Value Compression in Frequency Domain for Context Window Extension
ICLR 2026 [Paper] -
Accurate KV Cache Quantization with Outlier Tokens Tracing
ACL 2025 [Paper] [Code] -
NQKV: A KV Cache Quantization Scheme Based on Normal Distribution Characteristics
Arxiv 2025 [Paper] -
Titanus: Enabling KV Cache Pruning and Quantization On-the-Fly for LLM Acceleration
GLSVLSI 2025 [Paper] [Code] -
NSNQuant: A Double Normalization Approach for Calibration-Free Low-Bit Vector Quantization of KV Cache
Arxiv 2025 [Paper] -
PM-KVQ: Progressive Mixed-precision KV Cache Quantization for Long-CoT LLMs
ICLR 2026 [Paper] [Code] -
KVzip: Query-Agnostic KV Cache Compression with Context Reconstruction
NeurIPS 2025 [Paper] [Code] -
CommVQ: Commutative Vector Quantization for KV Cache Compression
ICML 2025 [Paper] [Code] -
LeanK: Learnable K Cache Channel Pruning for Efficient Decoding
Arxiv 2025 [Paper] -
CompressKV: Semantic Retrieval Heads Know What Tokens are Not Important Before Generation
Arxiv 2025 [Paper] [Code] -
Sparse-dLLM: Accelerating Diffusion LLMs with Dynamic Cache Eviction
Arxiv 2025 [Paper] [Code] -
SmallKV: Small Model Assisted Compensation of KV Cache Compression for Efficient LLM Inference
Arxiv 2025 [Paper] -
KVSink: Understanding and Enhancing the Preservation of Attention Sinks in KV Cache Quantization for LLMs
COLM 2025 [Paper] -
PiKV: KV Cache Management System for Mixture of Experts
Arxiv 2025 [Paper] [Code] -
Retrospective Sparse Attention for Efficient Long-Context Generation
Arxiv 2025 [Paper] -
XQuant: Breaking the Memory Wall for LLM Inference with KV Cache Rematerialization
Arxiv 2025 [Paper] -
ZigzagAttention: Efficient Long-Context Inference with Exclusive Retrieval and Streaming Heads
Arxiv 2025 [Paper] -
Accelerating LLM Inference via Dynamic KV Cache Placement in Heterogeneous Memory System
IEEE CAL 2025 [Paper] -
SparK: Query-Aware Unstructured Sparsity with Recoverable KV Cache Channel Pruning
AAAI 2026 [Paper] [Code] -
StreamMem: Query-Agnostic KV Cache Memory for Streaming Video Understanding
Arxiv 2025 [Paper] -
CommonKV: Compressing KV Cache with Cross-layer Parameter Sharing
Arxiv 2025 [Paper] -
Learned Structure in Cartridges: Keys as Shareable Routers in Self-Studied Representations
Arxiv 2025 [Paper] -
Spotlight Attention: Towards Efficient LLM Generation via Non-linear Hashing-based KV Cache Retrieval
Arxiv 2025 [Paper] -
Judge Q: Trainable Queries for Optimized Information Retention in KV Cache Eviction
AAAI 2026 [Paper] -
EpiCache: Episodic KV Cache Management for Long-Term Conversation on Resource-Constrained Environments
ICML 2026 [Paper] -
KaVa: Latent Reasoning via Compressed KV-Cache Distillation
ICLR 2026 [Paper] -
OBCache: Optimal Brain KV Cache Pruning for Efficient Long-Context LLM Inference
ICML 2026 [Paper] -
Mask Tokens as Prophet: Fine-Grained Cache Eviction for Efficient dLLM Inference
Arxiv 2025 [Paper] [Code] -
XQuant: Achieving Ultra-Low Bit KV Cache Quantization with Cross-Layer Compression
EMNLP 2025 [Paper] -
KVCOMM: Online Cross-context KV-cache Communication for Efficient LLM-based Multi-agent Systems
NeurIPS 2025 [Paper] [Code] -
Attention Is All You Need for KV Cache in Diffusion LLMs
Arxiv 2025 [Paper] [Code] -
StreamingTOM: Streaming Token Compression for Efficient Video Understanding
CVPR 2026 [Paper] -
Mixing Importance with Diversity: Joint Optimization for KV Cache Compression in Large Vision-Language Models
ICLR 2026 [Paper] [Code] -
FlexiCache: Leveraging Temporal Stability of Attention Heads for Efficient KV Cache Management
MLSys 2026 [Paper] -
KV Cache Transform Coding for Compact Storage in LLM Inference
ICLR 2026 [Paper] -
Reconstructing KV Caches with Cross-layer Fusion For Enhanced Transformers
ICLR 2026 [Paper] -
V-Rex: Real-Time Streaming Video LLM Acceleration via Dynamic KV Cache Retrieval
HPCA 2026 [Paper] -
PackKV: Reducing KV Cache Memory Footprint through LLM-Aware Lossy Compression
Arxiv 2025 [Paper] [Code]


2024 · 43 papers
-
KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization
NeurIPS 2024 [Paper] -
KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache
ICML 2024 [Paper] [Code] -
No Token Left Behind: Reliable KV Cache Compression via Importance-Aware Mixed Precision Quantization
Arxiv 2024 [Paper] -
Keyformer: KV Cache Reduction through Key Tokens Selection for Efficient Generative Inference
MLSys 2024 [Paper] -
GEAR: An Efficient KV Cache Compression Recipefor Near-Lossless Generative Inference of LLM
Arxiv 2024 [Paper] -
QAQ: Quality Adaptive Quantization for LLM KV Cache
Arxiv 2024 [Paper] [Code] -
KV Cache is 1 Bit Per Channel: Efficient Large Language Model Inference with Coupled Quantization
Arxiv 2024 [Paper] -
PyramidInfer: Pyramid KV Cache Compression for High-throughput LLM Inference
ACL 2024 [Paper] -
Unlocking Data-free Low-bit Quantization with Matrix Decomposition for KV Cache Compression
Arxiv 2024 [Paper] -
ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification
Arxiv 2024 [Paper] -
MiniCache: KV Cache Compression in Depth Dimension for Large Language Models
Arxiv 2024 [Paper] -
PyramidKV: Dynamic KV Cache Compression based on Pyramidal Information Funneling
Arxiv 2024 [Paper] -
QJL: 1-Bit Quantized JL Transform for KV Cache Quantization with Zero Overhead
Arxiv 2024 [Paper] [[Code]](https://githu


Truncated — view the full README on GitHub.
Contributors
(top 30 of 46)


Similar repos


Awesome LLM compression research papers and tools.
1,876
1,035 commits
updated Aug 27, 2026
README
Awesome LLM Compression
Awesome LLM compression research papers and tools to accelerate LLM training and inference.
Papers in each category are grouped by year in collapsible blocks, newest first — click a year to expand it. The current year is expanded by default.
Contents
Papers
Survey
2026 · 6 papers
-
Dynamic Model Routing and Cascading for Efficient LLM Inference: A Survey
Arxiv 2026 [Paper] -
A Survey of On-Policy Distillation for Large Language Models
Arxiv 2026 [Paper] -
Unifying Data, Memory, and Compute Efficiency in LLM training: A Survey
TAI 2026 [Paper] -
From Tensor Buffer to Distributed Memory Hierarchy: A Survey of KV Cache Management for LLM Serving
Arxiv 2026 [Paper] -
Towards Efficient Large Language Model Serving: A Survey on System-Aware KV Cache Optimization
ACL Findings 2026 [Paper] -
Accelerating Masked Diffusion Large Language Models: A Survey of Efficient Inference Techniques
IJCAI-ECAI 2026 (Survey Track) [Paper]
2025 · 14 papers
-
Compressed but Compromised? A Study of Jailbreaking in Compressed LLMs
NeurIPS Lock-LLM Workshop 2025 [Paper] [Blog] -
Scaling Down, Serving Fast: Compressing and Deploying Efficient LLMs for Recommendation Systems
EMNLP 2025 [Paper] -
Key, Value, Compress: A Systematic Exploration of KV Cache Compression Techniques
CICC 2025 [Paper] -
Are We There Yet? A Measurement Study of Efficiency for LLM Applications on Mobile Devices
Arxiv 2025 [Paper] -
Knowledge Distillation and Dataset Distillation of Large Language Models: Emerging Trends, Challenges, and Future Directions
Arxiv 2025 [Paper] -
An Empirical Study on Prompt Compression for Large Language Models
Building Trust Workshop @ ICLR 2025 2025 [Paper] [PCToolkit] -
Low-Precision Training of Large Language Models: Methods, Challenges, and Opportunities
Arxiv 2025 [Paper] [GitHub Page] -
Optimizing LLMs for Resource-Constrained Environments: A Survey of Model Compression Techniques
COMPSAC 2025 [Paper] -
A Survey on Inference Engines for Large Language Models: Perspectives on Optimization and Efficiency
Arxiv 2025 [Paper] [GitHub Page] -
EfficientLLM: Efficiency in Large Language Models
Arxiv 2025 [Paper] [Homepage] [Huggingface Page] -
KV Cache Compression for Inference Efficiency in LLMs: A Review
Arxiv 2025 [Paper] -
A Survey on Parallel Text Generation: From Parallel Decoding to Diffusion Language Models
Arxiv 2025 [Paper] [Code] -
A Survey on Collaborating Small and Large Language Models for Performance, Cost-effectiveness, Cloud-edge Privacy, and Trustworthiness
Arxiv 2025 [Paper] [Code] -
A Survey on Efficient Large Language Model Training: From Data-centric Perspectives
ACL 2025 [Paper] [Code]
2024 · 17 papers
-
Understanding LLMs: A Comprehensive Overview from Training to Inference
Arxiv 2024 [Paper] -
Faster and Lighter LLMs: A Survey on Current Challenges and Way Forward
IJCAI 2024 (Survey Track) [Paper] [GitHub Page] -
A Survey of Resource-efficient LLM and Multimodal Foundation Models
Arxiv 2024 [Paper] -
A Survey on Hardware Accelerators for Large Language Models
Arxiv 2024 [Paper] -
A Comprehensive Survey of Compression Algorithms for Language Models
Arxiv 2024 [Paper] -
A Survey on Transformer Compression
Arxiv 2024 [Paper] -
Model Compression and Efficient Inference for Large Language Models: A Survey
Arxiv 2024 [Paper] -
LLM Inference Unveiled: Survey and Roofline Model Insights
Arxiv 2024 [Paper] -
A Survey on Knowledge Distillation of Large Language Models
Arxiv 2024 [Paper] [GitHub Page] -
Efficient Prompting Methods for Large Language Models: A Survey
Arxiv 2024 [Paper] -
Survey on Knowledge Distillation for Large Language Models: Methods, Evaluation, and Application
Arxiv 2024 [Paper] -
On-Device Language Models: A Comprehensive Review
Arxiv 2024 [Paper] [Download On-device LLMs] -
A Survey of Low-bit Large Language Models: Basics, Systems, and Algorithms
Arxiv 2024 [Paper] -
Contextual Compression in Retrieval-Augmented Generation for Large Language Models: A Survey
Arxiv 2024 [Paper] -
Prompt Compression for Large Language Models: A Survey
Arxiv 2024 [Paper] -
A Comprehensive Study on Quantization Techniques for Large Language Models
Arxiv 2024 [Paper] -
A Survey on Large Language Model Acceleration based on KV Cache Management
TMLR 2025 [Paper]
2023 · 5 papers
-
A Survey on Model Compression for Large Language Models
TACL [Paper] -
The Cost of Compression: Investigating the Impact of Compression on Parametric Knowledge in Language Models
EMNLP 2023 [Paper] [Code] -
The Efficiency Spectrum of Large Language Models: An Algorithmic Survey
Arxiv 2023 [Paper] -
Efficient Large Language Models: A Survey
TMLR [Paper] [GitHub Page] -
Towards Efficient Generative Large Language Model Serving: A Survey from Algorithms to Systems
ICML 2024 Tutorial [Paper] [Tutorial]
Quantization
2026 · 56 papers
-
Can Large Language Models Still Explain Themselves? Investigating the Impact of Quantization on Self-Explanations
EMNLP Findings 2026 [Paper] -
QSLM: A Performance- and Memory-aware Quantization Framework with Tiered Search Strategy for Spike-driven Language Models
DATE 2026 [Paper] -
HAS-VQ: Hessian-Adaptive Sparse Vector Quantization for High-Fidelity LLM Compression
Arxiv 2026 [Paper] [Code] -
ARCQuant: Boosting NVFP4 Quantization with Augmented Residual Channels for LLMs
ACL 2026 [Paper] -
Sherry: Hardware-Efficient 1.25-Bit Ternary Quantization via Fine-grained Sparsification
Arxiv 2026 [Paper] [Code] -
Calibrating Beyond English: Language Diversity for Better Quantized Multilingual LLM
EACL 2026 [Paper] -
M2XFP: A Metadata-Augmented Microscaling Data Format for Efficient Low-bit Quantization
ASPLOS 2026 [Paper] -
Quartet II: Accurate LLM Pre-Training in NVFP4 by Improved Unbiased Gradient Estimation
Arxiv 2026 [Paper] [Code] -
Two-Stage Grid Optimization for Group-wise Quantization of LLMs
ICASSP 2026 [Paper] -
Quantized Evolution Strategies: High-precision Fine-tuning of Quantized LLMs at Low-precision Cost
Arxiv 2026 [Paper] [Code] -
QVLA: Not All Channels Are Equal in Vision-Language-Action Model's Quantization
ICLR 2026 [Paper] -
TurboBoA: Faster and Exact Attention-aware Quantization without Backpropagation
ICLR 2026 [Paper] -
RaBiT: Residual-Aware Binarization Training for Accurate and Efficient LLMs
ICML 2026 [Paper] -
NanoQuant: Efficient Sub-1-Bit Quantization of Large Language Models
ICML 2026 [Paper] -
On the Importance of a Multi-Scale Calibration for Quantization
ICASSP 2026 [Paper] -
QTALE: Quantization-Robust Token-Adaptive Layer Execution for LLMs
ICML 2026 [Paper] -
QuRL: Efficient Reinforcement Learning with Quantized Rollout
ICLR 2026 [Paper] -
SPQ: An Ensemble Technique for Large Language Model Compression
LREC 2026 [Paper] [Code] -
Quant Experts: Token-aware Adaptive Error Reconstruction with Mixture of Experts for Large Vision-Language Models Quantization
CVPR 2026 [Paper] -
MASQuant: Modality-Aware Smoothing Quantization for Multimodal Large Language Models
CVPR 2026 [Paper] -
SliderQuant: Accurate Post-Training Quantization for LLMs
ICLR 2026 [Paper] [Code] -
OneComp: One-Line Revolution for Generative AI Model Compression
Arxiv 2026 [Paper] [Code] -
Fast NF4 Dequantization Kernels for Large Language Model Inference
ASPLOS 2026 Workshop [Paper] -
RUQuant: Towards Refining Uniform Quantization for Large Language Models
KDD 2026 [Paper] -
SEPTQ: A Simple and Effective Post-Training Quantization Paradigm for Large Language Models
KDD 2025 [Paper] -
ReSpinQuant: Efficient Layer-Wise LLM Quantization via Subspace Residual Rotation Approximation
ICML 2026 [Paper] -
Robust Ultra Low-Bit Post-Training Quantization via Stable Diagonal Curvature Estimate
MLSys 2026 [Paper] -
AQPIM: Breaking the PIM Capacity Wall for LLMs with In-Memory Activation Quantization
HPCA 2026 [Paper] -
From Signal Degradation to Computation Collapse: Uncovering the Two Failure Modes of LLM Quantization
ACL Findings 2026 [Paper] -
Statistically-Lossless Quantization of Large Language Models
Arxiv 2026 [Paper] [Code] -
EdgeRazor: A Lightweight Framework for Large Language Models via Mixed-Precision Quantization-Aware Distillation
Arxiv 2026 [Paper] [Code] [Model] [Playground] -
OSAQ: Outlier Self-Absorption for Accurate Low-bit LLM Quantization
ICML 2026 [Paper] -
Normalized Architectures are Natively 4-Bit
Arxiv 2026 [Paper] [Code] -
RQ-MoE: Residual Quantization via Mixture of Experts for Efficient Input-Dependent Vector Compression
ICML 2026 [Paper] -
XFP: Quality-Targeted Adaptive Codebook Quantization with Sparse Outlier Separation for LLM Inference
Arxiv 2026 [Paper] [Code] -
GEMQ: Global Expert-Level Mixed-Precision Quantization for MoE LLMs
ICML 2026 [Paper] [Code] -
EVA: Accelerating LLM Decoding via an Efficient Vector Quantization Architecture
ISCA 2026 [Paper] -
Influence-Inspired Spectral Rotations for Extreme Low-Bit LLM Quantization
Arxiv 2026 [Paper] [Code] -
InfoQuant: Shaping Activation Distributions for Low-Bit LLM Quantization
Arxiv 2026 [Paper] [Code] -
LFQ: Logit-aware Final-block Quantization for Boosting the Generation Quality of Low-Bit Quantized LLMs
ICML 2026 [Paper] -
LiftQuant: Continuous Bit-Width LLM via Dimensional Lifting and Projection
ICML 2026 [Paper] -
UniSVQ: 2-bit Unified Scalar-Vector Quantization
ICML 2026 [Paper] -
LC-QAT: Data-Efficient 2-Bit QAT for LLMs via Linear-Constrained Vector Quantization
ICML 2026 [Paper] -
TWLA: Achieving Ternary Weights and Low-Bit Activations for LLMs via Post-Training Quantization
ICML 2026 [Paper] -
CAT-Q: Cost-efficient and Accurate Ternary Quantization for LLMs
ICML 2026 [Paper] [Code] -
Quantize the Target, Quantize the Drafter: Efficient Inference with Qwen3.5-4B
Arxiv 2026 [Paper] [Code] -
KronQ: LLM Quantization via Kronecker-Factored Hessian
COLM 2026 [Paper] -
Rethinking Small VLM Quantization: From Component-Wise Analysis to Hardware-Aware Edge Deployment
ICML 2026 Workshop [Paper] -
Reliability Scaling Laws for Quantized Large Language Models
TMLR 2026 [Paper] -
PolyQ: Codesigning End-to-End Quantization Framework for Scalable Edge CPU LLM Inference
ICCAD 2026 [Paper] -
ExaGEMM: Exploration Framework for CPU-Driven ML Inference via Associative In-Register Computing for Low-Bit GEMM
ICCAD 2026 [Paper] -
GyRot: Leveraging Hidden Synergy between Rotation and Fine-grained Group Quantization for Low-bit LLM Inference
HPCA 2026 [Paper] -
Attend to Your Own Thoughts: Breaking the Barrier for Post-Training Quantization of Reasoning LLMs through the Lens of 1.58-Bit Quantization
Arxiv 2026 [Paper] [Code] -
ARCHead: Activation-Metric Residual Correction for Large Language Model Output Heads
Arxiv 2026 [Paper] [Code] -
Compress and Forget: bitsandbytes Quantization Amplifies Proactive Interference in LLMs
Arxiv 2026 [Paper] [Code] -
Jacobian-guided Noise Injection for Quantization Robustness in Large Language Models
ICML 2026 [Paper]
2025 · 118 papers
-
HALO: Hadamard-Assisted Lower-Precision Optimization for LLMs
Arxiv 2025 [Paper] -
RaZeR: Pushing the Limits of NVFP4 Quantization with Redundant Zero Remapping
Arxiv 2025 [Paper] -
FlexQuant: Elastic Quantization Framework for Locally Hosted LLM on Edge Devices
Arxiv 2025 [Paper] -
Rethinking Post-Training Quantization: Introducing a Statistical Pre-Calibration Approach
Arxiv 2025 [Paper] -
Qrazor: Reliable and effortless 4-bit llm quantization by significant data razoring
Arxiv 2025 [Paper] -
OstQuant: Refining Large Language Model Quantization with Orthogonal and Scaling Transformations for Better Distribution Fitting
ICLR 2025 [Paper] [Code] -
SwiftPrune: Hessian-Free Weight Pruning for Large Language Models
Arxiv 2025 [Paper] -
Progressive Binarization with Semi-Structured Pruning for LLMs
Arxiv 2025 [Paper] [Code] -
Physics-Inspired Binary Neural Networks: Interpretable Compression with Theoretical Guarantees
Arxiv 2025 [Paper] -
QuEST: Stable Training of LLMs with 1-Bit Weights and Activations
Arxiv 2025 [Paper] -
ParetoQ: Scaling Laws in Extremely Low-bit LLM Quantization
NeurIPS 2025 [Paper] -
Systematic Outliers in Large Language Models
ICLR 2025 [Paper] [Code] -
Can Post-Training Quantization Benefit from an Additional QLoRA Integration?
NAACL 2025 [Paper] -
1bit-Merging: Dynamic Quantized Merging for Large Language Models
Arxiv 2025 [Paper] -
Towards Efficient Pre-training: Exploring FP4 Precision in Large Language Models
Arxiv 2025 [Paper] -
Continual Quantization-Aware Pre-Training: When to transition from 16-bit to 1.58-bit pre-training for BitNet language models?
Arxiv 2025 [Paper] -
QuZO: Quantized Zeroth-Order Fine-Tuning for Large Language Models
Arxiv 2025 [Paper] -
Benchmarking Post-Training Quantization in LLMs: Comprehensive Taxonomy, Unified Evaluation, and Comparative Analysis
Arxiv 2025 [Paper] -
Compression Scaling Laws:Unifying Sparsity and Quantization
Arxiv 2025 [Paper] -
M-ANT: Efficient Low-bit Group Quantization for LLMs via Mathematically Adaptive Numerical Type
Arxiv 2025 [Paper] -
Identifying Sensitive Weights via Post-quantization Integral
Arxiv 2025 [Paper] -
RSQ: Learning from Important Tokens Leads to Better Quantized LLMs
Arxiv 2025 [Paper] [Code] -
VQ-LLM: High-performance Code Generation for Vector Quantization Augmented LLM Inference
HPCA 2025 [Paper] -
Universality of Layer-Level Entropy-Weighted Quantization Beyond Model Architecture and Size
Arxiv 2025 [Paper] -
Towards Superior Quantization Accuracy: A Layer-sensitive Approach
Arxiv 2025 [Paper] -
MergeQuant: Accurate 4-bit Static Quantization of Large Language Models by Channel-wise Calibration
Arxiv 2025 [Paper] -
ClusComp: A Simple Paradigm for Model Compression and Efficient Finetuning
Arxiv 2025 [Paper] -
DynaMo: Runtime Switchable Quantization for MoE with Cross-Dataset Adaptation
DATE 2026 [Paper] -
Cocktail: Chunk-Adaptive Mixed-Precision Quantization for Long-Context LLM Inference
DATE 2025 [Paper] -
GPTQv2: Efficient Finetuning-Free Quantization for Asymmetric Calibration
ICML 2025 [Paper] [Code] -
Task-Circuit Quantization: Leveraging Knowledge Localization and Interpretability for Compression
COLM 2025 [Paper] [Code] -
Quantization Error Propagation: Revisiting Layer-Wise Post-Training Quantization
NeurIPS 2025 [Paper] [Code] -
RaanA: A Fast, Flexible, and Data-Efficient Post-Training Quantization Algorithm
Arxiv 2025 [Paper] [Code] -
Achieving binary weight and activation for LLMs using Post-Training Quantization
Arxiv 2025 [Paper] -
DL-QAT: Weight-Decomposed Low-Rank Quantization-Aware Training for Large Language Models
EMNLP 2024 [Paper] -
Gradual Binary Search and Dimension Expansion : A general method for activation quantization in LLMs
Arxiv 2025 [Paper] -
FGMP: Fine-Grained Mixed-Precision Weight and Activation Quantization for Hardware-Accelerated LLM Inference
Arxiv 2025 [Paper] -
BitNet v2: Native 4-bit Activations with Hadamard Transformation for 1-bit LLMs
Arxiv 2025 [Paper] -
FineQ: Software-Hardware Co-Design for Low-Bit Fine-Grained Mixed-Precision Quantization of LLMs
DATE 2025 [Paper] -
Precision Where It Matters: A Novel Spike Aware Mixed-Precision Quantization Strategy for LLaMA-based Language Models
Arxiv 2025 [Paper] -
ICQuant: Index Coding enables Low-bit LLM Quantization
Arxiv 2025 [Paper] -
Radio: Rate-Distortion Optimization for Large Language Model Compression
ICML 2025 [Paper] -
Balancing Fidelity and Plasticity: Aligning Mixed-Precision Fine-Tuning with Linguistic Hierarchies
Arxiv 2025 [Paper] -
MoEQuant: Enhancing Quantization for Mixture-of-Experts Large Language Models via Expert-Balanced Sampling and Affinity Guidance
ICML 2025 [Paper] -
Grouped Sequency-arranged Rotation: Optimizing Rotation Transformation for Quantization for Free
Arxiv 2025 [Paper] -
Improving Block-Wise LLM Quantization by 4-bit Block-Wise Optimal Float (BOF4): Analysis and Variations
Arxiv 2025 [Paper] -
GuidedQuant: Large Language Model Quantization via Exploiting End Loss Guidance
ICML 2025 [Paper] [Code] -
QuantX: A Framework for Hardware-Aware Quantization of Generative AI Workloads
Arxiv 2025 [Paper] -
An Extra RMSNorm is All You Need for Fine Tuning to 1.58 Bits
Arxiv 2025 [Paper] -
ITERA-LLM: Boosting Sub-8-Bit Large Language Model Inference via Iterative Tensor Decomposition
Arxiv 2025 [Paper] -
Fine-tuning Quantized Neural Networks with Zeroth-order Optimization
ICLR 2026 [Paper] -
Scaling Law for Quantization-Aware Training
Arxiv 2025 [Paper] -
Quaff: Quantized Parameter-Efficient Fine-Tuning under Outlier Spatial Stability Hypothesis
ACL 2025 [Paper] [Code] -
Is (Selective) Round-To-Nearest Quantization All You Need?
Arxiv 2025 [Paper] -
NeUQI: Near-Optimal Uniform Quantization Parameter Initialization
ICML 2026 [Paper] -
LoTA-QAF: Lossless Ternary Adaptation for Quantization-Aware Fine-Tuning
Arxiv 2025 [Paper] [Code] -
FP4 All the Way: Fully Quantized Training of LLMs
Arxiv 2025 [Paper] [Code] -
FireQ: Fast INT4-FP8 Kernel and RoPE-aware Quantization for LLM Inference Acceleration
Arxiv 2025 [Paper] -
Rethinking the Outlier Distribution in Large Language Models: An In-depth Study
Arxiv 2025 [Paper] -
Assigning Distinct Roles to Quantized and Low-Rank Matrices Toward Optimal Weight Decomposition
ACL Findings 2025 [Paper] -
Unifying Uniform and Binary-coding Quantization for Accurate Compression of Large Language Models
ACL 2025 [Paper] -
FPTQuant: Function-Preserving Transforms for LLM Quantization
ICML 2026 [Paper] -
BAQ: Efficient Bit Allocation Quantization for Large Language Models
Arxiv 2025 [Paper] [Code] -
MoQAE: Mixed-Precision Quantization for Long-Context LLM Inference via Mixture of Quantization-Aware Experts
ACL 2025 [Paper] -
Unifying Block-wise PTQ and Distillation-based QAT for Progressive Quantization toward 2-bit Instruction-Tuned LLMs
Arxiv 2025 [Paper] -
Boost Post-Training Quantization via Null Space Optimization for Large Language Models
Arxiv 2025 [Paper] [Code] -
FlexQuant: A Flexible and Efficient Dynamic Precision Switching Framework for LLM Quantization
Arxiv 2025 [Paper] -
BTC-LLM: Efficient Sub-1-Bit LLM Quantization via Learnable Transformation and Binary Codebook
Arxiv 2025 [Paper] -
ROSAQ: Rotation-based Saliency-Aware Weight Quantization for Efficiently Compressing Large Language Models
Arxiv 2025 [Paper] -
LittleBit: Ultra Low-Bit Quantization via Latent Factorization
NeurIPS 2025 [Paper] -
BASE-Q: Bias and Asymmetric Scaling Enhanced Rotational Quantization for Large Language Models
Arxiv 2025 [Paper] [Code] -
UltraSketchLLM: Sub-1-Bit LLM Compression via Sketch and Hardware-Friendly Operators
DAC 2026 [Paper] -
DBellQuant: Breaking the Bell with Double-Bell Transformation for LLMs Post Training Binarization
Arxiv 2025 [Paper] -
any4: Learned 4-bit Numeric Representation for LLMs
ICML 2025 [Paper] -
CCQ: Convolutional Code for Extreme Low-bit Quantization in LLMs
Arxiv 2025 [Paper] -
First-Order Error Matters: Accurate Compensation for Quantized Large Language Models
AAAI 2026 [Paper] -
PoTPTQ: A Two-step Power-of-Two Post-training for LLMs
ECAI 2025 [Paper] -
EAC-MoE: Expert-Selection Aware Compressor for Mixture-of-Experts Large Language Models
ACL 2025 [Paper] -
MicroMix: Efficient Mixed-Precision Quantization with Microscaling Formats for Large Language Models
Arxiv 2025 [Paper] [Code] -
VLMQ: Token Saliency-Driven Post-Training Quantization for Vision-language Models
Arxiv 2025 [Paper] -
FlashCommunication V2: Bit Splitting and Spike Reserving for Any Bit Communication
Arxiv 2025 [Paper] -
FlexQ: Efficient Post-training INT6 Quantization for LLM Serving via Algorithm-System Co-Design
Arxiv 2025 [Paper] [Code] -
Provable Post-Training Quantization: Theoretical Analysis of OPTQ and Qronos
Arxiv 2025 [Paper] -
iFairy: the First 2-bit Complex LLM with All Parameters in ${\pm1, \pm i}$
Arxiv 2025 [Paper] -
Pushing the Envelope of LLM Inference on AI-PC and Intel GPUs
Arxiv 2025 [Paper] -
Rethinking 1-bit Optimization Leveraging Pre-trained Large Language Models
Arxiv 2025 [Paper] -
Efficient Edge LLMs Deployment via HessianAware Quantization and CPU GPU Collaborative
Arxiv 2025 [Paper] -
Profiling Large Language Model Inference on Apple Silicon: A Quantization Perspective
Arxiv 2025 [Paper] -
LLM Compression: How Far Can We Go in Balancing Size and Performance?
RANLP 2025 [Paper] -
DLLMQuant: Quantizing Diffusion-based Large Language Models
Arxiv 2025 [Paper] -
Quantization Meets dLLMs: A Systematic Study of Post-training Quantization for Diffusion LLMs
Machine Intelligence Research 2025 [Paper] -
Systematic Characterization of LLM Quantization: A Performance, Energy, and Quality Perspective
Arxiv 2025 [Paper] -
Interpreting the Effects of Quantization on LLMs
AACL 2025 [Paper] -
Task-Stratified Knowledge Scaling Laws for Post-Training Quantized Large Language Models
ACL Findings 2026 [Paper] -
APT-LLM: Exploiting Arbitrary-Precision Tensor Core Computing for LLM Acceleration
TCAD 2025 [Paper] -
Quantized but Deceptive? A Multi-Dimensional Truthfulness Evaluation of Quantized LLMs
EMNLP 2025 [Paper] -
The Uneven Impact of Post-Training Quantization in Machine Translation
Arxiv 2025 [Paper] -
BitROM: Weight Reload-Free CiROM Architecture Towards Billion-Parameter 1.58-bit LLM Inference
ASP-DAC 2026 [Paper] -
AMQ: Enabling AutoML for Mixed-precision Weight-Only Quantization of Large Language Models
EMNLP 2025 [Paper] -
Fair-GPTQ: Bias-Aware Quantization for Large Language Models
Arxiv 2025 [Paper] -
QWHA: Quantization-Aware Walsh-Hadamard Adaptation for Parameter-Efficient Fine-Tuning on Large Language Models
ICLR 2026 [Paper] -
Q-Palette: Fractional-Bit Quantizers Toward Optimal Bit Allocation for Efficient LLM Deployment
NeurIPS 2025 [Paper] -
AnyBCQ: Hardware Efficient Flexible Binary-Coded Quantization for Multi-Precision LLMs
ICLR 2026 [Paper] -
QeRL: Beyond Efficiency -- Quantization-enhanced Reinforcement Learning for LLMs
Arxiv 2025 [Paper] [Code] -
F-BFQ: Flexible Block Floating-Point Quantization Accelerator for LLMs
ISCA 2025 Workshop [Paper] -
Learning Grouped Lattice Vector Quantizers for Low-Bit LLM Compression
NeurIPS 2025 [Paper] -
A Convergence Analysis of Adaptive Optimizers under Floating-point Quantization
ICLR 2026 [Paper] -
FALQON: Accelerating LoRA Fine-tuning with Low-Bit Floating-Point Arithmetic
NeurIPS 2025 [Paper] -
TetraJet-v2: Accurate NVFP4 Training for Large Language Models with Oscillation Suppression and Outlier Control
ICML 2026 [Paper] -
DartQuant: Efficient Rotational Distribution Calibration for LLM Quantization
NeurIPS 2025 [Paper] -
You Had One Job: Per-Task Quantization Using LLMs' Hidden Representations
ICML 2026 Workshop [Paper] -
P3-LLM: An Integrated NPU-PIM Accelerator for Edge LLM Inference Using Hybrid Numerical Formats
ISCA 2026 [Paper] -
ParoQuant: Pairwise Rotation Quantization for Efficient Reasoning LLM Inference
ICLR 2026 [Paper] [Code] -
SpecQuant: Spectral Decomposition and Adaptive Truncation for Ultra-Low-Bit LLMs Quantization
AAAI 2026 [Paper] -
T-SAR: A Full-Stack Co-design for CPU-Only Ternary LLM Inference via In-Place SIMD ALU Reorganization
DATE 2026 [Paper] -
Enhancing Trustworthiness with Mixed Precision: Benchmarks, Opportunities, and Challenges
ASP-DAC 2026 [Paper] -
SignRoundV2: Toward Closing the Performance Gap in Extremely Low-Bit Post-Training Quantization for LLMs
Arxiv 2025 [Paper] [Code] -
CodeGEMM: A Codebook-Centric Approach to Efficient GEMM in Quantized LLMs
NeurIPS 2025 [Paper]
2024 · 162 papers
-
FlightLLM: Efficient Large Language Model Inference with a Complete Mapping Flow on FPGA
FPGA 2024 [Paper] -
Extreme Compression of Large Language Models via Additive Quantization
ICML 2024 [Paper] [Code] -
Quantized Side Tuning: Fast and Memory-Efficient Tuning of Quantized Large Language Models
Arxiv 2024 [Paper] -
Inferflow: an Efficient and Highly Configurable Inference Engine for Large Language Models
Arxiv 2024 [Paper] -
FP6-LLM: Efficiently Serving Large Language Models Through FP6-Centric Algorithm-System Co-Design
USENIX ATC 2024 [Paper] -
Can Large Language Models Understand Context?
EACL Findings 2024 [Paper] -
Squat: Quant Small Language Models on the Edge
ICCAD 2025 [Paper] [Code] -
LQER: Low-Rank Quantization Error Reconstruction for LLMs
ICML 2024 [Paper] -
BiLLM: Pushing the Limit of Post-Training Quantization for LLMs
Arxiv 2024 [Paper] [Code] -
QuIP#: Even Better LLM Quantization with Hadamard Incoherence and Lattice Codebooks
ICML 2024 [Paper] [Code] -
L4Q: Parameter Efficient Quantization-Aware Training on Large Language Models via LoRA-wise LSQ
Arxiv 2024 [Paper] -
TP-Aware Dequantization
Arxiv 2024 [Paper] -
ApiQ: Finetuning of 2-Bit Quantized Large Language Model
EMNLP 2024 [Paper] -
Accurate LoRA-Finetuning Quantization of LLMs via Information Retention
Arxiv 2024 [Paper] [Code] -
BitDelta: Your Fine-Tune May Only Be Worth One Bit
NeurIPS 2024 [Paper] [Code] -
QDyLoRA: Quantized Dynamic Low-Rank Adaptation for Efficient Large Language Model Tuning
EMNLP 2024 Industry Track [Paper] -
Any-Precision LLM: Low-Cost Deployment of Multiple, Different-Sized LLMs
ICML 2024 [Paper] -
BitDistiller: Unleashing the Potential of Sub-4-Bit LLMs via Self-Distillation
ACL 2024 [Paper] [Code] -
OneBit: Towards Extremely Low-bit Large Language Models
NeurIPS 2024 [Paper] -
DB-LLM: Accurate Dual-Binarization for Efficient LLMs
ACL Findings 2024 [Paper] -
WKVQuant: Quantizing Weight and Key/Value Cache for Large Language Models Gains More
Arxiv 2024 [Paper] -
GPTVQ: The Blessing of Dimensionality for LLM Quantization
Arxiv 2024 [Paper] [Code] -
APTQ: Attention-aware Post-Training Mixed-Precision Quantization for Large Language Models
DAC 2024 [Paper] -
A Comprehensive Evaluation of Quantization Strategies for Large Language Models
ACL Findings 2024 [Paper] -
Evaluating Quantized Large Language Models
Arxiv 2024 [Paper] -
FlattenQuant: Breaking Through the Inference Compute-bound for Large Language Models with Per-tensor Quantization
Arxiv 2024 [Paper] -
LLM-PQ: Serving LLM on Heterogeneous Clusters with Phase-Aware Partition and Adaptive Quantization
Arxiv 2024 [Paper] -
IntactKV: Improving Large Languagze Model Quantization by Keeping Pivot Tokens Intact
ACL Findings 2024 [Paper] [Code] -
On the Compressibility of Quantized Large Language Models
Arxiv 2024 [Paper] -
EasyQuant: An Efficient Data-free Quantization Algorithm for LLMs
Arxiv 2024 [Paper] -
What Makes Quantization for Large Language Models Hard? An Empirical Study from the Lens of Perturbation
Arxiv 2024 [Paper] -
AffineQuant: Affine Transformation Quantization for Large Language Models
ICLR 2024 [Paper] [Code] -
Oh! We Freeze: Improving Quantized Knowledge Distillation via Signal Propagation Analysis for Large Language Models
ICLR Practical ML for Low Resource Settings Workshop 2024 [Paper] -
Accurate Block Quantization in LLMs with Outliers
Arxiv 2024 [Paper] -
QuaRot: Outlier-Free 4-Bit Inference in Rotated LLMs
Arxiv 2024 [Paper] [Code] -
Minimize Quantization Output Error with Bias Compensation
Arxiv 2024 [Paper] [Code] -
Cherry on Top: Parameter Heterogeneity and Quantization in Large Language Models
Arxiv 2024 [Paper] -
Fine-Tuning, Quantization, and LLMs: Navigating Unintended Outcomes
Arxiv 2024 [Paper] -
Quantization of Large Language Models with an Overdetermined Basis
Arxiv 2024 [Paper] -
An empirical study of LLaMA3 quantization: from LLMs to MLLMs
Arxiv 2024 [Paper] [Code] -
How to Parameterize Asymmetric Quantization Ranges for Quantization-Aware Training
Arxiv 2024 [Paper] -
Mitigating the Impact of Outlier Channels for Language Model Quantization with Activation Regularization
Arxiv 2024 [Paper] [Code] -
When Quantization Affects Confidence of Large Language Models?
NAACL 2024 [Paper] -
QServe: W4A8KV4 Quantization and System Co-design for Efficient LLM Serving
Arxiv 2024 [Paper] [Code] -
Learning from Students: Applying t-Distributions to Explore Accurate and Efficient Formats for LLMs
ICML 2024 [Paper] -
LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit
EMNLP 2024 [Paper] [Code] -
SKVQ: Sliding-window Key and Value Cache Quantization for Large Language Models
Arxiv 2024 [Paper] -
Post Training Quantization of Large Language Models with Microscaling Formats
Arxiv 2024 [Paper] -
Edge Intelligence Optimization for Large Language Model Inference with Batching and Quantization
Arxiv 2024 [Paper] -
SliM-LLM: Salience-Driven Mixed-Precision Quantization for Large Language Models
Arxiv 2024 [Paper] [Code] -
OAC: Output-adaptive Calibration for Accurate Post-training Quantization
Arxiv 2024 [Paper] -
PV-Tuning: Beyond Straight-Through Estimation for Extreme LLM Compression
Arxiv 2024 [Paper] -
SpinQuant -- LLM quantization with learned rotations
ICLR 2025 [Paper] -
Compressing Large Language Models using Low Rank and Low Precision Decomposition
NeurIPS 2024 [Paper] [Code] -
Athena: Efficient Block-Wise Post-Training Quantization for Large Language Models Using Second-Order Matrix Derivative Information
Arxiv 2024 [Paper] -
Exploiting LLM Quantization
Arxiv 2024 [Paper] -
One QuantLLM for ALL: Fine-tuning Quantized LLMs Once for Efficient Deployments
Arxiv 2024 [Paper] -
LCQ: Low-Rank Codebook based Quantization for Large Language Models
Arxiv 2024 [Paper] -
LoQT: Low Rank Adapters for Quantized Training
Arxiv 2024 [Paper] [Code] -
CLAQ: Pushing the Limits of Low-Bit Post-Training Quantization for LLMs
Arxiv 2024 [Paper] -
I-LLM: Efficient Integer-Only Inference for Fully-Quantized Low-Bit Large Language Models
Arxiv 2024 [Paper] -
Outliers and Calibration Sets have Diminishing Effect on Quantization of Modern LLMs
Arxiv 2024 [Paper] -
DuQuant: Distributing Outliers via Dual Transformation Makes Stronger Quantized LLMs
NeurIPS 2024 [Paper] [Code] -
ShiftAddLLM: Accelerating Pretrained LLMs via Post-Training Multiplication-Less Reparameterization
NeurIPS 2024 [Paper] [Code] -
Low-Rank Quantization-Aware Training for LLMs
Arxiv 2024 [Paper] -
TernaryLLM: Ternarized Large Language Model
Arxiv 2024 [Paper] -
Examining Post-Training Quantization for Mixture-of-Experts: A Benchmark
Arxiv 2024 [Paper] [Code] -
Delta-CoMe: Training-Free Delta-Compression with Mixed-Precision for Large Language Models
NeurIPS 2024 [Paper] -
QQQ: Quality Quattuor-Bit Quantization for Large Language Models
Arxiv 2024 [Paper] [Code] -
QTIP: Quantization with Trellises and Incoherence Processing
NeurIPS 2024 [Paper] [Code] -
Prefixing Attention Sinks can Mitigate Activation Outliers for Large Language Model Quantization
EMNLP 2024 [Paper] -
Mixture of Scales: Memory-Efficient Token-Adaptive Binarization for Large Language Models
NeurIPS 2024 [Paper] -
Tender: Accelerating Large Language Models via Tensor Decomposition and Runtime Requantization
ISCA 2024 [Paper] -
SDQ: Sparse Decomposed Quantization for LLM Inference
Arxiv 2024 [Paper] -
Attention-aware Post-training Quantization without Backpropagation
ICML 2025 [Paper] -
EDGE-LLM: Enabling Efficient Large Language Model Adaptation on Edge Devices via Layerwise Unified Compression and Adaptive Layer Tuning and Voting
Arxiv 2024 [Paper] [Code] -
Compensate Quantization Errors: Make Weights Hierarchical to Compensate Each Other
Arxiv 2024 [Paper] -
Layer-Wise Quantization: A Pragmatic and Effective Method for Quantizing LLMs Beyond Integer Bit-Levels
Arxiv 2024 [Paper] [Code] -
CDQuant: Greedy Coordinate Descent for Accurate LLM Quantization
Arxiv 2024 [Paper] -
OutlierTune: Efficient Channel-Wise Quantization for Large Language Models
Arxiv 2024 [Paper] -
T-MAC: CPU Renaissance via Table Lookup for Low-Bit LLM Deployment on Edge
EuroSys 2025 [Paper] [Code] -
GPTQT: Quantize Large Language Models Twice to Push the Efficiency
ICORIS 2024 [Paper] -
Improving Conversational Abilities of Quantized Large Language Models via Direct Preference Alignment
ACL 2024 [Paper] -
How Does Quantization Affect Multilingual LLMs?
EMNLP Findings 2024 [Paper] -
RoLoRA: Fine-tuning Rotated Outlier-free LLMs for Effective Weight-Activation Quantization
EMNLP Findings 2024 [Paper] [Code] -
Q-GaLore: Quantized GaLore with INT4 Projection and Layer-Adaptive Low-Rank Gradients
Arxiv 2024 [Paper] [Code] -
FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision
Arxiv 2024 [Paper] [Code] -
Accuracy is Not All You Need
Arxiv 2024 [Paper] -
BitNet b1.58 Reloaded: State-of-the-art Performance Also on Smaller Networks
Arxiv 2024 [Paper] -
LeanQuant: Accurate Large Language Model Quantization with Loss-Error-Aware Grid
ICLR 2025 [Paper] -
Fast Matrix Multiplications for Lookup Table-Quantized LLMs
EMNLP Findings 2024 [Paper] [Code] -
EfficientQAT: Efficient Quantization-Aware Training for Large Language Models
ACL 2025 [Paper] [Code] -
LRQ: Optimizing Post-Training Quantization for Large Language Models by Learning Low-Rank Weight-Scaling Matrices
NAACL 2025 [Paper] -
Exploring Quantization for Efficient Pre-Training of Transformer Language Models
EMNLP Findings 2024 [Paper] [Code] -
Spectra: Surprising Effectiveness of Pretraining Ternary Language Models at Scale
Arxiv 2024 [Paper] [Code] -
Mamba-PTQ: Outlier Channels in Recurrent Large Language Models
Efficient Systems for Foundation Models Workshop @ ICML 2024 [Paper] -
Compensate Quantization Errors+: Quantized Models Are Inquisitive Learners
Arxiv 2024 [Paper] -
Accurate and Efficient Fine-Tuning of Quantized Large Language Models Through Optimal Balance
Arxiv 2024 [Paper] [Code] -
STBLLM: Breaking the 1-Bit Barrier with Structured Binary LLMs
Arxiv 2024 [Paper] -
Advancing Multimodal Large Language Models with Quantization-Aware Scale Learning for Efficient Adaptation
ACM MM 2024 [Paper] -
ABQ-LLM: Arbitrary-Bit Quantized Inference Acceleration for Large Language Models
AAAI 2025 [Paper] -
MARLIN: Mixed-Precision Auto-Regressive Parallel Inference on Large Language Models
Arxiv 2024 [Paper] [Code (Marlin)] [Code (Sparse Marlin)] -
Matmul or No Matmal in the Era of 1-bit LLMs
Arxiv 2024 [Paper] -
MobileQuant: Mobile-friendly Quantization for On-device Language Models
EMNLP Findings 2024 [Paper] [Code] -
GIFT-SW: Gaussian noise Injected Fine-Tuning of Salient Weights for LLMs
Arxiv 2024 [Paper] [Code] -
Foundations of Large Language Model Compression -- Part 1: Weight Quantization
Arxiv 2024 [Paper] -
OPAL: Outlier-Preserved Microscaling Quantization A ccelerator for Generative Large Language Models
DAC 2024 [Paper] -
VPTQ: Extreme Low-bit Vector Post-Training Quantization for Large Language Models
EMNLP 2024 [Paper] [Code] -
Scaling FP8 training to trillion-token LLMs
Arxiv 2024 [Paper] -
Accumulator-Aware Post-Training Quantization
Arxiv 2024 [Paper] -
Efficient Arbitrary Precision Acceleration for Large Language Models on GPU Tensor Cores
ASP-DAC 2025 [Paper] -
Rotated Runtime Smooth: Training-Free Activation Smoother for accurate INT4 inference
Arxiv 2024 [Paper] [Code] -
EXAQ: Exponent Aware Quantization For LLMs Acceleration
Arxiv 2024 [Paper] -
ARB-LLM: Alternating Refined Binarizations for Large Language Models
Arxiv 2024 [Paper] [Code] -
PrefixQuant: Eliminating Outliers by Prefixed Tokens for Large Language Models Quantization
Arxiv 2024 [Paper] [Code] -
Sketch to Adapt: Fine-Tunable Sketches for Efficient LLM Adaptation
ICML 2025 [Paper] -
Scaling Laws For Mixed Quantization
Arxiv 2024 [Paper] -
Q-VLM: Post-training Quantization for Large Vision-Language Models
NeurIPS 2024 [Paper] [Code] -
CrossQuant: A Post-Training Quantization Method with Smaller Quantization Kernel for Precise Large Language Model Compression
Arxiv 2024 [Paper] -
FlatQuant: Flatness Matters for LLM Quantization
ICML 2025 [Paper] [Code] -
DeltaDQ: Ultra-High Delta Compression for Fine-Tuned LLMs via Group-wise Dropout and Separate Quantization
Arxiv 2024 [Paper] -
QEFT: Quantization for Efficient Fine-Tuning of LLMs
EMNLP Findings 2024 [Paper] [Code] -
Continuous Approximations for Improving Quantization Aware Training of LLMs
Arxiv 2024 [Paper] -
DAQ: Density-Aware Post-Training Weight-Only Quantization For LLMs
Arxiv 2024 [Paper] -
COMET: Towards Partical W4A4KV4 LLMs Serving
Arxiv 2024 [Paper] -
Scaling laws for post-training quantized large language models
Arxiv 2024 [Paper] -
Channel-Wise Mixed-Precision Quantization for Large Language Models
Arxiv 2024 [Paper] -
Understanding the difficulty of low-precision post-training quantization of large language models
Arxiv 2024 [Paper] -
QuAILoRA: Quantization-Aware Initialization for LoRA
NeurIPS Workshop on Efficient Natural Language and Speech Processing (ENLSP-IV) 2024 [Paper] -
SDP4Bit: Toward 4-bit Communication Quantization in Sharded Data Parallelism for LLM Training
NeurIPS 2024 [Paper] -
Pyramid Vector Quantization for LLMs
Arxiv 2024 [Paper] -
TesseraQ: Ultra Low-Bit LLM Post-Training Quantization with Block Reconstruction
Arxiv 2024 [Paper] [Code] -
COAT: Compressing Optimizer states and Activation for Memory-Efficient FP8 Training
ICLR 2025 [Paper] [Code] -
GWQ: Gradient-Aware Weight Quantization for Large Language Models
Arxiv 2024 [Paper] -
"Give Me BF16 or Give Me Death"? Accuracy-Performance Trade-Offs in LLM Quantization
ACL 2025 [Paper] -
Interactions Across Blocks in Post-Training Quantization of Large Language Models
Arxiv 2024 [Paper] -
BitNet a4.8: 4-bit Activations for 1-bit LLMs
Arxiv 2024 [Paper] -
The Super Weight in Large Language Models
Arxiv 2024 [Paper] [Code] -
ASER: Activation Smoothing and Error Reconstruction for Large Language Model Quantization
AAAI 2025 [Paper] -
Towards Low-bit Communication for Tensor Parallel LLM Inference
Arxiv 2024 [Paper] -
AMXFP4: Taming Activation Outliers with Asymmetric Microscaling Floating-Point for 4-bit LLM Inference
Arxiv 2024 [Paper] [Code] -
Scaling Laws for Precision
Arxiv 2024 [Paper] -
BitMoD: Bit-serial Mixture-of-Datatype LLM Acceleration
HPCA 2025 [Paper] [Code] -
SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization
ICML 2025 [Paper] [Code] -
AutoMixQ: Self-Adjusting Quantization for High Performance Memory-Efficient Fine-Tuning
Arxiv 2024 [Paper] -
Anda: Unlocking Efficient LLM Inference with a Variable-Length Grouped Activation Data Format
HPCA 2025 [Paper] -
MixPE: Quantization and Hardware Co-design for Efficient LLM Inference
Arxiv 2024 [Paper] -
Pushing the Limits of Large Language Model Quantization via the Linearity Theorem
Arxiv 2024 [Paper] -
Low-Bit Quantization Favors Undertrained LLMs: Scaling Laws for Quantized LLMs with 100T Training Tokens
Arxiv 2024 [Paper] [Models] -
DFRot: Achieving Outlier-Free and Massive Activation-Free for Rotated LLMs with Refined Rotation
COLM 2025 [Paper] [Code] -
RILQ: Rank-Insensitive LoRA-based Quantization Error Compensation for Boosting 2-bit Large Language Model Accuracy
AAAI 2025 [Paper] -
CPTQuant -- A Novel Mixed Precision Post-Training Quantization Techniques for Large Language Models
Arxiv 2024 [Paper] -
SKIM: Any-bit Quantization Pushing The Limits of Post-Training Quantization
Arxiv 2024 [Paper] -
Direct Quantized Training of Language Models with Stochastic Rounding
Arxiv 2024 [Paper] [Code] -
Taming Sensitive Weights : Noise Perturbation Fine-tuning for Robust LLM Quantization
Arxiv 2024 [Paper] -
Low-Rank Correction for Quantized LLMs
Arxiv 2024 [Paper] -
CRVQ: Channel-relaxed Vector Quantization for Extreme Compression of LLMs
Arxiv 2024 [Paper] -
ResQ: Mixed-Precision Quantization of Large Language Models with Low-Rank Residuals
Arxiv 2024 [Paper] [Code] -
MixLLM: LLM Quantization with Global Mixed-precision between Output-features and Highly-efficient System Design
MLSys 2026 [Paper] -
GQSA: Group Quantization and Sparsity for Accelerating Large Language Model Inference
Arxiv 2024 [Paper] -
LSAQ: Layer-Specific Adaptive Quantization for Large Language Model Deployment
Arxiv 2024 [Paper] -
DecDEC: A Systems Approach to Advancing Low-Bit LLM Quantization
OSDI 2025 [Paper]
2023 · 75 papers
-
FlexRound: Learnable Rounding based on Element-wise Division for Post-Training Quantization
ICML 2023 [Paper] [Code (DeepSpeed)] -
Understanding INT4 Quantization for Transformer Models: Latency Speedup, Composability, and Failure Cases
ICML 2023 [Paper] [Code] -
The case for 4-bit precision: k-bit Inference Scaling Laws
ICML 2023 [Paper] -
PreQuant: A Task-agnostic Quantization Approach for Pre-trained Language Models
ACL 2023 [Paper] -
Boost Transformer-based Language Models with GPU-Friendly Sparsity and Quantization
ACL 2023 [Paper] -
QLoRA: Efficient Finetuning of Quantized LLMs
NeurIPS 2023 [Paper] [Code] -
The Quantization Model of Neural Scaling
NeurIPS 2023 [Paper] -
Quantized Distributed Training of Large Models with Convergence Guarantees
ICML 2023 [Paper] -
RPTQ: Reorder-based Post-training Quantization for Large Language Models
Arxiv 2023 [Paper] [Code] -
ZeroQuant-V2: Exploring Post-training Quantization in LLMs from Comprehensive Study to Low Rank Compensation
AAAI 2024 [Paper] [Code] -
Integer or Floating Point? New Outlooks for Low-Bit Quantization on Large Language Models
ICML 2024 [Paper] -
Memory-Efficient Fine-Tuning of Compressed Large Language Models via sub-4-bit Integer Quantization
NeurIPS 2023 [Paper] -
Compress, Then Prompt: Improving Accuracy-Efficiency Trade-off of LLM Inference with Transferable Prompt
Arxiv 2023 [Paper] -
AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration
MLSys 2024 (Best Paper 🏆) [Paper] [Code] -
LLM-QAT: Data-Free Quantization Aware Training for Large Language Models
ACL Findings 2024 [Paper] [Code] -
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
ICLR 2024 [Paper] [Code] -
OWQ: Outlier-Aware Weight Quantization for Efficient Fine-Tuning and Inference of Large Language Models
AAAI 2024 [Paper] -
SqueezeLLM: Dense-and-Sparse Quantization
ICML 2024 [Paper] [Code] -
INT2.1: Towards Fine-Tunable Quantized Large Language Models with Error Correction through Low-Rank Adaptation
Arxiv 2023 [Paper] -
LQ-LoRA: Low-rank Plus Quantized Matrix Decomposition for Efficient Language Model Finetuning
ICLR 2024 [Paper] -
INT-FP-QSim: Mixed Precision and Formats For Large Language Models and Vision Transformers
Arxiv 2023 [Paper] [Code] -
QIGen: Generating Efficient Kernels for Quantized Inference on Large Language Models
Arxiv 2023 [Paper] [Code] -
Do Emergent Abilities Exist in Quantized Large Language Models: An Empirical Study
COLING 2024 [Paper] -
ZeroQuant-FP: A Leap Forward in LLMs Post-Training W4A8 Quantization Using Floating-Point Formats
Arxiv 2023 [Paper] [Code (DeepSpeed)] -
OliVe: Accelerating Large Language Models via Hardware-friendly Outlier-Victim Pair Quantization
ISCA 2023 [Paper] -
NUPES : Non-Uniform Post-Training Quantization via Power Exponent Search
Arxiv 2023 [Paper] -
GPT-Zip: Deep Compression of Finetuned Large Language Models
ICML 2023 Workshop ES-FoMO [Paper] -
Generating Efficient Kernels for Quantized Inference on Large Language Models
ICML 2023 Workshop ES-FoMO [Paper] -
Gradient-Based Post-Training Quantization: Challenging the Status Quo
Arxiv 2023 [Paper] -
FineQuant: Unlocking Efficiency with Fine-Grained Weight-Only Quantization for LLMs
Arxiv 2023 [Paper] -
OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models
ICLR 2024 [Paper] [Code] -
FPTQ: Fine-grained Post-Training Quantization for Large Language Models
Arxiv 2023 [Paper] -
eDKM: An Efficient and Accurate Train-time Weight Clustering for Large Language Models
IEEE Computer Architecture Letters 2023 [Paper] -
QuantEase: Optimization-based Quantization for Language Models -- An Efficient and Intuitive Algorithm
Arxiv 2023 [Paper] -
Norm Tweaking: High-performance Low-bit Quantization of Large Language Models
AAAI 2024 [Paper] -
Understanding the Impact of Post-Training Quantization on Large-scale Language Models
Arxiv 2023 [Paper] -
MEMORY-VQ: Compression for Tractable Internet-Scale Memory
NAACL 2024 [Paper] -
Optimize Weight Rounding via Signed Gradient Descent for the Quantization of LLMs
EMNLP Findings 2024 [Paper] [Code] -
Efficient Post-training Quantization with FP8 Formats
MLSys 2024 [Paper] [Code (Intel® Neural Compressor)] -
QA-LoRA: Quantization-Aware Low-Rank Adaptation of Large Language Models
ICLR 2024 [Paper] [Code] -
Rethinking Channel Dimensions to Isolate Outliers for Low-bit Weight Quantization of Large Language Models
ICLR 2024 [Paper] [Code] -
ModuLoRA: Finetuning 3-Bit LLMs on Consumer GPUs by Integrating with Modular Quantizers
TMLR (Featured Certification 🌟) [Paper] -
PB-LLM: Partially Binarized Large Language Models
ICLR 2024 [Paper] [Code] -
Dual Grained Quantization: Efficient Fine-Grained Quantization for LLM
Arxiv 2023 [Paper] -
QLLM: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models
ICLR 2024 [Paper] [Code] -
LoftQ: LoRA-Fine-Tuning-Aware Quantization for Large Language Models
ICLR 2024 [Paper] [Code] -
QFT: Quantized Full-parameter Tuning of LLMs with Affordable Resources
ICLR 2026 Workshop [Paper] -
TEQ: Trainable Equivalent Transformation for Quantization of LLMs
Arxiv 2023 [Paper] [Code (Intel® Neural Compressor)] -
BitNet: Scaling 1-bit Transformers for Large Language Models
Arxiv 2023 [Paper] [Code] -
FP8-LM: Training FP8 Large Language Models
Arxiv 2023 [Paper] [Code] -
QUIK: Towards End-to-End 4-Bit Inference on Generative Large Language Models
EMNLP 2024 [Paper] [Code] -
AFPQ: Asymmetric Floating Point Quantization for LLMs
ACL Findings 2024 [Paper] [Code] -
AWEQ: Post-Training Quantization with Activation-Weight Equalization for Large Language Models
Arxiv 2023 [Paper] -
Atom: Low-bit Quantization for Efficient and Accurate LLM Serving
MLSys 2024 [Paper] [Code] -
QMoE: Practical Sub-1-Bit Compression of Trillion-Parameter Models
Arxiv 2023 [Paper] -
Dissecting the Runtime Performance of the Training, Fine-tuning, and Inference of Large Language Models
Arxiv 2023 [Paper] -
On the Impact of Calibration Data in Post-training Quantization and Pruning
ACL 2024 [Paper] -
A Speed Odyssey for Deployable Quantization of LLMs
Arxiv 2023 [Paper] -
Fast and Efficient 2-bit LLM Inference on GPU: 2/4/16-bit in a Weight Matrix with Asynchronous Dequantization
Arxiv 2023 [Paper] -
Quantizable Transformers: Removing Outliers by Helping Attention Heads Do Nothing
NeurIPS 2023 [Paper] [Code] -
Efficient LLM Inference on CPUs
NeurIPS 2023 on Efficient Natural Language and Speech Processing [Paper] [Code] -
The Cost of Compression: Investigating the Impact of Compression on Parametric Knowledge in Language Models
EMNLP Findings 2023 [Paper] -
Zero-Shot Sharpness-Aware Quantization for Pre-trained Language Models
EMNLP 2023 [Paper] -
Revisiting Block-based Quantisation: What is Important for Sub-8-bit LLM Inference?
EMNLP 2023 [Paper] [Code] -
Outlier Suppression+: Accurate quantization of large language models by equivalent and optimal shifting and scaling
EMNLP 2023 [Paper] -
Watermarking LLMs with Weight Quantization
EMNLP 2023 [Paper] [Code] -
Enhancing Computation Efficiency in Large Language Models through Weight and Activation Quantization
EMNLP 2023 [Paper] -
LLM-FP4: 4-Bit Floating-Point Quantized Transformers
EMNLP 2023 [Paper] [Code] -
Agile-Quant: Activation-Guided Quantization for Faster Inference of LLMs on the Edge
AAAI 2024 [Paper] -
SmoothQuant+: Accurate and Efficient 4-bit Post-Training WeightQuantization for LLM
Arxiv 2023 [Paper] -
CBQ: Cross-Block Quantization for Large Language Models
Arxiv 2023 [Paper] -
ZeroQuant(4+2): Redefining LLMs Quantization with a New FP6-Centric Strategy for Diverse Generative Tasks
Arxiv 2023 [Paper] -
QuIP: 2-Bit Quantization of Large Language Models With Guarantees
NeurIPS 2023 [Paper] [Code] -
A Performance Evaluation of a Quantized Large Language Model on Various Smartphones
Arxiv 2023 [Paper] -
DeltaZip: Efficient Serving of Multiple Full-Model-Tuned LLMs
EuroSys 2025 [Paper] [Code]
2022 · 6 papers
-
ZeroQuant: Efficient and Affordable Post-Training Quantization for Large-Scale Transformers
NeurIPS 2022 [Paper] [Code (DeepSpeed)] -
LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale
NeurIPS 2022 [Paper] [Code] -
Outlier Suppression: Pushing the Limit of Low-bit Transformer Language Models
NeurIPS 2022 [Paper] [Code] -
LUT-GEMM: Quantized Matrix Multiplication based on LUTs for Efficient Inference in Large-Scale Generative Language Models
ICLR 2024 [Paper] -
SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models
ICML 2023 [Paper] [Code] -
GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers
ICLR 2023 [Paper] [Code]
Pruning and Sparsity
2026 · 33 papers
-
Adaptive Layer Selection for Layer-Wise Token Pruning in LLM Inference
ACL Findings 2026 [Paper] [Code] -
LLMs can Compress LLMs: Adaptive Pruning by Agents
Arxiv 2026 [Paper] -
Streaming-dLLM: Accelerating Diffusion LLMs via Suffix Pruning and Dynamic Decoding
Arxiv 2026 [Paper] [Code] -
GradPruner: Gradient-Guided Layer Pruning Enabling Efficient Fine-Tuning and Inference for LLMs
ICLR 2026 [Paper] -
FASA: Frequency-aware Sparse Attention
ICLR 2026 [Paper] -
Compressing LLMs with MoP: Mixture of Pruners
Arxiv 2026 [Paper] [Code] -
Pruning as a Cooperative Game: Surrogate-Assisted Layer Contribution Estimation for Large Language Models
ICLR 2026 [Paper] -
Sink-Aware Pruning for Diffusion Language Models
Arxiv 2026 [Paper] [Code] -
Curvature-Weighted Capacity Allocation: A Minimum Description Length Framework for Layer-Adaptive Large Language Model Optimization
UAI 2026 [Paper] [Code] -
Sparse-BitNet: 1.58-bit LLMs are Naturally Friendly to Semi-Structured Sparsity
Arxiv 2026 [Paper] [Code] -
Stem: Rethinking Causal Information Flow in Sparse Attention
ICML 2026 [Paper] -
High-Fidelity Pruning for Large Language Models
Arxiv 2026 [Paper] [Code] -
Sparser, Faster, Lighter Transformer Language Models
Arxiv 2026 [Paper] [Code] -
REAM: Merging Improves Pruning of Experts in LLMs
Arxiv 2026 [Paper] [Code] -
GRASPrune: Global Gating for Budgeted Structured Pruning of Large Language Models
ACL 2026 [Paper] -
Revisiting the Effectiveness of LLM Pruning for Test-Time Scaling
EMNLP Findings 2026 [Paper] -
Compute Where it Counts: Self Optimizing Language Models
Arxiv 2026 [Paper] [Code] -
Ghosted Layers: Unconstrained Activation Alignment for Recovering Layer-Pruned LLMs
Arxiv 2026 [Paper] [Code] -
LEAP: Learnable End-to-End Adaptive Pruning of Large Language Models
ICML 2026 Workshop [Paper] -
Efficient Long-Context Modeling in Diffusion Language Models via Block Approximate Sparse Attention
CVPR 2026 [Paper] -
Locality-Aware Redundancy Pruning for LLM Depth Compression
Arxiv 2026 [Paper] [Code] -
FlashMemory-DeepSeek-V4: Lightning Index Ultra-Long Context via Lookahead Sparse Attention
Arxiv 2026 [Paper] [Code] -
Beyond FLOPs: Benchmarking Real Inference Acceleration of LLM Pruning under a GEMM-Centric Taxonomy
Arxiv 2026 [Paper] [Code] -
Persona-Pruner: Sculpting Lightweight Models for Role-Playing
ICML 2026 [Paper] [Code] -
Dustin: Draft-Augmented Sparse Verification for Efficient Long-Context Generation with Speculative Decoding
ICML 2026 [Paper] -
EPTS: Elastic Post-Training Sparsity for Efficient Large Language Model Compression
KDD 2026 [Paper] -
Super-Tuning: From Activation-Aware Pruning to Sparse Fine-Tuning
Arxiv 2026 [Paper] [Code] -
WIDE: Boosting Adaptive LLM Inference via Token-level Dynamic Width Pruning
Arxiv 2026 [Paper] [Code] -
Celty: SpMspV GPU Kernel and SIMT Co-Design for Efficient Dual-Sparse LLM Inference
ICCAD 2026 [Paper] [Code] -
Prune Once: Retraining-Free Task-Agnostic Pruning for Vision-Language Models
ECCV 2026 [Paper] -
Router Sensitivity Under Lightweight Fine-Tuning Identifies Prunable Experts in Mixture-of-Experts Models
Arxiv 2026 [Paper] [Code] -
Reservoir of Importance: Learning Semi-Structured Sparsity with Differentiable Subset Sampling
EMNLP 2026 [Paper]
2025 · 60 papers
-
FASP: Fast and Accurate Structured Pruning of Large Language Models
Arxiv 2025 [Paper] -
MultiPruner: Balanced Structure Removal in Foundation Models
Arxiv 2025 [Paper] [Code] -
Mamba-Shedder: Post-Transformer Compression for Efficient Selective Structured State Space Models
NAACL 2025 [Paper] [Code] -
2SSP: A Two-Stage Framework for Structured Pruning of LLMs
Arxiv 2025 [Paper] [Code] -
You Only Prune Once: Designing Calibration-Free Model Compression With Policy Learning
ICLR 2025 [Paper] -
SwiftPrune: Hessian-Free Weight Pruning for Large Language Models
Arxiv 2025 [Paper] -
Pivoting Factorization: A Compact Meta Low-Rank Representation of Sparsity for Efficient Inference in Large Language Models
ICML 2025 [Paper] -
Twilight: Adaptive Attention Sparsity with Hierarchical Top-p Pruning
NeurIPS 2025 [Paper] -
Adapt-Pruner: Adaptive Structural Pruning for Efficient Small Language Model Training
Arxiv 2025 [Paper] -
Dobi-SVD: Differentiable SVD for LLM Compression and Some New Perspectives
ICLR 2025 [Paper] [Homepage] -
EfficientLLM: Scalable Pruning-Aware Pretraining for Architecture-Agnostic Edge Language Models
Arxiv 2025 [Paper] [Code] -
DarwinLM: Evolutionary Structured Pruning of Large Language Models
COLM 2026 [Paper] -
MaskPrune: Mask-based LLM Pruning for Layer-wise Uniform Structures
Arxiv 2025 [Paper] -
Determining Layer-wise Sparsity for Large Language Models Through a Theoretical Perspective
Arxiv 2025 [Paper] -
PPC-GPT: Federated Task-Specific Compression of Large Language Models via Pruning and Chain-of-Thought Distillation
Arxiv 2025 [Paper] -
Compression Scaling Laws: Unifying Sparsity and Quantization
Arxiv 2025 [Paper] -
PASER: Post-Training Data Selection for Efficient Pruned Large Language Model Recovery
ICLR 2026 [Paper] -
Týr-the-Pruner: Unlocking Accurate 50% Structural Pruning for LLMs via Global Sparsity Distribution Optimization
Arxiv 2025 [Paper] -
Thanos: A Block-wise Pruning Algorithm for Efficient Large Language Model Compression
Arxiv 2025 [Paper] -
Efficient LLMs with AMP: Attention Heads and MLP Pruning
IJCNN 2025 [Paper] -
ReplaceMe: Network Simplification via Layer Pruning and Linear Transformations
NeurIPS 2025 [Paper] [Code] -
Large Language Model Compression with Global Rank and Sparsity Optimization
Arxiv 2025 [Paper] -
TRIM: Achieving Extreme Sparsity with Targeted Row-wise Iterative Metric-driven Pruning
Arxiv 2025 [Paper] [Code] -
RAP: Runtime-Adaptive Pruning for LLM Inference
Arxiv 2025 [Paper] -
Two-Stage Regularization-Based Structured Pruning for LLMs
ACL 2026 [Paper] -
Pangu Light: Weight Re-Initialization for Pruning and Accelerating LLMs
Arxiv 2025 [Paper] -
Sparsified State-Space Models are Efficient Highway Networks
TMLR 2025 [Paper] [Code] -
SDMPrune: Self-Distillation MLP Pruning for Efficient Large Language Models
Arxiv 2025 [Paper] [Code] -
Amber Pruner: Leveraging N:M Activation Sparsity for Efficient Prefill in Large Language Models
Arxiv 2025 [Paper] -
Beyond Manually Designed Pruning Policies with Second-Level Performance Prediction: A Pruning Framework for LLMs
Arxiv 2025 [Paper] [Code] -
Pruning Large Language Models by Identifying and Preserving Functional Networks
Arxiv 2025 [Paper] [Code] -
SlimInfer: Accelerating Long-Context LLM Inference via Dynamic Token Pruning
Arxiv 2025 [Paper] [Code] -
EGGS-PTP: An Expander-Graph Guided Structured Post-training Pruning Method for Large Language Models
Arxiv 2025 [Paper] -
Z-Pruner: Post-Training Pruning of Large Language Models for Efficiency without Retraining
AICCSA 2025 [Paper] [Code] -
H2EAL: Hybrid-Bonding Architecture with Hybrid Sparse Attention for Efficient Long-Context LLM Inference
ICCAD 2025 [Paper] -
Less Is More? Examining Fairness in Pruned Large Language Models for Summarising Opinions
EMNLP 2025 [Paper] [Code] -
DualSparse-MoE: Coordinating Tensor/Neuron-Level Sparsity with Expert Partition and Reconstruction
Arxiv 2025 [Paper] -
Optimal Sparsity of Mixture-of-Experts Language Models for Reasoning Tasks
ICLR 2026 [Paper] [Code] -
Spatio-Temporal Pruning for Compressed Spiking Large Language Models
Arxiv 2025 [Paper] -
Dropping Experts, Recombining Neurons: Retraining-Free Pruning for Sparse Mixture-of-Experts LLMs
EMNLP 2025 [Paper] -
Reasoning Models Can be Accurately Pruned Via Chain-of-Thought Reconstruction
Arxiv 2025 [Paper] [Code] -
NIRVANA: Structured Pruning Reimagined for Large Language Model Compression
COLM 2026 [Paper] -
HEAPr: Hessian-based Efficient Atomic Expert Pruning in Output Space
ICLR 2026 [Paper] [Code] -
ProxyAttn: Guided Sparse Attention via Representative Heads
ICLR 2026 [Paper] -
Effective Model Pruning: Measure The Redundancy of Model Components
ICML 2026 [Paper] -
The Unseen Frontier: Pushing the Limits of LLM Sparsity with Surrogate-Free ADMM
ICLR 2026 [Paper] -
ARMOR: High-Performance Semi-Structured Pruning via Adaptive Matrix Factorization
ICLR 2026 [Paper] [Code] -
RCPU: Rotation-Constrained Error Compensation for Structured Pruning of Large Language Models
ICLR 2026 [Paper] -
Fewer Weights, More Problems: A Practical Attack on LLM Pruning
ICLR 2026 [Paper] [Code] -
From Local to Global: Revisiting Structured Pruning Paradigms for Large Language Models
ACL 2026 [Paper] -
Sparser Block-Sparse Attention via Token Permutation
ICML 2026 [Paper] [Code] -
Restoring Pruned Large Language Models via Lost Component Compensation
NeurIPS 2025 [Paper] -
When Fewer Layers Break More Chains: Layer Pruning Harms Test-Time Scaling in LLMs
Arxiv 2025 [Paper] [Code] -
1+1>2: A Synergistic Sparse and Low-Rank Compression Method for Large Language Models
EMNLP Findings 2025 [Paper] -
SpecAttn: Speculating Sparse Attention
NeurIPS 2025 Workshop [Paper] -
IG-Pruning: Input-Guided Block Pruning for Large Language Models
EMNLP 2025 [Paper] [Code] -
MACKO: Sparse Matrix-Vector Multiplication for Low Sparsity
Arxiv 2025 [Paper] [Code] -
Understanding and Harnessing Sparsity in Unified Multimodal Models
Arxiv 2025 [Paper] [Code] -
Resting Neurons, Active Insights: Robustifying Activation Sparsity in LLMs via Spontaneity
ICML 2026 [Paper] -
Fragile Knowledge, Robust Instruction-Following: The Width Pruning Dichotomy in Llama-3.2
Arxiv 2025 [Paper] [Code]
2024 · 77 papers
-
Plug-and-Play: An Efficient Post-training Pruning Method for Large Language Models
ICLR 2024 [Paper] [Code] -
Fast and Optimal Weight Update for Pruned Large Language Models
Arxiv 2024 [Paper] -
APT: Adaptive Pruning and Tuning Pretrained Language Models for Efficient Training and Inference
ICML 2024 [Paper] -
Scaling Sparse Fine-Tuning to Large Language Models
Arxiv 2024 [Paper] -
SliceGPT: Compress Large Language Models by Deleting Rows and Columns
ICLR 2024 [Paper] [Code] -
Shortened LLaMA: Depth Pruning for Large Language Models with Comparison of Retraining Methods
ICLR 2024 Workshop [Paper] -
Everybody Prune Now: Structured Pruning of LLMs with only Forward Passes
Arxiv 2024 [Paper] [Code] -
NutePrune: Efficient Progressive Pruning with Numerous Teachers for Large Language Models
Arxiv 2024 [Paper] -
LaCo: Large Language Model Pruning via Layer Collapse
EMNLP Findings 2024 [Paper] -
Why Lift so Heavy? Slimming Large Language Models by Cutting Off the Layers
Arxiv 2024 [Paper] -
EBFT: Effective and Block-Wise Fine-Tuning for Sparse LLMs
Arxiv 2024 [Paper] [Code] -
Data-free Weight Compress and Denoise for Large Language Models
Arxiv 2024 [Paper] -
Gradient-Free Adaptive Global Pruning for Pre-trained Language Models
NeurIPS 2024 [Paper] -
ShortGPT: Layers in Large Language Models are More Redundant Than You Expect
Arxiv 2024 [Paper] -
LLaVA-PruMerge: Adaptive Token Reduction for Efficient Large Multimodal Models
ICCV 2025 [Paper] [Code] -
Streamlining Redundant Layers to Compress Large Language Models
Arxiv 2024 [Paper] -
LoRAP: Transformer Sub-Layers Deserve Differentiated Structured Compression for Large Language Models
Arxiv 2024 [Paper] -
LoNAS: Elastic Low-Rank Adapters for Efficient Large Language Models
COLING 2024 [Paper] [Code] -
Shears: Unstructured Sparsity with Neural Low-rank Adapter Search
NAACL 2024 [Paper] [Code] -
Eigenpruning: an Interpretability-Inspired PEFT Method
NAACL 2024 Abstract [Paper] -
OpenBA-V2: Reaching 77.3% High Compression Ratio with Fast Multi-Stage Pruning
Arxiv 2024 [Paper] -
Pruning as a Domain-specific LLM Extractor
NAACL 2024 Findings [Paper] [Code] -
Differentiable Model Scaling using Differentiable Topk
ICML 2024 [Paper] -
COPAL: Continual Pruning in Large Language Generative Models
ICML 2024 [Paper] -
Pruner-Zero: Evolving Symbolic Pruning Metric from scratch for Large Language Models
ICML 2024 [Paper] [Code] -
Feature-based Low-Rank Compression of Large Language Models via Bayesian Optimization
ACL Findings 2024 [Paper] -
Surgical Feature-Space Decomposition of LLMs: Why, When and How?
ACL 2024 [Paper] -
Pruning Large Language Models to Intra-module Low-rank Architecture with Transitional Activations
ACL Findings 2024 [Paper] -
Light-PEFT: Lightening Parameter-Efficient Fine-Tuning via Early Pruning
ACL Findings 2024 [Paper] [Code] -
Quest: Query-Aware Sparsity for Efficient Long-Context LLM Inference
ICML 2024 [Paper] [Code] -
MoreauPruner: Robust Pruning of Large Language Models against Weight Perturbations
Arxiv 2024 [Paper] [Code] -
ALPS: Improved Optimization for Highly Sparse One-Shot Pruning for Large Language Models
Arxiv 2024 [Paper] -
A Training-free Sub-quadratic Cost Transformer Model Serving Framework With Hierarchically Pruned Attention
Arxiv 2024 [Paper] -
Bypass Back-propagation: Optimization-based Structural Pruning for Large Language Models via Policy Gradient
ACL 2025 [Paper] -
BlockPruner: Fine-grained Pruning for Large Language Models
ACL Findings 2025 [Paper] [Code] -
Rethinking Pruning Large Language Models: Benefits and Pitfalls of Reconstruction Error Minimization
EMNLP 2024 [Paper] -
RankAdaptor: Hierarchical Rank Allocation for Efficient Fine-Tuning Pruned LLMs via Performance Model
Arxiv 2024 [Paper] -
What Matters in Transformers? Not All Attention is Needed
Arxiv 2024 [Paper] [Code] -
Pruning via Merging: Compressing LLMs via Manifold Alignment Based Layer Merging
EMNLP 2024 [Paper] -
ShadowLLM: Predictor-based Contextual Sparsity for Large Language Models
EMNLP 2024 [Paper] [Code] -
Finding Transformer Circuits with Edge Pruning
NeurIPS 2024 [Paper] [Code] -
Efficient Expert Pruning for Sparse Mixture-of-Experts Language Models: Enhancing Performance and Reducing Inference Costs
Arxiv 2024 [Paper] [Code] -
MINI-LLM: Memory-Efficient Structured Pruning for Large Language Models
Arxiv 2024 [Paper] -
Reconstruct the Pruned Model without Any Retraining
Arxiv 2024 [Paper] -
A deeper look at depth pruning of LLMs
ICML TF2M Workshop 2024 [Paper] [Code] -
Greedy Output Approximation: Towards Efficient Structured Pruning for LLMs Without Retraining
Arxiv 2024 [Paper] -
Pruning Large Language Models with Semi-Structural Adaptive Sparse Training
Arxiv 2024 [Paper] -
A Convex-optimization-based Layer-wise Post-training Pruner for Large Language Models
Arxiv 2024 [Paper] -
ThinK: Thinner Key Cache by Query-Driven Pruning
ICLR 2025 [Paper] -
MoDeGPT: Modular Decomposition for Large Language Model Compression
ICLR 2025 [Paper] -
LLM-Barber: Block-Aware Rebuilder for Sparsity Mask in One-Shot for Large Language Models
ICCAD 2025 [Paper] [Code] -
LLM Pruning and Distillation in Practice: The Minitron Approach
Arxiv 2024 [Paper] [Models] -
Training-Free Activation Sparsity in Large Language Models
ICLR 2025 [Paper] -
Enhancing One-shot Pruned Pre-trained Language Models through Sparse-Dense-Sparse Mechanism
COLING 2025 [Paper] -
PAT: Pruning-Aware Tuning for Large Language Models
AAAI 2025 [Paper] [Code] -
Sirius: Contextual Sparsity with Correction for Efficient LLMs
Arxiv 2024 [Paper] [Code] -
STUN: Structured-Then-Unstructured Pruning for Scalable MoE Pruning
ACL 2025 [Paper] -
DISP-LLM: Dimension-Independent Structural Pruning for Large Language Models
NeurIPS 2024 [Paper] -
Search for Efficient Large Language Models
NeurIPS 2024 [Paper] -
SlimGPT: Layer-wise Structured Pruning for Large Language Models
NeurIPS 2024 [Paper] -
Learn To be Efficient: Build Structured Sparsity in Large Language Models
NeurIPS 2024 [Paper] -
ALS: Adaptive Layer Sparsity for Large Language Models via Activation Correlation Assessment
NeurIPS 2024 [Paper] -
Getting Free Bits Back from Rotational Symmetries in LLMs
Arxiv 2024 [Paper] -
SLiM: One-shot Quantization and Sparsity with Low-rank Approximation for LLM Weight Compression
ICML 2025 [Paper] [Code] -
Self-Data Distillation for Recovering Quality in Pruned Large Language Models
MLSys 2025 [Paper] -
EvoPress: Towards Optimal Dynamic Model Compression via Evolutionary Search
Arxiv 2024 [Paper] [Code] -
Pruning Foundation Models for High Accuracy without Retraining
EMNLP Findings 2024 [Paper] [Code] -
Beware of Calibration Data for Pruning Large Language Models
ICLR 2025 [Paper] -
SQFT: Low-cost Model Adaptation in Low-precision Sparse Foundation Models
EMNLP Findings 2024 [Paper] [Code] -
Change Is the Only Constant: Dynamic LLM Slicing based on Layer Redundancy
EMNLP Findings 2024 [Paper] [Code] -
Zeroth-Order Adaptive Neuron Alignment Based Pruning without Retraining
Arxiv 2025 [Paper] [Code] -
Scaling Law for Post-training after Model Pruning
ACL 2025 [Paper] -
LEMON: Reviving Stronger and Smaller LMs from Larger LMs with Linear Parameter Fusion
ACL 2024 [Paper] -
TrimLLM: Progressive Layer Dropping for Domain-Specific LLMs
Arxiv 2024 [Paper] -
FTP: A Fine-grained Token-wise Pruner for Large Language Models via Token Routing
Arxiv 2024 [Paper] -
Activation Sparsity Opportunities for Compressing General Large Language Models
Arxiv 2024 [Paper] -
FineGates: LLMs Finetuning with Compression using Stochastic Gates
Arxiv 2025 [Paper]
2023 · 41 papers
-
The Lazy Neuron Phenomenon: On Emergence of Activation Sparsity in Transformers
ICLR 2023 [Paper] -
Deja Vu: Contextual Sparsity for Efficient LLMs at Inference Time
ICML 2023 [Paper] [Code] -
LoSparse: Structured Compression of Large Language Models based on Low-Rank and Sparse Approximation
ICML 2023 [Paper] [Code] -
LLM-Pruner: On the Structural Pruning of Large Language Models
NeurIPS 2023 [Paper] [Code] -
ZipLM: Inference-Aware Structured Pruning of Language Models
NeurIPS 2023 [Paper] [Code] -
H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models
NeurIPS 2023 [Paper] [Code] -
The Emergence of Essential Sparsity in Large Pre-trained Models: The Weights that Matter
NeurIPS 2023 [Paper] [Code] -
Learning to Compress Prompts with Gist Tokens
NeurIPS 2023 [Paper] -
Dynamic Context Pruning for Efficient and Interpretable Autoregressive Transformers
NeurIPS 2023 [Paper] -
Prune and Tune: Improving Efficient Pruning Techniques for Massive Language Models
ICLR 2023 TinyPapers [Paper] -
SparseGPT: Massive Language Models Can Be Accurately Pruned in One-Shot
ICML 2023 [Paper] [Code] -
AdaLoRA: Adaptive Budget Allocation for Parameter-Efficient Fine-Tuning
ICLR 2023 [Paper] -
Structured Pruning for Efficient Generative Pre-trained Language Models
ACL 2023 [Paper] -
A Simple and Effective Pruning Approach for Large Language Models
ICLR 2024 [Paper] [Code] -
Pruning Meets Low-Rank Parameter-Efficient Fine-Tuning
ACL Findings 2024 [Paper] -
Structural pruning of large language models via neural architecture search
AutoML 2023 [Paper] -
Pruning Large Language Models via Accuracy Predictor
ICASSP 2024 [Paper] -
Flash-LLM: Enabling Cost-Effective and Highly-Efficient Large Generative Model Inference with Unstructured Sparsity
VLDB 2024 [Paper] [Code] -
Compressing LLMs: The Truth is Rarely Pure and Never Simple
ICLR 2024 [Paper] -
Pruning Small Pre-Trained Weights Irreversibly and Monotonically Impairs "Difficult" Downstream Tasks in LLMs
ICML 2024 [Paper] [Code] -
Compresso: Structured Pruning with Collaborative Prompting Learns Compact Large Language Models
Arxiv 2023 [Paper] [Code] -
Outlier Weighed Layerwise Sparsity (OWL): A Missing Secret Sauce for Pruning LLMs to High Sparsity
ICML 2024 [Paper] [Code] -
Sheared LLaMA: Accelerating Language Model Pre-training via Structured Pruning
Arxiv 2023 [Paper] [Code] -
Dynamic Sparse No Training: Training-Free Fine-tuning for Sparse LLMs
ICLR 2024 [Paper] [Code] -
One-Shot Sensitivity-Aware Mixed Sparsity Pruning for Large Language Models
ICASSP 2024 [Paper] -
Survival of the Most Influential Prompts: Efficient Black-Box Prompt Search via Clustering and Pruning
EMNLP Findings 2023 [Paper] -
The Cost of Compression: Investigating the Impact of Compression on Parametric Knowledge in Language Models
EMNLP Findings 2023 [Paper] -
Divergent Token Metrics: Measuring degradation to prune away LLM components -- and optimize quantization
Arxiv 2023 [Paper] -
LoRAShear: Efficient Large Language Model Structured Pruning and Knowledge Recovery
Arxiv 2023 [Paper] -
ReLU Strikes Back: Exploiting Activation Sparsity in Large Language Models
Arxiv 2023 [Paper] -
E-Sparse: Boosting the Large Language Model Inference through Entropy-based N:M Sparsity
Arxiv 2023 [Paper] -
Beyond Size: How Gradients Shape Pruning Decisions in Large Language Models
Arxiv 2023 [Paper] [Code] -
On the Impact of Calibration Data in Post-training Quantization and Pruning
ACL 2024 [Paper] -
BESA: Pruning Large Language Models with Blockwise Parameter-Efficient Sparsity Allocation
OpenReview [Paper] [Code] -
PUSHING GRADIENT TOWARDS ZERO: A NOVEL PRUNING METHOD FOR LARGE LANGUAGE MODELS
OpenReview 2023 [Paper] -
Lighter, yet More Faithful: Investigating Hallucinations in Pruned Large Language Models for Abstractive Summarization
TACL 2024 [Paper] [Code] -
Mini-GPTs: Efficient Large Language Models through Contextual Pruning
Arxiv 2023 [Paper] [Code] -
The LLM Surgeon
Arxiv 2023 [Paper] -
Fluctuation-based Adaptive Structured Pruning for Large Language Models
AAAI 2024 [Paper] -
How to Prune Your Language Model: Recovering Accuracy on the "Sparsity May Cry'' Benchmark
CPAL 2024 [Paper] -
PERP: Rethinking the Prune-Retrain Paradigm in the Era of LLMs
Arxiv 2023 [Paper]
2022 · 1 paper
Distillation
2026 · 30 papers
-
d3LLM: Ultra-Fast Diffusion LLM using Pseudo-Trajectory Distillation
ICML 2026 [Paper] -
RM-Distiller: Exploiting Generative LLM for Reward Model Distillation
ECAI 2026 [Paper] -
Self-Distilled Reasoner: On-Policy Self-Distillation for Large Language Models
Arxiv 2026 [Paper] [Code] -
Thinking Broad, Acting Fast: Latent Reasoning Distillation from Multi-Perspective Chain-of-Thought for E-Commerce Relevance
WWW 2026 [Paper] -
Exploring Knowledge Purification in Multi-Teacher Knowledge Distillation for LLMs
ICLR 2026 [Paper] -
FutureMind: Equipping Small Language Models with Strategic Thinking-Pattern Priors via Adaptive Knowledge Distillation
ICLR 2026 [Paper] -
Making Expert Reasoning Learnable with Self-Distillation
ICML 2026 [Paper] -
Pedagogically-Inspired Data Synthesis for Language Model Knowledge Distillation
ICLR 2026 [Paper] -
BRIDGE: Bridging Reasoning In Distillation Gap Elimination via Structure-Aware Masking
Arxiv 2026 [Paper] [Code] -
Surgical Post-Training: Proximal On-Policy Distillation for Reasoning with Knowledge Retention
Arxiv 2026 [Paper] [Code] -
KDFlow: A User-Friendly and Efficient Knowledge Distillation Framework for Large Language Models
Arxiv 2026 [Paper] [Code] -
Dual-Space Knowledge Distillation with Key-Query Matching for Large Language Models with Vocabulary Mismatch
ICASSP 2026 [Paper] -
Why Does Self-Distillation (Sometimes) Degrade the Reasoning Capability of LLMs?
COLM 2026 [Paper] [Code] -
Hybrid Policy Distillation for LLMs
ICML 2026 [Paper] -
Turning the TIDE: Cross-Architecture Distillation for Diffusion Large Language Models
Arxiv 2026 [Paper] [Code] -
SRA: Span Representation Alignment for Large Language Model Distillation
ACL 2026 [Paper] -
MTA: Multi-Granular Trajectory Alignment for Large Language Model Distillation
ACL 2026 [Paper] -
UniSD: Towards a Unified Self-Distillation Framework for Large Language Models
Arxiv 2026 [Paper] [Code] -
Rubric-based On-policy Distillation
Arxiv 2026 [Paper] [Code] -
Towards Resource-Efficient LLMs: End-to-End Energy Accounting of Distillation Pipelines
ICML 2026 [Paper] -
Skill-Conditioned Gated Self-Distillation for LLM Reasoning
EMNLP Findings 2026 [Paper] [Code] -
PADD: Path-Aligned Decompression Distillation for Non-Router Teacher to Guide MoE Student Learning
ICML 2026 [Paper] -
AsyncOPD: How Stale Can On-Policy Distillation Be?
Arxiv 2026 [Paper] [Code] -
Token-level Response-visual Attention Guidance for Multimodal LLMs Knowledge Distillation
ECCV 2026 [Paper] -
Answer-Conditioned Chains of Thought Degrade Verifiable-Reasoning Distillation in Large Language Models
Arxiv 2026 [Paper] [Code] -
On-Policy Self-Distillation without Any Supervision
Arxiv 2026 [Paper] [Code] -
Mismatch Matters: On-Policy Distillation Beyond Token Agreement
Arxiv 2026 [Paper] [Code] -
Thinking at the Right Size: Amortized Distillation Across Post-Trained LLMs
EMNLP Findings 2026 [Paper] -
SelFusion: Self-distillation for Diffusion Language Models
ACL 2026 [Paper] [Code]
2025 · 23 papers
-
Chunk-Distilled Language Modeling
Arxiv 2025 [Paper] -
CODI: Compressing Chain-of-Thought into Continuous Space via Self-Distillation
Arxiv 2025 [Paper] -
Every Expert Matters: Towards Effective Knowledge Distillation for Mixture-of-Experts Language Models
Arxiv 2025 [Paper] -
TinyR1-32B-Preview: Boosting Accuracy with Branch-Merge Distillation
Arxiv 2025 [Paper] -
UNDO: Understanding Distillation as Optimization
Arxiv 2025 [Paper] -
A Token is Worth over 1,000 Tokens: Efficient Knowledge Distillation through Low-Rank Clone
NeurIPS 2025 [Paper] [Code] -
SDMPrune: Self-Distillation MLP Pruning for Efficient Large Language Models
Arxiv 2025 [Paper] [Code] -
Less is More: Selective Reflection for Compatible and Efficient Knowledge Distillation in Large Language Models
Arxiv 2025 [Paper] -
Membership and Memorization in LLM Knowledge Distillation
Arxiv 2025 [Paper] -
Slow Tuning and Low-Entropy Masking for Safe Chain-of-Thought Distillation
Arxiv 2025 [Paper] -
Beyond Scaling Law: A Data-Efficient Distillation Framework for Reasoning
Arxiv 2025 [Paper] -
Can Large Models Teach Student Models to Solve Mathematical Problems Like Human Beings? A Reasoning Distillation Method via Multi-LoRA Interaction
IJCAI 2025 [Paper] -
Learning from Diverse Reasoning Paths with Routing and Collaboration
Arxiv 2025 [Paper] [Code] -
Student-Centered Distillation Narrows the Agentic Gap Between Small and Large LLMs
ICML 2026 [Paper] -
ORPO-Distill: Mixed-Policy Preference Optimization for Cross-Architecture LLM Distillation
NeurIPS 2025 Workshop [Paper] -
Distillation of Large Language Models via Concrete Score Matching
ICLR 2026 [Paper] -
SpikingMamba: Towards Energy-Efficient Large Language Models via Knowledge Distillation from Mamba
Arxiv 2025 [Paper] [Code] -
Boomerang Distillation Enables Zero-Shot Model Size Interpolation
ICLR 2026 [Paper] -
The Valley of Code Reasoning: Scaling Knowledge Distillation of Large Language Models
NeurIPS 2025 Workshop [Paper] -
AMiD: Knowledge Distillation for LLMs with $α$-mixture Assistant Distribution
ICLR 2026 [Paper] -
Few-Shot Knowledge Distillation of LLMs With Counterfactual Explanations
NeurIPS 2025 [Paper] -
Two Heads are Better than One: Distilling Large Language Model Features Into Small Models with Feature Decomposition and Mixture
AAAI 2026 [Paper] -
EM-KD: Distilling Efficient Multimodal Large Language Model with Unbalanced Vision Tokens
AAAI 2026 [Paper]
2024 · 28 papers
-
YODA: Teacher-Student Progressive Learning for Language Models
Arxiv 2023 [Paper] -
Knowledge Fusion of Large Language Models
ICLR 2024 [Paper] [Code] -
Knowledge Distillation for Closed-Source Language Models
Arxiv 2024 [Paper] -
Beyond Answers: Transferring Reasoning Capabilities to Smaller LLMs Using Multi-Teacher Knowledge Distillation
WSDM 2025 [Paper] -
Towards Cross-Tokenizer Distillation: the Universal Logit Distillation Loss for LLMs
Arxiv 2024 [Paper] -
Revisiting Knowledge Distillation for Autoregressive Language Models
ACL 2024 [Paper] -
Sinkhorn Distance Minimization for Knowledge Distillation
COLING 2024 [Paper] -
Divide-or-Conquer? Which Part Should You Distill Your LLM?
EMNLP Findings 2024 [Paper] -
Learning to Maximize Mutual Information for Chain-of-Thought Distillation
ACL 2024 Findings [Paper] -
DistiLLM: Towards Streamlined Distillation for Large Language Models
ICML 2024 [Paper] [Code] -
Efficiently Distilling LLMs for Edge Applications
NAACL 2024 [Paper] -
Rethinking Kullback-Leibler Divergence in Knowledge Distillation for Large Language Models
COLING 2025 [Paper] -
Distilling Algorithmic Reasoning from LLMs via Explaining Solution Programs
Arxiv 2024 [Paper] -
Direct Preference Knowledge Distillation for Large Language Models
Arxiv 2024 [Paper] [Code] -
Dual-Space Knowledge Distillation for Large Language Models
EMNLP 2024 [Paper] [Code] -
DDK: Distilling Domain Knowledge for Efficient Large Language Models
Arxiv 2024 [Paper] -
Compact Language Models via Pruning and Knowledge Distillation
Arxiv 2024 [Paper] [Code] -
LLM Pruning and Distillation in Practice: The Minitron Approach
Arxiv 2024 [Paper] [Models] -
The Mamba in the Llama: Distilling and Accelerating Hybrid Models
NeurIPS 2024 [Paper] -
DocKD: Knowledge Distillation from LLMs for Open-World Document Understanding Models
EMNLP 2024 [Paper] -
SWITCH: Studying with Teacher for Knowledge Distillation of Large Language Models
NAACL Findings 2025 [Paper] -
Mentor-KD: Making Small Language Models Better Multi-step Reasoners
EMNLP 2024 [Paper] [Code] -
Exploring and Enhancing the Transfer of Distribution in Knowledge Distillation for Autoregressive Language Models
Arxiv 2024 [Paper] -
LLM-Neo: Parameter Efficient Knowledge Distillation for Large Language Models
Arxiv 2024 [Paper] [Code] -
Enhancing Knowledge Distillation for LLMs with Response-Priming Prompting
Arxiv 2024 [Paper] [Code] -
Feature Alignment-Based Knowledge Distillation for Efficient Compression of Large Language Models
Arxiv 2024 [Paper] -
Lillama: Large Language Models Compression via Low-Rank Feature Distillation
NAACL 2025 [Paper] [Code] -
Multi-Level Optimal Transport for Universal Cross-Tokenizer Knowledge Distillation on Language Models
AAAI 2025 [Paper]
2023 · 20 papers
-
Lifting the Curse of Capacity Gap in Distilling Language Models
ACL 2023 [Paper] [Code] -
Symbolic Chain-of-Thought Distillation: Small Models Can Also "Think" Step-by-Step
ACL 2023 [Paper] -
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
ACL 2023 [Paper] -
SCOTT: Self-Consistent Chain-of-Thought Distillation
ACL 2023 [Paper] -
LaMini-LM: A Diverse Herd of Distilled Models from Large-Scale Instructions
EACL 2024 [Paper] [Code] -
Just CHOP: Embarrassingly Simple LLM Compression
Arxiv 2023 [Paper] -
The False Promise of Imitating Proprietary LLMs
Arxiv 2023 [Paper] -
GPT4All: Training an Assistant-style Chatbot with Large Scale Data Distillation from GPT-3.5-Turbo
Arxiv 2023 [Paper] [Code] -
PaD: Program-aided Distillation Can Teach Small Models Reasoning Better than Chain-of-thought Fine-tuning
NAACL 2024 [Paper] -
MiniLLM: Knowledge Distillation of Large Language Models
ICLR 2024 [Paper] [Code] -
On-Policy Distillation of Language Models: Learning from Self-Generated Mistakes
ICLR 2024 [Paper] -
Chain-of-Thought Prompt Distillation for Multimodal Named Entity and Multimodal Relation Extraction
Arxiv 2023 [Paper] -
Task-agnostic Distillation of Encoder-Decoder Language Models
Arxiv 2023 [Paper] -
Sci-CoT: Leveraging Large Language Models for Enhanced Knowledge Distillation in Small Models for Scientific QA
Arxiv 2023 [Paper] -
Baby Llama: knowledge distillation from an ensemble of teachers trained on a small dataset with no performance penalty
CoNLL 2023 [Paper] [Code] -
Can a student Large Language Model perform as well as it's teacher?
Arxiv 2023 [Paper] -
Multistage Collaborative Knowledge Distillation from Large Language Models
ACL 2024 [Paper] [Code] -
Lion: Adversarial Distillation of Closed-Source Large Language Model
EMNLP 2023 [Paper] [Code] -
MCC-KD: Multi-CoT Consistent Knowledge Distillation
EMNLP 2023 [Paper] -
PromptMix: A Class Boundary Augmentation Method for Large Language Model Distillation
EMNLP 2023 [Paper]
Efficient Prompting
2026 · 7 papers
-
SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents
Arxiv 2026 [Paper] [Code] -
COMI: Coarse-to-fine Context Compression via Marginal Information Gain
ICLR 2026 [Paper] -
Cross-Family Speculative Prefill: Training-Free Long-Context Compression with Small Draft Models
ICLR 2026 [Paper] -
Structured Distillation for Personalized Agent Memory: 11x Token Reduction with Retrieval Preservation
Arxiv 2026 [Paper] [Code] -
Density-aware Soft Context Compression with Semi-Dynamic Compression Ratio
Arxiv 2026 [Paper] [Code] -
LensVLM: Selective Context Expansion for Compressed Visual Representation of Text
Arxiv 2026 [Paper] -
AGORA: Adapter-Grounded Observation-Action Retention for Inference-Free Prompt Compression in LLM Agents
Arxiv 2026 [Paper] [Code]
2025 · 20 papers
-
ICPC: In-context Prompt Compression with Faster Inference
Arxiv 2025 [Paper] -
Efficient Prompt Compression with Evaluator Heads for Long-Context Transformer Inference
Arxiv 2025 [Paper] -
LCIRC: A Recurrent Compression Approach for Efficient Long-form Context and Query Dependent Modeling in LLMs
NAACL 2025 [Paper] -
TokenSkip: Controllable Chain-of-Thought Compression in LLMs
EMNLP 2025 [Paper] -
Task-agnostic Prompt Compression with Context-aware Sentence Embedding and Reward-guided Task Descriptor
Arxiv 2025 [Paper] -
LightThinker: Thinking Step-by-Step Compression
EMNLP 2025 [Paper] [Code] -
BatchGEMBA: Token-Efficient Machine Translation Evaluation with Batched Prompting and Prompt Compression
Arxiv 2025 [Paper] [Code] -
EFPC: Towards Efficient and Flexible Prompt Compression
Arxiv 2025 [Paper] -
KV-Distill: Nearly Lossless Learnable Context Compression for LLMs
Arxiv 2025 [Paper] -
Text Compression for Efficient Language Generation
NAACL Student Research Workshop (SRW) 2025 [Paper] -
Understanding and Improving Information Preservation in Prompt Compression for LLMs
EMNLP Findings 2025 [Paper] -
Dynamic Compressing Prompts for Efficient Inference of Large Language Models
Arxiv 2025 [Paper] [Code] -
PIS: Linking Importance Sampling and Attention Mechanisms for Efficient Prompt Compression
Arxiv 2025 [Paper] -
ProCut: LLM Prompt Compression via Attribution Estimation
Arxiv 2025 [Paper] -
SCOPE: A Generative Approach for LLM Prompt Compression
COLM 2026 [Paper] -
ILRe: Intermediate Layer Retrieval for Context Compression in Causal Language Models
Arxiv 2025 [Paper] -
AttnComp: Attention-Guided Adaptive Context Compression for Retrieval-Augmented Generation
EMNLP Findings 2025 [Paper] -
Distilling Many-Shot In-Context Learning into a Cheat Sheet
EMNLP Findings 2025 [Paper] -
ACON: Optimizing Context Compression for Long-horizon LLM Agents
ICML 2026 [Paper] -
Autoencoding-Free Context Compression for LLMs via Contextual Semantic Anchors
Arxiv 2025 [Paper] [Code]
2024 · 25 papers
-
The Impact of Reasoning Step Length on Large Language Models
ACL 2024 Findings [Paper] -
Learning to Compress Prompt in Natural Language Formats
Arxiv 2024 [Paper] -
Say More with Less: Understanding Prompt Learning Behaviors through Gist Compression
Arxiv 2024 [Paper] [Code] -
StreamingDialogue: Prolonged Dialogue Learning via Long Context Compression with Minimal Losses
Arxiv 2024 [Paper] -
LLMLingua-2: Data Distillation for Efficient and Faithful Task-Agnostic Prompt Compression
ACL Findings 2024 [Paper] [Code] -
PCToolkit: A Unified Plug-and-Play Prompt Compression Toolkit of Large Language Models
Arxiv 2024 [Paper] [Code] -
PROMPT-SAW: Leveraging Relation-Aware Graphs for Textual Prompt Compression
Arxiv 2024 [Paper] -
Prompts As Programs: A Structure-Aware Approach to Efficient Compile-Time Prompt Optimization
Arxiv 2024 [Paper] [Code] -
Adapting LLMs for Efficient Context Processing through Soft Prompt Compression
IPCA 2024 [Paper] -
Compressing Long Context for Enhancing RAG with AMR-based Concept Distillation
Arxiv 2024 [Paper] -
UniICL: An Efficient Unified Framework Unifying Compression, Selection, and Generation
ACL 2025 [Paper] -
SelfCP: Compressing Long Prompt to 1/12 Using the Frozen Large Language Model Itself
Arxiv 2024 [Paper] -
Fundamental Limits of Prompt Compression: A Rate-Distortion Framework for Black-Box Language Models
NeurIPS 2024 [Paper] -
QUITO: Accelerating Long-Context Reasoning through Query-Guided Context Compression
Arxiv 2024 [Paper] [Code] -
500xCompressor: Generalized Prompt Compression for Large Language Models
Arxiv 2024 [Paper] -
Enhancing and Accelerating Large Language Models via Instruction-Aware Contextual Compression
Arxiv 2024 [Paper] -
Prompt Compression with Context-Aware Sentence Encoding for Fast and Improved LLM Inference
Arxiv 2024 [Paper] [Code] -
Learning to Compress Contexts for Efficient Knowledge-based Visual Question Answering
Arxiv 2024 [Paper] -
Parse Trees Guided LLM Prompt Compression
Arxiv 2024 [Paper] -
AlphaZip: Neural Network-Enhanced Lossless Text Compression
Arxiv 2024 [Paper] -
Discovering the Gems in Early Layers: Accelerating Long-Context LLMs with 1000x Input Token Reduction
Arxiv 2024 [Paper] [Code] -
Perception Compressor:A training-free prompt compression method in long context scenarios
NAACL Findings 2025 [Paper] -
From Reading to Compressing: Exploring the Multi-document Reader for Prompt Compression
EMNLP Findings 2024 [Paper] [Code] -
Selection-p: Self-Supervised Task-Agnostic Prompt Compression for Faithfulness and Transferability
EMNLP Findings 2024 [Paper] -
Style-Compress: An LLM-Based Prompt Compression Framework Considering Task-Specific Styles
EMNLP Findings 2024 [Paper]
2023 · 17 papers
-
Did You Read the Instructions? Rethinking the Effectiveness of Task Definitions in Instruction Learning
ACL 2023 [Paper] [Code] -
Batch Prompting: Efficient Inference with Large Language Model APIs
EMNLP 2023 [Paper] [Code] -
Adapting Language Models to Compress Contexts
EMNLP 2023 [Paper] [Code] -
Compressing Context to Enhance Inference Efficiency of Large Language Models
EMNLP 2023 [Paper] [Code] -
LLMLingua: Compressing Prompts for Accelerated Inference of Large Language Models
EMNLP 2023 [Paper] [Code] -
Vector-Quantized Prompt Learning for Paraphrase Generation
EMNLP Findings 2023 [Paper] -
Efficient Prompting via Dynamic In-Context Learning
Arxiv 2023 [Paper] -
Learning to Compress Prompts with Gist Tokens
NeurIPS 2023 [Paper] [Code] -
In-context Autoencoder for Context Compression in a Large Language Model
ICLR 2024 [Paper] -
Discrete Prompt Compression with Reinforcement Learning
Arxiv 2023 [Paper] [Code] -
BatchPrompt: Accomplish more with less
Arxiv 2023 [Paper] -
Do Compressed LLMs Forget Knowledge? An Experimental Study with Practical Implications
Arxiv 2023 [Paper] -
RECOMP: Improving Retrieval-Augmented LMs with Compression and Selective Augmentation
Arxiv 2023 [Paper] [Code] -
LongLLMLingua: Accelerating and Enhancing LLMs in Long Context Scenarios via Prompt Compression
ACL 2024 [Paper] [Code] -
Extending Context Window of Large Language Models via Semantic Compression
Arxiv 2023 [Paper] -
Fewer is More: Boosting LLM Reasoning with Reinforced Context Pruning
EMNLP 2024 [Paper] [Code] -
Compressed Context Memory For Online Language Model Interaction
ICLR 2024 [Paper] [Code]
KV Cache Compression
2026 · 31 papers
-
Joint Encoding of KV-Cache Blocks for Scalable LLM Serving
Arxiv 2026 [Paper] [Code] -
OrbitFlow: SLO-Aware Long-Context LLM Serving with Fine-Grained KV Cache Reconfiguration
VLDB 2026 [Paper] -
HeteroCache: A Dynamic Retrieval Approach to Heterogeneous KV Cache Compression for Long-Context LLM Inference
ACL 2026 [Paper] -
LRAgent: Efficient KV Cache Sharing for Multi-LoRA LLM Agents
ICML 2026 [Paper] -
ForesightKV: Optimizing KV Cache Eviction for Reasoning Models by Learning Long-Term Contribution
ICML 2026 [Paper] -
ParisKV: Fast and Drift-Robust KV-Cache Retrieval for Long-Context LLMs
ICML 2026 [Paper] [Code] -
Learning to Evict from Key-Value Cache
ICML 2026 [Paper] [Code] -
KEEP: A KV-Cache-Centric Memory Management System for Efficient Embodied Planning
DAC 2026 [Paper] -
LookaheadKV: Fast and Accurate KV Cache Eviction by Glimpsing into the Future without Generation
ICLR 2026 [Paper] -
ScoutAttention: Efficient KV Cache Offloading via Layer-Ahead CPU Pre-computation for LLM Inference
DAC 2026 [Paper] -
Don't Waste Bits! Adaptive KV-Cache Quantization for Lightweight On-Device LLMs
CVPR 2026 [Paper] -
TriAttention: Efficient Long Reasoning with Trigonometric KV Compression
Arxiv 2026 [Paper] [Code] -
Latent-Condensed Transformer for Efficient Long Context Modeling
ACL 2026 [Paper] -
Open-TQ-Metal: Fused Compressed-Domain Attention for Long-Context LLM Inference on Apple Silicon
Arxiv 2026 [Paper] [Code] -
River-LLM: Large Language Model Seamless Exit Based on KV Share
ACL 2026 [Paper] -
PolyKV: A Shared Asymmetrically-Compressed KV Cache Pool for Multi-Agent LLM Inference
Arxiv 2026 [Paper] [Code] -
Rethinking KV Cache Eviction via a Unified Information-Theoretic Objective
Arxiv 2026 [Paper] [Code] -
Make Your LVLM KV Cache More Lightweight
TMLR 2026 [Paper] -
SplitZip: Ultra Fast Lossless KV Compression for Disaggregated LLM Serving
Arxiv 2026 [Paper] [Code] -
ReST-KV: Robust KV Cache Eviction with Layer-wise Output Reconstruction and Spatial-Temporal Smoothing
ICLR 2026 [Paper] [Code] -
MuKV: Multi-Grained KV Cache Compression for Long Streaming Video Question-Answering
Arxiv 2026 [Paper] [Code] -
Semantic Cache Distillation: Efficient State Transfer via Reuse and Selective Patching
ICML 2026 [Paper] -
RKSC: Reasoning-Aware KV Cache Sharing and Confident Early Exit for Multi-Step LLM Inference
ICML 2026 Workshop [Paper] -
KVEraser: Learning to Steer KV Cache for Efficient Localized Context Erasing
ICML 2026 Workshop [Paper] [Code] -
CompressKV: Semantic-Retrieval-Guided KV-Cache Compression for Resource-Efficient Long-Context LLM Inference
Arxiv 2026 [Paper] [Code] -
HARD-KV: Head-Adaptive Regularization for Decoding-time KV Compression
ICML 2026 [Paper] -
GSRQ: Gain-Shape Residual Quantization for Sub-1-bit KV Cache
ICML 2026 [Paper] -
Fractal KV-Cache Archives: Lossless Symbolic Storage with In-Place Retrieval for Long-Context LLM Inference
Arxiv 2026 [Paper] [Code] -
C$^2$KV: Compressed and Composable KV Cache Reuse for Efficient LLM Inference
KDD 2026 [Paper] -
WnW: Waxing-and-Waning KV Cache for Long-Form Speech LLMs
EMNLP 2026 [Paper] -
VisCache: Visual KV Cache Pruning for Efficient Vision Large Language Model Inference
Arxiv 2026 [Paper] [Code]
2025 · 69 papers
-
TreeKV: Smooth Key-Value Cache Compression with Tree Structures
Arxiv 2025 [Paper] -
RotateKV: Accurate and Robust 2-Bit KV Cache Quantization for LLMs via Outlier-Aware Adaptive Rotations
Arxiv 2025 [Paper] -
Cache Me If You Must: Adaptive Key-Value Quantization for Large Language Models
Arxiv 2025 [Paper] -
ChunkKV: Semantic-Preserving KV Cache Compression for Efficient Long-Context LLM Inference
NeurIPS 2025 [Paper] -
FastKV: Decoupling of Context Reduction and KV Cache Compression for Prefill-Decoding Acceleration
ACL Findings 2026 [Paper] [Code] -
Semantic Integrity Matters: Benchmarking and Preserving High-Density Reasoning in KV Cache Compression
ICML 2026 [Paper] -
PolarQuant: Quantizing KV Caches with Polar Transformation
Arxiv 2025 [Paper] -
Streaming Attention Approximation via Discrepancy Theory
Arxiv 2025 [Paper] -
Unshackling Context Length: An Efficient Selective Attention Approach through Query-Key Compression
Arxiv 2025 [Paper] -
RocketKV: Accelerating Long-Context LLM Inference via Two-Stage KV Cache Compression
ICML 2025 [Paper] -
Quantize What Counts: More for Keys, Less for Values
ACL 2026 [Paper] -
SVDq: 1.25-bit and 410x Key Cache Compression for LLM Attention
Arxiv 2025 [Paper] -
ReFreeKV: Towards Threshold-Free KV Cache Compression
ACL Findings 2026 [Paper] -
BaKlaVa -- Budgeted Allocation of KV cache for Long-context Inference
Arxiv 2025 [Paper] -
WeightedKV: Attention Scores Weighted Key-Value Cache Merging for Large Language Models
ICASSP 2025 [Paper] -
KVCrush: Key value cache size-reduction using similarity in head-behaviour
Arxiv 2025 [Paper] -
Q-Filters: Leveraging QK Geometry for Efficient KV Cache Compression
Arxiv 2025 [Paper] [Code] -
Beyond RAG: Task-Aware KV Cache Compression for Comprehensive Knowledge Reasoning
Arxiv 2025 [Paper] -
FastCache: Optimizing Multimodal LLM Serving through Lightweight KV-Cache Compression Framework
Arxiv 2025 [Paper] -
LLMs Know What to Drop: Self-Attention Guided KV Cache Eviction for Efficient Long-Context Inference
ICLR 2025 [Paper] -
ZeroMerge: Parameter-Free KV Cache Compression for Memory-Efficient Long-Context LLMs
Arxiv 2025 [Paper] [Code] -
Time and Memory Trade-off of KV-Cache Compression in Tensor Transformer Decoding
Arxiv 2025 [Paper] -
Plug-and-Play 1.x-Bit KV Cache Quantization for Video Large Language Models
Arxiv 2025 [Paper] [Code] -
OmniKV: Dynamic Context Selection for Efficient Long-Context LLMs
ICLR 2025 [Paper] -
WindowKV: Task-Adaptive Group-Wise KV Cache Window Selection for Efficient LLM Inference
Arxiv 2025 [Paper] [Code] -
xKV: Cross-Layer KV-Cache Compression via Aligned Singular Vector Extraction
ICML 2026 [Paper] [Code] -
LogQuant: Log-Distributed 2-Bit Quantization of KV Cache with Superior Accuracy Preservation
ICLR 2025 Workshop on Sparsity in LLMs (SLLM) [Paper] [Code] -
AirCache: Activating Inter-modal Relevancy KV Cache Compression for Efficient Large Vision-Language Model Inference
Arxiv 2025 [Paper] -
Rethinking Key-Value Cache Compression Techniques for Large Language Model Serving
MLSys 2025 [Paper] [Code] -
MILLION: Mastering Long-Context LLM Inference Via Outlier-Immunized KV Product Quantization
DAC 2025 [Paper] [Code] -
KeepKV: Eliminating Output Perturbation in KV Cache Compression for Efficient LLMs Inference
Arxiv 2025 [Paper] -
FreqKV: Key-Value Compression in Frequency Domain for Context Window Extension
ICLR 2026 [Paper] -
Accurate KV Cache Quantization with Outlier Tokens Tracing
ACL 2025 [Paper] [Code] -
NQKV: A KV Cache Quantization Scheme Based on Normal Distribution Characteristics
Arxiv 2025 [Paper] -
Titanus: Enabling KV Cache Pruning and Quantization On-the-Fly for LLM Acceleration
GLSVLSI 2025 [Paper] [Code] -
NSNQuant: A Double Normalization Approach for Calibration-Free Low-Bit Vector Quantization of KV Cache
Arxiv 2025 [Paper] -
PM-KVQ: Progressive Mixed-precision KV Cache Quantization for Long-CoT LLMs
ICLR 2026 [Paper] [Code] -
KVzip: Query-Agnostic KV Cache Compression with Context Reconstruction
NeurIPS 2025 [Paper] [Code] -
CommVQ: Commutative Vector Quantization for KV Cache Compression
ICML 2025 [Paper] [Code] -
LeanK: Learnable K Cache Channel Pruning for Efficient Decoding
Arxiv 2025 [Paper] -
CompressKV: Semantic Retrieval Heads Know What Tokens are Not Important Before Generation
Arxiv 2025 [Paper] [Code] -
Sparse-dLLM: Accelerating Diffusion LLMs with Dynamic Cache Eviction
Arxiv 2025 [Paper] [Code] -
SmallKV: Small Model Assisted Compensation of KV Cache Compression for Efficient LLM Inference
Arxiv 2025 [Paper] -
KVSink: Understanding and Enhancing the Preservation of Attention Sinks in KV Cache Quantization for LLMs
COLM 2025 [Paper] -
PiKV: KV Cache Management System for Mixture of Experts
Arxiv 2025 [Paper] [Code] -
Retrospective Sparse Attention for Efficient Long-Context Generation
Arxiv 2025 [Paper] -
XQuant: Breaking the Memory Wall for LLM Inference with KV Cache Rematerialization
Arxiv 2025 [Paper] -
ZigzagAttention: Efficient Long-Context Inference with Exclusive Retrieval and Streaming Heads
Arxiv 2025 [Paper] -
Accelerating LLM Inference via Dynamic KV Cache Placement in Heterogeneous Memory System
IEEE CAL 2025 [Paper] -
SparK: Query-Aware Unstructured Sparsity with Recoverable KV Cache Channel Pruning
AAAI 2026 [Paper] [Code] -
StreamMem: Query-Agnostic KV Cache Memory for Streaming Video Understanding
Arxiv 2025 [Paper] -
CommonKV: Compressing KV Cache with Cross-layer Parameter Sharing
Arxiv 2025 [Paper] -
Learned Structure in Cartridges: Keys as Shareable Routers in Self-Studied Representations
Arxiv 2025 [Paper] -
Spotlight Attention: Towards Efficient LLM Generation via Non-linear Hashing-based KV Cache Retrieval
Arxiv 2025 [Paper] -
Judge Q: Trainable Queries for Optimized Information Retention in KV Cache Eviction
AAAI 2026 [Paper] -
EpiCache: Episodic KV Cache Management for Long-Term Conversation on Resource-Constrained Environments
ICML 2026 [Paper] -
KaVa: Latent Reasoning via Compressed KV-Cache Distillation
ICLR 2026 [Paper] -
OBCache: Optimal Brain KV Cache Pruning for Efficient Long-Context LLM Inference
ICML 2026 [Paper] -
Mask Tokens as Prophet: Fine-Grained Cache Eviction for Efficient dLLM Inference
Arxiv 2025 [Paper] [Code] -
XQuant: Achieving Ultra-Low Bit KV Cache Quantization with Cross-Layer Compression
EMNLP 2025 [Paper] -
KVCOMM: Online Cross-context KV-cache Communication for Efficient LLM-based Multi-agent Systems
NeurIPS 2025 [Paper] [Code] -
Attention Is All You Need for KV Cache in Diffusion LLMs
Arxiv 2025 [Paper] [Code] -
StreamingTOM: Streaming Token Compression for Efficient Video Understanding
CVPR 2026 [Paper] -
Mixing Importance with Diversity: Joint Optimization for KV Cache Compression in Large Vision-Language Models
ICLR 2026 [Paper] [Code] -
FlexiCache: Leveraging Temporal Stability of Attention Heads for Efficient KV Cache Management
MLSys 2026 [Paper] -
KV Cache Transform Coding for Compact Storage in LLM Inference
ICLR 2026 [Paper] -
Reconstructing KV Caches with Cross-layer Fusion For Enhanced Transformers
ICLR 2026 [Paper] -
V-Rex: Real-Time Streaming Video LLM Acceleration via Dynamic KV Cache Retrieval
HPCA 2026 [Paper] -
PackKV: Reducing KV Cache Memory Footprint through LLM-Aware Lossy Compression
Arxiv 2025 [Paper] [Code]
2024 · 43 papers
-
KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization
NeurIPS 2024 [Paper] -
KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache
ICML 2024 [Paper] [Code] -
No Token Left Behind: Reliable KV Cache Compression via Importance-Aware Mixed Precision Quantization
Arxiv 2024 [Paper] -
Keyformer: KV Cache Reduction through Key Tokens Selection for Efficient Generative Inference
MLSys 2024 [Paper] -
GEAR: An Efficient KV Cache Compression Recipefor Near-Lossless Generative Inference of LLM
Arxiv 2024 [Paper] -
QAQ: Quality Adaptive Quantization for LLM KV Cache
Arxiv 2024 [Paper] [Code] -
KV Cache is 1 Bit Per Channel: Efficient Large Language Model Inference with Coupled Quantization
Arxiv 2024 [Paper] -
PyramidInfer: Pyramid KV Cache Compression for High-throughput LLM Inference
ACL 2024 [Paper] -
Unlocking Data-free Low-bit Quantization with Matrix Decomposition for KV Cache Compression
Arxiv 2024 [Paper] -
ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification
Arxiv 2024 [Paper] -
MiniCache: KV Cache Compression in Depth Dimension for Large Language Models
Arxiv 2024 [Paper] -
PyramidKV: Dynamic KV Cache Compression based on Pyramidal Information Funneling
Arxiv 2024 [Paper] -
QJL: 1-Bit Quantized JL Transform for KV Cache Quantization with Zero Overhead
Arxiv 2024 [Paper] [[Code]](https://githu
Truncated — view the full README on GitHub.
Similar repos
Contributors
(top 30 of 46)