
A curated collection of papers, benchmarks, surveys, and tools for model quantization, covering low-bit networks, LLMs, multimodal and generative models, vector and lattice quantization, and efficient deployment.
2,449
336 commits
updated Sep 21, 2026
README
Awesome Model Quantization 
Awesome Model Quantization is a curated, continuously updated collection of papers, benchmarks, surveys, and open-source implementations on neural network and model quantization. It spans binary and ternary networks, post-training quantization, quantization-aware training, vector and lattice quantization, low-bit LLMs, multimodal and generative models, KV-cache quantization, low-precision training, and hardware-efficient deployment.
Quick Navigation
- Research Landscape
- Representative Works
- Benchmarks · Survey Papers
- Papers by Year
2026 · 2025 · 2024 · 2023 · 2022 · 2021 · 2020 · 2019 · 2018 · 2017 · 2016 · 2015 · 2014 - Books · Related Repositories · Researcher Homepages · Contributing / Scope
Research Landscape
Model quantization can be organized along five dimensions:
- Optimization: post-training quantization (PTQ), quantization-aware training (QAT), quantized fine-tuning, data-free methods, and low-precision training.
- Representation: scalar, vector/codebook, lattice, binary-coded, binary/ternary, and mixed-precision quantization.
- Error reduction: rotations, outlier smoothing, residual reconstruction, error compensation, and sensitivity-aware methods.
- Quantized tensors: weights, activations, KV caches, training states, gradients, and communication.
- Models and deployment: vision, language, multimodal, generative, state space, and graph models, alongside edge and hardware systems.
Methods often combine several dimensions, such as PTQ with rotations and vector codebooks.
🔎 Explore the taxonomy and method connections · Click to expand
Optimization paradigm
Post-Training Quantization (PTQ) converts a pretrained model, often with calibration: GPTQ, SmoothQuant, AWQ, OmniQuant, QuaRot, SpinQuant, FlatQuant, BiLLM. Quantization-Aware Training (QAT) models quantization during optimization: PACT, LSQ, IR-Net. Quantized Fine-Tuning / Parameter-Efficient Fine-Tuning (PEFT) adapts low-bit models: QLoRA, QA-LoRA, LoftQ, IR-QLoRA, L4Q. Data-Free / Zero-Shot Quantization avoids original training data, using model statistics or synthetic samples: ZeroQ, Qimera. Low-Precision Training also reduces precision in training computation or stored states: INT8/FP8 training, 8-bit Optimizers.
Representation / coding structure
Scalar quantization codes individual values; non-uniform, logarithmic, and floating-point quantization change the available levels (AdaLog, LLM-FP4). Vector quantization jointly codes tuples; codebook quantization stores reusable representatives; product / grouped vector quantization partitions vectors into groups (GPTVQ, VPTQ, EPQuant). Lattice quantization uses structured geometric codebooks (QuIP#, NestQuant, grouped lattice vector quantizers). Binary-coded quantization combines binary bases (AnyBCQ); binary / ternary quantization constrains values to two / three levels (IR-Net, BiBERT, PT²-LLM). Mixed precision allocates different bit widths or formats across tensors or groups (HAWQ, SliM-LLM).
Transformation / error handling
Rotation / orthogonal transforms redistribute coordinates (QuaRot, SpinQuant); outlier smoothing / redistribution balances quantization difficulty (SmoothQuant, AWQ). Residual / low-rank reconstruction models remaining errors or outliers (LQER, SVDQuant); error compensation corrects quantization effects (GPTQ, First-Order Error Matters). Saliency-aware / Hessian-aware quantization uses importance or curvature to guide precision, reconstruction, or rounding (HAWQ, GPTQ, BiLLM). These techniques can accompany scalar or structured coding.
Quantized object
Weights (GPTQ, AWQ); activations (PACT); weight + activation (SmoothQuant, BiBERT); KV cache (KIVI, KVQuant, ZipCache, PM-KVQ); training states / optimizer states (ActNN, 8-bit Optimizers); gradients / communication (DoReFa-Net, SDP4Bit). Weight bit width does not imply the same activation, accumulator, or cache precision.
Model family / deployment
CNNs / classical vision (XNOR-Net, BRECQ); Vision Transformers (PTQ4ViT); Large Language Models (GPTQ, QLoRA); multimodal / VLM / VLA (Q-VLM, MQuant, AutoQVLA); diffusion / generative models (PTQ4DM, Q-Diffusion, PTQD, ViDiT-Q, SVDQuant, BinaryDM, Q-VDiT, S²Q-VDiT, QuantSparse); Mamba / state space models (Quamba2, SSDi8); graph / point cloud models (EPQuant, BiPointNet); edge / embedded / hardware-oriented systems (HAQ, FINN, LUT-GEMM).
For the structured-coding lineage, QuIP introduces incoherence processing for low-bit LLM quantization; QuIP# connects this direction to lattice codebooks, while QTIP uses trellis coding. GPTVQ, VPTQ, and NestQuant explore vector or lattice representations. TurboQuant and RaBitQ are also retained for their vector-quantization methodology; RaBitQ targets approximate nearest-neighbor search rather than LLM weight quantization.
Bit width alone does not specify storage overhead, arithmetic precision, or deployment speed.
Representative Works
Selected works grouped by technical approach, with authors and short method summaries. Each paper has one primary home here; the yearly collection includes the wider literature.
- Foundations: Classical / QAT · Data-free · Binary / ternary · Vector / codebook
- Language models: Transformer / LLM · Quantized fine-tuning · KV cache
- Models and systems: Generative models · Multimodal / state space · Vision / hardware · Floating-point formats · Training
Reading the links: Scholar opens a title search on Google Scholar, where citation counts can be viewed. Star badges show the linked GitHub repository’s stars, which may cover several papers. These are discovery aids, not rankings.
Classical Quantization and QAT
From binary weights and learned codebooks to integer arithmetic, learned quantizers and reconstruction-based PTQ.
-
BinaryConnect: Training Deep Neural Networks with binary weights during propagations
Matthieu Courbariaux, Yoshua Bengio, Jean-Pierre David
NeurIPS 2015 ·Neural NetworksQATBinary Weights· Paper · Code · Scholar
Trains neural networks with binary weights during forward and backward propagation. -
XNOR-Net: ImageNet Classification Using Binary Convolutional Neural Networks
Mohammad Rastegari, Vicente Ordonez, Joseph Redmon, Ali Farhadi
ECCV 2016 ·CNNBinaryWeight + Activation· Paper · Code · Scholar
Approximates convolutions with binary weights and inputs for efficient CNN inference. -
Deep Compression: Compressing Deep Neural Networks with Pruning, Trained Quantization and Huffman Coding
Song Han, Huizi Mao, William J. Dally
ICLR 2016 ·CNNWeight SharingCodebook· Paper · Scholar
Combines pruning, trained weight sharing and Huffman coding, connecting learned quantization to compressed model storage. -
PACT: Parameterized Clipping Activation for Quantized Neural Networks
Jungwook Choi, Zhuo Wang, Swagath Venkataramani, Pierce I-Jen Chuang, Vijayalakshmi Srinivasan, Kailash Gopalakrishnan
ICLR 2018 ·CNNQATActivations· Paper · Scholar
Learns activation clipping thresholds to support low-bit network training. -
Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference
Benoit Jacob, Skirmantas Kligys, Bo Chen, Menglong Zhu, Matthew Tang, Andrew Howard, Hartwig Adam, Dmitry Kalenichenko
CVPR 2018 ·QATINT8Integer-Only Inference· Paper · Scholar
Co-designs quantization-aware training and integer arithmetic for mobile inference, including scale and zero-point handling. -
HAWQ: Hessian AWare Quantization of Neural Networks With Mixed-Precision
Zhen Dong, Zhewei Yao, Amir Gholami, Michael W. Mahoney, Kurt Keutzer
ICCV 2019 ·Mixed PrecisionHessian-Aware· Paper · Scholar
Uses Hessian information to guide mixed-precision neural network quantization. -
Learned Step Size Quantization
Steven K. Esser, Jeffrey L. McKinstry, Deepika Bablani, Rathinakumar Appuswamy, Dharmendra S. Modha
ICLR 2020 ·QATLow-Bit· Paper · Scholar
Learns quantizer step sizes alongside network parameters. -
Up or Down? Adaptive Rounding for Post-Training Quantization
Markus Nagel, Rana Ali Amjad, Mart van Baalen, Christos Louizos, Tijmen Blankevoort
ICML 2020 ·PTQRounding· Paper · Scholar
Optimizes rounding decisions when converting pretrained weights to low precision. -
HAWQ-V2: Hessian Aware trace-Weighted Quantization of Neural Networks
Zhen Dong, Zhewei Yao, Daiyaan Arfeen, Amir Gholami, Michael Mahoney, Kurt Keutzer
NeurIPS 2020 ·Mixed PrecisionHessian-Aware· Paper · Scholar
Develops trace-weighted Hessian sensitivity for mixed-precision allocation. -
BRECQ: Pushing the Limit of Post-Training Quantization by Block Reconstruction
Yuhang Li, Ruihao Gong, Xu Tan, Yang Yang, Peng Hu, Qi Zhang, Fengwei Yu, Wei Wang, Shi Gu
ICLR 2021 ·CNNPTQReconstruction· Paper · Code · Scholar
Uses block reconstruction to reduce post-training quantization error. -
QDrop: Randomly Dropping Quantization for Extremely Low-bit Post-Training Quantization
Xiuying Wei, Ruihao Gong, Yuhang Li, Xianglong Liu, Fengwei Yu
ICLR 2022 ·PTQActivationsReconstruction· Paper · Code · Scholar
Randomly bypasses activation quantization during reconstruction to improve low-bit generalization beyond the calibration data.


Data-Free and Zero-Shot Quantization
These methods replace access to the original dataset with model statistics or generated samples; they may still require calibration or optimization.
-
Data-Free Quantization Through Weight Equalization and Bias Correction
Markus Nagel, Mart van Baalen, Tijmen Blankevoort, Max Welling
ICCV 2019 ·CNNPTQData-Free· Paper · Scholar
Equalizes channel ranges and corrects quantization-induced bias using model parameters and statistics. -
ZeroQ: A Novel Zero Shot Quantization Framework
Yaohui Cai, Zhewei Yao, Zhen Dong, Amir Gholami, Michael W. Mahoney, Kurt Keutzer
CVPR 2020 ·CNNData-FreeMixed Precision· Paper · Code · Scholar
Synthesizes calibration inputs from batch-normalization statistics to quantize without the original training dataset. -
Diversifying Sample Generation for Accurate Data-Free Quantization
Xiangguo Zhang, Haotong Qin, Yifu Ding, Ruihao Gong, Qinghua Yan, Renshuai Tao, Yuhang Li, Fengwei Yu, Xianglong Liu
CVPR 2021 · Oral ·CNNData-FreeSynthetic DataPTQ· Paper · Scholar
Relaxes batch-normalization statistic matching and varies layer-wise emphasis to diversify synthetic calibration samples for data-free quantization. -
Diverse Sample Generation: Pushing the Limit of Generative Data-Free Quantization
Haotong Qin, Yifu Ding, Xiangguo Zhang, Jiakai Wang, Xianglong Liu, Jiwen Lu
IEEE TPAMI 2023 ·CNNData-FreePTQ + QATSample Diversity· Paper · Code · Scholar
Extends the CVPR 2021 DSG method with theoretical analysis and inter-sample decorrelation, improving synthetic-data generation for both PTQ and QAT. -
LLM-QAT: Data-Free Quantization Aware Training for Large Language Models
Zechun Liu, Barlas Oguz, Changsheng Zhao, Ernie Chang, Pierre Stock, Yashar Mehdad, Yangyang Shi, Raghuraman Krishnamoorthi, Vikas Chandra
ACL Findings 2024 ·LLMQATData-FreeKV Cache· Paper · Scholar
Uses the pretrained model’s generated text for distillation-based QAT of weights, activations and KV caches.


Transformer and LLM Quantization
Weight-only compression, weight–activation quantization and QAT address different deployment needs. Sparse outlier handling and rotations offer complementary ways to control error.
-
LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale
Tim Dettmers, Mike Lewis, Younes Belkada, Luke Zettlemoyer
NeurIPS 2022 ·TransformerINT8Mixed Precision· Paper · Code · Scholar
Enables 8-bit matrix multiplication at transformer scale while handling outlier features in higher precision. -
GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers
Elias Frantar, Saleh Ashkboos, Torsten Hoefler, Dan Alistarh
ICLR 2023 ·LLMPTQWeights· Paper · Code · Scholar
Uses approximate second-order information and error compensation for low-bit weight quantization. -
SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models
Guangxuan Xiao, Ji Lin, Mickael Seznec, Hao Wu, Julien Demouth, Song Han
ICML 2023 ·LLMPTQWeight + Activation· Paper · Code · Scholar
Redistributes activation outlier difficulty into weights to enable low-precision matrix multiplication. -
AWQ: Activation-aware Weight Quantization for On-Device LLM Compression and Acceleration
Ji Lin, Jiaming Tang, Haotian Tang, Shang Yang, Wei-Ming Chen, Wei-Chen Wang, Guangxuan Xiao, Xingyu Dang, Chuang Gan, Song Han
MLSys 2024 ·LLMPTQWeightsSaliency-Aware· Paper · Code · Scholar
Uses activation information to guide weight quantization for on-device compression and acceleration. -
OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models
Wenqi Shao, Mengzhao Chen, Zhaoyang Zhang, Peng Xu, Lirui Zhao, Zhiqian Li, Kaipeng Zhang, Peng Gao, Yu Qiao, Ping Luo
ICLR 2024 ·LLMPTQCalibration· Paper · Code · Scholar
Optimizes clipping and equivalent transformations to calibrate low-bit LLMs. -
QuaRot: Outlier-Free 4-Bit Inference in Rotated LLMs
Saleh Ashkboos, Amirkeivan Mohtashami, Maximilian L. Croci, Bo Li, Pashmina Cameron, Martin Jaggi, Dan Alistarh, Torsten Hoefler, James Hensman
NeurIPS 2024 ·LLMPTQ4-BitRotation· Paper · Code · Scholar
Uses rotations to suppress outliers and enable 4-bit inference. -
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
Tim Dettmers, Ruslan Svirschevski, Vage Egiazarian, Denis Kuznedelev, Elias Frantar, Saleh Ashkboos, Alexander Borzunov, Torsten Hoefler, Dan Alistarh
ICLR 2024 ·LLMPTQWeightsSparse Outliers· Paper · Code · Scholar
Separates sensitive outlier weights into a sparse higher-precision component while quantizing the remaining weights. -
SqueezeLLM: Dense-and-Sparse Quantization
Sehoon Kim, Coleman Hooper, Amir Gholami, Zhen Dong, Xiuyu Li, Sheng Shen, Michael W. Mahoney, Kurt Keutzer
ICML 2024 ·LLMPTQNon-uniformSparse Outliers· Paper · Code · Scholar
Combines sensitivity-weighted non-uniform scalar quantization with a sparse component for outlier weights. -
SpinQuant: LLM Quantization with Learned Rotations
Zechun Liu, Changsheng Zhao, Igor Fedorov, Bilge Soran, Dhruv Choudhary, Raghuraman Krishnamoorthi, Vikas Chandra, Yuandong Tian, Tijmen Blankevoort
ICLR 2025 ·LLMPTQLearned Rotation· Paper · Code · Scholar
Learns rotations to make LLM representations more amenable to quantization. -
FlatQuant: Flatness Matters for LLM Quantization
Yuxuan Sun, Ruikang Liu, Haoli Bai, Han Bao, Kang Zhao, Yuening Li, Jiaxin Hu, Xianzhi Yu, Lu Hou, Chun Yuan, Xin Jiang, Wulong Liu, Jun Yao
ICML 2025 ·LLMPTQTransformation· Paper · Code · Scholar
Targets distribution flatness to improve LLM quantization. -
EfficientQAT: Efficient Quantization-Aware Training for Large Language Models
Mengzhao Chen, Wenqi Shao, Peng Xu, Jiahao Wang, Peng Gao, Kaipeng Zhang, Ping Luo
ACL 2025 ·LLMQATLow-Bit· Paper · Code · Scholar
Trains block parameters first, then quantization parameters end to end, to reduce the cost of LLM QAT.


Quantized Fine-Tuning
QLoRA and related methods adapt low-bit bases with low-rank updates; PV-Tuning also optimizes discrete compressed representations.
-
QLoRA: Efficient Finetuning of Quantized LLMs
Tim Dettmers, Artidoro Pagnoni, Ari Holtzman, Luke Zettlemoyer
NeurIPS 2023 ·LLMPEFT4-Bit· Paper · Code · Scholar
Fine-tunes low-rank adapters through a frozen 4-bit quantized base model. -
QA-LoRA: Quantization-Aware Low-Rank Adaptation of Large Language Models
Yuhui Xu, Lingxi Xie, Xiaotao Gu, Xin Chen, Heng Chang, Hengheng Zhang, Zhengsu Chen, Xiaopeng Zhang, Qi Tian
ICLR 2024 ·LLMPEFTQuantization-Aware· Paper · Code · Scholar
Combines quantization-aware optimization with low-rank adaptation. -
LoftQ: LoRA-Fine-Tuning-aware Quantization for Large Language Models
Yixiao Li, Yifan Yu, Chen Liang, Pengcheng He, Nikos Karampatziakis, Weizhu Chen, Tuo Zhao
ICLR 2024 ·LLMPEFTLow-Bit· Paper · Code · Scholar
Aligns quantization with LoRA initialization to reduce the error encountered during adaptation. -
Accurate LoRA-Finetuning Quantization of LLMs via Information Retention
Haotong Qin, Xudong Ma, Xingyu Zheng, Xiaoyang Li, Yang Zhang, Shouda Liu, Jie Luo, Xianglong Liu, Michele Magno
ICML 2024 ·LLMPEFTInformation-Aware· Paper · Code · Scholar
Uses information retention to improve low-bit quantization and LoRA adaptation. -
PV-Tuning: Beyond Straight-Through Estimation for Extreme LLM Compression
Vladimir Malinovskii, Denis Mazur, Ivan Ilin, Denis Kuznedelev, Konstantin Burlachenko, Kai Yi, Dan Alistarh, Peter Richtarik
NeurIPS 2024 ·LLMQuantized Fine-TuningDiscrete Optimization· Paper · Code · Scholar
Alternates continuous and discrete optimization to fine-tune extremely compressed models, including additive-codebook representations. -
L4Q: Parameter Efficient Quantization-Aware Fine-Tuning on Large Language Models
Hyesung Jeon, Yulhwa Kim, Jae-Joon Kim
ACL 2025 ·LLMPEFTQAT· Paper · Scholar
Combines parameter-efficient fine-tuning with quantization-aware training.


Extreme Low-Bit, Binary and Ternary
Binary CNNs and transformers, post-training binarization, and native ternary pretraining have different training costs and arithmetic requirements.
-
Bi-Real Net: Enhancing the Performance of 1-bit CNNs With Improved Representational Capability and Advanced Training Algorithm
Zechun Liu, Baoyuan Wu, Wenhan Luo, Xin Yang, Wei Liu, Kwang-Ting Cheng
ECCV 2018 ·CNNBinaryQAT· Paper · Code · Scholar
Connects real-valued intermediate activations through shortcuts to improve information flow in 1-bit CNNs. -
Forward and Backward Information Retention for Accurate Binary Neural Networks
Haotong Qin, Ruihao Gong, Xianglong Liu, Mingzhu Shen, Ziran Wei, Fengwei Yu, Jingkuan Song
CVPR 2020 ·CNNQATBinary1-Bit· Paper · Code · Scholar
Retains information in both forward activations and backward gradients when training binary neural networks. -
ReActNet: Towards Precise Binary Neural Network with Generalized Activation Functions
Zechun Liu, Zhiqiang Shen, Marios Savvides, Kwang-Ting Cheng
ECCV 2020 ·CNNBinaryQAT· Paper · Code · Scholar
Learns activation shifts and reshaping functions to reduce the accuracy gap between binary and real-valued networks. -
BiBERT: Accurate Fully Binarized BERT
Haotong Qin, Yifu Ding, Mingyuan Zhang, Qinghua Yan, Aishan Liu, Qingqing Dang, Ziwei Liu, Xianglong Liu
ICLR 2022 ·TransformerNLPBinaryWeight + Activation· Paper · Code · Scholar
Targets fully binarized BERT, extending binary networks to transformer language models. -
BiLLM: Pushing the Limit of Post-Training Quantization for LLMs
Wei Huang, Yangdong Liu, Haotong Qin, Ying Li, Shiming Zhang, Xianglong Liu, Michele Magno, Xiaojuan Qi
ICML 2024 ·LLMPTQBinaryExtreme Low-Bit· Paper · Code · Scholar
Uses saliency-aware binarization to push pretrained LLM weights into the extreme low-bit regime. -
DB-LLM: Accurate Dual-Binarization for Efficient LLMs
Hong Chen, Chengtao Lv, Liang Ding, Haotong Qin, Xiabin Zhou, Yifu Ding, Xuebo Liu, Min Zhang, Jinyang Guo, Xianglong Liu, Dacheng Tao
ACL Findings 2024 ·LLMDual BinarizationExtreme Low-Bit· Paper · Scholar
Uses dual binarization to compress LLMs while retaining accuracy. -
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
Shuming Ma, Hongyu Wang, Lingxiao Ma, Lei Wang, Wenhui Wang, Shaohan Huang, Li Dong, Ruiping Wang, Jilong Xue, Furu Wei
arXiv 2024 ·LLMQATTernary Weights8-Bit Activations· Paper · Scholar
Extends BitNet’s quantization-aware pretraining to ternary weights; this is a training recipe, distinct from post-training binarization. -
ARB-LLM: Alternating Refined Binarizations for Large Language Models
Zhiteng Li, Xianglong Yan, Tianao Zhang, Haotong Qin, Dong Xie, Jiang Tian, Zhongchao Shi, Linghe Kong, Yulun Zhang, Xiaokang Yang
ICLR 2025 ·LLMBinaryExtreme Low-Bit· Paper · Code · Scholar
Refines alternating binarizations for low-bit LLM representation. -
PTQ1.61: Push the Real Limit of Extremely Low-Bit Post-Training Quantization Methods for Large Language Models
Jiaqi Zhao, Miao Zhang, Ming Wang, Yuzhang Shang, Kaihao Zhang, Weili Guan, Yaowei Wang, Min Zhang
ACL 2025 ·LLMPTQExtreme Low-Bit· Paper · Code · Scholar
Explores extremely low-bit post-training quantization for LLMs. -
PT²-LLM: Post-Training Ternarization for Large Language Models
Xianglong Yan, Chengzhu Bao, Zhiteng Li, Tianao Zhang, Kaicheng Yang, Haotong Qin, Ruobing Xie, Xingwu Sun, Yulun Zhang
ICLR 2026 ·LLMPTQTernary· Paper · Code · Scholar
Converts pretrained large language models to ternary representations.


Vector, Lattice and Codebook Quantization
From CNN product quantization to LLM additive, lattice and trellis codes. QuIP provides the incoherence-processing precursor; RaBitQ contributes vector-search methodology.
-
Compressing Deep Convolutional Networks using Vector Quantization
Yunchao Gong, Liu Liu, Ming Yang, Lubomir Bourdev
arXiv 2014 ·CNNVector QuantizationProduct Quantization· Paper · Scholar
Studies clustering and product quantization of CNN parameters as early approaches to reducing model storage. -
QuIP: 2-Bit Quantization of Large Language Models With Guarantees
Jerry Chee, Yaohui Cai, Volodymyr Kuleshov, Christopher De Sa
NeurIPS 2023 ·LLMPTQ2-BitIncoherence· Paper · Code · Scholar
Uses incoherence processing for low-bit quantization with guarantees, forming a precursor to the QuIP# lattice-codebook lineage. -
QuIP#: Even Better LLM Quantization with Hadamard Incoherence and Lattice Codebooks
Albert Tseng, Jerry Chee, Qingyao Sun, Volodymyr Kuleshov, Christopher De Sa
ICML 2024 ·LLMLatticeCodebookHadamard· Paper · Code · Scholar
Combines Hadamard incoherence processing with lattice codebooks for LLM quantization. -
QTIP: Quantization with Trellises and Incoherence Processing
Albert Tseng, Qingyao Sun, David Hou, Christopher De Sa
NeurIPS 2024 ·LLMTrellis CodingIncoherence· Paper · Code · Scholar
Combines trellis-based quantization with incoherence processing for compact LLM representation. -
GPTVQ: The Blessing of Dimensionality for LLM Quantization
Mart van Baalen, Andrey Kuzmin, Ivan Koryakovskiy, Markus Nagel, Peter Couperus, Cedric Bastoul, Eric Mahurin, Tijmen Blankevoort, Paul Whatmough
arXiv 2024 ·LLMVector QuantizationWeights· Paper · Code · Scholar
Exploits joint quantization of multiple weight coordinates rather than coding each weight independently. -
VPTQ: Extreme Low-bit Vector Post-Training Quantization for Large Language Models
Yifei Liu, Jicheng Wen, Yang Wang, Shengyu Ye, Li Lyna Zhang, Ting Cao, Cheng Li, Mao Yang
EMNLP 2024 ·LLMPTQVector QuantizationExtreme Low-Bit· Paper · Code · Scholar
Uses vector post-training quantization for extremely low-bit LLM compression. -
RaBitQ: Quantizing High-Dimensional Vectors with a Theoretical Error Bound for Approximate Nearest Neighbor Search
Jianyang Gao, Cheng Long
SIGMOD 2024 ·Vector QuantizationBinary CodesVector Search· Paper · Code · Scholar
Quantizes high-dimensional vectors with a theoretical error bound for approximate nearest-neighbor search. -
Extreme Compression of Large Language Models via Additive Quantization
Vage Egiazarian, Andrei Panferov, Denis Kuznedelev, Elias Frantar, Artem Babenko, Dan Alistarh
ICML 2024 ·LLMPTQAdditive Codebooks2–3 Bit· Paper · Code · Scholar
Represents weight vectors as sums of learned codewords and jointly optimizes codebooks within transformer blocks. -
NestQuant: nested lattice quantization for matrix products and LLMs
Semyon Savkin, Eitan Porat, Or Ordentlich, Yury Polyanskiy
ICML 2025 ·LLMLatticeMatrix Products· Paper · Scholar
Uses nested lattice quantization for matrix products and LLMs. -
Learning Grouped Lattice Vector Quantizers for Low-Bit Large Language Models
Xi Zhang, Xiaolin Wu, Jiamang Wang, Weisi Lin
NeurIPS 2025 ·LLMGrouped Vector QuantizationLattice· Paper · Scholar
Learns grouped lattice vector quantizers for low-bit LLM representation. -
AnyBCQ: Hardware Efficient Flexible Binary-Coded Quantization for Multi-Precision LLMs
Gunho Park, Jeongin Bae, Beomseok Kwon, Byeongwook Kim, Se Jung Kwon, Dongsoo Lee
ICLR 2026 ·LLMBinary-CodedMixed PrecisionHardware· Paper · Code · Scholar
Develops flexible binary-coded quantization for hardware-efficient multi-precision LLMs. -
TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate
Amir Zandieh, Majid Daliri, Majid Hadian, Vahab Mirrokni
ICLR 2026 ·Vector QuantizationOnlineDistortion· Paper · Scholar
Studies online vector quantization with near-optimal distortion rate.


KV Cache Quantization
These methods compress inference-time key and value tensors; their bit widths are separate from model weight precision.
-
KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache
Zirui Liu, Jiayi Yuan, Hongye Jin, Shaochen Zhong, Zhaozhuo Xu, Vladimir Braverman, Beidi Chen, Xia Hu
ICML 2024 ·LLMKV Cache2-Bit· Paper · Code · Scholar
Uses asymmetric, tuning-free 2-bit quantization to compress key and value caches. -
KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization
Coleman Hooper, Sehoon Kim, Hiva Mohammadzadeh, Michael Mahoney, Sophia Shao, Kurt Keutzer, Amir Gholami
NeurIPS 2024 ·LLMKV CacheLong Context· Paper · Code · Scholar
Targets long-context inference by reducing the memory occupied by the KV cache. -
ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification
Yefei He, Luoming Zhang, Weijia Wu, Jing Liu, Hong Zhou, Bohan Zhuang
NeurIPS 2024 ·LLMKV CacheSalient Tokens· Paper · Code · Scholar
Uses salient-token identification to guide accurate and efficient cache quantization. -
PM-KVQ: Progressive Mixed-precision KV Cache Quantization for Long-CoT LLMs
Tengxuan Liu, Shiyao Li, Jiayi Yang, Tianchen Zhao, Feng Zhou, Xiaohui Song, Guohao Dai, Shengen Yan, Huazhong Yang, Yu Wang
ICLR 2026 ·LLMKV CacheMixed Precision· Paper · Code · Scholar
Progressively quantizes KV caches with mixed precision for long chain-of-thought inference.


Diffusion and Generative Model Quantization
Early diffusion PTQ addresses denoising-step sensitivity; later work extends to diffusion transformers, low-rank outlier handling and video generation.
-
Post-training Quantization on Diffusion Models
Yuzhang Shang, Zhihang Yuan, Bin Xie, Bingzhe Wu, Yan Yan
CVPR 2023 ·DiffusionPTQ· Paper · Code · Scholar
Adapts post-training quantization to diffusion model inference. -
Q-diffusion: Quantizing Diffusion Models
Xiuyu Li, Yijiang Liu, Long Lian, Huanrui Yang, Zhen Dong, Daniel Kang, Shanghang Zhang, Kurt Keutzer
ICCV 2023 ·DiffusionPTQ· Paper · Code · Scholar
Quantizes diffusion models to reduce the cost of iterative generation. -
PTQD: Accurate Post-Training Quantization for Diffusion Models
Yefei He, Luping Liu, Jing Liu, Weijia Wu, Hong Zhou, Bohan Zhuang
NeurIPS 2023 ·DiffusionPTQError Handling· Paper · Code · Scholar
Targets accurate diffusion generation through post-training quantization error handling. -
ViDiT-Q: Efficient and Accurate Quantization of Diffusion Transformers for Image and Video Generation
Tianchen Zhao, Tongcheng Fang, Haofeng Huang, Rui Wan, Widyadewi Soedarmadji, Enshu Liu, Shiyao Li, Zinan Lin, Guohao Dai, Shengen Yan, Huazhong Yang, Xuefei Ning, Yu Wang
ICLR 2025 ·Diffusion TransformerImage + VideoLow-Bit· Paper · Code · Scholar
Quantizes diffusion transformers for both image and video generation. -
SVDQuant: Absorbing Outliers by Low-Rank Component for 4-Bit Diffusion Models
Muyang Li, Yujun Lin, Zhekai Zhang, Tianle Cai, Xiuyu Li, Junxian Guo, Enze Xie, Chenlin Meng, Jun-Yan Zhu, Song Han
ICLR 2025 ·Diffusion4-BitLow-Rank· Paper · Code · Scholar
Absorbs outliers into a low-rank component to support 4-bit diffusion models. -
BinaryDM: Accurate Weight Binarization for Efficient Diffusion Models
Xingyu Zheng, Xianglong Liu, Haotong Qin, Xudong Ma, Mingyuan Zhang, Haojie Hao, Jiakai Wang, Zixiang Zhao, Jinyang Guo, Michele Magno
ICLR 2025 ·DiffusionBinary Weights· Paper · Code · Scholar
Binarizes diffusion model weights for efficient generation. -
Q-VDiT: Towards Accurate Quantization and Distillation of Video-Generation Diffusion Transformers
Weilun Feng, Chuanguang Yang, Haotong Qin, Xiangqi Li, Yu Wang, Zhulin An, Libo Huang, Boyu Diao, Zixiang Zhao, Yongjun Xu, Michele Magno
ICML 2025 ·Video DiffusionQuantizationDistillation· Paper · Code · Scholar
Combines quantization and distillation for video-generation diffusion transformers. -
S²Q-VDiT: Accurate Quantized Video Diffusion Transformer with Salient Data and Sparse Token Distillation
Weilun Feng, Haotong Qin, Chuanguang Yang, Xiangqi Li, Han Yang, Yuqi Li, Zhulin An, Libo Huang, Michele Magno, Yongjun Xu
NeurIPS 2025 ·Video DiffusionQuantizationDistillation· Paper · Code · Scholar
Uses salient data and sparse-token distillation to improve quantized video diffusion transformers. -
QuantSparse: Comprehensively Compressing Video Diffusion Transformer with Model Quantization and Attention Sparsification
Weilun Feng, Chuanguang Yang, Haotong Qin, Mingqiang Wu, Yuqi Li, Xiangqi Li, Zhulin An, Libo Huang, Yulun Zhang, Michele Magno, Yongjun Xu
ICLR 2026 ·Video DiffusionQuantizationAttention Sparsity· Paper · Code · Scholar
Combines model quantization and attention sparsification to compress video diffusion transformers.


Multimodal and State Space Models
Vision-language models and selective state space models introduce quantization sensitivities beyond those of language-only transformers.
-
Q-VLM: Post-training Quantization for Large Vision-Language Models
Changyuan Wang, Ziwei Wang, Xiuwei Xu, Yansong Tang, Jie Zhou, Jiwen Lu
NeurIPS 2024 ·VLMPTQCross-Layer Dependency· Paper · Code · Scholar
Uses cross-layer dependencies to guide block partitioning and quantization of vision-language models. -
Quamba2: A Robust and Scalable Post-training Quantization Framework for Selective State Space Models
Hung-Yueh Chiang, Chi-Chih Chang, Natalia Frumkin, Kai-Chiang Wu, Mohamed S. Abdelfattah, Diana Marculescu
ICML 2025 ·MambaState Space ModelsPTQW4A8 / W8A8· Paper · Code · Scholar
Uses channel clustering and state-group quantization to accommodate the sensitivity of Mamba’s selective state-space computations.


Vision, Edge and Hardware
Vision methods and deployment systems connect quantizer design to integer kernels, memory movement and hardware costs.
-
FINN: A Framework for Fast, Scalable Binarized Neural Network Inference
Yaman Umuroglu, Nicholas J. Fraser, Giulio Gambardella, Michaela Blott, Philip Leong, Magnus Jahre, Kees Vissers
FPGA 2017 ·Binary NetworksFPGAInference· Paper · Code · Scholar
Provides a framework for fast, scalable binarized neural network inference on FPGA hardware. -
HAQ: Hardware-Aware Automated Quantization with Mixed Precision
Kuan Wang, Zhijian Liu, Yujun Lin, Ji Lin, Song Han
CVPR 2019 ·CNNMixed PrecisionHardware-Aware· Paper · Code · Scholar
Automates mixed-precision quantization with hardware deployment costs in view. -
BiPointNet: Binary Neural Network for Point Clouds
Haotong Qin, Zhongang Cai, Mingyuan Zhang, Yifu Ding, Haiyu Zhao, Shuai Yi, Xianglong Liu, Hao Su
ICLR 2021 ·Point CloudsBinaryQAT1-Bit· Paper · Code · Scholar
Uses entropy-maximizing aggregation and layer-wise scale recovery to address feature homogenization and scale distortion in binary point-cloud networks. -
PTQ4ViT: Post-Training Quantization for Vision Transformers with Twin Uniform Quantization
Zhihang Yuan, Chenhao Xue, Yiqi Chen, Qiang Wu, Guangyu Sun
ECCV 2022 ·Vision TransformerPTQ· Paper · Code · Scholar
Uses twin uniform quantization to support post-training compression of vision transformers. -
QuantSR: Accurate Low-bit Quantization for Efficient Image Super-Resolution
Haotong Qin, Yulun Zhang, Yifu Ding, Yifan Liu, Xianglong Liu, Martin Danelljan, Fisher Yu
NeurIPS 2023 ·Super-ResolutionQAT2–4 Bit· Paper · Code · Scholar
Combines a redistribution-driven learnable quantizer with a depth-dynamic architecture for accurate low-bit image super-resolution. -
LUT-GEMM: Quantized Matrix Multiplication based on LUTs for Efficient Inference in Large-Scale Generative Language Models
Gunho Park, Baeseong Park, Minsub Kim, Sungjae Lee, Jeonghoon Kim, Beomseok Kwon, Se Jung Kwon, Byeongwook Kim, Youngjoo Lee, Dongsoo Lee
ICLR 2024 ·LLMQuantized Matrix MultiplicationLookup Tables· Paper · Scholar
Uses lookup tables for efficient quantized matrix multiplication in generative language models. -
Quant-LLM: Accelerating the Serving of Large Language Models via FP6-Centric Algorithm-System Co-Design on Modern GPUs
Haojun Xia, Zhen Zheng, Xiaoxia Wu, Shiyang Chen, Zhewei Yao, Stephen Youn, Arash Bakhtiari, Michael Wyatt, Donglin Zhuang, Zhongzhu Zhou, Olatunji Ruwase, Yuxiong He, Shuaiwen Leon Song
USENIX ATC 2024 ·LLMFP6GPU Kernels· Paper · Code · Scholar
Uses TC-FPx kernels to support non-power-of-two weight formats efficiently on GPUs; the codebase is also known as FP6-LLM. -
QServe: W4A8KV4 Quantization and System Co-design for Efficient LLM Serving
Yujun Lin, Haotian Tang, Shang Yang, Zhekai Zhang, Guangxuan Xiao, Chuang Gan, Song Han
MLSys 2025 ·LLMW4A8KV4GPU Serving· Paper · Code · Scholar
Co-designs progressive quantization, attention and GPU kernels to turn reduced precision into serving throughput.


Floating-Point and Microscaling Formats
Low-bit floating-point and shared-scale formats complement integer quantization. Format design and model calibration are separate choices.
-
FP8 Formats for Deep Learning
Paulius Micikevicius, Dusan Stosic, Neil Burgess, Marius Cornea, Pradeep Dubey, Richard Grisenthwaite, Sangwon Ha, Alexander Heinecke, Patrick Judd, John Kamalu, Naveen Mellempudi, Stuart Oberman, Mohammad Shoeybi, Michael Siu, Hao Wu
arXiv 2022 ·FP8E4M3 / E5M2Training + Inference· Paper · Scholar
Defines complementary FP8 encodings and evaluates their use in neural network training and inference. -
Microscaling Data Formats for Deep Learning
Bita Darvish Rouhani, Ritchie Zhao, Ankit More, Mathew Hall, Alireza Khodamoradi, Summer Deng, Dhruv Choudhary, Marius Cornea, Eric Dellinger, Kristof Denolf, Stosic Dusan, Venmugil Elango, Maximilian Golub, Alexander Heinecke, Phil James-Roxby, Dharmesh Jani, Gaurav Kolhe, Martin Langhammer, Ada Li, Levi Melnick, Maral Mesmakhosroshahi, Andres Rodriguez, Michael Schulte, Rasoul Shafipour, Lei Shao, Michael Siu, Pradeep Dubey, Paulius Micikevicius, Maxim Naumov, Colin Verrilli, Ralph Wittig, Doug Burger, Eric Chung
arXiv 2023 ·MX FormatsBlock ScalingTraining + Inference· Paper · Code · Scholar
Combines shared block scales with narrow element formats to balance numerical range and hardware efficiency. -
LLM-FP4: 4-Bit Floating-Point Quantized Transformers
Shih-yang Liu, Zechun Liu, Xijie Huang, Pingcheng Dong, Kwang-Ting Cheng
EMNLP 2023 ·LLMPTQFP4· Paper · Code · Scholar
Searches exponent configurations and quantization parameters to handle weight and activation range differences in 4-bit floating point.


Low-Precision Training and States
Quantization can reduce saved activations, optimizer states, gradient communication or training arithmetic; each targets a different part of the training cost.
-
QSGD: Communication-Efficient SGD via Gradient Quantization and Encoding
Dan Alistarh, Demjan Grubic, Jerry Li, Ryota Tomioka, Milan Vojnovic
NeurIPS 2017 ·TrainingGradientsCommunication· Paper · Scholar
Uses randomized gradient quantization with convergence guarantees to trade communication bandwidth against estimator variance. -
ActNN: Reducing Training Memory Footprint via 2-Bit Activation Compressed Training
Jianfei Chen, Lianmin Zheng, Zhewei Yao, Dequan Wang, Ion Stoica, Michael Mahoney, Joseph Gonzalez
ICML 2021 ·TrainingActivations2-Bit· Paper · Code · Scholar
Compresses saved activations to reduce the memory footprint of neural network training. -
8-bit Optimizers via Block-wise Quantization
Tim Dettmers, Mike Lewis, Sam Shleifer, Luke Zettlemoyer
ICLR 2022 ·TrainingOptimizer States8-Bit· Paper · Code · Scholar
Uses block-wise quantization to reduce optimizer-state memory. -
SDP4Bit: Toward 4-bit Communication Quantization in Sharded Data Parallelism for LLM Training
Jinda Jia, Cong Xie, Hanlin Lu, Daoce Wang, Hao Feng, Chengming Zhang, Baixi Sun, Haibin Lin, Zhi Zhang, Xin Liu, Dingwen Tao
NeurIPS 2024 ·LLM TrainingCommunication4-Bit· Paper · Code · Scholar
Targets 4-bit communication quantization in sharded data-parallel LLM training. -
Optimizing Large Language Model Training Using FP4 Quantization
Ruizhe Wang, Yeyun Gong, Xiao Liu, Guoshuai Zhao, Ziyue Yang, Baining Guo, Zhengjun Zha, Peng Cheng
ICML 2025 ·LLM TrainingFP4Gradient Estimation· Paper · Scholar
Combines differentiable quantization estimation with outlier handling to stabilize FP4 LLM training.


Benchmarks
Choose by evaluation scope: deployment reproducibility, binary networks, LLM capabilities or robustness. Expand a resource below for authors, figures and citation details.
| Resource | What it covers |
|---|---|
| MQBench: Towards Reproducible and Deployable Model Quantization Benchmark NeurIPS 2021 Datasets and Benchmarks Code · Scholar  | QAT + deployment Compares quantization algorithms under reproducible settings and hardware backend constraints. |
| BiBench: Benchmarking and Analyzing Network Binarization ICML 2023 Code · Scholar  | Binary networks Compares binarization methods across tasks, architectures and deployment settings. |
| Evaluating Quantized Large Language Models ICML 2024 Code · Scholar  | Weights, activations + KV cache Evaluates 11 model families on basic NLP, emergent abilities, trustworthiness, dialogue and long-context tasks. |
| LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit EMNLP 2024 Industry Track Code · Scholar  | LLM toolkit Compares calibration data, method pipelines and quantization configurations; the toolkit is now LightCompress. |
| An empirical study of LLaMA3 quantization: from LLMs to MLLMs Visual Intelligence 2024 Code · Scholar  | LLMs + multimodal Examines low-bit behavior across LLaMA3 language and multimodal models. |
| An Empirical Study of Qwen3 Quantization Visual Intelligence 2026 Code · Scholar  | Dense + MoE LLMs Studies quantization across Qwen3 model sizes, architectures and reasoning settings. |
| RobustMQ: Benchmarking Robustness of Quantized Models Visual Intelligence 2023 Scholar | Model robustness Tests quantized models beyond clean accuracy, including robustness under input perturbations. |
MQBench · Authors and BibTeX
Yuhang Li, Mingzhu Shen, Jian Ma, Yan Ren, Mingxin Zhao, Qi Zhang, Ruihao Gong, Fengwei Yu, Junjie Yan
@inproceedings{li2021mqbench,
  title={MQBench: Towards Reproducible and Deployable Model Quantization Benchmark},
  author={Li, Yuhang and Shen, Mingzhu and Ma, Jian and Ren, Yan and Zhao, Mingxin and Zhang, Qi and Gong, Ruihao and Yu, Fengwei and Yan, Junjie},
  booktitle={NeurIPS Datasets and Benchmarks},
  year={2021}
}
BiBench · Authors, overview and BibTeX
Haotong Qin, Mingyuan Zhang, Yifu Ding, Aoyu Li, Zhongang Cai, Ziwei Liu, Fisher Yu, Xianglong Liu
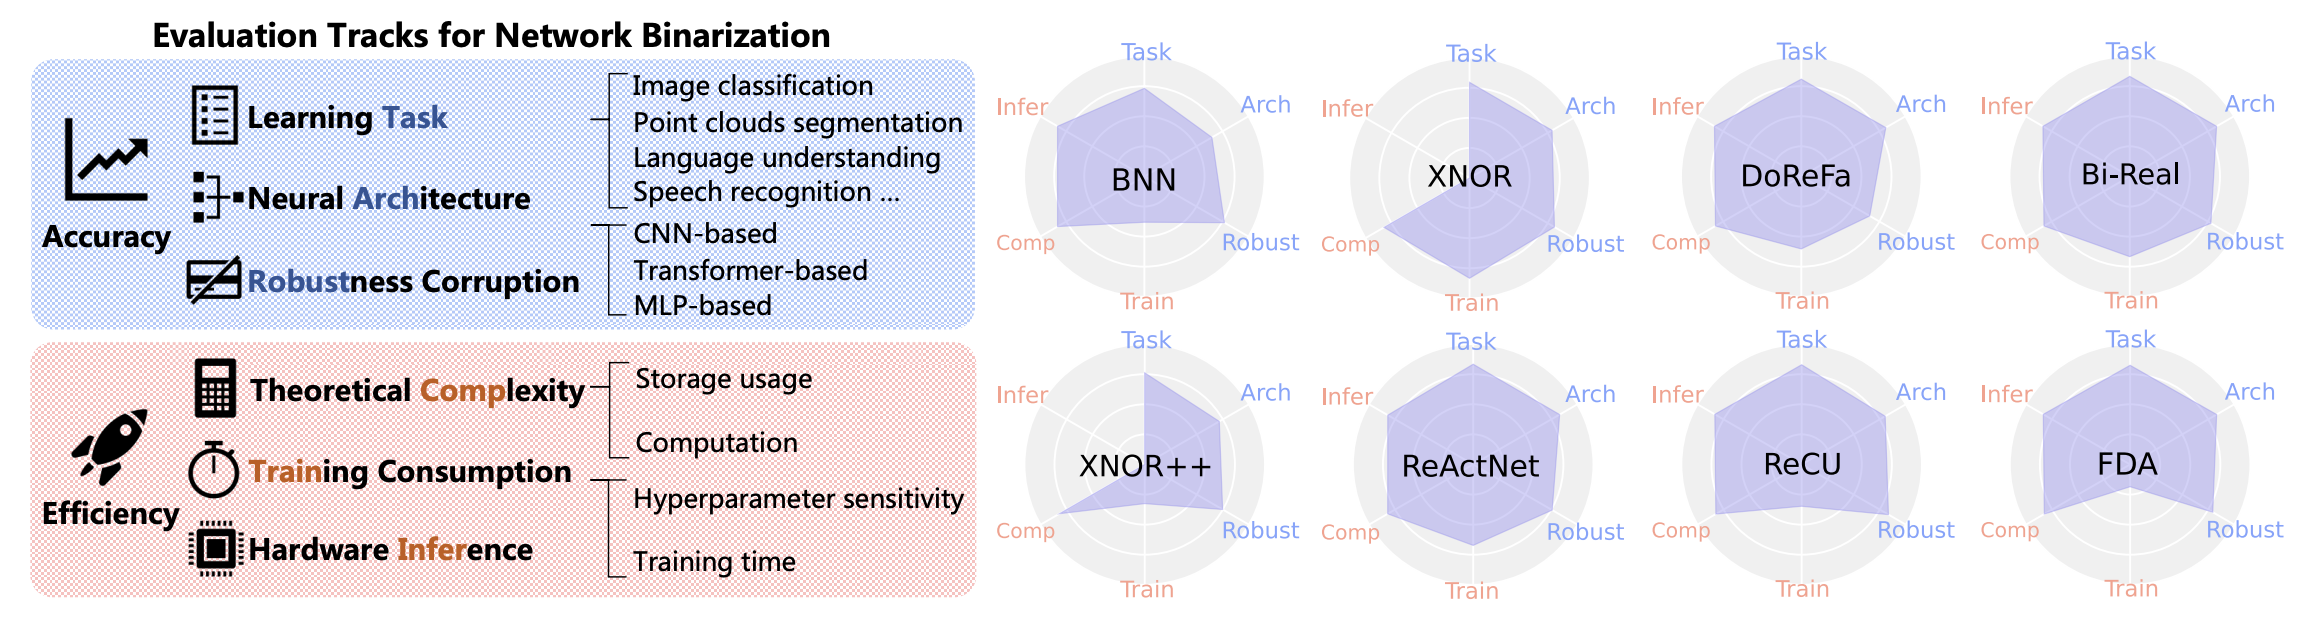
@inproceedings{qin2023bibench,
  title={BiBench: Benchmarking and Analyzing Network Binarization},
  author={Qin, Haotong and Zhang, Mingyuan and Ding, Yifu and Li, Aoyu and Cai, Zhongang and Liu, Ziwei and Yu, Fisher and Liu, Xianglong},
  booktitle={International Conference on Machine Learning (ICML)},
  year={2023}
}
QLLM-Eval · Authors and BibTeX
Shiyao Li, Xuefei Ning, Luning Wang, Tengxuan Liu, Xiangsheng Shi, Shengen Yan, Guohao Dai, Huazhong Yang, Yu Wang
@inproceedings{li2024evaluating,
  title={Evaluating Quantized Large Language Models},
  author={Li, Shiyao and Ning, Xuefei and Wang, Luning and Liu, Tengxuan and Shi, Xiangsheng and Yan, Shengen and Dai, Guohao and Yang, Huazhong and Wang, Yu},
  booktitle={International Conference on Machine Learning},
  year={2024},
  url={https://proceedings.mlr.press/v235/li24bb.html}
}
LLMC · Authors, overview and BibTeX
Ruihao Gong, Yang Yong, Shiqiao Gu, Yushi Huang, Chengtao Lv, Yunchen Zhang, Dacheng Tao, Xianglong Liu
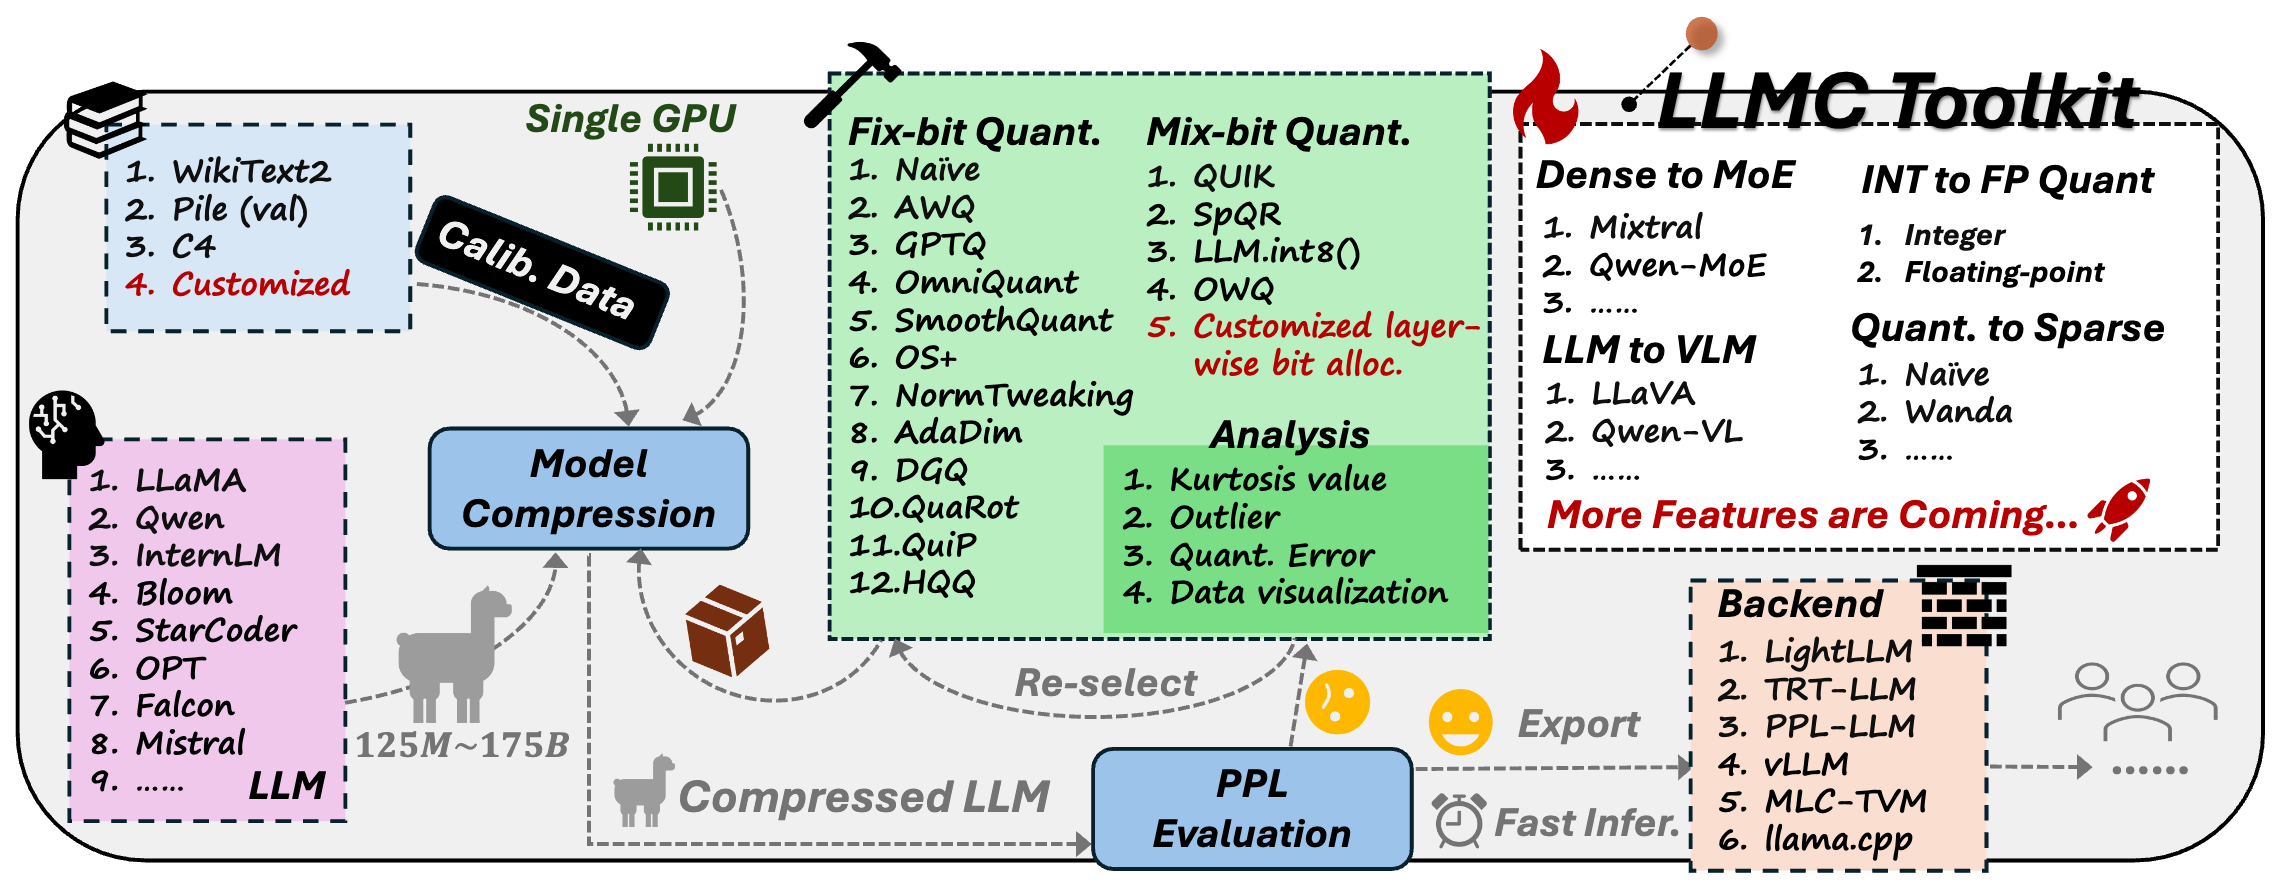
@inproceedings{gong2024llmc,
  title={Llmc: Benchmarking large language model quantization with a versatile compression toolkit},
  author={Gong, Ruihao and Yong, Yang and Gu, Shiqiao and Huang, Yushi and Lv, Chengtao and Zhang, Yunchen and Tao, Dacheng and Liu, Xianglong},
  booktitle={Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing: Industry Track},
  pages={132--152},
  year={2024}
}
LLaMA3 study · Authors, overview and BibTeX
Wei Huang, Xingyu Zheng, Xudong Ma, Haotong Qin, Chengtao Lv, Hong Chen, Jie Luo, Xiaojuan Qi, Xianglong Liu, Michele Magno
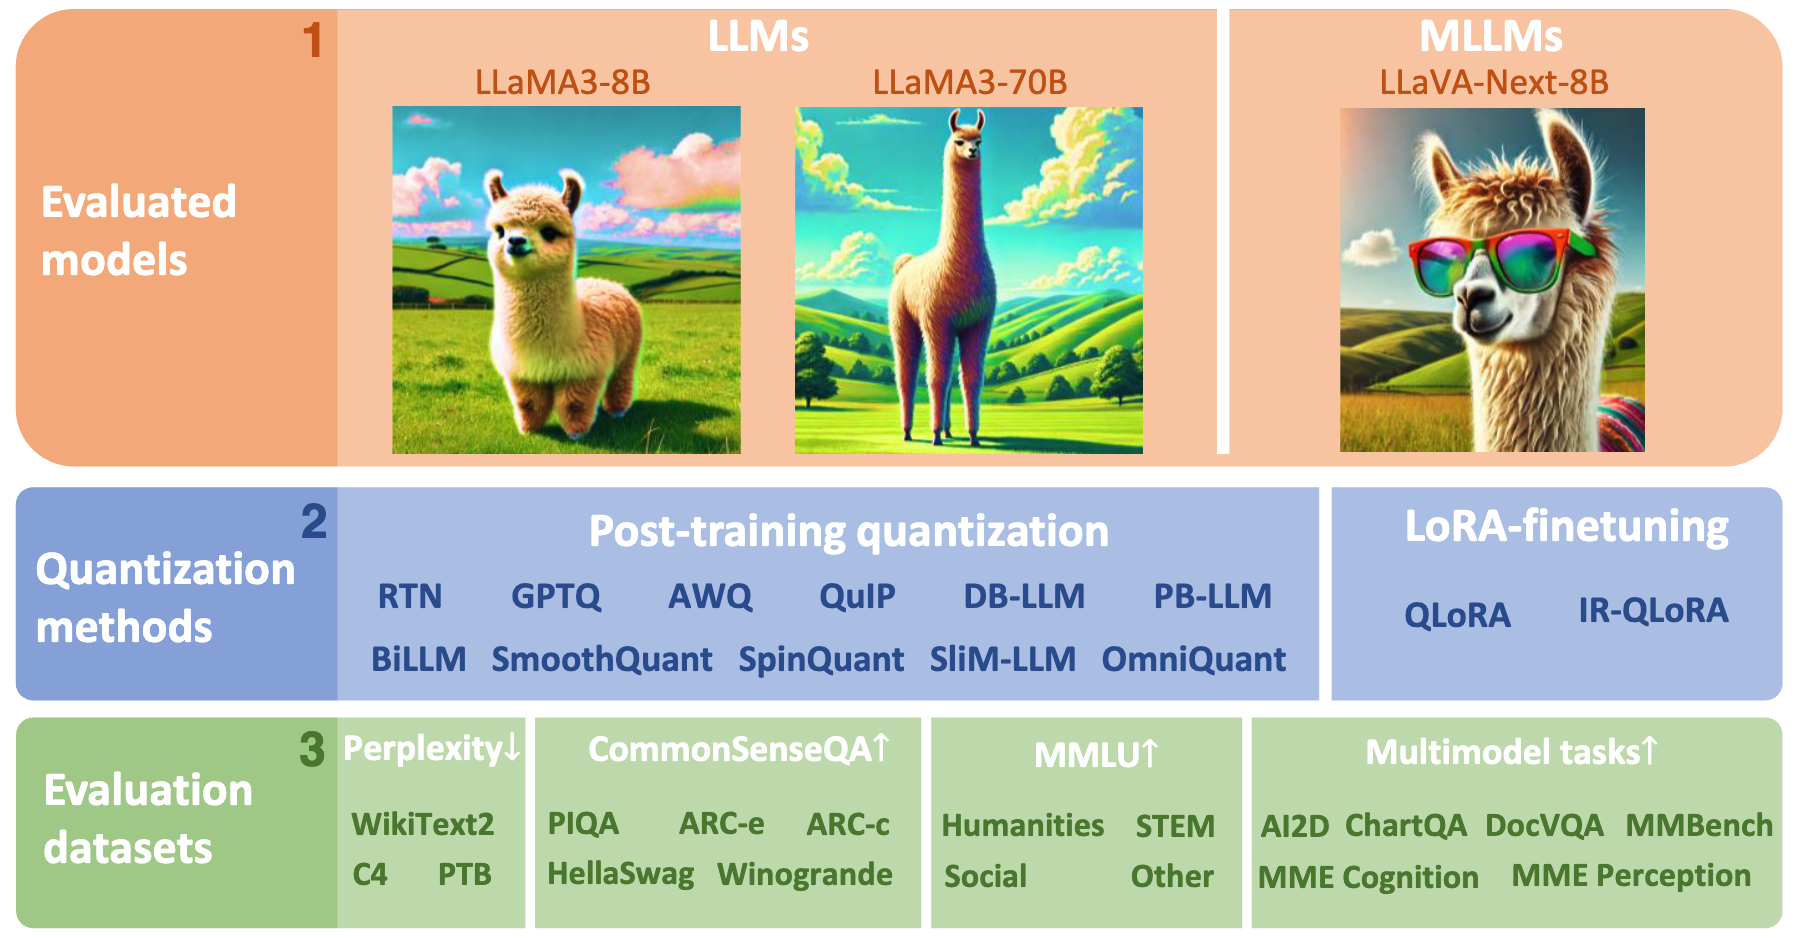
@article{huang2024empirical,
  title={An empirical study of llama3 quantization: From llms to mllms},
  author={Huang, Wei and Zheng, Xingyu and Ma, Xudong and Qin, Haotong and Lv, Chengtao and Chen, Hong and Luo, Jie and Qi, Xiaojuan and Liu, Xianglong and Magno, Michele},
  journal={Visual Intelligence},
  volume={2},
  number={1},
  pages={36},
  year={2024},
  publisher={Springer}
}
Qwen3 study · Authors, overview and BibTeX
Xingyu Zheng, Yuye Li, Haoran Chu, Yue Feng, Xudong Ma, Zining Wang, Jie Luo, Jinyang Guo, Haotong Qin, Michele Magno, Xianglong Liu
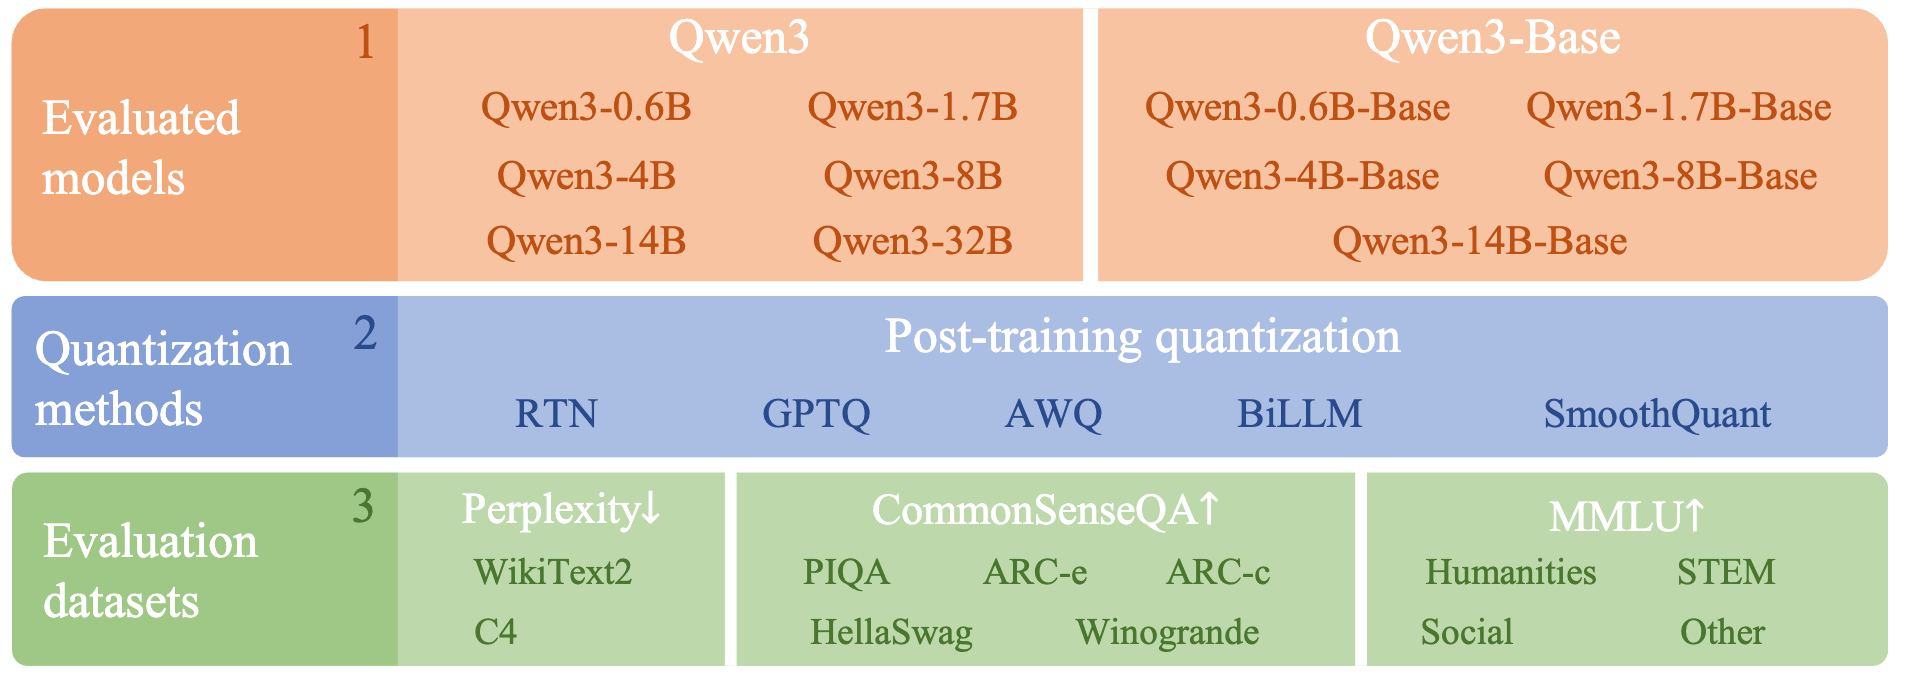
@article{zheng2026empirical,
  title={An empirical study of Qwen3 quantization},
  author={Zheng, Xingyu and Li, Yuye and Chu, Haoran and Feng, Yue and Ma, Xudong and Wang, Zining and Luo, Jie and Guo, Jinyang and Qin, Haotong and Magno, Michele and Liu, Xianglong},
  journal={Visual Intelligence},
  volume={4},
  pages={11},
  year={2026},
  doi={10.1007/s44267-026-00114-4}
}
RobustMQ · Authors, overview and BibTeX
Yisong Xiao, Aishan Liu, Tianyuan Zhang, Haotong Qin, Jinyang Guo, Xianglong Liu
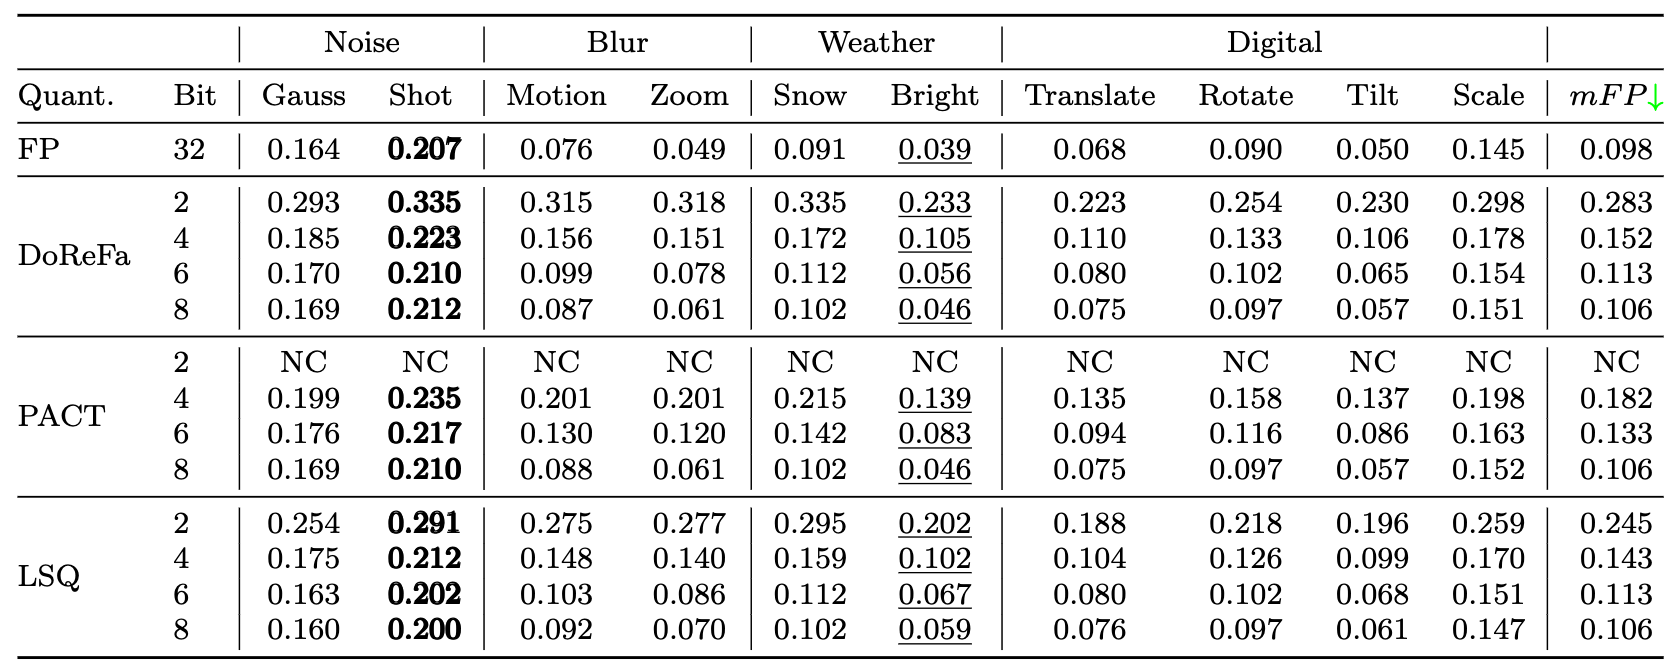
@article{xiao2023robustmq,
  title={Robustmq: benchmarking robustness of quantized models},
  author={Xiao, Yisong and Liu, Aishan and Zhang, Tianyuan and Qin, Haotong and Guo, Jinyang and Liu, Xianglong},
  journal={Visual Intelligence},
  volume={1},
  number={1},
  pages={30},
  year={2023},
  publisher={Springer}
}
Survey Papers
Start with the white paper for practical PTQ/QAT, then choose a survey for broader context or a specific model family. Figures and citation details are available below.
| Resource | What it covers |
|---|---|
| A White Paper on Neural Network Quantization arXiv 2021 Scholar | Practical PTQ + QAT Explains quantizer design, common failure modes and practical post-training and quantization-aware training workflows. |
| A Survey of Quantization Methods for Efficient Neural Network Inference arXiv 2021 Scholar | Foundations + taxonomy Reviews quantization design choices, mixed precision and the trade-offs between model accuracy and efficient inference. |
| Binary Neural Networks: A Survey Pattern Recognition 2020 Scholar | Binary networks Surveys binary network representations, training methods and applications. |
| A Survey of Low-bit Large Language Models: Basics, Systems, and Algorithms Neural Networks 2025 Scholar | LLM algorithms + systems Connects low-bit LLM algorithms with numerical formats and inference systems. |
| Low-bit Model Quantization for Deep Neural Networks: A Survey arXiv 2025 Scholar | Broad low-bit methods Maps low-bit quantization methods across neural network architectures and applications. |
Quantization white paper · Authors and BibTeX
Markus Nagel, Marios Fournarakis, Rana Ali Amjad, Yelysei Bondarenko, Mart van Baalen, Tijmen Blankevoort
@article{nagel2021white,
  title={A White Paper on Neural Network Quantization},
  author={Nagel, Markus and Fournarakis, Marios and Amjad, Rana Ali and Bondarenko, Yelysei and van Baalen, Mart and Blankevoort, Tijmen},
  journal={arXiv preprint arXiv:2106.08295},
  year={2021}
}
Quantization methods survey · Authors and BibTeX
Amir Gholami, Sehoon Kim, Zhen Dong, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer
@article{gholami2021survey,
  title={A Survey of Quantization Methods for Efficient Neural Network Inference},
  author={Gholami, Amir and Kim, Sehoon and Dong, Zhen and Yao, Zhewei and Mahoney, Michael W. and Keutzer, Kurt},
  journal={arXiv preprint arXiv:2103.13630},
  year={2021}
}
Binary networks survey · Authors, overview and BibTeX
Haotong Qin, Ruihao Gong, Xianglong Liu, Xiao Bai, Jingkuan Song, Nicu Sebe
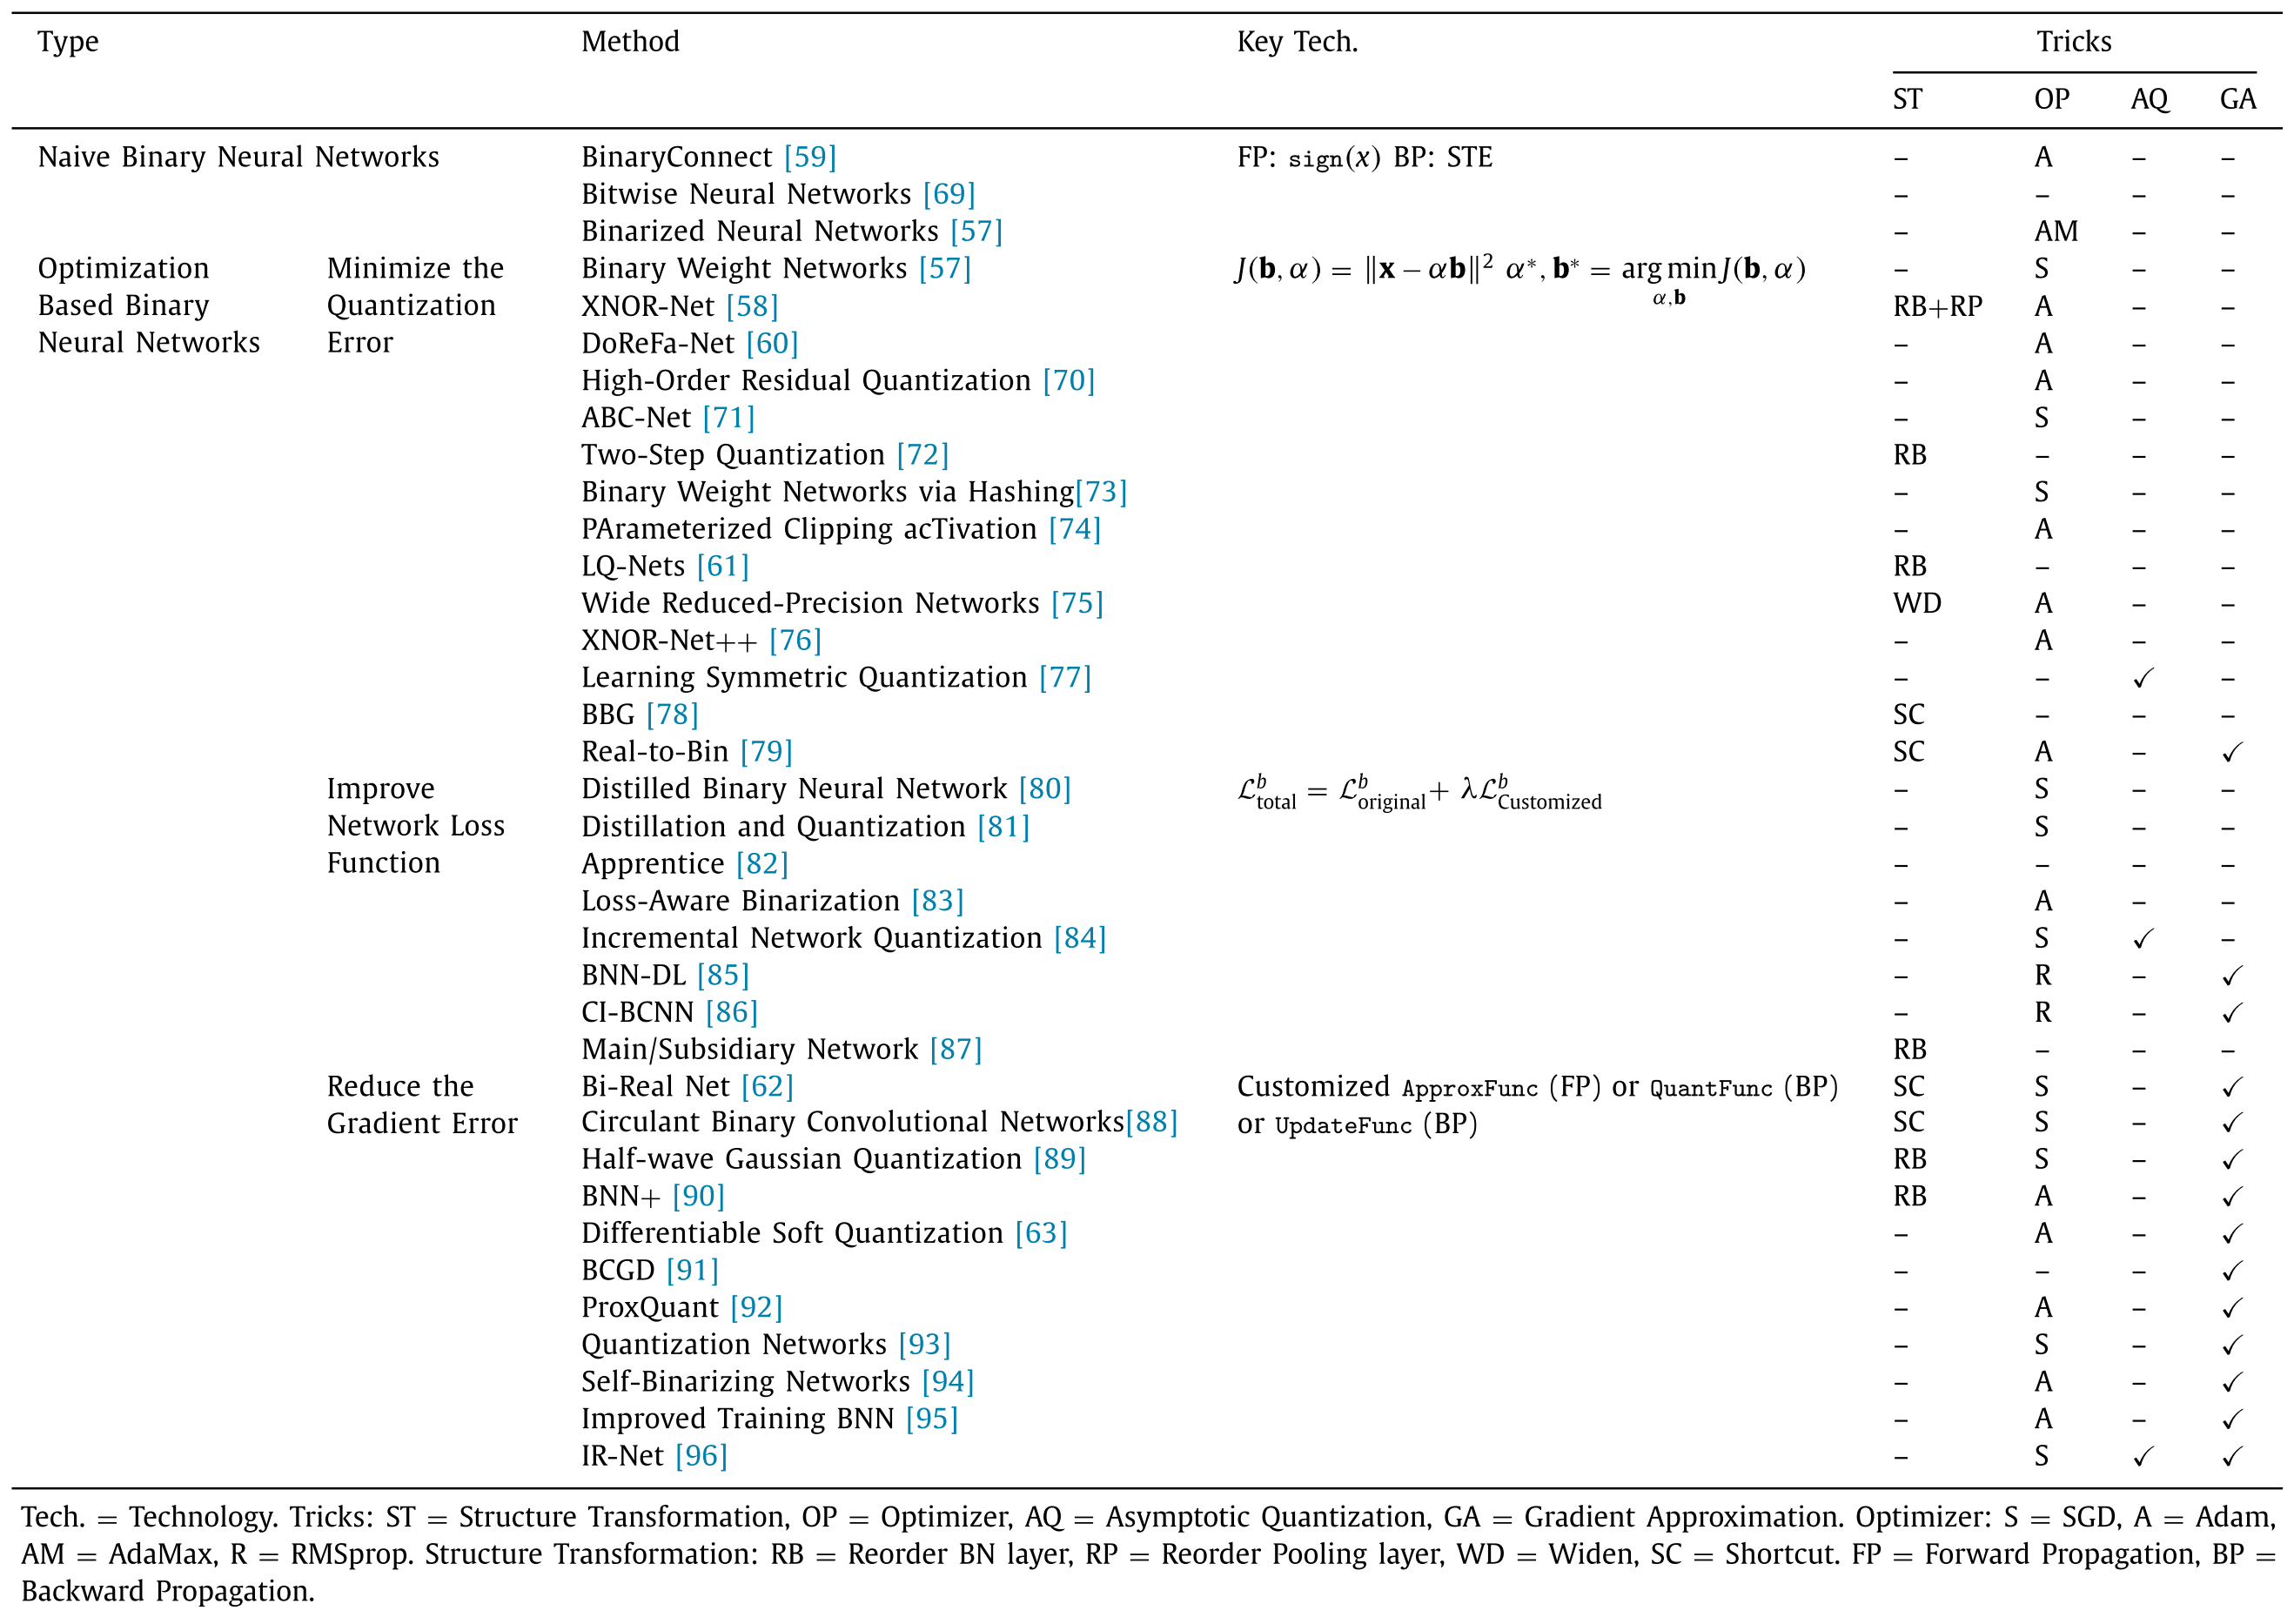
@article{Qin:pr20_bnn_survey,
    title = "Binary neural networks: A survey",
    author = "Haotong Qin and Ruihao Gong and Xianglong Liu and Xiao Bai and Jingkuan Song and Nicu Sebe",
    journal = "Pattern Recognition",
    volume = "105",
    pages = "107281",
    year = "2020"
}
Low-bit LLM survey · Authors, overview and BibTeX
Ruihao Gong, Yifu Ding, Zining Wang, Chengtao Lv, Xingyu Zheng, Jinyang Du, Yang Yong, Shiqiao Gu, Haotong Qin, Jinyang Guo, Dahua Lin, Michele Magno, Xianglong Liu
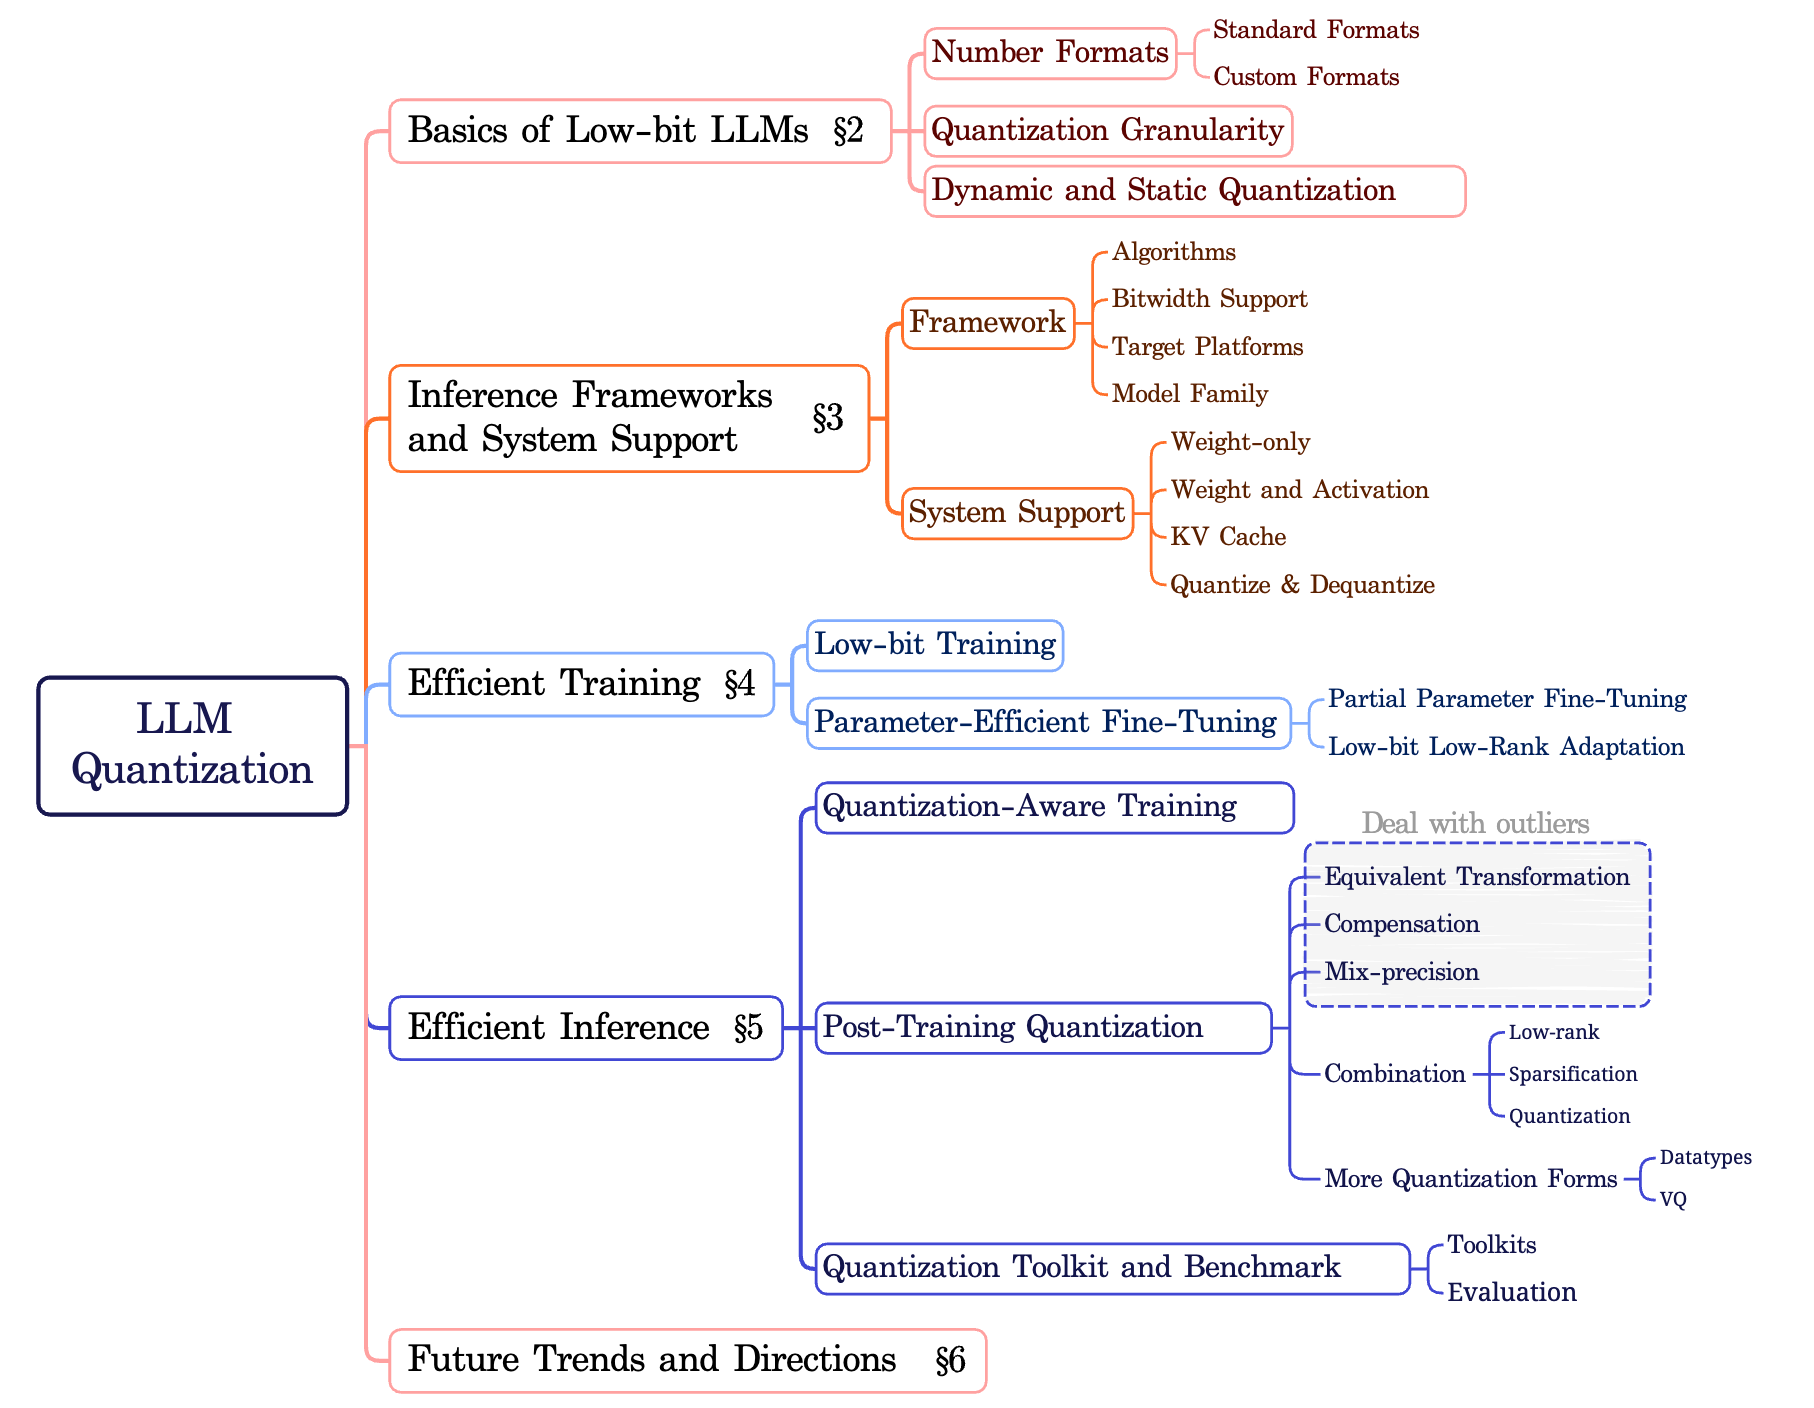
@article{gong2025survey,
  title={A survey of low-bit large language models: Basics, systems, and algorithms},
  author={Gong, Ruihao and Ding, Yifu and Wang, Zining and Lv, Chengtao and Zheng, Xingyu and Du, Jinyang and Yong, Yang and Gu, Shiqiao and Qin, Haotong and Guo, Jinyang and Lin, Dahua and Magno, Michele and Liu, Xianglong},
  journal={Neural Networks},
  pages={107856},
  year={2025}
}
Low-bit model survey · Authors, overview and BibTeX
Kai Liu, Qian Zheng, Kaiwen Tao, Zhiteng Li, Haotong Qin, Wenbo Li, Yong Guo, Xianglong Liu, Linghe Kong, Guihai Chen, Yulun Zhang, Xiaokang Yang
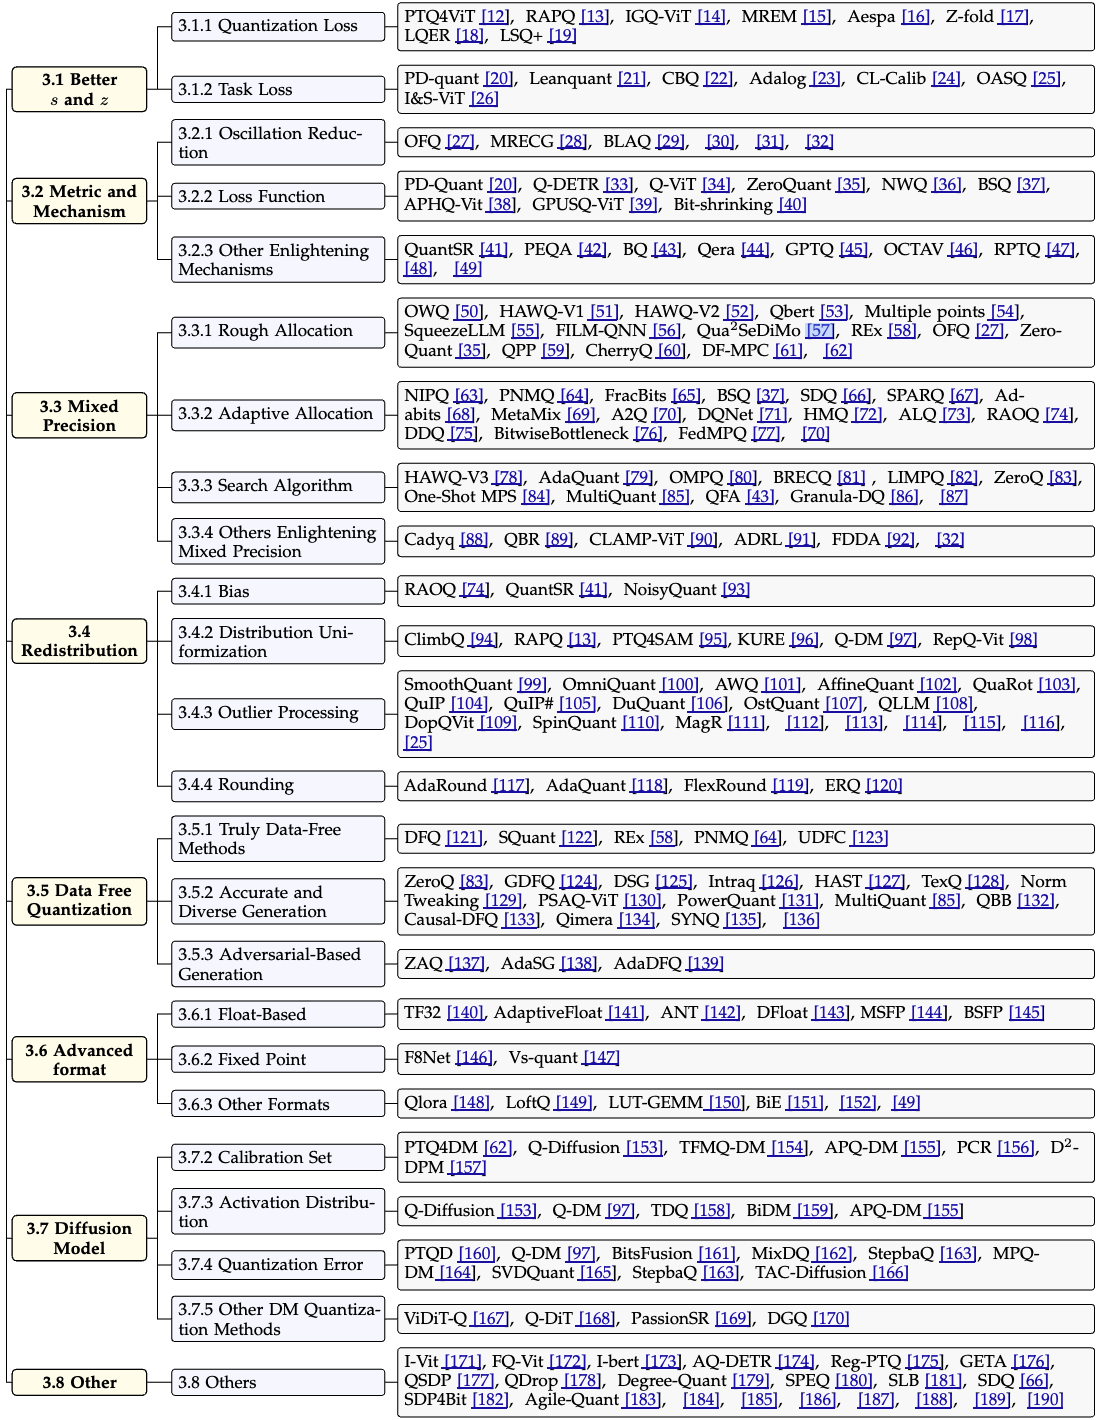
@article{liu2025low,
  title={Low-bit Model Quantization for Deep Neural Networks: A Survey},
  author={Liu, Kai and Zheng, Qian and Tao, Kaiwen and Li, Zhiteng and Qin, Haotong and Li, Wenbo and Guo, Yong and Liu, Xianglong and Kong, Linghe and Chen, Guihai and Zhang, Yulun and Yang, Xiaokang},
  journal={arXiv preprint arXiv:2505.05530},
  year={2025}
}
Papers by Year
All paper titles and links are kept in this README. Published work is grouped by venue year where verified; otherwise the recorded preprint year is used. Representative works, benchmarks and surveys also appear here for chronological browsing. Within each year, entries are grouped by conference or journal, with preprints at the end.
2026
- [AAAI] First-Order Error Matters: Accurate Compensation for Quantized Large Language Models [code]
- [AAAI] TR-DQ: Time-Rotation Diffusion Quantization
- [CVPR Findings] Q-MambaIR: Accurate Quantized Mamba for Efficient Image Restoration
- [EMNLP] All for 1-Bit: Towards Genuine 1-Bit Post-Training Quantization for LLMs [Scholar]
- [EMNLP] Colla-Q: Toward Collaborative Experts in MoE Quantization via Minimax Precision Balancing [code]
[Scholar]
- [ICCAD] Interface-Aware KV Cache Quantization for Dense On-Chip NVM in Long-Context LLM Decoding [Scholar]
- [ICLR] PT²-LLM: Post-Training Ternarization for Large Language Models [code]
- [ICLR] Quant-dLLM: Post-Training Extreme Low-Bit Quantization for Diffusion Large Language Models
- [ICLR] DVD-Quant: Data-free Video Diffusion Transformers Quantization
- [ICLR] Q&C: When Quantization Meets Cache in Efficient Generation
- [ICLR] Quantized Visual Geometry Grounded Transformer
- [ICLR] Post-Training Quantization for Video Matting
- [ICLR] QVGen: Pushing the Limit of Quantized Video Generative Models
- [ICLR] QuantSparse: Comprehensively Compressing Video Diffusion Transformer with Model Quantization and Attention Sparsification [code]
- [ICLR] TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate
- [ICLR] Optimal Brain Restoration for Joint Quantization and Sparsification of LLMs [code]
- [ICLR] AnyBCQ: Hardware Efficient Flexible Binary-Coded Quantization for Multi-Precision LLMs [code]
- [ICLR] Tequila: Deadzone-free Ternary Quantization for Large Language Models
- [ICLR] LogART: Pushing the Limit of Efficient Logarithmic Post-Training Quantization [code]
- [ICLR] ParoQuant: Pairwise Rotation Quantization for Efficient Reasoning LLM Inference [code]
- [ICLR] Improving Block-Wise LLM Quantization by 4-bit Generalized Normal Float Formats
- [ICLR] Channel-Aware Mixed-Precision Quantization for Efficient Long-Context Inference
- [ICLR] CodeQuant: Unified Clustering and Quantization for Enhanced Outlier Smoothing in Low-Precision Mixture-of-Experts
- [ICLR] QeRL: Beyond Efficiency - Quantization-enhanced Reinforcement Learning for LLMs [code]
- [ICLR] AutoQVLA: Not All Channels Are Equal in Vision-Language-Action Model's Quantization
- [ICLR] Achieving low-bit Muon through subspace preservation and grid quantization
- [ICLR] Shift-and-Sum Quantization for Visual Autoregressive Models
- [ICLR] Inlier-Centric Post-Training Quantization for Object Detection Models
- [ICLR] Efficient Quantization of Mixture-of-Experts with Theoretical Generalization Guarantees
- [ICLR] BBQ: Boosting Quantization Entropy with Bell Box Quantization
- [ICLR] Improving Block-Wise LLM Quantization by 4-bit Block-Wise Optimal Float (BOF4): Analysis and Variations [code]
- [ICLR] Learning under Quantization for High-Dimensional Linear Regression
- [ICLR] On-the-Fly Adaptation to Quantization: Configuration-Aware LoRA for Efficient Fine-Tuning of Quantized LLMs
- [ICLR] Bridging the Gap Between Promise and Performance for FP4 Quantization [code]
- [ICLR] KBVQ-MoE: KLT-guided SVD with Bias-Corrected Vector Quantization for MoE Large Language Models [code]
- [ICLR] UniQL: Unified Quantization and Low-rank Compression for Adaptive Edge LLMs [code]
- [ICLR] The Lattice Geometry of Neural Network Quantization: A Short Equivalence Proof of GPTQ and Babai's algorithm
- [ICLR] DPQuant: Efficient and Private Model Training via Dynamic Quantization Scheduling
- [ICLR] Towards Quantization-Aware Training for Ultra-Low-Bit Reasoning LLMs
- [ICLR] A Convergence Analysis of Adaptive Optimizers under Floating-point Quantization
- [ICLR] Training Dynamics Impact Post-Training Quantization Robustness [code]
- [ICLR] SSDi8: Accurate and Efficient 8-bit Quantization for State Space Duality
- [ICLR] The Geometry of LLM Quantization: GPTQ as Babai's Nearest Plane Algorithm
- [ICLR] PTQ4ARVG: Post-Training Quantization for AutoRegressive Visual Generation Models [code]
- [ICLR] QWHA: Quantization-Aware Walsh-Hadamard Adaptation for Parameter-Efficient Fine-Tuning on Large Language Models [code]
- [ICLR] Gradient-Aligned Calibration for Post-Training Quantization of Diffusion Models
- [ICLR] SERQ: Saliency-Aware Low-Rank Error Reconstruction for LLM Quantization
- [ICLR] Compute-Optimal Quantization-Aware Training
- [ICLR] PM-KVQ: Progressive Mixed-precision KV Cache Quantization for Long-CoT LLMs [code]
- [ICLR] Beyond Outliers: A Study of Optimizers Under Quantization
- [ICLR] Qronos: Correcting the Past by Shaping the Future... in Post-Training Quantization
- [ICLR] MicroMix: Efficient Mixed-Precision Quantization with Microscaling Formats for Large Language Models [code]
- [ICLR] TurboBoA: Faster and Exact Attention-aware Quantization without Backpropagation
- [ICLR] Beyond Uniformity: Sample and Frequency Meta Weighting for Post-Training Quantization of Diffusion Models
- [ICLR] Rethinking Residual Errors in Compensation-based LLM Quantization
- [ICLR] SPR²Q: Static Priority-based Rectifier Routing Quantization for Image Super-Resolution [code]
- [ICLR] STaMP: Sequence Transformation and Mixed Precision for Low-Precision Activation Quantization
- [Visual Intelligence] An Empirical Study of Qwen3 Quantization [code]
[arXiv]
- [arXiv] EdgeRazor: A Lightweight Framework for Large Language Models via Mixed-Precision Quantization-Aware Distillation [code]
- [arXiv] Sherry: Hardware-Efficient 1.25-Bit Ternary Quantization via Fine-grained Sparsification [code]
- [arXiv] D²Quant: Accurate Low-bit Post-Training Weight Quantization for LLMs
- [arXiv] QuantLRM: Quantization of Large Reasoning Models via Fine-Tuning Signals
- [arXiv] SliderQuant: Accurate Post-Training Quantization for LLMs
- [arXiv] What Makes Low-Bit Quantization-Aware Training Work for Reasoning LLMs? A Systematic Study
- [arXiv] OneComp: One-Line Revolution for Generative AI Model Compression [Code]


2025
- [AAAI] MPQ-DM: Mixed Precision Quantization for Extremely Low Bit Diffusion Models
- [AAAI] JAQ: Joint Efficient Architecture Design and Low-Bit Quantization
- [AAAI] OAC: Output-adaptive Calibration for Accurate Post-Training Quantization of LLMs
- [AAAI] Optimizing Quantized Diffusion Models via Distillation with Decay Timestep-Aware Loss
- [AAAI] Quantifiable Quantization Sensitivity of Diffusion Models
- [AAAI] TCAQ-DM: Timestep-Channel Adaptive Quantization for Diffusion Models
- [AAAI] Thinking in Granularity: Dynamic Quantization for Image Super-Resolution by Intriguing Multi-Granularity Clues [code]
- [AAAI] D2-DPM: Dual Denoising for Quantized Diffusion Probabilistic Models [code]
- [ACL] EfficientQAT: Efficient Quantization-Aware Training for Large Language Models [code]
- [ACL] L4Q: Parameter Efficient Quantization-Aware Fine-Tuning on Large Language Models
- [ACL] MoQAE: Mixed-Precision Quantization for Long-Context LLM Inference via Mixture of Quantization-Aware Experts
- [ACL] Outlier-Safe Pre-Training for Robust 4-Bit Quantization of Large Language Models
- [ACL] PTQ1.61: Push the Real Limit of Extremely Low-Bit Post-Training Quantization Methods for Large Language Models [code]
- [ACL] Unifying Uniform and Binary-coding Quantization for Accurate Compression of Large Language Models
- [ACL] “Give Me BF16 or Give Me Death”? Accuracy-Performance Trade-Offs in LLM Quantization
- [ACL Findings] Achieving Binary Weight and Activation for LLMs using Post-Training Quantization
- [ACM MM] DilateQuant: Accurate and Efficient Quantization-Aware Training for Diffusion Models via Weight Dilation
- [ACM MM] Learning Binarized Representations with Pseudo-positive Distillation
- [ACM MM] MQuant: Unleashing the Inference Potential of Multimodal Large Language Models with Post-Training Quantization
- [ACM MM] Pushing the Limit of Binarized Neural Network for Image Super Resolution with Smooth Information Transmission
- [ACM MM] Quantization Meets OOD: Generalizable Quantization-aware Training from a Flatness Perspective
- [CVPR] PassionSR: Post-Training Quantization with Adaptive Scale in One-Step Diffusion based Image Super-Resolution [code]
- [CVPR] Quantization without Tears
- [CVPR] APHQ-ViT: Post-Training Quantization with Average Perturbation Hessian Based Reconstruction for Vision Transformer [code]
- [EMNLP] AMQ: Enabling AutoML for Mixed-precision Weight-Only Quantization of Large Language Models
- [EMNLP] Does quantization affect models' performance on long-input and long-output tasks?
- [EMNLP Findings] KurTail: Kurtosis-based LLM Quantization
- [ICCV] Scheduling Weight Transitions for Quantization-Aware Training [code]
- [ICCV] Task-Specific Zero-shot Quantization-Aware Training for Object Detection [code]
- [ICCV] OuroMamba: A Data-Free Quantization Framework for Vision Mamba
- [ICCV] FedWSQ: Efficient Federated Learning with Weight Standardization and Distribution-Aware Non-Uniform Quantization [code]
- [ICCV] Semantic Alignment and Reinforcement for Data-Free Quantization of Vision Transformers [code]
- [ICCV] QuantCache: Adaptive Importance-Guided Quantization with Hierarchical Latent and Layer Caching for Video Generation [code]
- [ICCV] MixA-Q: Revisiting Activation Sparsity for Vision Transformers from a Mixed-Precision Quantization Perspective
- [ICCV] DMQ: Dissecting Outliers of Diffusion Models for Post-Training Quantization [code]
- [ICCV] AHCPTQ: Accurate and Hardware-Compatible Post-Training Quantization for Segment Anything Model
- [ICCV] MSQ: Memory-Efficient Bit Sparsification Quantization
- [ICCV] QuEST: Low-bit Diffusion Model Quantization via Efficient Selective Finetuning [code]
- [ICLR] ARB-LLM: Alternating Refined Binarizations for Large Language Models [code]
- [ICLR] BinaryDM: Accurate Weight Binarization for Efficient Diffusion Models [code]
- [ICLR] CBQ: Cross-Block Quantization for Large Language Models
- [ICLR] DGQ: Distribution-Aware Group Quantization for Text-to-Image Diffusion Models
- [ICLR] LeanQuant: Accurate and Scalable Large Language Model Quantization with Loss-error-aware Grid
- [ICLR] OSTQuant: Refining Large Language Model Quantization with Orthogonal and Scaling Transformations for Better Distribution Fitting [code]
- [ICLR] QERA: an Analytical Framework for Quantization Error Reconstruction [code]
- [ICLR] SpinQuant: LLM Quantization with Learned Rotations [code]
- [ICLR] SVDQuant: Absorbing Outliers by Low-Rank Component for 4-Bit Diffusion Models [code]
- [ICLR] ViDiT-Q: Efficient and Accurate Quantization of Diffusion Transformers for Image and Video Generation [code]
- [ICLR] SynQ: Accurate Zero-shot Quantization by Synthesis-aware Fine-tuning [code]
- [ICML] Q-VDiT: Towards Accurate Quantization and Distillation of Video-Generation Diffusion Transformers [code]
- [ICML] SliM-LLM: Salience-Driven Mixed-Precision Quantization for Large Language Models [code]
- [ICML] FlatQuant: Flatness Matters for LLM Quantization [code]
- [ICML] RoSTE: An Efficient Quantization-Aware Supervised Fine-Tuning Approach for Large Language Models [code]
- [ICML] GANQ: GPU-Adaptive Non-Uniform Quantization for Large Language Models
- [ICML] Modulated Diffusion: Accelerating Generative Modeling with Modulated Quantization [code]
- [ICML] GuidedQuant: Large Language Model Quantization via Exploiting End Loss Guidance [code]
- [ICML] ResQ: Mixed-Precision Quantization of Large Language Models with Low-Rank Residuals [code]
- [ICML] MxMoE: Mixed-precision Quantization for MoE with Accuracy and Performance Co-Design [code]
- [ICML] Learning from Loss Landscape: Generalizable Mixed-Precision Quantization via Adaptive Sharpness-Aware Gradient Aligning
- [ICML] PARQ: Piecewise-Affine Regularized Quantization [code]
- [ICML] Quamba2: A Robust and Scalable Post-training Quantization Framework for Selective State Space Models [code]
- [ICML] LRA-QViT: Integrating Low-Rank Approximation and Quantization for Robust and Efficient Vision Transformers
- [ICML] BoA: Attention-aware Post-training Quantization without Backpropagation
- [ICML] MoEQuant: Enhancing Quantization for Mixture-of-Experts Large Language Models via Expert-Balanced Sampling and Affinity Guidance [code]
- [ICML] NestQuant: nested lattice quantization for matrix products and LLMs
- [ICML] Q-resafe: Assessing Safety Risks and Quantization-aware Safety Patching for Quantized Large Language Models [code]
- [ICML] SLiM: One-shot Quantization and Sparsity with Low-rank Approximation for LLM Weight Compression [code]
- [ICML] QT-DoG: Quantization-Aware Training for Domain Generalization [code]
- [ICML] Matryoshka Quantization
- [ICML] Merge-Friendly Post-Training Quantization for Multi-Target Domain Adaptation [code]
- [ICML] Layer-wise Quantization for Quantized Optimistic Dual Averaging
- [ICML] Outlier-Aware Post-Training Quantization for Discrete Graph Diffusion Models
- [ICML] BlockDialect: Block-wise Fine-grained Mixed Format Quantization for Energy-Efficient LLM Inference
- [ICML] GPTAQ: Efficient Finetuning-Free Quantization with Asymmetric Calibration [code]
- [ICML] Optimizing Large Language Model Training Using FP4 Quantization
- [ICML] SKIM: Any-bit Quantization Pushing The Limits of Post-Training Quantization
- [ICML] SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization [code]
- [MLSys] QServe: W4A8KV4 Quantization and System Co-design for Efficient LLM Serving [code]
- [Neural Networks] A Survey of Low-bit Large Language Models: Basics, Systems, and Algorithms
- [NeurIPS] S²Q-VDiT: Accurate Quantized Video Diffusion Transformer with Salient Data and Sparse Token Distillation [code]
- [NeurIPS] DartQuant: Efficient Rotational Distribution Calibration for LLM Quantization [code]
- [NeurIPS] A Double Normalization Approach for Calibration-Free Low-Bit KV Cache Quantization
- [NeurIPS] Binary Quadratic Quantization: Beyond First-Order Quantization for Real-Valued Matrix Compression
- [NeurIPS] Learning Grouped Lattice Vector Quantizers for Low-Bit Large Language Models
- [NeurIPS] LittleBit: Ultra Low-Bit Quantization via Latent Factorization
- [NeurIPS] ParetoQ: Improving Scaling Laws in Extremely Low-bit LLM Quantization
- [NeurIPS] Q-Palette: Fractional-Bit Quantizers Toward Optimal Weight-Only Post-Training Quantization
- [NeurIPS] Wavelet-Enhanced High-Fidelity 1-Bit Quantization for LLMs
- [NeurIPS] Quantization Error Propagation: Revisiting Layer-Wise Post-Training Quantization [Code]
[arXiv]
- [NeurIPS] QBasicVSR: Temporal Awareness Adaptation Quantization for Video Super-Resolution
- [NeurIPS] Point4Bit: Post Training 4-bit Quantization for Point Cloud 3D Detection
- [NeurIPS] PMQ-VE: Progressive Multi-Frame Quantization for Video Enhancement [code]
- [NeurIPS] VETA-DiT: Variance-Equalized and Temporally Adaptive Quantization for Efficient 4-bit Diffusion Transformers
- [NeurIPS] LoTA-QAF: Lossless Ternary Adaptation for Quantization-Aware Fine-Tuning [code]
- [NeurIPS] Efficient Multi-bit Quantization Network Training via Weight Bias Correction and Bit-wise Coreset Sampling
- [NeurIPS] Efficient and Generalizable Mixed-Precision Quantization via Topological Entropy
- [NeurIPS] QSCA: Quantization with Self-Compensating Auxiliary for Monocular Depth Estimation
- [SIGMOD] Practical and Asymptotically Optimal Quantization of High-Dimensional Vectors in Euclidean Space for Approximate Nearest Neighbor Search [code]
- [TPAMI] BiVM: Accurate Binarized Neural Network for Efficient Video Matting
- [arXiv] BitNet b1.58 2B4T Technical Report [code]
[Models]
- [arXiv] Low-bit Model Quantization for Deep Neural Networks: A Survey




2024
- [AAAI] Agile-Quant: Activation-Guided Quantization for Faster Inference of LLMs on the Edge
- [AAAI] AQ-DETR: Low-Bit Quantized Detection Transformer with Auxiliary Queries
- [AAAI] Bi-ViT: Pushing the Limit of Vision Transformer Quantization
- [AAAI] Exploring Post-training Quantization in LLMs from Comprehensive Study to Low Rank Compensation
- [AAAI] Make RepVGG Greater Again: A Quantization-Aware Approach
- [AAAI] MetaMix: Meta-State Precision Searcher for Mixed-Precision Activation Quantization
- [AAAI] Norm Tweaking: High-Performance Low-Bit Quantization of Large Language Models
- [AAAI] OWQ: Outlier-Aware Weight Quantization for Efficient Fine-Tuning and Inference of Large Language Models
- [AAAI] PTMQ: Post-training Multi-Bit Quantization of Neural Networks
- [AAAI] Robustness-Guided Image Synthesis for Data-Free Quantization
- [AAAI] What Makes Quantization for Large Language Model Hard? An Empirical Study from the Lens of Perturbation
- [AAAI] One-Step Forward and Backtrack: Overcoming Zig-Zagging in Loss-Aware Quantization Training
- [ACL] Improving Conversational Abilities of Quantized Large Language Models via Direct Preference Alignment
- [ACL Findings] DB-LLM: Accurate Dual-Binarization for Efficient LLMs
- [ACL Findings] A Comprehensive Evaluation of Quantization Strategies for Large Language Models
- [ACL Findings] AFPQ: Asymmetric Floating Point Quantization for LLMs [code]
- [ACL Findings] LLM-QAT: Data-Free Quantization Aware Training for Large Language Models
- [ACM MM] Advancing Multimodal Large Language Models with Quantization-Aware Scale Learning Based on Warmup
- [CVPR] Data-Free Quantization via Pseudo-label Filtering
- [CVPR] Enhancing Post-training Quantization Calibration through Contrastive Learning
- [CVPR] Instance-Aware Group Quantization for Vision Transformers
- [CVPR] Mixed-Precision Quantization for Federated Learning on Resource-Constrained Heterogeneous Devices
- [CVPR] PTQ4SAM: Post-Training Quantization for Segment Anything
- [CVPR] Reg-PTQ: Regression-specialized Post-training Quantization for Fully Quantized Object Detector
- [CVPR] Retraining-Free Model Quantization via One-Shot Weight-Coupling Learning
- [CVPR] TFMQ-DM: Temporal Feature Maintenance Quantization for Diffusion Models
- [CVPR] Towards Accurate Post-training Quantization for Diffusion Models
- [ECCV] AdaLog: Post-Training Quantization for Vision Transformers with Adaptive Logarithm Quantizer
- [ECCV] CLAMP-ViT: Contrastive Data-Free Learning for Adaptive Post-Training Quantization of ViTs
- [ECCV] Memory-Efficient Fine-Tuning for Quantized Diffusion Model
- [ECCV] MetaAug: Meta-Data Augmentation for Post-Training Quantization
- [ECCV] MixDQ: Memory-Efficient Few-Step Text-to-Image Diffusion Models with Metric-Decoupled Mixed Precision Quantization
- [ECCV] Overcoming Distribution Mismatch in Quantizing Image Super-Resolution Networks
- [ECCV] Post-training Quantization with Progressive Calibration and Activation Relaxing for Text-to-Image Diffusion Models
- [ECCV] PQ-SAM: Post-training Quantization for Segment Anything Model
- [ECCV] Timestep-Aware Correction for Quantized Diffusion Models
- [ECCV] Towards Robust Full Low-bit Quantization of Super Resolution Networks
- [EMNLP] ApiQ: Finetuning of 2-Bit Quantized Large Language Model
- [EMNLP] Prefixing Attention Sinks can Mitigate Activation Outliers for Large Language Model Quantization
- [EMNLP] VPTQ: Extreme Low-bit Vector Post-Training Quantization for Large Language Models [code]
- [EMNLP Findings] ATQ: Activation Transformation for Weight-Activation Quantization of LLMs
- [EMNLP Findings] Fine-tuning Rotated Outlier-free LLMs for Effective Weight-Activation Quantization
- [EMNLP Findings] How Does Quantization Affect Multilingual LLMs?
- [EMNLP Findings] MobileQuant: Mobile-friendly Quantization for On-device Language Models
- [EMNLP Findings] QEFT: Quantization for Efficient Fine-Tuning of LLMs
- [EMNLP Industry] LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit
- [ICLR] AffineQuant: Affine Transformation Quantization for Large Language Models [code]
- [ICLR] EfficientDM: Efficient Quantization-Aware Fine-Tuning of Low-Bit Diffusion Models
- [ICLR] LiDAR-PTQ: Post-Training Quantization for Point Cloud 3D Object Detection
- [ICLR] LoftQ: LoRA-Fine-Tuning-aware Quantization for Large Language Models [code]
- [ICLR] LUT-GEMM: Quantized Matrix Multiplication based on LUTs for Efficient Inference in Large-Scale Generative Language Models
- [ICLR] OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models [code]
- [ICLR] PB-LLM: Partially Binarized Large Language Models [code]
- [ICLR] QA-LoRA: Quantization-Aware Low-Rank Adaptation of Large Language Models [code]
- [ICLR] QLLM: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models
- [ICLR] Rethinking Channel Dimensions to Isolate Outliers for Low-bit Weight Quantization of Large Language Models
- [ICLR] SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression [code]
- [ICML] BiLLM: Pushing the Limit of Post-Training Quantization for LLMs [code]
- [ICML] Compressing Large Language Models by Joint Sparsification and Quantization
- [ICML] Accurate LoRA-Finetuning Quantization of LLMs via Information Retention [code]
- [ICML] Flexible Residual Binarization for Image Super-Resolution
- [ICML] A2Q+: Improving Accumulator-Aware Weight Quantization
- [ICML] BiE: Bi-Exponent Block Floating-Point for Large Language Models Quantization
- [ICML] ERQ: Error Reduction for Post-Training Quantization of Vision Transformers
- [ICML] Evaluating Quantized Large Language Models [code]
- [ICML] Extreme Compression of Large Language Models via Additive Quantization [code]
- [ICML] FrameQuant: Flexible Low-Bit Quantization for Transformers
- [ICML] KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache [code]
- [ICML] LQER: Low-Rank Quantization Error Reconstruction for LLMs
- [ICML] Outlier-aware Slicing for Post-Training Quantization in Vision Transformer
- [ICML] Sharpness-Aware Data Generation for Zero-shot Quantization
- [ICML] SqueezeLLM: Dense-and-Sparse Quantization [code]
- [ICML] Learning from students: Applying t-distributions to explore accurate and efficient formats for llms [code]
- [ICML] Jetfire: Efficient and Accurate Transformer Pretraining with INT8 Data Flow and Per-Block Quantization
- [ICML] Reshape and Adapt for Output Quantization (RAOQ): Quantization-aware Training for In-memory Computing Systems
- [ICML] QuIP#: Even Better LLM Quantization with Hadamard Incoherence and Lattice Codebooks [code]
- [MLSys] AWQ: Activation-aware Weight Quantization for On-Device LLM Compression and Acceleration [code]
- [MLSys] Atom: Low-bit Quantization for Efficient and Accurate LLM Serving [code]
[arXiv]
- [NeurIPS] BiDM: Pushing the Limit of Quantization for Diffusion Models
- [NeurIPS] Binarized Diffusion Model for Image Super-Resolution [code]
- [NeurIPS] 2DQuant: Low-bit Post-Training Quantization for Image Super-Resolution [code]
- [NeurIPS] BitsFusion: 1.99 bits Weight Quantization of Diffusion Model
- [NeurIPS] DuQuant: Distributing Outliers via Dual Transformation Makes Stronger Quantized LLMs
- [NeurIPS] KV Cache is 1 Bit Per Channel: Efficient Large Language Model Inference with Coupled Quantization
- [NeurIPS] KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization [code]
- [NeurIPS] PTQ4DiT: Post-training Quantization for Diffusion Transformers
- [NeurIPS] Q-VLM: Post-training Quantization for Large Vision-Language Models [code]
- [NeurIPS] QBB: Quantization with Binary Bases for LLMs
- [NeurIPS] ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification [code]
- [NeurIPS] QuaRot: Outlier-Free 4-Bit Inference in Rotated LLMs [code]
- [NeurIPS] Towards Next-Level Post-Training Quantization of Hyper-Scale Transformers [code]
- [NeurIPS] MagR: Weight Magnitude Reduction for Enhancing Post-Training Quantization [code]
- [NeurIPS] Exploiting LLM Quantization
- [NeurIPS] Efficient Multi-task LLM Quantization and Serving for Multiple LoRA Adapters
- [NeurIPS] QTIP: Quantization with Trellises and Incoherence Processing [code]
- [NeurIPS] Generalizing CNNs to graphs with learnable neighborhood quantization [code]
- [NeurIPS] SDP4Bit: Toward 4-bit Communication Quantization in Sharded Data Parallelism for LLM Training [code]
- [NeurIPS] Optimal and Approximate Adaptive Stochastic Quantization [code]
- [NeurIPS] Cherry on Top: Parameter Heterogeneity and Quantization in Large Language Models
- [NeurIPS] StepbaQ: Stepping backward as Correction for Quantized Diffusion Models
- [NeurIPS] PV-Tuning: Beyond Straight-Through Estimation for Extreme LLM Compression [code]
- [SIGMOD] RaBitQ: Quantizing High-Dimensional Vectors with a Theoretical Error Bound for Approximate Nearest Neighbor Search [code]
- [USENIX ATC] Quant-LLM: Accelerating the Serving of Large Language Models via FP6-Centric Algorithm-System Co-Design on Modern GPUs [code]
- [Visual Intelligence] An empirical study of LLaMA3 quantization: from LLMs to MLLMs [code]
- [arXiv] APTQ: Attention-aware Post-Training Mixed-Precision Quantization for Large Language Models
- [arXiv] EasyQuant: An Efficient Data-free Quantization Algorithm for LLMs
- [arXiv] EdgeQAT: Entropy and Distribution Guided Quantization-Aware Training for the Acceleration of Lightweight LLMs on the Edge [code]
- [arXiv] FlattenQuant: Breaking Through the Inference Compute-bound for Large Language Models with Per-tensor Quantization
- [arXiv] GPTVQ: The Blessing of Dimensionality for LLM Quantization [code]
- [arXiv] IntactKV: Improving Large Language Model Quantization by Keeping Pivot Tokens Intact
- [arXiv] OneBit: Towards Extremely Low-bit Large Language Models
- [arXiv] RepQuant: Towards Accurate Post-Training Quantization of Large Transformer Models via Scale Reparameterization
- [arXiv] The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits


2023
- [AAAI] Fast and Accurate Binary Neural Networks Based on Depth-Width Reshaping
- [AAAI] OMPQ: Orthogonal Mixed Precision Quantization
- [AAAI] Quantized Feature Distillation for Network Quantization
- [AAAI] Resilient Binary Neural Network
- [AAAI] Rethinking Data-Free Quantization as a Zero-Sum Game
- [AAAI] Quantization-Aware Interval Bound Propagation for Training Certifiably Robust Quantized Neural Networks [code]
- [ACL] Boost Transformer-based Language Models with GPU-Friendly Sparsity and Quantization
- [ACL] PreQuant: A Task-agnostic Quantization Approach for Pre-trained Language Models
- [CVPR] ABCD : Arbitrary Bitwise Coefficient for De-quantization
- [CVPR] Adaptive Data-Free Quantization
- [CVPR] Bit-shrinking: Limiting Instantaneous Sharpness for Improving Post-training Quantization
- [CVPR] Boost Vision Transformer with GPU-Friendly Sparsity and Quantization
- [CVPR] GENIE: Show Me the Data for Quantization [code]
- [CVPR] Hard Sample Matters a Lot in Zero-Shot Quantization
- [CVPR] NIPQ: Noise proxy-based Integrated Pseudo-Quantization
- [CVPR] NoisyQuant: Noisy Bias-Enhanced Post-Training Activation Quantization for Vision Transformers
- [CVPR] One-Shot Model for Mixed-Precision Quantization
- [CVPR] PD-Quant: Post-Training Quantization Based on Prediction Difference Metric [code]
- [CVPR] Post-training Quantization on Diffusion Models [code]
- [CVPR] Q-DETR: An Efficient Low-Bit Quantized Detection Transformer [code]
- [CVPR] Regularized Vector Quantization for Tokenized Image Synthesis
- [CVPR] Solving Oscillation Problem in Post-Training Quantization Through a Theoretical Perspective [code]
- [CVPR] Toward Accurate Post-Training Quantization for Image Super Resolution
- [EMNLP] LLM-FP4: 4-Bit Floating-Point Quantized Transformers [code]
- [EMNLP] Outlier Suppression+: Accurate quantization of large language models by equivalent and optimal shifting and scaling
- [EMNLP] Revisiting Block-based Quantisation: What is Important for Sub-8-bit LLM Inference?
- [EMNLP] Watermarking LLMs with Weight Quantization [code]
- [EMNLP] Zero-Shot Sharpness-Aware Quantization for Pre-trained Language Models
- [ICCV] A2Q: Accumulator-Aware Quantization with Guaranteed Overflow Avoidance
- [ICCV] BiViT: Extremely Compressed Binary Vision Transformers
- [ICCV] Causal-DFQ: Causality Guided Data-Free Network Quantization [code]
- [ICCV] DenseShift: Towards Accurate and Efficient Low-Bit Power-of-Two Quantization
- [ICCV] EMQ: Evolving Training-free Proxies for Automated Mixed Precision Quantization
- [ICCV] EQ-Net: Elastic Quantization Neural Networks [code]
- [ICCV] Estimator Meets Equilibrium Perspective: A Rectified Straight Through Estimator for Binary Neural Networks Training [code]
- [ICCV] I-ViT: Integer-only Quantization for Efficient Vision Transformer Inference [code]
- [ICCV] Jumping through Local Minima: Quantization in the Loss Landscape of Vision Transformers
- [ICCV] Overcoming Forgetting Catastrophe in Quantization-Aware Training
- [ICCV] Q-diffusion: Quantizing Diffusion Models [code]
- [ICCV] QD-BEV: Quantization-aware View-guided Distillation for Multi-view 3D Object Detection
- [ICCV] RepQ-ViT: Scale Reparameterization for Post-Training Quantization of Vision Transformers [code]
- [ICCV] Unified Data-Free Compression: Pruning and Quantization without Fine-Tuning
- [ICLR] Analog Bits: Generating Discrete Data using Diffusion Models with Self-Conditioning
- [ICLR] GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers [code]
- [ICLR] PowerQuant: Automorphism Search For Non-Uniform Quantization
- [ICLR] Block and Subword-Scaling Floating-Point (BSFP) : An Efficient Non-Uniform Quantization For Low Precision Inference
- [ICLR] A^2Q: Aggregation-Aware Quantization for Graph Neural Networks
- [ICML] BiBench: Benchmarking and Analyzing Network Binarization [code]
- [ICML] Few-bit Backward: Quantized Gradients of Activation Functions for Memory Footprint Reduction [code]
- [ICML] FlexRound: Learnable Rounding based on Element-wise Division for Post-Training Quantization [code]
- [ICML] GPT-Zip: Deep Compression of Finetuned Large Language Models
- [ICML] Oscillation-free Quantization for Low-bit Vision Transformers [code]
- [ICML] QIGen: Generating Efficient Kernels for Quantized Inference on Large Language Models [code]
- [ICML] Quantized Distributed Training of Large Models with Convergence Guarantees
- [ICML] SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models [code]
[arXiv PDF]
- [ICML] The case for 4-bit precision: k-bit Inference Scaling Laws
- [ICML] Understanding Int4 Quantization for Language Models: Latency Speedup, Composability, and Failure Cases [arXiv] [Proceedings] [code]
- [IJCV] Distribution-sensitive Information Retention for Accurate Binary Neural Network
- [NeurIPS] BiMatting: Efficient Video Matting via Binarization [code]
- [NeurIPS] QuantSR: Accurate Low-bit Quantization for Efficient Image Super-Resolution [code]
- [NeurIPS] Binarized Spectral Compressive Imaging [code]
- [NeurIPS] Memory-Efficient Fine-Tuning of Compressed Large Language Models via sub-4-bit Integer Quantization
- [NeurIPS] PackQViT: Faster Sub-8-bit Vision Transformers via Full and Packed Quantization on the Mobile
- [NeurIPS] PTQD: Accurate Post-Training Quantization for Diffusion Models [code]
- [NeurIPS] Q-DM: An Efficient Low-bit Quantized Diffusion Model
- [NeurIPS] QLoRA: Efficient Finetuning of Quantized LLMs [code]
- [NeurIPS] QuIP: 2-Bit Quantization of Large Language Models With Guarantees [code]
- [NeurIPS] Temporal Dynamic Quantization for Diffusion Models
- [NeurIPS] TexQ: Zero-shot Network Quantization with Texture Feature Distribution Calibration
- [NeurIPS] Understanding Neural Network Binarization with Forward and Backward Proximal Quantizers
- [NeurIPS] REx: Data-Free Residual Quantization Error Expansion
- [NeurIPS] Intriguing Properties of Quantization at Scale
- [NeurIPS] Training Transformers with 4-bit Integers [code]
- [NeurIPS] Towards Efficient and Accurate Winograd Convolution via Full Quantization
- [NeurIPS] Pruning vs Quantization: Which is Better? [code]
- [TIP] MBFQuant: A Multiplier-Bitwidth-Fixed, Mixed-Precision Quantization Method for Mobile CNN-Based Applications
- [TNNLS] BiFSMNv2: Pushing Binary Neural Networks for Keyword Spotting to Real-Network Performance [code]
- [TPAMI] Diverse Sample Generation: Pushing the Limit of Generative Data-Free Quantization [code]
- [TPAMI] Optimization-Based Post-Training Quantization With Bit-Split and Stitching
- [TPAMI] Single-path Bit Sharing for Automatic Loss-aware Model Compression
- [Visual Intelligence] RobustMQ: Benchmarking Robustness of Quantized Models
- [arXiv] Efficient Post-training Quantization with FP8 Formats [code]
- [arXiv] QFT: Quantized Full-parameter Tuning of LLMs with Affordable Resources
- [arXiv] QMoE: Practical Sub-1-Bit Compression of Trillion-Parameter Models
- [arXiv] RPTQ: Reorder-based Post-training Quantization for Large Language Models [code]
- [arXiv] ZeroQuant-HERO: Hardware-Enhanced Robust Optimized Post-Training Quantization Framework for W8A8 Transformers
- [arXiv] BitNet: Scaling 1-bit Transformers for Large Language Models
- [arXiv] Microscaling Data Formats for Deep Learning [code]


2022
- [ACL] Compression of Generative Pre-trained Language Models via Quantization
- [ACM MM] Towards Accurate Post-Training Quantization for Vision Transformer
- [Applied Soft Computing] A neural network compression method based on knowledge-distillation and parameter quantization for the bearing fault diagnosis
- [ASE] QVIP: An ILP-based Formal Verification Approach for Quantized Neural Networks
- [CCF Transactions on High Performance Computing] An efficient segmented quantization for graph neural networks
- [CVPR] PokeBNN: A Binary Pursuit of Lightweight Accuracy [code]
- [CVPR] Data-Free Network Compression via Parametric Non-uniform Mixed Precision Quantization
- [CVPR] Instance-Aware Dynamic Neural Network Quantization
- [CVPR] IntraQ: Learning Synthetic Images With Intra-Class Heterogeneity for Zero-Shot Network Quantization [code]
- [CVPR] It's All In the Teacher: Zero-Shot Quantization Brought Closer to the Teacher [code]
- [CVPR] Learnable Lookup Table for Neural Network Quantization [code]
- [CVPR] Mr.BiQ: Post-Training Non-Uniform Quantization based on Minimizing the Reconstruction Error
- [CVPR] Nonuniform-to-Uniform Quantization: Towards Accurate Quantization via Generalized Straight-Through Estimation [code]
- [CVPR] RecDis-SNN: Rectifying Membrane Potential Distribution for Directly Training Spiking Neural Networks
- [CVPR Workshops] A Low Memory Footprint Quantized Neural Network for Depth Completion of Very Sparse Time-of-Flight Depth Maps
- [CVPR Workshops] Simulated Quantization, Real Power Savings
- [EANN] A Robust, Quantization-Aware Training Method for Photonic Neural Networks
- [ECCV] BASQ: Branch-wise Activation-clipping Search Quantization for Sub-4-bit Neural Networks [code]
- [ECCV] Mixed-Precision Neural Network Quantization via Learned Layer-Wise Importance [code]
- [ECCV] Neuromorphic Data Augmentation for Training Spiking Neural Networks. [code]
- [ECCV] Non-Uniform Step Size Quantization for Accurate Post-Training Quantization
- [ECCV] Patch Similarity Aware Data-Free Quantization for Vision Transformers [code]
- [ECCV] PTQ4ViT: Post-Training Quantization for Vision Transformers with Twin Uniform Quantization [code]
- [ECCV] RDO-Q: Extremely Fine-Grained Channel-Wise Quantization via Rate-Distortion Optimization
- [ECCV] Symmetry Regularization and Saturating Nonlinearity for Robust Quantization
- [ECCV] Towards Accurate Network Quantization with Equivalent Smooth Regularizer
- [ECCV] Weight Fixing Networks. [code]
- [ECCV] CADyQ: Content-Aware Dynamic Quantization for Image Super-Resolution
- [ECCV] Bitwidth-Adaptive Quantization-Aware Neural Network Training: A Meta-Learning Approach [code]
- [ECCV] Fine-grained Data Distribution Alignment for Post-Training Quantization [code]
- [Electronics] A Survey on Efficient Convolutional Neural Networks and Hardware Acceleration
- [ESE] DiverGet: a Search-Based Software Testing approach for Deep Neural Network Quantization assessment
- [FPGA] FILM-QNN: Efficient FPGA Acceleration of Deep Neural Networks with Intra-Layer, Mixed-Precision Quantization
- [ICCRD] Post Training Quantization after Neural Network
- [ICLR] BiBERT: Accurate Fully Binarized BERT. [code]
- [ICLR] 8-bit Optimizers via Block-wise Quantization [code]
- [ICLR] F8Net: Fixed-Point 8-bit Only Multiplication for Network Quantization
- [ICLR] Information Bottleneck: Exact Analysis of (Quantized) Neural Networks [code]
- [ICLR] Optimal ANN-SNN Conversion for High-accuracy and Ultra-low-latency Spiking Neural Networks
- [ICLR] QDrop: Randomly Dropping Quantization for Extremely Low-bit Post-Training Quantization [code]
- [ICLR] SQuant: On-the-Fly Data-Free Quantization via Diagonal Hessian Approximation. [code]
- [ICLR] Toward Efficient Low-Precision Training: Data Format Optimization and Hysteresis Quantization
- [ICLR] VC dimension of partially quantized neural networks in the overparametrized regime
- [ICML] Finding the Task-Optimal Low-Bit Sub-Distribution in Deep Neural Networks [code]
- [ICML] GACT: Activation Compressed Training for Generic Network Architectures [code]
- [ICML] Overcoming Oscillations in Quantization-Aware Training [code]
- [ICML] SDQ: Stochastic Differentiable Quantization with Mixed Precision
- [ICML] Optimal Clipping and Magnitude-aware Differentiation for Improved Quantization-aware Training
- [ICPR] Layer-Wise Data-Free CNN Compression
- [IEEE Internet of Things Journal] FedQNN: A Computation–Communication-Efficient Federated Learning Framework for IoT With Low-Bitwidth Neural Network Quantization
- [IJCAI] BiFSMN: Binary Neural Network for Keyword Spotting [code]
- [IJCAI] FQ-ViT: Post-Training Quantization for Fully Quantized Vision Transformer [code]
- [IJCAI] MultiQuant: Training Once for Multi-bit Quantization of Neural Networks
- [IJCAI] RAPQ: Rescuing Accuracy for Power-of-Two Low-bit Post-training Quantization [code]
- [IJCNN] Accuracy Evaluation of Transposed Convolution-Based Quantized Neural Networks
- [IJNS] Convolutional Neural Networks Quantization with Attention
- [Intelligent Automation & Soft Computing] A Resource-Efficient Convolutional Neural Network Accelerator Using Fine-Grained Logarithmic Quantization
- [ITSM] Edge–Artificial Intelligence-Powered Parking Surveillance With Quantized Neural Networks
- [LNAI] ECQ$^x$: Explainability-Driven Quantization for Low-Bit and Sparse DNNs
- [MICRO] ANT: Exploiting Adaptive Numerical Data Type for Low-bit Deep Neural Network Quantization
- [Neural Networks] Quantization-aware training for low precision photonic neural networks
- [NeurIPS] BiMLP: Compact Binary Architectures for Vision Multi-Layer Perceptrons [code]
- [NeurIPS] BiT: Robustly Binarized Multi-distilled Transformer [code]
- [NeurIPS] ClimbQ: Class Imbalanced Quantization Enabling Robustness on Efficient Inferences
- [NeurIPS] Entropy-Driven Mixed-Precision Quantization for Deep Network Design
- [NeurIPS] FP8 Quantization: The Power of the Exponent [code]
- [NeurIPS] Leveraging Inter-Layer Dependency for Post-Training Quantization
- [NeurIPS] LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale [code]
- [NeurIPS] Optimal Brain Compression: A Framework for Accurate Post-Training Quantization and Pruning [code]
- [NeurIPS] Q-ViT: Accurate and Fully Quantized Low-bit Vision Transformer [code]
- [NeurIPS] Redistribution of Weights and Activations for AdderNet Quantization
- [NeurIPS] Theoretically Better and Numerically Faster Distributed Optimization with Smoothness-Aware Quantization Techniques
- [NeurIPS] Towards Efficient Post-training Quantization of Pre-trained Language Models
- [NeurIPS] ZeroQuant: Efficient and Affordable Post-Training Quantization for Large-Scale Transformers [code]
- [Neurocomputing] EPQuant: A Graph Neural Network compression approach based on product quantization
- [PPoPP] QGTC: accelerating quantized graph neural networks via GPU tensor core
- [TCCN] Low-Bitwidth Convolutional Neural Networks for Wireless Interference Identification
- [TCSVT] An Efficient Implementation of Convolutional Neural Network With CLIP-Q Quantization on FPGA
- [TGARS] Accelerating Convolutional Neural Network-Based Hyperspectral Image Classification by Step Activation Quantization
- [tinyML Research Symposium] Power-of-Two Quantization for Low Bitwidth and Hardware Compliant Neural Networks
- [ACM Trans. Des. Autom. Electron. Syst.] Structured Dynamic Precision for Deep Neural Networks Quantization
- [TODAES] Dynamic Quantization Range Control for Analog-in-Memory Neural Networks Acceleration
- [arXiv] Edge Inference with Fully Differentiable Quantized Mixed Precision Neural Networks
- [arXiv] Neural network quantization with ai model efficiency toolkit (aimet)
- [arXiv] Q-ViT: Fully Differentiable Quantization for Vision Transformer
- [arXiv] QONNX: Representing Arbitrary-Precision Quantized Neural Networks
- [arXiv] Quantune: Post-training Quantization of Convolutional Neural Networks using Extreme Gradient Boosting for Fast Deployment
- [arXiv] Sub-8-Bit Quantization Aware Training for 8-Bit Neural Network Accelerator with On-Device Speech Recognition
- [arXiv] FP8 Formats for Deep Learning


2021
- [AAAI] Compressing Deep Convolutional Neural Networks by Stacking Low-Dimensional Binary Convolution Filters
- [AAAI] Distribution Adaptive INT8 Quantization for Training CNNs
- [AAAI] FracBits: Mixed Precision Quantization via Fractional Bit-Widths
- [AAAI] Memory and Computation-Efficient Kernel SVM via Binary Embedding and Ternary Coefficients
- [AAAI] OPQ: Compressing Deep Neural Networks with One-shot Pruning-Quantization
- [AAAI] Optimizing Information Theory Based Bitwise Bottlenecks for Efficient Mixed-Precision Activation Quantization
- [AAAI] Post-‐training Quantization with Multiple Points: Mixed Precision without Mixed Precision
- [AAAI] Scalable Verification of Quantized Neural Networks [code]
- [AAAI] Stochastic Precision Ensemble: Self‐Knowledge Distillation for Quantized Deep Neural Networks
- [AAAI] TRQ: Ternary Neural Networks with Residual Quantization
- [AAAI] Uncertainty Quantification in CNN through the Bootstrap of Convex Neural Networks
- [AAAI] Vector Quantized Bayesian Neural Network Inference for Data Streams
- [AAAI] Training Binary Neural Network without Batch Normalization for Image Super-Resolution
- [AAAI] SA-BNN: State-Aware Binary Neural Network
- [ACL] On the Distribution, Sparsity, and Inference-time Quantization of Attention Values in Transformers
- [ACM MM] Fully Quantized Image Super-Resolution Networks [code]
- [ACM MM] VQMG: Hierarchical Vector Quantised and Multi-hops Graph Reasoning for Explicit Representation Learning
- [CVPR Oral] Diversifying Sample Generation for Accurate Data-Free Quantization
- [CVPR] Binary Graph Neural Networks [code]
- [CVPR] Learnable Companding Quantization for Accurate Low-bit Neural Networks
- [CVPR] Network Quantization with Element-wise Gradient Scaling [code]
- [CVPR] Permute, Quantize, and Fine-tune: Efficient Compression of Neural Networks [code]
- [CVPR] S2-bnn: Bridging the gap between self-supervised real and 1-bit neural networks via guided distribution calibration [code]
- [CVPR] Zero-shot Adversarial Quantization [code]
- [CVPR] Automated Log-Scale Quantization for Low-Cost Deep Neural Networks
- [CVPR] QPP: Real-Time Quantization Parameter Prediction for Deep Neural Networks
- [ICCV] MixMix: All You Need for Data-Free Compression Are Feature and Data Mixing
- [ICLR] BiPointNet: Binary Neural Network for Point Clouds [code]
- [ICLR] BRECQ: Pushing the Limit of Post-Training Quantization by Block Reconstruction [code]
- [ICLR] BSQ: Exploring Bit-Level Sparsity for Mixed-Precision Neural Network Quantization [code]
- [ICLR] Degree-Quant: Quantization-Aware Training for Graph Neural Networks
- [ICLR] High-Capacity Expert Binary Networks [code]
- [ICLR] Incremental few-shot learning via vector quantization in deep embedded space
- [ICLR] Multi-Prize Lottery Ticket Hypothesis: Finding Accurate Binary Neural Networks by Pruning A Randomly Weighted Network [code]
- [ICLR] Neural gradients are near-lognormal: improved quantized and sparse training
- [ICLR] Reducing the Computational Cost of Deep Generative Models with Binary Neural Networks
- [ICLR] Simple Augmentation Goes a Long Way: ADRL for DNN Quantization
- [ICLR] Training with Quantization Noise for Extreme Model Compression [code]
[arXiv]
- [ICLR] WrapNet: Neural Net Inference with Ultra-Low-Resolution Arithmetic
- [ICLR] Improving Post Training Neural Quantization: Layer-wise Calibration and Integer Programming [code]
- [ICML] How Do Adam and Training Strategies Help BNNs Optimization? [code]
- [ICML] ActNN: Reducing Training Memory Footprint via 2-Bit Activation Compressed Training [code]
- [ICML] Auto-NBA: Efficient and Effective Search Over the Joint Space of Networks, Bitwidths, and Accelerators [code]
- [ICML] Differentiable Dynamic Quantization with Mixed Precision and Adaptive Resolution
- [ICML] HAWQ-V3: Dyadic Neural Network Quantization [code]
- [ICML] I-BERT: Integer-only BERT Quantization [code]
- [ICML] Accurate Post Training Quantization With Small Calibration Sets
- [NeurIPS] A Winning Hand: Compressing Deep Networks Can Improve Out-of-Distribution Robustness [code]
- [NeurIPS] Divergence Frontiers for Generative Models: Sample Complexity, Quantization Effects, and Frontier Integrals
- [NeurIPS] Post-Training Quantization for Vision Transformer
- [NeurIPS] Post-Training Sparsity-Aware Quantization [code]
- [NeurIPS] Qimera: Data-free Quantization with Synthetic Boundary Supporting Samples [code]
- [NeurIPS] Qu-ANTI-zation: Exploiting Quantization Artifacts for Achieving Adversarial Outcomes
- [NeurIPS] VQ-GNN: A Universal Framework to Scale up Graph Neural Networks using Vector Quantization
- [NeurIPS] BatchQuant: Quantized-for-all Architecture Search with Robust Quantizer
- [NeurIPS Datasets and Benchmarks] MQBench: Towards Reproducible and Deployable Model Quantization Benchmark [code]
- [arXiv] A Survey of Quantization Methods for Efficient Neural Network Inference
- [arXiv] A White Paper on Neural Network Quantization
- [arXiv] Any-Precision Deep Neural Networks [code]
- [arXiv] ReCU: Reviving the Dead Weights in Binary Neural Networks [code]


2020
- [AAAI] HLHLp: Quantized Neural Networks Training for Reaching Flat Minima in Loss Surface
- [AAAI] Q-BERT: Hessian Based Ultra Low Precision Quantization of BERT
- [AAAI] Sparsity-Inducing Binarized Neural Networks
- [AAAI] Towards Accurate Low Bit-Width Quantization with Multiple Phase Adaptations
- [ACL] End to End Binarized Neural Networks for Text Classification
- [COOL CHIPS] A Novel In-DRAM Accelerator Architecture for Binary Neural Network
- [CVPR] Forward and Backward Information Retention for Accurate Binary Neural Networks [code]
- [CVPR] APQ: Joint Search for Network Architecture, Pruning and Quantization Policy [code]
- [CVPR] BiDet: An Efficient Binarized Object Detector. [code]
- [CVPR] Fixed-Point Back-Propagation Training
- [CVPR] Rotation Consistent Margin Loss for Efficient Low-Bit Face Recognition
- [CVPR] ZeroQ: A Novel Zero Shot Quantization Framework [code]
- [CVPR] AdaBits: Neural Network Quantization With Adaptive Bit-Widths [code]
- [CVPR] Adaptive Loss-aware Quantization for Multi-bit Networks [code]
- [CVPR Workshops] Low-Bit Quantization Needs Good Distribution
- [DATE] BNNsplit: Binarized Neural Networks for embedded distributed FPGA-based computing systems
- [DATE] OrthrusPE: Runtime Reconfigurable Processing Elements for Binary Neural Networks
- [DATE] PhoneBit: Efficient GPU-Accelerated Binary Neural Network Inference Engine for Mobile Phones
- [ECCV] PAMS: Quantized Super-Resolution via Parameterized Max Scale [code]
- [ECCV] BATS: Binary ArchitecTure Search
- [ECCV] Differentiable Joint Pruning and Quantization for Hardware Efficiency
- [ECCV] Generative Low-bitwidth Data Free Quantization [code]
- [ECCV] Learning Architectures for Binary Networks [code]
- [ECCV] PROFIT: A Novel Training Method for sub-4-bit MobileNet Models
- [ECCV] ProxyBNN: Learning Binarized Neural Networks via Proxy Matrices
- [ECCV] ReActNet: Towards Precise Binary Neural Network with Generalized Acti


Truncated — view the full README on GitHub.
Contributors
(top 30 of 34)


A curated collection of papers, benchmarks, surveys, and tools for model quantization, covering low-bit networks, LLMs, multimodal and generative models, vector and lattice quantization, and efficient deployment.
2,449
336 commits
updated Sep 21, 2026
README
Awesome Model Quantization
Awesome Model Quantization is a curated, continuously updated collection of papers, benchmarks, surveys, and open-source implementations on neural network and model quantization. It spans binary and ternary networks, post-training quantization, quantization-aware training, vector and lattice quantization, low-bit LLMs, multimodal and generative models, KV-cache quantization, low-precision training, and hardware-efficient deployment.
Quick Navigation
- Research Landscape
- Representative Works
- Benchmarks · Survey Papers
- Papers by Year
2026 · 2025 · 2024 · 2023 · 2022 · 2021 · 2020 · 2019 · 2018 · 2017 · 2016 · 2015 · 2014 - Books · Related Repositories · Researcher Homepages · Contributing / Scope
Research Landscape
Model quantization can be organized along five dimensions:
- Optimization: post-training quantization (PTQ), quantization-aware training (QAT), quantized fine-tuning, data-free methods, and low-precision training.
- Representation: scalar, vector/codebook, lattice, binary-coded, binary/ternary, and mixed-precision quantization.
- Error reduction: rotations, outlier smoothing, residual reconstruction, error compensation, and sensitivity-aware methods.
- Quantized tensors: weights, activations, KV caches, training states, gradients, and communication.
- Models and deployment: vision, language, multimodal, generative, state space, and graph models, alongside edge and hardware systems.
Methods often combine several dimensions, such as PTQ with rotations and vector codebooks.
🔎 Explore the taxonomy and method connections · Click to expand
Optimization paradigm
Post-Training Quantization (PTQ) converts a pretrained model, often with calibration: GPTQ, SmoothQuant, AWQ, OmniQuant, QuaRot, SpinQuant, FlatQuant, BiLLM. Quantization-Aware Training (QAT) models quantization during optimization: PACT, LSQ, IR-Net. Quantized Fine-Tuning / Parameter-Efficient Fine-Tuning (PEFT) adapts low-bit models: QLoRA, QA-LoRA, LoftQ, IR-QLoRA, L4Q. Data-Free / Zero-Shot Quantization avoids original training data, using model statistics or synthetic samples: ZeroQ, Qimera. Low-Precision Training also reduces precision in training computation or stored states: INT8/FP8 training, 8-bit Optimizers.
Representation / coding structure
Scalar quantization codes individual values; non-uniform, logarithmic, and floating-point quantization change the available levels (AdaLog, LLM-FP4). Vector quantization jointly codes tuples; codebook quantization stores reusable representatives; product / grouped vector quantization partitions vectors into groups (GPTVQ, VPTQ, EPQuant). Lattice quantization uses structured geometric codebooks (QuIP#, NestQuant, grouped lattice vector quantizers). Binary-coded quantization combines binary bases (AnyBCQ); binary / ternary quantization constrains values to two / three levels (IR-Net, BiBERT, PT²-LLM). Mixed precision allocates different bit widths or formats across tensors or groups (HAWQ, SliM-LLM).
Transformation / error handling
Rotation / orthogonal transforms redistribute coordinates (QuaRot, SpinQuant); outlier smoothing / redistribution balances quantization difficulty (SmoothQuant, AWQ). Residual / low-rank reconstruction models remaining errors or outliers (LQER, SVDQuant); error compensation corrects quantization effects (GPTQ, First-Order Error Matters). Saliency-aware / Hessian-aware quantization uses importance or curvature to guide precision, reconstruction, or rounding (HAWQ, GPTQ, BiLLM). These techniques can accompany scalar or structured coding.
Quantized object
Weights (GPTQ, AWQ); activations (PACT); weight + activation (SmoothQuant, BiBERT); KV cache (KIVI, KVQuant, ZipCache, PM-KVQ); training states / optimizer states (ActNN, 8-bit Optimizers); gradients / communication (DoReFa-Net, SDP4Bit). Weight bit width does not imply the same activation, accumulator, or cache precision.
Model family / deployment
CNNs / classical vision (XNOR-Net, BRECQ); Vision Transformers (PTQ4ViT); Large Language Models (GPTQ, QLoRA); multimodal / VLM / VLA (Q-VLM, MQuant, AutoQVLA); diffusion / generative models (PTQ4DM, Q-Diffusion, PTQD, ViDiT-Q, SVDQuant, BinaryDM, Q-VDiT, S²Q-VDiT, QuantSparse); Mamba / state space models (Quamba2, SSDi8); graph / point cloud models (EPQuant, BiPointNet); edge / embedded / hardware-oriented systems (HAQ, FINN, LUT-GEMM).
For the structured-coding lineage, QuIP introduces incoherence processing for low-bit LLM quantization; QuIP# connects this direction to lattice codebooks, while QTIP uses trellis coding. GPTVQ, VPTQ, and NestQuant explore vector or lattice representations. TurboQuant and RaBitQ are also retained for their vector-quantization methodology; RaBitQ targets approximate nearest-neighbor search rather than LLM weight quantization.
Bit width alone does not specify storage overhead, arithmetic precision, or deployment speed.
Representative Works
Selected works grouped by technical approach, with authors and short method summaries. Each paper has one primary home here; the yearly collection includes the wider literature.
- Foundations: Classical / QAT · Data-free · Binary / ternary · Vector / codebook
- Language models: Transformer / LLM · Quantized fine-tuning · KV cache
- Models and systems: Generative models · Multimodal / state space · Vision / hardware · Floating-point formats · Training
Reading the links: Scholar opens a title search on Google Scholar, where citation counts can be viewed. Star badges show the linked GitHub repository’s stars, which may cover several papers. These are discovery aids, not rankings.
Classical Quantization and QAT
From binary weights and learned codebooks to integer arithmetic, learned quantizers and reconstruction-based PTQ.
-
BinaryConnect: Training Deep Neural Networks with binary weights during propagations
Matthieu Courbariaux, Yoshua Bengio, Jean-Pierre David
NeurIPS 2015 ·Neural NetworksQATBinary Weights· Paper · Code · Scholar
Trains neural networks with binary weights during forward and backward propagation. -
XNOR-Net: ImageNet Classification Using Binary Convolutional Neural Networks
Mohammad Rastegari, Vicente Ordonez, Joseph Redmon, Ali Farhadi
ECCV 2016 ·CNNBinaryWeight + Activation· Paper · Code · Scholar
Approximates convolutions with binary weights and inputs for efficient CNN inference. -
Deep Compression: Compressing Deep Neural Networks with Pruning, Trained Quantization and Huffman Coding
Song Han, Huizi Mao, William J. Dally
ICLR 2016 ·CNNWeight SharingCodebook· Paper · Scholar
Combines pruning, trained weight sharing and Huffman coding, connecting learned quantization to compressed model storage. -
PACT: Parameterized Clipping Activation for Quantized Neural Networks
Jungwook Choi, Zhuo Wang, Swagath Venkataramani, Pierce I-Jen Chuang, Vijayalakshmi Srinivasan, Kailash Gopalakrishnan
ICLR 2018 ·CNNQATActivations· Paper · Scholar
Learns activation clipping thresholds to support low-bit network training. -
Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference
Benoit Jacob, Skirmantas Kligys, Bo Chen, Menglong Zhu, Matthew Tang, Andrew Howard, Hartwig Adam, Dmitry Kalenichenko
CVPR 2018 ·QATINT8Integer-Only Inference· Paper · Scholar
Co-designs quantization-aware training and integer arithmetic for mobile inference, including scale and zero-point handling. -
HAWQ: Hessian AWare Quantization of Neural Networks With Mixed-Precision
Zhen Dong, Zhewei Yao, Amir Gholami, Michael W. Mahoney, Kurt Keutzer
ICCV 2019 ·Mixed PrecisionHessian-Aware· Paper · Scholar
Uses Hessian information to guide mixed-precision neural network quantization. -
Learned Step Size Quantization
Steven K. Esser, Jeffrey L. McKinstry, Deepika Bablani, Rathinakumar Appuswamy, Dharmendra S. Modha
ICLR 2020 ·QATLow-Bit· Paper · Scholar
Learns quantizer step sizes alongside network parameters. -
Up or Down? Adaptive Rounding for Post-Training Quantization
Markus Nagel, Rana Ali Amjad, Mart van Baalen, Christos Louizos, Tijmen Blankevoort
ICML 2020 ·PTQRounding· Paper · Scholar
Optimizes rounding decisions when converting pretrained weights to low precision. -
HAWQ-V2: Hessian Aware trace-Weighted Quantization of Neural Networks
Zhen Dong, Zhewei Yao, Daiyaan Arfeen, Amir Gholami, Michael Mahoney, Kurt Keutzer
NeurIPS 2020 ·Mixed PrecisionHessian-Aware· Paper · Scholar
Develops trace-weighted Hessian sensitivity for mixed-precision allocation. -
BRECQ: Pushing the Limit of Post-Training Quantization by Block Reconstruction
Yuhang Li, Ruihao Gong, Xu Tan, Yang Yang, Peng Hu, Qi Zhang, Fengwei Yu, Wei Wang, Shi Gu
ICLR 2021 ·CNNPTQReconstruction· Paper · Code · Scholar
Uses block reconstruction to reduce post-training quantization error. -
QDrop: Randomly Dropping Quantization for Extremely Low-bit Post-Training Quantization
Xiuying Wei, Ruihao Gong, Yuhang Li, Xianglong Liu, Fengwei Yu
ICLR 2022 ·PTQActivationsReconstruction· Paper · Code · Scholar
Randomly bypasses activation quantization during reconstruction to improve low-bit generalization beyond the calibration data.
Data-Free and Zero-Shot Quantization
These methods replace access to the original dataset with model statistics or generated samples; they may still require calibration or optimization.
-
Data-Free Quantization Through Weight Equalization and Bias Correction
Markus Nagel, Mart van Baalen, Tijmen Blankevoort, Max Welling
ICCV 2019 ·CNNPTQData-Free· Paper · Scholar
Equalizes channel ranges and corrects quantization-induced bias using model parameters and statistics. -
ZeroQ: A Novel Zero Shot Quantization Framework
Yaohui Cai, Zhewei Yao, Zhen Dong, Amir Gholami, Michael W. Mahoney, Kurt Keutzer
CVPR 2020 ·CNNData-FreeMixed Precision· Paper · Code · Scholar
Synthesizes calibration inputs from batch-normalization statistics to quantize without the original training dataset. -
Diversifying Sample Generation for Accurate Data-Free Quantization
Xiangguo Zhang, Haotong Qin, Yifu Ding, Ruihao Gong, Qinghua Yan, Renshuai Tao, Yuhang Li, Fengwei Yu, Xianglong Liu
CVPR 2021 · Oral ·CNNData-FreeSynthetic DataPTQ· Paper · Scholar
Relaxes batch-normalization statistic matching and varies layer-wise emphasis to diversify synthetic calibration samples for data-free quantization. -
Diverse Sample Generation: Pushing the Limit of Generative Data-Free Quantization
Haotong Qin, Yifu Ding, Xiangguo Zhang, Jiakai Wang, Xianglong Liu, Jiwen Lu
IEEE TPAMI 2023 ·CNNData-FreePTQ + QATSample Diversity· Paper · Code · Scholar
Extends the CVPR 2021 DSG method with theoretical analysis and inter-sample decorrelation, improving synthetic-data generation for both PTQ and QAT. -
LLM-QAT: Data-Free Quantization Aware Training for Large Language Models
Zechun Liu, Barlas Oguz, Changsheng Zhao, Ernie Chang, Pierre Stock, Yashar Mehdad, Yangyang Shi, Raghuraman Krishnamoorthi, Vikas Chandra
ACL Findings 2024 ·LLMQATData-FreeKV Cache· Paper · Scholar
Uses the pretrained model’s generated text for distillation-based QAT of weights, activations and KV caches.
Transformer and LLM Quantization
Weight-only compression, weight–activation quantization and QAT address different deployment needs. Sparse outlier handling and rotations offer complementary ways to control error.
-
LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale
Tim Dettmers, Mike Lewis, Younes Belkada, Luke Zettlemoyer
NeurIPS 2022 ·TransformerINT8Mixed Precision· Paper · Code · Scholar
Enables 8-bit matrix multiplication at transformer scale while handling outlier features in higher precision. -
GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers
Elias Frantar, Saleh Ashkboos, Torsten Hoefler, Dan Alistarh
ICLR 2023 ·LLMPTQWeights· Paper · Code · Scholar
Uses approximate second-order information and error compensation for low-bit weight quantization. -
SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models
Guangxuan Xiao, Ji Lin, Mickael Seznec, Hao Wu, Julien Demouth, Song Han
ICML 2023 ·LLMPTQWeight + Activation· Paper · Code · Scholar
Redistributes activation outlier difficulty into weights to enable low-precision matrix multiplication. -
AWQ: Activation-aware Weight Quantization for On-Device LLM Compression and Acceleration
Ji Lin, Jiaming Tang, Haotian Tang, Shang Yang, Wei-Ming Chen, Wei-Chen Wang, Guangxuan Xiao, Xingyu Dang, Chuang Gan, Song Han
MLSys 2024 ·LLMPTQWeightsSaliency-Aware· Paper · Code · Scholar
Uses activation information to guide weight quantization for on-device compression and acceleration. -
OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models
Wenqi Shao, Mengzhao Chen, Zhaoyang Zhang, Peng Xu, Lirui Zhao, Zhiqian Li, Kaipeng Zhang, Peng Gao, Yu Qiao, Ping Luo
ICLR 2024 ·LLMPTQCalibration· Paper · Code · Scholar
Optimizes clipping and equivalent transformations to calibrate low-bit LLMs. -
QuaRot: Outlier-Free 4-Bit Inference in Rotated LLMs
Saleh Ashkboos, Amirkeivan Mohtashami, Maximilian L. Croci, Bo Li, Pashmina Cameron, Martin Jaggi, Dan Alistarh, Torsten Hoefler, James Hensman
NeurIPS 2024 ·LLMPTQ4-BitRotation· Paper · Code · Scholar
Uses rotations to suppress outliers and enable 4-bit inference. -
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
Tim Dettmers, Ruslan Svirschevski, Vage Egiazarian, Denis Kuznedelev, Elias Frantar, Saleh Ashkboos, Alexander Borzunov, Torsten Hoefler, Dan Alistarh
ICLR 2024 ·LLMPTQWeightsSparse Outliers· Paper · Code · Scholar
Separates sensitive outlier weights into a sparse higher-precision component while quantizing the remaining weights. -
SqueezeLLM: Dense-and-Sparse Quantization
Sehoon Kim, Coleman Hooper, Amir Gholami, Zhen Dong, Xiuyu Li, Sheng Shen, Michael W. Mahoney, Kurt Keutzer
ICML 2024 ·LLMPTQNon-uniformSparse Outliers· Paper · Code · Scholar
Combines sensitivity-weighted non-uniform scalar quantization with a sparse component for outlier weights. -
SpinQuant: LLM Quantization with Learned Rotations
Zechun Liu, Changsheng Zhao, Igor Fedorov, Bilge Soran, Dhruv Choudhary, Raghuraman Krishnamoorthi, Vikas Chandra, Yuandong Tian, Tijmen Blankevoort
ICLR 2025 ·LLMPTQLearned Rotation· Paper · Code · Scholar
Learns rotations to make LLM representations more amenable to quantization. -
FlatQuant: Flatness Matters for LLM Quantization
Yuxuan Sun, Ruikang Liu, Haoli Bai, Han Bao, Kang Zhao, Yuening Li, Jiaxin Hu, Xianzhi Yu, Lu Hou, Chun Yuan, Xin Jiang, Wulong Liu, Jun Yao
ICML 2025 ·LLMPTQTransformation· Paper · Code · Scholar
Targets distribution flatness to improve LLM quantization. -
EfficientQAT: Efficient Quantization-Aware Training for Large Language Models
Mengzhao Chen, Wenqi Shao, Peng Xu, Jiahao Wang, Peng Gao, Kaipeng Zhang, Ping Luo
ACL 2025 ·LLMQATLow-Bit· Paper · Code · Scholar
Trains block parameters first, then quantization parameters end to end, to reduce the cost of LLM QAT.
Quantized Fine-Tuning
QLoRA and related methods adapt low-bit bases with low-rank updates; PV-Tuning also optimizes discrete compressed representations.
-
QLoRA: Efficient Finetuning of Quantized LLMs
Tim Dettmers, Artidoro Pagnoni, Ari Holtzman, Luke Zettlemoyer
NeurIPS 2023 ·LLMPEFT4-Bit· Paper · Code · Scholar
Fine-tunes low-rank adapters through a frozen 4-bit quantized base model. -
QA-LoRA: Quantization-Aware Low-Rank Adaptation of Large Language Models
Yuhui Xu, Lingxi Xie, Xiaotao Gu, Xin Chen, Heng Chang, Hengheng Zhang, Zhengsu Chen, Xiaopeng Zhang, Qi Tian
ICLR 2024 ·LLMPEFTQuantization-Aware· Paper · Code · Scholar
Combines quantization-aware optimization with low-rank adaptation. -
LoftQ: LoRA-Fine-Tuning-aware Quantization for Large Language Models
Yixiao Li, Yifan Yu, Chen Liang, Pengcheng He, Nikos Karampatziakis, Weizhu Chen, Tuo Zhao
ICLR 2024 ·LLMPEFTLow-Bit· Paper · Code · Scholar
Aligns quantization with LoRA initialization to reduce the error encountered during adaptation. -
Accurate LoRA-Finetuning Quantization of LLMs via Information Retention
Haotong Qin, Xudong Ma, Xingyu Zheng, Xiaoyang Li, Yang Zhang, Shouda Liu, Jie Luo, Xianglong Liu, Michele Magno
ICML 2024 ·LLMPEFTInformation-Aware· Paper · Code · Scholar
Uses information retention to improve low-bit quantization and LoRA adaptation. -
PV-Tuning: Beyond Straight-Through Estimation for Extreme LLM Compression
Vladimir Malinovskii, Denis Mazur, Ivan Ilin, Denis Kuznedelev, Konstantin Burlachenko, Kai Yi, Dan Alistarh, Peter Richtarik
NeurIPS 2024 ·LLMQuantized Fine-TuningDiscrete Optimization· Paper · Code · Scholar
Alternates continuous and discrete optimization to fine-tune extremely compressed models, including additive-codebook representations. -
L4Q: Parameter Efficient Quantization-Aware Fine-Tuning on Large Language Models
Hyesung Jeon, Yulhwa Kim, Jae-Joon Kim
ACL 2025 ·LLMPEFTQAT· Paper · Scholar
Combines parameter-efficient fine-tuning with quantization-aware training.
Extreme Low-Bit, Binary and Ternary
Binary CNNs and transformers, post-training binarization, and native ternary pretraining have different training costs and arithmetic requirements.
-
Bi-Real Net: Enhancing the Performance of 1-bit CNNs With Improved Representational Capability and Advanced Training Algorithm
Zechun Liu, Baoyuan Wu, Wenhan Luo, Xin Yang, Wei Liu, Kwang-Ting Cheng
ECCV 2018 ·CNNBinaryQAT· Paper · Code · Scholar
Connects real-valued intermediate activations through shortcuts to improve information flow in 1-bit CNNs. -
Forward and Backward Information Retention for Accurate Binary Neural Networks
Haotong Qin, Ruihao Gong, Xianglong Liu, Mingzhu Shen, Ziran Wei, Fengwei Yu, Jingkuan Song
CVPR 2020 ·CNNQATBinary1-Bit· Paper · Code · Scholar
Retains information in both forward activations and backward gradients when training binary neural networks. -
ReActNet: Towards Precise Binary Neural Network with Generalized Activation Functions
Zechun Liu, Zhiqiang Shen, Marios Savvides, Kwang-Ting Cheng
ECCV 2020 ·CNNBinaryQAT· Paper · Code · Scholar
Learns activation shifts and reshaping functions to reduce the accuracy gap between binary and real-valued networks. -
BiBERT: Accurate Fully Binarized BERT
Haotong Qin, Yifu Ding, Mingyuan Zhang, Qinghua Yan, Aishan Liu, Qingqing Dang, Ziwei Liu, Xianglong Liu
ICLR 2022 ·TransformerNLPBinaryWeight + Activation· Paper · Code · Scholar
Targets fully binarized BERT, extending binary networks to transformer language models. -
BiLLM: Pushing the Limit of Post-Training Quantization for LLMs
Wei Huang, Yangdong Liu, Haotong Qin, Ying Li, Shiming Zhang, Xianglong Liu, Michele Magno, Xiaojuan Qi
ICML 2024 ·LLMPTQBinaryExtreme Low-Bit· Paper · Code · Scholar
Uses saliency-aware binarization to push pretrained LLM weights into the extreme low-bit regime. -
DB-LLM: Accurate Dual-Binarization for Efficient LLMs
Hong Chen, Chengtao Lv, Liang Ding, Haotong Qin, Xiabin Zhou, Yifu Ding, Xuebo Liu, Min Zhang, Jinyang Guo, Xianglong Liu, Dacheng Tao
ACL Findings 2024 ·LLMDual BinarizationExtreme Low-Bit· Paper · Scholar
Uses dual binarization to compress LLMs while retaining accuracy. -
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
Shuming Ma, Hongyu Wang, Lingxiao Ma, Lei Wang, Wenhui Wang, Shaohan Huang, Li Dong, Ruiping Wang, Jilong Xue, Furu Wei
arXiv 2024 ·LLMQATTernary Weights8-Bit Activations· Paper · Scholar
Extends BitNet’s quantization-aware pretraining to ternary weights; this is a training recipe, distinct from post-training binarization. -
ARB-LLM: Alternating Refined Binarizations for Large Language Models
Zhiteng Li, Xianglong Yan, Tianao Zhang, Haotong Qin, Dong Xie, Jiang Tian, Zhongchao Shi, Linghe Kong, Yulun Zhang, Xiaokang Yang
ICLR 2025 ·LLMBinaryExtreme Low-Bit· Paper · Code · Scholar
Refines alternating binarizations for low-bit LLM representation. -
PTQ1.61: Push the Real Limit of Extremely Low-Bit Post-Training Quantization Methods for Large Language Models
Jiaqi Zhao, Miao Zhang, Ming Wang, Yuzhang Shang, Kaihao Zhang, Weili Guan, Yaowei Wang, Min Zhang
ACL 2025 ·LLMPTQExtreme Low-Bit· Paper · Code · Scholar
Explores extremely low-bit post-training quantization for LLMs. -
PT²-LLM: Post-Training Ternarization for Large Language Models
Xianglong Yan, Chengzhu Bao, Zhiteng Li, Tianao Zhang, Kaicheng Yang, Haotong Qin, Ruobing Xie, Xingwu Sun, Yulun Zhang
ICLR 2026 ·LLMPTQTernary· Paper · Code · Scholar
Converts pretrained large language models to ternary representations.
Vector, Lattice and Codebook Quantization
From CNN product quantization to LLM additive, lattice and trellis codes. QuIP provides the incoherence-processing precursor; RaBitQ contributes vector-search methodology.
-
Compressing Deep Convolutional Networks using Vector Quantization
Yunchao Gong, Liu Liu, Ming Yang, Lubomir Bourdev
arXiv 2014 ·CNNVector QuantizationProduct Quantization· Paper · Scholar
Studies clustering and product quantization of CNN parameters as early approaches to reducing model storage. -
QuIP: 2-Bit Quantization of Large Language Models With Guarantees
Jerry Chee, Yaohui Cai, Volodymyr Kuleshov, Christopher De Sa
NeurIPS 2023 ·LLMPTQ2-BitIncoherence· Paper · Code · Scholar
Uses incoherence processing for low-bit quantization with guarantees, forming a precursor to the QuIP# lattice-codebook lineage. -
QuIP#: Even Better LLM Quantization with Hadamard Incoherence and Lattice Codebooks
Albert Tseng, Jerry Chee, Qingyao Sun, Volodymyr Kuleshov, Christopher De Sa
ICML 2024 ·LLMLatticeCodebookHadamard· Paper · Code · Scholar
Combines Hadamard incoherence processing with lattice codebooks for LLM quantization. -
QTIP: Quantization with Trellises and Incoherence Processing
Albert Tseng, Qingyao Sun, David Hou, Christopher De Sa
NeurIPS 2024 ·LLMTrellis CodingIncoherence· Paper · Code · Scholar
Combines trellis-based quantization with incoherence processing for compact LLM representation. -
GPTVQ: The Blessing of Dimensionality for LLM Quantization
Mart van Baalen, Andrey Kuzmin, Ivan Koryakovskiy, Markus Nagel, Peter Couperus, Cedric Bastoul, Eric Mahurin, Tijmen Blankevoort, Paul Whatmough
arXiv 2024 ·LLMVector QuantizationWeights· Paper · Code · Scholar
Exploits joint quantization of multiple weight coordinates rather than coding each weight independently. -
VPTQ: Extreme Low-bit Vector Post-Training Quantization for Large Language Models
Yifei Liu, Jicheng Wen, Yang Wang, Shengyu Ye, Li Lyna Zhang, Ting Cao, Cheng Li, Mao Yang
EMNLP 2024 ·LLMPTQVector QuantizationExtreme Low-Bit· Paper · Code · Scholar
Uses vector post-training quantization for extremely low-bit LLM compression. -
RaBitQ: Quantizing High-Dimensional Vectors with a Theoretical Error Bound for Approximate Nearest Neighbor Search
Jianyang Gao, Cheng Long
SIGMOD 2024 ·Vector QuantizationBinary CodesVector Search· Paper · Code · Scholar
Quantizes high-dimensional vectors with a theoretical error bound for approximate nearest-neighbor search. -
Extreme Compression of Large Language Models via Additive Quantization
Vage Egiazarian, Andrei Panferov, Denis Kuznedelev, Elias Frantar, Artem Babenko, Dan Alistarh
ICML 2024 ·LLMPTQAdditive Codebooks2–3 Bit· Paper · Code · Scholar
Represents weight vectors as sums of learned codewords and jointly optimizes codebooks within transformer blocks. -
NestQuant: nested lattice quantization for matrix products and LLMs
Semyon Savkin, Eitan Porat, Or Ordentlich, Yury Polyanskiy
ICML 2025 ·LLMLatticeMatrix Products· Paper · Scholar
Uses nested lattice quantization for matrix products and LLMs. -
Learning Grouped Lattice Vector Quantizers for Low-Bit Large Language Models
Xi Zhang, Xiaolin Wu, Jiamang Wang, Weisi Lin
NeurIPS 2025 ·LLMGrouped Vector QuantizationLattice· Paper · Scholar
Learns grouped lattice vector quantizers for low-bit LLM representation. -
AnyBCQ: Hardware Efficient Flexible Binary-Coded Quantization for Multi-Precision LLMs
Gunho Park, Jeongin Bae, Beomseok Kwon, Byeongwook Kim, Se Jung Kwon, Dongsoo Lee
ICLR 2026 ·LLMBinary-CodedMixed PrecisionHardware· Paper · Code · Scholar
Develops flexible binary-coded quantization for hardware-efficient multi-precision LLMs. -
TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate
Amir Zandieh, Majid Daliri, Majid Hadian, Vahab Mirrokni
ICLR 2026 ·Vector QuantizationOnlineDistortion· Paper · Scholar
Studies online vector quantization with near-optimal distortion rate.
KV Cache Quantization
These methods compress inference-time key and value tensors; their bit widths are separate from model weight precision.
-
KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache
Zirui Liu, Jiayi Yuan, Hongye Jin, Shaochen Zhong, Zhaozhuo Xu, Vladimir Braverman, Beidi Chen, Xia Hu
ICML 2024 ·LLMKV Cache2-Bit· Paper · Code · Scholar
Uses asymmetric, tuning-free 2-bit quantization to compress key and value caches. -
KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization
Coleman Hooper, Sehoon Kim, Hiva Mohammadzadeh, Michael Mahoney, Sophia Shao, Kurt Keutzer, Amir Gholami
NeurIPS 2024 ·LLMKV CacheLong Context· Paper · Code · Scholar
Targets long-context inference by reducing the memory occupied by the KV cache. -
ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification
Yefei He, Luoming Zhang, Weijia Wu, Jing Liu, Hong Zhou, Bohan Zhuang
NeurIPS 2024 ·LLMKV CacheSalient Tokens· Paper · Code · Scholar
Uses salient-token identification to guide accurate and efficient cache quantization. -
PM-KVQ: Progressive Mixed-precision KV Cache Quantization for Long-CoT LLMs
Tengxuan Liu, Shiyao Li, Jiayi Yang, Tianchen Zhao, Feng Zhou, Xiaohui Song, Guohao Dai, Shengen Yan, Huazhong Yang, Yu Wang
ICLR 2026 ·LLMKV CacheMixed Precision· Paper · Code · Scholar
Progressively quantizes KV caches with mixed precision for long chain-of-thought inference.
Diffusion and Generative Model Quantization
Early diffusion PTQ addresses denoising-step sensitivity; later work extends to diffusion transformers, low-rank outlier handling and video generation.
-
Post-training Quantization on Diffusion Models
Yuzhang Shang, Zhihang Yuan, Bin Xie, Bingzhe Wu, Yan Yan
CVPR 2023 ·DiffusionPTQ· Paper · Code · Scholar
Adapts post-training quantization to diffusion model inference. -
Q-diffusion: Quantizing Diffusion Models
Xiuyu Li, Yijiang Liu, Long Lian, Huanrui Yang, Zhen Dong, Daniel Kang, Shanghang Zhang, Kurt Keutzer
ICCV 2023 ·DiffusionPTQ· Paper · Code · Scholar
Quantizes diffusion models to reduce the cost of iterative generation. -
PTQD: Accurate Post-Training Quantization for Diffusion Models
Yefei He, Luping Liu, Jing Liu, Weijia Wu, Hong Zhou, Bohan Zhuang
NeurIPS 2023 ·DiffusionPTQError Handling· Paper · Code · Scholar
Targets accurate diffusion generation through post-training quantization error handling. -
ViDiT-Q: Efficient and Accurate Quantization of Diffusion Transformers for Image and Video Generation
Tianchen Zhao, Tongcheng Fang, Haofeng Huang, Rui Wan, Widyadewi Soedarmadji, Enshu Liu, Shiyao Li, Zinan Lin, Guohao Dai, Shengen Yan, Huazhong Yang, Xuefei Ning, Yu Wang
ICLR 2025 ·Diffusion TransformerImage + VideoLow-Bit· Paper · Code · Scholar
Quantizes diffusion transformers for both image and video generation. -
SVDQuant: Absorbing Outliers by Low-Rank Component for 4-Bit Diffusion Models
Muyang Li, Yujun Lin, Zhekai Zhang, Tianle Cai, Xiuyu Li, Junxian Guo, Enze Xie, Chenlin Meng, Jun-Yan Zhu, Song Han
ICLR 2025 ·Diffusion4-BitLow-Rank· Paper · Code · Scholar
Absorbs outliers into a low-rank component to support 4-bit diffusion models. -
BinaryDM: Accurate Weight Binarization for Efficient Diffusion Models
Xingyu Zheng, Xianglong Liu, Haotong Qin, Xudong Ma, Mingyuan Zhang, Haojie Hao, Jiakai Wang, Zixiang Zhao, Jinyang Guo, Michele Magno
ICLR 2025 ·DiffusionBinary Weights· Paper · Code · Scholar
Binarizes diffusion model weights for efficient generation. -
Q-VDiT: Towards Accurate Quantization and Distillation of Video-Generation Diffusion Transformers
Weilun Feng, Chuanguang Yang, Haotong Qin, Xiangqi Li, Yu Wang, Zhulin An, Libo Huang, Boyu Diao, Zixiang Zhao, Yongjun Xu, Michele Magno
ICML 2025 ·Video DiffusionQuantizationDistillation· Paper · Code · Scholar
Combines quantization and distillation for video-generation diffusion transformers. -
S²Q-VDiT: Accurate Quantized Video Diffusion Transformer with Salient Data and Sparse Token Distillation
Weilun Feng, Haotong Qin, Chuanguang Yang, Xiangqi Li, Han Yang, Yuqi Li, Zhulin An, Libo Huang, Michele Magno, Yongjun Xu
NeurIPS 2025 ·Video DiffusionQuantizationDistillation· Paper · Code · Scholar
Uses salient data and sparse-token distillation to improve quantized video diffusion transformers. -
QuantSparse: Comprehensively Compressing Video Diffusion Transformer with Model Quantization and Attention Sparsification
Weilun Feng, Chuanguang Yang, Haotong Qin, Mingqiang Wu, Yuqi Li, Xiangqi Li, Zhulin An, Libo Huang, Yulun Zhang, Michele Magno, Yongjun Xu
ICLR 2026 ·Video DiffusionQuantizationAttention Sparsity· Paper · Code · Scholar
Combines model quantization and attention sparsification to compress video diffusion transformers.
Multimodal and State Space Models
Vision-language models and selective state space models introduce quantization sensitivities beyond those of language-only transformers.
-
Q-VLM: Post-training Quantization for Large Vision-Language Models
Changyuan Wang, Ziwei Wang, Xiuwei Xu, Yansong Tang, Jie Zhou, Jiwen Lu
NeurIPS 2024 ·VLMPTQCross-Layer Dependency· Paper · Code · Scholar
Uses cross-layer dependencies to guide block partitioning and quantization of vision-language models. -
Quamba2: A Robust and Scalable Post-training Quantization Framework for Selective State Space Models
Hung-Yueh Chiang, Chi-Chih Chang, Natalia Frumkin, Kai-Chiang Wu, Mohamed S. Abdelfattah, Diana Marculescu
ICML 2025 ·MambaState Space ModelsPTQW4A8 / W8A8· Paper · Code · Scholar
Uses channel clustering and state-group quantization to accommodate the sensitivity of Mamba’s selective state-space computations.
Vision, Edge and Hardware
Vision methods and deployment systems connect quantizer design to integer kernels, memory movement and hardware costs.
-
FINN: A Framework for Fast, Scalable Binarized Neural Network Inference
Yaman Umuroglu, Nicholas J. Fraser, Giulio Gambardella, Michaela Blott, Philip Leong, Magnus Jahre, Kees Vissers
FPGA 2017 ·Binary NetworksFPGAInference· Paper · Code · Scholar
Provides a framework for fast, scalable binarized neural network inference on FPGA hardware. -
HAQ: Hardware-Aware Automated Quantization with Mixed Precision
Kuan Wang, Zhijian Liu, Yujun Lin, Ji Lin, Song Han
CVPR 2019 ·CNNMixed PrecisionHardware-Aware· Paper · Code · Scholar
Automates mixed-precision quantization with hardware deployment costs in view. -
BiPointNet: Binary Neural Network for Point Clouds
Haotong Qin, Zhongang Cai, Mingyuan Zhang, Yifu Ding, Haiyu Zhao, Shuai Yi, Xianglong Liu, Hao Su
ICLR 2021 ·Point CloudsBinaryQAT1-Bit· Paper · Code · Scholar
Uses entropy-maximizing aggregation and layer-wise scale recovery to address feature homogenization and scale distortion in binary point-cloud networks. -
PTQ4ViT: Post-Training Quantization for Vision Transformers with Twin Uniform Quantization
Zhihang Yuan, Chenhao Xue, Yiqi Chen, Qiang Wu, Guangyu Sun
ECCV 2022 ·Vision TransformerPTQ· Paper · Code · Scholar
Uses twin uniform quantization to support post-training compression of vision transformers. -
QuantSR: Accurate Low-bit Quantization for Efficient Image Super-Resolution
Haotong Qin, Yulun Zhang, Yifu Ding, Yifan Liu, Xianglong Liu, Martin Danelljan, Fisher Yu
NeurIPS 2023 ·Super-ResolutionQAT2–4 Bit· Paper · Code · Scholar
Combines a redistribution-driven learnable quantizer with a depth-dynamic architecture for accurate low-bit image super-resolution. -
LUT-GEMM: Quantized Matrix Multiplication based on LUTs for Efficient Inference in Large-Scale Generative Language Models
Gunho Park, Baeseong Park, Minsub Kim, Sungjae Lee, Jeonghoon Kim, Beomseok Kwon, Se Jung Kwon, Byeongwook Kim, Youngjoo Lee, Dongsoo Lee
ICLR 2024 ·LLMQuantized Matrix MultiplicationLookup Tables· Paper · Scholar
Uses lookup tables for efficient quantized matrix multiplication in generative language models. -
Quant-LLM: Accelerating the Serving of Large Language Models via FP6-Centric Algorithm-System Co-Design on Modern GPUs
Haojun Xia, Zhen Zheng, Xiaoxia Wu, Shiyang Chen, Zhewei Yao, Stephen Youn, Arash Bakhtiari, Michael Wyatt, Donglin Zhuang, Zhongzhu Zhou, Olatunji Ruwase, Yuxiong He, Shuaiwen Leon Song
USENIX ATC 2024 ·LLMFP6GPU Kernels· Paper · Code · Scholar
Uses TC-FPx kernels to support non-power-of-two weight formats efficiently on GPUs; the codebase is also known as FP6-LLM. -
QServe: W4A8KV4 Quantization and System Co-design for Efficient LLM Serving
Yujun Lin, Haotian Tang, Shang Yang, Zhekai Zhang, Guangxuan Xiao, Chuang Gan, Song Han
MLSys 2025 ·LLMW4A8KV4GPU Serving· Paper · Code · Scholar
Co-designs progressive quantization, attention and GPU kernels to turn reduced precision into serving throughput.
Floating-Point and Microscaling Formats
Low-bit floating-point and shared-scale formats complement integer quantization. Format design and model calibration are separate choices.
-
FP8 Formats for Deep Learning
Paulius Micikevicius, Dusan Stosic, Neil Burgess, Marius Cornea, Pradeep Dubey, Richard Grisenthwaite, Sangwon Ha, Alexander Heinecke, Patrick Judd, John Kamalu, Naveen Mellempudi, Stuart Oberman, Mohammad Shoeybi, Michael Siu, Hao Wu
arXiv 2022 ·FP8E4M3 / E5M2Training + Inference· Paper · Scholar
Defines complementary FP8 encodings and evaluates their use in neural network training and inference. -
Microscaling Data Formats for Deep Learning
Bita Darvish Rouhani, Ritchie Zhao, Ankit More, Mathew Hall, Alireza Khodamoradi, Summer Deng, Dhruv Choudhary, Marius Cornea, Eric Dellinger, Kristof Denolf, Stosic Dusan, Venmugil Elango, Maximilian Golub, Alexander Heinecke, Phil James-Roxby, Dharmesh Jani, Gaurav Kolhe, Martin Langhammer, Ada Li, Levi Melnick, Maral Mesmakhosroshahi, Andres Rodriguez, Michael Schulte, Rasoul Shafipour, Lei Shao, Michael Siu, Pradeep Dubey, Paulius Micikevicius, Maxim Naumov, Colin Verrilli, Ralph Wittig, Doug Burger, Eric Chung
arXiv 2023 ·MX FormatsBlock ScalingTraining + Inference· Paper · Code · Scholar
Combines shared block scales with narrow element formats to balance numerical range and hardware efficiency. -
LLM-FP4: 4-Bit Floating-Point Quantized Transformers
Shih-yang Liu, Zechun Liu, Xijie Huang, Pingcheng Dong, Kwang-Ting Cheng
EMNLP 2023 ·LLMPTQFP4· Paper · Code · Scholar
Searches exponent configurations and quantization parameters to handle weight and activation range differences in 4-bit floating point.
Low-Precision Training and States
Quantization can reduce saved activations, optimizer states, gradient communication or training arithmetic; each targets a different part of the training cost.
-
QSGD: Communication-Efficient SGD via Gradient Quantization and Encoding
Dan Alistarh, Demjan Grubic, Jerry Li, Ryota Tomioka, Milan Vojnovic
NeurIPS 2017 ·TrainingGradientsCommunication· Paper · Scholar
Uses randomized gradient quantization with convergence guarantees to trade communication bandwidth against estimator variance. -
ActNN: Reducing Training Memory Footprint via 2-Bit Activation Compressed Training
Jianfei Chen, Lianmin Zheng, Zhewei Yao, Dequan Wang, Ion Stoica, Michael Mahoney, Joseph Gonzalez
ICML 2021 ·TrainingActivations2-Bit· Paper · Code · Scholar
Compresses saved activations to reduce the memory footprint of neural network training. -
8-bit Optimizers via Block-wise Quantization
Tim Dettmers, Mike Lewis, Sam Shleifer, Luke Zettlemoyer
ICLR 2022 ·TrainingOptimizer States8-Bit· Paper · Code · Scholar
Uses block-wise quantization to reduce optimizer-state memory. -
SDP4Bit: Toward 4-bit Communication Quantization in Sharded Data Parallelism for LLM Training
Jinda Jia, Cong Xie, Hanlin Lu, Daoce Wang, Hao Feng, Chengming Zhang, Baixi Sun, Haibin Lin, Zhi Zhang, Xin Liu, Dingwen Tao
NeurIPS 2024 ·LLM TrainingCommunication4-Bit· Paper · Code · Scholar
Targets 4-bit communication quantization in sharded data-parallel LLM training. -
Optimizing Large Language Model Training Using FP4 Quantization
Ruizhe Wang, Yeyun Gong, Xiao Liu, Guoshuai Zhao, Ziyue Yang, Baining Guo, Zhengjun Zha, Peng Cheng
ICML 2025 ·LLM TrainingFP4Gradient Estimation· Paper · Scholar
Combines differentiable quantization estimation with outlier handling to stabilize FP4 LLM training.
Benchmarks
Choose by evaluation scope: deployment reproducibility, binary networks, LLM capabilities or robustness. Expand a resource below for authors, figures and citation details.
| Resource | What it covers |
|---|---|
| MQBench: Towards Reproducible and Deployable Model Quantization Benchmark NeurIPS 2021 Datasets and Benchmarks Code · Scholar | QAT + deployment Compares quantization algorithms under reproducible settings and hardware backend constraints. |
| BiBench: Benchmarking and Analyzing Network Binarization ICML 2023 Code · Scholar | Binary networks Compares binarization methods across tasks, architectures and deployment settings. |
| Evaluating Quantized Large Language Models ICML 2024 Code · Scholar | Weights, activations + KV cache Evaluates 11 model families on basic NLP, emergent abilities, trustworthiness, dialogue and long-context tasks. |
| LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit EMNLP 2024 Industry Track Code · Scholar | LLM toolkit Compares calibration data, method pipelines and quantization configurations; the toolkit is now LightCompress. |
| An empirical study of LLaMA3 quantization: from LLMs to MLLMs Visual Intelligence 2024 Code · Scholar | LLMs + multimodal Examines low-bit behavior across LLaMA3 language and multimodal models. |
| An Empirical Study of Qwen3 Quantization Visual Intelligence 2026 Code · Scholar | Dense + MoE LLMs Studies quantization across Qwen3 model sizes, architectures and reasoning settings. |
| RobustMQ: Benchmarking Robustness of Quantized Models Visual Intelligence 2023 Scholar | Model robustness Tests quantized models beyond clean accuracy, including robustness under input perturbations. |
MQBench · Authors and BibTeX
Yuhang Li, Mingzhu Shen, Jian Ma, Yan Ren, Mingxin Zhao, Qi Zhang, Ruihao Gong, Fengwei Yu, Junjie Yan
@inproceedings{li2021mqbench,
  title={MQBench: Towards Reproducible and Deployable Model Quantization Benchmark},
  author={Li, Yuhang and Shen, Mingzhu and Ma, Jian and Ren, Yan and Zhao, Mingxin and Zhang, Qi and Gong, Ruihao and Yu, Fengwei and Yan, Junjie},
  booktitle={NeurIPS Datasets and Benchmarks},
  year={2021}
}
BiBench · Authors, overview and BibTeX
Haotong Qin, Mingyuan Zhang, Yifu Ding, Aoyu Li, Zhongang Cai, Ziwei Liu, Fisher Yu, Xianglong Liu
@inproceedings{qin2023bibench,
  title={BiBench: Benchmarking and Analyzing Network Binarization},
  author={Qin, Haotong and Zhang, Mingyuan and Ding, Yifu and Li, Aoyu and Cai, Zhongang and Liu, Ziwei and Yu, Fisher and Liu, Xianglong},
  booktitle={International Conference on Machine Learning (ICML)},
  year={2023}
}
QLLM-Eval · Authors and BibTeX
Shiyao Li, Xuefei Ning, Luning Wang, Tengxuan Liu, Xiangsheng Shi, Shengen Yan, Guohao Dai, Huazhong Yang, Yu Wang
@inproceedings{li2024evaluating,
  title={Evaluating Quantized Large Language Models},
  author={Li, Shiyao and Ning, Xuefei and Wang, Luning and Liu, Tengxuan and Shi, Xiangsheng and Yan, Shengen and Dai, Guohao and Yang, Huazhong and Wang, Yu},
  booktitle={International Conference on Machine Learning},
  year={2024},
  url={https://proceedings.mlr.press/v235/li24bb.html}
}
LLMC · Authors, overview and BibTeX
Ruihao Gong, Yang Yong, Shiqiao Gu, Yushi Huang, Chengtao Lv, Yunchen Zhang, Dacheng Tao, Xianglong Liu
@inproceedings{gong2024llmc,
  title={Llmc: Benchmarking large language model quantization with a versatile compression toolkit},
  author={Gong, Ruihao and Yong, Yang and Gu, Shiqiao and Huang, Yushi and Lv, Chengtao and Zhang, Yunchen and Tao, Dacheng and Liu, Xianglong},
  booktitle={Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing: Industry Track},
  pages={132--152},
  year={2024}
}
LLaMA3 study · Authors, overview and BibTeX
Wei Huang, Xingyu Zheng, Xudong Ma, Haotong Qin, Chengtao Lv, Hong Chen, Jie Luo, Xiaojuan Qi, Xianglong Liu, Michele Magno
@article{huang2024empirical,
  title={An empirical study of llama3 quantization: From llms to mllms},
  author={Huang, Wei and Zheng, Xingyu and Ma, Xudong and Qin, Haotong and Lv, Chengtao and Chen, Hong and Luo, Jie and Qi, Xiaojuan and Liu, Xianglong and Magno, Michele},
  journal={Visual Intelligence},
  volume={2},
  number={1},
  pages={36},
  year={2024},
  publisher={Springer}
}
Qwen3 study · Authors, overview and BibTeX
Xingyu Zheng, Yuye Li, Haoran Chu, Yue Feng, Xudong Ma, Zining Wang, Jie Luo, Jinyang Guo, Haotong Qin, Michele Magno, Xianglong Liu
@article{zheng2026empirical,
  title={An empirical study of Qwen3 quantization},
  author={Zheng, Xingyu and Li, Yuye and Chu, Haoran and Feng, Yue and Ma, Xudong and Wang, Zining and Luo, Jie and Guo, Jinyang and Qin, Haotong and Magno, Michele and Liu, Xianglong},
  journal={Visual Intelligence},
  volume={4},
  pages={11},
  year={2026},
  doi={10.1007/s44267-026-00114-4}
}
RobustMQ · Authors, overview and BibTeX
Yisong Xiao, Aishan Liu, Tianyuan Zhang, Haotong Qin, Jinyang Guo, Xianglong Liu
@article{xiao2023robustmq,
  title={Robustmq: benchmarking robustness of quantized models},
  author={Xiao, Yisong and Liu, Aishan and Zhang, Tianyuan and Qin, Haotong and Guo, Jinyang and Liu, Xianglong},
  journal={Visual Intelligence},
  volume={1},
  number={1},
  pages={30},
  year={2023},
  publisher={Springer}
}
Survey Papers
Start with the white paper for practical PTQ/QAT, then choose a survey for broader context or a specific model family. Figures and citation details are available below.
| Resource | What it covers |
|---|---|
| A White Paper on Neural Network Quantization arXiv 2021 Scholar | Practical PTQ + QAT Explains quantizer design, common failure modes and practical post-training and quantization-aware training workflows. |
| A Survey of Quantization Methods for Efficient Neural Network Inference arXiv 2021 Scholar | Foundations + taxonomy Reviews quantization design choices, mixed precision and the trade-offs between model accuracy and efficient inference. |
| Binary Neural Networks: A Survey Pattern Recognition 2020 Scholar | Binary networks Surveys binary network representations, training methods and applications. |
| A Survey of Low-bit Large Language Models: Basics, Systems, and Algorithms Neural Networks 2025 Scholar | LLM algorithms + systems Connects low-bit LLM algorithms with numerical formats and inference systems. |
| Low-bit Model Quantization for Deep Neural Networks: A Survey arXiv 2025 Scholar | Broad low-bit methods Maps low-bit quantization methods across neural network architectures and applications. |
Quantization white paper · Authors and BibTeX
Markus Nagel, Marios Fournarakis, Rana Ali Amjad, Yelysei Bondarenko, Mart van Baalen, Tijmen Blankevoort
@article{nagel2021white,
  title={A White Paper on Neural Network Quantization},
  author={Nagel, Markus and Fournarakis, Marios and Amjad, Rana Ali and Bondarenko, Yelysei and van Baalen, Mart and Blankevoort, Tijmen},
  journal={arXiv preprint arXiv:2106.08295},
  year={2021}
}
Quantization methods survey · Authors and BibTeX
Amir Gholami, Sehoon Kim, Zhen Dong, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer
@article{gholami2021survey,
  title={A Survey of Quantization Methods for Efficient Neural Network Inference},
  author={Gholami, Amir and Kim, Sehoon and Dong, Zhen and Yao, Zhewei and Mahoney, Michael W. and Keutzer, Kurt},
  journal={arXiv preprint arXiv:2103.13630},
  year={2021}
}
Binary networks survey · Authors, overview and BibTeX
Haotong Qin, Ruihao Gong, Xianglong Liu, Xiao Bai, Jingkuan Song, Nicu Sebe
@article{Qin:pr20_bnn_survey,
    title = "Binary neural networks: A survey",
    author = "Haotong Qin and Ruihao Gong and Xianglong Liu and Xiao Bai and Jingkuan Song and Nicu Sebe",
    journal = "Pattern Recognition",
    volume = "105",
    pages = "107281",
    year = "2020"
}
Low-bit LLM survey · Authors, overview and BibTeX
Ruihao Gong, Yifu Ding, Zining Wang, Chengtao Lv, Xingyu Zheng, Jinyang Du, Yang Yong, Shiqiao Gu, Haotong Qin, Jinyang Guo, Dahua Lin, Michele Magno, Xianglong Liu
@article{gong2025survey,
  title={A survey of low-bit large language models: Basics, systems, and algorithms},
  author={Gong, Ruihao and Ding, Yifu and Wang, Zining and Lv, Chengtao and Zheng, Xingyu and Du, Jinyang and Yong, Yang and Gu, Shiqiao and Qin, Haotong and Guo, Jinyang and Lin, Dahua and Magno, Michele and Liu, Xianglong},
  journal={Neural Networks},
  pages={107856},
  year={2025}
}
Low-bit model survey · Authors, overview and BibTeX
Kai Liu, Qian Zheng, Kaiwen Tao, Zhiteng Li, Haotong Qin, Wenbo Li, Yong Guo, Xianglong Liu, Linghe Kong, Guihai Chen, Yulun Zhang, Xiaokang Yang
@article{liu2025low,
  title={Low-bit Model Quantization for Deep Neural Networks: A Survey},
  author={Liu, Kai and Zheng, Qian and Tao, Kaiwen and Li, Zhiteng and Qin, Haotong and Li, Wenbo and Guo, Yong and Liu, Xianglong and Kong, Linghe and Chen, Guihai and Zhang, Yulun and Yang, Xiaokang},
  journal={arXiv preprint arXiv:2505.05530},
  year={2025}
}
Papers by Year
All paper titles and links are kept in this README. Published work is grouped by venue year where verified; otherwise the recorded preprint year is used. Representative works, benchmarks and surveys also appear here for chronological browsing. Within each year, entries are grouped by conference or journal, with preprints at the end.
2026
- [AAAI] First-Order Error Matters: Accurate Compensation for Quantized Large Language Models [code]
- [AAAI] TR-DQ: Time-Rotation Diffusion Quantization
- [CVPR Findings] Q-MambaIR: Accurate Quantized Mamba for Efficient Image Restoration
- [EMNLP] All for 1-Bit: Towards Genuine 1-Bit Post-Training Quantization for LLMs [Scholar]
- [EMNLP] Colla-Q: Toward Collaborative Experts in MoE Quantization via Minimax Precision Balancing [code]
- [ICCAD] Interface-Aware KV Cache Quantization for Dense On-Chip NVM in Long-Context LLM Decoding [Scholar]
- [ICLR] PT²-LLM: Post-Training Ternarization for Large Language Models [code]
- [ICLR] Quant-dLLM: Post-Training Extreme Low-Bit Quantization for Diffusion Large Language Models
- [ICLR] DVD-Quant: Data-free Video Diffusion Transformers Quantization
- [ICLR] Q&C: When Quantization Meets Cache in Efficient Generation
- [ICLR] Quantized Visual Geometry Grounded Transformer
- [ICLR] Post-Training Quantization for Video Matting
- [ICLR] QVGen: Pushing the Limit of Quantized Video Generative Models
- [ICLR] QuantSparse: Comprehensively Compressing Video Diffusion Transformer with Model Quantization and Attention Sparsification [code]
- [ICLR] TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate
- [ICLR] Optimal Brain Restoration for Joint Quantization and Sparsification of LLMs [code]
- [ICLR] AnyBCQ: Hardware Efficient Flexible Binary-Coded Quantization for Multi-Precision LLMs [code]
- [ICLR] Tequila: Deadzone-free Ternary Quantization for Large Language Models
- [ICLR] LogART: Pushing the Limit of Efficient Logarithmic Post-Training Quantization [code]
- [ICLR] ParoQuant: Pairwise Rotation Quantization for Efficient Reasoning LLM Inference [code]
- [ICLR] Improving Block-Wise LLM Quantization by 4-bit Generalized Normal Float Formats
- [ICLR] Channel-Aware Mixed-Precision Quantization for Efficient Long-Context Inference
- [ICLR] CodeQuant: Unified Clustering and Quantization for Enhanced Outlier Smoothing in Low-Precision Mixture-of-Experts
- [ICLR] QeRL: Beyond Efficiency - Quantization-enhanced Reinforcement Learning for LLMs [code]
- [ICLR] AutoQVLA: Not All Channels Are Equal in Vision-Language-Action Model's Quantization
- [ICLR] Achieving low-bit Muon through subspace preservation and grid quantization
- [ICLR] Shift-and-Sum Quantization for Visual Autoregressive Models
- [ICLR] Inlier-Centric Post-Training Quantization for Object Detection Models
- [ICLR] Efficient Quantization of Mixture-of-Experts with Theoretical Generalization Guarantees
- [ICLR] BBQ: Boosting Quantization Entropy with Bell Box Quantization
- [ICLR] Improving Block-Wise LLM Quantization by 4-bit Block-Wise Optimal Float (BOF4): Analysis and Variations [code]
- [ICLR] Learning under Quantization for High-Dimensional Linear Regression
- [ICLR] On-the-Fly Adaptation to Quantization: Configuration-Aware LoRA for Efficient Fine-Tuning of Quantized LLMs
- [ICLR] Bridging the Gap Between Promise and Performance for FP4 Quantization [code]
- [ICLR] KBVQ-MoE: KLT-guided SVD with Bias-Corrected Vector Quantization for MoE Large Language Models [code]
- [ICLR] UniQL: Unified Quantization and Low-rank Compression for Adaptive Edge LLMs [code]
- [ICLR] The Lattice Geometry of Neural Network Quantization: A Short Equivalence Proof of GPTQ and Babai's algorithm
- [ICLR] DPQuant: Efficient and Private Model Training via Dynamic Quantization Scheduling
- [ICLR] Towards Quantization-Aware Training for Ultra-Low-Bit Reasoning LLMs
- [ICLR] A Convergence Analysis of Adaptive Optimizers under Floating-point Quantization
- [ICLR] Training Dynamics Impact Post-Training Quantization Robustness [code]
- [ICLR] SSDi8: Accurate and Efficient 8-bit Quantization for State Space Duality
- [ICLR] The Geometry of LLM Quantization: GPTQ as Babai's Nearest Plane Algorithm
- [ICLR] PTQ4ARVG: Post-Training Quantization for AutoRegressive Visual Generation Models [code]
- [ICLR] QWHA: Quantization-Aware Walsh-Hadamard Adaptation for Parameter-Efficient Fine-Tuning on Large Language Models [code]
- [ICLR] Gradient-Aligned Calibration for Post-Training Quantization of Diffusion Models
- [ICLR] SERQ: Saliency-Aware Low-Rank Error Reconstruction for LLM Quantization
- [ICLR] Compute-Optimal Quantization-Aware Training
- [ICLR] PM-KVQ: Progressive Mixed-precision KV Cache Quantization for Long-CoT LLMs [code]
- [ICLR] Beyond Outliers: A Study of Optimizers Under Quantization
- [ICLR] Qronos: Correcting the Past by Shaping the Future... in Post-Training Quantization
- [ICLR] MicroMix: Efficient Mixed-Precision Quantization with Microscaling Formats for Large Language Models [code]
- [ICLR] TurboBoA: Faster and Exact Attention-aware Quantization without Backpropagation
- [ICLR] Beyond Uniformity: Sample and Frequency Meta Weighting for Post-Training Quantization of Diffusion Models
- [ICLR] Rethinking Residual Errors in Compensation-based LLM Quantization
- [ICLR] SPR²Q: Static Priority-based Rectifier Routing Quantization for Image Super-Resolution [code]
- [ICLR] STaMP: Sequence Transformation and Mixed Precision for Low-Precision Activation Quantization
- [Visual Intelligence] An Empirical Study of Qwen3 Quantization [code]
- [arXiv] EdgeRazor: A Lightweight Framework for Large Language Models via Mixed-Precision Quantization-Aware Distillation [code]
- [arXiv] Sherry: Hardware-Efficient 1.25-Bit Ternary Quantization via Fine-grained Sparsification [code]
- [arXiv] D²Quant: Accurate Low-bit Post-Training Weight Quantization for LLMs
- [arXiv] QuantLRM: Quantization of Large Reasoning Models via Fine-Tuning Signals
- [arXiv] SliderQuant: Accurate Post-Training Quantization for LLMs
- [arXiv] What Makes Low-Bit Quantization-Aware Training Work for Reasoning LLMs? A Systematic Study
- [arXiv] OneComp: One-Line Revolution for Generative AI Model Compression [Code]
2025
- [AAAI] MPQ-DM: Mixed Precision Quantization for Extremely Low Bit Diffusion Models
- [AAAI] JAQ: Joint Efficient Architecture Design and Low-Bit Quantization
- [AAAI] OAC: Output-adaptive Calibration for Accurate Post-Training Quantization of LLMs
- [AAAI] Optimizing Quantized Diffusion Models via Distillation with Decay Timestep-Aware Loss
- [AAAI] Quantifiable Quantization Sensitivity of Diffusion Models
- [AAAI] TCAQ-DM: Timestep-Channel Adaptive Quantization for Diffusion Models
- [AAAI] Thinking in Granularity: Dynamic Quantization for Image Super-Resolution by Intriguing Multi-Granularity Clues [code]
- [AAAI] D2-DPM: Dual Denoising for Quantized Diffusion Probabilistic Models [code]
- [ACL] EfficientQAT: Efficient Quantization-Aware Training for Large Language Models [code]
- [ACL] L4Q: Parameter Efficient Quantization-Aware Fine-Tuning on Large Language Models
- [ACL] MoQAE: Mixed-Precision Quantization for Long-Context LLM Inference via Mixture of Quantization-Aware Experts
- [ACL] Outlier-Safe Pre-Training for Robust 4-Bit Quantization of Large Language Models
- [ACL] PTQ1.61: Push the Real Limit of Extremely Low-Bit Post-Training Quantization Methods for Large Language Models [code]
- [ACL] Unifying Uniform and Binary-coding Quantization for Accurate Compression of Large Language Models
- [ACL] “Give Me BF16 or Give Me Death”? Accuracy-Performance Trade-Offs in LLM Quantization
- [ACL Findings] Achieving Binary Weight and Activation for LLMs using Post-Training Quantization
- [ACM MM] DilateQuant: Accurate and Efficient Quantization-Aware Training for Diffusion Models via Weight Dilation
- [ACM MM] Learning Binarized Representations with Pseudo-positive Distillation
- [ACM MM] MQuant: Unleashing the Inference Potential of Multimodal Large Language Models with Post-Training Quantization
- [ACM MM] Pushing the Limit of Binarized Neural Network for Image Super Resolution with Smooth Information Transmission
- [ACM MM] Quantization Meets OOD: Generalizable Quantization-aware Training from a Flatness Perspective
- [CVPR] PassionSR: Post-Training Quantization with Adaptive Scale in One-Step Diffusion based Image Super-Resolution [code]
- [CVPR] Quantization without Tears
- [CVPR] APHQ-ViT: Post-Training Quantization with Average Perturbation Hessian Based Reconstruction for Vision Transformer [code]
- [EMNLP] AMQ: Enabling AutoML for Mixed-precision Weight-Only Quantization of Large Language Models
- [EMNLP] Does quantization affect models' performance on long-input and long-output tasks?
- [EMNLP Findings] KurTail: Kurtosis-based LLM Quantization
- [ICCV] Scheduling Weight Transitions for Quantization-Aware Training [code]
- [ICCV] Task-Specific Zero-shot Quantization-Aware Training for Object Detection [code]
- [ICCV] OuroMamba: A Data-Free Quantization Framework for Vision Mamba
- [ICCV] FedWSQ: Efficient Federated Learning with Weight Standardization and Distribution-Aware Non-Uniform Quantization [code]
- [ICCV] Semantic Alignment and Reinforcement for Data-Free Quantization of Vision Transformers [code]
- [ICCV] QuantCache: Adaptive Importance-Guided Quantization with Hierarchical Latent and Layer Caching for Video Generation [code]
- [ICCV] MixA-Q: Revisiting Activation Sparsity for Vision Transformers from a Mixed-Precision Quantization Perspective
- [ICCV] DMQ: Dissecting Outliers of Diffusion Models for Post-Training Quantization [code]
- [ICCV] AHCPTQ: Accurate and Hardware-Compatible Post-Training Quantization for Segment Anything Model
- [ICCV] MSQ: Memory-Efficient Bit Sparsification Quantization
- [ICCV] QuEST: Low-bit Diffusion Model Quantization via Efficient Selective Finetuning [code]
- [ICLR] ARB-LLM: Alternating Refined Binarizations for Large Language Models [code]
- [ICLR] BinaryDM: Accurate Weight Binarization for Efficient Diffusion Models [code]
- [ICLR] CBQ: Cross-Block Quantization for Large Language Models
- [ICLR] DGQ: Distribution-Aware Group Quantization for Text-to-Image Diffusion Models
- [ICLR] LeanQuant: Accurate and Scalable Large Language Model Quantization with Loss-error-aware Grid
- [ICLR] OSTQuant: Refining Large Language Model Quantization with Orthogonal and Scaling Transformations for Better Distribution Fitting [code]
- [ICLR] QERA: an Analytical Framework for Quantization Error Reconstruction [code]
- [ICLR] SpinQuant: LLM Quantization with Learned Rotations [code]
- [ICLR] SVDQuant: Absorbing Outliers by Low-Rank Component for 4-Bit Diffusion Models [code]
- [ICLR] ViDiT-Q: Efficient and Accurate Quantization of Diffusion Transformers for Image and Video Generation [code]
- [ICLR] SynQ: Accurate Zero-shot Quantization by Synthesis-aware Fine-tuning [code]
- [ICML] Q-VDiT: Towards Accurate Quantization and Distillation of Video-Generation Diffusion Transformers [code]
- [ICML] SliM-LLM: Salience-Driven Mixed-Precision Quantization for Large Language Models [code]
- [ICML] FlatQuant: Flatness Matters for LLM Quantization [code]
- [ICML] RoSTE: An Efficient Quantization-Aware Supervised Fine-Tuning Approach for Large Language Models [code]
- [ICML] GANQ: GPU-Adaptive Non-Uniform Quantization for Large Language Models
- [ICML] Modulated Diffusion: Accelerating Generative Modeling with Modulated Quantization [code]
- [ICML] GuidedQuant: Large Language Model Quantization via Exploiting End Loss Guidance [code]
- [ICML] ResQ: Mixed-Precision Quantization of Large Language Models with Low-Rank Residuals [code]
- [ICML] MxMoE: Mixed-precision Quantization for MoE with Accuracy and Performance Co-Design [code]
- [ICML] Learning from Loss Landscape: Generalizable Mixed-Precision Quantization via Adaptive Sharpness-Aware Gradient Aligning
- [ICML] PARQ: Piecewise-Affine Regularized Quantization [code]
- [ICML] Quamba2: A Robust and Scalable Post-training Quantization Framework for Selective State Space Models [code]
- [ICML] LRA-QViT: Integrating Low-Rank Approximation and Quantization for Robust and Efficient Vision Transformers
- [ICML] BoA: Attention-aware Post-training Quantization without Backpropagation
- [ICML] MoEQuant: Enhancing Quantization for Mixture-of-Experts Large Language Models via Expert-Balanced Sampling and Affinity Guidance [code]
- [ICML] NestQuant: nested lattice quantization for matrix products and LLMs
- [ICML] Q-resafe: Assessing Safety Risks and Quantization-aware Safety Patching for Quantized Large Language Models [code]
- [ICML] SLiM: One-shot Quantization and Sparsity with Low-rank Approximation for LLM Weight Compression [code]
- [ICML] QT-DoG: Quantization-Aware Training for Domain Generalization [code]
- [ICML] Matryoshka Quantization
- [ICML] Merge-Friendly Post-Training Quantization for Multi-Target Domain Adaptation [code]
- [ICML] Layer-wise Quantization for Quantized Optimistic Dual Averaging
- [ICML] Outlier-Aware Post-Training Quantization for Discrete Graph Diffusion Models
- [ICML] BlockDialect: Block-wise Fine-grained Mixed Format Quantization for Energy-Efficient LLM Inference
- [ICML] GPTAQ: Efficient Finetuning-Free Quantization with Asymmetric Calibration [code]
- [ICML] Optimizing Large Language Model Training Using FP4 Quantization
- [ICML] SKIM: Any-bit Quantization Pushing The Limits of Post-Training Quantization
- [ICML] SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization [code]
- [MLSys] QServe: W4A8KV4 Quantization and System Co-design for Efficient LLM Serving [code]
- [Neural Networks] A Survey of Low-bit Large Language Models: Basics, Systems, and Algorithms
- [NeurIPS] S²Q-VDiT: Accurate Quantized Video Diffusion Transformer with Salient Data and Sparse Token Distillation [code]
- [NeurIPS] DartQuant: Efficient Rotational Distribution Calibration for LLM Quantization [code]
- [NeurIPS] A Double Normalization Approach for Calibration-Free Low-Bit KV Cache Quantization
- [NeurIPS] Binary Quadratic Quantization: Beyond First-Order Quantization for Real-Valued Matrix Compression
- [NeurIPS] Learning Grouped Lattice Vector Quantizers for Low-Bit Large Language Models
- [NeurIPS] LittleBit: Ultra Low-Bit Quantization via Latent Factorization
- [NeurIPS] ParetoQ: Improving Scaling Laws in Extremely Low-bit LLM Quantization
- [NeurIPS] Q-Palette: Fractional-Bit Quantizers Toward Optimal Weight-Only Post-Training Quantization
- [NeurIPS] Wavelet-Enhanced High-Fidelity 1-Bit Quantization for LLMs
- [NeurIPS] Quantization Error Propagation: Revisiting Layer-Wise Post-Training Quantization [Code]
- [NeurIPS] QBasicVSR: Temporal Awareness Adaptation Quantization for Video Super-Resolution
- [NeurIPS] Point4Bit: Post Training 4-bit Quantization for Point Cloud 3D Detection
- [NeurIPS] PMQ-VE: Progressive Multi-Frame Quantization for Video Enhancement [code]
- [NeurIPS] VETA-DiT: Variance-Equalized and Temporally Adaptive Quantization for Efficient 4-bit Diffusion Transformers
- [NeurIPS] LoTA-QAF: Lossless Ternary Adaptation for Quantization-Aware Fine-Tuning [code]
- [NeurIPS] Efficient Multi-bit Quantization Network Training via Weight Bias Correction and Bit-wise Coreset Sampling
- [NeurIPS] Efficient and Generalizable Mixed-Precision Quantization via Topological Entropy
- [NeurIPS] QSCA: Quantization with Self-Compensating Auxiliary for Monocular Depth Estimation
- [SIGMOD] Practical and Asymptotically Optimal Quantization of High-Dimensional Vectors in Euclidean Space for Approximate Nearest Neighbor Search [code]
- [TPAMI] BiVM: Accurate Binarized Neural Network for Efficient Video Matting
- [arXiv] BitNet b1.58 2B4T Technical Report [code]
- [arXiv] Low-bit Model Quantization for Deep Neural Networks: A Survey
2024
- [AAAI] Agile-Quant: Activation-Guided Quantization for Faster Inference of LLMs on the Edge
- [AAAI] AQ-DETR: Low-Bit Quantized Detection Transformer with Auxiliary Queries
- [AAAI] Bi-ViT: Pushing the Limit of Vision Transformer Quantization
- [AAAI] Exploring Post-training Quantization in LLMs from Comprehensive Study to Low Rank Compensation
- [AAAI] Make RepVGG Greater Again: A Quantization-Aware Approach
- [AAAI] MetaMix: Meta-State Precision Searcher for Mixed-Precision Activation Quantization
- [AAAI] Norm Tweaking: High-Performance Low-Bit Quantization of Large Language Models
- [AAAI] OWQ: Outlier-Aware Weight Quantization for Efficient Fine-Tuning and Inference of Large Language Models
- [AAAI] PTMQ: Post-training Multi-Bit Quantization of Neural Networks
- [AAAI] Robustness-Guided Image Synthesis for Data-Free Quantization
- [AAAI] What Makes Quantization for Large Language Model Hard? An Empirical Study from the Lens of Perturbation
- [AAAI] One-Step Forward and Backtrack: Overcoming Zig-Zagging in Loss-Aware Quantization Training
- [ACL] Improving Conversational Abilities of Quantized Large Language Models via Direct Preference Alignment
- [ACL Findings] DB-LLM: Accurate Dual-Binarization for Efficient LLMs
- [ACL Findings] A Comprehensive Evaluation of Quantization Strategies for Large Language Models
- [ACL Findings] AFPQ: Asymmetric Floating Point Quantization for LLMs [code]
- [ACL Findings] LLM-QAT: Data-Free Quantization Aware Training for Large Language Models
- [ACM MM] Advancing Multimodal Large Language Models with Quantization-Aware Scale Learning Based on Warmup
- [CVPR] Data-Free Quantization via Pseudo-label Filtering
- [CVPR] Enhancing Post-training Quantization Calibration through Contrastive Learning
- [CVPR] Instance-Aware Group Quantization for Vision Transformers
- [CVPR] Mixed-Precision Quantization for Federated Learning on Resource-Constrained Heterogeneous Devices
- [CVPR] PTQ4SAM: Post-Training Quantization for Segment Anything
- [CVPR] Reg-PTQ: Regression-specialized Post-training Quantization for Fully Quantized Object Detector
- [CVPR] Retraining-Free Model Quantization via One-Shot Weight-Coupling Learning
- [CVPR] TFMQ-DM: Temporal Feature Maintenance Quantization for Diffusion Models
- [CVPR] Towards Accurate Post-training Quantization for Diffusion Models
- [ECCV] AdaLog: Post-Training Quantization for Vision Transformers with Adaptive Logarithm Quantizer
- [ECCV] CLAMP-ViT: Contrastive Data-Free Learning for Adaptive Post-Training Quantization of ViTs
- [ECCV] Memory-Efficient Fine-Tuning for Quantized Diffusion Model
- [ECCV] MetaAug: Meta-Data Augmentation for Post-Training Quantization
- [ECCV] MixDQ: Memory-Efficient Few-Step Text-to-Image Diffusion Models with Metric-Decoupled Mixed Precision Quantization
- [ECCV] Overcoming Distribution Mismatch in Quantizing Image Super-Resolution Networks
- [ECCV] Post-training Quantization with Progressive Calibration and Activation Relaxing for Text-to-Image Diffusion Models
- [ECCV] PQ-SAM: Post-training Quantization for Segment Anything Model
- [ECCV] Timestep-Aware Correction for Quantized Diffusion Models
- [ECCV] Towards Robust Full Low-bit Quantization of Super Resolution Networks
- [EMNLP] ApiQ: Finetuning of 2-Bit Quantized Large Language Model
- [EMNLP] Prefixing Attention Sinks can Mitigate Activation Outliers for Large Language Model Quantization
- [EMNLP] VPTQ: Extreme Low-bit Vector Post-Training Quantization for Large Language Models [code]
- [EMNLP Findings] ATQ: Activation Transformation for Weight-Activation Quantization of LLMs
- [EMNLP Findings] Fine-tuning Rotated Outlier-free LLMs for Effective Weight-Activation Quantization
- [EMNLP Findings] How Does Quantization Affect Multilingual LLMs?
- [EMNLP Findings] MobileQuant: Mobile-friendly Quantization for On-device Language Models
- [EMNLP Findings] QEFT: Quantization for Efficient Fine-Tuning of LLMs
- [EMNLP Industry] LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit
- [ICLR] AffineQuant: Affine Transformation Quantization for Large Language Models [code]
- [ICLR] EfficientDM: Efficient Quantization-Aware Fine-Tuning of Low-Bit Diffusion Models
- [ICLR] LiDAR-PTQ: Post-Training Quantization for Point Cloud 3D Object Detection
- [ICLR] LoftQ: LoRA-Fine-Tuning-aware Quantization for Large Language Models [code]
- [ICLR] LUT-GEMM: Quantized Matrix Multiplication based on LUTs for Efficient Inference in Large-Scale Generative Language Models
- [ICLR] OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models [code]
- [ICLR] PB-LLM: Partially Binarized Large Language Models [code]
- [ICLR] QA-LoRA: Quantization-Aware Low-Rank Adaptation of Large Language Models [code]
- [ICLR] QLLM: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models
- [ICLR] Rethinking Channel Dimensions to Isolate Outliers for Low-bit Weight Quantization of Large Language Models
- [ICLR] SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression [code]
- [ICML] BiLLM: Pushing the Limit of Post-Training Quantization for LLMs [code]
- [ICML] Compressing Large Language Models by Joint Sparsification and Quantization
- [ICML] Accurate LoRA-Finetuning Quantization of LLMs via Information Retention [code]
- [ICML] Flexible Residual Binarization for Image Super-Resolution
- [ICML] A2Q+: Improving Accumulator-Aware Weight Quantization
- [ICML] BiE: Bi-Exponent Block Floating-Point for Large Language Models Quantization
- [ICML] ERQ: Error Reduction for Post-Training Quantization of Vision Transformers
- [ICML] Evaluating Quantized Large Language Models [code]
- [ICML] Extreme Compression of Large Language Models via Additive Quantization [code]
- [ICML] FrameQuant: Flexible Low-Bit Quantization for Transformers
- [ICML] KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache [code]
- [ICML] LQER: Low-Rank Quantization Error Reconstruction for LLMs
- [ICML] Outlier-aware Slicing for Post-Training Quantization in Vision Transformer
- [ICML] Sharpness-Aware Data Generation for Zero-shot Quantization
- [ICML] SqueezeLLM: Dense-and-Sparse Quantization [code]
- [ICML] Learning from students: Applying t-distributions to explore accurate and efficient formats for llms [code]
- [ICML] Jetfire: Efficient and Accurate Transformer Pretraining with INT8 Data Flow and Per-Block Quantization
- [ICML] Reshape and Adapt for Output Quantization (RAOQ): Quantization-aware Training for In-memory Computing Systems
- [ICML] QuIP#: Even Better LLM Quantization with Hadamard Incoherence and Lattice Codebooks [code]
- [MLSys] AWQ: Activation-aware Weight Quantization for On-Device LLM Compression and Acceleration [code]
- [MLSys] Atom: Low-bit Quantization for Efficient and Accurate LLM Serving [code]
- [NeurIPS] BiDM: Pushing the Limit of Quantization for Diffusion Models
- [NeurIPS] Binarized Diffusion Model for Image Super-Resolution [code]
- [NeurIPS] 2DQuant: Low-bit Post-Training Quantization for Image Super-Resolution [code]
- [NeurIPS] BitsFusion: 1.99 bits Weight Quantization of Diffusion Model
- [NeurIPS] DuQuant: Distributing Outliers via Dual Transformation Makes Stronger Quantized LLMs
- [NeurIPS] KV Cache is 1 Bit Per Channel: Efficient Large Language Model Inference with Coupled Quantization
- [NeurIPS] KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization [code]
- [NeurIPS] PTQ4DiT: Post-training Quantization for Diffusion Transformers
- [NeurIPS] Q-VLM: Post-training Quantization for Large Vision-Language Models [code]
- [NeurIPS] QBB: Quantization with Binary Bases for LLMs
- [NeurIPS] ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification [code]
- [NeurIPS] QuaRot: Outlier-Free 4-Bit Inference in Rotated LLMs [code]
- [NeurIPS] Towards Next-Level Post-Training Quantization of Hyper-Scale Transformers [code]
- [NeurIPS] MagR: Weight Magnitude Reduction for Enhancing Post-Training Quantization [code]
- [NeurIPS] Exploiting LLM Quantization
- [NeurIPS] Efficient Multi-task LLM Quantization and Serving for Multiple LoRA Adapters
- [NeurIPS] QTIP: Quantization with Trellises and Incoherence Processing [code]
- [NeurIPS] Generalizing CNNs to graphs with learnable neighborhood quantization [code]
- [NeurIPS] SDP4Bit: Toward 4-bit Communication Quantization in Sharded Data Parallelism for LLM Training [code]
- [NeurIPS] Optimal and Approximate Adaptive Stochastic Quantization [code]
- [NeurIPS] Cherry on Top: Parameter Heterogeneity and Quantization in Large Language Models
- [NeurIPS] StepbaQ: Stepping backward as Correction for Quantized Diffusion Models
- [NeurIPS] PV-Tuning: Beyond Straight-Through Estimation for Extreme LLM Compression [code]
- [SIGMOD] RaBitQ: Quantizing High-Dimensional Vectors with a Theoretical Error Bound for Approximate Nearest Neighbor Search [code]
- [USENIX ATC] Quant-LLM: Accelerating the Serving of Large Language Models via FP6-Centric Algorithm-System Co-Design on Modern GPUs [code]
- [Visual Intelligence] An empirical study of LLaMA3 quantization: from LLMs to MLLMs [code]
- [arXiv] APTQ: Attention-aware Post-Training Mixed-Precision Quantization for Large Language Models
- [arXiv] EasyQuant: An Efficient Data-free Quantization Algorithm for LLMs
- [arXiv] EdgeQAT: Entropy and Distribution Guided Quantization-Aware Training for the Acceleration of Lightweight LLMs on the Edge [code]
- [arXiv] FlattenQuant: Breaking Through the Inference Compute-bound for Large Language Models with Per-tensor Quantization
- [arXiv] GPTVQ: The Blessing of Dimensionality for LLM Quantization [code]
- [arXiv] IntactKV: Improving Large Language Model Quantization by Keeping Pivot Tokens Intact
- [arXiv] OneBit: Towards Extremely Low-bit Large Language Models
- [arXiv] RepQuant: Towards Accurate Post-Training Quantization of Large Transformer Models via Scale Reparameterization
- [arXiv] The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
2023
- [AAAI] Fast and Accurate Binary Neural Networks Based on Depth-Width Reshaping
- [AAAI] OMPQ: Orthogonal Mixed Precision Quantization
- [AAAI] Quantized Feature Distillation for Network Quantization
- [AAAI] Resilient Binary Neural Network
- [AAAI] Rethinking Data-Free Quantization as a Zero-Sum Game
- [AAAI] Quantization-Aware Interval Bound Propagation for Training Certifiably Robust Quantized Neural Networks [code]
- [ACL] Boost Transformer-based Language Models with GPU-Friendly Sparsity and Quantization
- [ACL] PreQuant: A Task-agnostic Quantization Approach for Pre-trained Language Models
- [CVPR] ABCD : Arbitrary Bitwise Coefficient for De-quantization
- [CVPR] Adaptive Data-Free Quantization
- [CVPR] Bit-shrinking: Limiting Instantaneous Sharpness for Improving Post-training Quantization
- [CVPR] Boost Vision Transformer with GPU-Friendly Sparsity and Quantization
- [CVPR] GENIE: Show Me the Data for Quantization [code]
- [CVPR] Hard Sample Matters a Lot in Zero-Shot Quantization
- [CVPR] NIPQ: Noise proxy-based Integrated Pseudo-Quantization
- [CVPR] NoisyQuant: Noisy Bias-Enhanced Post-Training Activation Quantization for Vision Transformers
- [CVPR] One-Shot Model for Mixed-Precision Quantization
- [CVPR] PD-Quant: Post-Training Quantization Based on Prediction Difference Metric [code]
- [CVPR] Post-training Quantization on Diffusion Models [code]
- [CVPR] Q-DETR: An Efficient Low-Bit Quantized Detection Transformer [code]
- [CVPR] Regularized Vector Quantization for Tokenized Image Synthesis
- [CVPR] Solving Oscillation Problem in Post-Training Quantization Through a Theoretical Perspective [code]
- [CVPR] Toward Accurate Post-Training Quantization for Image Super Resolution
- [EMNLP] LLM-FP4: 4-Bit Floating-Point Quantized Transformers [code]
- [EMNLP] Outlier Suppression+: Accurate quantization of large language models by equivalent and optimal shifting and scaling
- [EMNLP] Revisiting Block-based Quantisation: What is Important for Sub-8-bit LLM Inference?
- [EMNLP] Watermarking LLMs with Weight Quantization [code]
- [EMNLP] Zero-Shot Sharpness-Aware Quantization for Pre-trained Language Models
- [ICCV] A2Q: Accumulator-Aware Quantization with Guaranteed Overflow Avoidance
- [ICCV] BiViT: Extremely Compressed Binary Vision Transformers
- [ICCV] Causal-DFQ: Causality Guided Data-Free Network Quantization [code]
- [ICCV] DenseShift: Towards Accurate and Efficient Low-Bit Power-of-Two Quantization
- [ICCV] EMQ: Evolving Training-free Proxies for Automated Mixed Precision Quantization
- [ICCV] EQ-Net: Elastic Quantization Neural Networks [code]
- [ICCV] Estimator Meets Equilibrium Perspective: A Rectified Straight Through Estimator for Binary Neural Networks Training [code]
- [ICCV] I-ViT: Integer-only Quantization for Efficient Vision Transformer Inference [code]
- [ICCV] Jumping through Local Minima: Quantization in the Loss Landscape of Vision Transformers
- [ICCV] Overcoming Forgetting Catastrophe in Quantization-Aware Training
- [ICCV] Q-diffusion: Quantizing Diffusion Models [code]
- [ICCV] QD-BEV: Quantization-aware View-guided Distillation for Multi-view 3D Object Detection
- [ICCV] RepQ-ViT: Scale Reparameterization for Post-Training Quantization of Vision Transformers [code]
- [ICCV] Unified Data-Free Compression: Pruning and Quantization without Fine-Tuning
- [ICLR] Analog Bits: Generating Discrete Data using Diffusion Models with Self-Conditioning
- [ICLR] GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers [code]
- [ICLR] PowerQuant: Automorphism Search For Non-Uniform Quantization
- [ICLR] Block and Subword-Scaling Floating-Point (BSFP) : An Efficient Non-Uniform Quantization For Low Precision Inference
- [ICLR] A^2Q: Aggregation-Aware Quantization for Graph Neural Networks
- [ICML] BiBench: Benchmarking and Analyzing Network Binarization [code]
- [ICML] Few-bit Backward: Quantized Gradients of Activation Functions for Memory Footprint Reduction [code]
- [ICML] FlexRound: Learnable Rounding based on Element-wise Division for Post-Training Quantization [code]
- [ICML] GPT-Zip: Deep Compression of Finetuned Large Language Models
- [ICML] Oscillation-free Quantization for Low-bit Vision Transformers [code]
- [ICML] QIGen: Generating Efficient Kernels for Quantized Inference on Large Language Models [code]
- [ICML] Quantized Distributed Training of Large Models with Convergence Guarantees
- [ICML] SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models [code]
- [ICML] The case for 4-bit precision: k-bit Inference Scaling Laws
- [ICML] Understanding Int4 Quantization for Language Models: Latency Speedup, Composability, and Failure Cases [arXiv] [Proceedings] [code]
- [IJCV] Distribution-sensitive Information Retention for Accurate Binary Neural Network
- [NeurIPS] BiMatting: Efficient Video Matting via Binarization [code]
- [NeurIPS] QuantSR: Accurate Low-bit Quantization for Efficient Image Super-Resolution [code]
- [NeurIPS] Binarized Spectral Compressive Imaging [code]
- [NeurIPS] Memory-Efficient Fine-Tuning of Compressed Large Language Models via sub-4-bit Integer Quantization
- [NeurIPS] PackQViT: Faster Sub-8-bit Vision Transformers via Full and Packed Quantization on the Mobile
- [NeurIPS] PTQD: Accurate Post-Training Quantization for Diffusion Models [code]
- [NeurIPS] Q-DM: An Efficient Low-bit Quantized Diffusion Model
- [NeurIPS] QLoRA: Efficient Finetuning of Quantized LLMs [code]
- [NeurIPS] QuIP: 2-Bit Quantization of Large Language Models With Guarantees [code]
- [NeurIPS] Temporal Dynamic Quantization for Diffusion Models
- [NeurIPS] TexQ: Zero-shot Network Quantization with Texture Feature Distribution Calibration
- [NeurIPS] Understanding Neural Network Binarization with Forward and Backward Proximal Quantizers
- [NeurIPS] REx: Data-Free Residual Quantization Error Expansion
- [NeurIPS] Intriguing Properties of Quantization at Scale
- [NeurIPS] Training Transformers with 4-bit Integers [code]
- [NeurIPS] Towards Efficient and Accurate Winograd Convolution via Full Quantization
- [NeurIPS] Pruning vs Quantization: Which is Better? [code]
- [TIP] MBFQuant: A Multiplier-Bitwidth-Fixed, Mixed-Precision Quantization Method for Mobile CNN-Based Applications
- [TNNLS] BiFSMNv2: Pushing Binary Neural Networks for Keyword Spotting to Real-Network Performance [code]
- [TPAMI] Diverse Sample Generation: Pushing the Limit of Generative Data-Free Quantization [code]
- [TPAMI] Optimization-Based Post-Training Quantization With Bit-Split and Stitching
- [TPAMI] Single-path Bit Sharing for Automatic Loss-aware Model Compression
- [Visual Intelligence] RobustMQ: Benchmarking Robustness of Quantized Models
- [arXiv] Efficient Post-training Quantization with FP8 Formats [code]
- [arXiv] QFT: Quantized Full-parameter Tuning of LLMs with Affordable Resources
- [arXiv] QMoE: Practical Sub-1-Bit Compression of Trillion-Parameter Models
- [arXiv] RPTQ: Reorder-based Post-training Quantization for Large Language Models [code]
- [arXiv] ZeroQuant-HERO: Hardware-Enhanced Robust Optimized Post-Training Quantization Framework for W8A8 Transformers
- [arXiv] BitNet: Scaling 1-bit Transformers for Large Language Models
- [arXiv] Microscaling Data Formats for Deep Learning [code]
2022
- [ACL] Compression of Generative Pre-trained Language Models via Quantization
- [ACM MM] Towards Accurate Post-Training Quantization for Vision Transformer
- [Applied Soft Computing] A neural network compression method based on knowledge-distillation and parameter quantization for the bearing fault diagnosis
- [ASE] QVIP: An ILP-based Formal Verification Approach for Quantized Neural Networks
- [CCF Transactions on High Performance Computing] An efficient segmented quantization for graph neural networks
- [CVPR] PokeBNN: A Binary Pursuit of Lightweight Accuracy [code]
- [CVPR] Data-Free Network Compression via Parametric Non-uniform Mixed Precision Quantization
- [CVPR] Instance-Aware Dynamic Neural Network Quantization
- [CVPR] IntraQ: Learning Synthetic Images With Intra-Class Heterogeneity for Zero-Shot Network Quantization [code]
- [CVPR] It's All In the Teacher: Zero-Shot Quantization Brought Closer to the Teacher [code]
- [CVPR] Learnable Lookup Table for Neural Network Quantization [code]
- [CVPR] Mr.BiQ: Post-Training Non-Uniform Quantization based on Minimizing the Reconstruction Error
- [CVPR] Nonuniform-to-Uniform Quantization: Towards Accurate Quantization via Generalized Straight-Through Estimation [code]
- [CVPR] RecDis-SNN: Rectifying Membrane Potential Distribution for Directly Training Spiking Neural Networks
- [CVPR Workshops] A Low Memory Footprint Quantized Neural Network for Depth Completion of Very Sparse Time-of-Flight Depth Maps
- [CVPR Workshops] Simulated Quantization, Real Power Savings
- [EANN] A Robust, Quantization-Aware Training Method for Photonic Neural Networks
- [ECCV] BASQ: Branch-wise Activation-clipping Search Quantization for Sub-4-bit Neural Networks [code]
- [ECCV] Mixed-Precision Neural Network Quantization via Learned Layer-Wise Importance [code]
- [ECCV] Neuromorphic Data Augmentation for Training Spiking Neural Networks. [code]
- [ECCV] Non-Uniform Step Size Quantization for Accurate Post-Training Quantization
- [ECCV] Patch Similarity Aware Data-Free Quantization for Vision Transformers [code]
- [ECCV] PTQ4ViT: Post-Training Quantization for Vision Transformers with Twin Uniform Quantization [code]
- [ECCV] RDO-Q: Extremely Fine-Grained Channel-Wise Quantization via Rate-Distortion Optimization
- [ECCV] Symmetry Regularization and Saturating Nonlinearity for Robust Quantization
- [ECCV] Towards Accurate Network Quantization with Equivalent Smooth Regularizer
- [ECCV] Weight Fixing Networks. [code]
- [ECCV] CADyQ: Content-Aware Dynamic Quantization for Image Super-Resolution
- [ECCV] Bitwidth-Adaptive Quantization-Aware Neural Network Training: A Meta-Learning Approach [code]
- [ECCV] Fine-grained Data Distribution Alignment for Post-Training Quantization [code]
- [Electronics] A Survey on Efficient Convolutional Neural Networks and Hardware Acceleration
- [ESE] DiverGet: a Search-Based Software Testing approach for Deep Neural Network Quantization assessment
- [FPGA] FILM-QNN: Efficient FPGA Acceleration of Deep Neural Networks with Intra-Layer, Mixed-Precision Quantization
- [ICCRD] Post Training Quantization after Neural Network
- [ICLR] BiBERT: Accurate Fully Binarized BERT. [code]
- [ICLR] 8-bit Optimizers via Block-wise Quantization [code]
- [ICLR] F8Net: Fixed-Point 8-bit Only Multiplication for Network Quantization
- [ICLR] Information Bottleneck: Exact Analysis of (Quantized) Neural Networks [code]
- [ICLR] Optimal ANN-SNN Conversion for High-accuracy and Ultra-low-latency Spiking Neural Networks
- [ICLR] QDrop: Randomly Dropping Quantization for Extremely Low-bit Post-Training Quantization [code]
- [ICLR] SQuant: On-the-Fly Data-Free Quantization via Diagonal Hessian Approximation. [code]
- [ICLR] Toward Efficient Low-Precision Training: Data Format Optimization and Hysteresis Quantization
- [ICLR] VC dimension of partially quantized neural networks in the overparametrized regime
- [ICML] Finding the Task-Optimal Low-Bit Sub-Distribution in Deep Neural Networks [code]
- [ICML] GACT: Activation Compressed Training for Generic Network Architectures [code]
- [ICML] Overcoming Oscillations in Quantization-Aware Training [code]
- [ICML] SDQ: Stochastic Differentiable Quantization with Mixed Precision
- [ICML] Optimal Clipping and Magnitude-aware Differentiation for Improved Quantization-aware Training
- [ICPR] Layer-Wise Data-Free CNN Compression
- [IEEE Internet of Things Journal] FedQNN: A Computation–Communication-Efficient Federated Learning Framework for IoT With Low-Bitwidth Neural Network Quantization
- [IJCAI] BiFSMN: Binary Neural Network for Keyword Spotting [code]
- [IJCAI] FQ-ViT: Post-Training Quantization for Fully Quantized Vision Transformer [code]
- [IJCAI] MultiQuant: Training Once for Multi-bit Quantization of Neural Networks
- [IJCAI] RAPQ: Rescuing Accuracy for Power-of-Two Low-bit Post-training Quantization [code]
- [IJCNN] Accuracy Evaluation of Transposed Convolution-Based Quantized Neural Networks
- [IJNS] Convolutional Neural Networks Quantization with Attention
- [Intelligent Automation & Soft Computing] A Resource-Efficient Convolutional Neural Network Accelerator Using Fine-Grained Logarithmic Quantization
- [ITSM] Edge–Artificial Intelligence-Powered Parking Surveillance With Quantized Neural Networks
- [LNAI] ECQ$^x$: Explainability-Driven Quantization for Low-Bit and Sparse DNNs
- [MICRO] ANT: Exploiting Adaptive Numerical Data Type for Low-bit Deep Neural Network Quantization
- [Neural Networks] Quantization-aware training for low precision photonic neural networks
- [NeurIPS] BiMLP: Compact Binary Architectures for Vision Multi-Layer Perceptrons [code]
- [NeurIPS] BiT: Robustly Binarized Multi-distilled Transformer [code]
- [NeurIPS] ClimbQ: Class Imbalanced Quantization Enabling Robustness on Efficient Inferences
- [NeurIPS] Entropy-Driven Mixed-Precision Quantization for Deep Network Design
- [NeurIPS] FP8 Quantization: The Power of the Exponent [code]
- [NeurIPS] Leveraging Inter-Layer Dependency for Post-Training Quantization
- [NeurIPS] LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale [code]
- [NeurIPS] Optimal Brain Compression: A Framework for Accurate Post-Training Quantization and Pruning [code]
- [NeurIPS] Q-ViT: Accurate and Fully Quantized Low-bit Vision Transformer [code]
- [NeurIPS] Redistribution of Weights and Activations for AdderNet Quantization
- [NeurIPS] Theoretically Better and Numerically Faster Distributed Optimization with Smoothness-Aware Quantization Techniques
- [NeurIPS] Towards Efficient Post-training Quantization of Pre-trained Language Models
- [NeurIPS] ZeroQuant: Efficient and Affordable Post-Training Quantization for Large-Scale Transformers [code]
- [Neurocomputing] EPQuant: A Graph Neural Network compression approach based on product quantization
- [PPoPP] QGTC: accelerating quantized graph neural networks via GPU tensor core
- [TCCN] Low-Bitwidth Convolutional Neural Networks for Wireless Interference Identification
- [TCSVT] An Efficient Implementation of Convolutional Neural Network With CLIP-Q Quantization on FPGA
- [TGARS] Accelerating Convolutional Neural Network-Based Hyperspectral Image Classification by Step Activation Quantization
- [tinyML Research Symposium] Power-of-Two Quantization for Low Bitwidth and Hardware Compliant Neural Networks
- [ACM Trans. Des. Autom. Electron. Syst.] Structured Dynamic Precision for Deep Neural Networks Quantization
- [TODAES] Dynamic Quantization Range Control for Analog-in-Memory Neural Networks Acceleration
- [arXiv] Edge Inference with Fully Differentiable Quantized Mixed Precision Neural Networks
- [arXiv] Neural network quantization with ai model efficiency toolkit (aimet)
- [arXiv] Q-ViT: Fully Differentiable Quantization for Vision Transformer
- [arXiv] QONNX: Representing Arbitrary-Precision Quantized Neural Networks
- [arXiv] Quantune: Post-training Quantization of Convolutional Neural Networks using Extreme Gradient Boosting for Fast Deployment
- [arXiv] Sub-8-Bit Quantization Aware Training for 8-Bit Neural Network Accelerator with On-Device Speech Recognition
- [arXiv] FP8 Formats for Deep Learning
2021
- [AAAI] Compressing Deep Convolutional Neural Networks by Stacking Low-Dimensional Binary Convolution Filters
- [AAAI] Distribution Adaptive INT8 Quantization for Training CNNs
- [AAAI] FracBits: Mixed Precision Quantization via Fractional Bit-Widths
- [AAAI] Memory and Computation-Efficient Kernel SVM via Binary Embedding and Ternary Coefficients
- [AAAI] OPQ: Compressing Deep Neural Networks with One-shot Pruning-Quantization
- [AAAI] Optimizing Information Theory Based Bitwise Bottlenecks for Efficient Mixed-Precision Activation Quantization
- [AAAI] Post-‐training Quantization with Multiple Points: Mixed Precision without Mixed Precision
- [AAAI] Scalable Verification of Quantized Neural Networks [code]
- [AAAI] Stochastic Precision Ensemble: Self‐Knowledge Distillation for Quantized Deep Neural Networks
- [AAAI] TRQ: Ternary Neural Networks with Residual Quantization
- [AAAI] Uncertainty Quantification in CNN through the Bootstrap of Convex Neural Networks
- [AAAI] Vector Quantized Bayesian Neural Network Inference for Data Streams
- [AAAI] Training Binary Neural Network without Batch Normalization for Image Super-Resolution
- [AAAI] SA-BNN: State-Aware Binary Neural Network
- [ACL] On the Distribution, Sparsity, and Inference-time Quantization of Attention Values in Transformers
- [ACM MM] Fully Quantized Image Super-Resolution Networks [code]
- [ACM MM] VQMG: Hierarchical Vector Quantised and Multi-hops Graph Reasoning for Explicit Representation Learning
- [CVPR Oral] Diversifying Sample Generation for Accurate Data-Free Quantization
- [CVPR] Binary Graph Neural Networks [code]
- [CVPR] Learnable Companding Quantization for Accurate Low-bit Neural Networks
- [CVPR] Network Quantization with Element-wise Gradient Scaling [code]
- [CVPR] Permute, Quantize, and Fine-tune: Efficient Compression of Neural Networks [code]
- [CVPR] S2-bnn: Bridging the gap between self-supervised real and 1-bit neural networks via guided distribution calibration [code]
- [CVPR] Zero-shot Adversarial Quantization [code]
- [CVPR] Automated Log-Scale Quantization for Low-Cost Deep Neural Networks
- [CVPR] QPP: Real-Time Quantization Parameter Prediction for Deep Neural Networks
- [ICCV] MixMix: All You Need for Data-Free Compression Are Feature and Data Mixing
- [ICLR] BiPointNet: Binary Neural Network for Point Clouds [code]
- [ICLR] BRECQ: Pushing the Limit of Post-Training Quantization by Block Reconstruction [code]
- [ICLR] BSQ: Exploring Bit-Level Sparsity for Mixed-Precision Neural Network Quantization [code]
- [ICLR] Degree-Quant: Quantization-Aware Training for Graph Neural Networks
- [ICLR] High-Capacity Expert Binary Networks [code]
- [ICLR] Incremental few-shot learning via vector quantization in deep embedded space
- [ICLR] Multi-Prize Lottery Ticket Hypothesis: Finding Accurate Binary Neural Networks by Pruning A Randomly Weighted Network [code]
- [ICLR] Neural gradients are near-lognormal: improved quantized and sparse training
- [ICLR] Reducing the Computational Cost of Deep Generative Models with Binary Neural Networks
- [ICLR] Simple Augmentation Goes a Long Way: ADRL for DNN Quantization
- [ICLR] Training with Quantization Noise for Extreme Model Compression [code]
- [ICLR] WrapNet: Neural Net Inference with Ultra-Low-Resolution Arithmetic
- [ICLR] Improving Post Training Neural Quantization: Layer-wise Calibration and Integer Programming [code]
- [ICML] How Do Adam and Training Strategies Help BNNs Optimization? [code]
- [ICML] ActNN: Reducing Training Memory Footprint via 2-Bit Activation Compressed Training [code]
- [ICML] Auto-NBA: Efficient and Effective Search Over the Joint Space of Networks, Bitwidths, and Accelerators [code]
- [ICML] Differentiable Dynamic Quantization with Mixed Precision and Adaptive Resolution
- [ICML] HAWQ-V3: Dyadic Neural Network Quantization [code]
- [ICML] I-BERT: Integer-only BERT Quantization [code]
- [ICML] Accurate Post Training Quantization With Small Calibration Sets
- [NeurIPS] A Winning Hand: Compressing Deep Networks Can Improve Out-of-Distribution Robustness [code]
- [NeurIPS] Divergence Frontiers for Generative Models: Sample Complexity, Quantization Effects, and Frontier Integrals
- [NeurIPS] Post-Training Quantization for Vision Transformer
- [NeurIPS] Post-Training Sparsity-Aware Quantization [code]
- [NeurIPS] Qimera: Data-free Quantization with Synthetic Boundary Supporting Samples [code]
- [NeurIPS] Qu-ANTI-zation: Exploiting Quantization Artifacts for Achieving Adversarial Outcomes
- [NeurIPS] VQ-GNN: A Universal Framework to Scale up Graph Neural Networks using Vector Quantization
- [NeurIPS] BatchQuant: Quantized-for-all Architecture Search with Robust Quantizer
- [NeurIPS Datasets and Benchmarks] MQBench: Towards Reproducible and Deployable Model Quantization Benchmark [code]
- [arXiv] A Survey of Quantization Methods for Efficient Neural Network Inference
- [arXiv] A White Paper on Neural Network Quantization
- [arXiv] Any-Precision Deep Neural Networks [code]
- [arXiv] ReCU: Reviving the Dead Weights in Binary Neural Networks [code]
2020
- [AAAI] HLHLp: Quantized Neural Networks Training for Reaching Flat Minima in Loss Surface
- [AAAI] Q-BERT: Hessian Based Ultra Low Precision Quantization of BERT
- [AAAI] Sparsity-Inducing Binarized Neural Networks
- [AAAI] Towards Accurate Low Bit-Width Quantization with Multiple Phase Adaptations
- [ACL] End to End Binarized Neural Networks for Text Classification
- [COOL CHIPS] A Novel In-DRAM Accelerator Architecture for Binary Neural Network
- [CVPR] Forward and Backward Information Retention for Accurate Binary Neural Networks [code]
- [CVPR] APQ: Joint Search for Network Architecture, Pruning and Quantization Policy [code]
- [CVPR] BiDet: An Efficient Binarized Object Detector. [code]
- [CVPR] Fixed-Point Back-Propagation Training
- [CVPR] Rotation Consistent Margin Loss for Efficient Low-Bit Face Recognition
- [CVPR] ZeroQ: A Novel Zero Shot Quantization Framework [code]
- [CVPR] AdaBits: Neural Network Quantization With Adaptive Bit-Widths [code]
- [CVPR] Adaptive Loss-aware Quantization for Multi-bit Networks [code]
- [CVPR Workshops] Low-Bit Quantization Needs Good Distribution
- [DATE] BNNsplit: Binarized Neural Networks for embedded distributed FPGA-based computing systems
- [DATE] OrthrusPE: Runtime Reconfigurable Processing Elements for Binary Neural Networks
- [DATE] PhoneBit: Efficient GPU-Accelerated Binary Neural Network Inference Engine for Mobile Phones
- [ECCV] PAMS: Quantized Super-Resolution via Parameterized Max Scale [code]
- [ECCV] BATS: Binary ArchitecTure Search
- [ECCV] Differentiable Joint Pruning and Quantization for Hardware Efficiency
- [ECCV] Generative Low-bitwidth Data Free Quantization [code]
- [ECCV] Learning Architectures for Binary Networks [code]
- [ECCV] PROFIT: A Novel Training Method for sub-4-bit MobileNet Models
- [ECCV] ProxyBNN: Learning Binarized Neural Networks via Proxy Matrices
- [ECCV] ReActNet: Towards Precise Binary Neural Network with Generalized Acti
Truncated — view the full README on GitHub.
Similar repos
Contributors
(top 30 of 34)