EDT-Former, a brige for LLM and graph data. Entropy-guided Dynamic Token Transformer for Graph-LLM alignment. Accepted at ICLR 2026.
Python
3
99 commits
updated May 13, 2026




Accepted at ICLR 2026
Authors: Zihao Jing, Qiuhao Zeng, Ruiyi Fang, Yan Sun, Boyu Wang, Pingzhao Hu
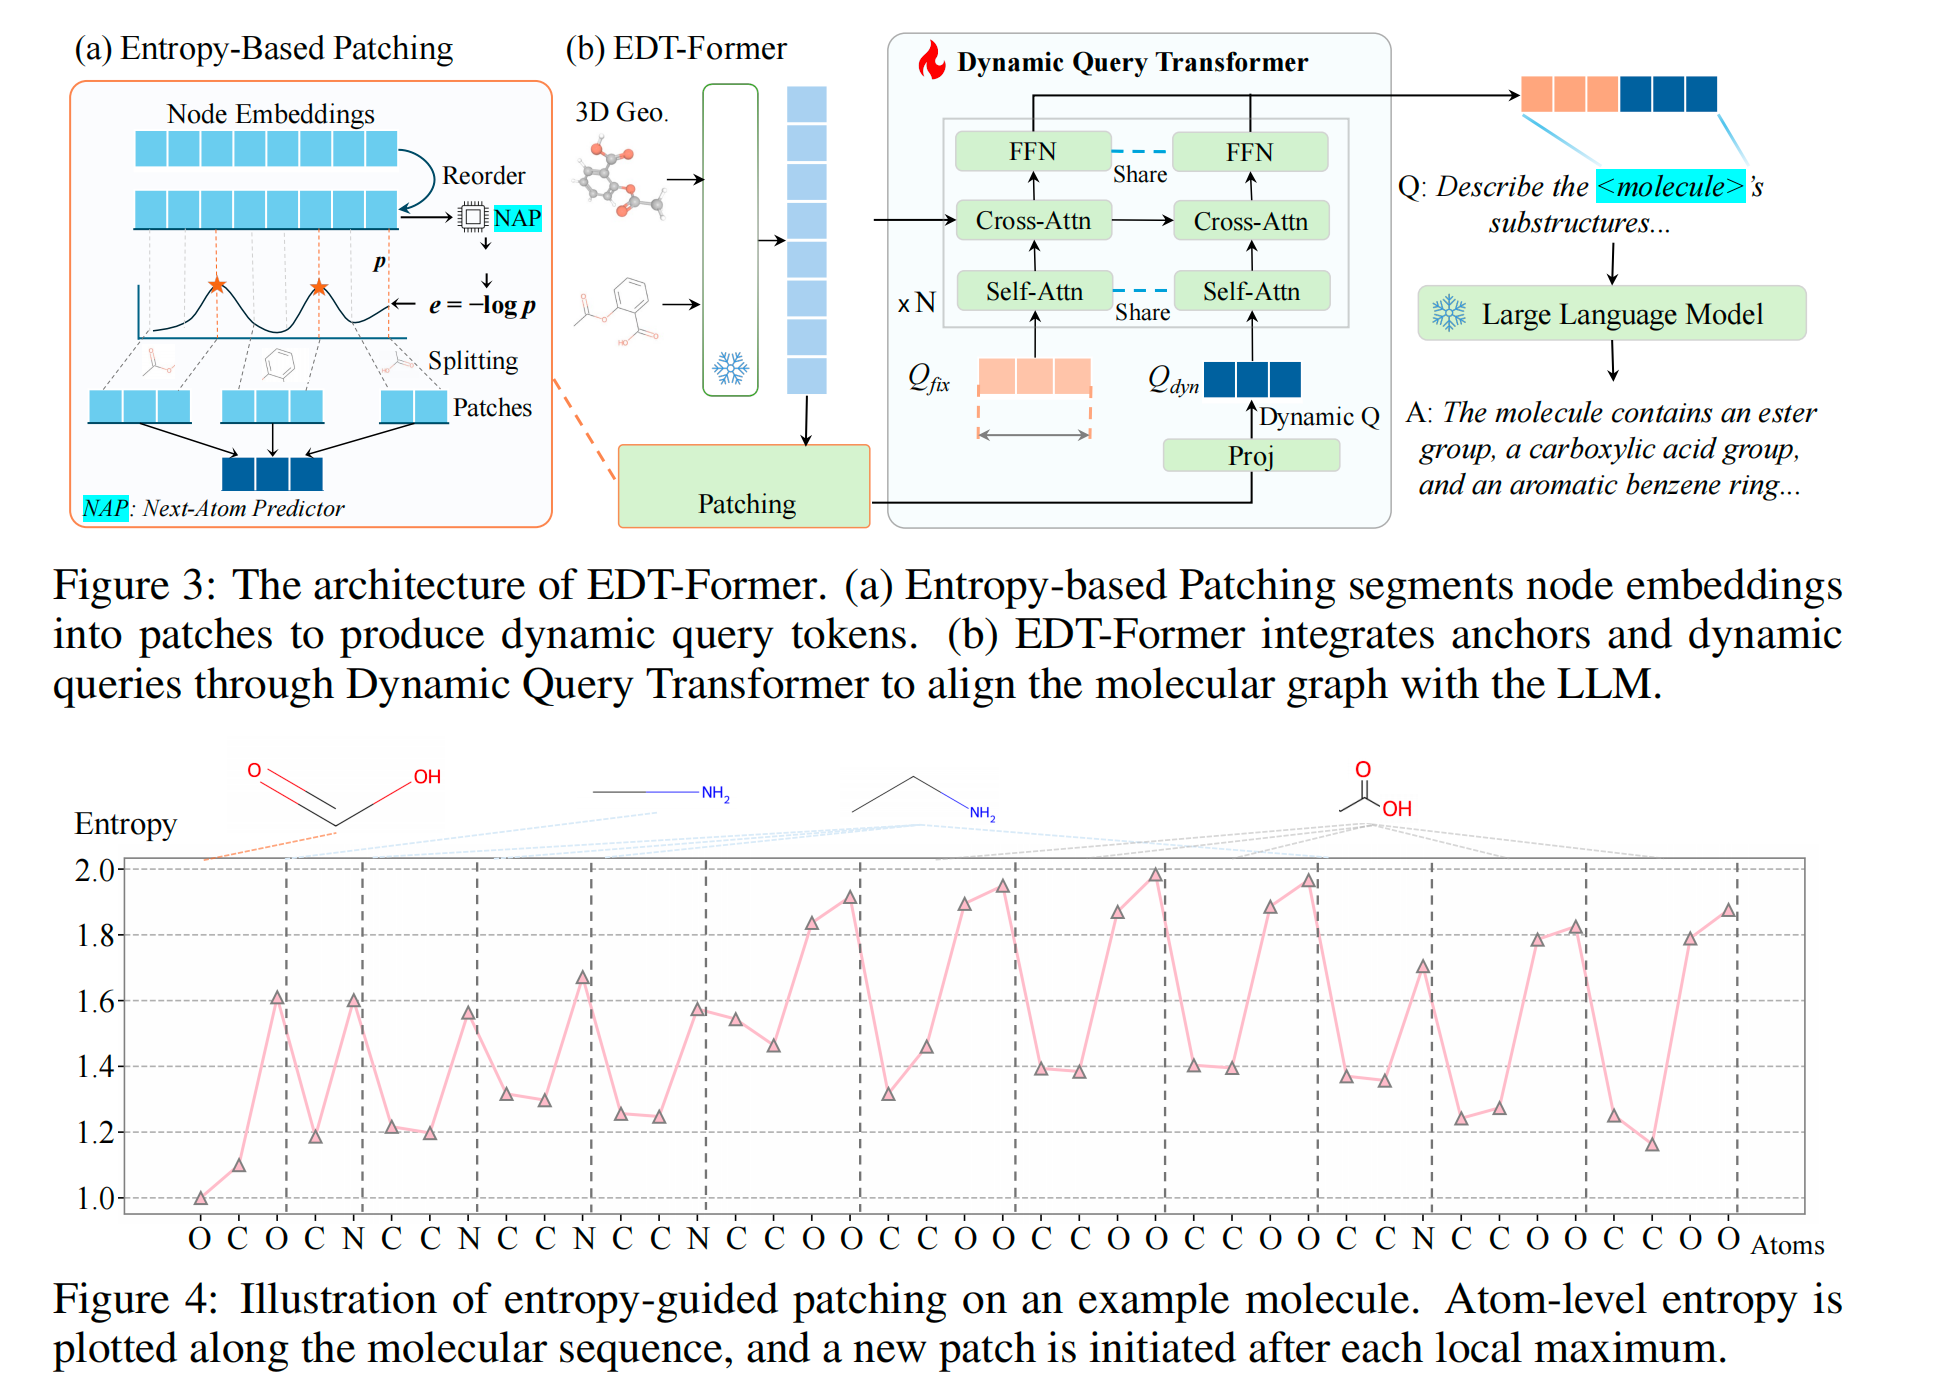
Molecular understanding is central to advancing areas such as scientific and drug discovery, yet Large Language Models (LLMs) struggle to understand molecular graphs effectively. Existing graph–LLM bridges often adapt the Q-Former-style connector with fixed-length static tokens, which is originally designed for vision tasks. These designs overlook stereochemistry and substructural context and typically require costly LLM-backbone fine-tuning, limiting efficiency and generalization. We introduce EDT-Former, an Entropy-guided Dynamic Token Transformer that generates tokens aligned with informative molecular patches, thereby preserving both local and global structural features for molecular graph understanding. Beyond prior approaches, EDT-Former enables alignment between frozen graph encoders and LLMs without tuning the LLM backbone (excluding the embedding layer), resulting in computationally efficient finetuning, and achieves state-of-the-art results on MoleculeQA, Mol-Instructions, and property prediction benchmarks (TDC, MoleculeNet), underscoring its effectiveness for scalable and generalizable multimodal molecular understanding.
Using environment.yml (Recommended)
conda env create -f environment.yml
conda activate edtformer
pip install --no-deps --no-build-isolation torch-geometric
pip install --no-deps --no-build-isolation flash-attn
pip install --no-deps --no-build-isolation torch-scatter
# The torch-scatter installation will take a long time, please kindly wait for it.
If you want to use Uni-Mol model as a encoder, please run:
git clone https://github.com/dptech-corp/Uni-Core.git
pip install --no-deps --no-build-isolation ./Uni-Core/
cp env.sh local.env.sh
# Edit local.env.sh: set HF_HOME, BASE_DIR, DATA_DIR, DATA_CACHE_DIR, CHECKPOINT_DIR
source local.env.sh
Pre-trained models and datasets are available on HuggingFace:
| Resource | HuggingFace Link | Description |
|---|---|---|
| Pretrain Data | zihaojing/EDT-Former-pretrain-data | Stage 1 encoder pretraining corpus (~12 GB, from PubChem) |
| SFT Data | zihaojing/EDT-Former-sft-data | Stage 2 instruction-tuning corpus (~12 GB, from Mol-LLaMA-Instruct) |
| Encoder | zihaojing/EDT-Former-encoder | Stage 1 EDT-Former encoder checkpoint (~699 MB) |
| Full Model | zihaojing/EDT-Former-model | Stage 2 full EDT-Former model (encoder + Llama-3.1-8B-Instruct, ~16 GB) |
Quick download:
from huggingface_hub import snapshot_download

# Download pretrained encoder (Stage 1)
snapshot_download("zihaojing/EDT-Former-encoder", local_dir="checkpoints/edt_former_s1_large/final_model")

# Download full model (Stage 2)
snapshot_download("zihaojing/EDT-Former-model", local_dir="checkpoints/edt_former_s2_large/final_model")

# Download pretraining data
snapshot_download("zihaojing/EDT-Former-pretrain-data", repo_type="dataset", local_dir="data/pretrain")

# Download SFT data
snapshot_download("zihaojing/EDT-Former-sft-data", repo_type="dataset", local_dir="data/finetune")
data/.configs/*/data_config*.yaml accept either a local path or a HuggingFace repo ID for preprocessed_data.scripts/preprocess/ and data_provider/preprocess/.The main entrypoint is runner/pretrain.py, launched via DeepSpeed.
deepspeed --include localhost:0 \
    runner/pretrain.py -- \
    --model_config_path    configs/stage1/model_config.yaml \
    --training_config_path configs/stage1/training_config.yaml \
    --data_config_path     configs/stage1/data_config_preprocessed.yaml
Or use the provided helper script (edit local.env.sh first):
bash scripts/training/pretraining.sh
The main entrypoint is runner/finetuning.py.
deepspeed --include localhost:0 \
    runner/finetuning.py \
    --model_config_path    configs/stage2/model_config.yaml \
    --training_config_path configs/stage2/training_config.yaml \
    --data_config_path     configs/stage2/data_config_preprocessed.yaml
Or:
bash scripts/training/finetuning.sh
Set the pretrained checkpoint path in model_config.yaml (model_name_or_path).
QA training uses runner/qa_finetuning.py. Example for MoleculeQA:
deepspeed --include localhost:0,1 \
    runner/qa_finetuning.py \
    --model_config_path    configs/qa/mol_qa/model_config.yaml \
    --training_config_path configs/qa/mol_qa/training_config.yaml \
    --data_config_path     configs/qa/mol_qa/data_config_preprocessed.yaml \
    --deepspeed_stage 2
Helper scripts for all downstream tasks are in scripts/qa/.
See LICENSE.
If you find this work helpful, please consider citing:
@inproceedings{jing2026edtformer,
  title={Entropy-Guided Dynamic Tokens for Graph-LLM Alignment in Molecular Understanding},
  author={Jing, Zihao and Zeng, Qiuhao and Fang, Ruiyi and Sun, Yan and Wang, Boyu and Hu, Pingzhao},
  booktitle={International Conference on Learning Representations (ICLR)},
  year={2026}
}
EDT-Former, a brige for LLM and graph data. Entropy-guided Dynamic Token Transformer for Graph-LLM alignment. Accepted at ICLR 2026.
Python
3
99 commits
updated May 13, 2026
Accepted at ICLR 2026
Authors: Zihao Jing, Qiuhao Zeng, Ruiyi Fang, Yan Sun, Boyu Wang, Pingzhao Hu
Molecular understanding is central to advancing areas such as scientific and drug discovery, yet Large Language Models (LLMs) struggle to understand molecular graphs effectively. Existing graph–LLM bridges often adapt the Q-Former-style connector with fixed-length static tokens, which is originally designed for vision tasks. These designs overlook stereochemistry and substructural context and typically require costly LLM-backbone fine-tuning, limiting efficiency and generalization. We introduce EDT-Former, an Entropy-guided Dynamic Token Transformer that generates tokens aligned with informative molecular patches, thereby preserving both local and global structural features for molecular graph understanding. Beyond prior approaches, EDT-Former enables alignment between frozen graph encoders and LLMs without tuning the LLM backbone (excluding the embedding layer), resulting in computationally efficient finetuning, and achieves state-of-the-art results on MoleculeQA, Mol-Instructions, and property prediction benchmarks (TDC, MoleculeNet), underscoring its effectiveness for scalable and generalizable multimodal molecular understanding.
Using environment.yml (Recommended)
conda env create -f environment.yml
conda activate edtformer
pip install --no-deps --no-build-isolation torch-geometric
pip install --no-deps --no-build-isolation flash-attn
pip install --no-deps --no-build-isolation torch-scatter
# The torch-scatter installation will take a long time, please kindly wait for it.
If you want to use Uni-Mol model as a encoder, please run:
git clone https://github.com/dptech-corp/Uni-Core.git
pip install --no-deps --no-build-isolation ./Uni-Core/
cp env.sh local.env.sh
# Edit local.env.sh: set HF_HOME, BASE_DIR, DATA_DIR, DATA_CACHE_DIR, CHECKPOINT_DIR
source local.env.sh
Pre-trained models and datasets are available on HuggingFace:
| Resource | HuggingFace Link | Description |
|---|---|---|
| Pretrain Data | zihaojing/EDT-Former-pretrain-data | Stage 1 encoder pretraining corpus (~12 GB, from PubChem) |
| SFT Data | zihaojing/EDT-Former-sft-data | Stage 2 instruction-tuning corpus (~12 GB, from Mol-LLaMA-Instruct) |
| Encoder | zihaojing/EDT-Former-encoder | Stage 1 EDT-Former encoder checkpoint (~699 MB) |
| Full Model | zihaojing/EDT-Former-model | Stage 2 full EDT-Former model (encoder + Llama-3.1-8B-Instruct, ~16 GB) |
Quick download:
from huggingface_hub import snapshot_download

# Download pretrained encoder (Stage 1)
snapshot_download("zihaojing/EDT-Former-encoder", local_dir="checkpoints/edt_former_s1_large/final_model")

# Download full model (Stage 2)
snapshot_download("zihaojing/EDT-Former-model", local_dir="checkpoints/edt_former_s2_large/final_model")

# Download pretraining data
snapshot_download("zihaojing/EDT-Former-pretrain-data", repo_type="dataset", local_dir="data/pretrain")

# Download SFT data
snapshot_download("zihaojing/EDT-Former-sft-data", repo_type="dataset", local_dir="data/finetune")
data/.configs/*/data_config*.yaml accept either a local path or a HuggingFace repo ID for preprocessed_data.scripts/preprocess/ and data_provider/preprocess/.The main entrypoint is runner/pretrain.py, launched via DeepSpeed.
deepspeed --include localhost:0 \
    runner/pretrain.py -- \
    --model_config_path    configs/stage1/model_config.yaml \
    --training_config_path configs/stage1/training_config.yaml \
    --data_config_path     configs/stage1/data_config_preprocessed.yaml
Or use the provided helper script (edit local.env.sh first):
bash scripts/training/pretraining.sh
The main entrypoint is runner/finetuning.py.
deepspeed --include localhost:0 \
    runner/finetuning.py \
    --model_config_path    configs/stage2/model_config.yaml \
    --training_config_path configs/stage2/training_config.yaml \
    --data_config_path     configs/stage2/data_config_preprocessed.yaml
Or:
bash scripts/training/finetuning.sh
Set the pretrained checkpoint path in model_config.yaml (model_name_or_path).
QA training uses runner/qa_finetuning.py. Example for MoleculeQA:
deepspeed --include localhost:0,1 \
    runner/qa_finetuning.py \
    --model_config_path    configs/qa/mol_qa/model_config.yaml \
    --training_config_path configs/qa/mol_qa/training_config.yaml \
    --data_config_path     configs/qa/mol_qa/data_config_preprocessed.yaml \
    --deepspeed_stage 2
Helper scripts for all downstream tasks are in scripts/qa/.
See LICENSE.
If you find this work helpful, please consider citing:
@inproceedings{jing2026edtformer,
  title={Entropy-Guided Dynamic Tokens for Graph-LLM Alignment in Molecular Understanding},
  author={Jing, Zihao and Zeng, Qiuhao and Fang, Ruiyi and Sun, Yan and Wang, Boyu and Hu, Pingzhao},
  booktitle={International Conference on Learning Representations (ICLR)},
  year={2026}
}



