
Handwritten Text Recognition and Character Detection
Python
174
36 commits
updated Sep 28, 2025
README
General Detection-based Text Line Recognition (DTLR)
NeurIPS 2024
Raphael Baena
Syrine Kalleli
Mathieu Aubry
Description
This repository is the official implementation for General Detection-based Text Line Recognition, the paper is available on arXiv.
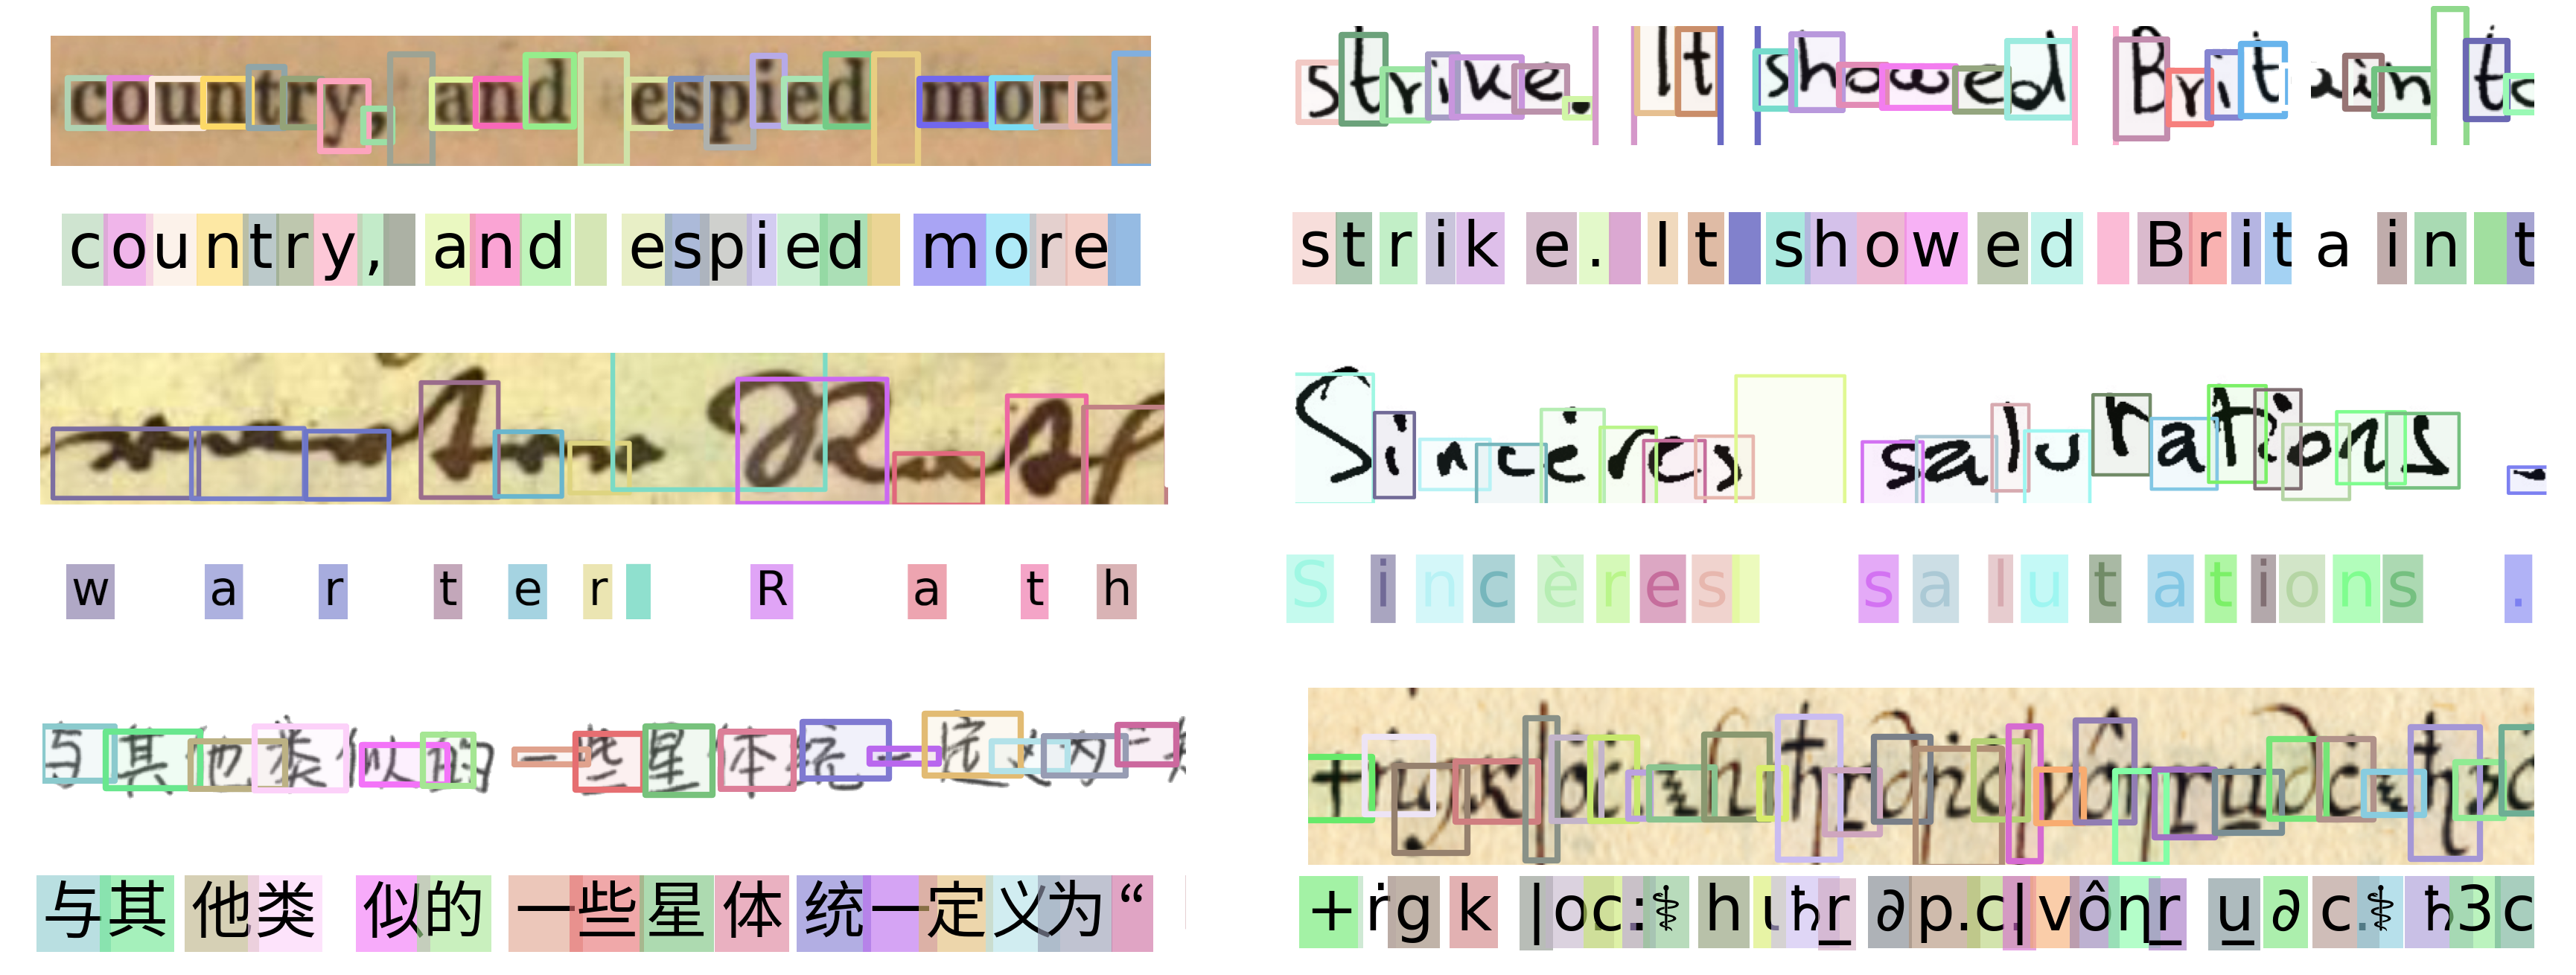
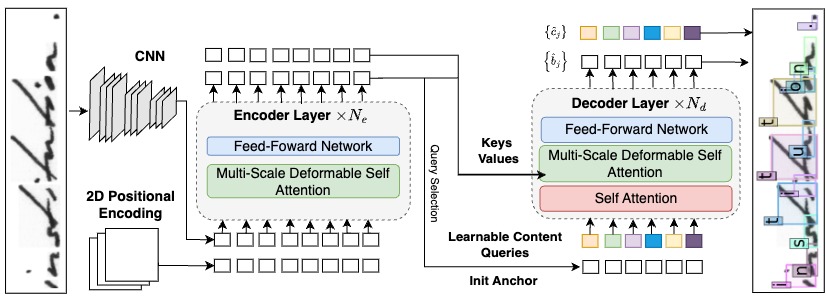
This repository builds on the code for DINO-DETR, the official implementation of the paper "DINO: DETR with Improved DeNoising Anchor Boxes for End-to-End Object Detection". We present a model that adapts DINO-DETR for text recognition as a detection and recognition task. The model is pretrained on synthetic data using the same loss as DINO-DETR and then fine-tuned on a real dataset with CTC loss.
Content
Installation, Datasets, and Weights
Installation, Datasets, and Weights
1. Installation
The model was trained with python=3.11.0, pytorch=2.1.0, cuda=11.8 and builds on the DETR-variants DINO/DN/DAB and Deformable-DETR.
- Clone this repository and create a virtual environment
- Follow instructions to install a Pytorch version compatible with your system and CUDA version
- Install other dependencies
pip install -r requirements.txt - Compiling CUDA operators
python models/dino/ops/setup.py build install # 'cuda not available', run => export CUDA_HOME=/usr/local/cuda-<version>
# unit test (should see all checking is True) # could output an outofmemory error
python models/dino/ops/test.py
2. Datasets
Datasets should be placed in the appropriate folder specified in datasets/config.json. We preprocess the images and annotations for the IAM dataset, while all other datasets are used in their original form. For each dataset (except IAM), a charset file (.pkl) is required. Charset files can be found in the folder data.
Handwritten
- IAM: the official website is here. We preprocess the images and annotation following the instruction in the PyLai Repository. The annotations are stored in data/IAM_new/labels.pkl.
- RIMES: TEKLIA provide the dataset here. After downloading, place the charset file in the same folder as the dataset.
- READ: the dataset is available here. After downloading, place the charset file in the same folder as the dataset.
Chinese The official website is here. Images and annotations are provide only in bytes format for these datasets.
- CASIA v1: Download the dataset in bytes format with the link above and place the charset in the same folder as the dataset.
- CASIA v2: We provide directly a version of the dataset with images (PNG) and annotations (TXT). Download the dataset here.
Ciphers The ciphers borg and copiale are available here. The charset files are provided in the folder data.
3. Weights
Pretrained checkpoints can be found here. The folder includes the weights of the following pretrained models:
- General model: Trained on random Latin characters. Typically used for finetuning on ciphers.
- English model: Trained on English text with random erasing. Typically used for finetuning on IAM.
- French model: Trained on French text with random erasing. Typically used for finetuning on RIMES.
- German model: Trained on German text with random erasing. Typically used for finetuning on READ.
- Chinese model: Trained on random handwritten Chinese characters from HWDB 1. Typically used for finetuning on HWDB 2.
Finetuned checkpoints can be found here.
Checkpoints should be organized as follows:
  logs/
    └── IAM/
      └── checkpoint.pth
    └── other_model/
      └── checkpoint.pth
    ...
Pretraining
Pretraining
Pretraining scipts are available in scripts/pretraining.
Latin scripts
You need to download the folder resources (background, fonts, noises, texts) and place it in the folder dataset.
To train models with random erasing:
sh scripts/pretraining/Synthetic_english_w_masking.sh
sh scripts/pretraining/Synthetic_german_w_masking.sh
sh scripts/pretraining/Synthetic_french_w_masking.sh
sh scripts/pretraining/Synthetic_general.sh
Chinese scripts
You need the dataset CASIA v1 [here]
To train a model with random erasing
sh scripts/pretraining/Synthetic_english.sh
Then for instances to train a model for chinese with random erasing:
bash scripts/pretraining/Synthetic_chinese_w_masking.sh
Finetuning
Finetuning
Finetuning occurs in two stages. The scripts are available in scripts/finetuning.. For Step 1 it is expected that a model is pretrained is placed in the folder logs/your_model_name.
Evaluation
Evaluation
Use the scripts in scripts/evaluating to evaluate the model on the different datasets.
Ngram
Ngram
Evaluation
We provide our N-gran models for RIMES, READ and IAM here. We strongly advice to create a separate environment for the ngram model and to install the libraries in the ngram/mini_guide.md. To run an evalutation with the ngram model:
bash python ngram/clean_gen_ngram_preds.py --config_path ngram/IAM.yaml
bash python ngram/clean_gen_ngram_preds.py --config_path ngram/READ.yaml
bash python ngram/clean_gen_ngram_preds.py --config_path ngram/RIMES.yaml
Training a ngram model
To train you own ngram model, follow the instructions in the ngram/mini_guide.md
Citation
If you find this code useful, don't forget to star the repo :star: and cite the papers :point_down:
@article{baena2024DTLR, title={General Detection-based Text Line Recognition},
author={Raphael Baena and Syrine Kalleli and Mathieu Aubry},
booktitle={NeurIPS},
year={2024}},
url={https://arxiv.org/abs/2409.17095},
Contributors

29 commits

7 commits
Similar repos


Languages
Python
53.5%
Jupyter Notebook
39.8%
Cuda
5.3%
Handwritten Text Recognition and Character Detection
Python
174
36 commits
updated Sep 28, 2025
README
General Detection-based Text Line Recognition (DTLR)
NeurIPS 2024
Raphael Baena
Syrine Kalleli
Mathieu Aubry
Description
This repository is the official implementation for General Detection-based Text Line Recognition, the paper is available on arXiv.
This repository builds on the code for DINO-DETR, the official implementation of the paper "DINO: DETR with Improved DeNoising Anchor Boxes for End-to-End Object Detection". We present a model that adapts DINO-DETR for text recognition as a detection and recognition task. The model is pretrained on synthetic data using the same loss as DINO-DETR and then fine-tuned on a real dataset with CTC loss.
Content
Installation, Datasets, and Weights
Installation, Datasets, and Weights
1. Installation
The model was trained with python=3.11.0, pytorch=2.1.0, cuda=11.8 and builds on the DETR-variants DINO/DN/DAB and Deformable-DETR.
- Clone this repository and create a virtual environment
- Follow instructions to install a Pytorch version compatible with your system and CUDA version
- Install other dependencies
pip install -r requirements.txt - Compiling CUDA operators
python models/dino/ops/setup.py build install # 'cuda not available', run => export CUDA_HOME=/usr/local/cuda-<version>
# unit test (should see all checking is True) # could output an outofmemory error
python models/dino/ops/test.py
2. Datasets
Datasets should be placed in the appropriate folder specified in datasets/config.json. We preprocess the images and annotations for the IAM dataset, while all other datasets are used in their original form. For each dataset (except IAM), a charset file (.pkl) is required. Charset files can be found in the folder data.
Handwritten
- IAM: the official website is here. We preprocess the images and annotation following the instruction in the PyLai Repository. The annotations are stored in data/IAM_new/labels.pkl.
- RIMES: TEKLIA provide the dataset here. After downloading, place the charset file in the same folder as the dataset.
- READ: the dataset is available here. After downloading, place the charset file in the same folder as the dataset.
Chinese The official website is here. Images and annotations are provide only in bytes format for these datasets.
- CASIA v1: Download the dataset in bytes format with the link above and place the charset in the same folder as the dataset.
- CASIA v2: We provide directly a version of the dataset with images (PNG) and annotations (TXT). Download the dataset here.
Ciphers The ciphers borg and copiale are available here. The charset files are provided in the folder data.
3. Weights
Pretrained checkpoints can be found here. The folder includes the weights of the following pretrained models:
- General model: Trained on random Latin characters. Typically used for finetuning on ciphers.
- English model: Trained on English text with random erasing. Typically used for finetuning on IAM.
- French model: Trained on French text with random erasing. Typically used for finetuning on RIMES.
- German model: Trained on German text with random erasing. Typically used for finetuning on READ.
- Chinese model: Trained on random handwritten Chinese characters from HWDB 1. Typically used for finetuning on HWDB 2.
Finetuned checkpoints can be found here.
Checkpoints should be organized as follows:
  logs/
    └── IAM/
      └── checkpoint.pth
    └── other_model/
      └── checkpoint.pth
    ...
Pretraining
Pretraining
Pretraining scipts are available in scripts/pretraining.
Latin scripts
You need to download the folder resources (background, fonts, noises, texts) and place it in the folder dataset.
To train models with random erasing:
sh scripts/pretraining/Synthetic_english_w_masking.sh
sh scripts/pretraining/Synthetic_german_w_masking.sh
sh scripts/pretraining/Synthetic_french_w_masking.sh
sh scripts/pretraining/Synthetic_general.sh
Chinese scripts
You need the dataset CASIA v1 [here]
To train a model with random erasing
sh scripts/pretraining/Synthetic_english.sh
Then for instances to train a model for chinese with random erasing:
bash scripts/pretraining/Synthetic_chinese_w_masking.sh
Finetuning
Finetuning
Finetuning occurs in two stages. The scripts are available in scripts/finetuning.. For Step 1 it is expected that a model is pretrained is placed in the folder logs/your_model_name.
Evaluation
Evaluation
Use the scripts in scripts/evaluating to evaluate the model on the different datasets.
Ngram
Ngram
Evaluation
We provide our N-gran models for RIMES, READ and IAM here. We strongly advice to create a separate environment for the ngram model and to install the libraries in the ngram/mini_guide.md. To run an evalutation with the ngram model:
bash python ngram/clean_gen_ngram_preds.py --config_path ngram/IAM.yaml
bash python ngram/clean_gen_ngram_preds.py --config_path ngram/READ.yaml
bash python ngram/clean_gen_ngram_preds.py --config_path ngram/RIMES.yaml
Training a ngram model
To train you own ngram model, follow the instructions in the ngram/mini_guide.md
Citation
If you find this code useful, don't forget to star the repo :star: and cite the papers :point_down:
@article{baena2024DTLR, title={General Detection-based Text Line Recognition},
author={Raphael Baena and Syrine Kalleli and Mathieu Aubry},
booktitle={NeurIPS},
year={2024}},
url={https://arxiv.org/abs/2409.17095},
Similar repos
Contributors
29 commits
7 commits
Languages
Python
53.5%
Jupyter Notebook
39.8%
Cuda
5.3%