
Papers, Datasets, Algorithms, SOTA for STR. Long-time Maintaining
Python
354
114 commits
updated Nov 29, 2023
README
Scene Text Recognition Recommendations
Everything about Scene Text Recognition
SOTA • Papers • Datasets • Code • Our Framework
Contents
Checkout Our New Work!
Revisiting Scene Text Recognition: A Data Perspective
1. Papers
- Latest Papers:
up to (2023-11-29)
up to (2023-8-11)
up to (2023-7-25)
- ACMMM-2023: Relational Contrastive Learning for Scene Text Recognition
- arXiv-2023: HiREN: Towards Higher Supervision Quality for Better Scene Text Image Super-Resolution
- arXiv-2023: Context Perception Parallel Decoder for Scene Text Recognition
- IJCAI-2023: Towards Robust Scene Text Image Super-resolution via Explicit Location Enhancement
up to (2023-7-25)
up to (2023-7-20)
up to (2023-6-1)
- arXiv-2023:GlyphDraw: Seamlessly Rendering Text with Intricate Spatial Structures in Text-to-Image Generation
- arXiv-2023:TextDiffuser: Diffusion Models as Text Painters
- arXiv-2023:DiffUTE: Universal Text Editing Diffusion Model
- arXiv-2023:GlyphControl: Glyph Conditional Control for Visual Text Generation
up to (2023-5-16)
- IJCAI-2023:TPS++: Attention-Enhanced Thin-Plate Spline for Scene Text Recognition
- IJCAI-2022:Linguistic More: Taking a Further Step toward Efficient and Accurate Scene Text Recognition
- ICDAR-2023:Scene Text Recognition with Image-Text Matching-guided Dictionary
- arXiv-2023:Improving Scene Text Recognition for Character-Level Long-Tailed Distribution
up to (2023-3-16)
- arXiv-2023:CLIPTER: Looking at the Bigger Picture in Scene Text Recognition
- ECCVW-2022:On calibration of scene-text recognition models
- Others:STR transformer: a cross-domain transformer for scene text recognition
- TIP-2023:Text prior guided scene text image super-resolution
- Neurocomputing-2023:DPF-S2S: A novel dual-pathway-fusion-based sequence-to-sequence text recognition model
- WACV-2023:Seq-UPS: Sequential Uncertainty-aware Pseudo-label Selection for Semi-Supervised Text Recognition
- PR-2023:Towards open-set text recognition via label-to-prototype learning
up to (2022-12-29)
- BMVC-2022:Visual-semantic transformer for scene text recognition
- BMVC-2022:Parallel and Robust Text Rectifier for Scene Text Recognition
- ICFHR-2022:A Vision Transformer Based Scene Text Recognizer with Multi-grained Encoding and Decoding
- ECCV-2022:TextAdaIN: Paying Attention to Shortcut Learning in Text Recognizers
up to (2022-11-1)
- arxiv-2022: IterVM: Iterative Vision Modeling Module for Scene Text Recognition
- Applied intelligence:Scene text recognition based on two-stage attention and multi-branch feature fusion module
- ICPR-2022: Portmanteauing Features for Scene Text Recognition
- ECCV-2022: Pure Transformer with Integrated Experts for Scene Text Recognition
- BMCV-2022: Masked Vision-Language Transformers for Scene Text Recognition
up to (2022-11-1)
- AAAI-2022:Visual Semantics Allow for Textual Reasoning Better in Scene Text Recognition
- ECCV-2022:Background-Insensitive Scene Text Recognition with Text Semantic Segmentation
- ACCESS-2022:Scene Text Recognition with Semantics
- TIP-2022:PETR: Rethinking the Capability of Transformer-Based Language Model in Scene Text Recognition
- TMM-2022:Dual Relation Network for Scene Text Recognition
up to (2022-9-20)
- ECCV-2022:Levenshtein OCR
- ECCV-2022:Multi-Granularity Prediction for Scene Text Recognition
- arXiv-2022:A Scene-Text Synthesis Engine Achieved Through Learning from Decomposed Real-World Data
- arXiv-2022:Scene Text Recognition with Single-Point Decoding Network
- ECCV-2022-Technical-Report:Vision-Language Adaptive Mutual Decoder for OOV-STR
- WACV-2023:Seq-UPS: Sequential Uncertainty-aware Pseudo-label Selection for Semi-Supervised Text Recognition
- ECCV-2022-Technical-Report:1st Place Solution to ECCV 2022 Challenge on Out of Vocabulary Scene Text Understanding: End-to-End Recognition of Out of Vocabulary Words
- ECCV-2022-Technical-Report:Runner-Up Solution to ECCV 2022 Challenge on Out of Vocabulary Scene Text Understanding: Cropped Word Recognition
up to (2022-8-9)
up to (2022-7-24)
up to (2022-7-9)
up to (2022-5-12)
2. Datasets
2.1 Synthetic Training Datasets
| Dataset | Description | Examples | BaiduNetdisk link |
|---|---|---|---|
| SynthText | 9 million synthetic text instance images from a set of 90k common English words. Words are rendered onto nartural images with random transformations | 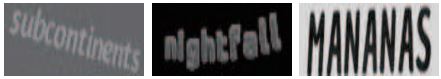 | Scene text datasets(提取码:emco) |
| MJSynth | 6 million synthetic text instances. It's a generation of SynthText. | 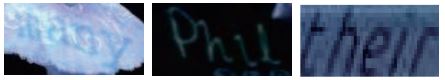 | Scene text datasets(提取码:emco) |
2.2 Benchmarks
| Dataset | Description | Examples | BaiduNetdisk link |
|---|---|---|---|
| IIIT5k-Words(IIIT5K) | 3000 test images instances. Take from street scenes and from originally-digital images |  | Scene text datasets(提取码:emco) |
| Street View Text(SVT) | 647 test images instances. Some images are severely corrupted by noise, blur, and low resolution |  | Scene text datasets(提取码:emco) |
| StreetViewText-Perspective(SVT-P) | 639 test images instances. It is specifically designed to evaluate perspective distorted textrecognition. It is built based on the original SVT dataset by selecting the images at the sameaddress on Google Street View but with different view angles. Therefore, most text instancesare heavily distorted by the non-frontal view angle. |  | Scene text datasets(提取码:emco) |
| ICDAR 2003(IC03) | 867 test image instances |  | Scene text datasets(提取码:mfir) |
| ICDAR 2013(IC13) | 1015 test images instances |  | Scene text datasets(提取码:emco) |
| ICDAR 2015(IC15) | 2077 test images instances. As text images were taken by Google Glasses without ensuringthe image quality, most of the text is very small, blurred, and multi-oriented |  | Scene text datasets(提取码:emco) |
| CUTE80(CUTE) | 288 It focuses on curved text recognition. Most images in CUTE have acomplex background, perspective distortion, and poor resolution |  | Scene text datasets(提取码:emco) |
2.3 Other Real Datasets
- The Real Datasets refer to this repo ku21fan/STR-Fewer-Labels
| Dataset | Description | Examples | BaiduNetdisk link |
|---|---|---|---|
| COCO-Text | 39K Created from the MS COCO dataset. As the MS COCO dataset is not intended to capture text. COCO contains many occluded or low-resolution texts |  | Others(提取码:DLVC) |
| RCTW | 8186 in English. RCTW is created for Reading Chinese Text in the Wild competition. We select those in english |  | Others(提取码:DLVC) |
| Uber-Text | 92K. Collecetd from Bing Maps Streetside. Many are house number, and some are text on signboards |  | Others(提取码:DLVC) |
| Art | 29K. Art is created to recognize Arbitrary-shaped Text. Many are perspective or curved texts. It also includes Totaltext and CTW1500, which contain many rotated or curved texts |  | Others(提取码:DLVC) |
| LSVT | 34K in English. LSVT is a Large-scale Streeet View Text dataset, collected from streets in China. We select those in english |  | Others(提取码:DLVC) |
| MLT19 | 46K in English. MLT19 is created to recognize Multi-Lingual Text. It consists of seven languages:Arabic, Latin, Chinese, Japanese, Korean, Bangla, and Hindi. We select those in english |  | Others(提取码:DLVC) |
| ReCTS | 23K in English. ReCTS is created for the Reading Chinese Text on Signboard competition. It contains many irregular texts arranged in various layouts or written with unique fonts. We select those in english |  | Others(提取码:DLVC) |
3 Public Code
3.1 Frameworks
PaddleOCR (百度)
- PaddlePaddle/PaddleOCR
- 特性 (截取至PaddleOCR):
- 使用百度自研深度学习框架PaddlePaddle搭建
- PP-OCR系列高质量预训练模型,准确的识别效果
- 超轻量PP-OCRv2系列:检测(3.1M)+ 方向分类器(1.4M)+ 识别(8.5M)= 13.0M
- 超轻量PP-OCR mobile移动端系列:检测(3.0M)+方向分类器(1.4M)+ 识别(5.0M)= 9.4M
- 通用PPOCR server系列:检测(47.1M)+方向分类器(1.4M)+ 识别(94.9M)= 143.4M
- 支持中英文数字组合识别、竖排文本识别、长文本识别
- 支持多语言识别:韩语、日语、德语、法语
- 丰富易用的OCR相关工具组件
- 半自动数据标注工具PPOCRLabel:支持快速高效的数据标注
- 数据合成工具Style-Text:批量合成大量与目标场景类似的图像
- 文档分析能力PP-Structure:版面分析与表格识别
- 支持用户自定义训练,提供丰富的预测推理部署方案
- 支持PIP快速安装使用
- 可运行于Linux、Windows、MacOS等多种系统
- 支持算法(识别):
- CRNN
- Rosetta
- STAR-Net
- RARE
- SRN
- NRTR
MMOCR (OpenMMLab)
- open-mmlab/mmocr
- 特性(截取至MMOCR):
- MMOCR 是基于 PyTorch 和 mmdetection 的开源工具箱,专注于文本检测,文本识别以及相应的下游任务,如关键信息提取。 它是 OpenMMLab 项目的一部分。
- 该工具箱不仅支持文本检测和文本识别,还支持其下游任务,例如关键信息提取。
- 支持算法(识别)
- ABINet (CVPR'2021)
- CRNN (TPAMI'2016)
- MASTER (PR'2021)
- NRTR (ICDAR'2019)
- RobustScanner (ECCV'2020)
- SAR (AAAI'2019)
- SATRN (CVPR'2020 Workshop on Text and Documents in the Deep Learning Era)
- SegOCR (Manuscript'2021)
Deep Text Recognition Benchmark (ClovaAI)
- clovaai/deep-text-recognition-benchmark
- 特性:
- Offical Pytorch implementation of What Is Wrong With Scene Text Recognition Model Comparisons? Dataset and Model Analysis
- 可自定义四阶段组件,如CRNN,ASTER
- 容易上手,推荐使用
DAVAR-Lab-OCR (海康威视)
- hikopensource/DAVAR-Lab-OCR
- 特性:
- 基于mmocr搭建,复现了一些算法,同时将来会用于海康自研算法开源
- 支持算法(识别)
- Attention(CVPR 2016)
- CRNN(TPAMI 2017)
- ACE(CVPR 2019)
- SPIN(AAAI 2021)
- RF-Learning(ICDAR 2021)
3.2. Algorithms
CRNN
- Lua, Offical, 1.9k⭐: bgshih/crnn
- 官方实现版本,使用Lua
- Pytorch, 1.9k⭐: meijeru/crnn.pytorch
- 推荐使用🀄
- Tensorflow, 972⭐:MaybeShewill-CV/CRNN_Tensorflow
- Pytorch, 1.4k⭐:Sierkinhance/CRNN_Chinese_Characters_Rec
- 用于中文识别版本的CRNN
ASTER
- Tensorflow, official, 651⭐: bgshih/aster
- 官方实现版本,使用Tensorflow
- Pytorch, 535⭐:ayumuymk/aster.pytorch
- Pytorch版本,准确率相较原文有明显提升
MORANv2
- Pytorch, official, 572⭐:Canjie-Luo/MORAN_v2
- MORAN v2版本。更加稳定的单阶段训练,更换ResNet做backbone,使用双向解码器
4. SOTAs
All the models are evaluated in a lexicon-free manner
| Regular Dataset | Irregular dataset | |||||||||
| Model | Year | IIIT | SVT | IC13(857) | IC13(1015) | IC15(1811) | IC15(2077) | SVTP | CUTE | |
| CRNN | 2015 | 78.2 | 80.8 | - | 86.7 | - | - | - | - | |
| ASTER(L2R) | 2015 | 92.67 | 91.16 | - | 90.74 | 76.1 | - | 78.76 | 76.39 | |
| CombBest | 2019 | 87.9 | 87.5 | 93.6 | 92.3 | 77.6 | 71.8 | 79.2 | 74 | |
| ESIR | 2019 | 93.3 | 90.2 | - | 91.3 | - | 76.9 | 79.6 | 83.3 | |
| SE-ASTER | 2020 | 93.8 | 89.6 | - | 92.8 | 80 | 81.4 | 83.6 | ||
| DAN | 2020 | 94.3 | 89.2 | - | 93.9 | - | 74.5 | 80 | 84.4 | |
| RobustScanner | 2020 | 95.3 | 88.1 | - | 94.8 | - | 77.1 | 79.5 | 90.3 | |
| AutoSTR | 2020 | 94.7 | 90.9 | - | 94.2 | 81.8 | - | 81.7 | - | |
| Yang et al. | 2020 | 94.7 | 88.9 | - | 93.2 | 79.5 | 77.1 | 80.9 | 85.4 | |
| SATRN | 2020 | 92.8 | 91.3 | - | 94.1 | - | 79 | 86.5 | 87.8 | |
| SRN | 2020 | 94.8 | 91.5 | 95.5 | - | 82.7 | - | 85.1 | 87.8 | |
| GA-SPIN | 2021 | 95.2 | 90.9 | - | 94.8 | 82.8 | 79.5 | 83.2 | 87.5 | |
| PREN2D | 2021 | 95.6 | 94 | 96.4 | - | 83 | - | 87.6 | 91.7 | |
| Bhunia et al. | 2021 | 95.2 | 92.2 | - | 95.5 | - | 84 | 85.7 | 89.7 | |
| Luo et al. | 2021 | 95.6 | 90.6 | - | 96.0 | 83.9 | 81.4 | 85.1 | 91.3 | |
| VisionLAN | 2021 | 95.8 | 91.7 | 95.7 | - | 83.7 | - | 86 | 88.5 | |
| ABINet | 2021 | 96.2 | 93.5 | 97.4 | - | 86.0 | - | 89.3 | 89.2 | |
| MATRN | 2021 | 96.7 | 94.9 | 97.9 | 95.8 | 86.6 | 82.9 | 90.5 | 94.1 | |
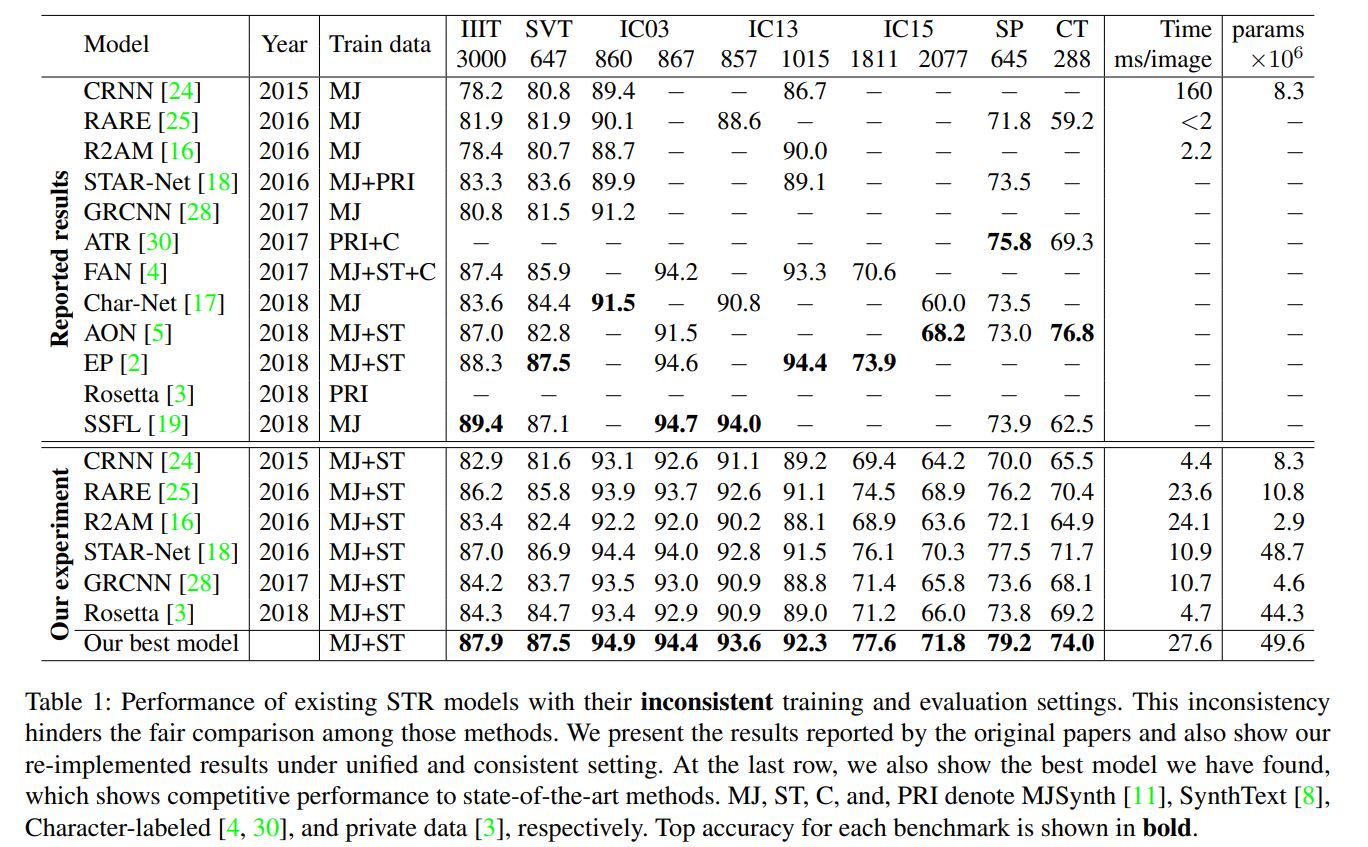
Baek's Reimplementation Version
aster-pytorch
crnn-pytorch
datasets
frameworks
paper-recommendations
scene-text-recogniton
sotas
Contributors

Mountchicken
113 commits

HCIILAB
1 commits
Similar repos


Languages
Python
96.7%
Shell
3.3%
Papers, Datasets, Algorithms, SOTA for STR. Long-time Maintaining
Python
354
114 commits
updated Nov 29, 2023
README
Scene Text Recognition Recommendations
Everything about Scene Text Recognition
SOTA • Papers • Datasets • Code • Our Framework
Contents
Checkout Our New Work!
Revisiting Scene Text Recognition: A Data Perspective
1. Papers
- Latest Papers:
up to (2023-11-29)
up to (2023-8-11)
up to (2023-7-25)
- ACMMM-2023: Relational Contrastive Learning for Scene Text Recognition
- arXiv-2023: HiREN: Towards Higher Supervision Quality for Better Scene Text Image Super-Resolution
- arXiv-2023: Context Perception Parallel Decoder for Scene Text Recognition
- IJCAI-2023: Towards Robust Scene Text Image Super-resolution via Explicit Location Enhancement
up to (2023-7-25)
up to (2023-7-20)
up to (2023-6-1)
- arXiv-2023:GlyphDraw: Seamlessly Rendering Text with Intricate Spatial Structures in Text-to-Image Generation
- arXiv-2023:TextDiffuser: Diffusion Models as Text Painters
- arXiv-2023:DiffUTE: Universal Text Editing Diffusion Model
- arXiv-2023:GlyphControl: Glyph Conditional Control for Visual Text Generation
up to (2023-5-16)
- IJCAI-2023:TPS++: Attention-Enhanced Thin-Plate Spline for Scene Text Recognition
- IJCAI-2022:Linguistic More: Taking a Further Step toward Efficient and Accurate Scene Text Recognition
- ICDAR-2023:Scene Text Recognition with Image-Text Matching-guided Dictionary
- arXiv-2023:Improving Scene Text Recognition for Character-Level Long-Tailed Distribution
up to (2023-3-16)
- arXiv-2023:CLIPTER: Looking at the Bigger Picture in Scene Text Recognition
- ECCVW-2022:On calibration of scene-text recognition models
- Others:STR transformer: a cross-domain transformer for scene text recognition
- TIP-2023:Text prior guided scene text image super-resolution
- Neurocomputing-2023:DPF-S2S: A novel dual-pathway-fusion-based sequence-to-sequence text recognition model
- WACV-2023:Seq-UPS: Sequential Uncertainty-aware Pseudo-label Selection for Semi-Supervised Text Recognition
- PR-2023:Towards open-set text recognition via label-to-prototype learning
up to (2022-12-29)
- BMVC-2022:Visual-semantic transformer for scene text recognition
- BMVC-2022:Parallel and Robust Text Rectifier for Scene Text Recognition
- ICFHR-2022:A Vision Transformer Based Scene Text Recognizer with Multi-grained Encoding and Decoding
- ECCV-2022:TextAdaIN: Paying Attention to Shortcut Learning in Text Recognizers
up to (2022-11-1)
- arxiv-2022: IterVM: Iterative Vision Modeling Module for Scene Text Recognition
- Applied intelligence:Scene text recognition based on two-stage attention and multi-branch feature fusion module
- ICPR-2022: Portmanteauing Features for Scene Text Recognition
- ECCV-2022: Pure Transformer with Integrated Experts for Scene Text Recognition
- BMCV-2022: Masked Vision-Language Transformers for Scene Text Recognition
up to (2022-11-1)
- AAAI-2022:Visual Semantics Allow for Textual Reasoning Better in Scene Text Recognition
- ECCV-2022:Background-Insensitive Scene Text Recognition with Text Semantic Segmentation
- ACCESS-2022:Scene Text Recognition with Semantics
- TIP-2022:PETR: Rethinking the Capability of Transformer-Based Language Model in Scene Text Recognition
- TMM-2022:Dual Relation Network for Scene Text Recognition
up to (2022-9-20)
- ECCV-2022:Levenshtein OCR
- ECCV-2022:Multi-Granularity Prediction for Scene Text Recognition
- arXiv-2022:A Scene-Text Synthesis Engine Achieved Through Learning from Decomposed Real-World Data
- arXiv-2022:Scene Text Recognition with Single-Point Decoding Network
- ECCV-2022-Technical-Report:Vision-Language Adaptive Mutual Decoder for OOV-STR
- WACV-2023:Seq-UPS: Sequential Uncertainty-aware Pseudo-label Selection for Semi-Supervised Text Recognition
- ECCV-2022-Technical-Report:1st Place Solution to ECCV 2022 Challenge on Out of Vocabulary Scene Text Understanding: End-to-End Recognition of Out of Vocabulary Words
- ECCV-2022-Technical-Report:Runner-Up Solution to ECCV 2022 Challenge on Out of Vocabulary Scene Text Understanding: Cropped Word Recognition
up to (2022-8-9)
up to (2022-7-24)
up to (2022-7-9)
up to (2022-5-12)
2. Datasets
2.1 Synthetic Training Datasets
| Dataset | Description | Examples | BaiduNetdisk link |
|---|---|---|---|
| SynthText | 9 million synthetic text instance images from a set of 90k common English words. Words are rendered onto nartural images with random transformations | | Scene text datasets(提取码:emco) |
| MJSynth | 6 million synthetic text instances. It's a generation of SynthText. | | Scene text datasets(提取码:emco) |
2.2 Benchmarks
| Dataset | Description | Examples | BaiduNetdisk link |
|---|---|---|---|
| IIIT5k-Words(IIIT5K) | 3000 test images instances. Take from street scenes and from originally-digital images | | Scene text datasets(提取码:emco) |
| Street View Text(SVT) | 647 test images instances. Some images are severely corrupted by noise, blur, and low resolution | | Scene text datasets(提取码:emco) |
| StreetViewText-Perspective(SVT-P) | 639 test images instances. It is specifically designed to evaluate perspective distorted textrecognition. It is built based on the original SVT dataset by selecting the images at the sameaddress on Google Street View but with different view angles. Therefore, most text instancesare heavily distorted by the non-frontal view angle. | | Scene text datasets(提取码:emco) |
| ICDAR 2003(IC03) | 867 test image instances | | Scene text datasets(提取码:mfir) |
| ICDAR 2013(IC13) | 1015 test images instances | | Scene text datasets(提取码:emco) |
| ICDAR 2015(IC15) | 2077 test images instances. As text images were taken by Google Glasses without ensuringthe image quality, most of the text is very small, blurred, and multi-oriented | | Scene text datasets(提取码:emco) |
| CUTE80(CUTE) | 288 It focuses on curved text recognition. Most images in CUTE have acomplex background, perspective distortion, and poor resolution | | Scene text datasets(提取码:emco) |
2.3 Other Real Datasets
- The Real Datasets refer to this repo ku21fan/STR-Fewer-Labels
| Dataset | Description | Examples | BaiduNetdisk link |
|---|---|---|---|
| COCO-Text | 39K Created from the MS COCO dataset. As the MS COCO dataset is not intended to capture text. COCO contains many occluded or low-resolution texts | | Others(提取码:DLVC) |
| RCTW | 8186 in English. RCTW is created for Reading Chinese Text in the Wild competition. We select those in english | | Others(提取码:DLVC) |
| Uber-Text | 92K. Collecetd from Bing Maps Streetside. Many are house number, and some are text on signboards | | Others(提取码:DLVC) |
| Art | 29K. Art is created to recognize Arbitrary-shaped Text. Many are perspective or curved texts. It also includes Totaltext and CTW1500, which contain many rotated or curved texts | | Others(提取码:DLVC) |
| LSVT | 34K in English. LSVT is a Large-scale Streeet View Text dataset, collected from streets in China. We select those in english | | Others(提取码:DLVC) |
| MLT19 | 46K in English. MLT19 is created to recognize Multi-Lingual Text. It consists of seven languages:Arabic, Latin, Chinese, Japanese, Korean, Bangla, and Hindi. We select those in english | | Others(提取码:DLVC) |
| ReCTS | 23K in English. ReCTS is created for the Reading Chinese Text on Signboard competition. It contains many irregular texts arranged in various layouts or written with unique fonts. We select those in english | | Others(提取码:DLVC) |
3 Public Code
3.1 Frameworks
PaddleOCR (百度)
- PaddlePaddle/PaddleOCR
- 特性 (截取至PaddleOCR):
- 使用百度自研深度学习框架PaddlePaddle搭建
- PP-OCR系列高质量预训练模型,准确的识别效果
- 超轻量PP-OCRv2系列:检测(3.1M)+ 方向分类器(1.4M)+ 识别(8.5M)= 13.0M
- 超轻量PP-OCR mobile移动端系列:检测(3.0M)+方向分类器(1.4M)+ 识别(5.0M)= 9.4M
- 通用PPOCR server系列:检测(47.1M)+方向分类器(1.4M)+ 识别(94.9M)= 143.4M
- 支持中英文数字组合识别、竖排文本识别、长文本识别
- 支持多语言识别:韩语、日语、德语、法语
- 丰富易用的OCR相关工具组件
- 半自动数据标注工具PPOCRLabel:支持快速高效的数据标注
- 数据合成工具Style-Text:批量合成大量与目标场景类似的图像
- 文档分析能力PP-Structure:版面分析与表格识别
- 支持用户自定义训练,提供丰富的预测推理部署方案
- 支持PIP快速安装使用
- 可运行于Linux、Windows、MacOS等多种系统
- 支持算法(识别):
- CRNN
- Rosetta
- STAR-Net
- RARE
- SRN
- NRTR
MMOCR (OpenMMLab)
- open-mmlab/mmocr
- 特性(截取至MMOCR):
- MMOCR 是基于 PyTorch 和 mmdetection 的开源工具箱,专注于文本检测,文本识别以及相应的下游任务,如关键信息提取。 它是 OpenMMLab 项目的一部分。
- 该工具箱不仅支持文本检测和文本识别,还支持其下游任务,例如关键信息提取。
- 支持算法(识别)
- ABINet (CVPR'2021)
- CRNN (TPAMI'2016)
- MASTER (PR'2021)
- NRTR (ICDAR'2019)
- RobustScanner (ECCV'2020)
- SAR (AAAI'2019)
- SATRN (CVPR'2020 Workshop on Text and Documents in the Deep Learning Era)
- SegOCR (Manuscript'2021)
Deep Text Recognition Benchmark (ClovaAI)
- clovaai/deep-text-recognition-benchmark
- 特性:
- Offical Pytorch implementation of What Is Wrong With Scene Text Recognition Model Comparisons? Dataset and Model Analysis
- 可自定义四阶段组件,如CRNN,ASTER
- 容易上手,推荐使用
DAVAR-Lab-OCR (海康威视)
- hikopensource/DAVAR-Lab-OCR
- 特性:
- 基于mmocr搭建,复现了一些算法,同时将来会用于海康自研算法开源
- 支持算法(识别)
- Attention(CVPR 2016)
- CRNN(TPAMI 2017)
- ACE(CVPR 2019)
- SPIN(AAAI 2021)
- RF-Learning(ICDAR 2021)
3.2. Algorithms
CRNN
- Lua, Offical, 1.9k⭐: bgshih/crnn
- 官方实现版本,使用Lua
- Pytorch, 1.9k⭐: meijeru/crnn.pytorch
- 推荐使用🀄
- Tensorflow, 972⭐:MaybeShewill-CV/CRNN_Tensorflow
- Pytorch, 1.4k⭐:Sierkinhance/CRNN_Chinese_Characters_Rec
- 用于中文识别版本的CRNN
ASTER
- Tensorflow, official, 651⭐: bgshih/aster
- 官方实现版本,使用Tensorflow
- Pytorch, 535⭐:ayumuymk/aster.pytorch
- Pytorch版本,准确率相较原文有明显提升
MORANv2
- Pytorch, official, 572⭐:Canjie-Luo/MORAN_v2
- MORAN v2版本。更加稳定的单阶段训练,更换ResNet做backbone,使用双向解码器
4. SOTAs
All the models are evaluated in a lexicon-free manner
| Regular Dataset | Irregular dataset | |||||||||
| Model | Year | IIIT | SVT | IC13(857) | IC13(1015) | IC15(1811) | IC15(2077) | SVTP | CUTE | |
| CRNN | 2015 | 78.2 | 80.8 | - | 86.7 | - | - | - | - | |
| ASTER(L2R) | 2015 | 92.67 | 91.16 | - | 90.74 | 76.1 | - | 78.76 | 76.39 | |
| CombBest | 2019 | 87.9 | 87.5 | 93.6 | 92.3 | 77.6 | 71.8 | 79.2 | 74 | |
| ESIR | 2019 | 93.3 | 90.2 | - | 91.3 | - | 76.9 | 79.6 | 83.3 | |
| SE-ASTER | 2020 | 93.8 | 89.6 | - | 92.8 | 80 | 81.4 | 83.6 | ||
| DAN | 2020 | 94.3 | 89.2 | - | 93.9 | - | 74.5 | 80 | 84.4 | |
| RobustScanner | 2020 | 95.3 | 88.1 | - | 94.8 | - | 77.1 | 79.5 | 90.3 | |
| AutoSTR | 2020 | 94.7 | 90.9 | - | 94.2 | 81.8 | - | 81.7 | - | |
| Yang et al. | 2020 | 94.7 | 88.9 | - | 93.2 | 79.5 | 77.1 | 80.9 | 85.4 | |
| SATRN | 2020 | 92.8 | 91.3 | - | 94.1 | - | 79 | 86.5 | 87.8 | |
| SRN | 2020 | 94.8 | 91.5 | 95.5 | - | 82.7 | - | 85.1 | 87.8 | |
| GA-SPIN | 2021 | 95.2 | 90.9 | - | 94.8 | 82.8 | 79.5 | 83.2 | 87.5 | |
| PREN2D | 2021 | 95.6 | 94 | 96.4 | - | 83 | - | 87.6 | 91.7 | |
| Bhunia et al. | 2021 | 95.2 | 92.2 | - | 95.5 | - | 84 | 85.7 | 89.7 | |
| Luo et al. | 2021 | 95.6 | 90.6 | - | 96.0 | 83.9 | 81.4 | 85.1 | 91.3 | |
| VisionLAN | 2021 | 95.8 | 91.7 | 95.7 | - | 83.7 | - | 86 | 88.5 | |
| ABINet | 2021 | 96.2 | 93.5 | 97.4 | - | 86.0 | - | 89.3 | 89.2 | |
| MATRN | 2021 | 96.7 | 94.9 | 97.9 | 95.8 | 86.6 | 82.9 | 90.5 | 94.1 | |
Baek's Reimplementation Version
aster-pytorch
crnn-pytorch
datasets
frameworks
paper-recommendations
scene-text-recogniton
sotas
Similar repos
Contributors
Mountchicken
113 commits
HCIILAB
1 commits
Languages
Python
96.7%
Shell
3.3%