Iris-3B: pixel-space generation & general vision learner. A 3B diffusion transformer that generates every pixel directly (no VAE); the same prior, fine-tuned, does monocular depth estimation and 4x image restoration. Paper, weights, training code and demo.
See the codePixel-space generation & general vision learner
Generative priors are a promising foundation for downstream vision tasks. In this project we explore pixel-space generative models as an alternative to vision foundation models such as DINOv2.
Iris-3B is a 3B-parameter diffusion transformer that generates directly in pixel space: no VAE, no latent space, every pixel is produced by the model, so nothing is lost to a lossy, texture-biased latent. It is not only an image generator: the same pixel-space prior, fine-tuned, estimates monocular depth and restores and upscales images — one backbone, three tasks. This repository contains the model, the training and fine-tuning code, and inference.



https://github.com/user-attachments/assets/2345a853-c673-4ddb-83b9-7e05c83198ed
Samples from the final checkpoint at native aspect ratios of about one megapixel (CFG 3, 100 steps, one fixed seed, no prompt rewriting).
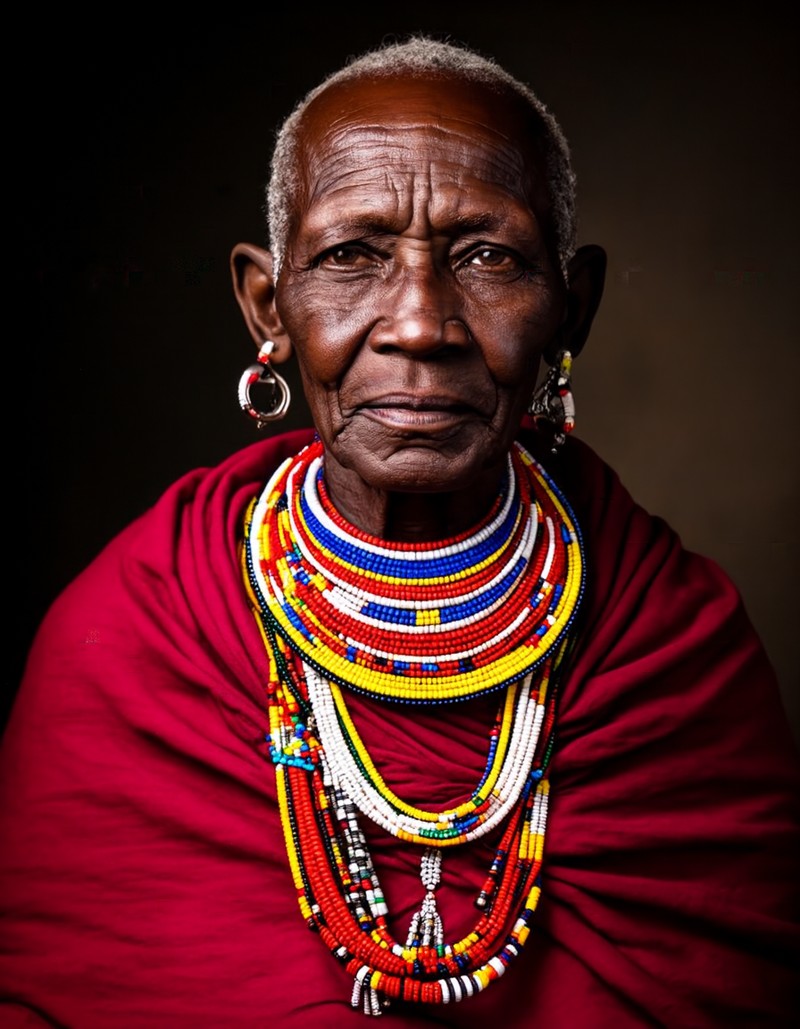 Studio portrait of a Maasai elder wearing vibrant beaded jewelry, deep red cloth, dark backdrop, Rembrandt lighting, ultra detailed skin texture | 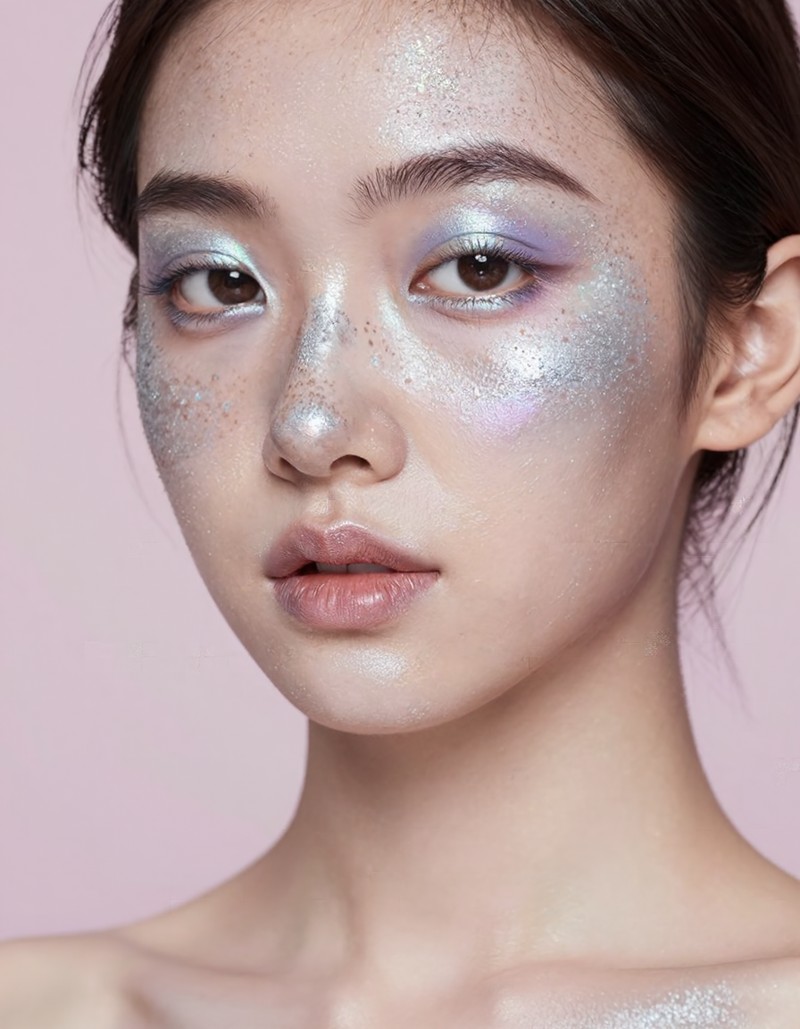 Close-up portrait of a young woman with silver glitter freckles and iridescent makeup, soft pastel background, high fashion beauty photography | 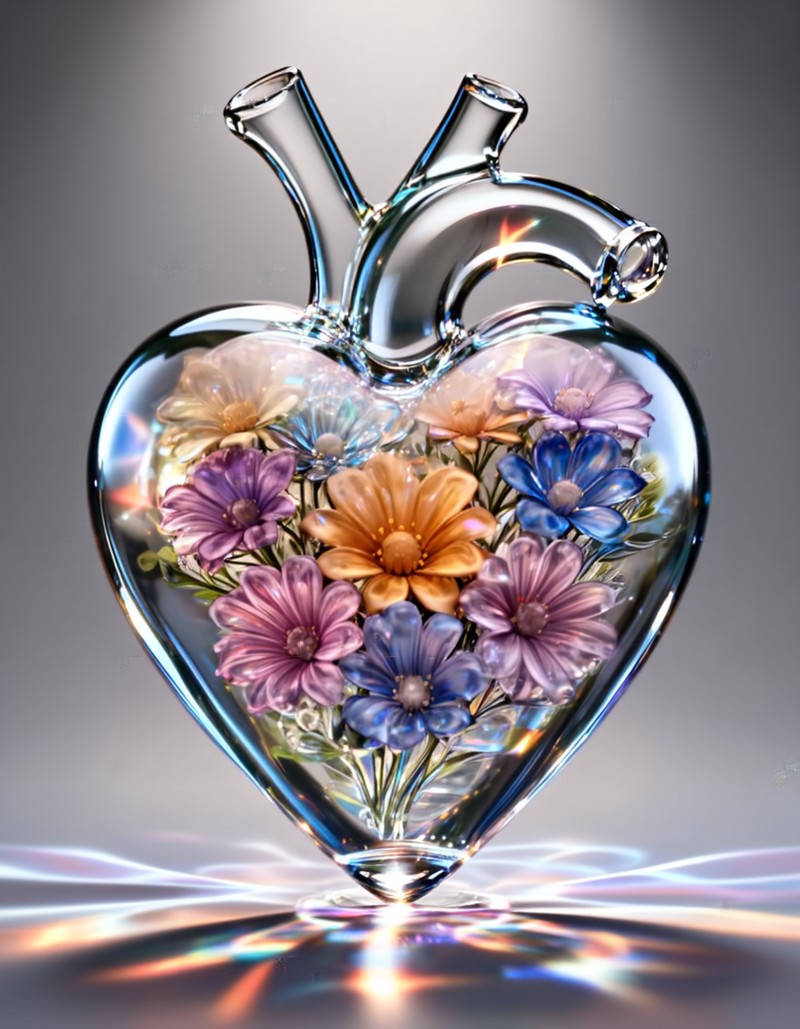 A glass sculpture of a heart filled with flowers, caustics and reflections, 3D render |
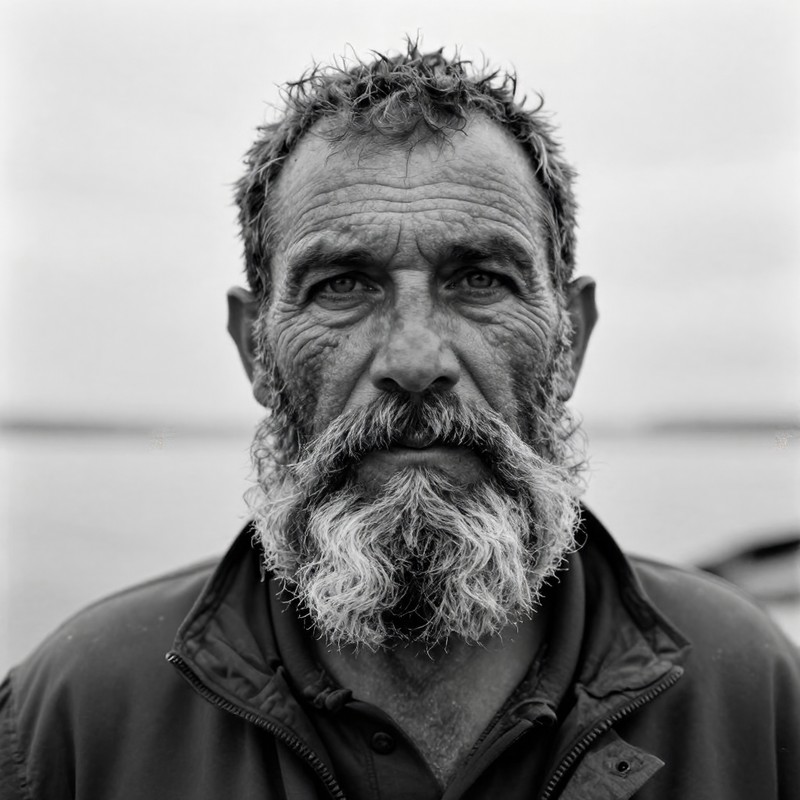 Black and white portrait of a fisherman with a thick grey beard and deep wrinkles, piercing eyes, overcast light, fine grain film photograph | 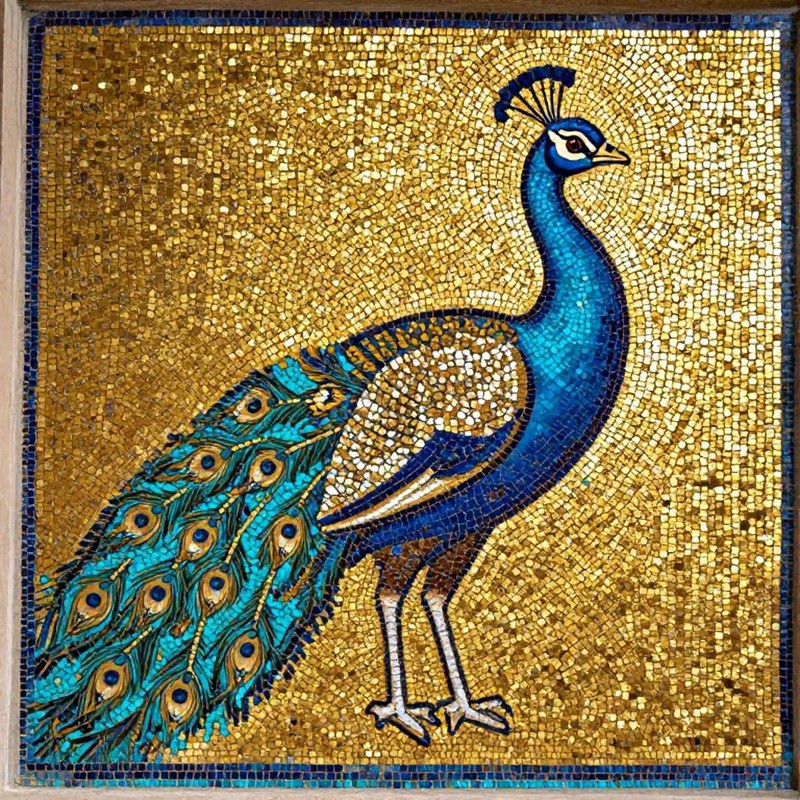 A Byzantine-style mosaic of a peacock made of tiny gold and turquoise tiles, shimmering texture | 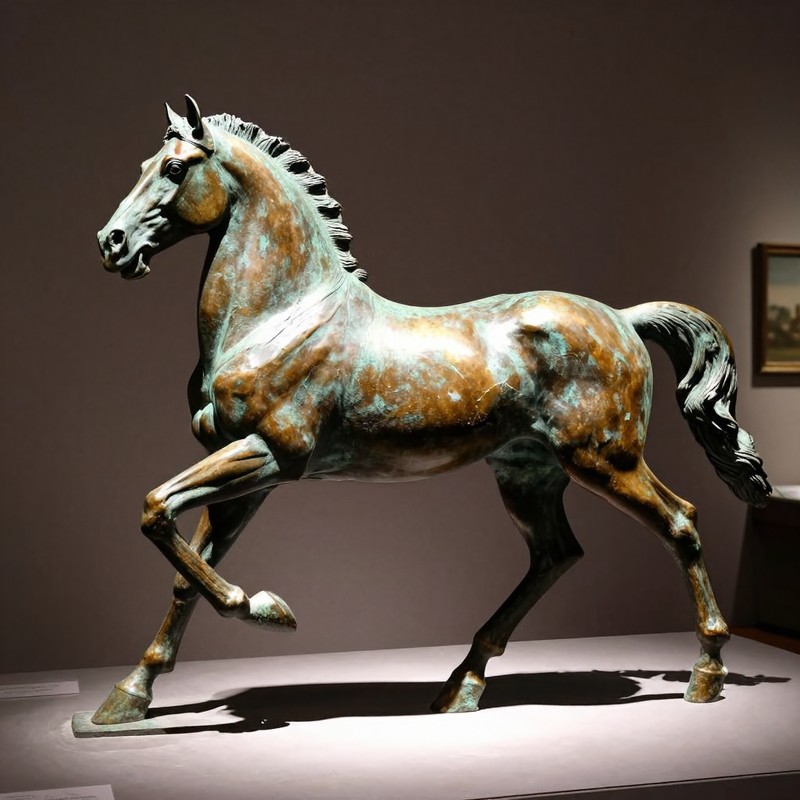 A bronze sculpture of a horse in motion, patina, dramatic museum spotlight |
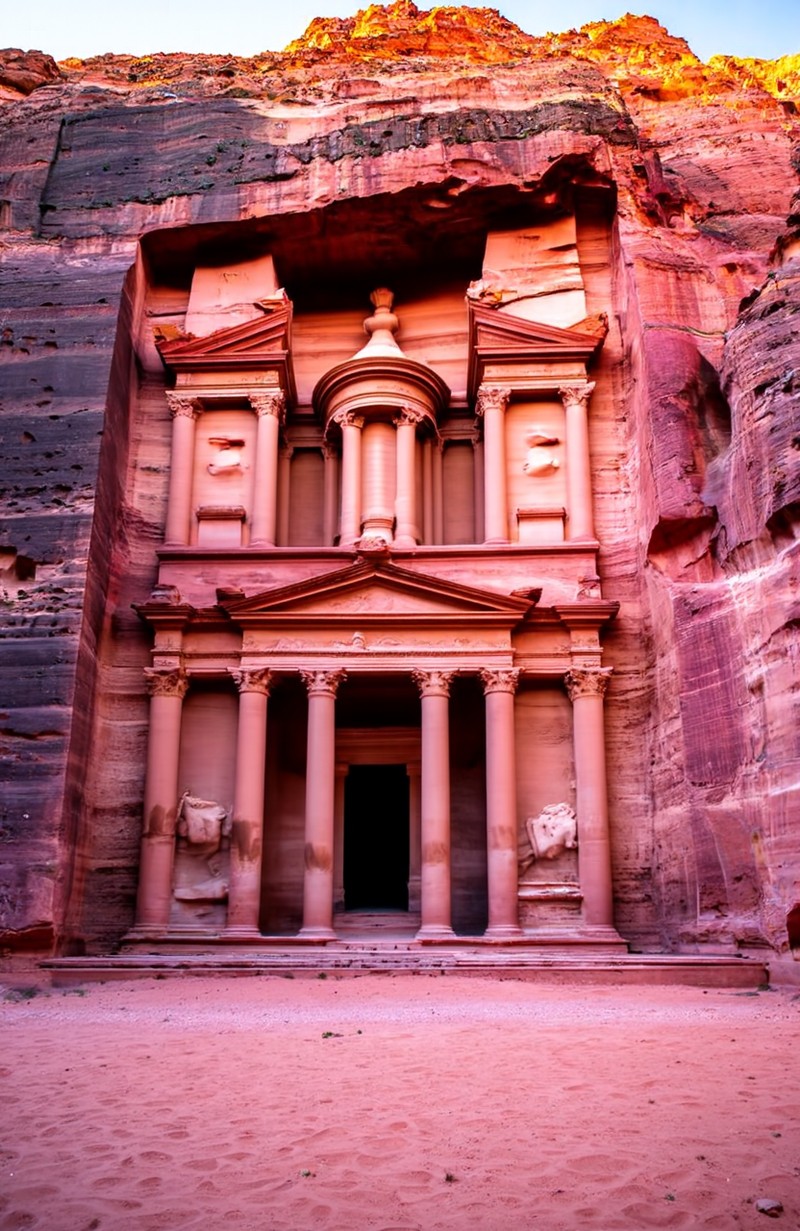 The ancient city of Petra with the Treasury carved into pink sandstone, morning light | 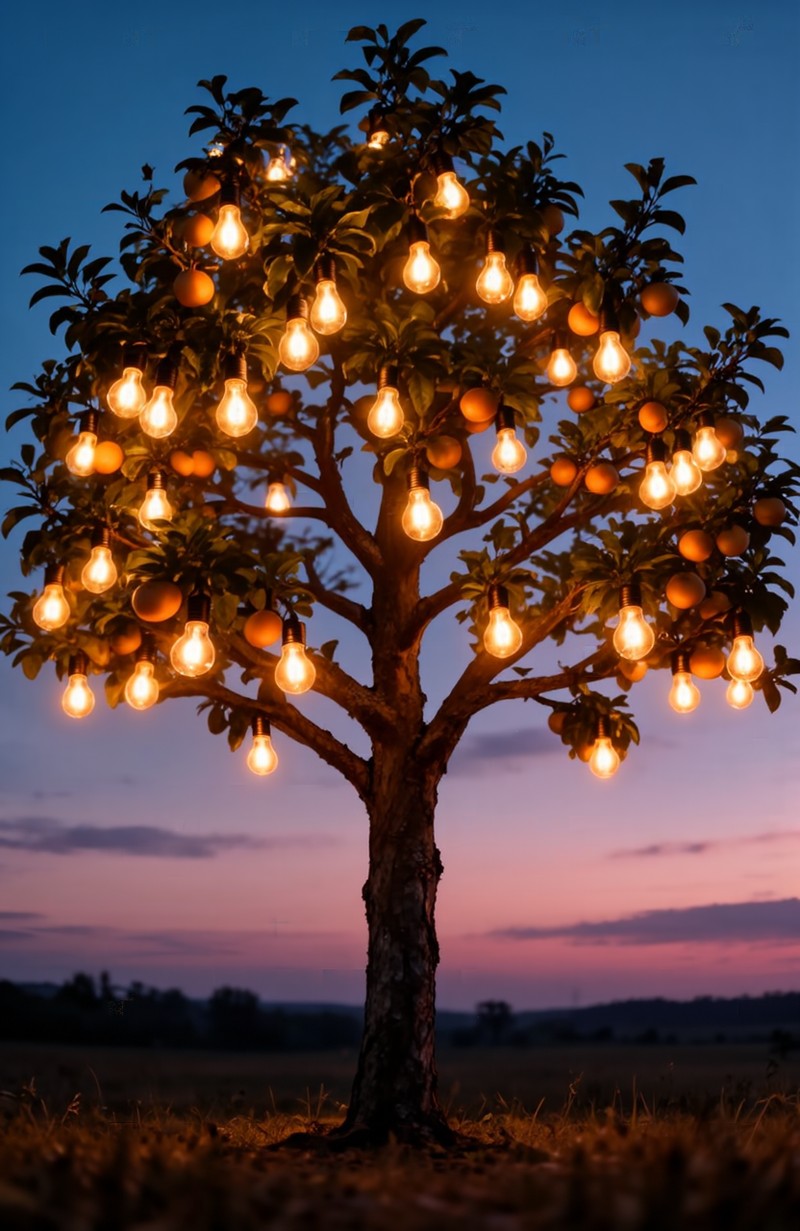 A tree with lightbulbs instead of fruits glowing at dusk, surreal concept art | 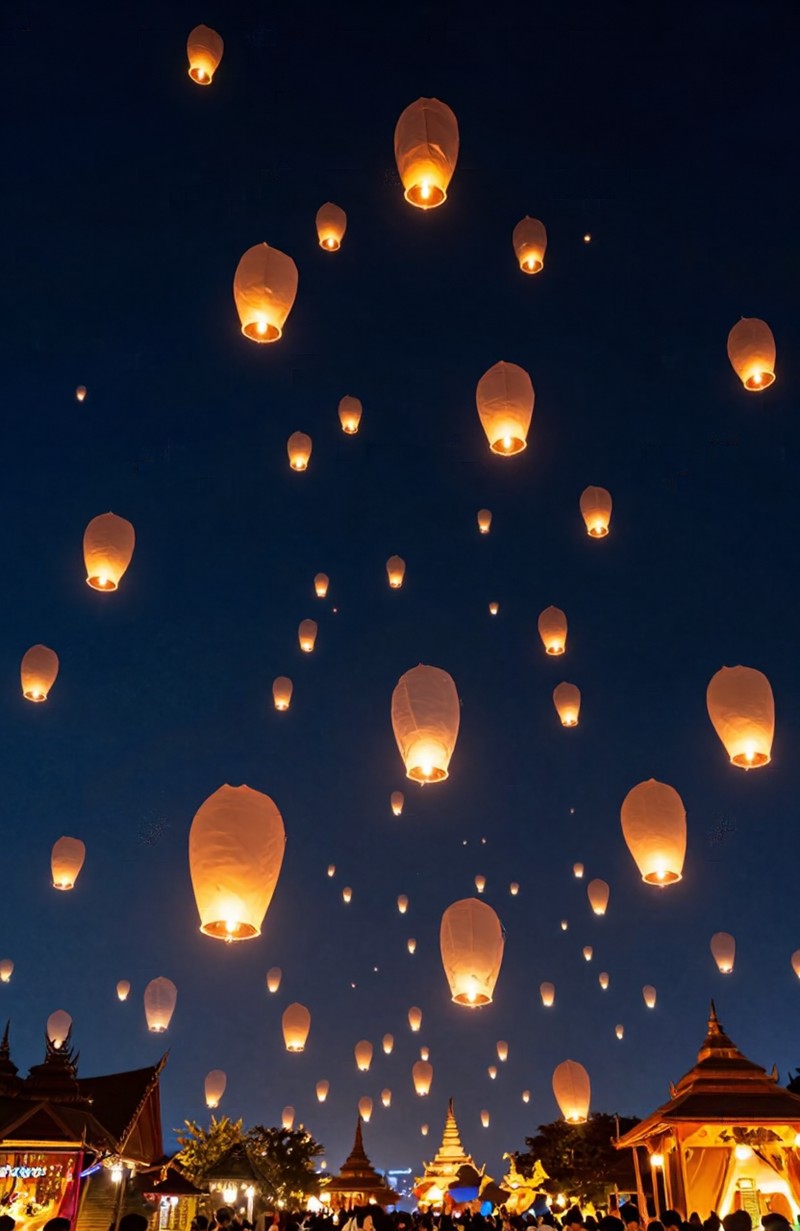 Thousands of sky lanterns rising into the night sky at Yi Peng festival in Chiang Mai |
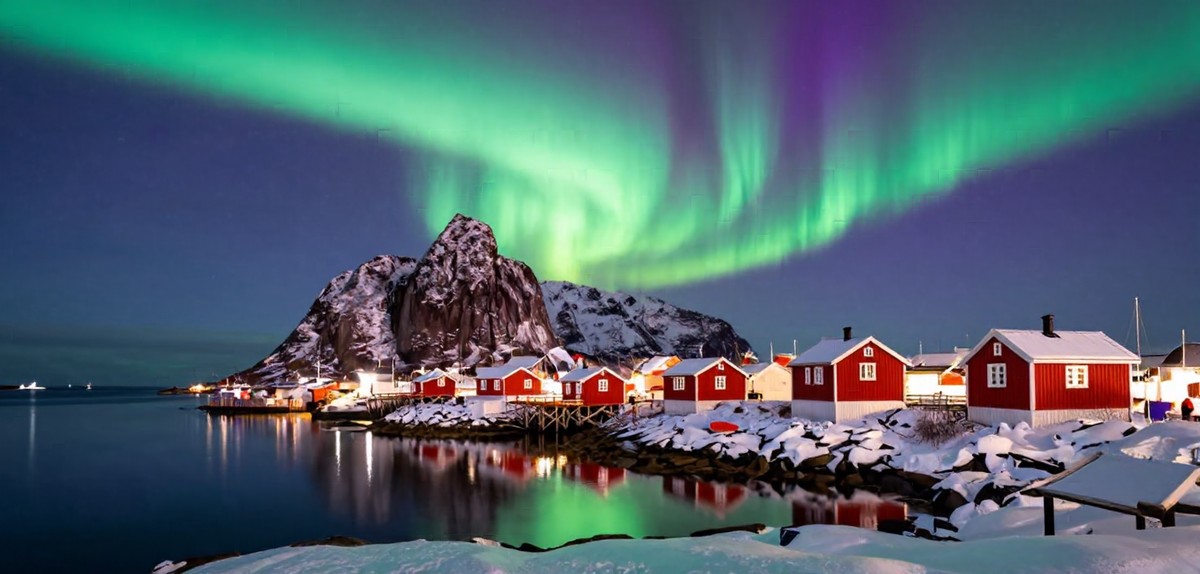 The aurora borealis swirling green and violet over a snowy Lofoten fishing village with red wooden cabins, reflections in a calm fjord, night photograph | 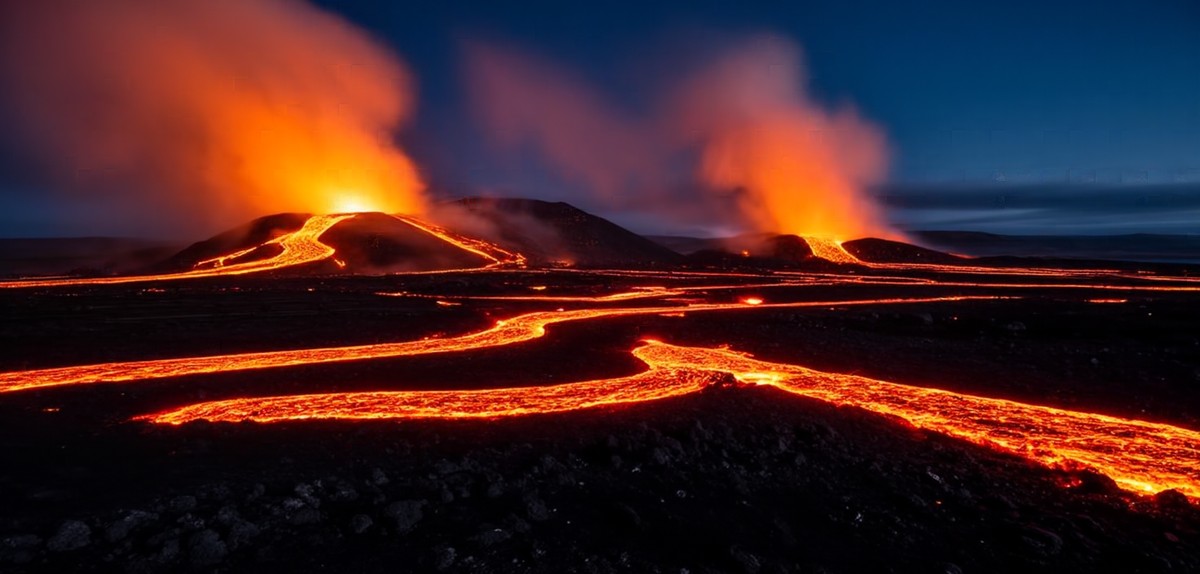 Volcanic eruption at night in Iceland, rivers of glowing lava flowing across black fields, plumes of steam lit orange, long exposure |
More samples: project page.
Iris-3B is a general vision learner, not only a text-to-image model: the same pixel-space backbone, fine-tuned with no architectural change, does dense vision tasks where detail matters. Both fine-tunes ship with the release (see Depth, image restoration and upscaling for usage).
Monocular depth — photo → relative depth, one forward pass:
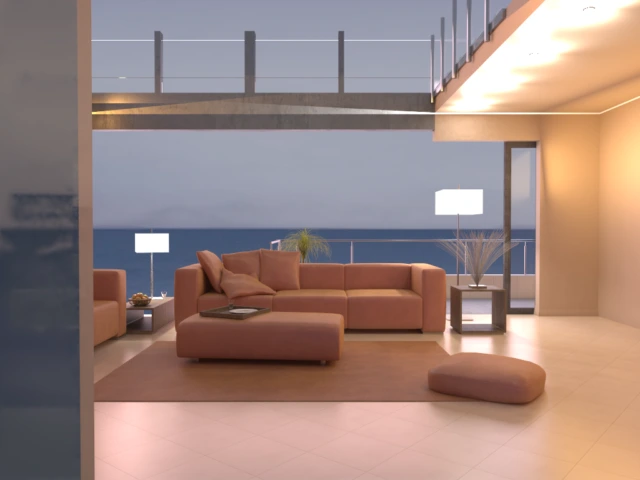 Photo | 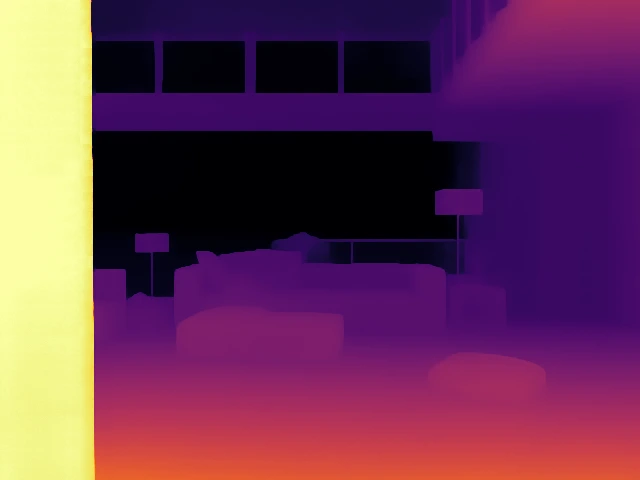 Iris-3B depth | 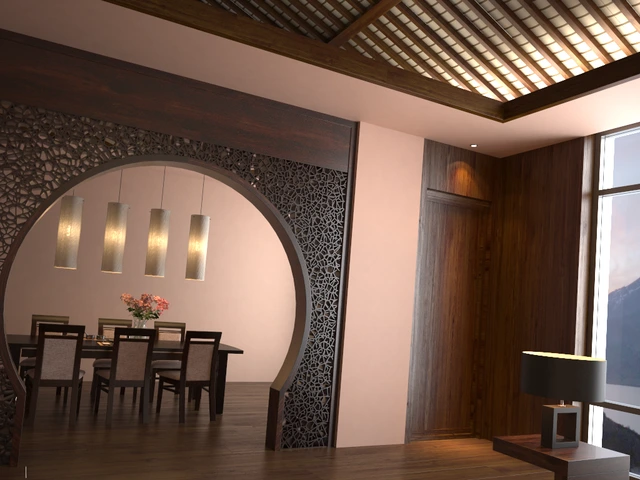 Photo | 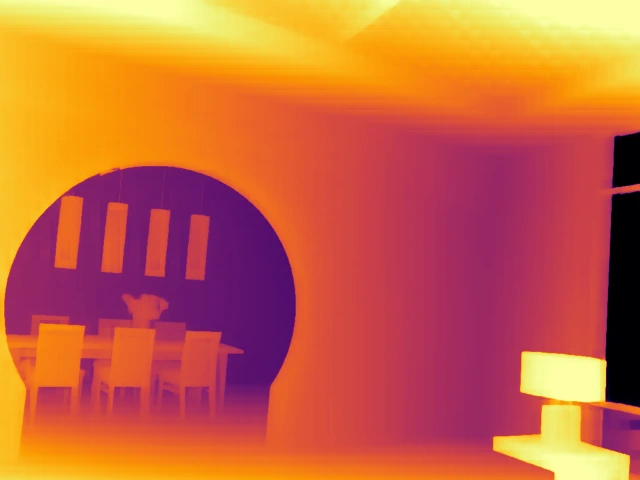 Iris-3B depth |
Image restoration and upscaling — degraded input → restored image:
 Input | 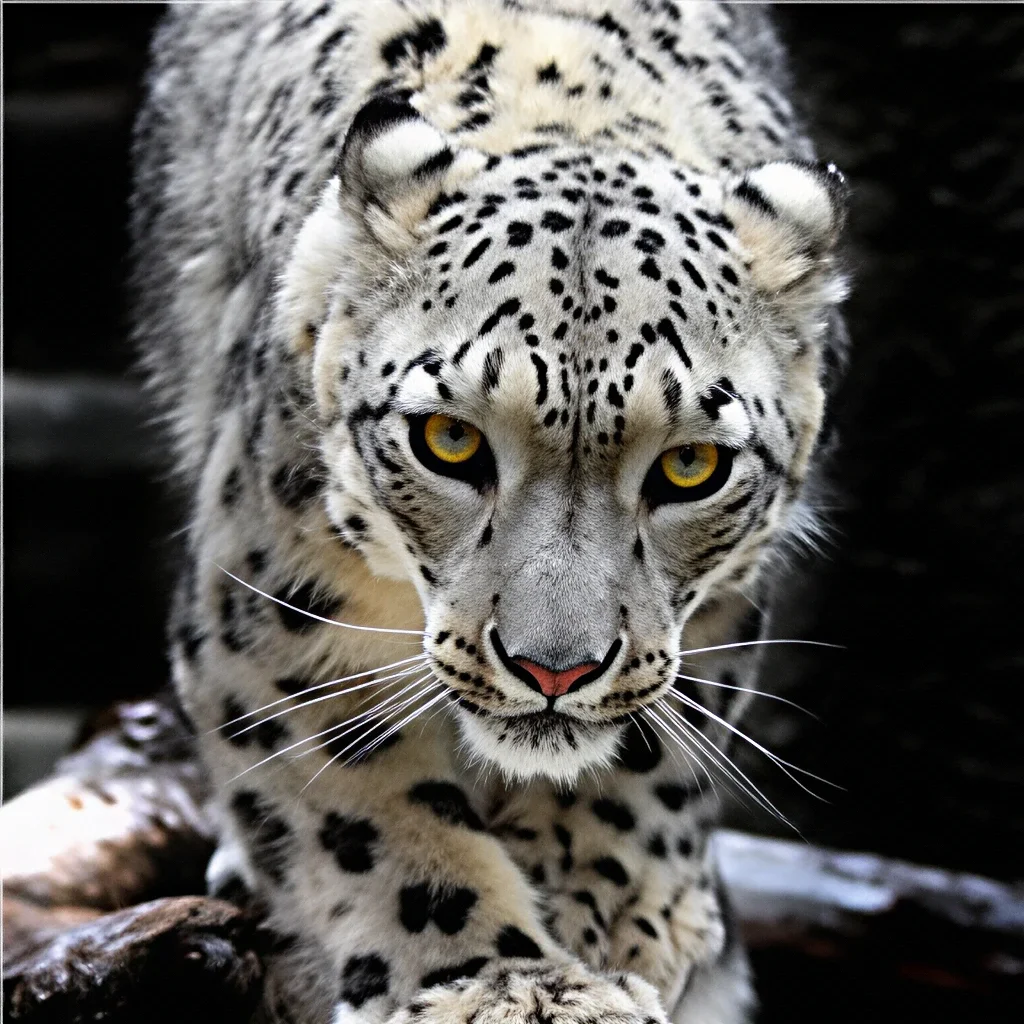 Iris-3B |  Input | 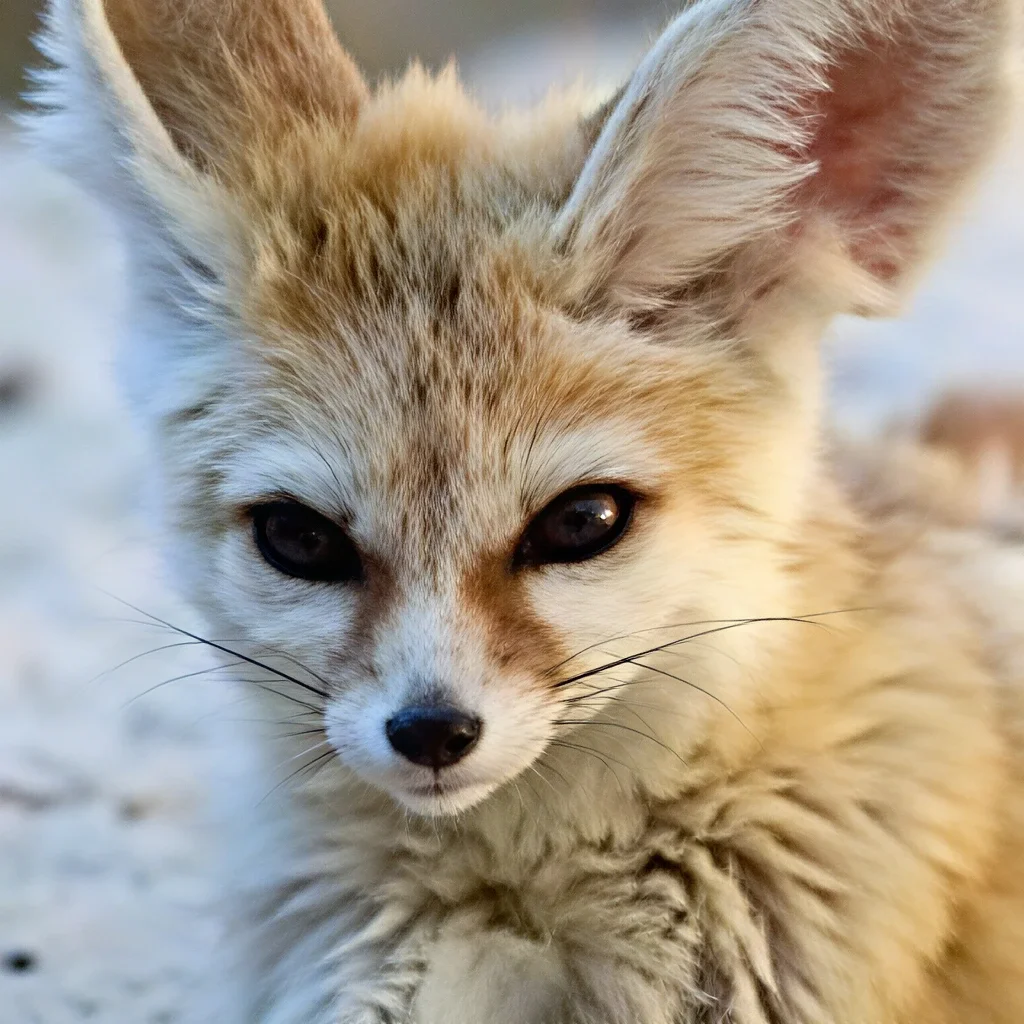 Iris-3B |
Interactive depth point clouds and before/after sliders: project page · demo.
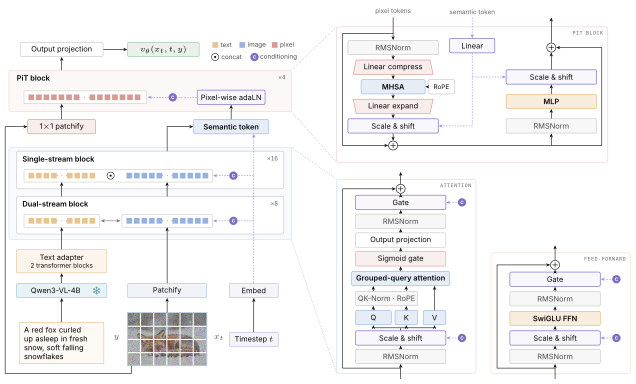
| Parameters | 3B (excluding the frozen text encoder) |
| Trunk | 24 blocks at width 2560: 8 dual-stream (separate image/text weights, joint attention) + 16 single-stream; GQA 20 query / 5 key-value heads, gated attention, sandwich RMSNorm, shared-bias adaLN |
| Patch size | 16 |
| Pixel head | 4 pixel-transformer (PiT) blocks: each patch is decoded back to pixels with per-pixel modulation, attending across patches |
| Text encoder | Qwen3-VL-4B-Instruct (frozen), 12 hidden layers aggregated by a learned layer-attention adapter |
| Objective | rectified flow, v-prediction, logit-normal timesteps |
pip install -e .            # Python >= 3.11, PyTorch >= 2.7.1
pip install -e ".[dev]"     # + pytest, ruff
Or with uv, which creates .venv and installs the package editable:
uv sync --extra dev         # add --extra ui for the demo
uv run pytest -q
uv run python scripts/sample.py --checkpoint iris-3b --prompt "..."
hf download speridlabs/iris-3b --local-dir iris-3b    # ~12 GB
python scripts/sample.py --checkpoint iris-3b \
    --prompt "a red fox sleeping in fresh snow, golden hour"
--checkpoint is a directory holding model.safetensors + config.yaml, or a
training .pth (its EMA weights and embedded config are used). Defaults:
1024×1024, 100 DPM-Solver++ (order 2) steps, CFG 3. Use --txt-file for a
prompt list, --steps, --seed, --negative-prompt to adjust. The device
defaults to CUDA, then Apple MPS, then CPU. On CUDA and MPS the weights are held
in BF16 (--weights-dtype fp32 keeps the FP32 release precision), which halves
their memory at the same speed, since inference runs under BF16 autocast either way.
Faster sampling, training-free (each trades some fidelity for speed; compare against the defaults on your prompts):
--steps 30: second-order DPM-Solver++ usually needs far fewer than the
default 100 steps; cost is linear in steps.--cfg-interval 0 0.9: skip CFG on the noisiest steps, which then cost one
forward instead of two (t = 1 is noise; with shift 4 about a third of the
steps lie above 0.9).--cache-threshold 0.1: reuse the trunk's output between adjacent steps
while the first block's input barely changes (first-block caching). A reused
step costs ~15% of a full one; the pixel head always runs on the current
image. 0 disables it; at most 3 steps in a row are reused.On an M3 Max (40-core GPU) a 1024×1024 forward takes ~6.4 s with CFG and ~3.1 s
without, so the defaults take ~11 min per image and --steps 30 --cfg-interval 0 0.9
~2.6 min; with --cache-threshold 0.1 on top, one measured image reused the
trunk on 18 of 30 steps and took 77 s.
scripts/distill_turbo.py distills the model into a 4-step LoRA with the
guidance baked in (DMD2: the student, the teacher and the DMD critic share one
frozen copy of the weights; only two rank-64 adapters train, from prompts
alone). Train at ~1 MP: the released checkpoint shows 16 px block artifacts at
512, which a 512 student would inherit.
python scripts/distill_turbo.py --checkpoint iris-3b --prompts prompts.txt \
    --out output/turbo --device cuda:0 --text-device cuda:1 --iters 3000
python scripts/sample.py --checkpoint iris-3b --lora output/turbo/latest/student.safetensors \
    --prompt "a red fox sleeping in fresh snow, golden hour"
--lora also takes a Hub id: --lora pentacoxian-dev/iris-3b-turbo-lora loads the published
default adapter, ...:r1-1500 a named one (the repo's config.json manifest lists them).
The adapter is merged into the weights at load, so a step costs one plain forward (no CFG batch): 4 steps at 1024² take ~11–13 s per image on an M3 Max and ~0.9 s on an RTX 5090.
demo/speed.py is a Gradio page that times every mode on the same prompt and
seed: Fast (the 4-step turbo LoRA, on its own merged bf16 copy so it runs at
sample.py speed; --live-lora saves the 6 GB at ~10% per step), Balanced (the
training-free 30-step settings) and Standard (the 100-step sampler). Models are
warmed up at launch. It reports
wall time, forward passes, time per forward, images per minute and the speed-up
over the 100-step sampler (measured once that has run, otherwise estimated from
measured forward times).
pip install -e ".[ui]"
python demo/speed.py --lora output/turbo/latest/student.safetensors   # http://127.0.0.1:7861
--preset mac16 fits a 16 GB Mac: the prompts are encoded in a short-lived
child process (the text encoder and the image model never coexist), the image
model is streamed onto the GPU tensor by tensor with the LoRA merged on the way,
weight-only int8 is applied to the text encoder and the image trunk
(--quantize none keeps bf16), and images are generated one at a time. Measured
on an M3 Max with GPU allocations capped at a 16 GB Mac's ~10.7 GB working set:
6.9 GB peak footprint and ~11 s per 1024² turbo image (base M-series GPUs are
slower). int8 kept text embeddings at cosine 0.9999 and images visually
unchanged (28–38 dB PSNR against bf16 on the 4-step sampler).
python scripts/sample.py --checkpoint iris-3b --preset mac16 \
    --lora output/turbo/latest/student.safetensors --prompt "a red fox sleeping in fresh snow"
| Peak memory (1024², turbo) | |
|---|---|
| FP32 weights, text encoder resident | 30.3 GB |
| BF16 weights (default), text encoder resident | 24.3 GB |
--preset mac16 --quantize none | 9.3 GB |
--preset mac16 (int8) | 6.9 GB |
Turn a training checkpoint into a release directory (EMA weights only, FP32 by default, config reduced to model/text-encoder/flow settings):
python scripts/export_checkpoint.py output/run/checkpoints/latest.pth exported/iris-3b
The release also ships Iris-3B fine-tuned for monocular depth estimation and
for image restoration and upscaling — the general-vision-learner side of
the model — in the depth/ and upscaler/ folders of the same Hugging Face
repo (~12 GB each). Both run the full model in
a single forward pass with the empty prompt, so no text encoder is loaded.
python scripts/depth.py photo.jpg --out depth_out      # <name>.npy + colorized <name>.png
python scripts/upscale.py photo.jpg --out upscaled     # <name>_x4.png
--max-side 0 keeps native resolution).--no-budget keeps the input size.Python API: iris3b.downstream.depth.DepthPredictor and
iris3b.downstream.restoration.Restorer. Fine-tuning checkpoints are converted
with scripts/export_downstream.py.
The Gradio app behind the Hugging Face Space
(text-to-image, depth and upscaling tabs) is in demo/; it runs on ZeroGPU
there and on any local GPU. All three models together take ~45 GB of GPU memory;
with IRIS_OFFLOAD=1 they stay on the CPU and each request moves only the model it
needs to the GPU (~20 GB peak), which is what the Space does:
pip install -e ".[ui]"
python demo/app.py          # IRIS_MODEL_REPO=<dir or repo id> to use other weights
Training reads tar shards indexed by a wids-meta.json. Each sample is an
image plus a JSON with its caption, height and width. Build them from a
folder of images with .txt/.json caption sidecars, or from a Hugging Face
dataset:
python scripts/prepare_wids.py folder /path/to/images --out /data/my-set
python scripts/prepare_wids.py hf user/dataset --split train \
    --image-column image --caption-column text --out /data/my-set
Iris-3B was trained in three resolution stages followed by supervised
fine-tuning, each resuming from the previous one. The configs list only what
differs from the defaults in src/iris3b/config.py:
| Config | Resolution | Steps | Global batch | Shift | Notes |
|---|---|---|---|---|---|
configs/iris3b/stage1_256.yaml | 256² | 0 → 365K | 1024 | 2 | REPA (DINOv2-B/14, weight 0.5) |
configs/iris3b/stage2_512.yaml | 512, multi-aspect | 365K → 530K | 1024 | 3 | |
configs/iris3b/stage3_1024.yaml | 1024, multi-aspect | 530K → 625K | 512 | 4 | LR 5e-5 |
configs/iris3b/sft_1024.yaml | 1024, multi-aspect | 625K → 665K | 512 | 4 | constant LR 4e-5, no warmup |
Common to all stages: hybrid Muon — Muon (momentum 0.95, Nesterov, RMS-matched
LR) for hidden weight matrices, AdamW (β₁ 0.9, β₂ 0.95) for embeddings, norms and
biases — with weight decay 0, gradient clipping at 0.5 and a constant LR of 1e-4
after a 2K-step linear warmup unless noted. EMA decay 0.9999, 10% caption dropout
for classifier-free guidance, logit-normal (0, 1) timesteps with the
resolution-dependent shift above. From the 512 stage on, RoPE uses isotropic
coordinates for non-square images. bf16, FSDP2 hybrid sharding, torch.compile.
Single node:
torchrun --nproc_per_node=8 scripts/train.py --config configs/iris3b/stage1_256.yaml \
    data.data_dirs=[/data/my-set] train.expected_global_batch=128
Multi-node (run on every node with its own NODE_RANK):
NNODES=8 NODE_RANK=0 MASTER_ADDR=node0 \
    scripts/launch_multinode.sh configs/iris3b/stage1_256.yaml data.data_dirs=[/data/my-set]
Any config key can be overridden as key=value after the config path.
pytest -q
The dual-level design (a patch-level transformer followed by a pixel-level transformer head) follows the architecture described in PixelDiT. This is an independent implementation; it contains no code from that project. We also build on DiT, REPA, Muon through Dion, Qwen3-VL and DINOv2.
The code in this repository and the model weights on Hugging Face are licensed under the Apache License 2.0; see also NOTICE.
Third-party components are not redistributed here and remain under their own licenses:
| Component | Use | License |
|---|---|---|
| Qwen3-VL-4B-Instruct | frozen text encoder, downloaded at runtime | Apache 2.0 |
| DINOv2 | REPA teacher (training only), downloaded at runtime | Apache 2.0 |
| Dion | Muon optimizer, pip dependency | MIT |
@article{licai2026iris,
  title   = {Iris-3B: Going Beyond the Latent with Pixel-Space
             Diffusion Training, Conversion and Fine-Tuning},
  author  = {Li Cai, Hanqiu and Garabito, Chema},
  journal = {arXiv preprint arXiv:2610.09450},
  year    = {2026},
  url     = {https://arxiv.org/abs/2610.09450}
}
Made with ❤️ by speridlabs.com
Iris-3B: pixel-space generation & general vision learner. A 3B diffusion transformer that generates every pixel directly (no VAE); the same prior, fine-tuned, does monocular depth estimation and 4x image restoration. Paper, weights, training code and demo.
See the codePixel-space generation & general vision learner
Generative priors are a promising foundation for downstream vision tasks. In this project we explore pixel-space generative models as an alternative to vision foundation models such as DINOv2.
Iris-3B is a 3B-parameter diffusion transformer that generates directly in pixel space: no VAE, no latent space, every pixel is produced by the model, so nothing is lost to a lossy, texture-biased latent. It is not only an image generator: the same pixel-space prior, fine-tuned, estimates monocular depth and restores and upscales images — one backbone, three tasks. This repository contains the model, the training and fine-tuning code, and inference.
https://github.com/user-attachments/assets/2345a853-c673-4ddb-83b9-7e05c83198ed
Samples from the final checkpoint at native aspect ratios of about one megapixel (CFG 3, 100 steps, one fixed seed, no prompt rewriting).
Studio portrait of a Maasai elder wearing vibrant beaded jewelry, deep red cloth, dark backdrop, Rembrandt lighting, ultra detailed skin texture | Close-up portrait of a young woman with silver glitter freckles and iridescent makeup, soft pastel background, high fashion beauty photography | A glass sculpture of a heart filled with flowers, caustics and reflections, 3D render |
Black and white portrait of a fisherman with a thick grey beard and deep wrinkles, piercing eyes, overcast light, fine grain film photograph | A Byzantine-style mosaic of a peacock made of tiny gold and turquoise tiles, shimmering texture | A bronze sculpture of a horse in motion, patina, dramatic museum spotlight |
The ancient city of Petra with the Treasury carved into pink sandstone, morning light | A tree with lightbulbs instead of fruits glowing at dusk, surreal concept art | Thousands of sky lanterns rising into the night sky at Yi Peng festival in Chiang Mai |
The aurora borealis swirling green and violet over a snowy Lofoten fishing village with red wooden cabins, reflections in a calm fjord, night photograph | Volcanic eruption at night in Iceland, rivers of glowing lava flowing across black fields, plumes of steam lit orange, long exposure |
More samples: project page.
Iris-3B is a general vision learner, not only a text-to-image model: the same pixel-space backbone, fine-tuned with no architectural change, does dense vision tasks where detail matters. Both fine-tunes ship with the release (see Depth, image restoration and upscaling for usage).
Monocular depth — photo → relative depth, one forward pass:
Photo | Iris-3B depth | Photo | Iris-3B depth |
Image restoration and upscaling — degraded input → restored image:
Input | Iris-3B | Input | Iris-3B |
Interactive depth point clouds and before/after sliders: project page · demo.
| Parameters | 3B (excluding the frozen text encoder) |
| Trunk | 24 blocks at width 2560: 8 dual-stream (separate image/text weights, joint attention) + 16 single-stream; GQA 20 query / 5 key-value heads, gated attention, sandwich RMSNorm, shared-bias adaLN |
| Patch size | 16 |
| Pixel head | 4 pixel-transformer (PiT) blocks: each patch is decoded back to pixels with per-pixel modulation, attending across patches |
| Text encoder | Qwen3-VL-4B-Instruct (frozen), 12 hidden layers aggregated by a learned layer-attention adapter |
| Objective | rectified flow, v-prediction, logit-normal timesteps |
pip install -e .            # Python >= 3.11, PyTorch >= 2.7.1
pip install -e ".[dev]"     # + pytest, ruff
Or with uv, which creates .venv and installs the package editable:
uv sync --extra dev         # add --extra ui for the demo
uv run pytest -q
uv run python scripts/sample.py --checkpoint iris-3b --prompt "..."
hf download speridlabs/iris-3b --local-dir iris-3b    # ~12 GB
python scripts/sample.py --checkpoint iris-3b \
    --prompt "a red fox sleeping in fresh snow, golden hour"
--checkpoint is a directory holding model.safetensors + config.yaml, or a
training .pth (its EMA weights and embedded config are used). Defaults:
1024×1024, 100 DPM-Solver++ (order 2) steps, CFG 3. Use --txt-file for a
prompt list, --steps, --seed, --negative-prompt to adjust. The device
defaults to CUDA, then Apple MPS, then CPU. On CUDA and MPS the weights are held
in BF16 (--weights-dtype fp32 keeps the FP32 release precision), which halves
their memory at the same speed, since inference runs under BF16 autocast either way.
Faster sampling, training-free (each trades some fidelity for speed; compare against the defaults on your prompts):
--steps 30: second-order DPM-Solver++ usually needs far fewer than the
default 100 steps; cost is linear in steps.--cfg-interval 0 0.9: skip CFG on the noisiest steps, which then cost one
forward instead of two (t = 1 is noise; with shift 4 about a third of the
steps lie above 0.9).--cache-threshold 0.1: reuse the trunk's output between adjacent steps
while the first block's input barely changes (first-block caching). A reused
step costs ~15% of a full one; the pixel head always runs on the current
image. 0 disables it; at most 3 steps in a row are reused.On an M3 Max (40-core GPU) a 1024×1024 forward takes ~6.4 s with CFG and ~3.1 s
without, so the defaults take ~11 min per image and --steps 30 --cfg-interval 0 0.9
~2.6 min; with --cache-threshold 0.1 on top, one measured image reused the
trunk on 18 of 30 steps and took 77 s.
scripts/distill_turbo.py distills the model into a 4-step LoRA with the
guidance baked in (DMD2: the student, the teacher and the DMD critic share one
frozen copy of the weights; only two rank-64 adapters train, from prompts
alone). Train at ~1 MP: the released checkpoint shows 16 px block artifacts at
512, which a 512 student would inherit.
python scripts/distill_turbo.py --checkpoint iris-3b --prompts prompts.txt \
    --out output/turbo --device cuda:0 --text-device cuda:1 --iters 3000
python scripts/sample.py --checkpoint iris-3b --lora output/turbo/latest/student.safetensors \
    --prompt "a red fox sleeping in fresh snow, golden hour"
--lora also takes a Hub id: --lora pentacoxian-dev/iris-3b-turbo-lora loads the published
default adapter, ...:r1-1500 a named one (the repo's config.json manifest lists them).
The adapter is merged into the weights at load, so a step costs one plain forward (no CFG batch): 4 steps at 1024² take ~11–13 s per image on an M3 Max and ~0.9 s on an RTX 5090.
demo/speed.py is a Gradio page that times every mode on the same prompt and
seed: Fast (the 4-step turbo LoRA, on its own merged bf16 copy so it runs at
sample.py speed; --live-lora saves the 6 GB at ~10% per step), Balanced (the
training-free 30-step settings) and Standard (the 100-step sampler). Models are
warmed up at launch. It reports
wall time, forward passes, time per forward, images per minute and the speed-up
over the 100-step sampler (measured once that has run, otherwise estimated from
measured forward times).
pip install -e ".[ui]"
python demo/speed.py --lora output/turbo/latest/student.safetensors   # http://127.0.0.1:7861
--preset mac16 fits a 16 GB Mac: the prompts are encoded in a short-lived
child process (the text encoder and the image model never coexist), the image
model is streamed onto the GPU tensor by tensor with the LoRA merged on the way,
weight-only int8 is applied to the text encoder and the image trunk
(--quantize none keeps bf16), and images are generated one at a time. Measured
on an M3 Max with GPU allocations capped at a 16 GB Mac's ~10.7 GB working set:
6.9 GB peak footprint and ~11 s per 1024² turbo image (base M-series GPUs are
slower). int8 kept text embeddings at cosine 0.9999 and images visually
unchanged (28–38 dB PSNR against bf16 on the 4-step sampler).
python scripts/sample.py --checkpoint iris-3b --preset mac16 \
    --lora output/turbo/latest/student.safetensors --prompt "a red fox sleeping in fresh snow"
| Peak memory (1024², turbo) | |
|---|---|
| FP32 weights, text encoder resident | 30.3 GB |
| BF16 weights (default), text encoder resident | 24.3 GB |
--preset mac16 --quantize none | 9.3 GB |
--preset mac16 (int8) | 6.9 GB |
Turn a training checkpoint into a release directory (EMA weights only, FP32 by default, config reduced to model/text-encoder/flow settings):
python scripts/export_checkpoint.py output/run/checkpoints/latest.pth exported/iris-3b
The release also ships Iris-3B fine-tuned for monocular depth estimation and
for image restoration and upscaling — the general-vision-learner side of
the model — in the depth/ and upscaler/ folders of the same Hugging Face
repo (~12 GB each). Both run the full model in
a single forward pass with the empty prompt, so no text encoder is loaded.
python scripts/depth.py photo.jpg --out depth_out      # <name>.npy + colorized <name>.png
python scripts/upscale.py photo.jpg --out upscaled     # <name>_x4.png
--max-side 0 keeps native resolution).--no-budget keeps the input size.Python API: iris3b.downstream.depth.DepthPredictor and
iris3b.downstream.restoration.Restorer. Fine-tuning checkpoints are converted
with scripts/export_downstream.py.
The Gradio app behind the Hugging Face Space
(text-to-image, depth and upscaling tabs) is in demo/; it runs on ZeroGPU
there and on any local GPU. All three models together take ~45 GB of GPU memory;
with IRIS_OFFLOAD=1 they stay on the CPU and each request moves only the model it
needs to the GPU (~20 GB peak), which is what the Space does:
pip install -e ".[ui]"
python demo/app.py          # IRIS_MODEL_REPO=<dir or repo id> to use other weights
Training reads tar shards indexed by a wids-meta.json. Each sample is an
image plus a JSON with its caption, height and width. Build them from a
folder of images with .txt/.json caption sidecars, or from a Hugging Face
dataset:
python scripts/prepare_wids.py folder /path/to/images --out /data/my-set
python scripts/prepare_wids.py hf user/dataset --split train \
    --image-column image --caption-column text --out /data/my-set
Iris-3B was trained in three resolution stages followed by supervised
fine-tuning, each resuming from the previous one. The configs list only what
differs from the defaults in src/iris3b/config.py:
| Config | Resolution | Steps | Global batch | Shift | Notes |
|---|---|---|---|---|---|
configs/iris3b/stage1_256.yaml | 256² | 0 → 365K | 1024 | 2 | REPA (DINOv2-B/14, weight 0.5) |
configs/iris3b/stage2_512.yaml | 512, multi-aspect | 365K → 530K | 1024 | 3 | |
configs/iris3b/stage3_1024.yaml | 1024, multi-aspect | 530K → 625K | 512 | 4 | LR 5e-5 |
configs/iris3b/sft_1024.yaml | 1024, multi-aspect | 625K → 665K | 512 | 4 | constant LR 4e-5, no warmup |
Common to all stages: hybrid Muon — Muon (momentum 0.95, Nesterov, RMS-matched
LR) for hidden weight matrices, AdamW (β₁ 0.9, β₂ 0.95) for embeddings, norms and
biases — with weight decay 0, gradient clipping at 0.5 and a constant LR of 1e-4
after a 2K-step linear warmup unless noted. EMA decay 0.9999, 10% caption dropout
for classifier-free guidance, logit-normal (0, 1) timesteps with the
resolution-dependent shift above. From the 512 stage on, RoPE uses isotropic
coordinates for non-square images. bf16, FSDP2 hybrid sharding, torch.compile.
Single node:
torchrun --nproc_per_node=8 scripts/train.py --config configs/iris3b/stage1_256.yaml \
    data.data_dirs=[/data/my-set] train.expected_global_batch=128
Multi-node (run on every node with its own NODE_RANK):
NNODES=8 NODE_RANK=0 MASTER_ADDR=node0 \
    scripts/launch_multinode.sh configs/iris3b/stage1_256.yaml data.data_dirs=[/data/my-set]
Any config key can be overridden as key=value after the config path.
pytest -q
The dual-level design (a patch-level transformer followed by a pixel-level transformer head) follows the architecture described in PixelDiT. This is an independent implementation; it contains no code from that project. We also build on DiT, REPA, Muon through Dion, Qwen3-VL and DINOv2.
The code in this repository and the model weights on Hugging Face are licensed under the Apache License 2.0; see also NOTICE.
Third-party components are not redistributed here and remain under their own licenses:
| Component | Use | License |
|---|---|---|
| Qwen3-VL-4B-Instruct | frozen text encoder, downloaded at runtime | Apache 2.0 |
| DINOv2 | REPA teacher (training only), downloaded at runtime | Apache 2.0 |
| Dion | Muon optimizer, pip dependency | MIT |
@article{licai2026iris,
  title   = {Iris-3B: Going Beyond the Latent with Pixel-Space
             Diffusion Training, Conversion and Fine-Tuning},
  author  = {Li Cai, Hanqiu and Garabito, Chema},
  journal = {arXiv preprint arXiv:2610.09450},
  year    = {2026},
  url     = {https://arxiv.org/abs/2610.09450}
}
Made with ❤️ by speridlabs.com





