This repository contains our course project materials for "Large Language Models for Natural Language Processing" designed by Dr. Sasha Apartsin. Here you will find our project presentations, code, datasets, results, and visual abstract.
Python
0
93 commits
updated Feb 3, 2026
Banking Compliance Made Intelligent: Navigating regulatory complexity with RAG-enhanced Fine-Tuned LLMs.


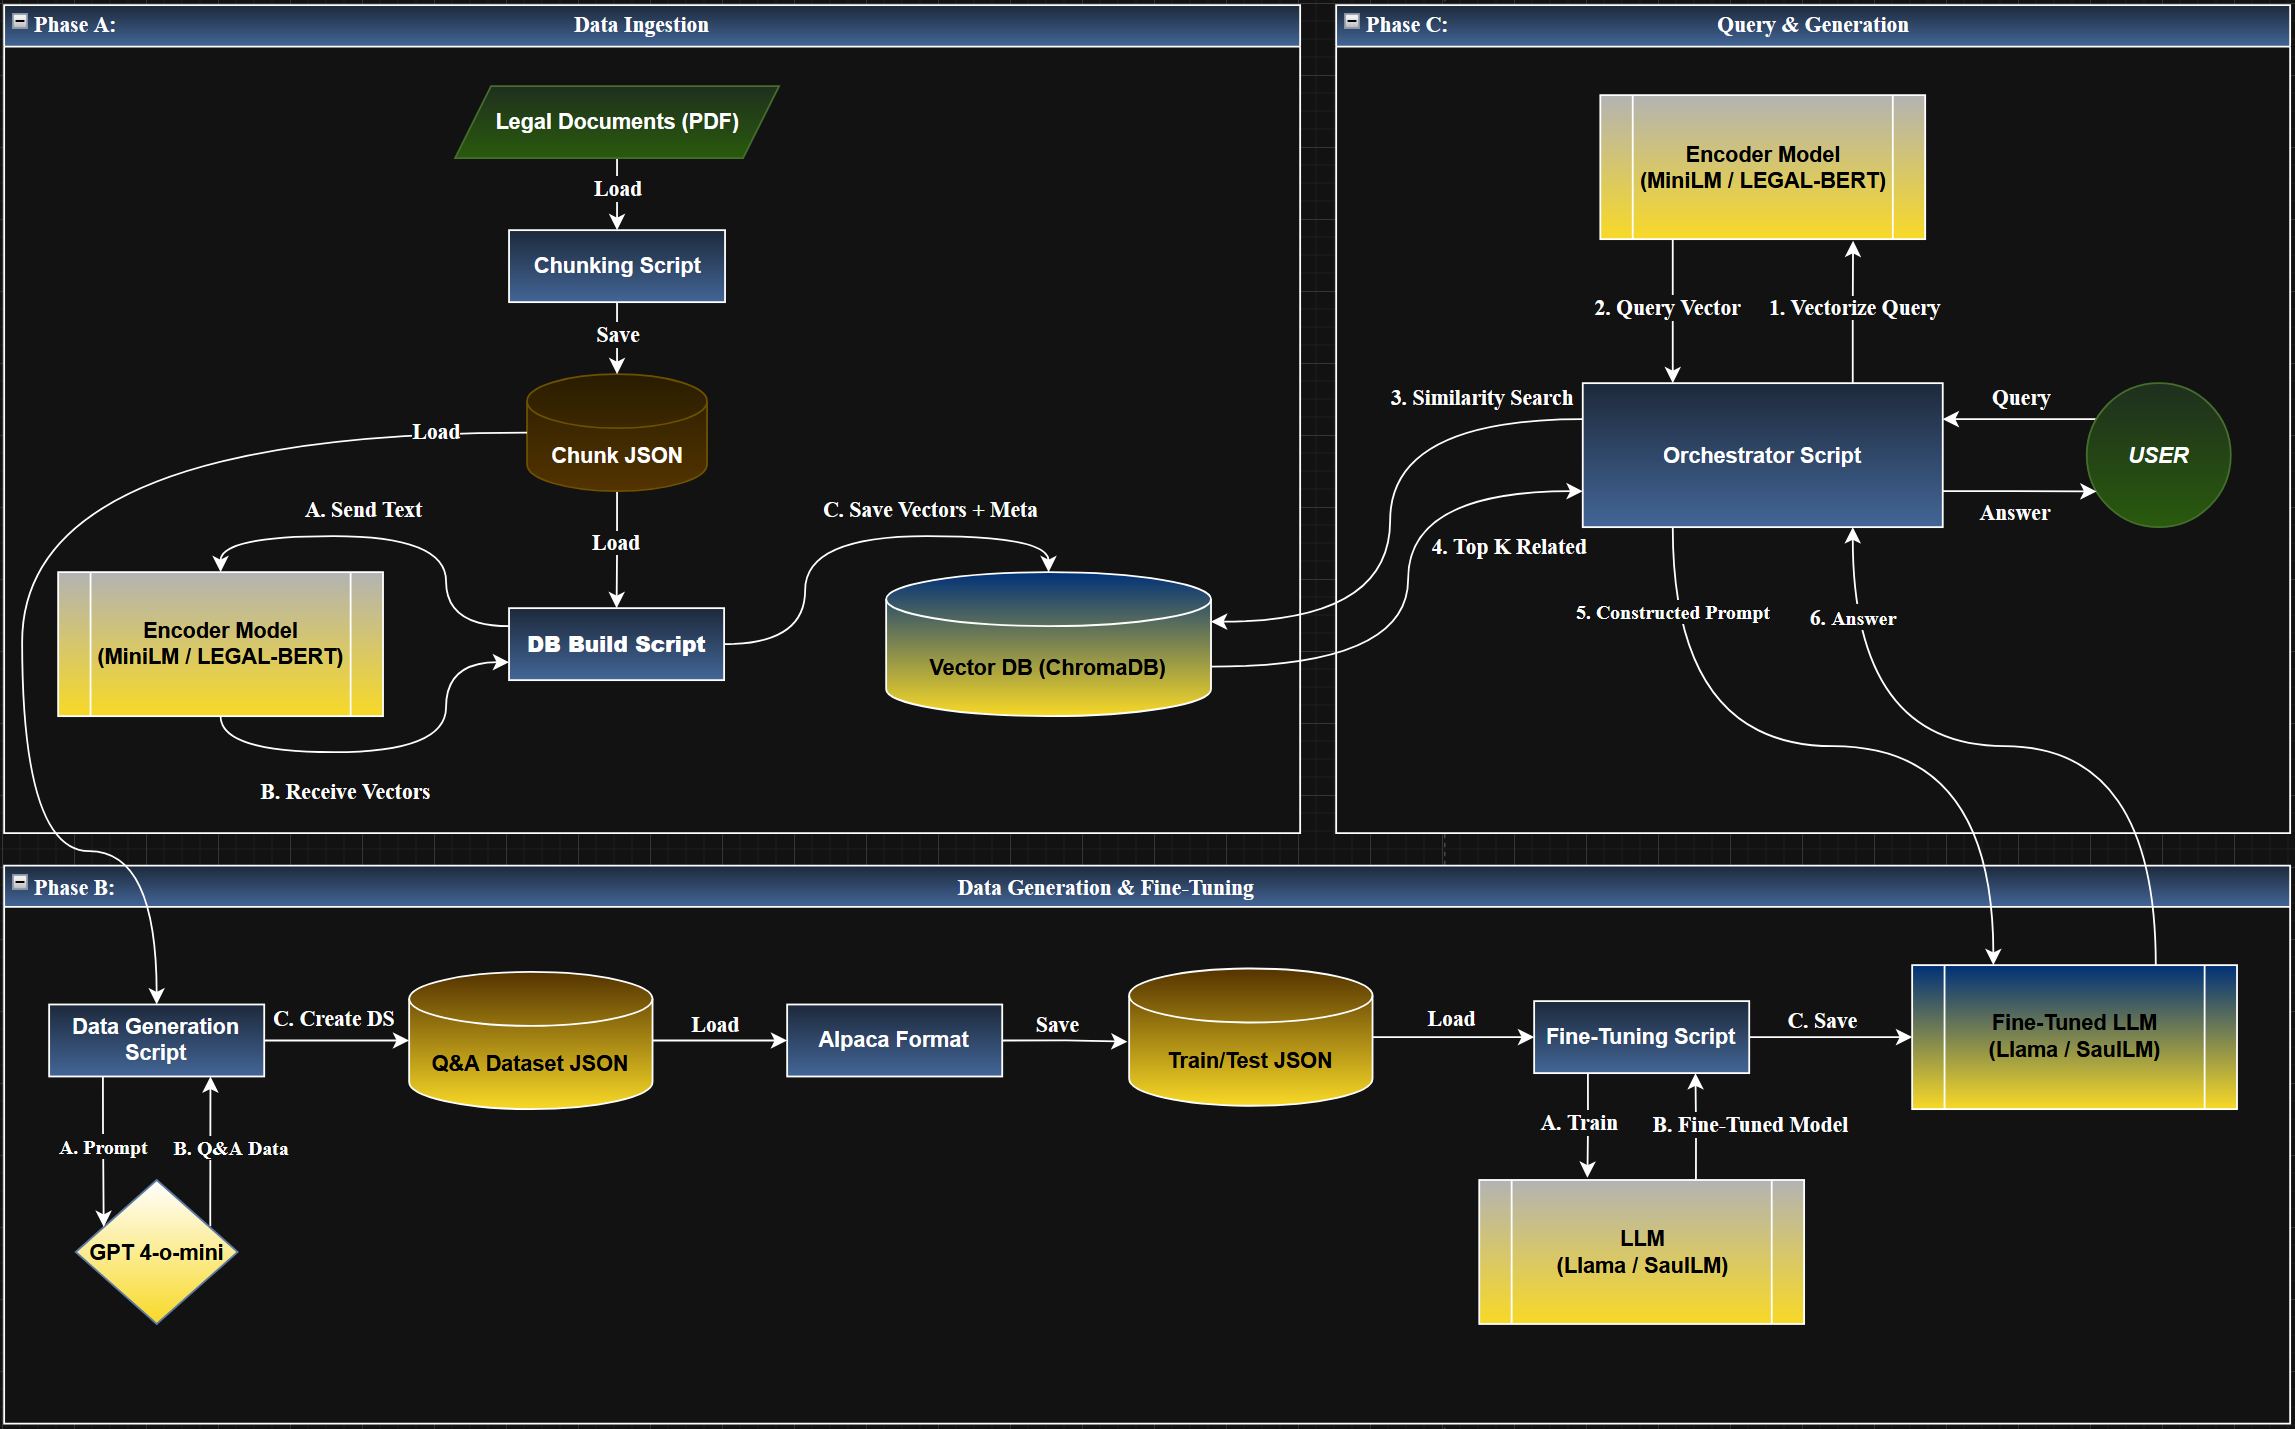
Banking compliance is a major bottleneck due to dense, constantly changing regulations scattered across multiple sources. RegulAItions centralizes these documents in one searchable place and uses modern LLMs to provide instant, structured, and verifiable regulatory insights. ⚖️
General-purpose LLMs are inadequate for banking compliance due to three fundamental failures:
Hallucinations: Models behave like stochastic parrots, fabricating rules when evidence is missing. 🦜
Domain Gap: They lack fluency in Israeli banking terminology and regulatory semantics. 🏦
Unstructured Output: They default to conversational prose instead of machine-consumable JSON required by compliance systems. 📄➡️🧾
📁 Data Used:
Source Material: 6 official Bank of Israel PDF circulars.
Vector Database (RAG): 518 optimized text chunks stored in ChromaDB as high-dimensional vector embeddings. 🔍
🔧 Data Augmentation & Generation:
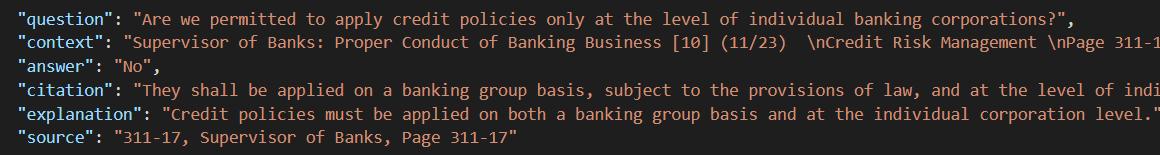
Fine-Tuning Gold Set: 2,000+ generated structured Queries, each sample contains query, response, verdict, and exact document location.
Hallucination Training: 15–20% Negative Samples (Hard & Soft). These force the model to output "N.A" when evidence is absent, reducing hallucinations and overconfidence. 🛡️
🤖 Generative Models (LLMs):
🔎 Embedding Models (Encoders):
⚙️ Training Setup
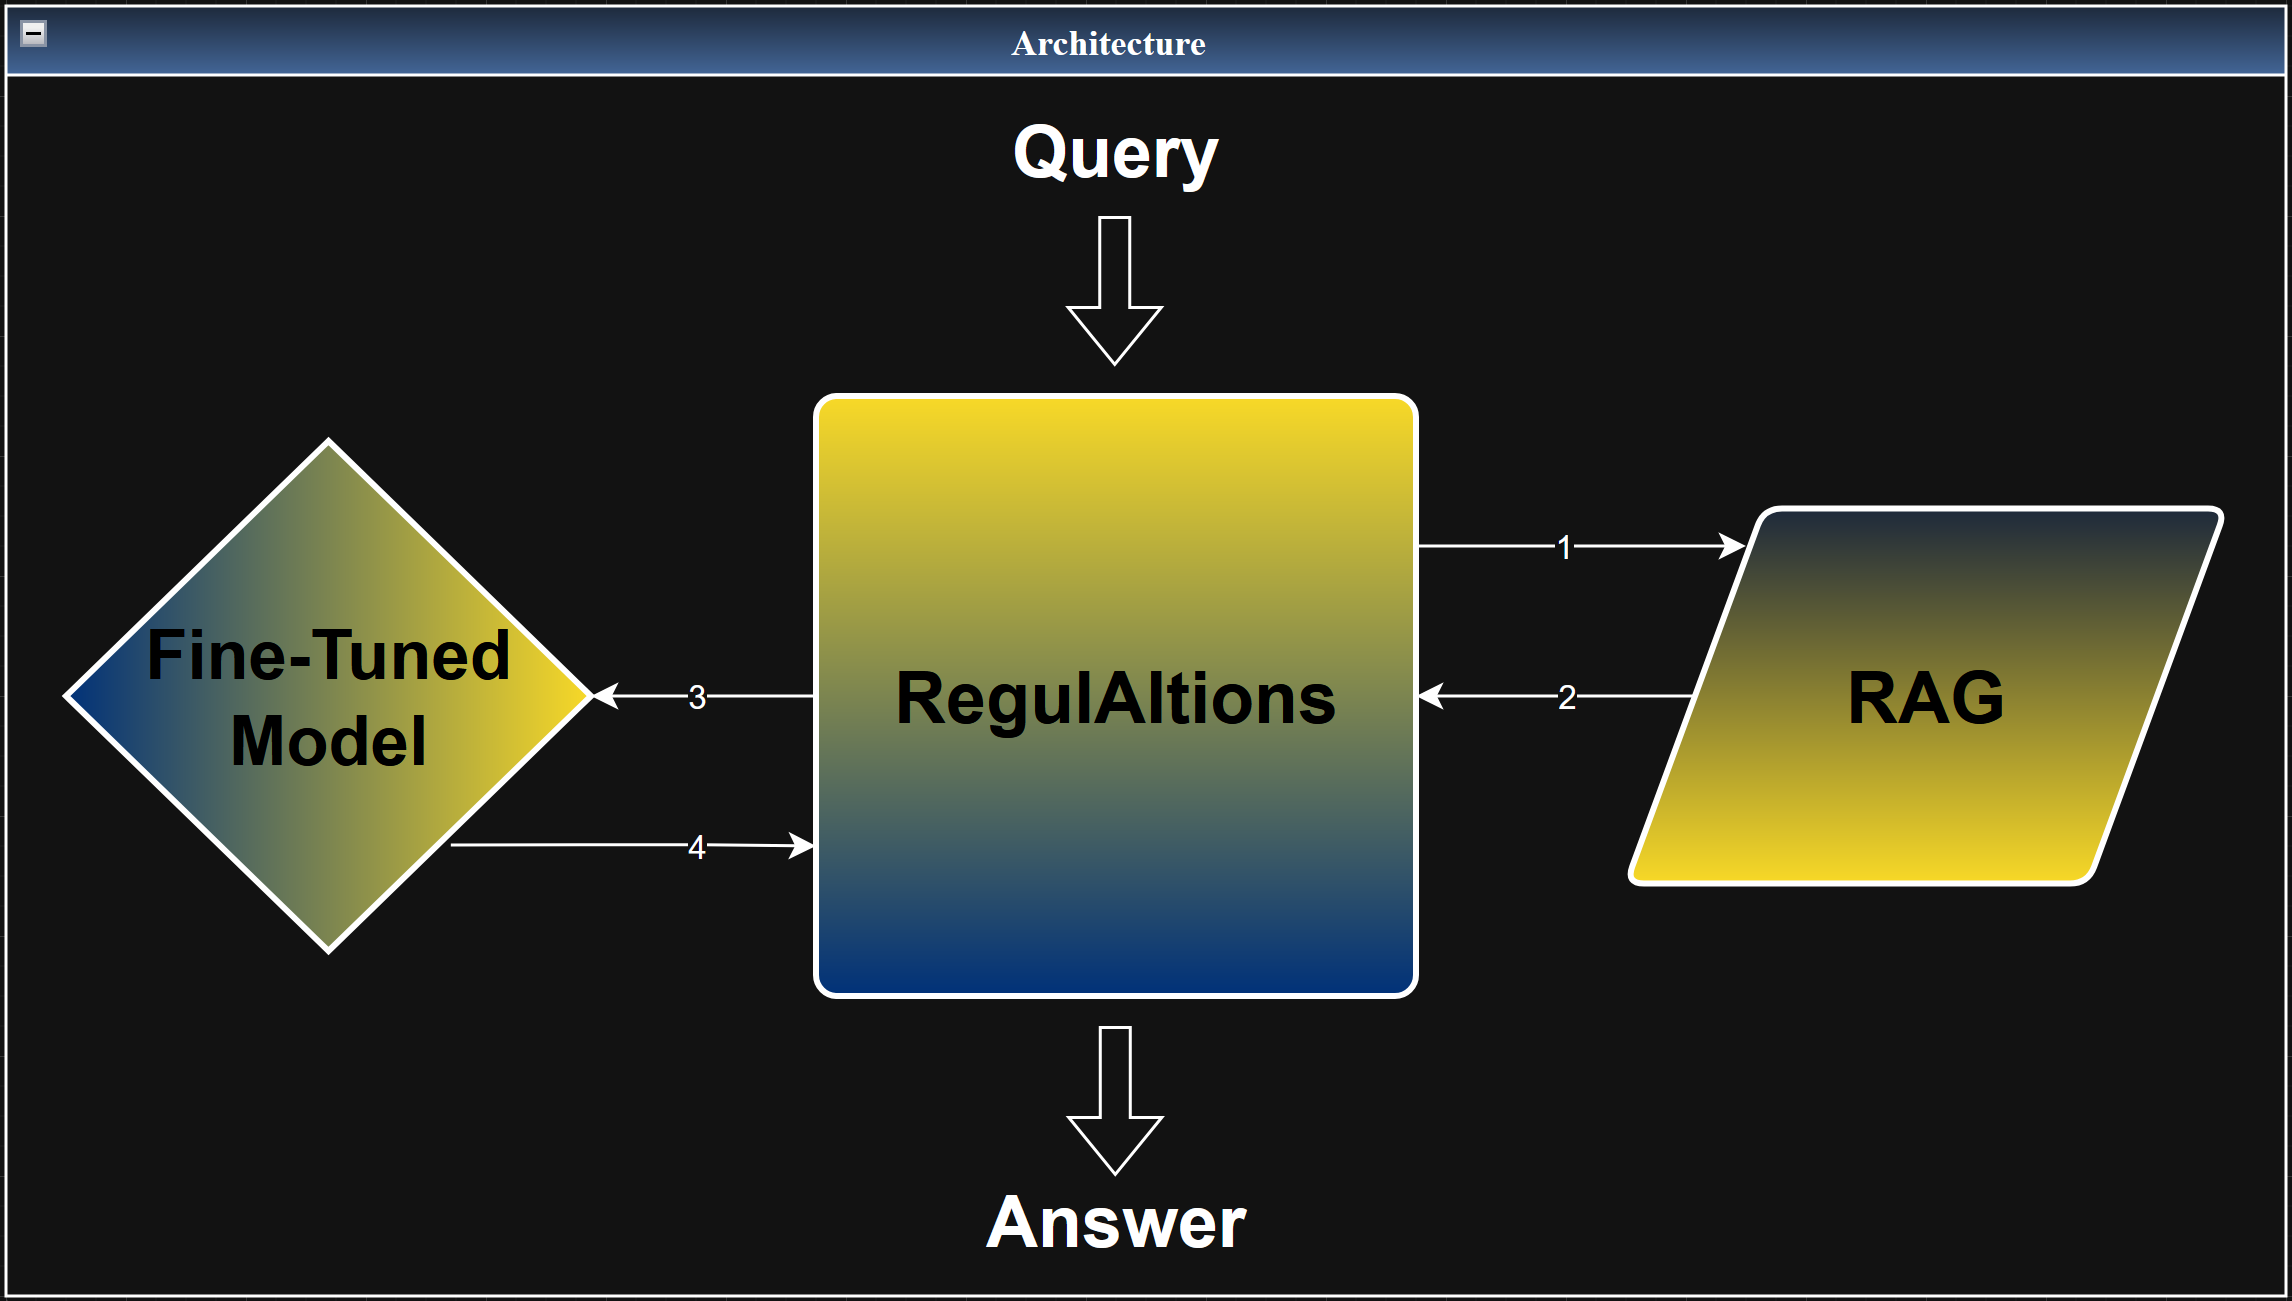
📖 RAG (The “What”)
🧠 Fine-Tuning (The “How”)
🔀Integration
Input:
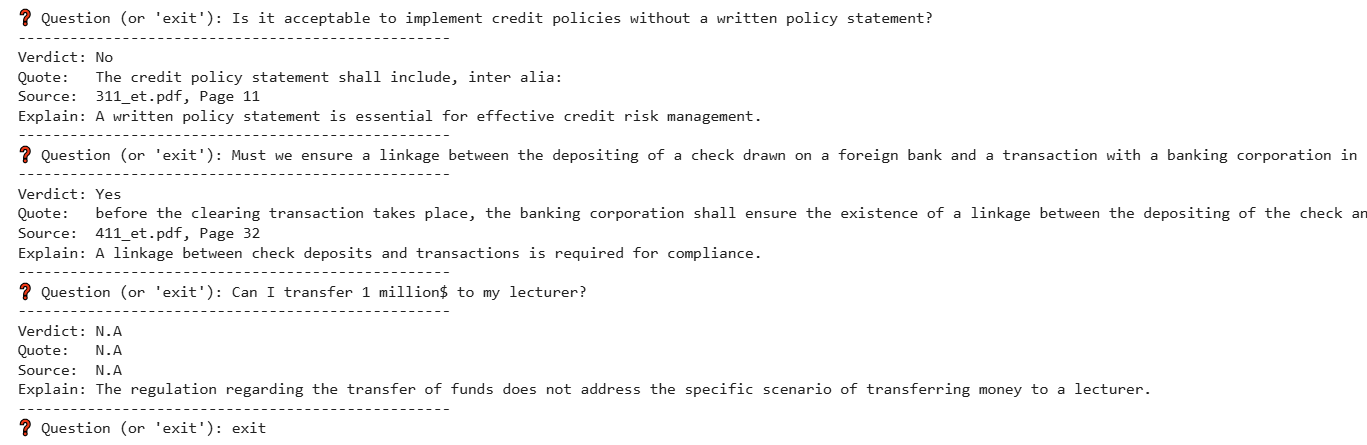
Output (Strict JSON):
{
"verdict": "Yes | No | N.A",
"quote": "citation anwser is based on",
"source": "Circular Name, Page Number",
"explanation": "grounded text reasoning"
}
📏 Metrics:
📈 Results:
Key Finding: SaulLM + all-MiniLM achieved the highest precision on complex legal reasoning tasks. 🏆
📁Presentations – Proposal, interim, and final presentations
📁Environment_dependencies - Libraries and environment settings
📁Code – Implementation
📁Data – Datasets
📁Models - Saved model weights and configurations
📁Results – Model evaluation metrics and outputs
📁Visuals – Diagrams, visual abstracts, and illustrations
📁Resources – Supplementary materials and external references
This repository contains our course project materials for "Large Language Models for Natural Language Processing" designed by Dr. Sasha Apartsin. Here you will find our project presentations, code, datasets, results, and visual abstract.
Python
0
93 commits
updated Feb 3, 2026
Banking Compliance Made Intelligent: Navigating regulatory complexity with RAG-enhanced Fine-Tuned LLMs.
Banking compliance is a major bottleneck due to dense, constantly changing regulations scattered across multiple sources. RegulAItions centralizes these documents in one searchable place and uses modern LLMs to provide instant, structured, and verifiable regulatory insights. ⚖️
General-purpose LLMs are inadequate for banking compliance due to three fundamental failures:
Hallucinations: Models behave like stochastic parrots, fabricating rules when evidence is missing. 🦜
Domain Gap: They lack fluency in Israeli banking terminology and regulatory semantics. 🏦
Unstructured Output: They default to conversational prose instead of machine-consumable JSON required by compliance systems. 📄➡️🧾
📁 Data Used:
Source Material: 6 official Bank of Israel PDF circulars.
Vector Database (RAG): 518 optimized text chunks stored in ChromaDB as high-dimensional vector embeddings. 🔍
🔧 Data Augmentation & Generation:
Fine-Tuning Gold Set: 2,000+ generated structured Queries, each sample contains query, response, verdict, and exact document location.
Hallucination Training: 15–20% Negative Samples (Hard & Soft). These force the model to output "N.A" when evidence is absent, reducing hallucinations and overconfidence. 🛡️
🤖 Generative Models (LLMs):
🔎 Embedding Models (Encoders):
⚙️ Training Setup
📖 RAG (The “What”)
🧠 Fine-Tuning (The “How”)
🔀Integration
Input:
Output (Strict JSON):
{
"verdict": "Yes | No | N.A",
"quote": "citation anwser is based on",
"source": "Circular Name, Page Number",
"explanation": "grounded text reasoning"
}
📏 Metrics:
📈 Results:
Key Finding: SaulLM + all-MiniLM achieved the highest precision on complex legal reasoning tasks. 🏆
📁Presentations – Proposal, interim, and final presentations
📁Environment_dependencies - Libraries and environment settings
📁Code – Implementation
📁Data – Datasets
📁Models - Saved model weights and configurations
📁Results – Model evaluation metrics and outputs
📁Visuals – Diagrams, visual abstracts, and illustrations
📁Resources – Supplementary materials and external references