
Open-source long-term, time-aware memory engine for AI agents (MCP + hybrid search + bi-temporal recall)
See the codeSee what people are saying
README
Nexusyn Engine
Long-Term, Time-Aware Memory Engine for AI Agents
Stop building agents that forget. Give your LLMs persistent, grounded memory across sessions.


Quickstart • MCP Integration • Architecture • Benchmarks • Cloud vs Self-Hosted • Documentation
The Problem: Why Vector Databases Alone Aren't "Memory"
Most AI agent frameworks implement memory by taking the last conversation turn, calculating an embedding, and storing it in a vector database.
When the agent queries this "memory", it runs a simple nearest-neighbor search. This breaks down in production:
- Vectors don't understand time: If a user says "I live in Berlin" in January and "I moved to Madrid" in August, both vectors have identical semantic similarity to "Where do I live?". A pure vector search frequently returns the outdated fact.
- Context window bloat: Dumping raw matching chunks into the prompt forces the LLM to resolve contradictions, inflating token costs and increasing hallucination rates.
- No entity understanding: Vector similarity misses relational facts that don't share keywords (e.g. connecting a bug report to the architecture decision that caused it).
The Solution: How Nexusyn Works
Nexusyn is a dedicated data plane engine designed specifically for agentic long-term memory:
- 🕓 Bi-Temporal Versioning: Every fact is stamped with transaction time and valid time (
valid_from/valid_to). New statements supersede older ones automatically without deleting history. - 🔀 Hybrid Retrieval (RRF): Fuses dense vector similarity (
pgvectorHNSW) + BM25 full-text search + entity graph expansion + recency & date-anchor boosts using Reciprocal Rank Fusion. - 🎯 Reranking: High-precision cross-encoder re-scoring of candidate chunks before generation.
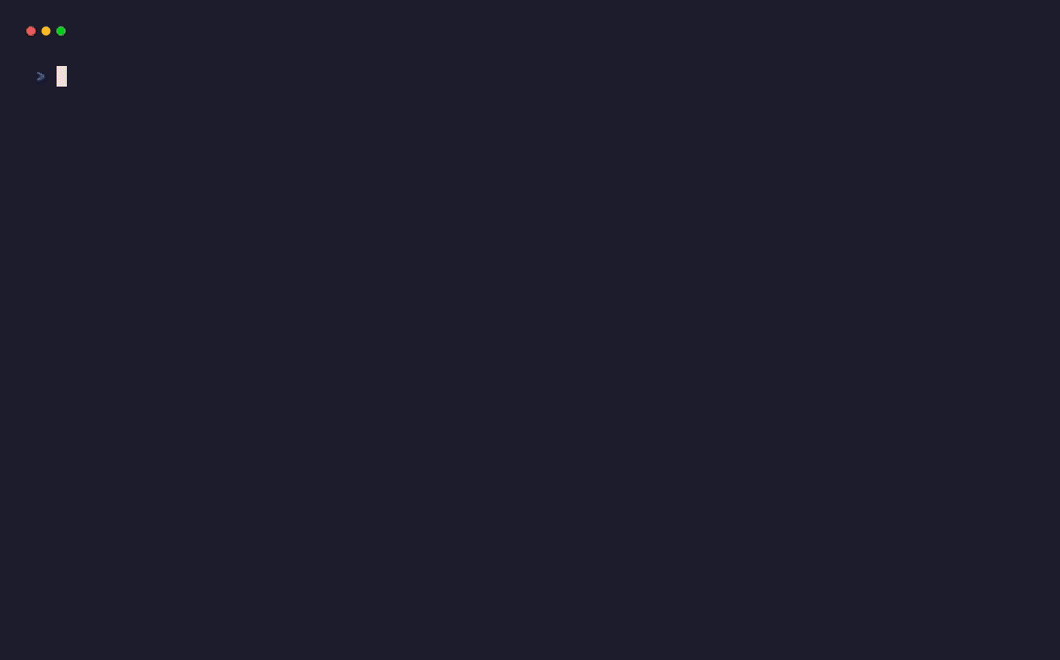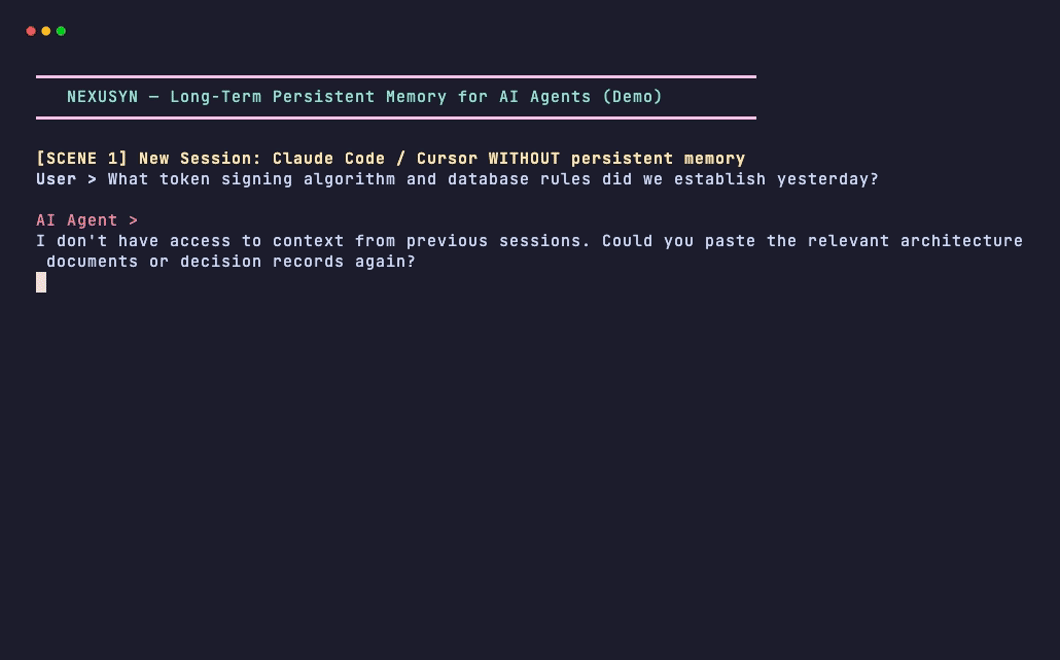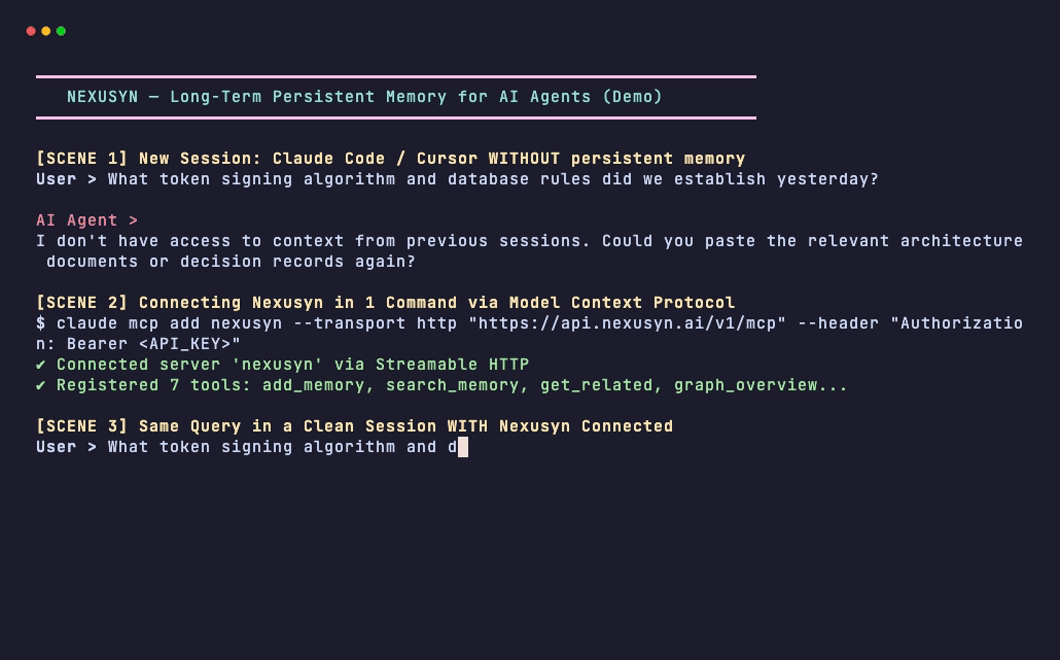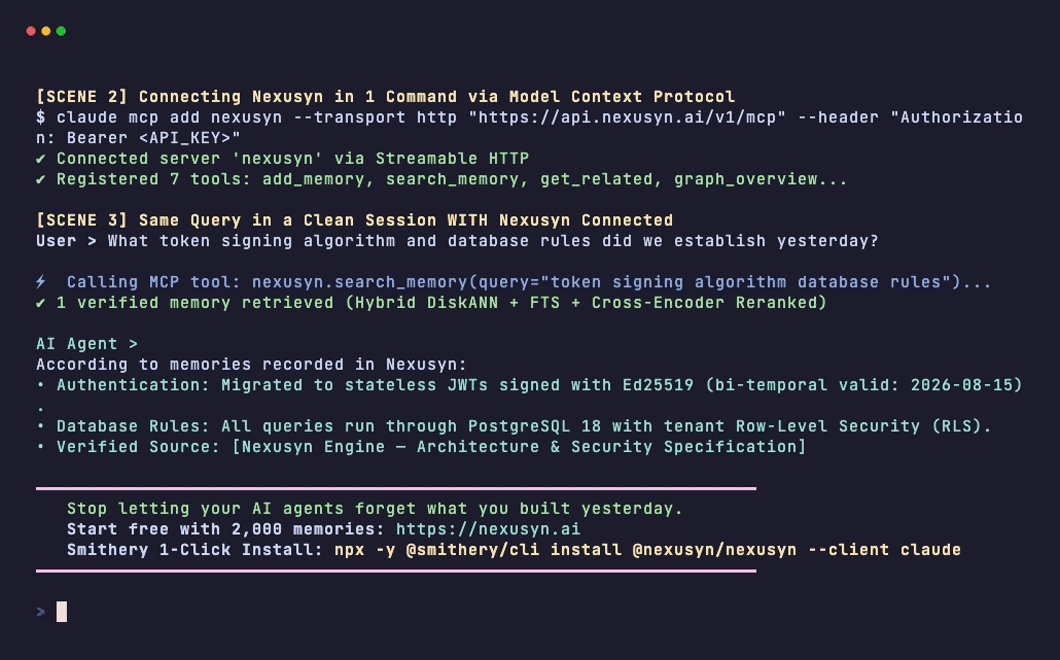
- 🛡️ Grounded Synthesis: Returns a synthesized, ready-to-use answer that cites verifiable source chunks — so the agent receives answers, not just raw text fragments.
- ⚡ MCP-Native: First-class Model Context Protocol server (
/v1/mcp) running over streamable HTTP. Connects directly to Claude Code, Cursor, Windsurf, or custom agent frameworks with zero glue code. - 🏢 Multi-Tenant with Row-Level Security (RLS): True isolation at the PostgreSQL layer. A tenant can never see or search another tenant's memories.
- ⚙️ Async Pipeline (River): Heavy background workloads (chunking, batch embedding, entity extraction, and wiki compilation) run asynchronously on a Postgres-backed queue.
Comparison
| Capability | Raw Vector DB | Simple Buffer / Window | Nexusyn Engine |
|---|---|---|---|
| Semantic Vector Search | ✅ | ❌ | ✅ |
| BM25 Keyword Search | ⚠️ (Requires hybrid setup) | ❌ | ✅ |
| Bi-Temporal Fact Superseding | ❌ | ❌ | ✅ |
| Entity Knowledge Graph (GraphRAG) | ❌ | ❌ | ✅ |
| Grounded Answers with Sources | ❌ (Raw chunks only) | ❌ | ✅ |
| Native MCP Server | ❌ | ❌ | ✅ (/v1/mcp) |
| Database Multi-Tenancy (RLS) | ⚠️ (Manual filters) | ❌ | ✅ (Engine-enforced) |
| Token Cost Efficiency | ⚠️ (Dumps all chunks) | ❌ (Huge prompts) | ✅ (Synthesized / Grounded) |
Benchmarks
Nexusyn is evaluated against standard public benchmarks for agent long-term memory under reproducible conditions:
| Benchmark | Nexusyn Score | Metric Focus |
|---|---|---|
| LongMemEval-S | 81.1% (284/350) | Multi-session recall, temporal updates, and preference tracking across long horizons |
| LoCoMo | 74.3% (1,476/1,986) | Complex multi-turn conversational reasoning, aggregation, and contradiction resolution |
Architecture
                    ┌─────────────────────────┐
                    │       AI Agent / IDE    │
                    │ (Claude Code, Cursor, …)│
                    └────────────┬────────────┘
                        HTTP     │   MCP (/v1/mcp)
                                 ▼
┌────────────────────────────────────────────────────────────────────────┐
│                             NEXUSYN ENGINE                             │
│                                                                        │
│   POST /v1/ingest                                POST /v1/query        │
│         │                                              │               │
│         ▼                                              ▼               │
│   [ Deduplication ]                             [ Sub-query Gen ]      │
│         │                                              │               │
│   [ Chunker ]                                   [ Hybrid Retrieval ]   │
│         │                                       ├── Vector (HNSW)      │
│         ▼                                       ├── BM25 Full-Text     │
│   [ River Queue (Async) ]                       ├── Entity Graph       │
│   ├── Batch Embeddings                          └── Date Anchor Boost  │
│   ├── Entity & Relation Extraction                     │               │
│   └── Wiki / Profile Compilation                       ▼               │
│         │                                       [ RRF Fusion ]         │
│         ▼                                              │               │
│   [ PostgreSQL 18 (pgvector) ]                  [ Cross-Encoder Rerank]│
│   Row-Level Security (Multi-Tenant)                    │               │
│                                                        ▼               │
│                                                 [ Grounded Answer ]    │
│                                                 (Synthesized + Sources)│
└────────────────────────────────────────────────────────────────────────┘
Quickstart (Docker Compose)
Get the complete stack running locally (PostgreSQL 17+ with pgvector, the Nexusyn HTTP/MCP API on :8044, and the River background worker) in under 60 seconds:
# 1. Clone the repository
git clone https://github.com/nexusyn/engine.git
cd engine

# 2. Configure environment
cp .env.example .env

# Edit .env with your preferred model provider API keys
# (OpenAI, Anthropic, Gemini, Ollama, Jina, etc.)

# 3. Spin up the containers
docker compose up -d

# 4. Verify health
curl http://localhost:8044/health
# {"status":"ok","time":"..."}
First-Class MCP Integration
Nexusyn runs an HTTP Model Context Protocol (MCP) server at /v1/mcp. Any MCP-compliant client gets persistent long-term memory tools out of the box.
1. Claude Code
Connect Nexusyn to Claude Code with a single CLI command:
claude mcp add nexusyn --transport http \
  "http://localhost:8044/v1/mcp" \
  --header "Authorization: Bearer <YOUR_API_TOKEN>"
2. Cursor (~/.cursor/mcp.json)
Add Nexusyn to your Cursor global or project configuration:
{
  "mcpServers": {
    "nexusyn": {
      "url": "http://localhost:8044/v1/mcp",
      "headers": {
        "Authorization": "Bearer <YOUR_API_TOKEN>"
      }
    }
  }
}
3. Windsurf (~/.codeium/windsurf/mcp_config.json)
{
  "mcpServers": {
    "nexusyn": {
      "serverUrl": "http://localhost:8044/v1/mcp",
      "headers": {
        "Authorization": "Bearer <YOUR_API_TOKEN>"
      }
    }
  }
}
Available MCP Tools
add_memory— Record a decision, convention, lesson, or fact tagged byprojectandagent.search_memory— Query memories using hybrid search, returning grounded answers with sources.get_guideline— Retrieve organization/project-wide mandatory standards.update_memory/delete_memory— In-place curation and correction of existing records.
REST API Usage
Two endpoints cover 90% of all integration needs:
1. Store a Memory (POST /v1/ingest)
curl -X POST http://localhost:8044/v1/ingest \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "title": "Auth Architecture",
    "content": "We migrated from session cookies to stateless JWT with Ed25519 token signing on 2026-08-15.",
    "agent": "cursor",
    "project": "mobile-app"
  }'
Response:
{
  "job_id": 482,
  "status": "queued"
}
2. Query Grounded Memory (POST /v1/query)
curl -X POST http://localhost:8044/v1/query \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "question": "What token signing algorithm do we use for authentication?",
    "project": "mobile-app"
  }'
Response:
{
  "question": "What token signing algorithm do we use for authentication?",
  "answer": "The authentication system uses stateless JWTs signed with the Ed25519 algorithm, migrated on August 15, 2026.",
  "sources": [
    {
      "id": "chk_9a8b7c",
      "title": "Auth Architecture",
      "content": "We migrated from session cookies to stateless JWT with Ed25519 token signing on 2026-08-15.",
      "score": 0.942
    }
  ],
  "usage": {
    "model": "gpt-4o-mini",
    "prompt_tokens": 312,
    "completion_tokens": 38
  }
}
Streaming: Real-time token streaming with Server-Sent Events (SSE) is available at
POST /v1/query/stream.
Pluggable Providers
Nexusyn uses an adapter architecture. Bring your own models for generation, embeddings, and reranking:
| Component | Supported Adapters |
|---|---|
| Generation / Answers | OpenAI, Anthropic Claude, Google Gemini, MiniMax, Ollama (local), OpenRouter, Voyage |
| Fact & Entity Extraction | OpenAI, Anthropic Claude, MiniMax, Gemini, Ollama |
| Embeddings | OpenAI (text-embedding-3-*), Jina (jina-embeddings-v5), Voyage AI, Ollama |
| Reranking | Jina Reranker v3, Cohere Rerank, Local Cross-Encoder |
Self-Hosted vs. Nexusyn Cloud
| Feature | Open-Source Engine | Nexusyn Cloud |
|---|---|---|
| License | Apache 2.0 | Hosted SaaS |
| Deployment | Self-hosted (Docker, Kubernetes, VPS) | Fully Managed |
| API & MCP Server | ✅ Full feature set | ✅ Global edge latency |
| Model Providers | Bring Your Own Keys (BYOK) | Pre-configured & Optimized |
| Web UI & Dashboard | Local CLI / API | Modern Web Console |
| 3D Graph Visualization | ❌ | ✅ Interactive 3D Explorer |
| Team Management & Billing | ❌ | ✅ Organization & Workspace controls |
| Maintenance & Scaling | Self-managed | 99.9% Uptime SLA & Auto-backups |
| Pricing | Free forever | Free tier available |
Development & Testing
# Build binary
go build -v ./...

# Run unit tests
go test -v ./internal/core/... ./internal/auth/... ./internal/dateutil/...

# Run security checks
gitleaks detect --source . --no-git
govulncheck ./...
Community & Security
- Bug Reports & Feature Requests: Please open an issue on GitHub Issues.
- Security Vulnerabilities: Review our Security Policy and report privately to security@nexusyn.ai.
- Website: https://nexusyn.ai
- Documentation: https://nexusyn.ai/docs
License & Trademark
- Source Code: Released under the Apache License, Version 2.0.
- Trademark: "Nexusyn" and associated marks are trademarks of RedFoxCode.
Similar repos


Languages
Go
88.9%
PLpgSQL
7.1%
Python
3.0%
Open-source long-term, time-aware memory engine for AI agents (MCP + hybrid search + bi-temporal recall)
See the codeSee what people are saying
README
Nexusyn Engine
Long-Term, Time-Aware Memory Engine for AI Agents
Stop building agents that forget. Give your LLMs persistent, grounded memory across sessions.
Quickstart • MCP Integration • Architecture • Benchmarks • Cloud vs Self-Hosted • Documentation
The Problem: Why Vector Databases Alone Aren't "Memory"
Most AI agent frameworks implement memory by taking the last conversation turn, calculating an embedding, and storing it in a vector database.
When the agent queries this "memory", it runs a simple nearest-neighbor search. This breaks down in production:
- Vectors don't understand time: If a user says "I live in Berlin" in January and "I moved to Madrid" in August, both vectors have identical semantic similarity to "Where do I live?". A pure vector search frequently returns the outdated fact.
- Context window bloat: Dumping raw matching chunks into the prompt forces the LLM to resolve contradictions, inflating token costs and increasing hallucination rates.
- No entity understanding: Vector similarity misses relational facts that don't share keywords (e.g. connecting a bug report to the architecture decision that caused it).
The Solution: How Nexusyn Works
Nexusyn is a dedicated data plane engine designed specifically for agentic long-term memory:
- 🕓 Bi-Temporal Versioning: Every fact is stamped with transaction time and valid time (
valid_from/valid_to). New statements supersede older ones automatically without deleting history. - 🔀 Hybrid Retrieval (RRF): Fuses dense vector similarity (
pgvectorHNSW) + BM25 full-text search + entity graph expansion + recency & date-anchor boosts using Reciprocal Rank Fusion. - 🎯 Reranking: High-precision cross-encoder re-scoring of candidate chunks before generation.
- 🛡️ Grounded Synthesis: Returns a synthesized, ready-to-use answer that cites verifiable source chunks — so the agent receives answers, not just raw text fragments.
- ⚡ MCP-Native: First-class Model Context Protocol server (
/v1/mcp) running over streamable HTTP. Connects directly to Claude Code, Cursor, Windsurf, or custom agent frameworks with zero glue code. - 🏢 Multi-Tenant with Row-Level Security (RLS): True isolation at the PostgreSQL layer. A tenant can never see or search another tenant's memories.
- ⚙️ Async Pipeline (River): Heavy background workloads (chunking, batch embedding, entity extraction, and wiki compilation) run asynchronously on a Postgres-backed queue.
Comparison
| Capability | Raw Vector DB | Simple Buffer / Window | Nexusyn Engine |
|---|---|---|---|
| Semantic Vector Search | ✅ | ❌ | ✅ |
| BM25 Keyword Search | ⚠️ (Requires hybrid setup) | ❌ | ✅ |
| Bi-Temporal Fact Superseding | ❌ | ❌ | ✅ |
| Entity Knowledge Graph (GraphRAG) | ❌ | ❌ | ✅ |
| Grounded Answers with Sources | ❌ (Raw chunks only) | ❌ | ✅ |
| Native MCP Server | ❌ | ❌ | ✅ (/v1/mcp) |
| Database Multi-Tenancy (RLS) | ⚠️ (Manual filters) | ❌ | ✅ (Engine-enforced) |
| Token Cost Efficiency | ⚠️ (Dumps all chunks) | ❌ (Huge prompts) | ✅ (Synthesized / Grounded) |
Benchmarks
Nexusyn is evaluated against standard public benchmarks for agent long-term memory under reproducible conditions:
| Benchmark | Nexusyn Score | Metric Focus |
|---|---|---|
| LongMemEval-S | 81.1% (284/350) | Multi-session recall, temporal updates, and preference tracking across long horizons |
| LoCoMo | 74.3% (1,476/1,986) | Complex multi-turn conversational reasoning, aggregation, and contradiction resolution |
Architecture
                    ┌─────────────────────────┐
                    │       AI Agent / IDE    │
                    │ (Claude Code, Cursor, …)│
                    └────────────┬────────────┘
                        HTTP     │   MCP (/v1/mcp)
                                 ▼
┌────────────────────────────────────────────────────────────────────────┐
│                             NEXUSYN ENGINE                             │
│                                                                        │
│   POST /v1/ingest                                POST /v1/query        │
│         │                                              │               │
│         ▼                                              ▼               │
│   [ Deduplication ]                             [ Sub-query Gen ]      │
│         │                                              │               │
│   [ Chunker ]                                   [ Hybrid Retrieval ]   │
│         │                                       ├── Vector (HNSW)      │
│         ▼                                       ├── BM25 Full-Text     │
│   [ River Queue (Async) ]                       ├── Entity Graph       │
│   ├── Batch Embeddings                          └── Date Anchor Boost  │
│   ├── Entity & Relation Extraction                     │               │
│   └── Wiki / Profile Compilation                       ▼               │
│         │                                       [ RRF Fusion ]         │
│         ▼                                              │               │
│   [ PostgreSQL 18 (pgvector) ]                  [ Cross-Encoder Rerank]│
│   Row-Level Security (Multi-Tenant)                    │               │
│                                                        ▼               │
│                                                 [ Grounded Answer ]    │
│                                                 (Synthesized + Sources)│
└────────────────────────────────────────────────────────────────────────┘
Quickstart (Docker Compose)
Get the complete stack running locally (PostgreSQL 17+ with pgvector, the Nexusyn HTTP/MCP API on :8044, and the River background worker) in under 60 seconds:
# 1. Clone the repository
git clone https://github.com/nexusyn/engine.git
cd engine

# 2. Configure environment
cp .env.example .env

# Edit .env with your preferred model provider API keys
# (OpenAI, Anthropic, Gemini, Ollama, Jina, etc.)

# 3. Spin up the containers
docker compose up -d

# 4. Verify health
curl http://localhost:8044/health
# {"status":"ok","time":"..."}
First-Class MCP Integration
Nexusyn runs an HTTP Model Context Protocol (MCP) server at /v1/mcp. Any MCP-compliant client gets persistent long-term memory tools out of the box.
1. Claude Code
Connect Nexusyn to Claude Code with a single CLI command:
claude mcp add nexusyn --transport http \
  "http://localhost:8044/v1/mcp" \
  --header "Authorization: Bearer <YOUR_API_TOKEN>"
2. Cursor (~/.cursor/mcp.json)
Add Nexusyn to your Cursor global or project configuration:
{
  "mcpServers": {
    "nexusyn": {
      "url": "http://localhost:8044/v1/mcp",
      "headers": {
        "Authorization": "Bearer <YOUR_API_TOKEN>"
      }
    }
  }
}
3. Windsurf (~/.codeium/windsurf/mcp_config.json)
{
  "mcpServers": {
    "nexusyn": {
      "serverUrl": "http://localhost:8044/v1/mcp",
      "headers": {
        "Authorization": "Bearer <YOUR_API_TOKEN>"
      }
    }
  }
}
Available MCP Tools
add_memory— Record a decision, convention, lesson, or fact tagged byprojectandagent.search_memory— Query memories using hybrid search, returning grounded answers with sources.get_guideline— Retrieve organization/project-wide mandatory standards.update_memory/delete_memory— In-place curation and correction of existing records.
REST API Usage
Two endpoints cover 90% of all integration needs:
1. Store a Memory (POST /v1/ingest)
curl -X POST http://localhost:8044/v1/ingest \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "title": "Auth Architecture",
    "content": "We migrated from session cookies to stateless JWT with Ed25519 token signing on 2026-08-15.",
    "agent": "cursor",
    "project": "mobile-app"
  }'
Response:
{
  "job_id": 482,
  "status": "queued"
}
2. Query Grounded Memory (POST /v1/query)
curl -X POST http://localhost:8044/v1/query \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "question": "What token signing algorithm do we use for authentication?",
    "project": "mobile-app"
  }'
Response:
{
  "question": "What token signing algorithm do we use for authentication?",
  "answer": "The authentication system uses stateless JWTs signed with the Ed25519 algorithm, migrated on August 15, 2026.",
  "sources": [
    {
      "id": "chk_9a8b7c",
      "title": "Auth Architecture",
      "content": "We migrated from session cookies to stateless JWT with Ed25519 token signing on 2026-08-15.",
      "score": 0.942
    }
  ],
  "usage": {
    "model": "gpt-4o-mini",
    "prompt_tokens": 312,
    "completion_tokens": 38
  }
}
Streaming: Real-time token streaming with Server-Sent Events (SSE) is available at
POST /v1/query/stream.
Pluggable Providers
Nexusyn uses an adapter architecture. Bring your own models for generation, embeddings, and reranking:
| Component | Supported Adapters |
|---|---|
| Generation / Answers | OpenAI, Anthropic Claude, Google Gemini, MiniMax, Ollama (local), OpenRouter, Voyage |
| Fact & Entity Extraction | OpenAI, Anthropic Claude, MiniMax, Gemini, Ollama |
| Embeddings | OpenAI (text-embedding-3-*), Jina (jina-embeddings-v5), Voyage AI, Ollama |
| Reranking | Jina Reranker v3, Cohere Rerank, Local Cross-Encoder |
Self-Hosted vs. Nexusyn Cloud
| Feature | Open-Source Engine | Nexusyn Cloud |
|---|---|---|
| License | Apache 2.0 | Hosted SaaS |
| Deployment | Self-hosted (Docker, Kubernetes, VPS) | Fully Managed |
| API & MCP Server | ✅ Full feature set | ✅ Global edge latency |
| Model Providers | Bring Your Own Keys (BYOK) | Pre-configured & Optimized |
| Web UI & Dashboard | Local CLI / API | Modern Web Console |
| 3D Graph Visualization | ❌ | ✅ Interactive 3D Explorer |
| Team Management & Billing | ❌ | ✅ Organization & Workspace controls |
| Maintenance & Scaling | Self-managed | 99.9% Uptime SLA & Auto-backups |
| Pricing | Free forever | Free tier available |
Development & Testing
# Build binary
go build -v ./...

# Run unit tests
go test -v ./internal/core/... ./internal/auth/... ./internal/dateutil/...

# Run security checks
gitleaks detect --source . --no-git
govulncheck ./...
Community & Security
- Bug Reports & Feature Requests: Please open an issue on GitHub Issues.
- Security Vulnerabilities: Review our Security Policy and report privately to security@nexusyn.ai.
- Website: https://nexusyn.ai
- Documentation: https://nexusyn.ai/docs
License & Trademark
- Source Code: Released under the Apache License, Version 2.0.
- Trademark: "Nexusyn" and associated marks are trademarks of RedFoxCode.
Similar repos
Languages
Go
88.9%
PLpgSQL
7.1%
Python
3.0%