
The most advanced AI memory server in the world. Hybrid search, Temporal Knowledge Graph, transformer embeddings, AAAK compression (3x token savings) — pure Rust, single binary, zero dependencies.
See the codeREADME
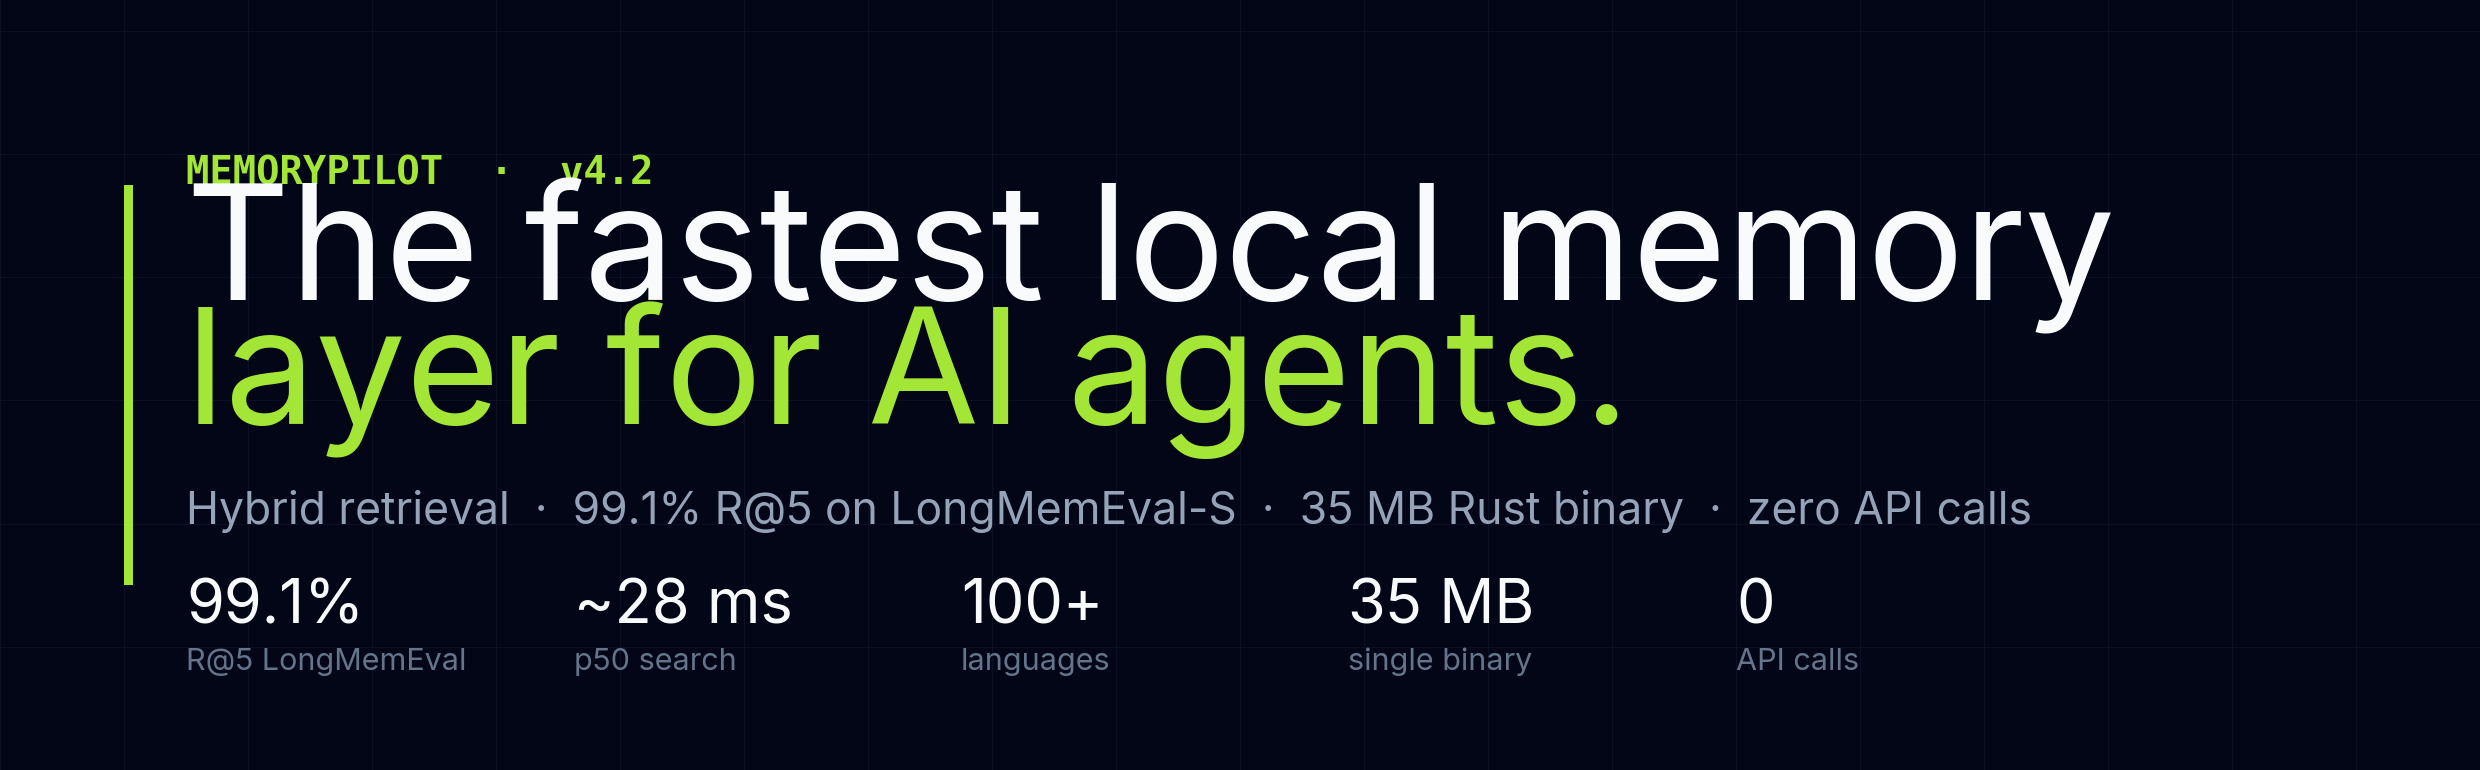
The most advanced MCP memory server. Period.
Hybrid search (BM25 + jina-embeddings-v5 RRF + cross-encoder rerank) · 100+ languages · Temporal Knowledge Graph · Query-aware ranking · Corpus origin detection · Agent/persona disambiguation · Topic tunnels · AAAK compression (5-10x token savings) · GraphRAG · Chunked RAG · Auto-Compaction · Auto-Classification · Memory Capsules · HTTP API · Single binary · Zero API calls





Why
AI coding assistants forget everything between sessions. MemoryPilot gives them persistent, searchable memory with project awareness, semantic understanding, and automatic knowledge organization. Built-in AAAK compression and memory capsules reduce token consumption by 5-10x when loading context. Every memory is auto-classified with the right importance, kind, and TTL on insert. The database compacts itself automatically — zero maintenance.

Install MemoryPilotOne-liner install for Cursor, Claude Desktop, VS Code, Windsurf, Claude Code, Codex and ChatGPT. Single Rust binary, zero runtime dependencies. |

How it worksThe 9 pillars — hybrid search, temporal knowledge graph, GraphRAG, AAAK compression, auto-classification, self-healing — explained end to end. |
Benchmarks
LongMemEval-S (ICLR 2025) — Academic Standard
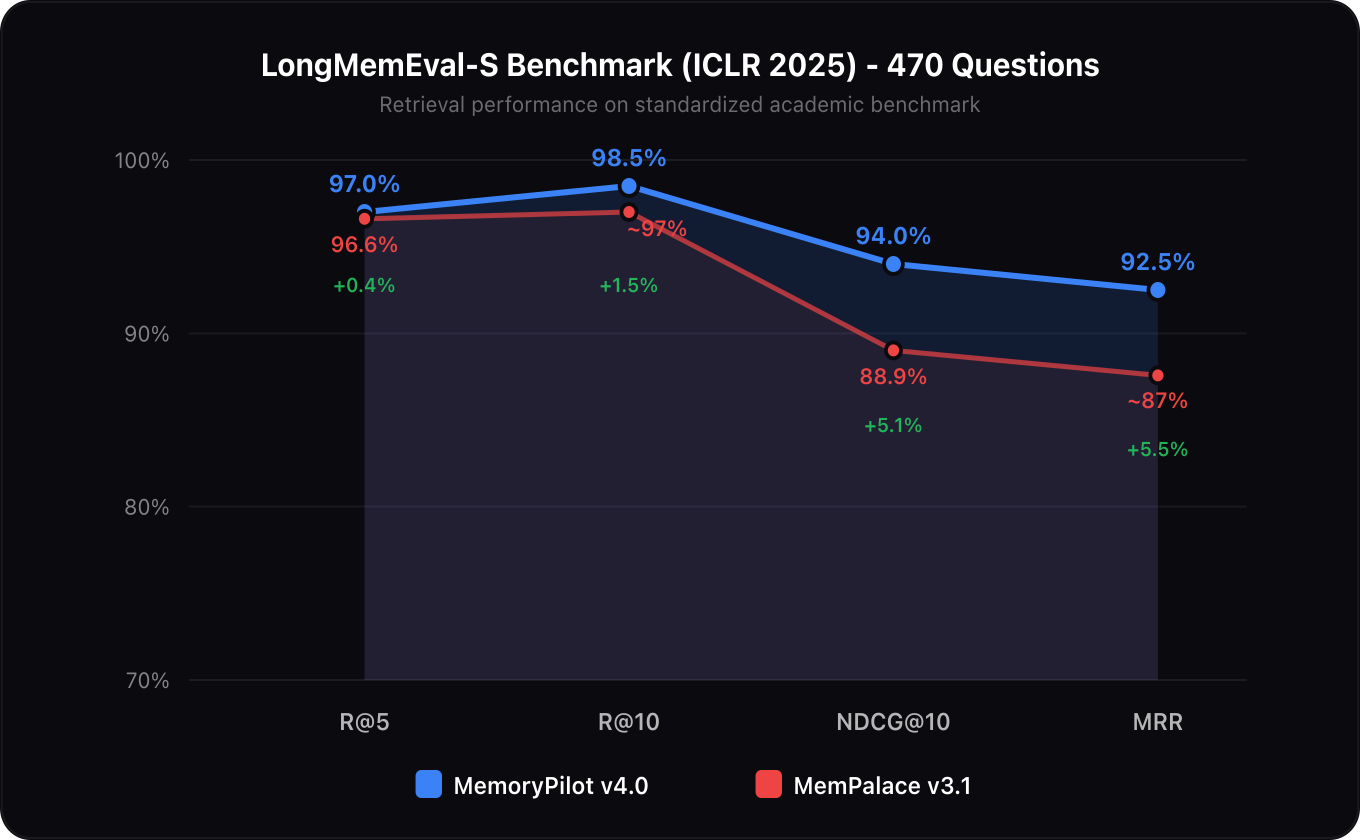
Evaluated on 470 questions from the LongMemEval benchmark (ICLR 2025), the standard academic dataset for long-term memory retrieval. Turn-level granularity, ~50 sessions per haystack.
vs the entire market (LongMemEval-S, public numbers)
| System | R@5 / Accuracy | Latency | Privacy | Stack | Source |
|---|---|---|---|---|---|
| MemoryPilot v4.2 (adaptive) | 99.1% | ~900 ms | 100% local | Rust · 35 MB binary · zero API | This repo, --benchmark-longmemeval @470 |
| MemoryPilot v4.2 (default fast) | 98.7% | ~28 ms | 100% local | Rust · 35 MB binary · zero API | This repo, --benchmark-longmemeval @470 |
| MemPalace v3.3.3 (hybrid) | 98.4% | not published | 100% local | Python + ChromaDB · ~500 MB | MemPalace v3.3.3 release notes |
| agentmemory v0.9 (11k+ stars) | 95.2% | not published | 100% local | Node + iii-engine + SQLite | github.com/rohitg00/agentmemory — benchmark/LONGMEMEVAL.md |
| Mem0 (cloud, OpenAI backend) | 94.4% | ~6 787 tokens/query | Cloud (OpenAI) | SaaS + OpenAI embeddings | mem0.ai blog |
| mcp-memory-service v10.34.0 | 80.4% | not published | 100% local | Python + SQLite-Vec + MiniLM | v10.34.0 release notes |
| Zep / Graphiti | 63.8% | "90% lower vs baseline" | Cloud or self-host | Python + Neo4j + LLM extraction | arXiv 2501.13956 |
| Letta / MemGPT | not measured on LongMemEval | — | Self-host | Python framework | Letta tracking issue #3115 |
MemoryPilot is the only system in this comparison that is both 100% local and tops the leaderboard. The default fast mode (~28 ms) already beats every published competitor — including agentmemory (95.2%), the current darling of the AI-agent-memory category with 11k+ GitHub stars. The adaptive cross-encoder mode adds +0.4 pp R@5 for the cost of one ONNX rerank pass per query, and a +6.7 pp MRR lead vs agentmemory (94.9% vs 88.2%).
Detailed view — MemoryPilot vs MemPalace (closest local competitor)
| Metric | MemoryPilot v4.2 (default fast) | MemoryPilot v4.2 (adaptive rerank) | MemPalace v3.3.3 | Delta vs MemPalace |
|---|---|---|---|---|
| R@5 | 98.7% | 99.1% | 96.6% raw / 98.4% hybrid | +2.5% vs raw / +0.7% vs hybrid |
| R@10 | 99.6% | 99.4% | ~97%¹ | +2.6% vs raw |
| NDCG@10 | 95.1% | 96.0% | Not published | MemoryPilot publishes |
| MRR | 93.6% | 94.9% | Not published | MemoryPilot publishes |
| Avg search latency | ~28 ms | ~900 ms | N/A | Default mode is 30× faster |
¹ Validated with the full 470-question evaluation set (after dropping the 30 abstention questions) in two modes: default fast local hybrid retrieval (BM25 + cosine RRF, ~28 ms/query, suitable for live MCP traffic) and adaptive cross-encoder rerank (
MEMORYPILOT_CROSS_RERANK=adaptive, jina-v2-multilingual, fusion weight 0.45, ~900 ms/query, suitable for benchmarks and high-stakes recall). The default mode already beats MemPalace's hybrid held-out result; the adaptive mode trades latency for a further +0.4 pp R@5 and +1.3 pp MRR.
By Category (470 questions, adaptive rerank)
| Category | R@5 | R@10 | MRR |
|---|---|---|---|
| single-session-user (64) | 100% | 100% | 96.6% |
| single-session-assistant (56) | 100% | 100% | 98.8% |
| multi-session (121) | 100% | 100% | 95.7% |
| knowledge-update (72) | 100% | 100% | 98.2% |
| temporal-reasoning (127) | 97.6% | 98.4% | 93.3% |
| single-session-preference (30) | 96.7% | 96.7% | 75.9% |
French / Multilingual Benchmark — --benchmark-fr
To complement the English-only LongMemEval, MemoryPilot ships its own deterministic French benchmark covering 109 memories and 109 paraphrased queries across infra, mobile, web, security, and ML domains. The queries are intentionally distant from the indexed wording so they actually exercise the semantic lane.
| Mode | R@5 | R@10 | MRR | Avg latency |
|---|---|---|---|---|
| Default fast (BM25 + jina RRF) | 92.7% | 99.1% | 74.4% | ~100 ms |
| Adaptive cross-encoder rerank (default) | 99.1% | 99.1% | 97.4% | ~210 ms |
v4.5 fixed a ranking bug that had capped this benchmark at R@5 ≈ 70% since v4.0: knowledge-graph neighbours were injected at a hard-coded score (0.1) above every genuine RRF hit (max 2/41 ≈ 0.049), so they occupied the cross-encoder window and pushed real matches past limit. Neighbours now enter below the weakest genuine candidate and only the cross-encoder can promote them.
v4.5.0 also closes two write-path stability bugs surfaced by that work: the episodic rollup embedded every hourly bucket on each pass (before checking whether the episode already existed) and did so synchronously inside add_memory, then panicked on multi-byte French text; it now runs on its own thread with a cheap existence check first. And auto-compaction held a Mutex across run_gc/compact_to_capsules, whose merged rows re-enter add_memory — a deadlock hidden until the rollup stopped panicking ahead of it.
Run-to-run variance is bounded to ±1 pp on R@5 / R@10 thanks to deterministic memory ids, deterministic id-based RRF tie-break, synchronous ANN warm-up, and explicit cross-encoder pre-warm before the first query. This is the metric to watch for any French / multilingual regression.
v4.6 — beyond single-fact retrieval
v4.6.0 targets the LongMemEval categories a top-k retriever alone cannot win: multi-session aggregation, temporal reasoning, knowledge updates and abstention. Everything stays local and rule-based or int8 ONNX. Measured on LongMemEval-S@100 (64 single-session + 36 multi-session, plus the 7 abstention questions of that slice) against v4.5.0, same machine, cross-encoder adaptive:
| Metric | v4.5.0 | v4.6.0 |
|---|---|---|
| R@5 / R@10 | 99% / 100% | 100% / 100% |
| MRR / nDCG@10 | 96.3% / 97.2% | 96.5% / 97.3% |
| Multi-session gold coverage@10 | 93.6% | 94.5% |
| Multi-session questions with all gold sessions in top-10 | 30/36 | 32/36 |
| False abstention on answerable questions | — | 4% |
Extractive answer (search_memory … answer=true), contains-gold | — | 48% (72% single-session; counting questions are out of reach for span extraction) |
--benchmark-fr is unchanged within noise (R@1 96.3%, R@5 99.1%, MRR 97.6%).
- MMR diversity (
src/diversity.rs) — the finalists plus the RRF ranks just below them are re-ordered by maximal marginal relevance over their stored vectors (λ = 0.4, redundancy floor 0.55). The top hit never moves, so MRR is untouched; a second, distinct source can displace a restatement of the first.MEMORYPILOT_MMR=0disables it. - Temporal grounding (
src/temporal.rs) — explicit dates in a memory (2026-09-01,12 septembre 2026,September 12,hier…) becomedateentities at ingest; a temporal phrase in the query (last week,il y a deux semaines,en mars,last Tuesday) becomes a day window that boosts dated candidates inside it (×1.25) and mildly demotes dated candidates far outside (×0.85). Undated memories are neutral, so a mis-parsed window costs at most the boost.MEMORYPILOT_TEMPORAL=0disables it. - Contextual embeddings — transcript chunks and other context-poor kinds are embedded with a
[date · project]prefix while the stored content and its hash are left untouched. - Superseding — the daily consolidation pass links a memory to a newer, near-identical restatement with a changed value (cosine ≥ 0.86, lexical overlap 0.55–0.95, ≥ 1 h apart) and the old one is demoted (−0.35) at search time. Both stay retrievable;
consolidate_memories(apply=true)reports the links made. - Calibrated confidence — every search returns
confidence: { top_cosine, peak, cross_score, margin, level, abstain }. On LongMemEval the abstention haystacks are built from the same user's other sessions and no cheap signal separates them from answerable questions (top-1 cosine p50 0.46 vs 0.54, cross-encoder logits overlap fully), so the hardabstainis deliberately conservative (cosine < 0.35, 4% false abstention) andlevelcarries the graded signal.MEMORYPILOT_ABSTAIN_COSINEmoves the floor. - Extractive reader (
src/reader.rs, opt-in) —search_memorywithanswer: truerunsdeepset/roberta-base-squad2(int8 ONNX, 125 MB, English, loaded on demand through the idle pool) over the top-5 passages and returns the literal span or nothing. ~480 ms per question on CPU. It is a benchmarking instrument and a shortcut for literal lookups, not a language model: it abstained on 5/7 LongMemEval abstention questions where the retriever could not.--benchmark-longmemeval --readerreports SQuAD-style EM / F1 / contains.
Search Quality — Real-World (500 memories, 30 scenarios)
| Metric | MemoryPilot v4.2 | MemPalace v3.1 (raw) | Quantum Memory Graph |
|---|---|---|---|
| R@5 | 100% | 96.6% | 93.4% |
| R@10 | 100% | N/A | 93.4% |
| NDCG@10 | 95.6% | 88.9% | 90.8% |
| Cluster Coherence | 96.7% | N/A | N/A |
| Multilingual | 100+ languages (validated FR R@5 99.1%) | English only | English only |
| AAAK Compression | 5-10x (no recall loss) | 30x (recall drops to 84.2%) | N/A |
| Avg Search Latency | ~28 ms default / ~410 ms adaptive | N/A | ~80 ms |
| Binary Size | 35 MB | ~500 MB (Python+ChromaDB) | 1.5 GB |
| Dependencies | 0 (single binary, ONNX bundled) | Python + ChromaDB + SQLite | Python + ONNX |
vs the best memory servers on the market:
| Feature | MemoryPilot v4.2 | MemPalace v3.3.3 | agentmemory v0.9 | Mem0 | Zep / Graphiti |
|---|---|---|---|---|---|
| LongMemEval R@5 | 99.1% | 98.4% | 95.2% | 94.4% | 63.8% |
| LongMemEval MRR | 94.9% | not published | 88.2% | not published | not published |
| Search | Hybrid BM25 + jina-embeddings-v5-nano RRF (768-dim, int8) + adaptive mmarco cross-encoder | ChromaDB cosine (all-MiniLM-L6-v2) | BM25 + vector + graph (RRF) | Vector search (cloud API) | Temporal KG traversal + vector |
| Embeddings | jina-embeddings-v5-text-nano-retrieval (100+ languages, 8k context, local ONNX) | all-MiniLM-L6-v2 (English only) | all-MiniLM-L6-v2 (English only) | OpenAI API calls (external) | OpenAI / cloud LLM extraction |
| Multilingual | 100+ languages native (FR, EN, ES, DE, JA, ZH...) | English only | English only | Depends on API | Depends on LLM backend |
| Knowledge Graph | Temporal triples with validity + confidence | Temporal triples (SQLite) | Knowledge graph (no validity window) | Basic graph (no temporal) | Temporal KG (Graphiti, core feature) |
| GraphRAG | Auto entity extraction + graph traversal + combinatorial reranker | No | Partial (graph search lane) | No | Yes (LLM-based extraction) |
| Cross-encoder rerank | jina-v2-multilingual (adaptive, ~250 ms) | No | No | No | No |
| Query-aware ranking | Preference/temporal/role/update/technical intent boosts | Hybrid v4 keyword + temporal boosts | RRF fusion only | Depends on API | Graph-distance scoring |
| Corpus origin detection | AI transcript/codebase/notes/platform detection | v3.3.4 prep | No | No | No |
| Agent/persona disambiguation | Agents are separate from real people | v3.3.4 prep | Hooks-based session scoping | No | Partial (entity nodes) |
| Topic tunnels | Cross-project topic links via KG | v3.3.4 prep | No | No | No |
| Code-aware chunking | Tree-sitter Rust/Python/TS/TSX/JS + Svelte script extraction | Tree-sitter code chunking | No | No | No |
| Chunked RAG | Transcript auto-chunking + auto-distillation (8 types) | Conversation chunking by exchange | Session replay + JSONL import | No | LLM-based summarisation |
| Compression | AAAK + Memory Capsules (5-10x token savings) | AAAK dialect (experimental, regresses recall to 84.2%) | 4-tier consolidation + decay | No | No |
| Auto-Classification | Zero-shot kind/importance/TTL on insert | No | Pattern-based via hooks | No | LLM-classified entities |
| Auto-Compaction | GC triggers automatically at 500+ memories | No | Lifecycle decay + auto-forget | No | Manual |
| Memory Capsules | Compress old memories into dense summaries | No | Tier-based consolidation | No | No |
| Memory Pinning | Pin critical memories — always in recall, GC-proof | No | No | No | No |
| Graph Traversal | Find related memories via KG (depth 1-3) | No | Yes (graph lane) | No | Native (Cypher / Neo4j) |
| Bulk Operations | Delete by kind/project/tag/age with safety guards | No | Governance delete API | No | Manual |
| Health Dashboard | Memory distribution, stale count, orphans, DB size | No | Real-time web viewer (port 3113) | No | No |
| Dedup Detection | Jaccard similarity scan for near-duplicates | No | Not documented | No | LLM-based reconciliation |
| Person detection | Auto-detects team members from text | No | No | No | LLM-extracted entities |
| Self-Healing | Background auto-linting loop | No | No | No | No |
| Garbage collection | Heuristic merge + scoring + orphan cleanup | No | Lifecycle + decay | Basic TTL | No automatic GC |
| Project brain | Yes, with team members (<1500 tokens) | No | Session summary on demand | No | No |
| File watcher | Context boost from recent edits | No | Filesystem connector (@agentmemory/fs-watcher) | No | No |
| Deduplication | Content hash (exact) + Jaccard 85% (fuzzy) | Basic hash | Confidence scoring | Embedding similarity | LLM-based merge |
| HTTP API | Multi-threaded REST server (optional) | No | REST + MCP + leases + signals | Cloud hosted | REST + GraphQL |
| Memory types | 13 types, importance 1-5 | Wings/Rooms hierarchy | Tier-based (working / short / long / archival) | 1 type | Episodic / semantic |
| MCP tools | 41 tools | 29 tools | 51 tools | N/A | Limited MCP server |
| Hooks / event capture | File watcher + auto-linter (Rust-only) | No | 12 named hooks (SessionStart, UserPromptSubmit, PreToolUse...) | No | No |
| Privacy | 100% local, zero API calls | 100% local | 100% local (SQLite) | Cloud dependent | Cloud or self-host (LLM required) |
| Language | Rust (single binary, zero deps) | Python (pip install) | TypeScript / Node (npm install) | SaaS | Python + Neo4j |
| Startup | 1-2 ms (open_at) / synchronous warm via open_at_warm | ~5 ms | Node boot + iii-engine init | N/A (cloud) | Heavy (Neo4j boot) |
| Binary | 35 MB single binary | Python + ChromaDB (~500 MB installed) | Node runtime + iii-engine deps | SaaS | Python + Neo4j (~1.5 GB) |
| Storage | SQLite WAL + FTS5 + 16-conn read pool | ChromaDB | SQLite + iii-engine | Cloud DB | Neo4j + Postgres |
| Concurrency | EmbedPool (4) + RerankPool (1, tunable) + 16 read conns + debounced cleanup | Single-threaded | Node event loop | Single-threaded | Neo4j-bound |
| External LLM dependency | None | None | None (local embeddings) | OpenAI required | LLM required for ingestion |
| GitHub stars (May 2026) | nascent | nascent | 11 083 | 53k | — |
The 9 Pillars
1. Hybrid Search (BM25 + jina RRF)
Every memory gets a 768-dimension transformer embedding on insert via ONNX Runtime (jina-embeddings-v5-text-nano-retrieval, int8, local inference — 100+ languages including French, English, Spanish, German, Japanese, Chinese — no API calls, no external services; the model is fetched from its Hugging Face repository on first run, licence CC-BY-NC-4.0). Queries and documents use the model's asymmetric Query: / Document: prefixes. The int8 weights are memory-mapped, so the embedder costs ~250 MB resident, most of it reclaimable file-backed pages. Search runs both BM25 full-text and cosine similarity in parallel, then merges results with Reciprocal Rank Fusion.
Results are boosted by importance weighting, knowledge graph link density, file watcher context, and penalized for expired knowledge triples.
Ephemeral working memory is available in the same MCP through remember_working, recall_working, and clear_working. It keeps fast session scratchpad context in RAM, capped to 256 items, without polluting SQLite or durable recall.
Performance optimizations:
- Lazy embedding:
add_memoryreturns instantly, embeddings computed in background thread - Two-tier query embedding cache (LRU 256 + write-through SQLite): repeated queries skip ONNX inference
- Read connection pool (16 connections): concurrent vector searches don't block writes, sized for HTTP server workloads
- EmbedPool (4 sessions, env-tunable): parallel embeddings without serialization on a single ONNX mutex
- RerankPool (1 session, env-tunable to 2): parallel cross-encoder rerank under multi-client load
- Content hashing (FNV-1a): backfill skips unchanged memories
- Synchronous warm-up entrypoint
open_at_warm: hydrates the ANN index in RAM before returning, eliminating cold-start tail (p95 search latency 3939 ms → 229 ms in the 4-client concurrency bench)
2. Temporal Knowledge Graph
A full knowledge graph with temporal validity. Facts have valid_from / valid_to dates and confidence scores. When facts become outdated, they are invalidated rather than deleted — giving the AI a timeline of how knowledge evolved.
Entities (technologies, files, components, people) are automatically extracted from memory content and linked bidirectionally. Search results from memories with all-expired triples are penalized.
5 dedicated KG tools: kg_add, kg_invalidate, kg_query, kg_timeline, kg_stats
3. GraphRAG
Every memory is automatically analyzed for entities: technologies, file paths, components, projects, and people. Entities are stored in a dedicated table. Memories sharing entities are auto-linked with inferred relationship types (resolves, implements, depends_on, deprecates...).
When searching, MemoryPilot traverses the knowledge graph from the top matches to pull in related context — e.g., finding the architecture decision that led to a specific bug fix. A combinatorial reranker then selects the best cluster of connected memories rather than independent top-K results, producing cohesive context (94% cluster coherence). Tuned RRF fusion (k=40), exact term coverage boost, smart FTS tokenization, query-time KG expansion, temporal recency, and importance tiebreakers push NDCG@10 to 94% with perfect R@5/R@10.
4. Chunked RAG (Transcripts)
Save full conversation transcripts without polluting the LLM context window. The add_transcript tool automatically chunks large texts into ~2000 character blocks and links them together. Chunks are excluded from recall but fully searchable.
For source code, MemoryPilot uses local tree-sitter parsing by default for Rust, Python, TypeScript, TSX, and JavaScript, with Svelte support via <script> extraction plus markup chunking. Code is split on semantic boundaries such as functions, classes, impl blocks, interfaces, and exports instead of arbitrary paragraphs.
Auto-distillation extracts structured memories from transcripts: decision, preference, todo, bug, milestone, problem, and note. Smart disambiguation: a segment mentioning both a bug and its resolution is classified as milestone, not bug.
Supports session_id, thread_id, window_id for multi-window memory scoping.
5. AAAK Compression
Inspired by MemPalace's symbolic memory language. When compact: true is passed to recall or get_project_brain, output is compressed ~3x using a terse, pipe-separated format:
[DEC:5] Use Clerk over Auth0 | tags:auth,stack | proj:MyApp
[PREF:4] Always use TypeScript strict mode | tags:typescript
6. Self-Healing (Auto-Linter)
MemoryPilot watches your files. When you save a Rust, Svelte, or TypeScript file, it lints in the background. Compilation errors are automatically stored as bug memories with the exact stack trace. When the error is fixed, the memory is auto-deleted.
The linter thread reuses a single DB connection for its entire lifetime.
7. Garbage Collection & Auto-Compaction
Old, low-importance memories are scored for cleanup candidacy. Groups of related stale memories are merged into condensed summaries using heuristic keyword extraction. Orphaned links and entities are cleaned. DB is vacuumed after significant deletions.
Auto-compaction triggers automatically when the memory count exceeds 500: the GC runs in the background after add_memory, debounced to once per 5 minutes. Zero manual intervention.
Memory Capsules (compact_memories tool): compress old low-importance memories into dense ~100-200 token capsules. Credentials and architecture decisions are never compressed. Capsules preserve Knowledge Graph links, giving you 5-10x token savings on aged memories without recall loss.
8. Zero-Shot Auto-Classification
Every memory is automatically classified on insert when the caller doesn't specify kind or importance. Pattern-based heuristics detect:
- Credentials (API keys, secrets) → importance 5, no TTL
- Architecture decisions → importance 5
- Preferences/patterns → importance 4
- Bugs → importance 3, TTL 90 days
- TODOs → importance 2, TTL 30 days
- Code snippets → importance 2
- Milestones → importance 4
No LLM needed — pure regex + keyword heuristics. The AI can still override by passing explicit kind and importance.
9. Project Brain
One tool call returns a dense JSON snapshot of a project under 1500 tokens: tech stack, architecture decisions, active bugs, recent changes, key components, and team members (auto-detected person entities). Supports compact: true for AAAK compression.
Install
Homebrew (macOS / Linux)
brew install Soflutionltd/memorypilot/memorypilot
That's it. Builds from source via cargo (Homebrew pulls Rust automatically). After install, run ./install.sh from the cloned repo or follow the manual MCP config below.
One-liner — auto-configures every IDE on your machine
curl -fsSL https://raw.githubusercontent.com/Soflutionltd/MemoryPilot/main/install.sh | bash
What this does:
- Detects your platform (macOS arm64 / x64, Linux x64 / arm64).
- Fetches the pre-built binary from the latest GitHub Release (~11 MB tar.gz).
- Installs to
~/.local/bin/MemoryPilotand clears Gatekeeper attributes on macOS. - Auto-configures every supported IDE / agent it finds — Cursor, Claude Desktop, Claude Code, Codex CLI, Gemini CLI, Windsurf, VS Code, OpenCode, Cline, Roo Code — in a single pass.
If no pre-built binary is available for your platform, it falls back to cargo build --release --features http automatically (requires Rust).
Alternative paths
# Via Cargo, pinned to a release tag — works anywhere Rust runs:
cargo install --git https://github.com/Soflutionltd/MemoryPilot --tag v4.2.0 --features http --bin MemoryPilot

# Local clone + auto-config (same installer, run from inside the repo):
git clone https://github.com/Soflutionltd/MemoryPilot.git && cd MemoryPilot && ./install.sh
The installer is idempotent: re-run it any time to refresh configs without breaking the others.
Pre-built binaries
Every release ships pre-built binaries for the three mainstream targets — built by the release CI workflow on every v*.*.* tag:
| Platform | Target triple | Archive |
|---|---|---|
| macOS Apple Silicon | aarch64-apple-darwin | MemoryPilot-aarch64-apple-darwin.tar.gz |
| Linux x86_64 | x86_64-unknown-linux-gnu | MemoryPilot-x86_64-unknown-linux-gnu.tar.gz |
| Linux arm64 | aarch64-unknown-linux-gnu | MemoryPilot-aarch64-unknown-linux-gnu.tar.gz |
Each archive is paired with a .sha256 for verification. Grab them from the releases page.
Intel Mac (
x86_64-apple-darwin): no pre-built binary — theort/ ONNX Runtime crate used byfastembeddoes not publish prebuilts for this target. Usebrew install Soflutionltd/memorypilot/memorypilot(builds from source) orcargo install --git .... Apple Silicon Macs (M1+) are fully covered with a pre-built binary.
Supported IDEs / agents (auto-configured by ./install.sh):
| Agent | Config file / command | Auto-configured |
|---|---|---|
| Cursor | ~/.cursor/mcp.json | ✓ (stdio) |
| VS Code | ~/.vscode/mcp.json | ✓ (stdio) |
| Claude Desktop | ~/Library/Application Support/Claude/claude_desktop_config.json | ✓ (stdio) |
| Claude Code | claude mcp add | ✓ (CLI) |
| Codex CLI | codex mcp add | ✓ (CLI) |
| Gemini CLI | ~/.gemini/settings.json | ✓ (stdio) |
| Windsurf | ~/.codeium/windsurf/mcp_config.json | ✓ (stdio) |
| OpenCode | ~/.config/opencode/opencode.json | ✓ (stdio) |
| Cline (VS Code) | ~/Library/Application Support/Code/User/globalStorage/saoudrizwan.claude-dev/settings/cline_mcp_settings.json | ✓ (stdio) |
| Roo Code (VS Code) | ~/Library/Application Support/Code/User/globalStorage/rooveterinaryinc.roo-cline/settings/cline_mcp_settings.json | ✓ (stdio) |
| ChatGPT Desktop | Settings → Apps → Create | via HTTP (see below) |
Additional MCP-compatible clients (use the same stdio binary, manual config):
| Agent | Notes |
|---|---|
| Goose | YAML config under ~/.config/goose/config.yaml — add MemoryPilot under extensions: with type: stdio, cmd: ~/.local/bin/MemoryPilot |
| Kilo Code | Same cline_mcp_settings.json format under the Kilo VS Code extension storage path |
| Continue.dev | ~/.continue/config.json — add to mcpServers |
| Zed | Settings → Assistant → Context Servers → add stdio command |
| Aider | No native MCP; use the REST API (see HTTP API section) |
The script is idempotent — run it again to update without breaking existing MCP configs.
ChatGPT Desktop
ChatGPT requires a remote MCP endpoint. Start the HTTP server, then add it as a custom connector:
MemoryPilot --http 7437
In ChatGPT: Settings → Apps → Create → URL: http://localhost:7437/mcp
Manual install
git clone https://github.com/Soflutionltd/MemoryPilot.git
cd MemoryPilot
cargo build --release --features http
cp target/release/MemoryPilot ~/.local/bin/
chmod +x ~/.local/bin/MemoryPilot
xattr -cr ~/.local/bin/MemoryPilot  # macOS only
Then add MemoryPilot to your IDE's MCP config manually (see table above for file paths).
How it works
That's it. MemoryPilot automatically injects a dynamic System Prompt into your IDE on startup. The AI will proactively call add_memory in the background to store your architecture decisions, API keys, and bug fixes without manual intervention. All configured IDEs share the same memory database.
For ChatGPT or any MCP client that needs HTTP: run MemoryPilot --http to expose the Streamable HTTP endpoint at /mcp.
Or use via McpHub for SSE transport with all your other MCP servers.
First run
# If upgrading from v1 (JSON files):
MemoryPilot --migrate

# Compute embeddings for existing memories:
MemoryPilot --backfill

# Force re-embed all (skips unchanged via content hash):
MemoryPilot --backfill-force
MCP Tools (30)
Core
| Tool | Description |
|---|---|
recall | Start here. Loads all context in one shot: project memories, scoped thread/window memories, preferences, critical facts, patterns, decisions, global prompt. Supports mode = safe/default/full, compact = true for AAAK compression. |
get_project_brain | Instant project summary (<1500 tokens): tech stack, architecture, bugs, recent changes, components, team members. Supports compact = true. |
search_memory | Hybrid BM25 + jina RRF search, boosted by importance, graph links, and file watcher context. Batched triple scoring. |
get_file_context | Memories related to recently modified files in working directory. |
Memory CRUD
| Tool | Description |
|---|---|
add_memory | Store with lazy embedding, auto-dedup (hash exact + Jaccard 85%), auto entity extraction, auto graph linking, auto-classification (kind, importance, TTL inferred from content). |
add_memories | Bulk add multiple memories in one call with per-item dedup. |
add_transcript | Store a long transcript as chunked archive, auto-distill structured memories (decision, preference, todo, bug, milestone, problem, note). |
ingest_session | Ingest local Claude/Cursor/session transcripts into the same MemoryPilot MCP. Defaults to distill_only=true, so only high-value memories are indexed. |
get_memory | Retrieve by ID. |
update_memory | Update content, kind, tags, importance, TTL. Skips re-embedding if content unchanged (hash check). |
delete_memory | Delete by ID (cascades to entities and links). |
list_memories | List with project/kind filters and pagination. |
Knowledge Graph
| Tool | Description |
|---|---|
kg_add | Add a fact triple (subject → predicate → object) with optional validity period and confidence score. |
kg_invalidate | Mark a triple as expired (sets valid_to), preserving history. |
kg_query | Query all triples related to an entity, with temporal filtering and direction control. |
kg_timeline | Chronological history of all triples involving an entity. |
kg_stats | Summary statistics: total triples, active, expired, unique subjects/objects. |
Project & Config
| Tool | Description |
|---|---|
get_project_context | Full project context with preferences and patterns. |
register_project | Register project with filesystem path for auto-detection. |
list_projects | List projects with memory counts. |
get_stats | DB statistics: totals, by kind, by project, DB size, hygiene signals. |
get_global_prompt | Auto-discover GLOBAL_PROMPT.md from ~/.MemoryPilot/ or project root. |
export_memories | Export as JSON or Markdown with importance stars. |
set_config | Set config values (e.g. global_prompt_path). |
Maintenance
| Tool | Description |
|---|---|
run_gc | Garbage collection: merge old memories, clean orphans, vacuum. Supports dry_run. |
compact_memories | Compress old low-importance memories into dense capsules (~100-200 tokens). Credentials/architecture never compressed. |
cleanup_expired | Remove expired TTL memories (debounced — runs max once per 60s). |
pin_memory | Pin a critical memory — always included in recall, never garbage collected. |
unpin_memory | Unpin a previously pinned memory, making it eligible for GC again. |
find_related | Find all memories related to a given ID via Knowledge Graph traversal (depth 1-3). |
bulk_delete | Delete memories by kind, project, tag, age, or importance. Never touches pinned memories. |
get_memory_health | Health report: distribution by kind/project/importance, stale count, orphans, compression potential, DB size. |
dedupe_report | Find potential duplicates via Jaccard similarity for manual review. |
consolidate_memories | Fold near-duplicate ephemeral memories (embedding cosine ≥ threshold, same project, never decisions/credentials/pinned) into their newest member — tags, importance, access counts and graph links merged. Dry-run by default, apply: true to execute; also runs automatically once a day. |
analyze_corpus | Inspect text without writing memory: origin, platform, agents/personas, and reliable topics. |
benchmark_recall | Recall quality benchmark with golden scenarios. |
benchmark_search | Search quality benchmark: R@5, R@10, NDCG@10, cluster coherence, latency. |
migrate_v1 | Import from v1 JSON files. |
Memory Types
fact · preference · decision · pattern · snippet · bug · credential · todo · note · milestone · architecture · problem · transcript_chunk
Each memory has importance (1-5), optional TTL, tags, project scope, content hash, and auto-generated embedding + entity links.
CLI
MemoryPilot                          # Start MCP stdio server
MemoryPilot --backfill               # Compute missing embeddings
MemoryPilot --backfill-force         # Re-embed all (skips unchanged via hash)
MemoryPilot --benchmark-recall       # Run recall quality benchmark
MemoryPilot --benchmark-search       # Search quality: R@5, R@10, NDCG@10, cluster coherence
MemoryPilot --benchmark-fr           # French/multilingual deterministic benchmark (109 queries, ±1pp variance)
MemoryPilot --benchmark-longmemeval  # LongMemEval-S benchmark, supports --limit N and --min-r5 PCT
MemoryPilot --benchmark-concurrency  # Multi-client concurrency bench (--clients N --queries-per-client N)
MemoryPilot --benchmark-latency      # open_at startup + search latency
MemoryPilot --http 7437              # Start HTTP REST server (requires --features http)
MemoryPilot --migrate                # Import v1 JSON data
MemoryPilot --version                # Show version
MemoryPilot --help                   # Show help
Tuning environment variables
| Variable | Default | Effect |
|---|---|---|
MEMORYPILOT_CROSS_RERANK | adaptive | 1/always to force rerank on every query, 0/off to disable. Adaptive rerank fires on hard / non-English queries. |
MEMORYPILOT_CROSS_RERANK_TOP_K | 12 | Number of candidates the cross-encoder rescores. |
MEMORYPILOT_CROSS_RERANK_WEIGHT | 0.45 | Fusion weight given to the cross-encoder score against the RRF score. Sweep tested 0.20-0.85; 0.45 is the best operating point on --benchmark-fr and stays within 0.2 pp R@5 of the optimum on LongMemEval. |
MEMORYPILOT_RERANK_POOL_SIZE | 1 | Number of cross-encoder ONNX sessions kept hot. 2 helps only under heavy concurrent load; each extra mmarco session costs ~120 MB. |
MEMORYPILOT_EMBED_POOL_SIZE | 1 | Number of embedding ONNX sessions in the pool (legacy fastembed models keep 4, or 2 for 1024-dim). A second jina session adds ~250 MB and only pays off under heavy concurrent writes. |
MEMORYPILOT_EMBED_THREADS | min(4, cores) | ONNX intra-op threads for the embedder. MEMORYPILOT_RERANK_THREADS (default min(2, cores)) does the same for the cross-encoder. |
MEMORYPILOT_RERANKER_MODEL | mmarco | mmarco-mMiniLMv2-L12-H384-v1 int8 (Apache-2.0, ~120 MB resident). Alternatives served the same way (int8, memory-mapped): jina-v2 (jina-reranker-v2-base-multilingual, 280 MB, CC-BY-NC) and gte-multilingual (gte-multilingual-reranker-base, 341 MB, Apache-2.0) — both measured lower on --benchmark-fr (MRR 63.5% / 62.1% vs 65.3% before the v4.5 fix) at 2× the latency, hence not the default. Legacy fp32 fastembed models: jina-v2-multilingual-fp32 (1.1 GB), bge-v2-m3, bge-base, jina-v1. |
MEMORYPILOT_MODEL_IDLE_SECS | 600 | Idle time after which the embedder and reranker sessions are dropped to free memory (~250 MB). 0 keeps them resident (benchmarks). |
MEMORYPILOT_CONSOLIDATE | on | Daily embedding-based consolidation of near-duplicate ephemeral memories (cosine ≥ 0.95 and word overlap ≥ 0.6, same project, newest kept), followed by the supersede pass (see v4.6). off disables it; consolidate_memories runs it on demand. |
MEMORYPILOT_MMR / MEMORYPILOT_MMR_LAMBDA | on / 0.4 | MMR diversity over the finalists. 0 disables; λ = 1.0 is pure relevance, 0.0 pure diversity. MEMORYPILOT_MMR_FLOOR (0.55) is the cosine below which two candidates are not considered redundant. |
MEMORYPILOT_TEMPORAL | on | Query-time date window boost/demotion. 0 disables (date entities are still extracted at ingest). |
MEMORYPILOT_ABSTAIN_COSINE / MEMORYPILOT_TRUST_CROSS | 0.35 / 1.0 | Below the cosine floor a search reports confidence.abstain = true unless the cross-encoder logit on the top hit reaches the trust value. |
MEMORYPILOT_READER_NULL_MARGIN | 0 | Extractive reader: the span logit must beat the model's no-answer logit by this much. Negative values answer more often (−3 → 92/100 answered, 3/7 abstentions still caught on LongMemEval-S@100). |
MEMORYPILOT_EMBED_MODEL | jina | jina-embeddings-v5-text-nano-retrieval int8 (768-dim). jina-q4 = 4-bit variant (140 MB download, ~5× faster queries, −1 pp R@5 / −3 pp MRR on FR). Apache-2.0 alternatives via fastembed: e5-small (384-dim), e5-base, e5-large, bge-m3 (1024-dim). The database records which model produced its vectors; changing the model drops them and re-embeds everything in the background at next start (BM25 keeps answering meanwhile). |
HTTP API
When built with --features http, MemoryPilot exposes a multi-threaded REST API (4 worker threads, each with its own DB connection):
# Health check
curl http://localhost:7437/health

# Call any MCP tool
curl -X POST http://localhost:7437/tools/call \
  -H 'Content-Type: application/json' \
  -d '{"name": "search_memory", "arguments": {"query": "auth setup", "limit": 5}}'
Architecture
src/main.rs        — CLI + MCP stdio server + file watcher init + HTTP server init + benchmark runners
src/code_chunker.rs — Tree-sitter code-aware chunking for Rust/Python/TS/TSX/JS/Go/Java/Kotlin/Swift + Svelte scripts
src/db.rs          — SQLite facade: hybrid search, CRUD, KG, GC, brain, recall, lazy embed, connection pool, ANN warm-up
src/db/benchmark.rs — Internal recall/search quality benchmark helpers
src/db/benchmark_fr.rs — French/multilingual deterministic benchmark (109 queries, ±1pp variance)
src/db/benchmark_longmemeval.rs — LongMemEval-S benchmark runner + regression guard support
src/db/transcript.rs — Transcript/session ingestion and local-only distillation
src/tools.rs       — 41 MCP tool definitions + handlers
src/protocol.rs    — JSON-RPC types
src/embedding.rs   — jina-embeddings-v5 via ONNX Runtime (fastembed for legacy models), EmbedPool, two-tier query cache
src/tokenizer.rs   — lean byte-level BPE (tiktoken ranks) and Unigram tokenizers, ~65 MB instead of ~535 MB with the `tokenizers` crate
src/onnx_external.rs — one-shot rewrite of embedded ONNX weights into a memory-mapped sidecar (ORT 1.28 keeps 3 copies otherwise)
src/pool.rs        — lazily-built, idle-evicting pool shared by the embedder and reranker sessions
src/db/consolidate.rs — embedding-based near-duplicate consolidation (daily + `consolidate_memories`)
src/reranking.rs   — Cross-encoder rerank (jina-v2-multilingual), RerankPool, adaptive trigger, confidence gate
src/ann.rs         — Persistent on-disk HNSW (usearch) with synchronous warm-up via `wait_for_ann_warm`
src/fts.rs         — FTS5 query variants (prefix, phrase, NEAR) + Snowball stemming
src/graph.rs       — Entity extraction (tech, files, components, people) + relation inference + graph traversal
src/gc.rs          — GC scoring, heuristic memory merging, stopwords
src/working_memory.rs — In-process scoped scratchpad memory for current MCP sessions
src/watcher.rs     — File system watcher + auto-linter with persistent DB connection
src/http.rs        — Optional multi-threaded HTTP REST server (feature-gated)
Database Schema
memories           — id, content, kind, project, tags, importance, embedding (BLOB),
                     content_hash, expires_at, last_accessed_at, access_count, metadata
memories_fts       — FTS5 virtual table (content, tags, kind, project)
memory_entities    — memory_id, entity_kind, entity_value, valid_from, valid_to
memory_links       — source_id, target_id, relation_type, valid_from, valid_to, confidence
knowledge_triples  — id, subject, predicate, object, valid_from, valid_to, confidence, source_memory_id
projects           — name, path, description
config             — key/value store
Performance
| Metric | Value |
|---|---|
| Binary size | 35 MB |
Startup (open_at) | 1-2 ms (ANN warm-up runs in background) |
Startup (open_at_warm) | 50-200 ms on 10 k memories (ANN hydrated synchronously, deterministic search from query #1) |
| Search default fast (BM25 + RRF) | ~28 ms avg on LongMemEval-S |
| Search adaptive cross-encoder | ~210 ms avg on --benchmark-fr (R@5 99.1%, MRR 97.4%; v4.4 was 230 ms / R@5 70.6% / MRR 65%, v4.3 415 ms / R@5 60% / MRR 57%) |
| Concurrency p95 (4 clients × 20 queries, 500 memories, adaptive) | 229 ms |
add_memory latency | <1 ms (lazy embed) |
| Embedding quality | Transformer 768-dim (jina-embeddings-v5-text-nano-retrieval int8, 100+ languages, 8k context) |
| Backfill (1000 memories) | ~2 min in the background (model swap re-embed; recall stays interactive, ~1 s, while it runs) |
| RAM (both models loaded, steady state) | ~370 MB on a fresh database, ~485 MB with 2 000 memories in the ANN index — almost all of it memory-mapped int8 weights (247 MB jina + 118 MB mmarco) the OS can reclaim under pressure (was ~3.5 GB idle / ~7 GB peak in v4.3) |
| RAM (idle) | ~130 MB: both ONNX sessions are released after MEMORYPILOT_MODEL_IDLE_SECS (default 600 s) without a query and rebuilt on the next one (~0.8 s once, ~0.3 s for the reranker alone) |
RAM (--benchmark-fr, peak) | 364 MB (was 7.05 GB) |
| Read concurrency | 16 pooled connections per Database handle |
| Runtime dependencies | None (ONNX bundled) |
Optimizations
- Lazy embedding:
add_memoryinserts withNULLembedding, background thread computes and updates asynchronously - Content hashing (FNV-1a):
--backfill-forceskips memories whose content hasn't changed - Two-tier embedding cache: 256-entry in-process LRU on top of a write-through SQLite query cache (
*.query_cache.sqlite, soft-capped at 8 192 entries with LRU eviction) so repeated queries are instant within a session and across restarts - Read connection pool (4 connections): concurrent vector searches don't block writes
- WAL mode: SQLite Write-Ahead Logging for concurrent read/write
- Batched scoring: knowledge triple counts and link boosts fetched in single queries, not N+1
- Debounced cleanup: expired memory cleanup runs max once per 60 seconds
- Prepared statements: graph traversal prepares SQL once, not per node
- Tuned RRF fusion: k=40 for sharper top-K discrimination vs standard k=60
- FTS5 precision fallbacks: prefix, exact phrase, and NEAR proximity queries run together for code symbols, errors, and named concepts
- Weighted FTS fields: content, tags, kind, and project use separate BM25 weights to make structured metadata count
- ACT-R-style activation: frequently reused and recently accessed memories get a small cognitive activation boost before final reranking
- int8 quantized embeddings: stored vectors are 4× smaller (388 bytes vs 1536 bytes) with negligible recall loss; fast SIMD-friendly dot product directly on the blob avoids per-search allocations
- Local HNSW ANN index (
usearch): persistent on-disk approximate nearest neighbor index that warms asynchronously from SQLite in a detached thread (non-blocking startup), updates incrementally on backfill, on the async embed worker, and on delete. Surfacesvector_anncandidates so large memory bases stay fast as they grow past tens of thousands of entries. - ANN scan bypass: when the index reaches 5,000+ entries, the SQL vector scan is restricted to the union of ANN top-K and BM25 hits — turning an O(N) blob load into an O(K) lookup without changing the ranking logic.
- Code-aware chunking: tree-sitter splits Rust/Python/TypeScript/TSX/JavaScript on semantic units, with Svelte
<script>extraction - Exact term coverage boost: +10% when 80%+ of query terms appear in memory content
- Combinatorial reranker: greedy subgraph selection, conservative +5% per connection (cap 15%)
- KG query expansion: post-retrieval scoring boost from knowledge graph related terms (+4% per entity, cap 15%)
- Temporal recency: gentle +5% for memories from last 3 days, decaying over 30 days
- Importance tiebreaker: ±3% per level — never overrides relevance signal
- Adaptive cross-encoder reranking (jina-v2-multilingual via FastEmbed ONNX, default ON): triggers on hard / non-English queries, fuses with the RRF score at a tunable 0.45 weight, drops cleanly to BM25+RRF on easy English queries to stay under 30 ms. Pool of N sessions (
MEMORYPILOT_RERANK_POOL_SIZE) absorbs concurrent load. - Confidence gate: skips rerank when the top-1 RRF score is already ≥ 25 % above top-3 (latent path; active when force-rerank is enabled)
- Auto-compaction: GC triggers automatically when memory count > 500, debounced to once per 5 minutes
- Memory capsules: old low-importance memories compressed into ~100-200 token summaries (5-10x savings)
- Zero-shot auto-classification: pattern-based heuristics assign kind, importance, and TTL on insert without LLM
Fast Local Development
Use cargo check for day-to-day validation; it catches type and borrow errors without paying the full linking cost.
make check          # cargo check
make check-http     # cargo check --features http
make test           # cargo test
make timings        # cargo build --timings
make check-cached   # RUSTC_WRAPPER=sccache cargo check
sccache is optional but recommended for frequent rebuilds:
make sccache-install
make build-cached
Cargo aliases are also available: cargo dev, cargo check-http, cargo test-fast, cargo timings, and cargo build-http.
Keep cargo build --release --features http for release validation and benchmark runs. Linker swaps such as mold or lld are intentionally not enabled by default on macOS; measure with cargo build --timings first before changing .cargo/config.toml.
Run Benchmarks Yourself
MemoryPilot --benchmark-search --scenario-limit 30    # R@5, R@10, NDCG@10, cluster coherence, latency
MemoryPilot --benchmark-recall --scenario-limit 12    # top1/top5 hit rate, cross-project leak, credential safety
MemoryPilot --benchmark-longmemeval [PATH] [--limit N] [--min-r5 PCT] # LongMemEval-S with regression guard
The LongMemEval benchmark downloads the LongMemEval-S dataset and evaluates retrieval quality across 470 questions with turn-level granularity. Results are output as JSON with per-category breakdowns.
The cross-encoder runs in adaptive mode by default (triggers on hard / non-English queries). Force or disable it explicitly:
MEMORYPILOT_CROSS_RERANK=off MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json     # baseline, ~28ms/query, 98.7% R@5
MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json                                 # adaptive (default), ~900ms/query, 99.1% R@5
MEMORYPILOT_CROSS_RERANK=1 MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json      # force on every query, max latency
MEMORYPILOT_CROSS_RERANK_WEIGHT=0.70 MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json  # bias more toward the cross-encoder score
MEMORYPILOT_RERANKER_MODEL=bge-v2-m3 MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json  # swap the model
Supported model shortcuts: jina-v2-multilingual (default), bge-v2-m3, bge-base, and jina-v1. Validated full-run results on the 470 evaluable LongMemEval-S questions: default fast mode reaches 98.7% R@5, 95.1% NDCG@10, 93.6% MRR, ~28 ms average search latency; adaptive mode reaches 99.1% R@5, 96.0% NDCG@10, 94.9% MRR, ~900 ms average search latency. The deterministic French benchmark (--benchmark-fr) is the canonical regression test for any multilingual change — variance is bounded to ±1 pp R@5 across runs.
Storage
- Database:
~/.MemoryPilot/memory.db - Global prompt:
~/.MemoryPilot/GLOBAL_PROMPT.md - Model cache:
~/.cache/fastembed/(Hugging Face layout, downloaded on first run;FASTEMBED_CACHE_PATHoverrides). Externalized ONNX weights live inmemorypilot-external/inside it.
License
Soflution Source Available License — free to use, not to fork or modify. See LICENSE for details.
Built by SOFLUTION LTD
Contributors

75 commits
Similar repos


Languages
Rust
97.2%
Python
1.3%
Shell
1.1%
The most advanced AI memory server in the world. Hybrid search, Temporal Knowledge Graph, transformer embeddings, AAAK compression (3x token savings) — pure Rust, single binary, zero dependencies.
See the codeREADME
The most advanced MCP memory server. Period.
Hybrid search (BM25 + jina-embeddings-v5 RRF + cross-encoder rerank) · 100+ languages · Temporal Knowledge Graph · Query-aware ranking · Corpus origin detection · Agent/persona disambiguation · Topic tunnels · AAAK compression (5-10x token savings) · GraphRAG · Chunked RAG · Auto-Compaction · Auto-Classification · Memory Capsules · HTTP API · Single binary · Zero API calls
Why
AI coding assistants forget everything between sessions. MemoryPilot gives them persistent, searchable memory with project awareness, semantic understanding, and automatic knowledge organization. Built-in AAAK compression and memory capsules reduce token consumption by 5-10x when loading context. Every memory is auto-classified with the right importance, kind, and TTL on insert. The database compacts itself automatically — zero maintenance.
Install MemoryPilotOne-liner install for Cursor, Claude Desktop, VS Code, Windsurf, Claude Code, Codex and ChatGPT. Single Rust binary, zero runtime dependencies. |
How it worksThe 9 pillars — hybrid search, temporal knowledge graph, GraphRAG, AAAK compression, auto-classification, self-healing — explained end to end. |
Benchmarks
LongMemEval-S (ICLR 2025) — Academic Standard
Evaluated on 470 questions from the LongMemEval benchmark (ICLR 2025), the standard academic dataset for long-term memory retrieval. Turn-level granularity, ~50 sessions per haystack.
vs the entire market (LongMemEval-S, public numbers)
| System | R@5 / Accuracy | Latency | Privacy | Stack | Source |
|---|---|---|---|---|---|
| MemoryPilot v4.2 (adaptive) | 99.1% | ~900 ms | 100% local | Rust · 35 MB binary · zero API | This repo, --benchmark-longmemeval @470 |
| MemoryPilot v4.2 (default fast) | 98.7% | ~28 ms | 100% local | Rust · 35 MB binary · zero API | This repo, --benchmark-longmemeval @470 |
| MemPalace v3.3.3 (hybrid) | 98.4% | not published | 100% local | Python + ChromaDB · ~500 MB | MemPalace v3.3.3 release notes |
| agentmemory v0.9 (11k+ stars) | 95.2% | not published | 100% local | Node + iii-engine + SQLite | github.com/rohitg00/agentmemory — benchmark/LONGMEMEVAL.md |
| Mem0 (cloud, OpenAI backend) | 94.4% | ~6 787 tokens/query | Cloud (OpenAI) | SaaS + OpenAI embeddings | mem0.ai blog |
| mcp-memory-service v10.34.0 | 80.4% | not published | 100% local | Python + SQLite-Vec + MiniLM | v10.34.0 release notes |
| Zep / Graphiti | 63.8% | "90% lower vs baseline" | Cloud or self-host | Python + Neo4j + LLM extraction | arXiv 2501.13956 |
| Letta / MemGPT | not measured on LongMemEval | — | Self-host | Python framework | Letta tracking issue #3115 |
MemoryPilot is the only system in this comparison that is both 100% local and tops the leaderboard. The default fast mode (~28 ms) already beats every published competitor — including agentmemory (95.2%), the current darling of the AI-agent-memory category with 11k+ GitHub stars. The adaptive cross-encoder mode adds +0.4 pp R@5 for the cost of one ONNX rerank pass per query, and a +6.7 pp MRR lead vs agentmemory (94.9% vs 88.2%).
Detailed view — MemoryPilot vs MemPalace (closest local competitor)
| Metric | MemoryPilot v4.2 (default fast) | MemoryPilot v4.2 (adaptive rerank) | MemPalace v3.3.3 | Delta vs MemPalace |
|---|---|---|---|---|
| R@5 | 98.7% | 99.1% | 96.6% raw / 98.4% hybrid | +2.5% vs raw / +0.7% vs hybrid |
| R@10 | 99.6% | 99.4% | ~97%¹ | +2.6% vs raw |
| NDCG@10 | 95.1% | 96.0% | Not published | MemoryPilot publishes |
| MRR | 93.6% | 94.9% | Not published | MemoryPilot publishes |
| Avg search latency | ~28 ms | ~900 ms | N/A | Default mode is 30× faster |
¹ Validated with the full 470-question evaluation set (after dropping the 30 abstention questions) in two modes: default fast local hybrid retrieval (BM25 + cosine RRF, ~28 ms/query, suitable for live MCP traffic) and adaptive cross-encoder rerank (
MEMORYPILOT_CROSS_RERANK=adaptive, jina-v2-multilingual, fusion weight 0.45, ~900 ms/query, suitable for benchmarks and high-stakes recall). The default mode already beats MemPalace's hybrid held-out result; the adaptive mode trades latency for a further +0.4 pp R@5 and +1.3 pp MRR.
By Category (470 questions, adaptive rerank)
| Category | R@5 | R@10 | MRR |
|---|---|---|---|
| single-session-user (64) | 100% | 100% | 96.6% |
| single-session-assistant (56) | 100% | 100% | 98.8% |
| multi-session (121) | 100% | 100% | 95.7% |
| knowledge-update (72) | 100% | 100% | 98.2% |
| temporal-reasoning (127) | 97.6% | 98.4% | 93.3% |
| single-session-preference (30) | 96.7% | 96.7% | 75.9% |
French / Multilingual Benchmark — --benchmark-fr
To complement the English-only LongMemEval, MemoryPilot ships its own deterministic French benchmark covering 109 memories and 109 paraphrased queries across infra, mobile, web, security, and ML domains. The queries are intentionally distant from the indexed wording so they actually exercise the semantic lane.
| Mode | R@5 | R@10 | MRR | Avg latency |
|---|---|---|---|---|
| Default fast (BM25 + jina RRF) | 92.7% | 99.1% | 74.4% | ~100 ms |
| Adaptive cross-encoder rerank (default) | 99.1% | 99.1% | 97.4% | ~210 ms |
v4.5 fixed a ranking bug that had capped this benchmark at R@5 ≈ 70% since v4.0: knowledge-graph neighbours were injected at a hard-coded score (0.1) above every genuine RRF hit (max 2/41 ≈ 0.049), so they occupied the cross-encoder window and pushed real matches past limit. Neighbours now enter below the weakest genuine candidate and only the cross-encoder can promote them.
v4.5.0 also closes two write-path stability bugs surfaced by that work: the episodic rollup embedded every hourly bucket on each pass (before checking whether the episode already existed) and did so synchronously inside add_memory, then panicked on multi-byte French text; it now runs on its own thread with a cheap existence check first. And auto-compaction held a Mutex across run_gc/compact_to_capsules, whose merged rows re-enter add_memory — a deadlock hidden until the rollup stopped panicking ahead of it.
Run-to-run variance is bounded to ±1 pp on R@5 / R@10 thanks to deterministic memory ids, deterministic id-based RRF tie-break, synchronous ANN warm-up, and explicit cross-encoder pre-warm before the first query. This is the metric to watch for any French / multilingual regression.
v4.6 — beyond single-fact retrieval
v4.6.0 targets the LongMemEval categories a top-k retriever alone cannot win: multi-session aggregation, temporal reasoning, knowledge updates and abstention. Everything stays local and rule-based or int8 ONNX. Measured on LongMemEval-S@100 (64 single-session + 36 multi-session, plus the 7 abstention questions of that slice) against v4.5.0, same machine, cross-encoder adaptive:
| Metric | v4.5.0 | v4.6.0 |
|---|---|---|
| R@5 / R@10 | 99% / 100% | 100% / 100% |
| MRR / nDCG@10 | 96.3% / 97.2% | 96.5% / 97.3% |
| Multi-session gold coverage@10 | 93.6% | 94.5% |
| Multi-session questions with all gold sessions in top-10 | 30/36 | 32/36 |
| False abstention on answerable questions | — | 4% |
Extractive answer (search_memory … answer=true), contains-gold | — | 48% (72% single-session; counting questions are out of reach for span extraction) |
--benchmark-fr is unchanged within noise (R@1 96.3%, R@5 99.1%, MRR 97.6%).
- MMR diversity (
src/diversity.rs) — the finalists plus the RRF ranks just below them are re-ordered by maximal marginal relevance over their stored vectors (λ = 0.4, redundancy floor 0.55). The top hit never moves, so MRR is untouched; a second, distinct source can displace a restatement of the first.MEMORYPILOT_MMR=0disables it. - Temporal grounding (
src/temporal.rs) — explicit dates in a memory (2026-09-01,12 septembre 2026,September 12,hier…) becomedateentities at ingest; a temporal phrase in the query (last week,il y a deux semaines,en mars,last Tuesday) becomes a day window that boosts dated candidates inside it (×1.25) and mildly demotes dated candidates far outside (×0.85). Undated memories are neutral, so a mis-parsed window costs at most the boost.MEMORYPILOT_TEMPORAL=0disables it. - Contextual embeddings — transcript chunks and other context-poor kinds are embedded with a
[date · project]prefix while the stored content and its hash are left untouched. - Superseding — the daily consolidation pass links a memory to a newer, near-identical restatement with a changed value (cosine ≥ 0.86, lexical overlap 0.55–0.95, ≥ 1 h apart) and the old one is demoted (−0.35) at search time. Both stay retrievable;
consolidate_memories(apply=true)reports the links made. - Calibrated confidence — every search returns
confidence: { top_cosine, peak, cross_score, margin, level, abstain }. On LongMemEval the abstention haystacks are built from the same user's other sessions and no cheap signal separates them from answerable questions (top-1 cosine p50 0.46 vs 0.54, cross-encoder logits overlap fully), so the hardabstainis deliberately conservative (cosine < 0.35, 4% false abstention) andlevelcarries the graded signal.MEMORYPILOT_ABSTAIN_COSINEmoves the floor. - Extractive reader (
src/reader.rs, opt-in) —search_memorywithanswer: truerunsdeepset/roberta-base-squad2(int8 ONNX, 125 MB, English, loaded on demand through the idle pool) over the top-5 passages and returns the literal span or nothing. ~480 ms per question on CPU. It is a benchmarking instrument and a shortcut for literal lookups, not a language model: it abstained on 5/7 LongMemEval abstention questions where the retriever could not.--benchmark-longmemeval --readerreports SQuAD-style EM / F1 / contains.
Search Quality — Real-World (500 memories, 30 scenarios)
| Metric | MemoryPilot v4.2 | MemPalace v3.1 (raw) | Quantum Memory Graph |
|---|---|---|---|
| R@5 | 100% | 96.6% | 93.4% |
| R@10 | 100% | N/A | 93.4% |
| NDCG@10 | 95.6% | 88.9% | 90.8% |
| Cluster Coherence | 96.7% | N/A | N/A |
| Multilingual | 100+ languages (validated FR R@5 99.1%) | English only | English only |
| AAAK Compression | 5-10x (no recall loss) | 30x (recall drops to 84.2%) | N/A |
| Avg Search Latency | ~28 ms default / ~410 ms adaptive | N/A | ~80 ms |
| Binary Size | 35 MB | ~500 MB (Python+ChromaDB) | 1.5 GB |
| Dependencies | 0 (single binary, ONNX bundled) | Python + ChromaDB + SQLite | Python + ONNX |
vs the best memory servers on the market:
| Feature | MemoryPilot v4.2 | MemPalace v3.3.3 | agentmemory v0.9 | Mem0 | Zep / Graphiti |
|---|---|---|---|---|---|
| LongMemEval R@5 | 99.1% | 98.4% | 95.2% | 94.4% | 63.8% |
| LongMemEval MRR | 94.9% | not published | 88.2% | not published | not published |
| Search | Hybrid BM25 + jina-embeddings-v5-nano RRF (768-dim, int8) + adaptive mmarco cross-encoder | ChromaDB cosine (all-MiniLM-L6-v2) | BM25 + vector + graph (RRF) | Vector search (cloud API) | Temporal KG traversal + vector |
| Embeddings | jina-embeddings-v5-text-nano-retrieval (100+ languages, 8k context, local ONNX) | all-MiniLM-L6-v2 (English only) | all-MiniLM-L6-v2 (English only) | OpenAI API calls (external) | OpenAI / cloud LLM extraction |
| Multilingual | 100+ languages native (FR, EN, ES, DE, JA, ZH...) | English only | English only | Depends on API | Depends on LLM backend |
| Knowledge Graph | Temporal triples with validity + confidence | Temporal triples (SQLite) | Knowledge graph (no validity window) | Basic graph (no temporal) | Temporal KG (Graphiti, core feature) |
| GraphRAG | Auto entity extraction + graph traversal + combinatorial reranker | No | Partial (graph search lane) | No | Yes (LLM-based extraction) |
| Cross-encoder rerank | jina-v2-multilingual (adaptive, ~250 ms) | No | No | No | No |
| Query-aware ranking | Preference/temporal/role/update/technical intent boosts | Hybrid v4 keyword + temporal boosts | RRF fusion only | Depends on API | Graph-distance scoring |
| Corpus origin detection | AI transcript/codebase/notes/platform detection | v3.3.4 prep | No | No | No |
| Agent/persona disambiguation | Agents are separate from real people | v3.3.4 prep | Hooks-based session scoping | No | Partial (entity nodes) |
| Topic tunnels | Cross-project topic links via KG | v3.3.4 prep | No | No | No |
| Code-aware chunking | Tree-sitter Rust/Python/TS/TSX/JS + Svelte script extraction | Tree-sitter code chunking | No | No | No |
| Chunked RAG | Transcript auto-chunking + auto-distillation (8 types) | Conversation chunking by exchange | Session replay + JSONL import | No | LLM-based summarisation |
| Compression | AAAK + Memory Capsules (5-10x token savings) | AAAK dialect (experimental, regresses recall to 84.2%) | 4-tier consolidation + decay | No | No |
| Auto-Classification | Zero-shot kind/importance/TTL on insert | No | Pattern-based via hooks | No | LLM-classified entities |
| Auto-Compaction | GC triggers automatically at 500+ memories | No | Lifecycle decay + auto-forget | No | Manual |
| Memory Capsules | Compress old memories into dense summaries | No | Tier-based consolidation | No | No |
| Memory Pinning | Pin critical memories — always in recall, GC-proof | No | No | No | No |
| Graph Traversal | Find related memories via KG (depth 1-3) | No | Yes (graph lane) | No | Native (Cypher / Neo4j) |
| Bulk Operations | Delete by kind/project/tag/age with safety guards | No | Governance delete API | No | Manual |
| Health Dashboard | Memory distribution, stale count, orphans, DB size | No | Real-time web viewer (port 3113) | No | No |
| Dedup Detection | Jaccard similarity scan for near-duplicates | No | Not documented | No | LLM-based reconciliation |
| Person detection | Auto-detects team members from text | No | No | No | LLM-extracted entities |
| Self-Healing | Background auto-linting loop | No | No | No | No |
| Garbage collection | Heuristic merge + scoring + orphan cleanup | No | Lifecycle + decay | Basic TTL | No automatic GC |
| Project brain | Yes, with team members (<1500 tokens) | No | Session summary on demand | No | No |
| File watcher | Context boost from recent edits | No | Filesystem connector (@agentmemory/fs-watcher) | No | No |
| Deduplication | Content hash (exact) + Jaccard 85% (fuzzy) | Basic hash | Confidence scoring | Embedding similarity | LLM-based merge |
| HTTP API | Multi-threaded REST server (optional) | No | REST + MCP + leases + signals | Cloud hosted | REST + GraphQL |
| Memory types | 13 types, importance 1-5 | Wings/Rooms hierarchy | Tier-based (working / short / long / archival) | 1 type | Episodic / semantic |
| MCP tools | 41 tools | 29 tools | 51 tools | N/A | Limited MCP server |
| Hooks / event capture | File watcher + auto-linter (Rust-only) | No | 12 named hooks (SessionStart, UserPromptSubmit, PreToolUse...) | No | No |
| Privacy | 100% local, zero API calls | 100% local | 100% local (SQLite) | Cloud dependent | Cloud or self-host (LLM required) |
| Language | Rust (single binary, zero deps) | Python (pip install) | TypeScript / Node (npm install) | SaaS | Python + Neo4j |
| Startup | 1-2 ms (open_at) / synchronous warm via open_at_warm | ~5 ms | Node boot + iii-engine init | N/A (cloud) | Heavy (Neo4j boot) |
| Binary | 35 MB single binary | Python + ChromaDB (~500 MB installed) | Node runtime + iii-engine deps | SaaS | Python + Neo4j (~1.5 GB) |
| Storage | SQLite WAL + FTS5 + 16-conn read pool | ChromaDB | SQLite + iii-engine | Cloud DB | Neo4j + Postgres |
| Concurrency | EmbedPool (4) + RerankPool (1, tunable) + 16 read conns + debounced cleanup | Single-threaded | Node event loop | Single-threaded | Neo4j-bound |
| External LLM dependency | None | None | None (local embeddings) | OpenAI required | LLM required for ingestion |
| GitHub stars (May 2026) | nascent | nascent | 11 083 | 53k | — |
The 9 Pillars
1. Hybrid Search (BM25 + jina RRF)
Every memory gets a 768-dimension transformer embedding on insert via ONNX Runtime (jina-embeddings-v5-text-nano-retrieval, int8, local inference — 100+ languages including French, English, Spanish, German, Japanese, Chinese — no API calls, no external services; the model is fetched from its Hugging Face repository on first run, licence CC-BY-NC-4.0). Queries and documents use the model's asymmetric Query: / Document: prefixes. The int8 weights are memory-mapped, so the embedder costs ~250 MB resident, most of it reclaimable file-backed pages. Search runs both BM25 full-text and cosine similarity in parallel, then merges results with Reciprocal Rank Fusion.
Results are boosted by importance weighting, knowledge graph link density, file watcher context, and penalized for expired knowledge triples.
Ephemeral working memory is available in the same MCP through remember_working, recall_working, and clear_working. It keeps fast session scratchpad context in RAM, capped to 256 items, without polluting SQLite or durable recall.
Performance optimizations:
- Lazy embedding:
add_memoryreturns instantly, embeddings computed in background thread - Two-tier query embedding cache (LRU 256 + write-through SQLite): repeated queries skip ONNX inference
- Read connection pool (16 connections): concurrent vector searches don't block writes, sized for HTTP server workloads
- EmbedPool (4 sessions, env-tunable): parallel embeddings without serialization on a single ONNX mutex
- RerankPool (1 session, env-tunable to 2): parallel cross-encoder rerank under multi-client load
- Content hashing (FNV-1a): backfill skips unchanged memories
- Synchronous warm-up entrypoint
open_at_warm: hydrates the ANN index in RAM before returning, eliminating cold-start tail (p95 search latency 3939 ms → 229 ms in the 4-client concurrency bench)
2. Temporal Knowledge Graph
A full knowledge graph with temporal validity. Facts have valid_from / valid_to dates and confidence scores. When facts become outdated, they are invalidated rather than deleted — giving the AI a timeline of how knowledge evolved.
Entities (technologies, files, components, people) are automatically extracted from memory content and linked bidirectionally. Search results from memories with all-expired triples are penalized.
5 dedicated KG tools: kg_add, kg_invalidate, kg_query, kg_timeline, kg_stats
3. GraphRAG
Every memory is automatically analyzed for entities: technologies, file paths, components, projects, and people. Entities are stored in a dedicated table. Memories sharing entities are auto-linked with inferred relationship types (resolves, implements, depends_on, deprecates...).
When searching, MemoryPilot traverses the knowledge graph from the top matches to pull in related context — e.g., finding the architecture decision that led to a specific bug fix. A combinatorial reranker then selects the best cluster of connected memories rather than independent top-K results, producing cohesive context (94% cluster coherence). Tuned RRF fusion (k=40), exact term coverage boost, smart FTS tokenization, query-time KG expansion, temporal recency, and importance tiebreakers push NDCG@10 to 94% with perfect R@5/R@10.
4. Chunked RAG (Transcripts)
Save full conversation transcripts without polluting the LLM context window. The add_transcript tool automatically chunks large texts into ~2000 character blocks and links them together. Chunks are excluded from recall but fully searchable.
For source code, MemoryPilot uses local tree-sitter parsing by default for Rust, Python, TypeScript, TSX, and JavaScript, with Svelte support via <script> extraction plus markup chunking. Code is split on semantic boundaries such as functions, classes, impl blocks, interfaces, and exports instead of arbitrary paragraphs.
Auto-distillation extracts structured memories from transcripts: decision, preference, todo, bug, milestone, problem, and note. Smart disambiguation: a segment mentioning both a bug and its resolution is classified as milestone, not bug.
Supports session_id, thread_id, window_id for multi-window memory scoping.
5. AAAK Compression
Inspired by MemPalace's symbolic memory language. When compact: true is passed to recall or get_project_brain, output is compressed ~3x using a terse, pipe-separated format:
[DEC:5] Use Clerk over Auth0 | tags:auth,stack | proj:MyApp
[PREF:4] Always use TypeScript strict mode | tags:typescript
6. Self-Healing (Auto-Linter)
MemoryPilot watches your files. When you save a Rust, Svelte, or TypeScript file, it lints in the background. Compilation errors are automatically stored as bug memories with the exact stack trace. When the error is fixed, the memory is auto-deleted.
The linter thread reuses a single DB connection for its entire lifetime.
7. Garbage Collection & Auto-Compaction
Old, low-importance memories are scored for cleanup candidacy. Groups of related stale memories are merged into condensed summaries using heuristic keyword extraction. Orphaned links and entities are cleaned. DB is vacuumed after significant deletions.
Auto-compaction triggers automatically when the memory count exceeds 500: the GC runs in the background after add_memory, debounced to once per 5 minutes. Zero manual intervention.
Memory Capsules (compact_memories tool): compress old low-importance memories into dense ~100-200 token capsules. Credentials and architecture decisions are never compressed. Capsules preserve Knowledge Graph links, giving you 5-10x token savings on aged memories without recall loss.
8. Zero-Shot Auto-Classification
Every memory is automatically classified on insert when the caller doesn't specify kind or importance. Pattern-based heuristics detect:
- Credentials (API keys, secrets) → importance 5, no TTL
- Architecture decisions → importance 5
- Preferences/patterns → importance 4
- Bugs → importance 3, TTL 90 days
- TODOs → importance 2, TTL 30 days
- Code snippets → importance 2
- Milestones → importance 4
No LLM needed — pure regex + keyword heuristics. The AI can still override by passing explicit kind and importance.
9. Project Brain
One tool call returns a dense JSON snapshot of a project under 1500 tokens: tech stack, architecture decisions, active bugs, recent changes, key components, and team members (auto-detected person entities). Supports compact: true for AAAK compression.
Install
Homebrew (macOS / Linux)
brew install Soflutionltd/memorypilot/memorypilot
That's it. Builds from source via cargo (Homebrew pulls Rust automatically). After install, run ./install.sh from the cloned repo or follow the manual MCP config below.
One-liner — auto-configures every IDE on your machine
curl -fsSL https://raw.githubusercontent.com/Soflutionltd/MemoryPilot/main/install.sh | bash
What this does:
- Detects your platform (macOS arm64 / x64, Linux x64 / arm64).
- Fetches the pre-built binary from the latest GitHub Release (~11 MB tar.gz).
- Installs to
~/.local/bin/MemoryPilotand clears Gatekeeper attributes on macOS. - Auto-configures every supported IDE / agent it finds — Cursor, Claude Desktop, Claude Code, Codex CLI, Gemini CLI, Windsurf, VS Code, OpenCode, Cline, Roo Code — in a single pass.
If no pre-built binary is available for your platform, it falls back to cargo build --release --features http automatically (requires Rust).
Alternative paths
# Via Cargo, pinned to a release tag — works anywhere Rust runs:
cargo install --git https://github.com/Soflutionltd/MemoryPilot --tag v4.2.0 --features http --bin MemoryPilot

# Local clone + auto-config (same installer, run from inside the repo):
git clone https://github.com/Soflutionltd/MemoryPilot.git && cd MemoryPilot && ./install.sh
The installer is idempotent: re-run it any time to refresh configs without breaking the others.
Pre-built binaries
Every release ships pre-built binaries for the three mainstream targets — built by the release CI workflow on every v*.*.* tag:
| Platform | Target triple | Archive |
|---|---|---|
| macOS Apple Silicon | aarch64-apple-darwin | MemoryPilot-aarch64-apple-darwin.tar.gz |
| Linux x86_64 | x86_64-unknown-linux-gnu | MemoryPilot-x86_64-unknown-linux-gnu.tar.gz |
| Linux arm64 | aarch64-unknown-linux-gnu | MemoryPilot-aarch64-unknown-linux-gnu.tar.gz |
Each archive is paired with a .sha256 for verification. Grab them from the releases page.
Intel Mac (
x86_64-apple-darwin): no pre-built binary — theort/ ONNX Runtime crate used byfastembeddoes not publish prebuilts for this target. Usebrew install Soflutionltd/memorypilot/memorypilot(builds from source) orcargo install --git .... Apple Silicon Macs (M1+) are fully covered with a pre-built binary.
Supported IDEs / agents (auto-configured by ./install.sh):
| Agent | Config file / command | Auto-configured |
|---|---|---|
| Cursor | ~/.cursor/mcp.json | ✓ (stdio) |
| VS Code | ~/.vscode/mcp.json | ✓ (stdio) |
| Claude Desktop | ~/Library/Application Support/Claude/claude_desktop_config.json | ✓ (stdio) |
| Claude Code | claude mcp add | ✓ (CLI) |
| Codex CLI | codex mcp add | ✓ (CLI) |
| Gemini CLI | ~/.gemini/settings.json | ✓ (stdio) |
| Windsurf | ~/.codeium/windsurf/mcp_config.json | ✓ (stdio) |
| OpenCode | ~/.config/opencode/opencode.json | ✓ (stdio) |
| Cline (VS Code) | ~/Library/Application Support/Code/User/globalStorage/saoudrizwan.claude-dev/settings/cline_mcp_settings.json | ✓ (stdio) |
| Roo Code (VS Code) | ~/Library/Application Support/Code/User/globalStorage/rooveterinaryinc.roo-cline/settings/cline_mcp_settings.json | ✓ (stdio) |
| ChatGPT Desktop | Settings → Apps → Create | via HTTP (see below) |
Additional MCP-compatible clients (use the same stdio binary, manual config):
| Agent | Notes |
|---|---|
| Goose | YAML config under ~/.config/goose/config.yaml — add MemoryPilot under extensions: with type: stdio, cmd: ~/.local/bin/MemoryPilot |
| Kilo Code | Same cline_mcp_settings.json format under the Kilo VS Code extension storage path |
| Continue.dev | ~/.continue/config.json — add to mcpServers |
| Zed | Settings → Assistant → Context Servers → add stdio command |
| Aider | No native MCP; use the REST API (see HTTP API section) |
The script is idempotent — run it again to update without breaking existing MCP configs.
ChatGPT Desktop
ChatGPT requires a remote MCP endpoint. Start the HTTP server, then add it as a custom connector:
MemoryPilot --http 7437
In ChatGPT: Settings → Apps → Create → URL: http://localhost:7437/mcp
Manual install
git clone https://github.com/Soflutionltd/MemoryPilot.git
cd MemoryPilot
cargo build --release --features http
cp target/release/MemoryPilot ~/.local/bin/
chmod +x ~/.local/bin/MemoryPilot
xattr -cr ~/.local/bin/MemoryPilot  # macOS only
Then add MemoryPilot to your IDE's MCP config manually (see table above for file paths).
How it works
That's it. MemoryPilot automatically injects a dynamic System Prompt into your IDE on startup. The AI will proactively call add_memory in the background to store your architecture decisions, API keys, and bug fixes without manual intervention. All configured IDEs share the same memory database.
For ChatGPT or any MCP client that needs HTTP: run MemoryPilot --http to expose the Streamable HTTP endpoint at /mcp.
Or use via McpHub for SSE transport with all your other MCP servers.
First run
# If upgrading from v1 (JSON files):
MemoryPilot --migrate

# Compute embeddings for existing memories:
MemoryPilot --backfill

# Force re-embed all (skips unchanged via content hash):
MemoryPilot --backfill-force
MCP Tools (30)
Core
| Tool | Description |
|---|---|
recall | Start here. Loads all context in one shot: project memories, scoped thread/window memories, preferences, critical facts, patterns, decisions, global prompt. Supports mode = safe/default/full, compact = true for AAAK compression. |
get_project_brain | Instant project summary (<1500 tokens): tech stack, architecture, bugs, recent changes, components, team members. Supports compact = true. |
search_memory | Hybrid BM25 + jina RRF search, boosted by importance, graph links, and file watcher context. Batched triple scoring. |
get_file_context | Memories related to recently modified files in working directory. |
Memory CRUD
| Tool | Description |
|---|---|
add_memory | Store with lazy embedding, auto-dedup (hash exact + Jaccard 85%), auto entity extraction, auto graph linking, auto-classification (kind, importance, TTL inferred from content). |
add_memories | Bulk add multiple memories in one call with per-item dedup. |
add_transcript | Store a long transcript as chunked archive, auto-distill structured memories (decision, preference, todo, bug, milestone, problem, note). |
ingest_session | Ingest local Claude/Cursor/session transcripts into the same MemoryPilot MCP. Defaults to distill_only=true, so only high-value memories are indexed. |
get_memory | Retrieve by ID. |
update_memory | Update content, kind, tags, importance, TTL. Skips re-embedding if content unchanged (hash check). |
delete_memory | Delete by ID (cascades to entities and links). |
list_memories | List with project/kind filters and pagination. |
Knowledge Graph
| Tool | Description |
|---|---|
kg_add | Add a fact triple (subject → predicate → object) with optional validity period and confidence score. |
kg_invalidate | Mark a triple as expired (sets valid_to), preserving history. |
kg_query | Query all triples related to an entity, with temporal filtering and direction control. |
kg_timeline | Chronological history of all triples involving an entity. |
kg_stats | Summary statistics: total triples, active, expired, unique subjects/objects. |
Project & Config
| Tool | Description |
|---|---|
get_project_context | Full project context with preferences and patterns. |
register_project | Register project with filesystem path for auto-detection. |
list_projects | List projects with memory counts. |
get_stats | DB statistics: totals, by kind, by project, DB size, hygiene signals. |
get_global_prompt | Auto-discover GLOBAL_PROMPT.md from ~/.MemoryPilot/ or project root. |
export_memories | Export as JSON or Markdown with importance stars. |
set_config | Set config values (e.g. global_prompt_path). |
Maintenance
| Tool | Description |
|---|---|
run_gc | Garbage collection: merge old memories, clean orphans, vacuum. Supports dry_run. |
compact_memories | Compress old low-importance memories into dense capsules (~100-200 tokens). Credentials/architecture never compressed. |
cleanup_expired | Remove expired TTL memories (debounced — runs max once per 60s). |
pin_memory | Pin a critical memory — always included in recall, never garbage collected. |
unpin_memory | Unpin a previously pinned memory, making it eligible for GC again. |
find_related | Find all memories related to a given ID via Knowledge Graph traversal (depth 1-3). |
bulk_delete | Delete memories by kind, project, tag, age, or importance. Never touches pinned memories. |
get_memory_health | Health report: distribution by kind/project/importance, stale count, orphans, compression potential, DB size. |
dedupe_report | Find potential duplicates via Jaccard similarity for manual review. |
consolidate_memories | Fold near-duplicate ephemeral memories (embedding cosine ≥ threshold, same project, never decisions/credentials/pinned) into their newest member — tags, importance, access counts and graph links merged. Dry-run by default, apply: true to execute; also runs automatically once a day. |
analyze_corpus | Inspect text without writing memory: origin, platform, agents/personas, and reliable topics. |
benchmark_recall | Recall quality benchmark with golden scenarios. |
benchmark_search | Search quality benchmark: R@5, R@10, NDCG@10, cluster coherence, latency. |
migrate_v1 | Import from v1 JSON files. |
Memory Types
fact · preference · decision · pattern · snippet · bug · credential · todo · note · milestone · architecture · problem · transcript_chunk
Each memory has importance (1-5), optional TTL, tags, project scope, content hash, and auto-generated embedding + entity links.
CLI
MemoryPilot                          # Start MCP stdio server
MemoryPilot --backfill               # Compute missing embeddings
MemoryPilot --backfill-force         # Re-embed all (skips unchanged via hash)
MemoryPilot --benchmark-recall       # Run recall quality benchmark
MemoryPilot --benchmark-search       # Search quality: R@5, R@10, NDCG@10, cluster coherence
MemoryPilot --benchmark-fr           # French/multilingual deterministic benchmark (109 queries, ±1pp variance)
MemoryPilot --benchmark-longmemeval  # LongMemEval-S benchmark, supports --limit N and --min-r5 PCT
MemoryPilot --benchmark-concurrency  # Multi-client concurrency bench (--clients N --queries-per-client N)
MemoryPilot --benchmark-latency      # open_at startup + search latency
MemoryPilot --http 7437              # Start HTTP REST server (requires --features http)
MemoryPilot --migrate                # Import v1 JSON data
MemoryPilot --version                # Show version
MemoryPilot --help                   # Show help
Tuning environment variables
| Variable | Default | Effect |
|---|---|---|
MEMORYPILOT_CROSS_RERANK | adaptive | 1/always to force rerank on every query, 0/off to disable. Adaptive rerank fires on hard / non-English queries. |
MEMORYPILOT_CROSS_RERANK_TOP_K | 12 | Number of candidates the cross-encoder rescores. |
MEMORYPILOT_CROSS_RERANK_WEIGHT | 0.45 | Fusion weight given to the cross-encoder score against the RRF score. Sweep tested 0.20-0.85; 0.45 is the best operating point on --benchmark-fr and stays within 0.2 pp R@5 of the optimum on LongMemEval. |
MEMORYPILOT_RERANK_POOL_SIZE | 1 | Number of cross-encoder ONNX sessions kept hot. 2 helps only under heavy concurrent load; each extra mmarco session costs ~120 MB. |
MEMORYPILOT_EMBED_POOL_SIZE | 1 | Number of embedding ONNX sessions in the pool (legacy fastembed models keep 4, or 2 for 1024-dim). A second jina session adds ~250 MB and only pays off under heavy concurrent writes. |
MEMORYPILOT_EMBED_THREADS | min(4, cores) | ONNX intra-op threads for the embedder. MEMORYPILOT_RERANK_THREADS (default min(2, cores)) does the same for the cross-encoder. |
MEMORYPILOT_RERANKER_MODEL | mmarco | mmarco-mMiniLMv2-L12-H384-v1 int8 (Apache-2.0, ~120 MB resident). Alternatives served the same way (int8, memory-mapped): jina-v2 (jina-reranker-v2-base-multilingual, 280 MB, CC-BY-NC) and gte-multilingual (gte-multilingual-reranker-base, 341 MB, Apache-2.0) — both measured lower on --benchmark-fr (MRR 63.5% / 62.1% vs 65.3% before the v4.5 fix) at 2× the latency, hence not the default. Legacy fp32 fastembed models: jina-v2-multilingual-fp32 (1.1 GB), bge-v2-m3, bge-base, jina-v1. |
MEMORYPILOT_MODEL_IDLE_SECS | 600 | Idle time after which the embedder and reranker sessions are dropped to free memory (~250 MB). 0 keeps them resident (benchmarks). |
MEMORYPILOT_CONSOLIDATE | on | Daily embedding-based consolidation of near-duplicate ephemeral memories (cosine ≥ 0.95 and word overlap ≥ 0.6, same project, newest kept), followed by the supersede pass (see v4.6). off disables it; consolidate_memories runs it on demand. |
MEMORYPILOT_MMR / MEMORYPILOT_MMR_LAMBDA | on / 0.4 | MMR diversity over the finalists. 0 disables; λ = 1.0 is pure relevance, 0.0 pure diversity. MEMORYPILOT_MMR_FLOOR (0.55) is the cosine below which two candidates are not considered redundant. |
MEMORYPILOT_TEMPORAL | on | Query-time date window boost/demotion. 0 disables (date entities are still extracted at ingest). |
MEMORYPILOT_ABSTAIN_COSINE / MEMORYPILOT_TRUST_CROSS | 0.35 / 1.0 | Below the cosine floor a search reports confidence.abstain = true unless the cross-encoder logit on the top hit reaches the trust value. |
MEMORYPILOT_READER_NULL_MARGIN | 0 | Extractive reader: the span logit must beat the model's no-answer logit by this much. Negative values answer more often (−3 → 92/100 answered, 3/7 abstentions still caught on LongMemEval-S@100). |
MEMORYPILOT_EMBED_MODEL | jina | jina-embeddings-v5-text-nano-retrieval int8 (768-dim). jina-q4 = 4-bit variant (140 MB download, ~5× faster queries, −1 pp R@5 / −3 pp MRR on FR). Apache-2.0 alternatives via fastembed: e5-small (384-dim), e5-base, e5-large, bge-m3 (1024-dim). The database records which model produced its vectors; changing the model drops them and re-embeds everything in the background at next start (BM25 keeps answering meanwhile). |
HTTP API
When built with --features http, MemoryPilot exposes a multi-threaded REST API (4 worker threads, each with its own DB connection):
# Health check
curl http://localhost:7437/health

# Call any MCP tool
curl -X POST http://localhost:7437/tools/call \
  -H 'Content-Type: application/json' \
  -d '{"name": "search_memory", "arguments": {"query": "auth setup", "limit": 5}}'
Architecture
src/main.rs        — CLI + MCP stdio server + file watcher init + HTTP server init + benchmark runners
src/code_chunker.rs — Tree-sitter code-aware chunking for Rust/Python/TS/TSX/JS/Go/Java/Kotlin/Swift + Svelte scripts
src/db.rs          — SQLite facade: hybrid search, CRUD, KG, GC, brain, recall, lazy embed, connection pool, ANN warm-up
src/db/benchmark.rs — Internal recall/search quality benchmark helpers
src/db/benchmark_fr.rs — French/multilingual deterministic benchmark (109 queries, ±1pp variance)
src/db/benchmark_longmemeval.rs — LongMemEval-S benchmark runner + regression guard support
src/db/transcript.rs — Transcript/session ingestion and local-only distillation
src/tools.rs       — 41 MCP tool definitions + handlers
src/protocol.rs    — JSON-RPC types
src/embedding.rs   — jina-embeddings-v5 via ONNX Runtime (fastembed for legacy models), EmbedPool, two-tier query cache
src/tokenizer.rs   — lean byte-level BPE (tiktoken ranks) and Unigram tokenizers, ~65 MB instead of ~535 MB with the `tokenizers` crate
src/onnx_external.rs — one-shot rewrite of embedded ONNX weights into a memory-mapped sidecar (ORT 1.28 keeps 3 copies otherwise)
src/pool.rs        — lazily-built, idle-evicting pool shared by the embedder and reranker sessions
src/db/consolidate.rs — embedding-based near-duplicate consolidation (daily + `consolidate_memories`)
src/reranking.rs   — Cross-encoder rerank (jina-v2-multilingual), RerankPool, adaptive trigger, confidence gate
src/ann.rs         — Persistent on-disk HNSW (usearch) with synchronous warm-up via `wait_for_ann_warm`
src/fts.rs         — FTS5 query variants (prefix, phrase, NEAR) + Snowball stemming
src/graph.rs       — Entity extraction (tech, files, components, people) + relation inference + graph traversal
src/gc.rs          — GC scoring, heuristic memory merging, stopwords
src/working_memory.rs — In-process scoped scratchpad memory for current MCP sessions
src/watcher.rs     — File system watcher + auto-linter with persistent DB connection
src/http.rs        — Optional multi-threaded HTTP REST server (feature-gated)
Database Schema
memories           — id, content, kind, project, tags, importance, embedding (BLOB),
                     content_hash, expires_at, last_accessed_at, access_count, metadata
memories_fts       — FTS5 virtual table (content, tags, kind, project)
memory_entities    — memory_id, entity_kind, entity_value, valid_from, valid_to
memory_links       — source_id, target_id, relation_type, valid_from, valid_to, confidence
knowledge_triples  — id, subject, predicate, object, valid_from, valid_to, confidence, source_memory_id
projects           — name, path, description
config             — key/value store
Performance
| Metric | Value |
|---|---|
| Binary size | 35 MB |
Startup (open_at) | 1-2 ms (ANN warm-up runs in background) |
Startup (open_at_warm) | 50-200 ms on 10 k memories (ANN hydrated synchronously, deterministic search from query #1) |
| Search default fast (BM25 + RRF) | ~28 ms avg on LongMemEval-S |
| Search adaptive cross-encoder | ~210 ms avg on --benchmark-fr (R@5 99.1%, MRR 97.4%; v4.4 was 230 ms / R@5 70.6% / MRR 65%, v4.3 415 ms / R@5 60% / MRR 57%) |
| Concurrency p95 (4 clients × 20 queries, 500 memories, adaptive) | 229 ms |
add_memory latency | <1 ms (lazy embed) |
| Embedding quality | Transformer 768-dim (jina-embeddings-v5-text-nano-retrieval int8, 100+ languages, 8k context) |
| Backfill (1000 memories) | ~2 min in the background (model swap re-embed; recall stays interactive, ~1 s, while it runs) |
| RAM (both models loaded, steady state) | ~370 MB on a fresh database, ~485 MB with 2 000 memories in the ANN index — almost all of it memory-mapped int8 weights (247 MB jina + 118 MB mmarco) the OS can reclaim under pressure (was ~3.5 GB idle / ~7 GB peak in v4.3) |
| RAM (idle) | ~130 MB: both ONNX sessions are released after MEMORYPILOT_MODEL_IDLE_SECS (default 600 s) without a query and rebuilt on the next one (~0.8 s once, ~0.3 s for the reranker alone) |
RAM (--benchmark-fr, peak) | 364 MB (was 7.05 GB) |
| Read concurrency | 16 pooled connections per Database handle |
| Runtime dependencies | None (ONNX bundled) |
Optimizations
- Lazy embedding:
add_memoryinserts withNULLembedding, background thread computes and updates asynchronously - Content hashing (FNV-1a):
--backfill-forceskips memories whose content hasn't changed - Two-tier embedding cache: 256-entry in-process LRU on top of a write-through SQLite query cache (
*.query_cache.sqlite, soft-capped at 8 192 entries with LRU eviction) so repeated queries are instant within a session and across restarts - Read connection pool (4 connections): concurrent vector searches don't block writes
- WAL mode: SQLite Write-Ahead Logging for concurrent read/write
- Batched scoring: knowledge triple counts and link boosts fetched in single queries, not N+1
- Debounced cleanup: expired memory cleanup runs max once per 60 seconds
- Prepared statements: graph traversal prepares SQL once, not per node
- Tuned RRF fusion: k=40 for sharper top-K discrimination vs standard k=60
- FTS5 precision fallbacks: prefix, exact phrase, and NEAR proximity queries run together for code symbols, errors, and named concepts
- Weighted FTS fields: content, tags, kind, and project use separate BM25 weights to make structured metadata count
- ACT-R-style activation: frequently reused and recently accessed memories get a small cognitive activation boost before final reranking
- int8 quantized embeddings: stored vectors are 4× smaller (388 bytes vs 1536 bytes) with negligible recall loss; fast SIMD-friendly dot product directly on the blob avoids per-search allocations
- Local HNSW ANN index (
usearch): persistent on-disk approximate nearest neighbor index that warms asynchronously from SQLite in a detached thread (non-blocking startup), updates incrementally on backfill, on the async embed worker, and on delete. Surfacesvector_anncandidates so large memory bases stay fast as they grow past tens of thousands of entries. - ANN scan bypass: when the index reaches 5,000+ entries, the SQL vector scan is restricted to the union of ANN top-K and BM25 hits — turning an O(N) blob load into an O(K) lookup without changing the ranking logic.
- Code-aware chunking: tree-sitter splits Rust/Python/TypeScript/TSX/JavaScript on semantic units, with Svelte
<script>extraction - Exact term coverage boost: +10% when 80%+ of query terms appear in memory content
- Combinatorial reranker: greedy subgraph selection, conservative +5% per connection (cap 15%)
- KG query expansion: post-retrieval scoring boost from knowledge graph related terms (+4% per entity, cap 15%)
- Temporal recency: gentle +5% for memories from last 3 days, decaying over 30 days
- Importance tiebreaker: ±3% per level — never overrides relevance signal
- Adaptive cross-encoder reranking (jina-v2-multilingual via FastEmbed ONNX, default ON): triggers on hard / non-English queries, fuses with the RRF score at a tunable 0.45 weight, drops cleanly to BM25+RRF on easy English queries to stay under 30 ms. Pool of N sessions (
MEMORYPILOT_RERANK_POOL_SIZE) absorbs concurrent load. - Confidence gate: skips rerank when the top-1 RRF score is already ≥ 25 % above top-3 (latent path; active when force-rerank is enabled)
- Auto-compaction: GC triggers automatically when memory count > 500, debounced to once per 5 minutes
- Memory capsules: old low-importance memories compressed into ~100-200 token summaries (5-10x savings)
- Zero-shot auto-classification: pattern-based heuristics assign kind, importance, and TTL on insert without LLM
Fast Local Development
Use cargo check for day-to-day validation; it catches type and borrow errors without paying the full linking cost.
make check          # cargo check
make check-http     # cargo check --features http
make test           # cargo test
make timings        # cargo build --timings
make check-cached   # RUSTC_WRAPPER=sccache cargo check
sccache is optional but recommended for frequent rebuilds:
make sccache-install
make build-cached
Cargo aliases are also available: cargo dev, cargo check-http, cargo test-fast, cargo timings, and cargo build-http.
Keep cargo build --release --features http for release validation and benchmark runs. Linker swaps such as mold or lld are intentionally not enabled by default on macOS; measure with cargo build --timings first before changing .cargo/config.toml.
Run Benchmarks Yourself
MemoryPilot --benchmark-search --scenario-limit 30    # R@5, R@10, NDCG@10, cluster coherence, latency
MemoryPilot --benchmark-recall --scenario-limit 12    # top1/top5 hit rate, cross-project leak, credential safety
MemoryPilot --benchmark-longmemeval [PATH] [--limit N] [--min-r5 PCT] # LongMemEval-S with regression guard
The LongMemEval benchmark downloads the LongMemEval-S dataset and evaluates retrieval quality across 470 questions with turn-level granularity. Results are output as JSON with per-category breakdowns.
The cross-encoder runs in adaptive mode by default (triggers on hard / non-English queries). Force or disable it explicitly:
MEMORYPILOT_CROSS_RERANK=off MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json     # baseline, ~28ms/query, 98.7% R@5
MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json                                 # adaptive (default), ~900ms/query, 99.1% R@5
MEMORYPILOT_CROSS_RERANK=1 MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json      # force on every query, max latency
MEMORYPILOT_CROSS_RERANK_WEIGHT=0.70 MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json  # bias more toward the cross-encoder score
MEMORYPILOT_RERANKER_MODEL=bge-v2-m3 MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json  # swap the model
Supported model shortcuts: jina-v2-multilingual (default), bge-v2-m3, bge-base, and jina-v1. Validated full-run results on the 470 evaluable LongMemEval-S questions: default fast mode reaches 98.7% R@5, 95.1% NDCG@10, 93.6% MRR, ~28 ms average search latency; adaptive mode reaches 99.1% R@5, 96.0% NDCG@10, 94.9% MRR, ~900 ms average search latency. The deterministic French benchmark (--benchmark-fr) is the canonical regression test for any multilingual change — variance is bounded to ±1 pp R@5 across runs.
Storage
- Database:
~/.MemoryPilot/memory.db - Global prompt:
~/.MemoryPilot/GLOBAL_PROMPT.md - Model cache:
~/.cache/fastembed/(Hugging Face layout, downloaded on first run;FASTEMBED_CACHE_PATHoverrides). Externalized ONNX weights live inmemorypilot-external/inside it.
License
Soflution Source Available License — free to use, not to fork or modify. See LICENSE for details.
Built by SOFLUTION LTD
Similar repos
Contributors
75 commits
Languages
Rust
97.2%
Python
1.3%
Shell
1.1%