
A comprehensive collection of papers and datasets on generative models and their applications in style transfer across image, text, 3D, and video domains.
47
81 commits
updated Aug 11, 2026
README




🎨 About This Repository
A curated collection of style transfer research papers spanning 🖼️ 2D image, 🎬 video, 🧊 3D (NeRF / mesh / point cloud / 3DGS) and ⏳ 4D (dynamic scene) stylization — from classic neural style transfer to the latest diffusion- and foundation-model-era methods — organized by the Style-Carrier Taxonomy from our survey Style Transfer: A Decade Survey (revised version coming soon).
Domain tags: 🖼️ Image — single-image stylization · 🎬 Video — temporally consistent stylization · 🧊 3D — stylization of neural / explicit 3D representations · ⏳ 4D — stylization of dynamic, time-varying 3D scenes · 🌐 Multiple — methods covering more than one domain
Instead of grouping papers by year, backbone (CNN / GAN / Diffusion / DiT), or output domain, we ask a single question:
In what form is style-specific information materialized, and how is it reused for new content?
Every method has exactly one canonical home — five style carriers spanning 2015–2026 across 🖼️ image, 🎬 video, 🧊 3D and ⏳ 4D stylization.
🖼️ Style Transfer Examples
| Content Image | Style Image | Transferred Result |
|---|---|---|
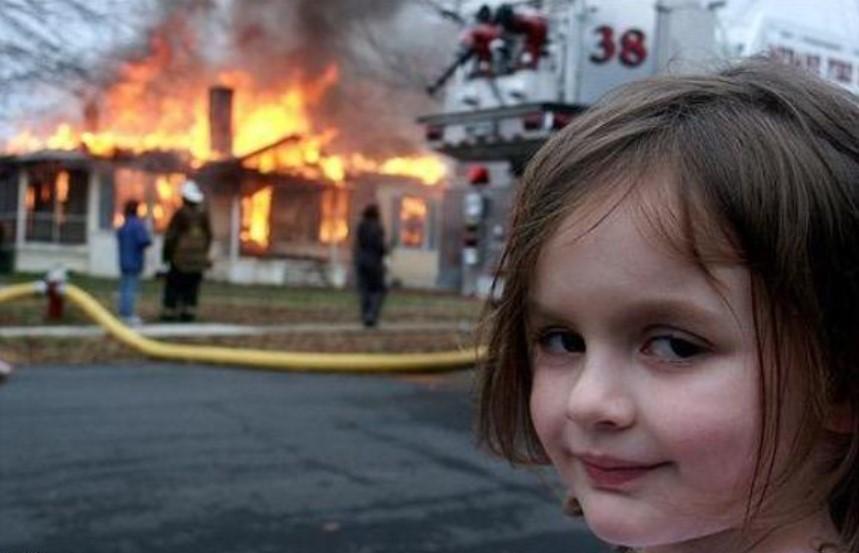 | 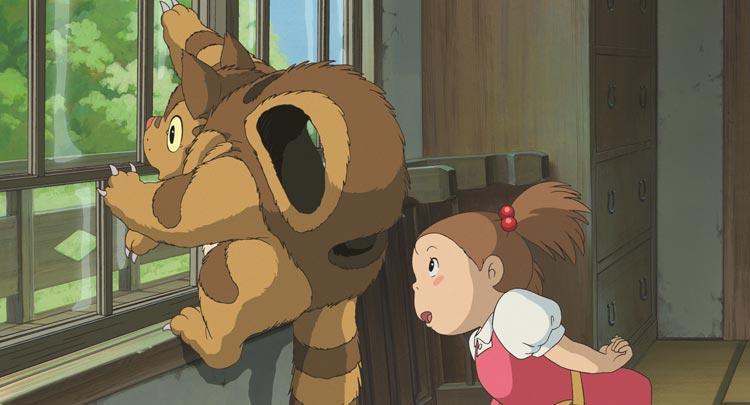 | 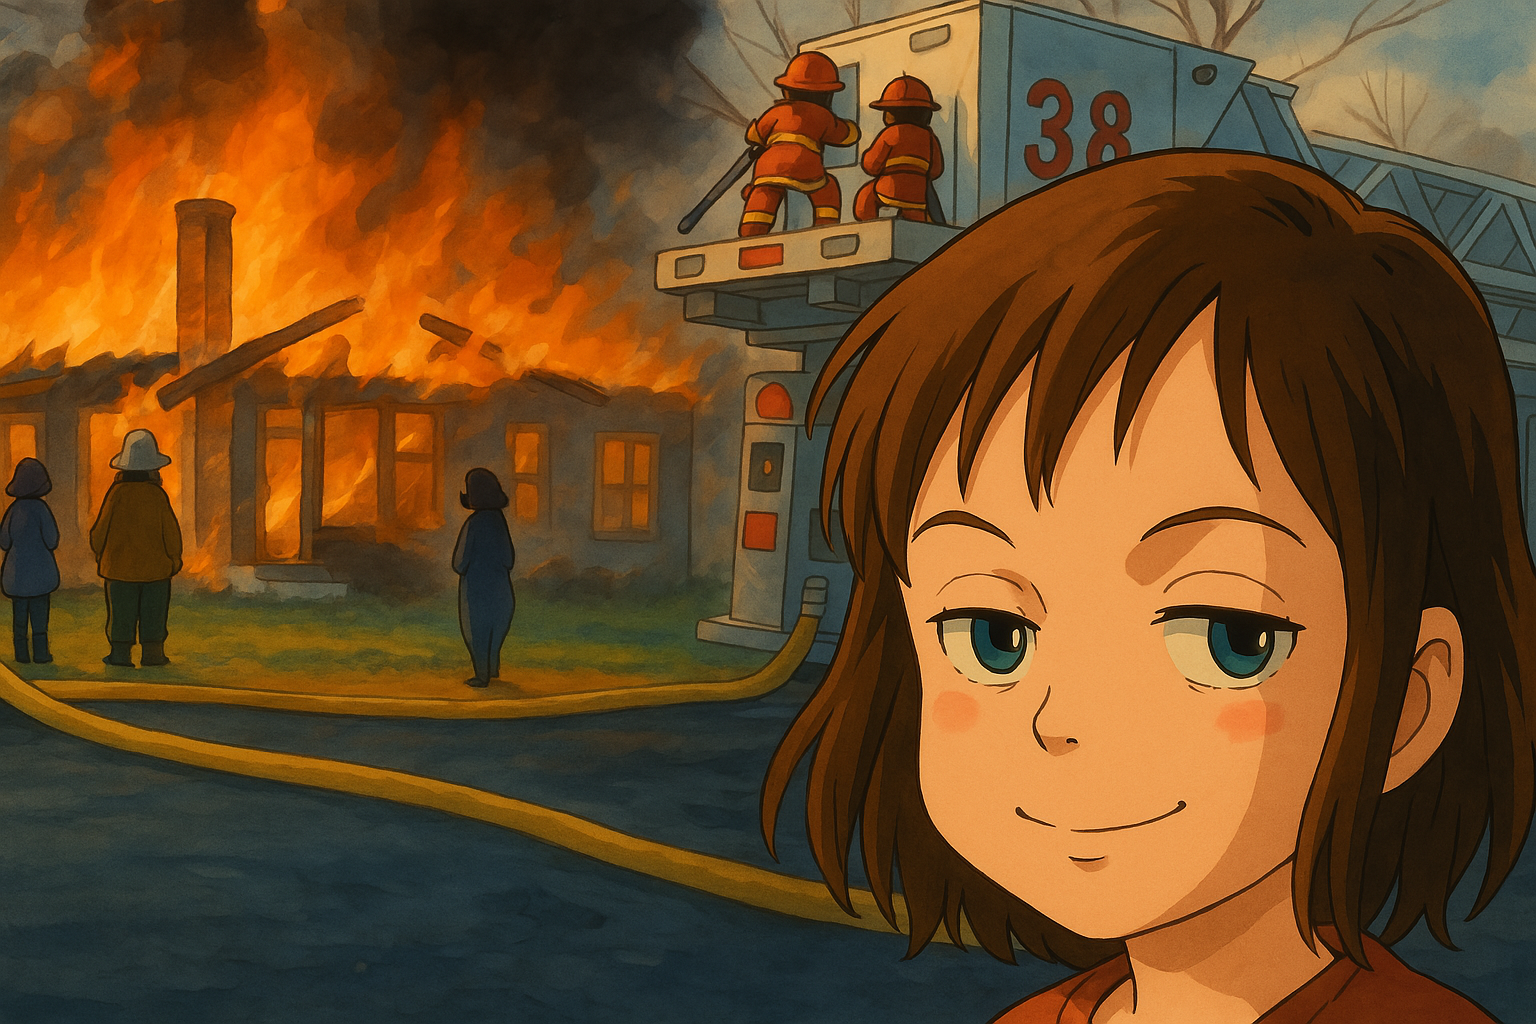 |
| Disaster Girl | となりのトトロ | Transferred Result |
🧭 The Style-Carrier Taxonomy
| Carrier | Core idea | Anchors | Papers |
|---|---|---|---|
| 🎯 Style as Optimization Objective | Style exists only as a loss, score, or guidance signal — no transferable style representation is ever materialized. | Gatys et al. 2015 | 20 |
| 🧩 Style as Feature Operator | Style acts through direct matching, replacement, transport, or attention coupling of content/style activations. | AdaIN · WCT | 27 |
| 🌀 Style as Latent Variable | Style is a native generative latent with its own prior — sampleable, mixable, and editable without any reference. | MUNIT · StyleGAN | 11 |
| ⚙️ Style as Model Parameters | Style is materialized as a persistent parameter asset (weights, LoRA, learned tokens) reusable across new content. | Johnson 2016 · LoRA | 25 |
| 🔌 Style as Learned Condition | An external reference is encoded into a standalone style condition consumed via a dedicated conditioning interface. | Ghiasi 2017 · IP-Adapter | 27 |
📌 What the taxonomy is not based on: year, backbone family, output domain, or auxiliary mechanisms (ControlNet, SDS, DDIM inversion …) — those are tags, not categories. The same perceptual objective underlies Gatys (🎯 objective), Johnson (⚙️ parameter) and Ghiasi (🔌 condition); AdaIN, StyTr² and StyleAligned are all 🧩 feature operators despite spanning CNN, Transformer and Diffusion eras.
📊 Coverage at a Glance
| Carrier | 🖼️ Image | 🎬 Video | 🧊 3D | ⏳ 4D |
|---|---|---|---|---|
| 🎯 Optimization Objective | 6 | — | 12 | 1 |
| 🧩 Feature Operator | 22 | 2 | 1 | — |
| 🌀 Latent Variable | 9 | 2 | — | — |
| ⚙️ Model Parameters | 18 | 6 | 1 | — |
| 🔌 Learned Condition | 21 | 2 | 3 | — |
Empty cells are open problems, not omissions — e.g. ⏳ 4D stylization remains nearly untouched.
📑 Table of Contents
- 🎯 Style as Optimization Objective — 20 papers
- 🧩 Style as Feature Operator — 27 papers
- 🌀 Style as Latent Variable — 11 papers
- ⚙️ Style as Model Parameters — 25 papers
- 🔌 Style as Learned Condition — 27 papers
- 📚 Datasets
- 🤝 Contributing
🗂️ Papers by Style Carrier
1. 🎯 Style as Optimization Objective
Style exists only as a loss, score, or guidance signal — no transferable style representation is ever materialized.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| A neural algorithm of artistic style | arXiv | 2015 | 🖼️ | paper |
| Deep photo style transfer | CVPR | 2017 | 🖼️ | paper |
| Style transfer by relaxed optimal transport and self-similarity | CVPR | 2019 | 🖼️ | paper |
| Arf: Artistic radiance fields | ECCV | 2022 | 🧊 | paper |
| CLIPstyler: Image style transfer with a single text condition | CVPR | 2022 | 🖼️ | paper |
| SNeRF: Stylized neural implicit representations for 3D scenes | SIGGRAPH Asia | 2022 | 🧊 | paper |
| StyleMesh: Style transfer for indoor 3D scene reconstructions | CVPR | 2022 | 🧊 | paper |
| Diffusion-based image translation using disentangled style and content representation | ICLR | 2023 | 🖼️ | paper |
| Ref-NPR: Reference-Based Non-Photorealistic Radiance Fields for Controllable Scene Stylization | CVPR | 2023 | 🧊 | paper |
| 3D Paintbrush: Local Stylization of 3D Shapes with Cascaded Score Distillation | CVPR | 2024 | 🧊 | paper |
| NeRF-Art: Text-Driven Neural Radiance Fields Stylization | IEEE TVCG | 2024 | 🧊 | paper |
| Balanced image stylization with style matching score | ICCV | 2025 | 🖼️ | paper |
| CLIPGaussian: Universal and Multimodal Style Transfer Based on Gaussian Splatting | NeurIPS | 2025 | 🌐 | paper |
| GAS-NeRF: Geometry-Aware Stylization of Dynamic Radiance Fields | arXiv | 2025 | ⏳ | paper |
| GT²-GS: Geometry-aware Texture Transfer for Gaussian Splatting | arXiv | 2025 | 🧊 | paper |
| Morpheus: Text-Driven 3D Gaussian Splat Shape and Color Stylization | CVPR | 2025 | 🧊 | paper |
| SGSST: Scaling Gaussian Splatting Style Transfer | CVPR | 2025 | 🧊 | paper |
| Stylizedgs: Controllable stylization for 3d gaussian splatting | TPAMI | 2025 | 🧊 | paper |
| DiffStyle3D: Consistent 3D Gaussian Stylization via Attention Optimization | arXiv | 2026 | 🧊 | paper |
| Fantasystyle: Controllable stylized distillation for 3d gaussian splatting | AAAI | 2026 | 🧊 | paper |
2. 🧩 Style as Feature Operator
Style acts through direct matching, replacement, transport, or attention coupling of content/style activations.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| Arbitrary style transfer in real-time with adaptive instance normalization | ICCV | 2017 | 🖼️ | paper |
| Universal style transfer via feature transforms | NeurIPS | 2017 | 🖼️ | paper |
| A closed-form solution to photorealistic image stylization | ECCV | 2018 | 🖼️ | paper |
| Avatar-net: Multi-scale zero-shot style transfer by feature decoration | CVPR | 2018 | 🖼️ | paper |
| Arbitrary Style Transfer with Style-Attentional Networks | CVPR | 2019 | 🖼️ | paper |
| Learning linear transformations for fast image and video style transfer | CVPR | 2019 | 🌐 | paper |
| Photorealistic style transfer via wavelet transforms | ICCV | 2019 | 🖼️ | paper |
| AdaAttN: Revisit attention mechanism in arbitrary neural style transfer | ICCV | 2021 | 🖼️ | paper |
| Arbitrary video style transfer via multi-channel correlation | ICCV | 2021 | 🎬 | paper |
| Artflow: Unbiased image style transfer via reversible neural flows | CVPR | 2021 | 🖼️ | paper |
| CCPL: Contrastive coherence preserving loss for versatile style transfer | ECCV | 2022 | 🌐 | paper |
| Domain enhanced arbitrary image style transfer via contrastive learning | SIGGRAPH | 2022 | 🖼️ | paper |
| Exact feature distribution matching for arbitrary style transfer and domain generalization | CVPR | 2022 | 🖼️ | paper |
| Stytr2: Image style transfer with transformers | CVPR | 2022 | 🖼️ | paper |
| CAP-VSTNet: Content affinity preserved versatile style transfer | CVPR | 2023 | 🖼️ | paper |
| Ctrl-x: Controlling structure and appearance for text-to-image generation without guidance | NeurIPS | 2024 | 🖼️ | paper |
| Puff-Net: Efficient Style Transfer with Pure Content and Style Feature Fusion Network | CVPR | 2024 | 🖼️ | paper |
| Style aligned image generation via shared attention | CVPR | 2024 | 🖼️ | paper |
| Style injection in diffusion: A training-free approach for adapting large-scale diffusion models for style transfer | CVPR | 2024 | 🖼️ | paper |
| Training-free consistent text-to-image generation | ACM TOG | 2024 | 🖼️ | paper |
| AttenST: A Training-Free Attention-Driven Style Transfer Framework with Pre-Trained Diffusion Models | arXiv | 2025 | 🖼️ | paper |
| DVI: Disentangling Semantic and Visual Identity for Training-Free Personalized Generation | arXiv | 2025 | 🖼️ | paper |
| FPGS: Feed-Forward Semantic-aware Photorealistic Style Transfer of Large-Scale Gaussian Splatting | Int. J. Comput. Vis. 2026 | 2025 | 🧊 | paper |
| SCSA: A Plug-and-Play Semantic Continuous-Sparse Attention for Arbitrary Semantic Style Transfer | CVPR | 2025 | 🖼️ | paper |
| SOYO: A Tuning-Free Approach for Video Style Morphing via Style-Adaptive Interpolation in Diffusion Models | arXiv | 2025 | 🎬 | paper |
| StyleSSP: Sampling StartPoint Enhancement for Training-free Diffusion-based Method for Style Transfer | CVPR | 2025 | 🖼️ | paper |
| StyleStudio: Text-Driven Style Transfer with Selective Control of Style Elements | CVPR | 2025 | 🖼️ | paper |
3. 🌀 Style as Latent Variable
Style is a native generative latent with its own prior — sampleable, mixable, and editable without any reference.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| Diverse image-to-image translation via disentangled representations | ECCV | 2018 | 🖼️ | paper |
| MoCoGAN: Decomposing motion and content for video generation | CVPR | 2018 | 🎬 | paper |
| Multimodal unsupervised image-to-image translation | ECCV | 2018 | 🖼️ | paper |
| Multimodal Unsupervised Image-to-image Translation | ECCV | 2018 | 🖼️ | paper |
| A style-based generator architecture for generative adversarial networks | CVPR | 2019 | 🖼️ | paper |
| Analyzing and Improving the Image Quality of StyleGAN | CVPR | 2020 | 🖼️ | paper |
| Analyzing and Improving the Image Quality of StyleGAN | CVPR | 2020 | 🖼️ | paper |
| Alias-Free Generative Adversarial Networks | NeurIPS | 2021 | 🖼️ | paper |
| Styleclip: Text-driven manipulation of stylegan imagery | ICCV | 2021 | 🖼️ | paper |
| Diffusion autoencoders: Toward a meaningful and decodable representation | CVPR | 2022 | 🖼️ | paper |
| Styleinv: A temporal style modulated inversion network for unconditional video generation | ICCV | 2023 | 🎬 | paper |
4. ⚙️ Style as Model Parameters
Style is materialized as a persistent parameter asset (weights, LoRA, learned tokens) reusable across new content.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| Perceptual losses for real-time style transfer and super-resolution | ECCV | 2016 | 🖼️ | paper |
| Texture networks: Feed-forward synthesis of textures and stylized images | ICML | 2016 | 🖼️ | paper |
| A Learned Representation for Artistic Style | ICLR | 2017 | 🖼️ | paper |
| Coherent online video style transfer | ICCV | 2017 | 🎬 | paper |
| Real-time neural style transfer for videos | CVPR | 2017 | 🎬 | paper |
| ReCoNet: Real-time coherent video style transfer network | ECCV | 2018 | 🎬 | paper |
| VToonify: Controllable High-Resolution Portrait Video Style Transfer | ACM TOG | 2022 | 🎬 | paper |
| An image is worth one word: Personalizing text-to-image generation using textual inversion | ICLR | 2023 | 🖼️ | paper |
| Break-a-scene: Extracting multiple concepts from a single image | SIGGRAPH Asia | 2023 | 🖼️ | paper |
| Cones: Concept neurons in diffusion models for customized generation | ICML | 2023 | 🖼️ | paper |
| DreamBooth3D: Subject-Driven Text-to-3D Generation | ICCV | 2023 | 🧊 | paper |
| Dreambooth: Fine tuning text-to-image diffusion models for subject-driven generation | CVPR | 2023 | 🖼️ | paper |
| Inversion-Based Style Transfer With Diffusion Models | CVPR | 2023 | 🖼️ | paper |
| Key-locked rank one editing for text-to-image personalization | SIGGRAPH | 2023 | 🖼️ | paper |
| Mix-of-show: Decentralized low-rank adaptation for multi-concept customization of diffusion models | NeurIPS | 2023 | 🖼️ | paper |
| Multi-concept customization of text-to-image diffusion | CVPR | 2023 | 🖼️ | paper |
| Prospect: Prompt spectrum for attribute-aware personalization of diffusion models | ACM TOG | 2023 | 🖼️ | paper |
| Styledrop: Text-to-image generation in any style | arXiv | 2023 | 🖼️ | paper |
| Dreamvideo: Composing your dream videos with customized subject and motion | CVPR | 2024 | 🎬 | paper |
| Implicit style-content separation using b-lora | ECCV | 2024 | 🖼️ | paper |
| Magic-me: Identity-specific video customized diffusion | ECCV | 2024 | 🎬 | paper |
| ZipLoRA: Any Subject in Any Style by Effectively Merging LoRAs | ECCV | 2024 | 🖼️ | paper |
| APT: Adaptive Personalized Training for Diffusion Models with Limited Data | CVPR | 2025 | 🖼️ | paper |
| ConsisLoRA: Enhancing Content and Style Consistency for LoRA-based Style Transfer | arXiv | 2025 | 🖼️ | paper |
| Photodoodle: Learning artistic image editing from few-shot pairwise data | arXiv | 2025 | 🖼️ | paper |
5. 🔌 Style as Learned Condition
An external reference is encoded into a standalone style condition consumed via a dedicated conditioning interface.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| CLIP-NeRF: Text-and-image driven manipulation of neural radiance fields | CVPR | 2022 | 🧊 | paper |
| Blip-diffusion: Pre-trained subject representation for controllable text-to-image generation and editing | NeurIPS | 2023 | 🖼️ | paper |
| Elite: Encoding visual concepts into textual embeddings for customized text-to-image generation | ICCV | 2023 | 🖼️ | paper |
| IP-Adapter: Text Compatible Image Prompt Adapter for Text-to-Image Diffusion Models | arXiv | 2023 | 🖼️ | paper |
| Arc2Face: A Foundation Model for ID-Consistent Human Faces | ECCV | 2024 | 🖼️ | paper |
| ArtAdapter: Text-to-Image Style Transfer using Multi-Level Style Encoder and Explicit Adaptation | CVPR | 2024 | 🖼️ | paper |
| Deadiff: An efficient stylization diffusion model with disentangled representations | CVPR | 2024 | 🖼️ | paper |
| DiffStyler: Diffusion-based Localized Image Style Transfer | arXiv | 2024 | 🖼️ | paper |
| Instantid: Zero-shot identity-preserving generation in seconds | arXiv | 2024 | 🖼️ | paper |
| InstantStyle-Plus: Style Transfer with Content-Preserving in Text-to-Image Generation | arXiv | 2024 | 🖼️ | paper |
| InstantStyle: Free Lunch towards Style-Preserving in Text-to-Image Generation | arXiv | 2024 | 🖼️ | paper |
| Photomaker: Customizing realistic human photos via stacked id embedding | CVPR | 2024 | 🖼️ | paper |
| Pulid: Pure and lightning id customization via contrastive alignment | NeurIPS | 2024 | 🖼️ | paper |
| Ssr-encoder: Encoding selective subject representation for subject-driven generation | CVPR | 2024 | 🖼️ | paper |
| StyleCrafter: Taming Artistic Video Diffusion with Reference-Augmented Adapter Learning | ACM TOG | 2024 | 🎬 | paper |
| CSGO: Content-Style Composition in Text-to-Image Generation | NeurIPS | 2025 | 🖼️ | paper |
| Free-lunch color-texture disentanglement for stylized image generation | NeurIPS | 2025 | 🖼️ | paper |
| ID-Consistent, Precise Expression Generation with Blendshape-Guided Diffusion | ICCV | 2025 | 🖼️ | paper |
| Nested attention: Semantic-aware attention values for concept personalization | SIGGRAPH | 2025 | 🖼️ | paper |
| Omni-Attribute: Open-vocabulary Attribute Encoder for Visual Concept Personalization | arXiv | 2025 | 🖼️ | paper |
| Stylemaster: Stylize your video with artistic generation and translation | CVPR | 2025 | 🎬 | paper |
| Styleshot: A snapshot on any style | TPAMI | 2025 | 🖼️ | paper |
| Stylos: Multi-View 3D Stylization with Single-Forward Gaussian Splatting | arXiv | 2025 | 🧊 | paper |
| U-StyDiT: Ultra-high quality artistic style transfer using diffusion transformers | arXiv preprint arXiv:2503.08157 | 2025 | 🖼️ | paper |
| Uso: Unified style and subject-driven generation via disentangled and reward learning | arXiv preprint arXiv:2508.18966 | 2025 | 🖼️ | paper |
| AnyStyle: Single-Pass Multimodal Stylization for 3D Gaussian Splatting | arXiv | 2026 | 🧊 | paper |
| TeleStyle: Content-Preserving Style Transfer in Images and Videos | arXiv preprint arXiv:2601.20175 | 2026 | 🌐 | paper |
📚 Datasets
🖼️ Image Datasets
| Dataset | Year | Size | Description | Link |
|---|---|---|---|---|
| WikiArt | 2018 | 42,129 images | Style, Artist, Genre | link |
| Stylized ImageNet | 2018 | ~134GB | Style Transfer | link |
| BAM | 2017 | 2.5M images | Artistic Media | link |
| ArtBench-10 | 2022 | 60,000 images | Artwork Benchmark | link |
| FFHQ | 2019 | 70,000 images | Human Faces | link |
| MetFaces | 2020 | 1,336 images | Artistic Faces | link |
| AAHQ | 2021 | 25,000 images | Artistic Faces | link |
| Ukiyo-e Faces | 2020 | 5,209 images | Aligned Ukiyo-e Faces | link |
| DiffusionDB | 2022 | 14M images | Text-to-image | link |
| JourneyDB | 2023 | 4.4M images | Multimodal Vision | link |
| StyleShot | 2024 | - | Style Transfer | link |
| Danbooru2017 | 2017 | 2.94M images | Anime | link |
| Chinese Style Transfer | 2018 | 1000 content, 100 style | Chinese Painting | link |
| 4SKST | 2023 | 25 color, 100 sketches | Sketch Style | link |
🎬 Video Datasets
🧊 3D / Motion Datasets
🤝 Contributing
We welcome contributions! When suggesting a paper, please indicate which style carrier it belongs to:
- 🎯 Objective — style lives only in the loss / score / guidance
- 🧩 Feature — direct activation matching, transport, or attention coupling
- 🌀 Latent — native generative latent, sampleable without a reference
- ⚙️ Parameter — persistent style asset (weights / LoRA / tokens)
- 🔌 Condition — reference-encoded standalone style condition
Ways to help:
- 🐛 Report bugs and issues
- 💡 Suggest new papers or resources
- 🔧 Submit pull requests
- ⭐ Star this repository if you find it helpful!
📖 Citation
If you find this repository useful for your research, please consider citing:
@article{zhang2025style,
  title={Style transfer: A decade survey},
  author={Zhang, Tianshan and Tang, Hao},
  journal={arXiv preprint arXiv:2506.19278},
  year={2025}
}
⭐ Star History
🙏 Acknowledgments
Thanks to all researchers and developers who made their work publicly available.
Contributors

79 commits

2 commits
Similar repos


A comprehensive collection of papers and datasets on generative models and their applications in style transfer across image, text, 3D, and video domains.
47
81 commits
updated Aug 11, 2026
README
🎨 About This Repository
A curated collection of style transfer research papers spanning 🖼️ 2D image, 🎬 video, 🧊 3D (NeRF / mesh / point cloud / 3DGS) and ⏳ 4D (dynamic scene) stylization — from classic neural style transfer to the latest diffusion- and foundation-model-era methods — organized by the Style-Carrier Taxonomy from our survey Style Transfer: A Decade Survey (revised version coming soon).
Domain tags: 🖼️ Image — single-image stylization · 🎬 Video — temporally consistent stylization · 🧊 3D — stylization of neural / explicit 3D representations · ⏳ 4D — stylization of dynamic, time-varying 3D scenes · 🌐 Multiple — methods covering more than one domain
Instead of grouping papers by year, backbone (CNN / GAN / Diffusion / DiT), or output domain, we ask a single question:
In what form is style-specific information materialized, and how is it reused for new content?
Every method has exactly one canonical home — five style carriers spanning 2015–2026 across 🖼️ image, 🎬 video, 🧊 3D and ⏳ 4D stylization.
🖼️ Style Transfer Examples
| Content Image | Style Image | Transferred Result |
|---|---|---|
| | |
| Disaster Girl | となりのトトロ | Transferred Result |
🧭 The Style-Carrier Taxonomy
| Carrier | Core idea | Anchors | Papers |
|---|---|---|---|
| 🎯 Style as Optimization Objective | Style exists only as a loss, score, or guidance signal — no transferable style representation is ever materialized. | Gatys et al. 2015 | 20 |
| 🧩 Style as Feature Operator | Style acts through direct matching, replacement, transport, or attention coupling of content/style activations. | AdaIN · WCT | 27 |
| 🌀 Style as Latent Variable | Style is a native generative latent with its own prior — sampleable, mixable, and editable without any reference. | MUNIT · StyleGAN | 11 |
| ⚙️ Style as Model Parameters | Style is materialized as a persistent parameter asset (weights, LoRA, learned tokens) reusable across new content. | Johnson 2016 · LoRA | 25 |
| 🔌 Style as Learned Condition | An external reference is encoded into a standalone style condition consumed via a dedicated conditioning interface. | Ghiasi 2017 · IP-Adapter | 27 |
📌 What the taxonomy is not based on: year, backbone family, output domain, or auxiliary mechanisms (ControlNet, SDS, DDIM inversion …) — those are tags, not categories. The same perceptual objective underlies Gatys (🎯 objective), Johnson (⚙️ parameter) and Ghiasi (🔌 condition); AdaIN, StyTr² and StyleAligned are all 🧩 feature operators despite spanning CNN, Transformer and Diffusion eras.
📊 Coverage at a Glance
| Carrier | 🖼️ Image | 🎬 Video | 🧊 3D | ⏳ 4D |
|---|---|---|---|---|
| 🎯 Optimization Objective | 6 | — | 12 | 1 |
| 🧩 Feature Operator | 22 | 2 | 1 | — |
| 🌀 Latent Variable | 9 | 2 | — | — |
| ⚙️ Model Parameters | 18 | 6 | 1 | — |
| 🔌 Learned Condition | 21 | 2 | 3 | — |
Empty cells are open problems, not omissions — e.g. ⏳ 4D stylization remains nearly untouched.
📑 Table of Contents
- 🎯 Style as Optimization Objective — 20 papers
- 🧩 Style as Feature Operator — 27 papers
- 🌀 Style as Latent Variable — 11 papers
- ⚙️ Style as Model Parameters — 25 papers
- 🔌 Style as Learned Condition — 27 papers
- 📚 Datasets
- 🤝 Contributing
🗂️ Papers by Style Carrier
1. 🎯 Style as Optimization Objective
Style exists only as a loss, score, or guidance signal — no transferable style representation is ever materialized.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| A neural algorithm of artistic style | arXiv | 2015 | 🖼️ | paper |
| Deep photo style transfer | CVPR | 2017 | 🖼️ | paper |
| Style transfer by relaxed optimal transport and self-similarity | CVPR | 2019 | 🖼️ | paper |
| Arf: Artistic radiance fields | ECCV | 2022 | 🧊 | paper |
| CLIPstyler: Image style transfer with a single text condition | CVPR | 2022 | 🖼️ | paper |
| SNeRF: Stylized neural implicit representations for 3D scenes | SIGGRAPH Asia | 2022 | 🧊 | paper |
| StyleMesh: Style transfer for indoor 3D scene reconstructions | CVPR | 2022 | 🧊 | paper |
| Diffusion-based image translation using disentangled style and content representation | ICLR | 2023 | 🖼️ | paper |
| Ref-NPR: Reference-Based Non-Photorealistic Radiance Fields for Controllable Scene Stylization | CVPR | 2023 | 🧊 | paper |
| 3D Paintbrush: Local Stylization of 3D Shapes with Cascaded Score Distillation | CVPR | 2024 | 🧊 | paper |
| NeRF-Art: Text-Driven Neural Radiance Fields Stylization | IEEE TVCG | 2024 | 🧊 | paper |
| Balanced image stylization with style matching score | ICCV | 2025 | 🖼️ | paper |
| CLIPGaussian: Universal and Multimodal Style Transfer Based on Gaussian Splatting | NeurIPS | 2025 | 🌐 | paper |
| GAS-NeRF: Geometry-Aware Stylization of Dynamic Radiance Fields | arXiv | 2025 | ⏳ | paper |
| GT²-GS: Geometry-aware Texture Transfer for Gaussian Splatting | arXiv | 2025 | 🧊 | paper |
| Morpheus: Text-Driven 3D Gaussian Splat Shape and Color Stylization | CVPR | 2025 | 🧊 | paper |
| SGSST: Scaling Gaussian Splatting Style Transfer | CVPR | 2025 | 🧊 | paper |
| Stylizedgs: Controllable stylization for 3d gaussian splatting | TPAMI | 2025 | 🧊 | paper |
| DiffStyle3D: Consistent 3D Gaussian Stylization via Attention Optimization | arXiv | 2026 | 🧊 | paper |
| Fantasystyle: Controllable stylized distillation for 3d gaussian splatting | AAAI | 2026 | 🧊 | paper |
2. 🧩 Style as Feature Operator
Style acts through direct matching, replacement, transport, or attention coupling of content/style activations.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| Arbitrary style transfer in real-time with adaptive instance normalization | ICCV | 2017 | 🖼️ | paper |
| Universal style transfer via feature transforms | NeurIPS | 2017 | 🖼️ | paper |
| A closed-form solution to photorealistic image stylization | ECCV | 2018 | 🖼️ | paper |
| Avatar-net: Multi-scale zero-shot style transfer by feature decoration | CVPR | 2018 | 🖼️ | paper |
| Arbitrary Style Transfer with Style-Attentional Networks | CVPR | 2019 | 🖼️ | paper |
| Learning linear transformations for fast image and video style transfer | CVPR | 2019 | 🌐 | paper |
| Photorealistic style transfer via wavelet transforms | ICCV | 2019 | 🖼️ | paper |
| AdaAttN: Revisit attention mechanism in arbitrary neural style transfer | ICCV | 2021 | 🖼️ | paper |
| Arbitrary video style transfer via multi-channel correlation | ICCV | 2021 | 🎬 | paper |
| Artflow: Unbiased image style transfer via reversible neural flows | CVPR | 2021 | 🖼️ | paper |
| CCPL: Contrastive coherence preserving loss for versatile style transfer | ECCV | 2022 | 🌐 | paper |
| Domain enhanced arbitrary image style transfer via contrastive learning | SIGGRAPH | 2022 | 🖼️ | paper |
| Exact feature distribution matching for arbitrary style transfer and domain generalization | CVPR | 2022 | 🖼️ | paper |
| Stytr2: Image style transfer with transformers | CVPR | 2022 | 🖼️ | paper |
| CAP-VSTNet: Content affinity preserved versatile style transfer | CVPR | 2023 | 🖼️ | paper |
| Ctrl-x: Controlling structure and appearance for text-to-image generation without guidance | NeurIPS | 2024 | 🖼️ | paper |
| Puff-Net: Efficient Style Transfer with Pure Content and Style Feature Fusion Network | CVPR | 2024 | 🖼️ | paper |
| Style aligned image generation via shared attention | CVPR | 2024 | 🖼️ | paper |
| Style injection in diffusion: A training-free approach for adapting large-scale diffusion models for style transfer | CVPR | 2024 | 🖼️ | paper |
| Training-free consistent text-to-image generation | ACM TOG | 2024 | 🖼️ | paper |
| AttenST: A Training-Free Attention-Driven Style Transfer Framework with Pre-Trained Diffusion Models | arXiv | 2025 | 🖼️ | paper |
| DVI: Disentangling Semantic and Visual Identity for Training-Free Personalized Generation | arXiv | 2025 | 🖼️ | paper |
| FPGS: Feed-Forward Semantic-aware Photorealistic Style Transfer of Large-Scale Gaussian Splatting | Int. J. Comput. Vis. 2026 | 2025 | 🧊 | paper |
| SCSA: A Plug-and-Play Semantic Continuous-Sparse Attention for Arbitrary Semantic Style Transfer | CVPR | 2025 | 🖼️ | paper |
| SOYO: A Tuning-Free Approach for Video Style Morphing via Style-Adaptive Interpolation in Diffusion Models | arXiv | 2025 | 🎬 | paper |
| StyleSSP: Sampling StartPoint Enhancement for Training-free Diffusion-based Method for Style Transfer | CVPR | 2025 | 🖼️ | paper |
| StyleStudio: Text-Driven Style Transfer with Selective Control of Style Elements | CVPR | 2025 | 🖼️ | paper |
3. 🌀 Style as Latent Variable
Style is a native generative latent with its own prior — sampleable, mixable, and editable without any reference.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| Diverse image-to-image translation via disentangled representations | ECCV | 2018 | 🖼️ | paper |
| MoCoGAN: Decomposing motion and content for video generation | CVPR | 2018 | 🎬 | paper |
| Multimodal unsupervised image-to-image translation | ECCV | 2018 | 🖼️ | paper |
| Multimodal Unsupervised Image-to-image Translation | ECCV | 2018 | 🖼️ | paper |
| A style-based generator architecture for generative adversarial networks | CVPR | 2019 | 🖼️ | paper |
| Analyzing and Improving the Image Quality of StyleGAN | CVPR | 2020 | 🖼️ | paper |
| Analyzing and Improving the Image Quality of StyleGAN | CVPR | 2020 | 🖼️ | paper |
| Alias-Free Generative Adversarial Networks | NeurIPS | 2021 | 🖼️ | paper |
| Styleclip: Text-driven manipulation of stylegan imagery | ICCV | 2021 | 🖼️ | paper |
| Diffusion autoencoders: Toward a meaningful and decodable representation | CVPR | 2022 | 🖼️ | paper |
| Styleinv: A temporal style modulated inversion network for unconditional video generation | ICCV | 2023 | 🎬 | paper |
4. ⚙️ Style as Model Parameters
Style is materialized as a persistent parameter asset (weights, LoRA, learned tokens) reusable across new content.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| Perceptual losses for real-time style transfer and super-resolution | ECCV | 2016 | 🖼️ | paper |
| Texture networks: Feed-forward synthesis of textures and stylized images | ICML | 2016 | 🖼️ | paper |
| A Learned Representation for Artistic Style | ICLR | 2017 | 🖼️ | paper |
| Coherent online video style transfer | ICCV | 2017 | 🎬 | paper |
| Real-time neural style transfer for videos | CVPR | 2017 | 🎬 | paper |
| ReCoNet: Real-time coherent video style transfer network | ECCV | 2018 | 🎬 | paper |
| VToonify: Controllable High-Resolution Portrait Video Style Transfer | ACM TOG | 2022 | 🎬 | paper |
| An image is worth one word: Personalizing text-to-image generation using textual inversion | ICLR | 2023 | 🖼️ | paper |
| Break-a-scene: Extracting multiple concepts from a single image | SIGGRAPH Asia | 2023 | 🖼️ | paper |
| Cones: Concept neurons in diffusion models for customized generation | ICML | 2023 | 🖼️ | paper |
| DreamBooth3D: Subject-Driven Text-to-3D Generation | ICCV | 2023 | 🧊 | paper |
| Dreambooth: Fine tuning text-to-image diffusion models for subject-driven generation | CVPR | 2023 | 🖼️ | paper |
| Inversion-Based Style Transfer With Diffusion Models | CVPR | 2023 | 🖼️ | paper |
| Key-locked rank one editing for text-to-image personalization | SIGGRAPH | 2023 | 🖼️ | paper |
| Mix-of-show: Decentralized low-rank adaptation for multi-concept customization of diffusion models | NeurIPS | 2023 | 🖼️ | paper |
| Multi-concept customization of text-to-image diffusion | CVPR | 2023 | 🖼️ | paper |
| Prospect: Prompt spectrum for attribute-aware personalization of diffusion models | ACM TOG | 2023 | 🖼️ | paper |
| Styledrop: Text-to-image generation in any style | arXiv | 2023 | 🖼️ | paper |
| Dreamvideo: Composing your dream videos with customized subject and motion | CVPR | 2024 | 🎬 | paper |
| Implicit style-content separation using b-lora | ECCV | 2024 | 🖼️ | paper |
| Magic-me: Identity-specific video customized diffusion | ECCV | 2024 | 🎬 | paper |
| ZipLoRA: Any Subject in Any Style by Effectively Merging LoRAs | ECCV | 2024 | 🖼️ | paper |
| APT: Adaptive Personalized Training for Diffusion Models with Limited Data | CVPR | 2025 | 🖼️ | paper |
| ConsisLoRA: Enhancing Content and Style Consistency for LoRA-based Style Transfer | arXiv | 2025 | 🖼️ | paper |
| Photodoodle: Learning artistic image editing from few-shot pairwise data | arXiv | 2025 | 🖼️ | paper |
5. 🔌 Style as Learned Condition
An external reference is encoded into a standalone style condition consumed via a dedicated conditioning interface.
| Paper | Venue | Year | Rep | Link |
|---|---|---|---|---|
| CLIP-NeRF: Text-and-image driven manipulation of neural radiance fields | CVPR | 2022 | 🧊 | paper |
| Blip-diffusion: Pre-trained subject representation for controllable text-to-image generation and editing | NeurIPS | 2023 | 🖼️ | paper |
| Elite: Encoding visual concepts into textual embeddings for customized text-to-image generation | ICCV | 2023 | 🖼️ | paper |
| IP-Adapter: Text Compatible Image Prompt Adapter for Text-to-Image Diffusion Models | arXiv | 2023 | 🖼️ | paper |
| Arc2Face: A Foundation Model for ID-Consistent Human Faces | ECCV | 2024 | 🖼️ | paper |
| ArtAdapter: Text-to-Image Style Transfer using Multi-Level Style Encoder and Explicit Adaptation | CVPR | 2024 | 🖼️ | paper |
| Deadiff: An efficient stylization diffusion model with disentangled representations | CVPR | 2024 | 🖼️ | paper |
| DiffStyler: Diffusion-based Localized Image Style Transfer | arXiv | 2024 | 🖼️ | paper |
| Instantid: Zero-shot identity-preserving generation in seconds | arXiv | 2024 | 🖼️ | paper |
| InstantStyle-Plus: Style Transfer with Content-Preserving in Text-to-Image Generation | arXiv | 2024 | 🖼️ | paper |
| InstantStyle: Free Lunch towards Style-Preserving in Text-to-Image Generation | arXiv | 2024 | 🖼️ | paper |
| Photomaker: Customizing realistic human photos via stacked id embedding | CVPR | 2024 | 🖼️ | paper |
| Pulid: Pure and lightning id customization via contrastive alignment | NeurIPS | 2024 | 🖼️ | paper |
| Ssr-encoder: Encoding selective subject representation for subject-driven generation | CVPR | 2024 | 🖼️ | paper |
| StyleCrafter: Taming Artistic Video Diffusion with Reference-Augmented Adapter Learning | ACM TOG | 2024 | 🎬 | paper |
| CSGO: Content-Style Composition in Text-to-Image Generation | NeurIPS | 2025 | 🖼️ | paper |
| Free-lunch color-texture disentanglement for stylized image generation | NeurIPS | 2025 | 🖼️ | paper |
| ID-Consistent, Precise Expression Generation with Blendshape-Guided Diffusion | ICCV | 2025 | 🖼️ | paper |
| Nested attention: Semantic-aware attention values for concept personalization | SIGGRAPH | 2025 | 🖼️ | paper |
| Omni-Attribute: Open-vocabulary Attribute Encoder for Visual Concept Personalization | arXiv | 2025 | 🖼️ | paper |
| Stylemaster: Stylize your video with artistic generation and translation | CVPR | 2025 | 🎬 | paper |
| Styleshot: A snapshot on any style | TPAMI | 2025 | 🖼️ | paper |
| Stylos: Multi-View 3D Stylization with Single-Forward Gaussian Splatting | arXiv | 2025 | 🧊 | paper |
| U-StyDiT: Ultra-high quality artistic style transfer using diffusion transformers | arXiv preprint arXiv:2503.08157 | 2025 | 🖼️ | paper |
| Uso: Unified style and subject-driven generation via disentangled and reward learning | arXiv preprint arXiv:2508.18966 | 2025 | 🖼️ | paper |
| AnyStyle: Single-Pass Multimodal Stylization for 3D Gaussian Splatting | arXiv | 2026 | 🧊 | paper |
| TeleStyle: Content-Preserving Style Transfer in Images and Videos | arXiv preprint arXiv:2601.20175 | 2026 | 🌐 | paper |
📚 Datasets
🖼️ Image Datasets
| Dataset | Year | Size | Description | Link |
|---|---|---|---|---|
| WikiArt | 2018 | 42,129 images | Style, Artist, Genre | link |
| Stylized ImageNet | 2018 | ~134GB | Style Transfer | link |
| BAM | 2017 | 2.5M images | Artistic Media | link |
| ArtBench-10 | 2022 | 60,000 images | Artwork Benchmark | link |
| FFHQ | 2019 | 70,000 images | Human Faces | link |
| MetFaces | 2020 | 1,336 images | Artistic Faces | link |
| AAHQ | 2021 | 25,000 images | Artistic Faces | link |
| Ukiyo-e Faces | 2020 | 5,209 images | Aligned Ukiyo-e Faces | link |
| DiffusionDB | 2022 | 14M images | Text-to-image | link |
| JourneyDB | 2023 | 4.4M images | Multimodal Vision | link |
| StyleShot | 2024 | - | Style Transfer | link |
| Danbooru2017 | 2017 | 2.94M images | Anime | link |
| Chinese Style Transfer | 2018 | 1000 content, 100 style | Chinese Painting | link |
| 4SKST | 2023 | 25 color, 100 sketches | Sketch Style | link |
🎬 Video Datasets
🧊 3D / Motion Datasets
🤝 Contributing
We welcome contributions! When suggesting a paper, please indicate which style carrier it belongs to:
- 🎯 Objective — style lives only in the loss / score / guidance
- 🧩 Feature — direct activation matching, transport, or attention coupling
- 🌀 Latent — native generative latent, sampleable without a reference
- ⚙️ Parameter — persistent style asset (weights / LoRA / tokens)
- 🔌 Condition — reference-encoded standalone style condition
Ways to help:
- 🐛 Report bugs and issues
- 💡 Suggest new papers or resources
- 🔧 Submit pull requests
- ⭐ Star this repository if you find it helpful!
📖 Citation
If you find this repository useful for your research, please consider citing:
@article{zhang2025style,
  title={Style transfer: A decade survey},
  author={Zhang, Tianshan and Tang, Hao},
  journal={arXiv preprint arXiv:2506.19278},
  year={2025}
}
⭐ Star History
🙏 Acknowledgments
Thanks to all researchers and developers who made their work publicly available.
Similar repos
Contributors
79 commits
2 commits