
Papers and codes collection for customized, personalized and editable generative models
28
59 commits
updated Oct 1, 2024
README
awesome-customized-generative-AI
Papers and codes collection for customize, personalized and editable generative models in 2D and 3D domains.

Introduction
Artificial Intelligence Generated Content (AIGC) has become ubiquitous, demonstrating the power of generating mesmerizing results of random portraits. However, users generally show greater interest in personalized information (for example, faces from familiar people or celebrities) in these generated results than in generic faces. This tendency toward customization in AIGC arouses attention to customized, personalized, and editable generative AI.
This repo mainly focuses on visual generative models (leaving out LLMs), including 2D image-to-image, 2D text-to-image, and text-guided 3D generation/manipulation, collecting customized, personalized, and editable works in these specific domains. For any addition about other 2D/3D AIGC domains or bugs report, please open an issue, pull requests, or e-mail me at normanzheng6606@gmail.com for better communication.
Frequantly updating, please stay tuned!
Table of Contents
Customized 2D Image-to-Image
Image-prompted Generation
2024
-
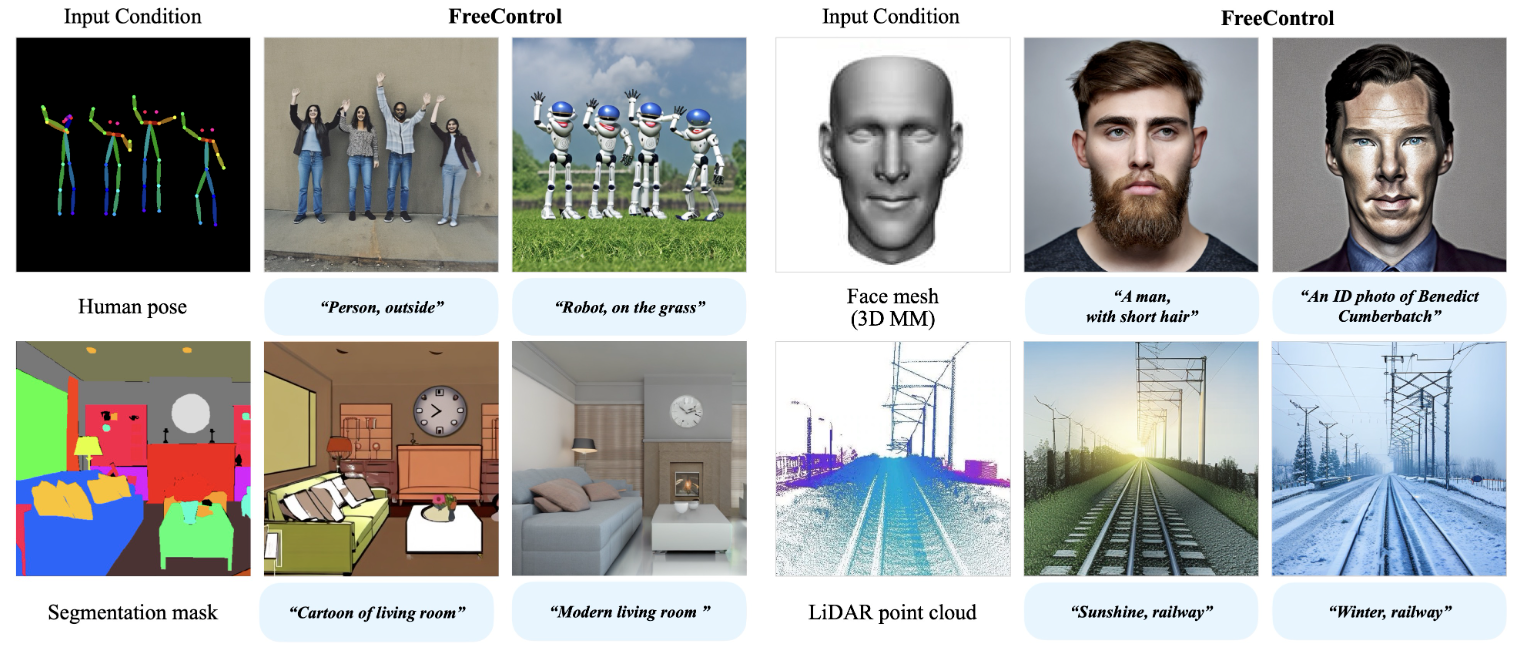
FreeControl: Training-Free Spatial Control of Any Text-to-Image Diffusion Model with Any Condition
CVPR2024{Paper} {Code} {Webpage}Details
-
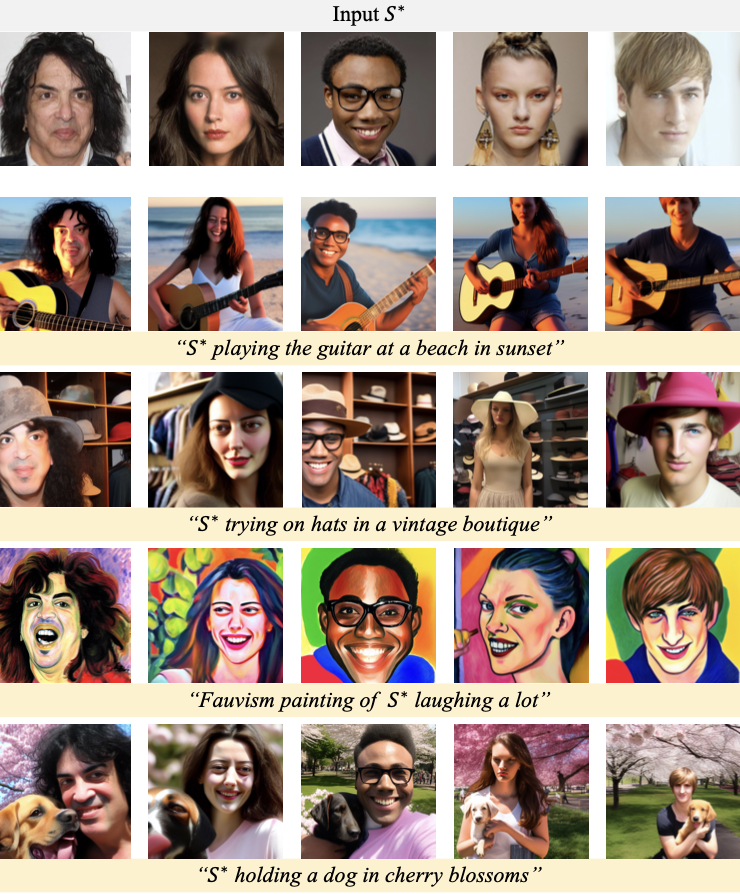
Face2Diffusion for Fast and Editable Face Personalization
CVPR2024{Paper} {Code} {Webpage}Details
-
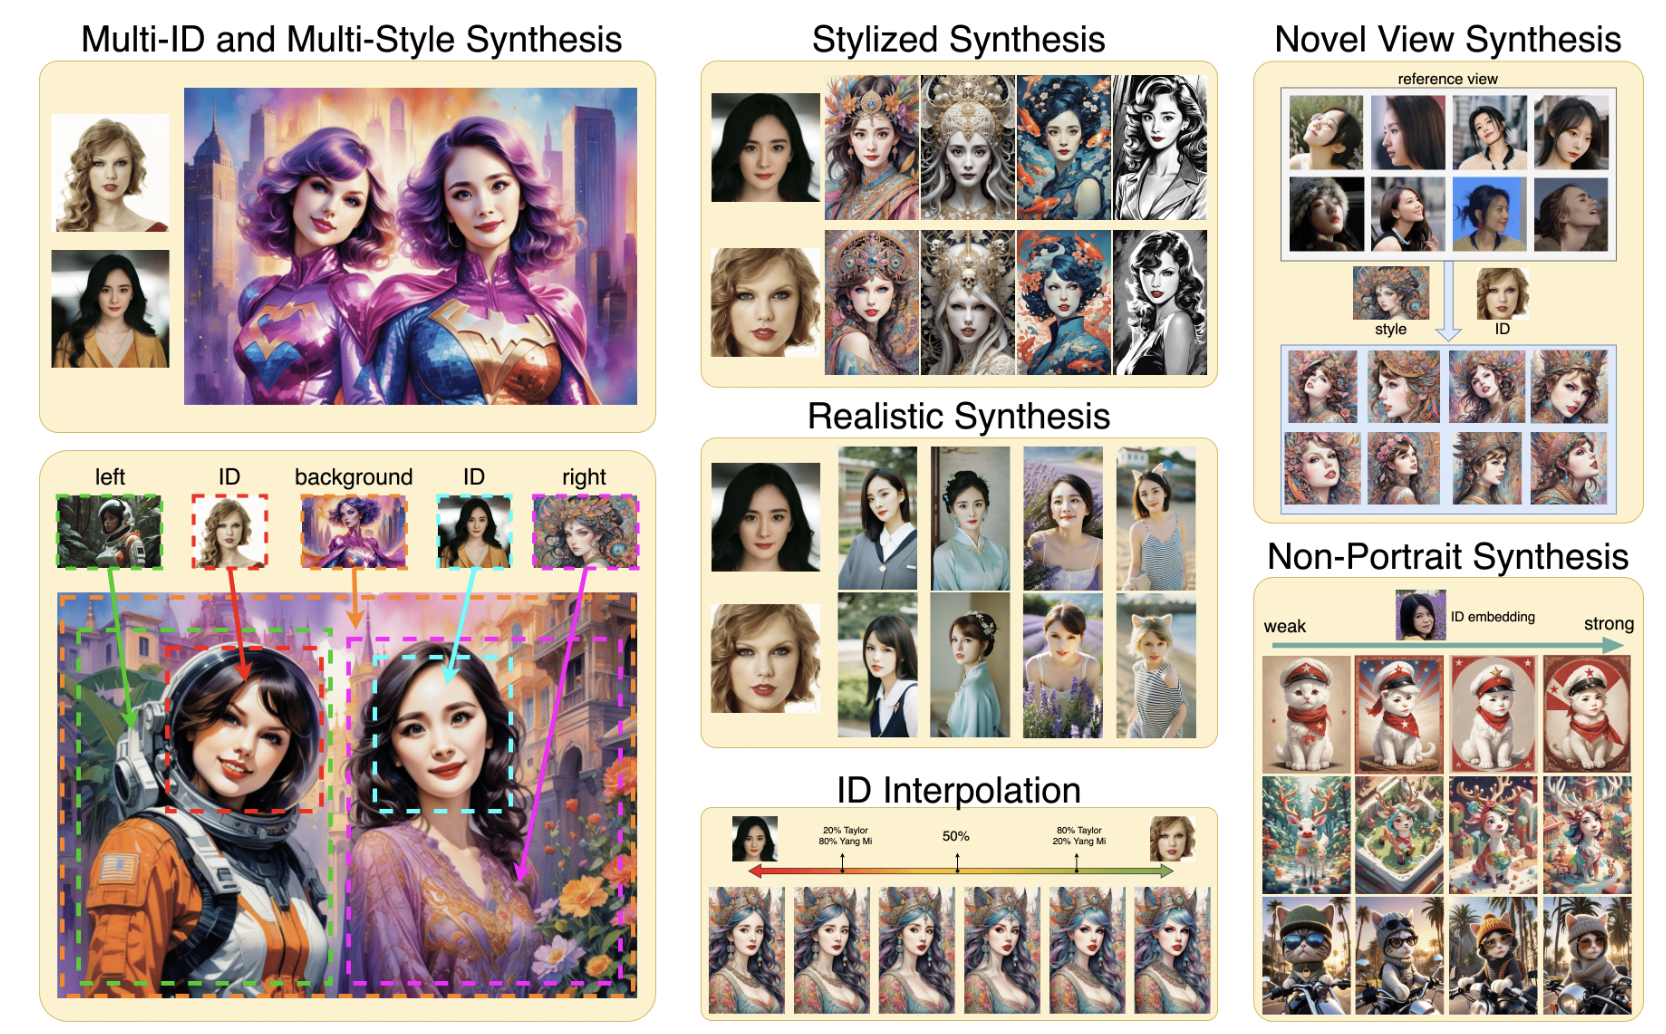
InstantID: Zero-shot Identity-Preserving Generation in Seconds
arxiv{Paper} {Code} {Webpage}Details
-
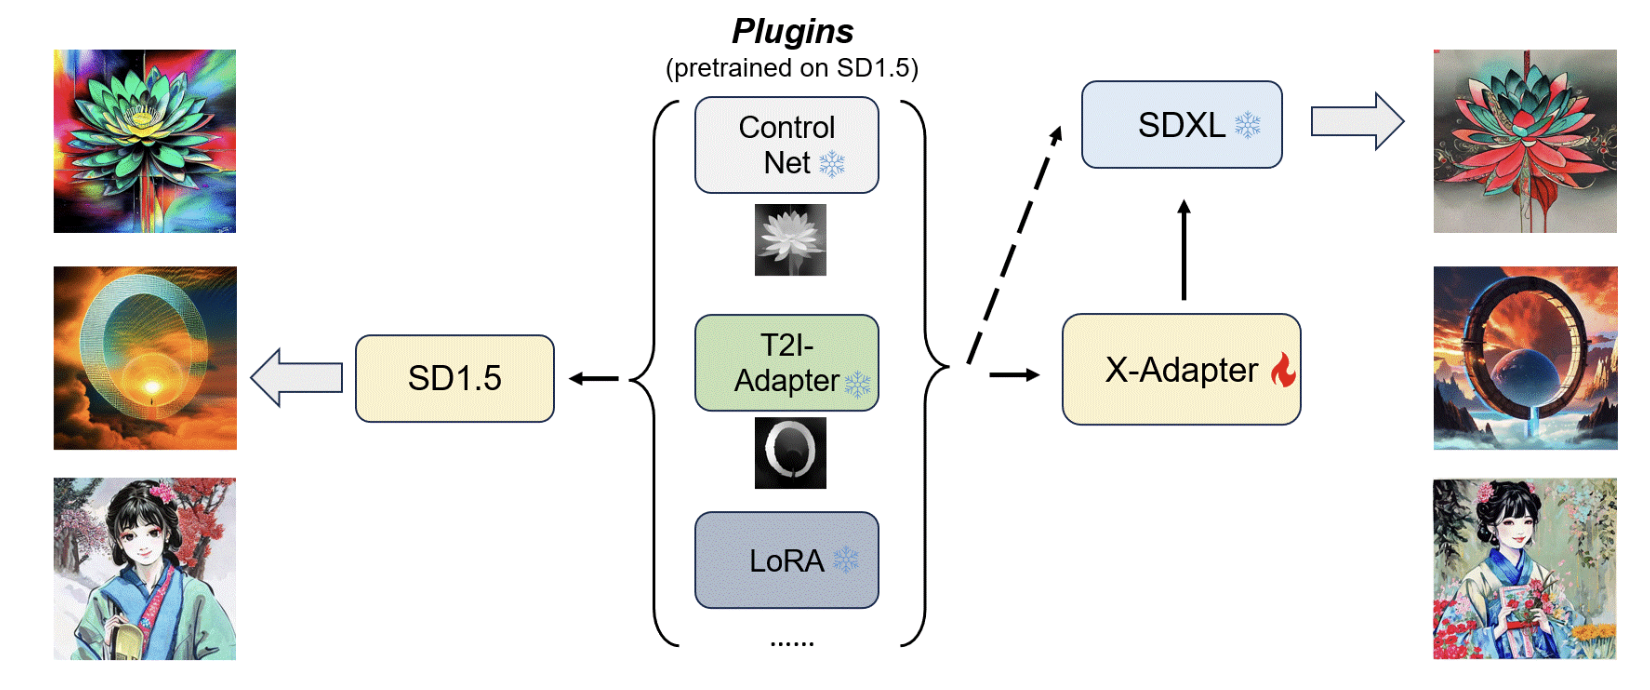
X-Adapter: Adding Universal Compatibility of Plugins for Upgraded Diffusion Model
CVPR2024{Paper} {Code} {Webpage}Details
-
MagiCapture: High-Resolution Multi-Concept Portrait Customization
AAAI2024{Paper} {Code} {Webpage} -
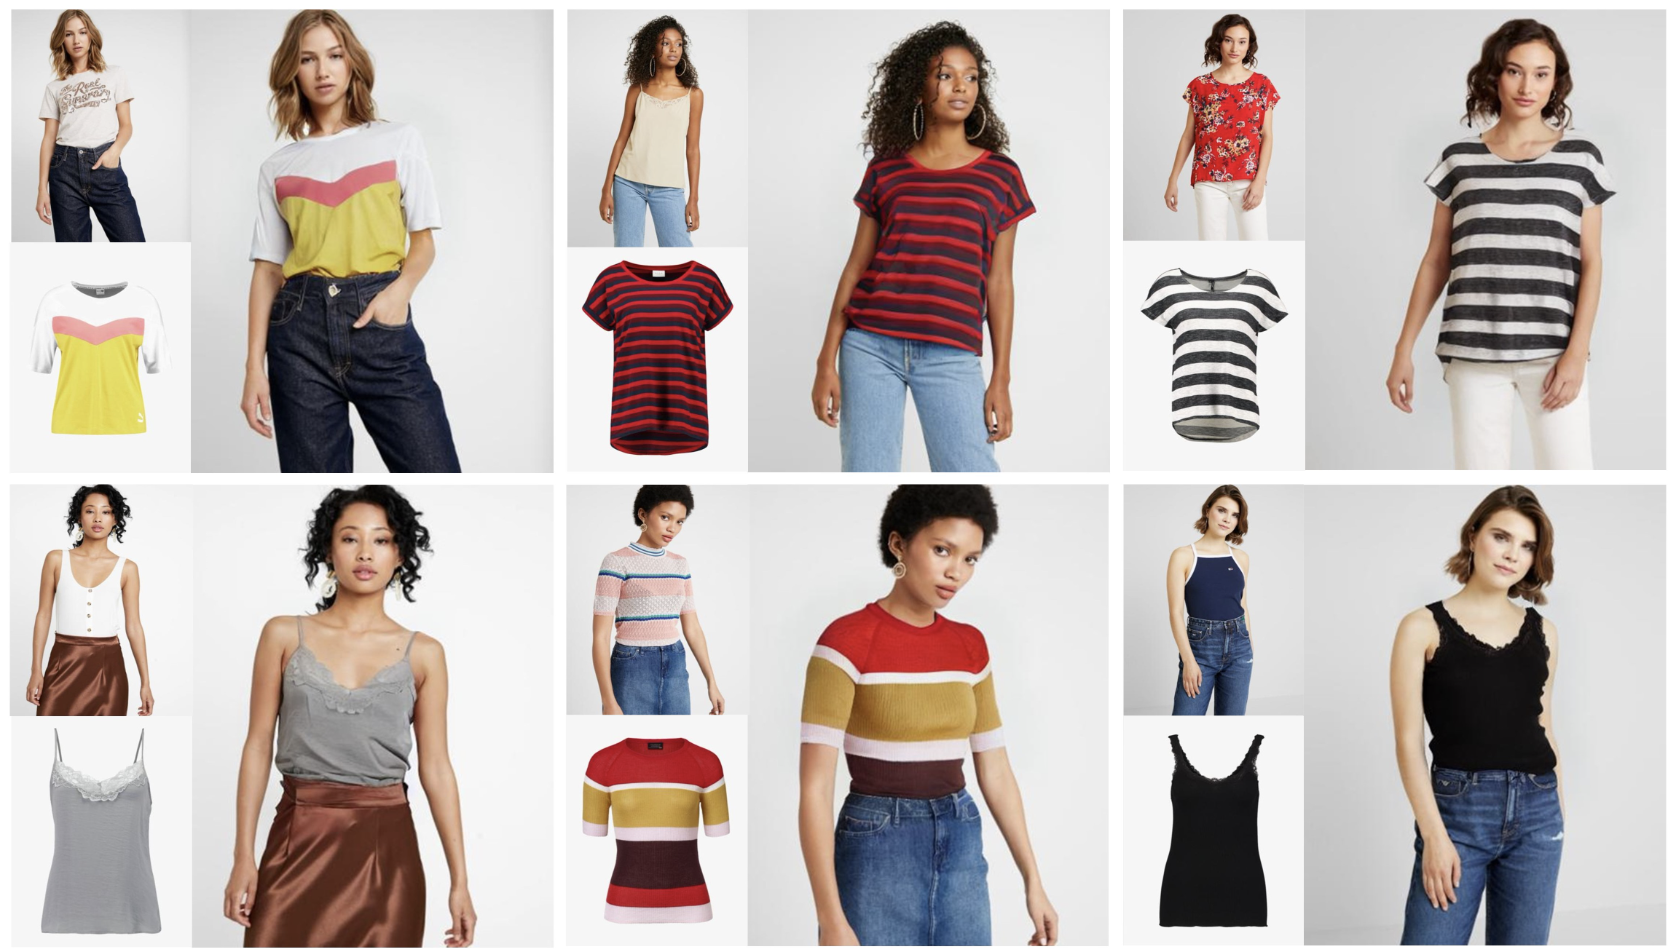
Texture-Preserving Diffusion Models for High-Fidelity Virtual Try-On
CVPR2024{Paper} {Code}Details
-
Orthogonal Adaptation for Modular Customization of Diffusion Models
CVPR2024{Paper} {Webpage} -
High-fidelity Person-centric Subject-to-Image Synthesis
CVPR 2024{Paper} {Code} -
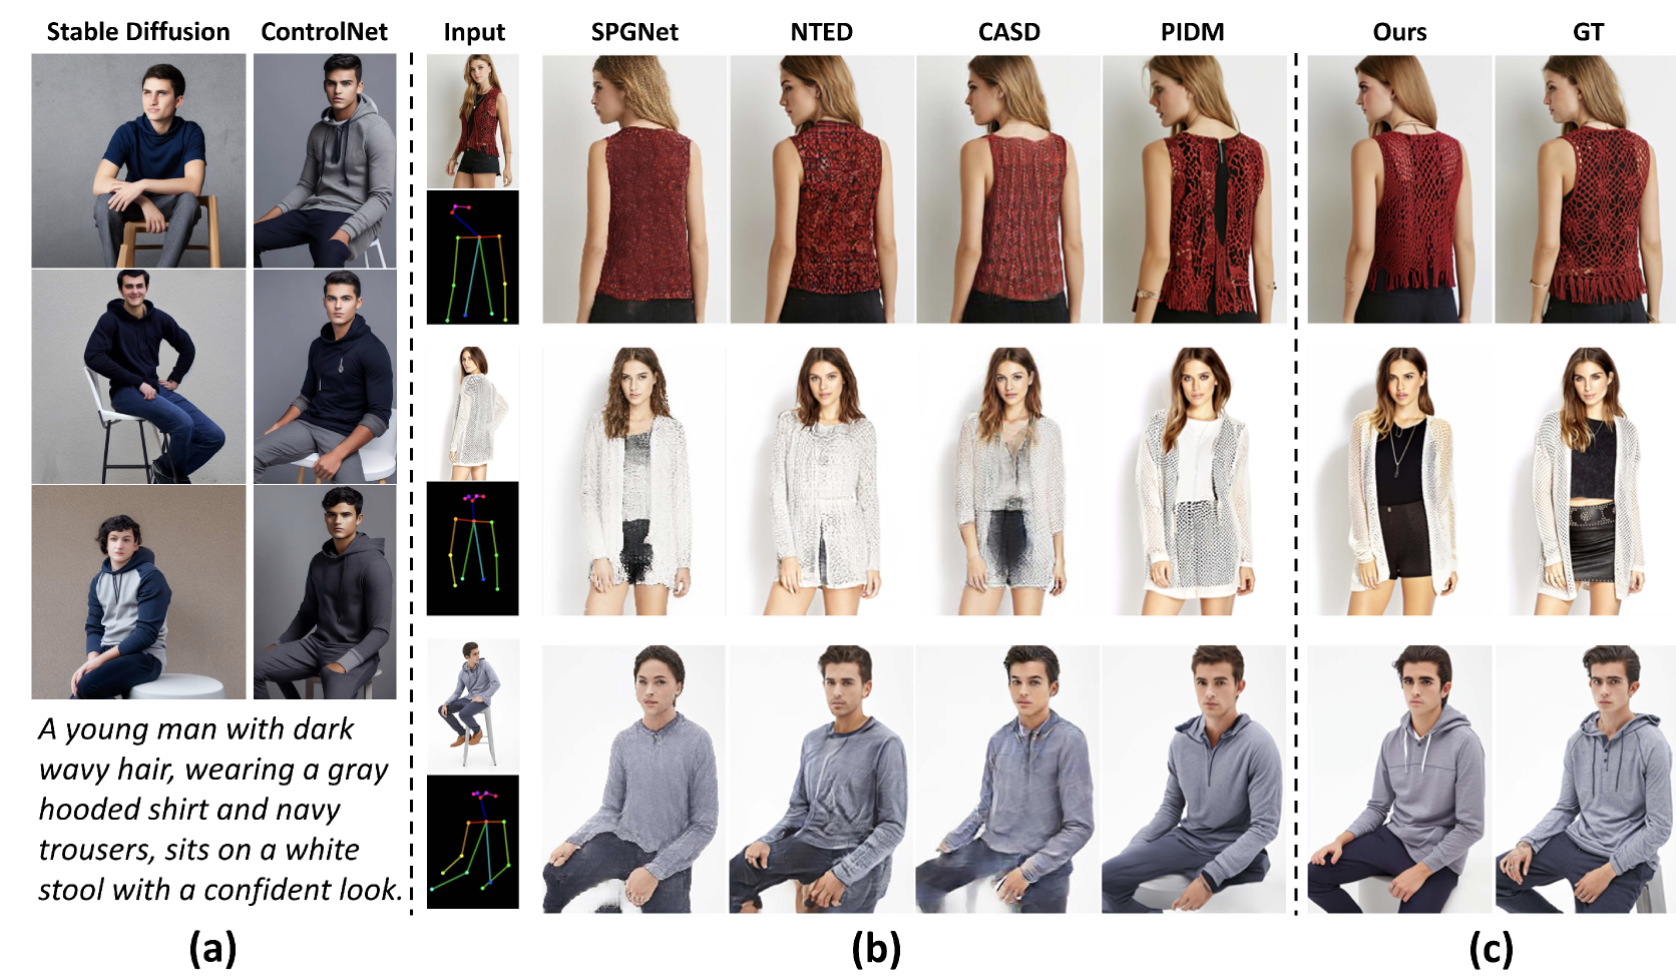
Coarse-to-Fine Latent Diffusion for Pose-Guided Person Image Synthesis
CVPR 2024{Paper} {Code}Details
-
Non-confusing Generation of Customized Concepts in Diffusion Models
ICML 2024{Paper} {Code} {Webpage} -
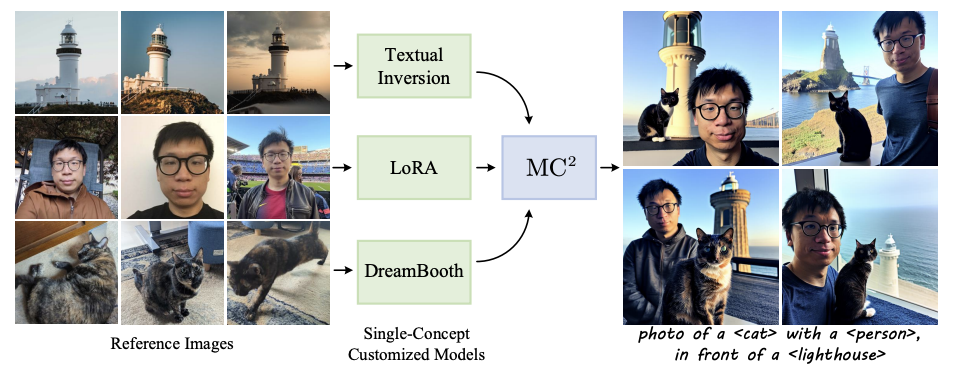
MC2: Multi-concept Guidance for Customized Multi-concept Generation
arxiv{Paper} {Code}Details
-
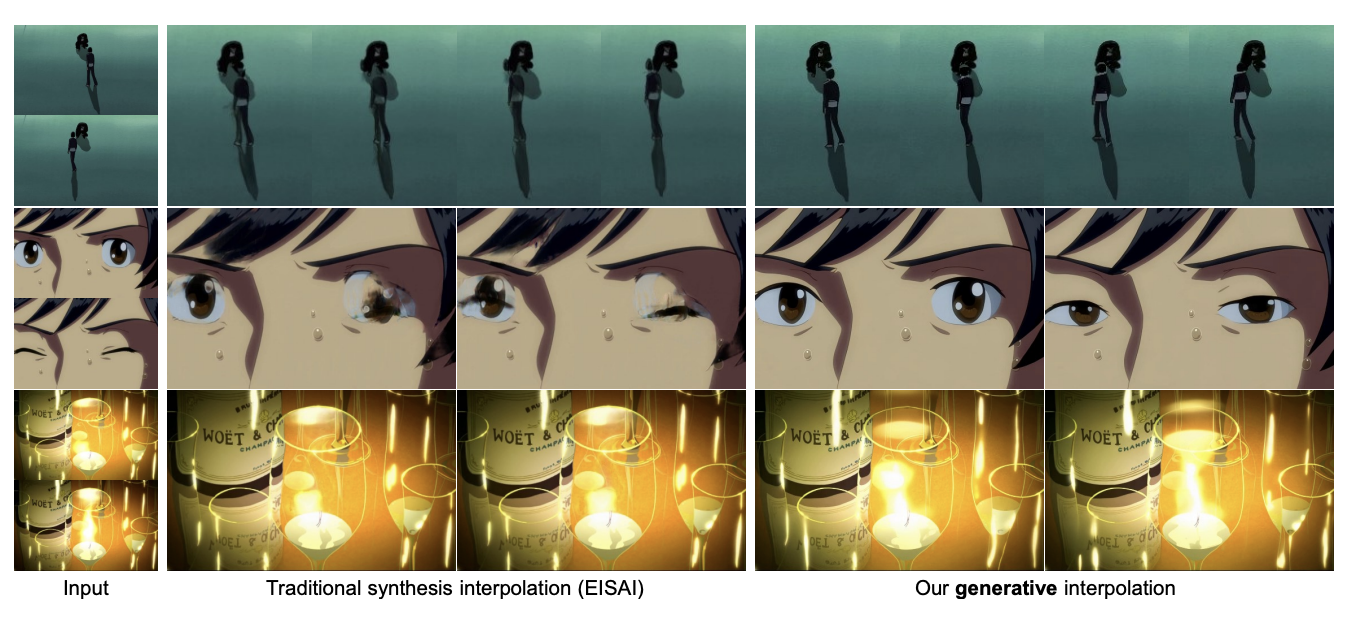
ToonCrafter: Generative Cartoon Interpolation
arxiv{Paper} {Code} {Webpage}Details
-
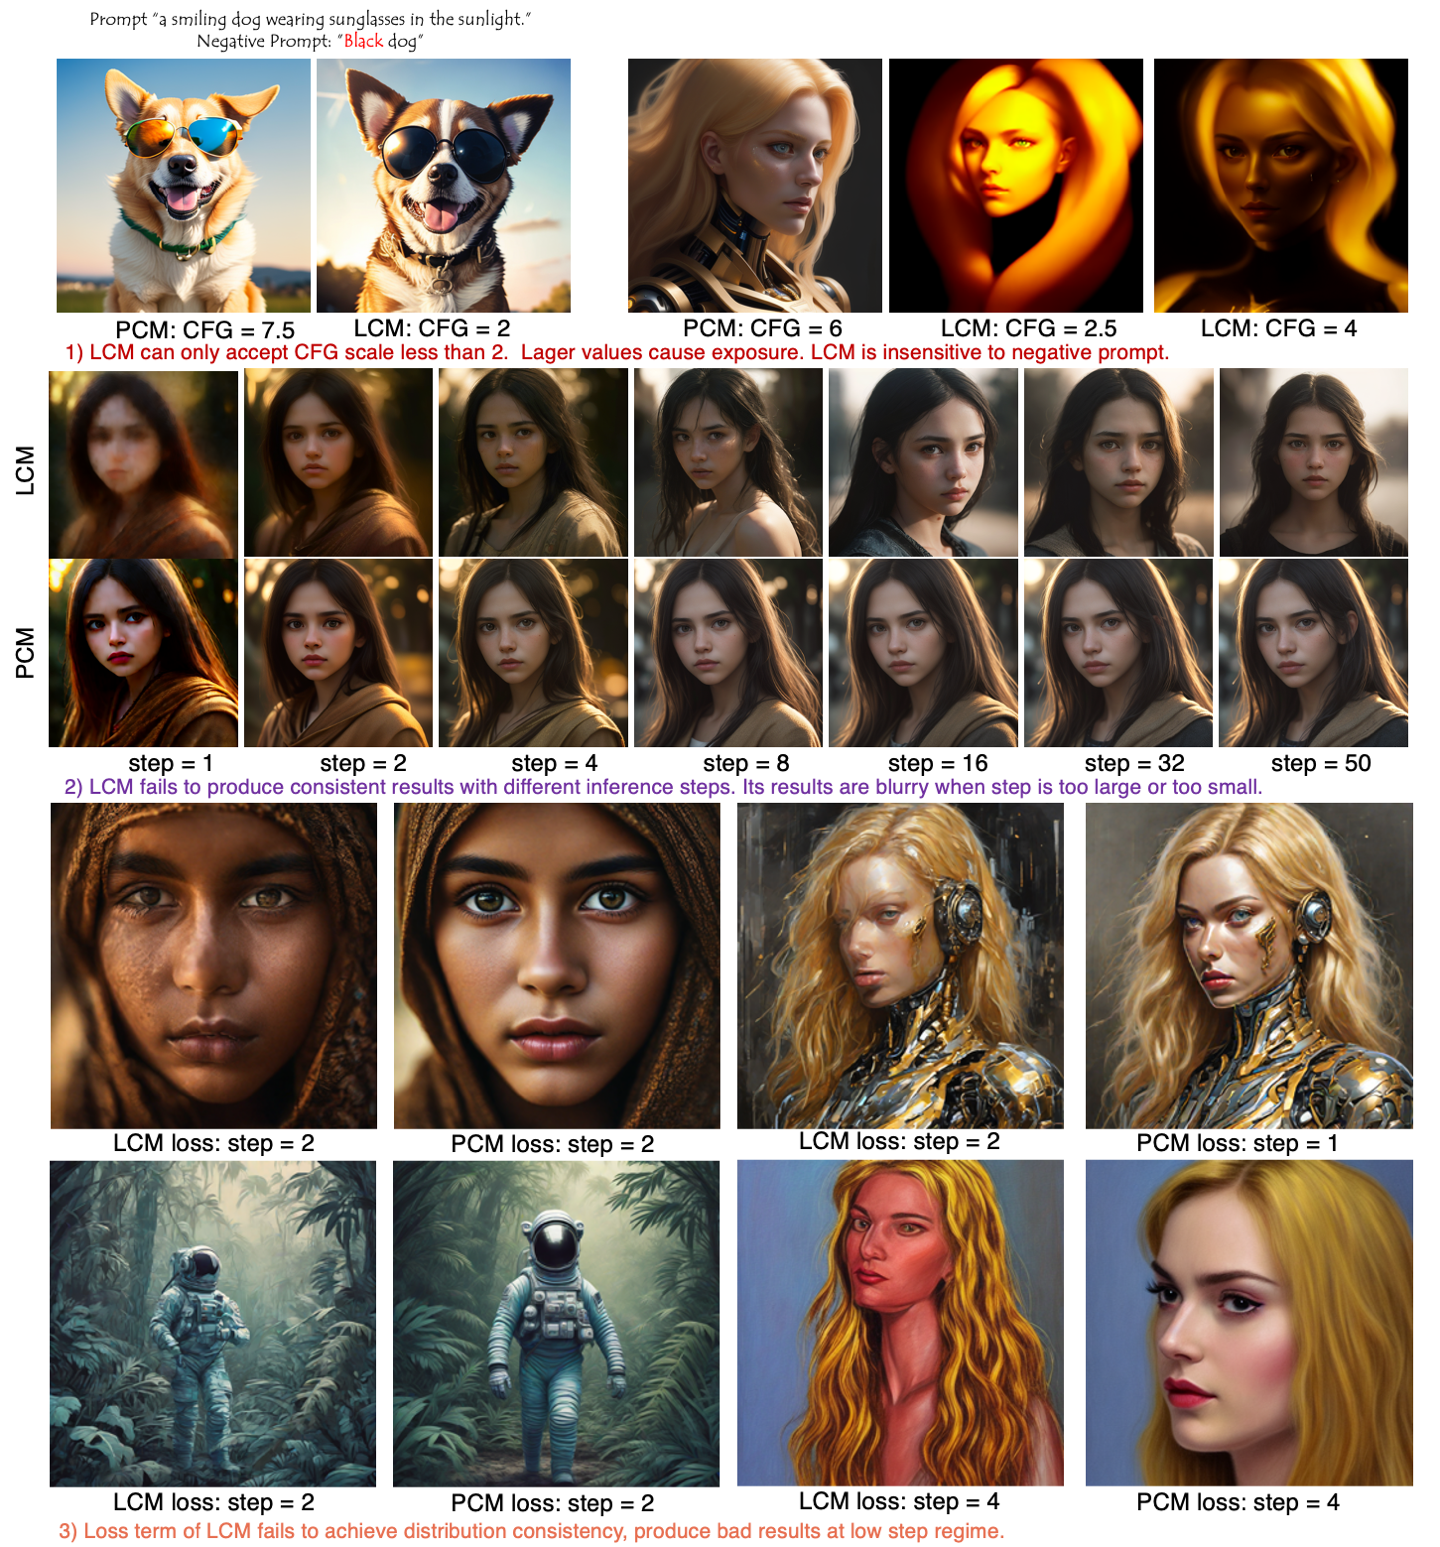
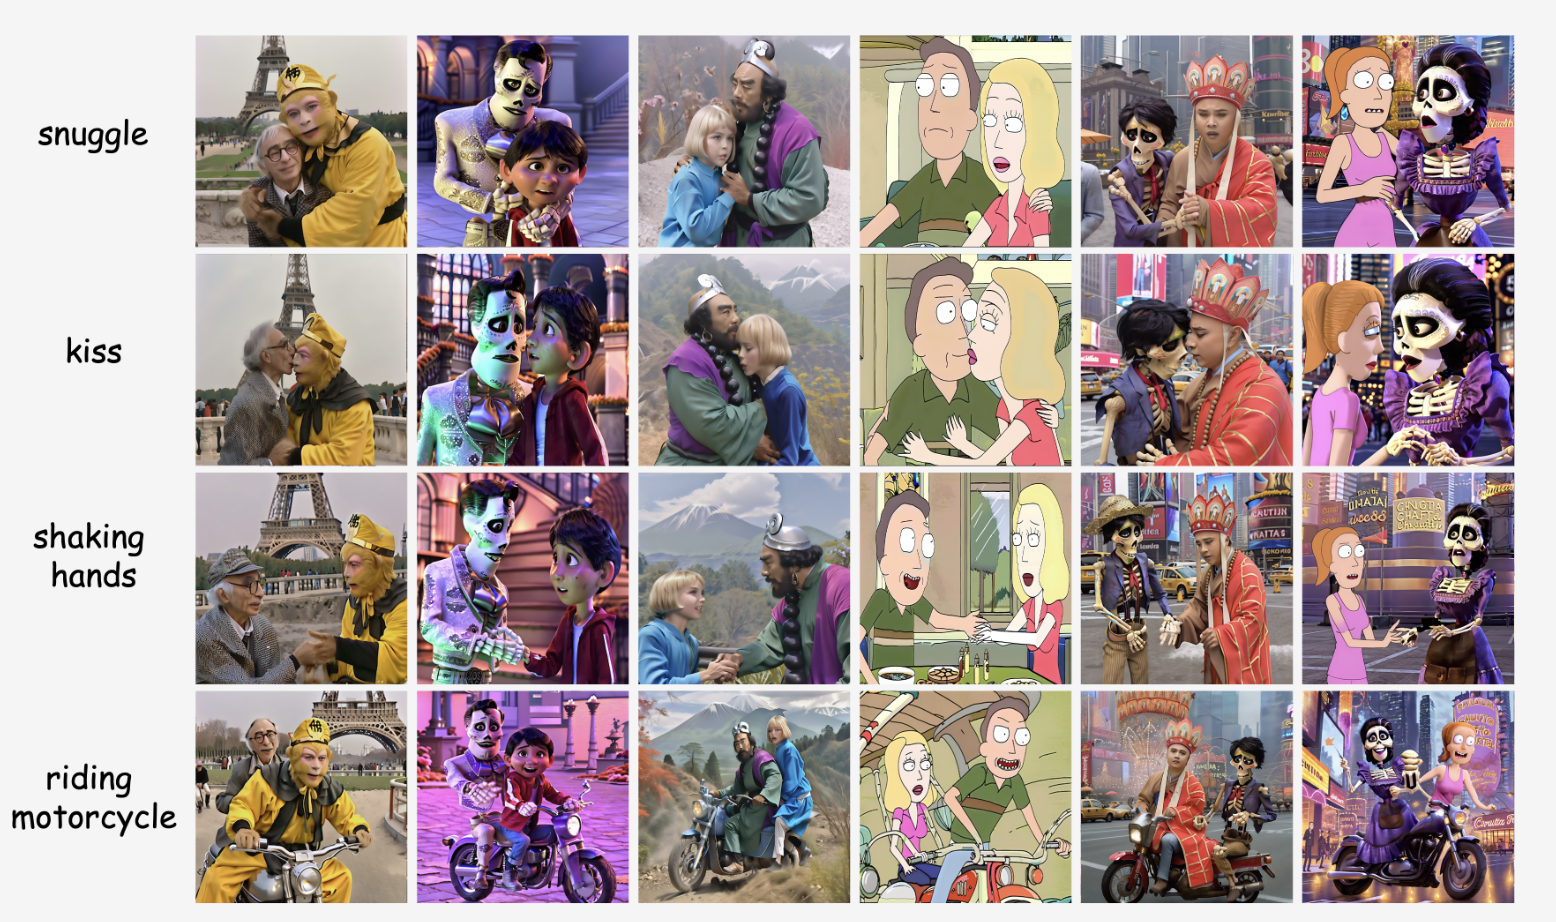
PCM : Phased Consistency Model
arxiv{Paper} {Code} {Webpage}Details
2023
-
IP-Adapter: Text Compatible Image Prompt Adapter for Text-to-Image Diffusion Models
arxiv{Paper} {Code} {Webpage} -
ViscoNet: Bridging and Harmonizing Visual and Textual Conditioning for ControlNet
arxiv{Paper} {Code} {Webpage}
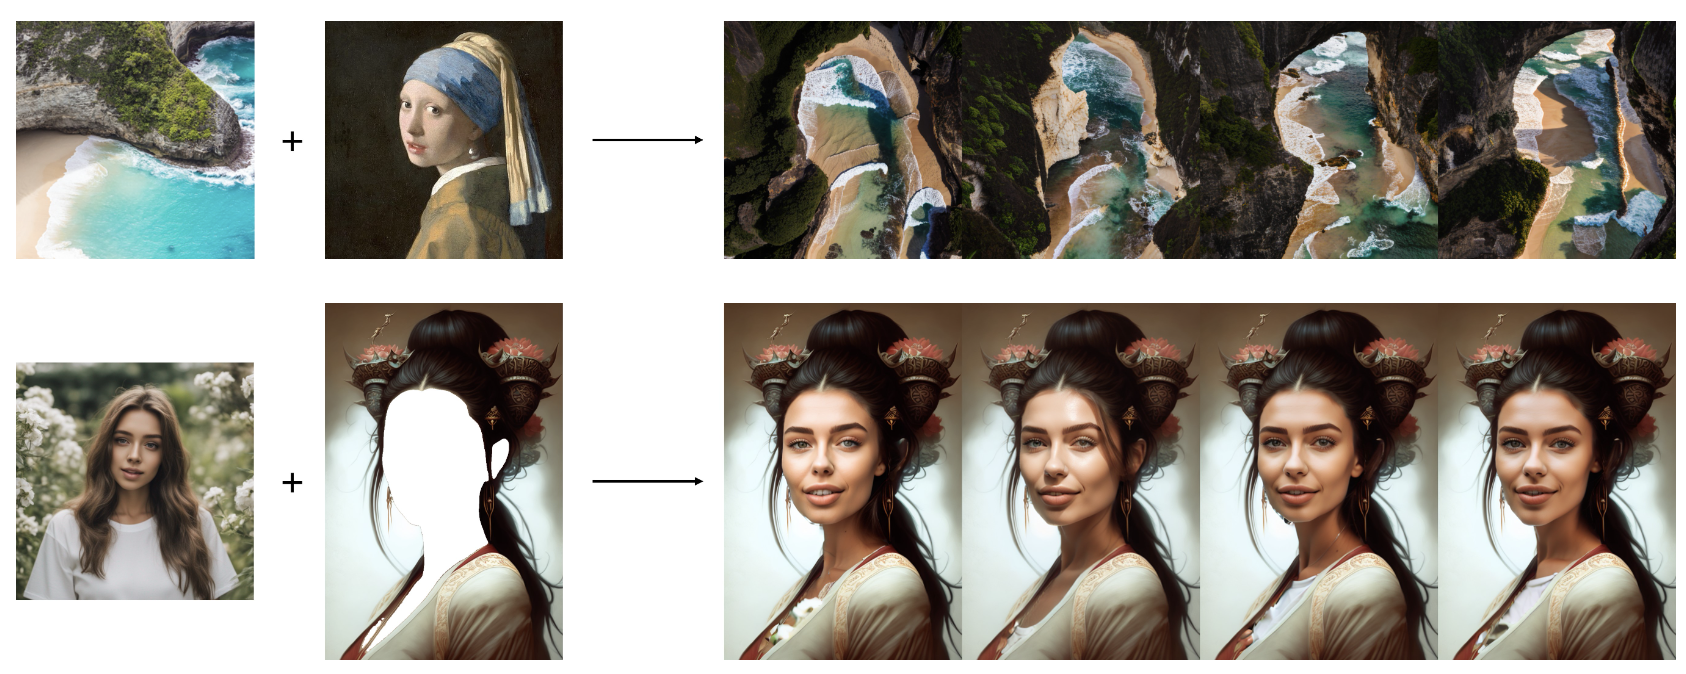

- When StyleGAN Meets Stable Diffusion: a 𝒲+ Adapter for Personalized Image Generation
arxiv{Paper} {Code}Details

-
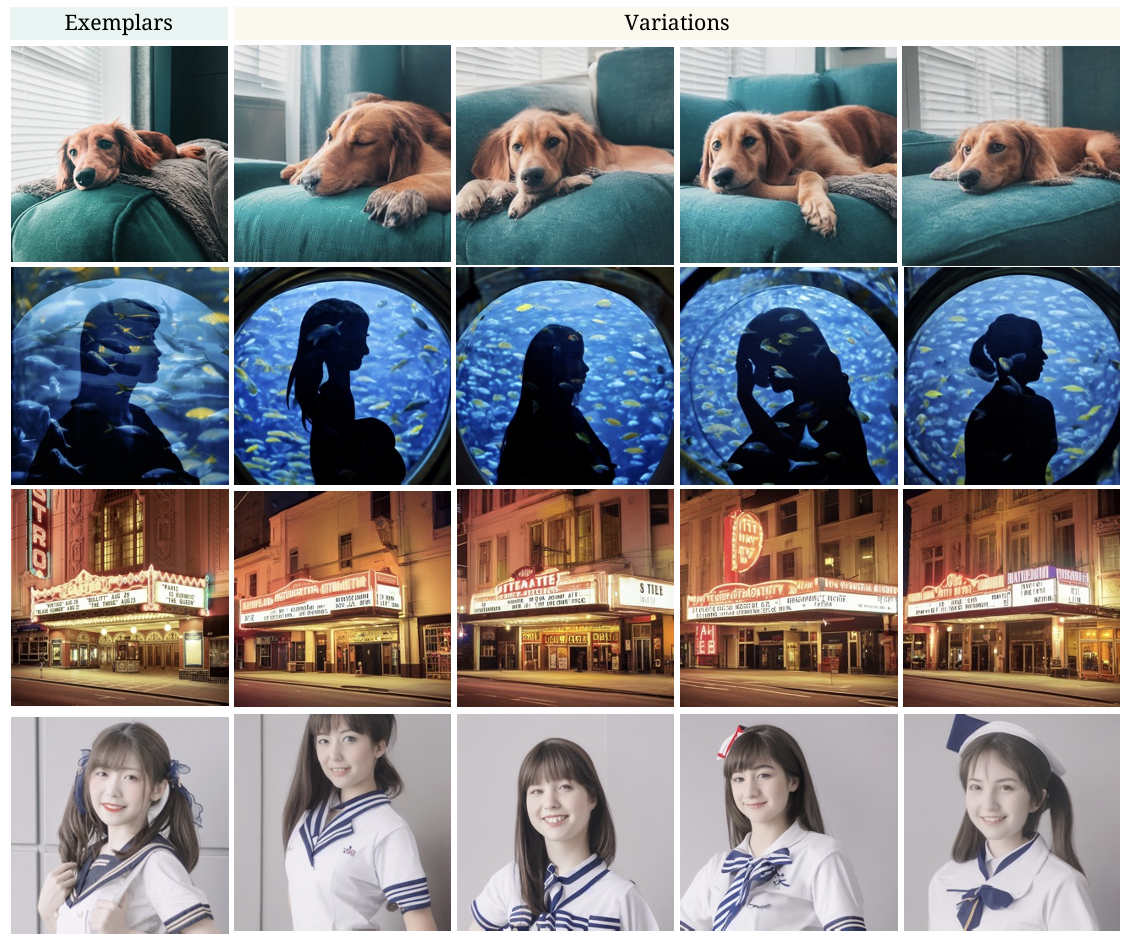
Real-World Image Variation by Aligning Diffusion Inversion Chain
NeurIPS2023{Paper} {Code} {Webpage} -
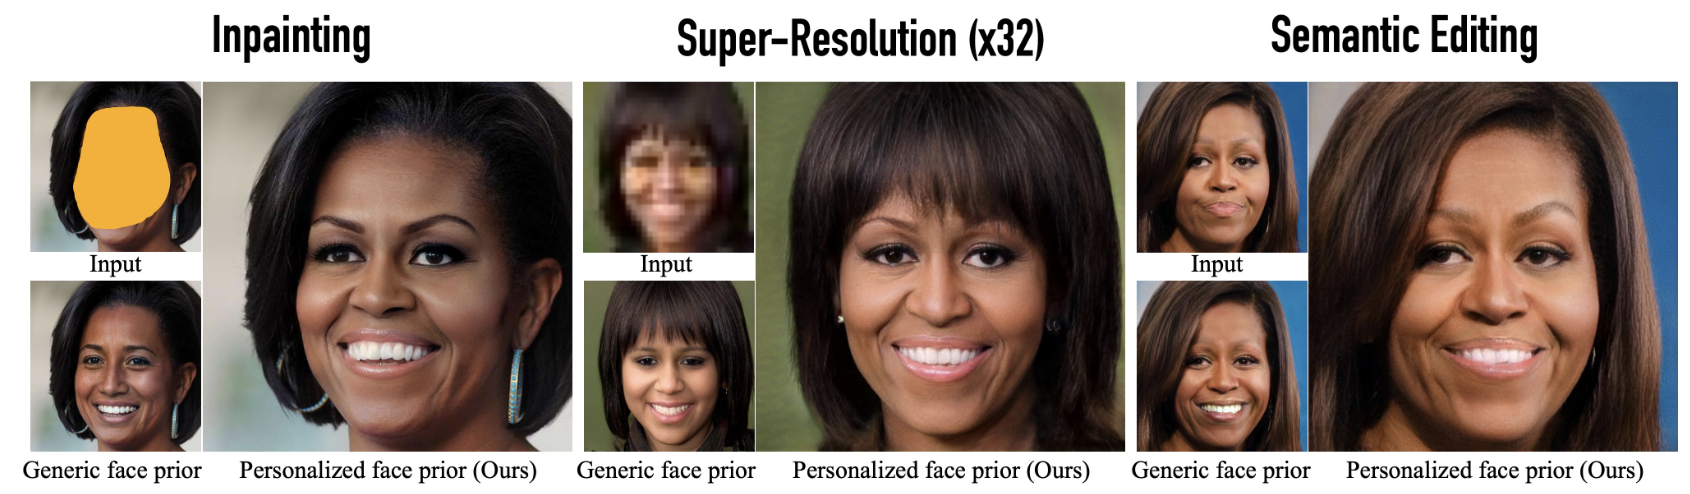
MyStyle++: A Controllable Personalized Generative Prior
SIGGRAPH ASIA 2023{Paper} {Code} {Webpage}Details
-
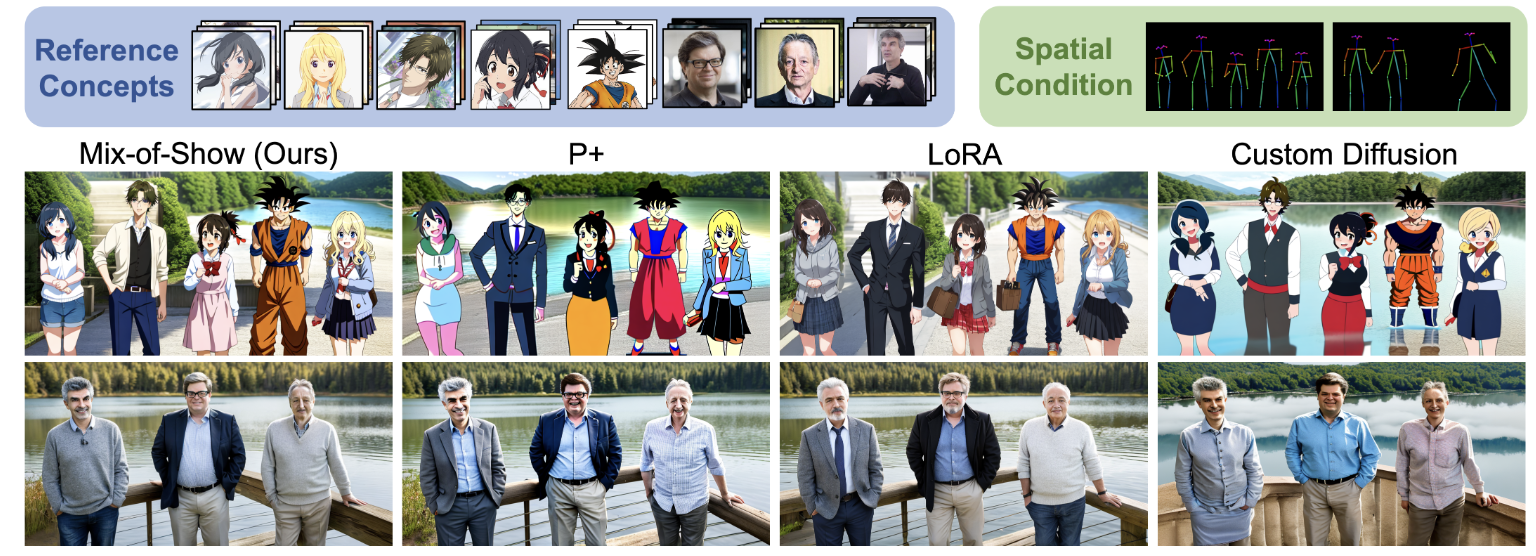
Mix-of-Show: Decentralized Low-Rank Adaptation for Multi-Concept Customization of Diffusion Models
NeurIPS2023{Paper} {Code} {Webpage} -
SingleInsert: Inserting New Concepts from a Single Image into Text-to-Image Models for Flexible Editing
arxiv{Paper} {Code} {Webpage} -
Cones 2: Customizable Image Synthesis with Multiple Subjects
NeurIPS2023{Paper} {Code} {Webpage} -
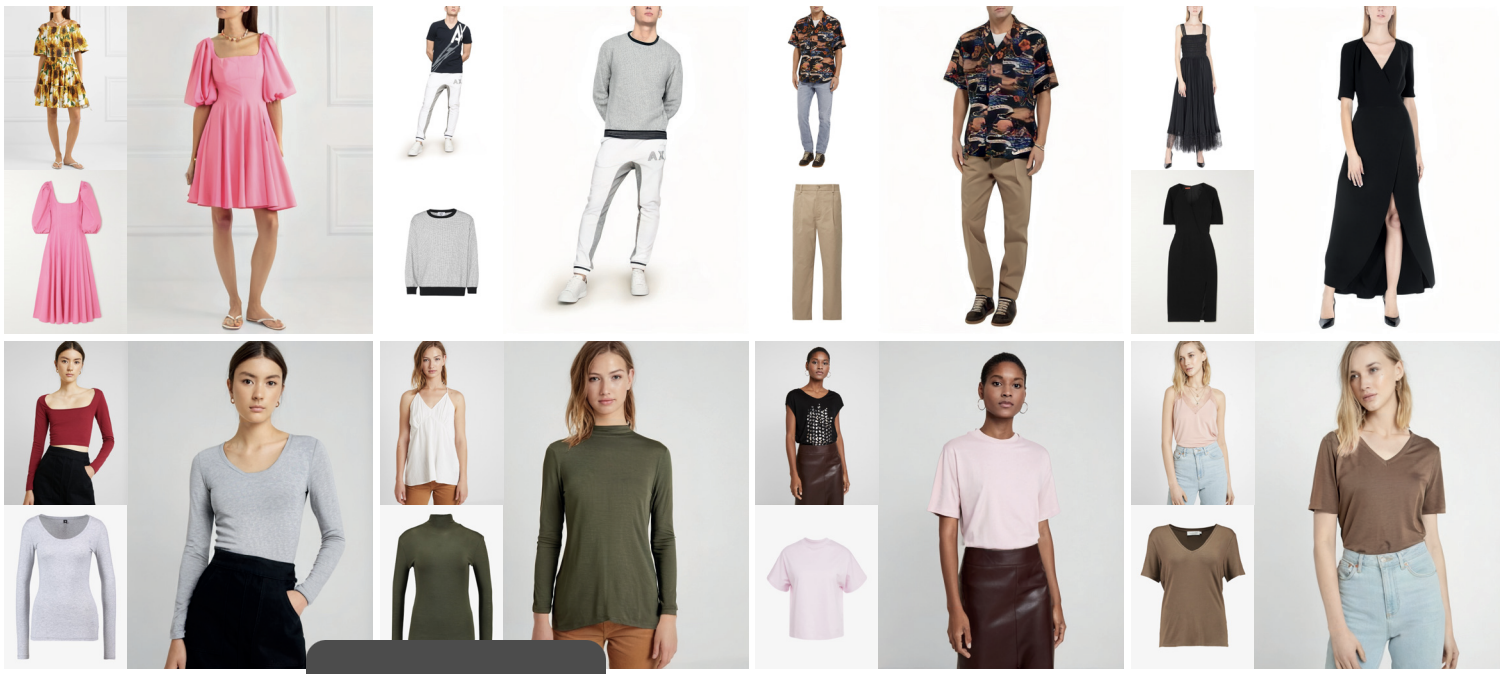
LaDI-VTON: Latent Diffusion Textual-Inversion Enhanced Virtual Try-On
ACM MM 2023{Paper} {Code}Details
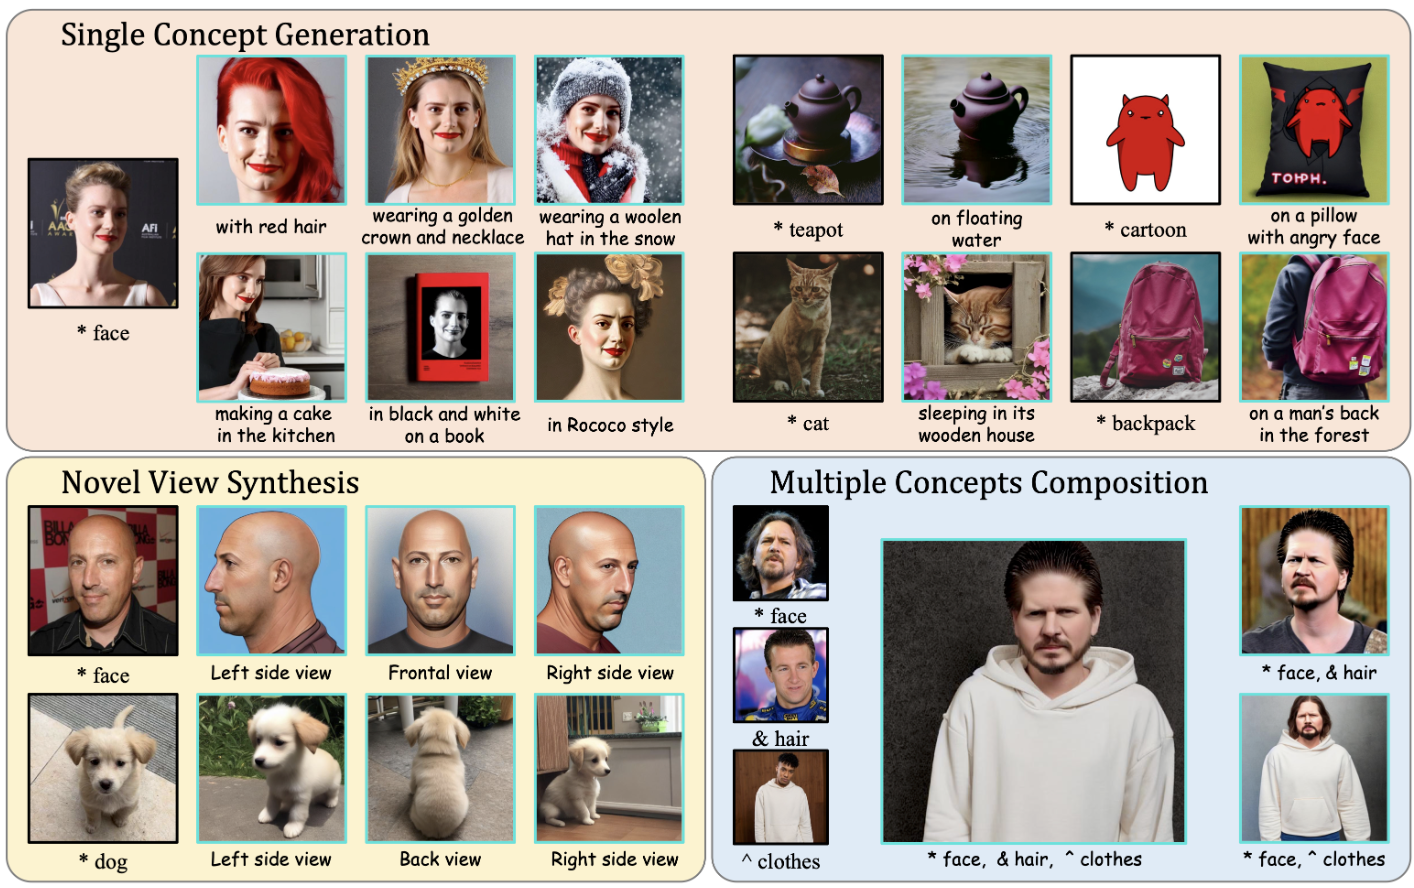
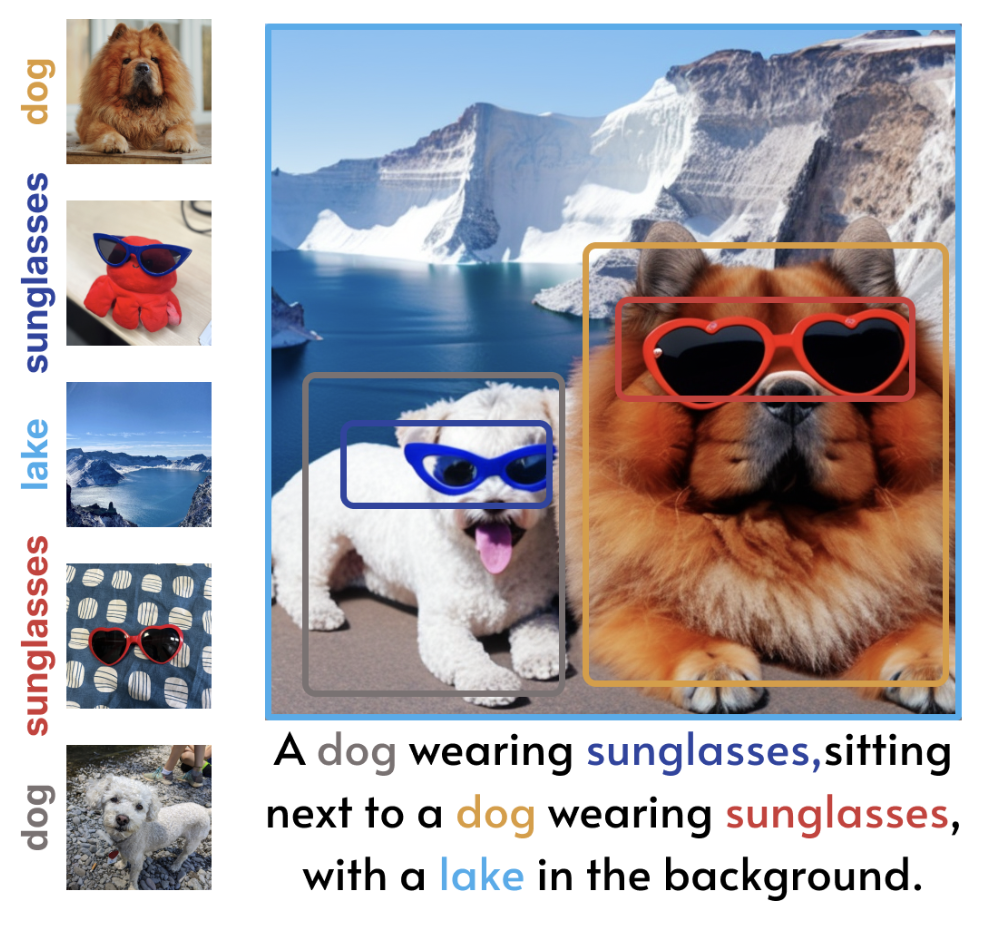
2022
Portrait Style Transfer
2024
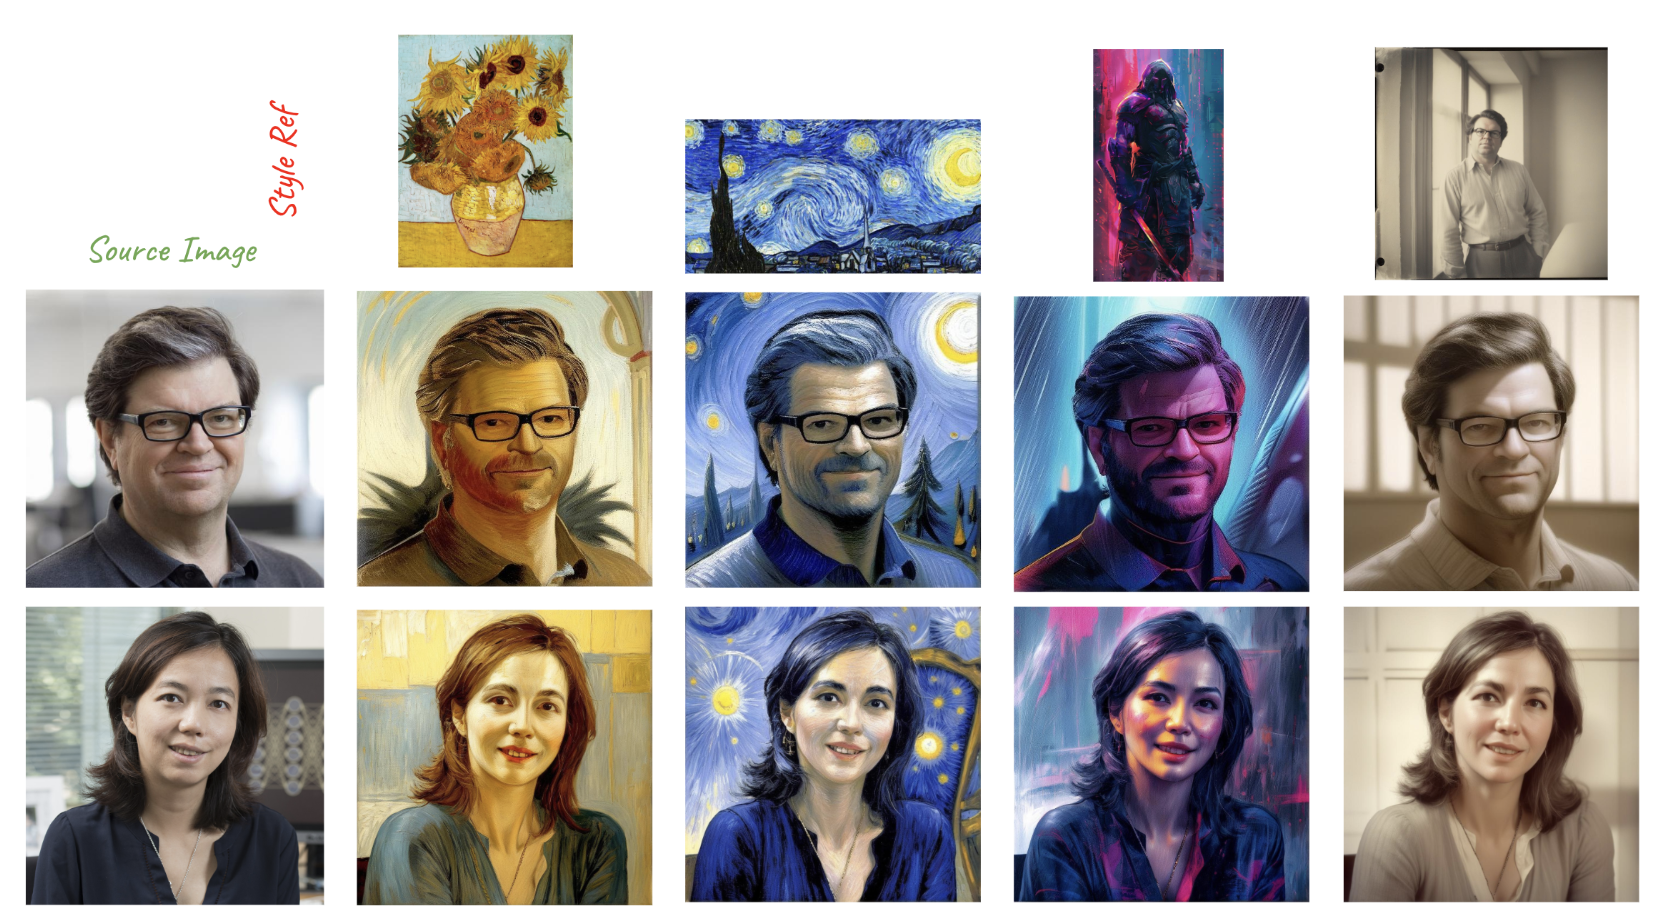
- InstantStyle: Free Lunch towards Style-Preserving in Text-to-Image Generation
arxiv{Paper} {Code}Details
-
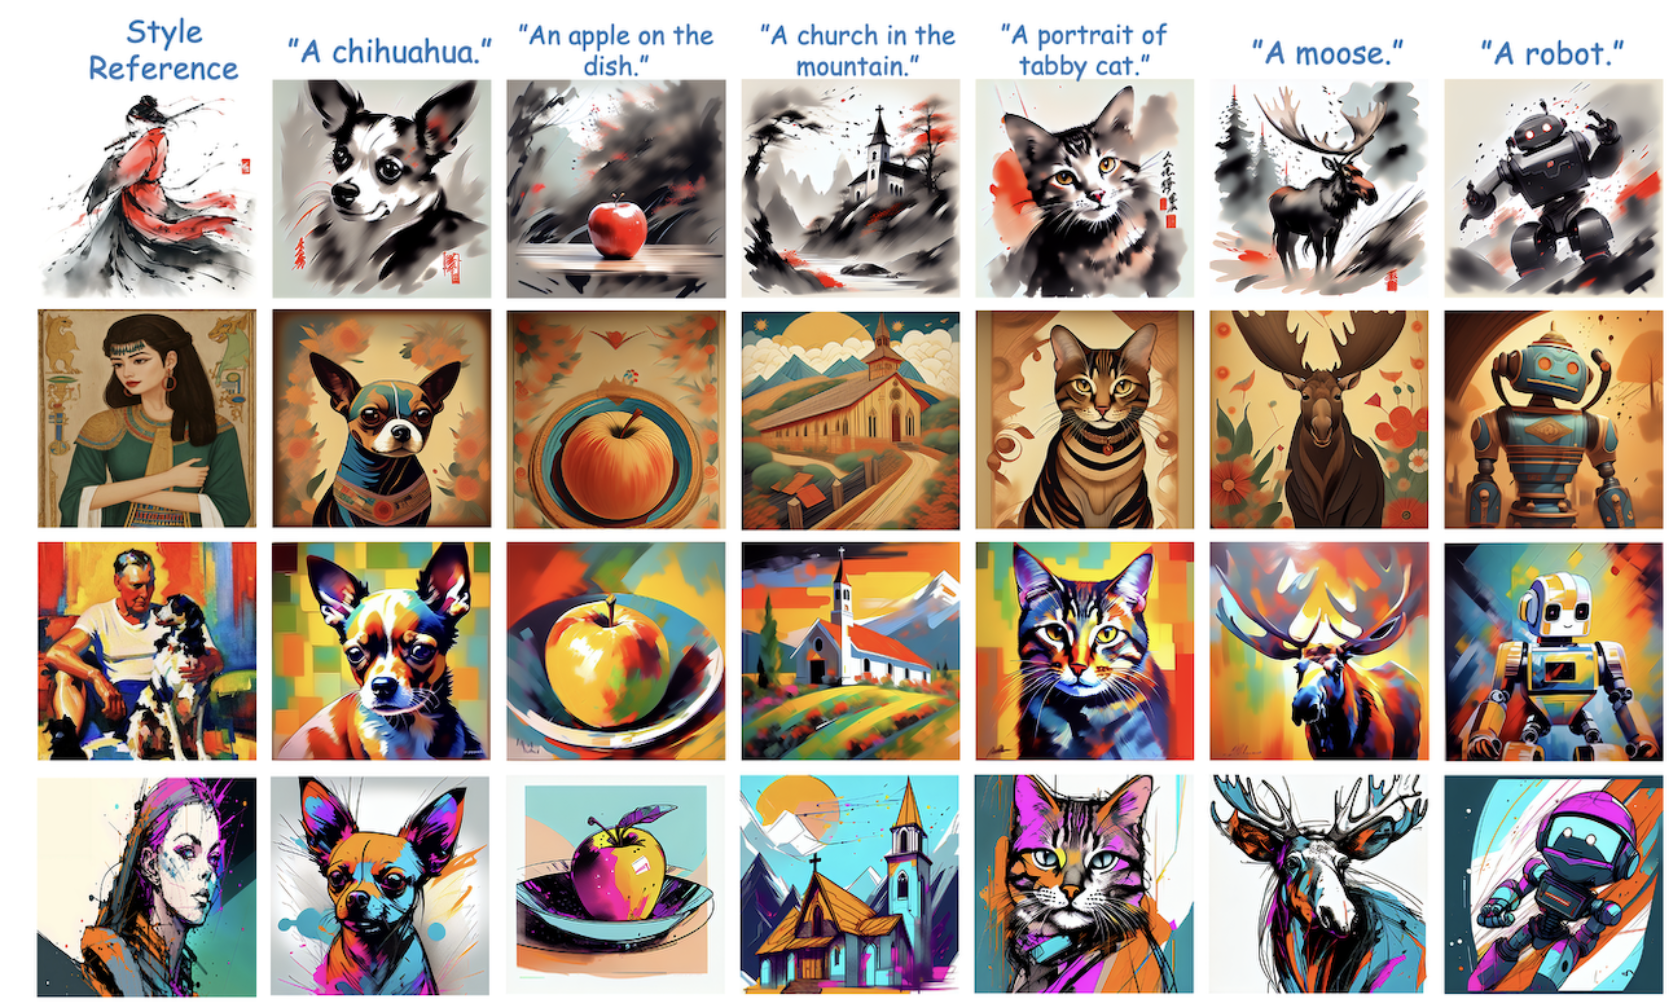
DEADiff: An Efficient Stylization Diffusion Model with Disentangled Representations
CVPR 2024{Paper} {Code} {Webpage}Details
-
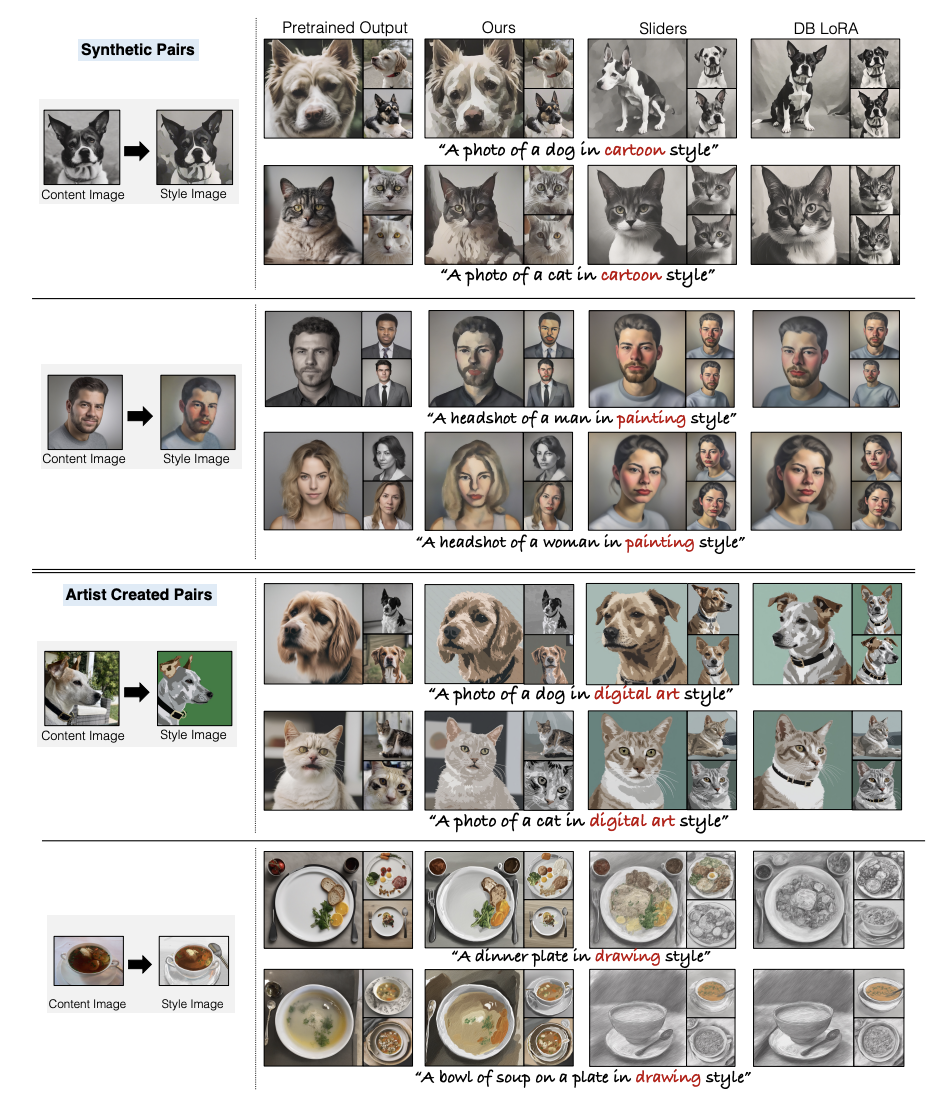
Customizing Text-to-Image Models with a Single Image Pair
arxiv{Paper}Details
2023
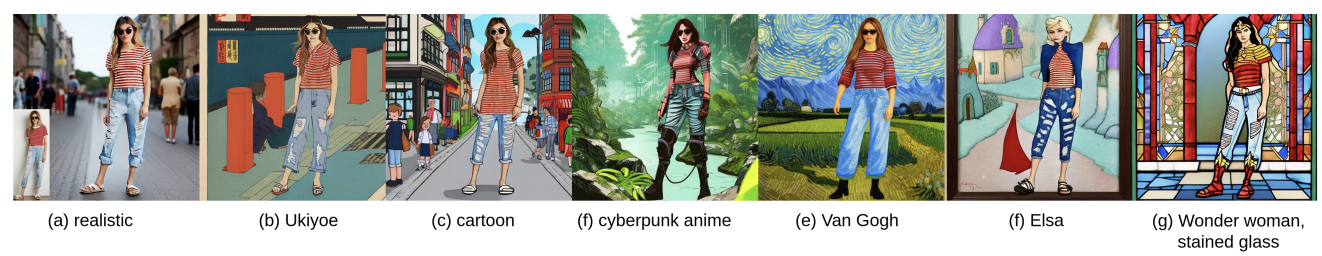
- ViscoNet: Bridging and Harmonizing Visual and Textual Conditioning for ControlNet
arxiv{Paper} {Code} {Webpage}
-
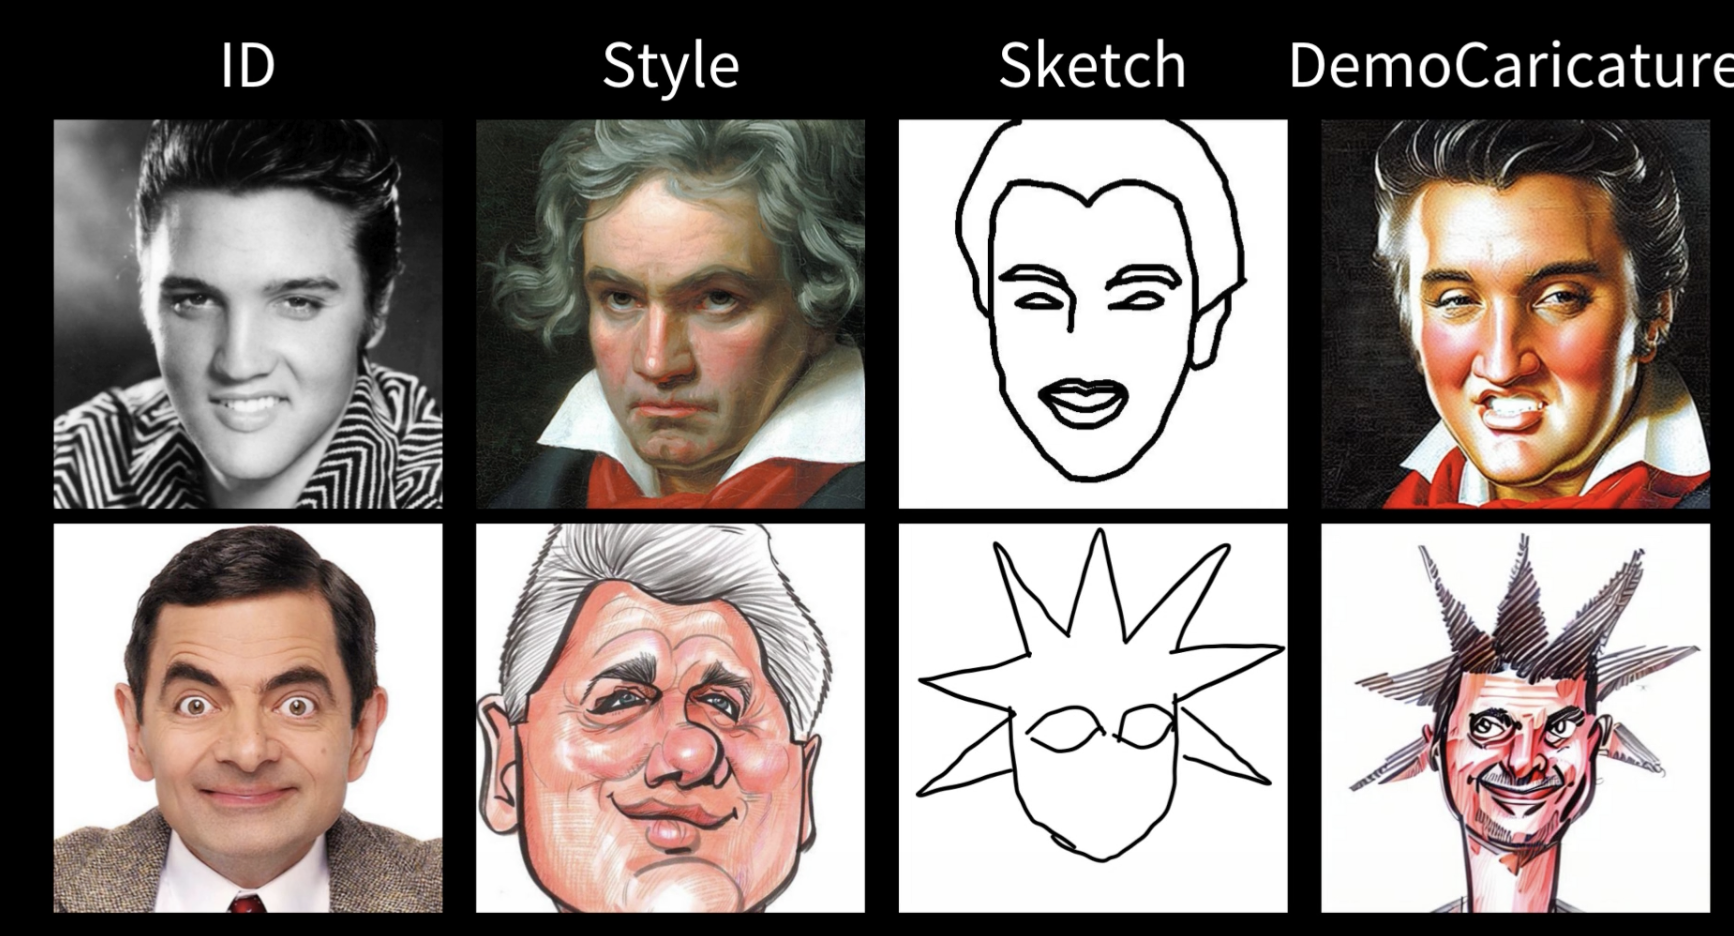
DemoCaricature: Democratising Caricature Generation with a Rough Sketch
arxiv{Paper} {Webpage}Details
-
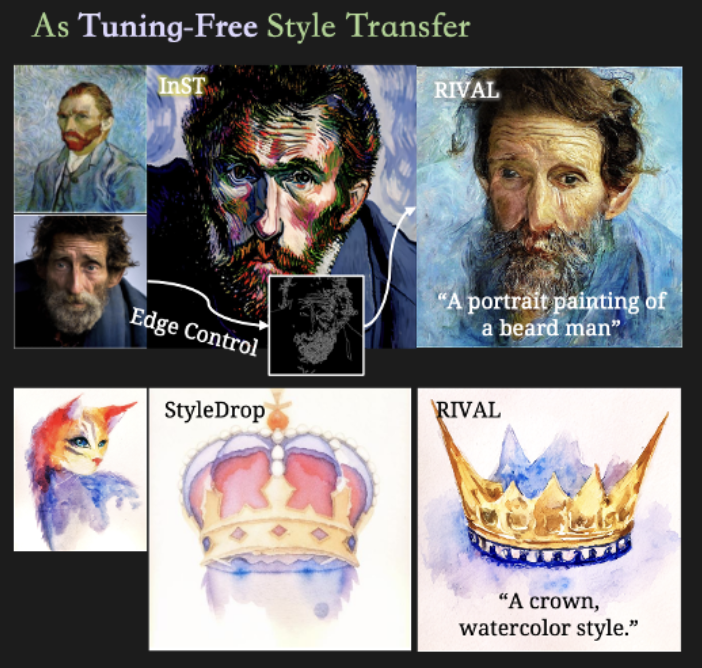
Real-World Image Variation by Aligning Diffusion Inversion Chain
NeurIPS2023{Paper} {Code} {Webpage} -
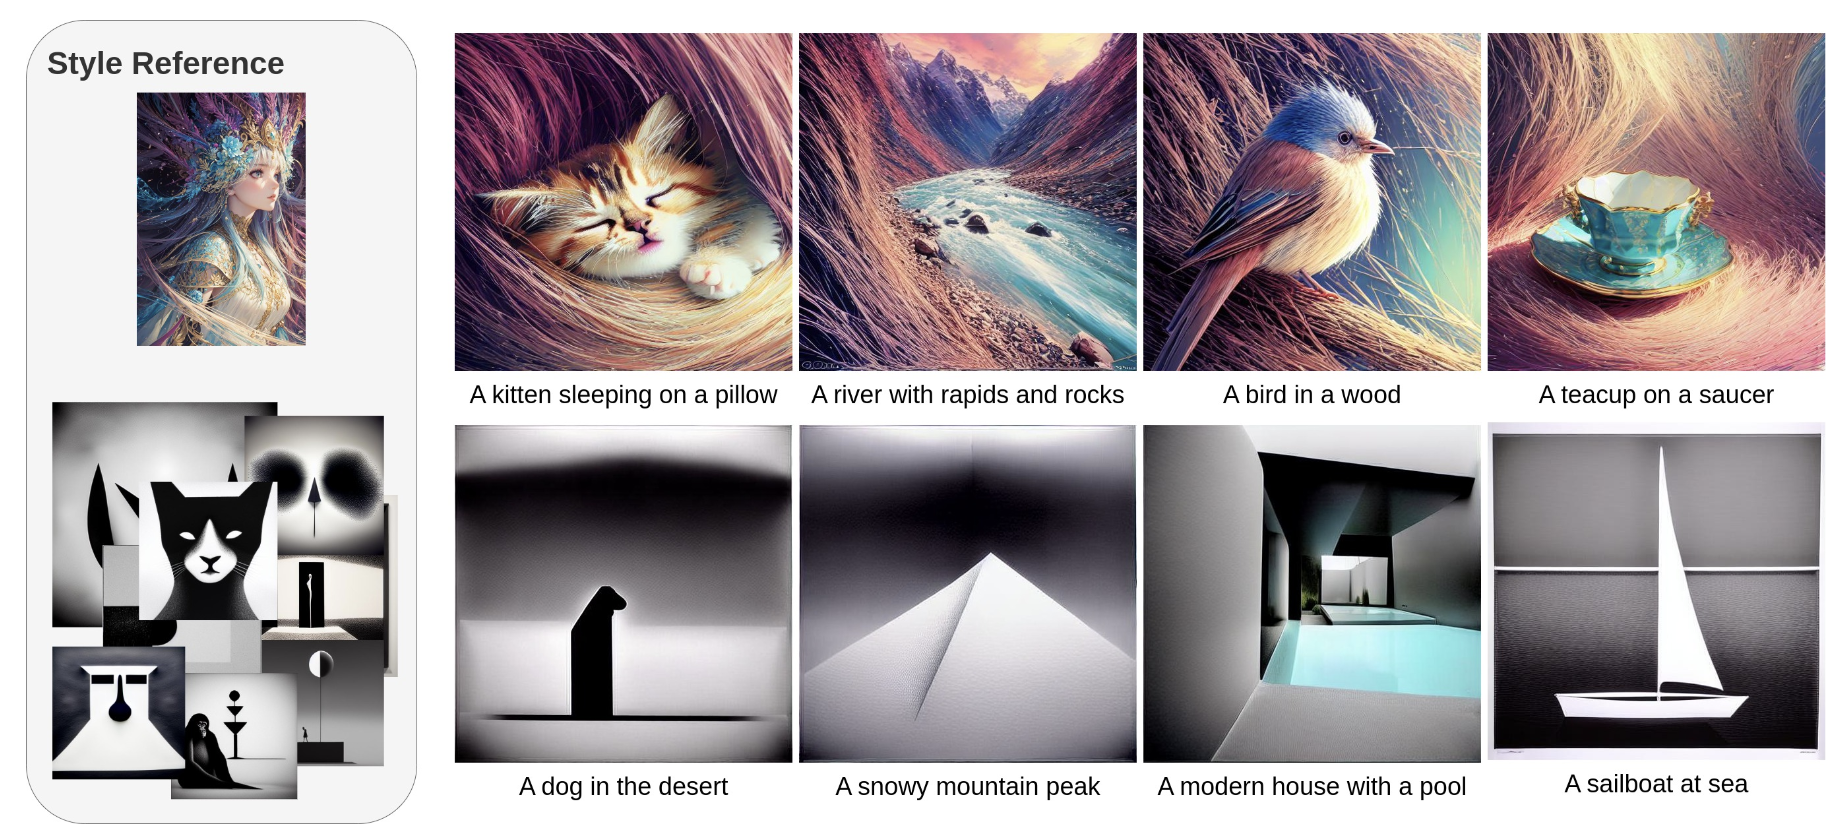
ArtAdapter: Text-to-Image Style Transfer using Multi-Level Style Encoder and Explicit Adaptation
arxiv{Paper} {Code} {Webpage}Details
Interactive Image Editing
2024
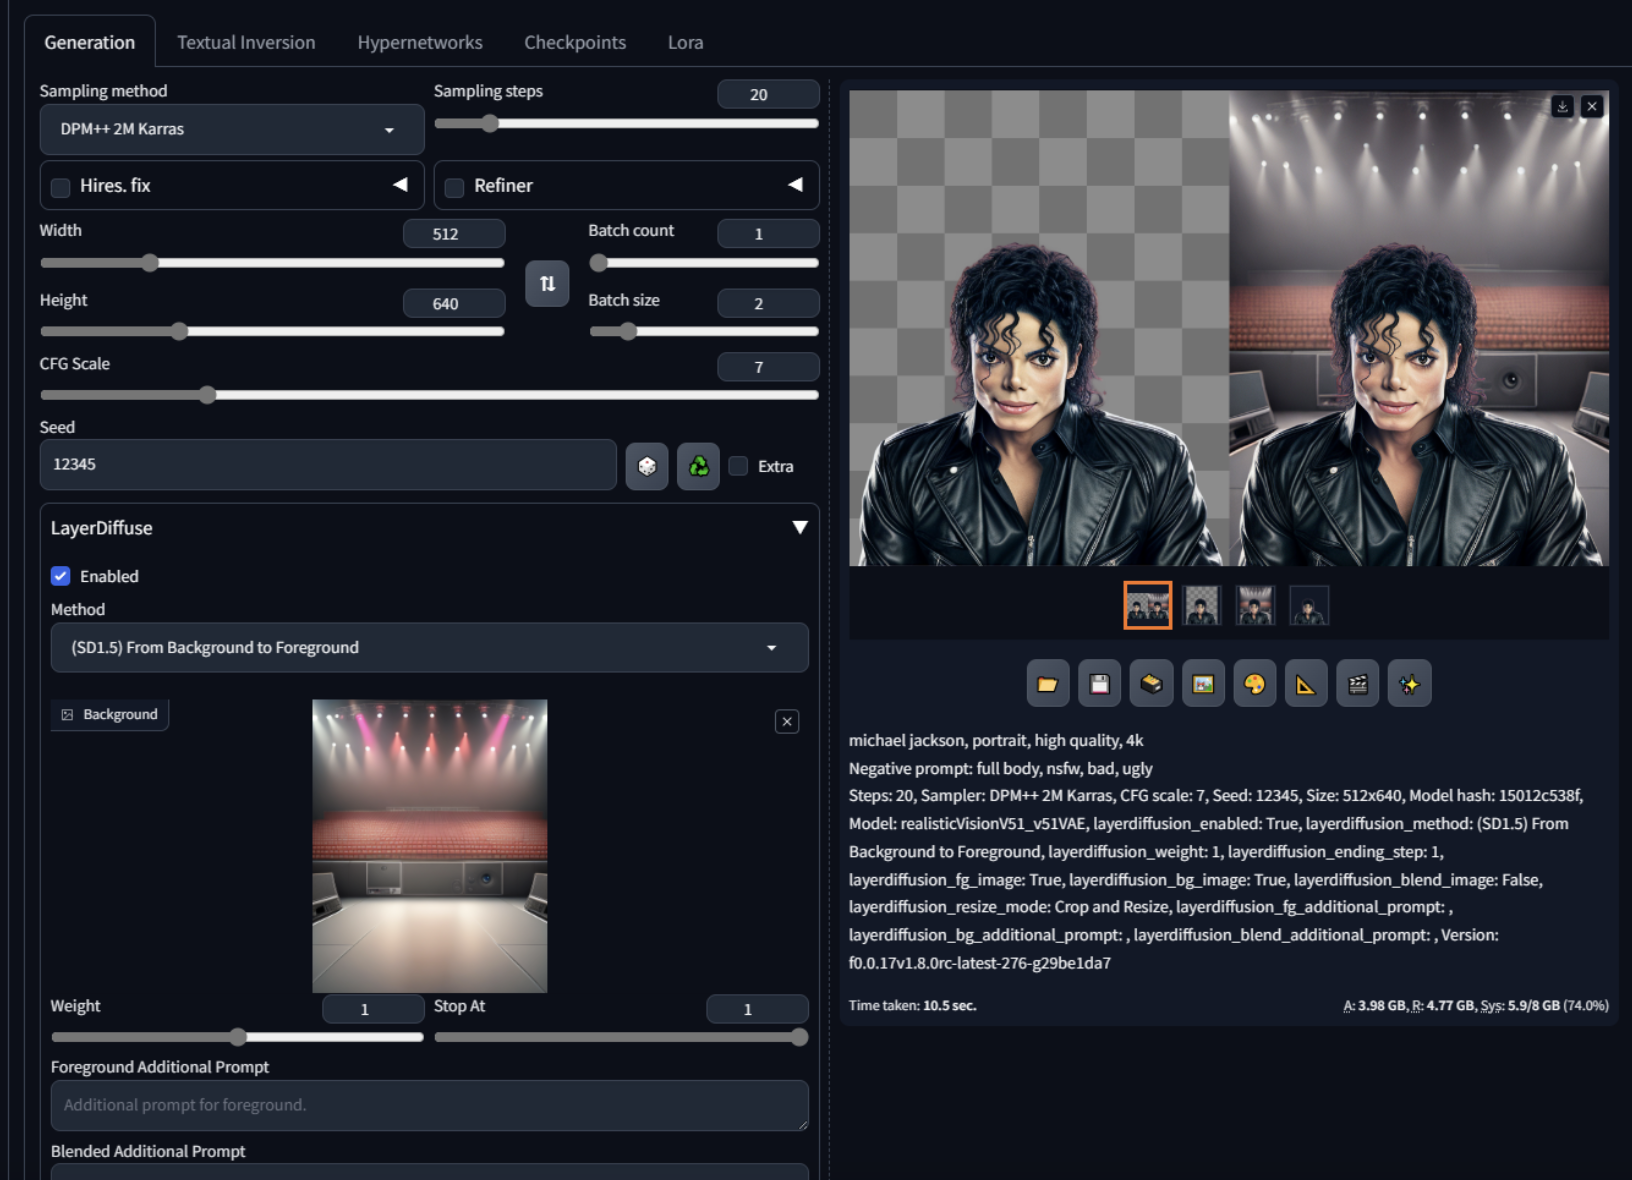
- Transparent Image Layer Diffusion using Latent Transparency
arxiv{Paper} {Code}Powerful PhotoShop cutout replacement!Details
-
MagiCapture: High-Resolution Multi-Concept Portrait Customization
AAAI2024{Paper} {Code} {Webpage} -
MIGC: Multi-Instance Generation Controller for Text-to-Image Synthesis
CVPR 2024{Paper} {Code} {Webpage} -
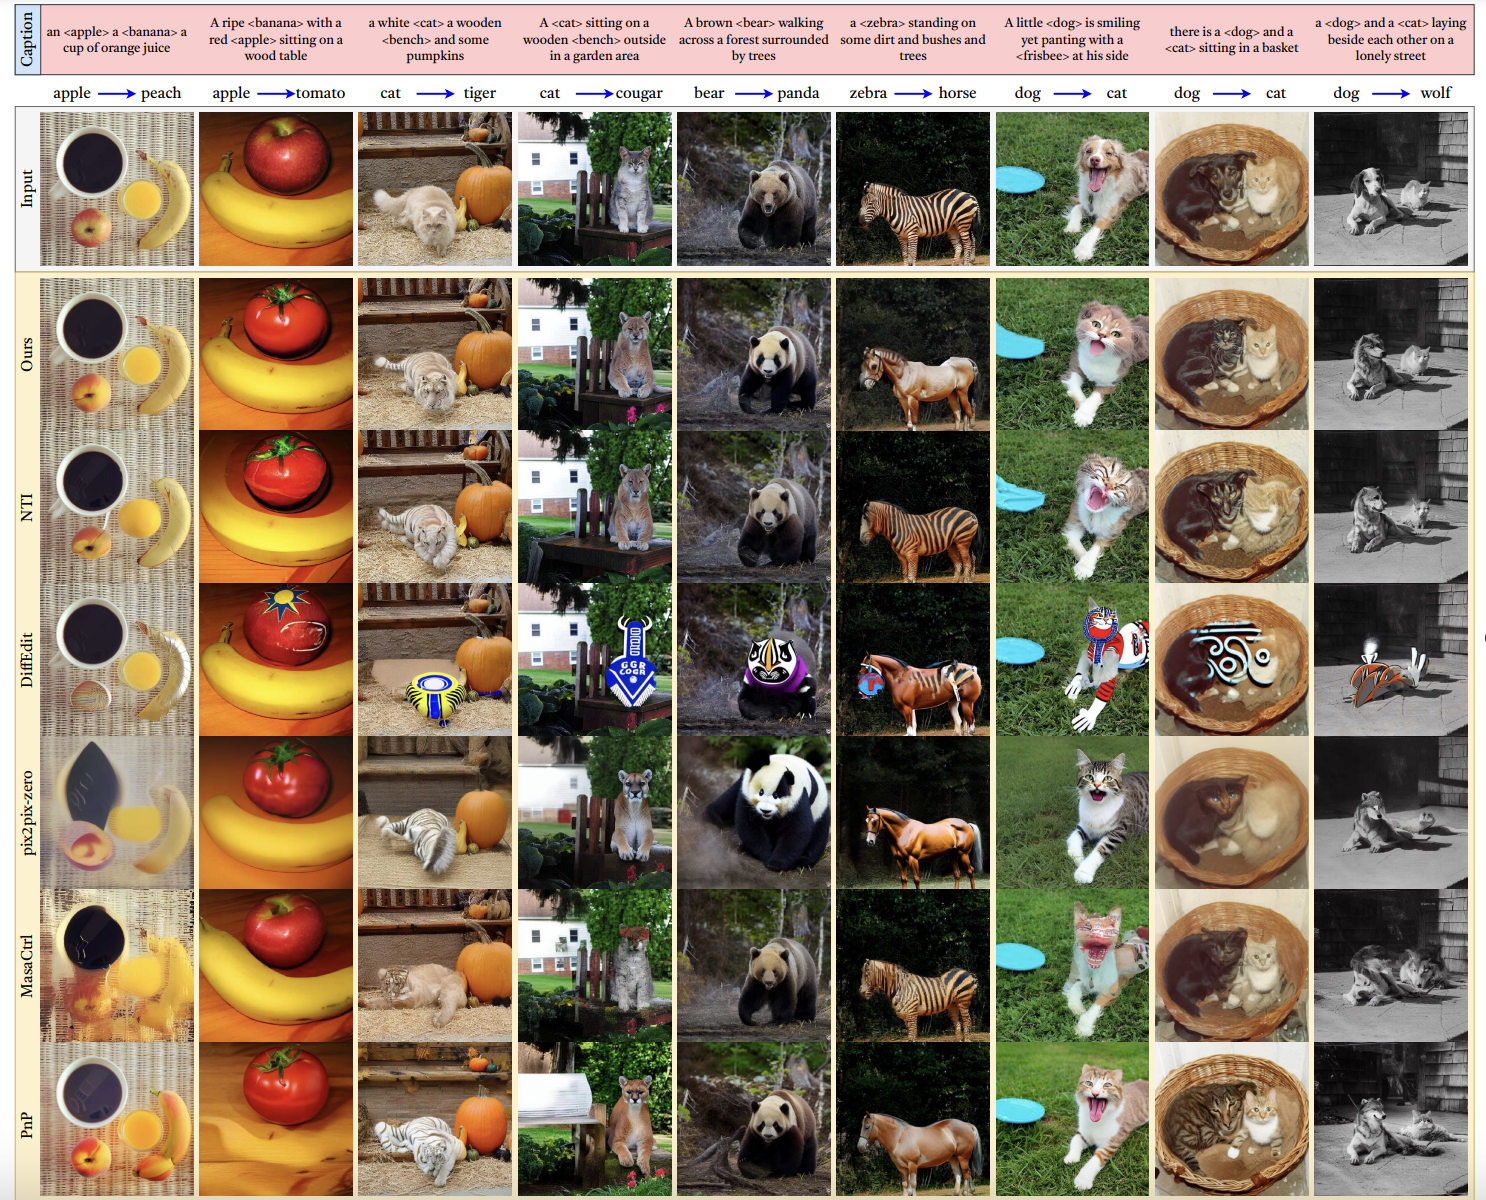
LocInv: Localization-aware Inversion for Text-Guided Image Editing
arxiv{Paper}Details
-
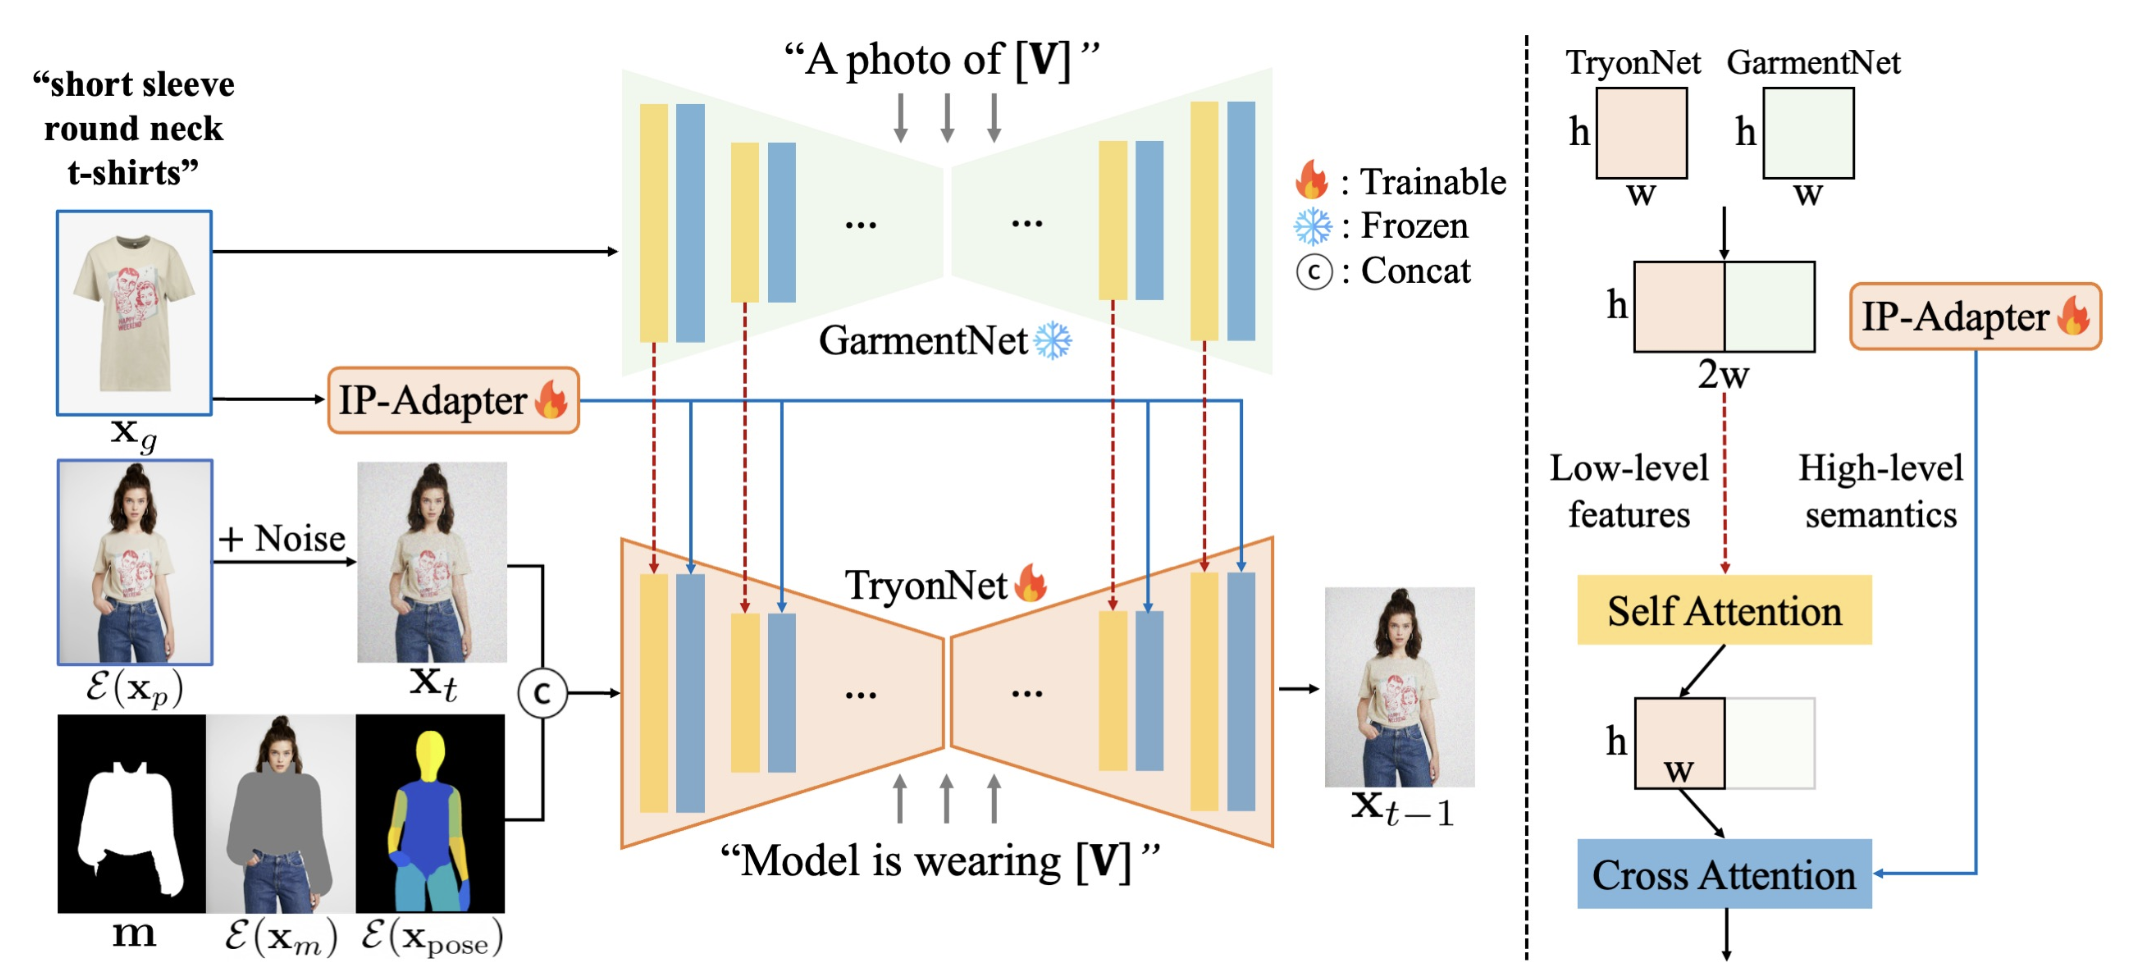
IDM-VTON : Improving Diffusion Models for Authentic Virtual Try-on in the Wild
arxiv{Paper} {Code} {Webpage}Details
-
Diffree: Text-Guided Shape Free Object Inpainting with Diffusion Model
arxiv{Paper} {Code} {Webpage} -
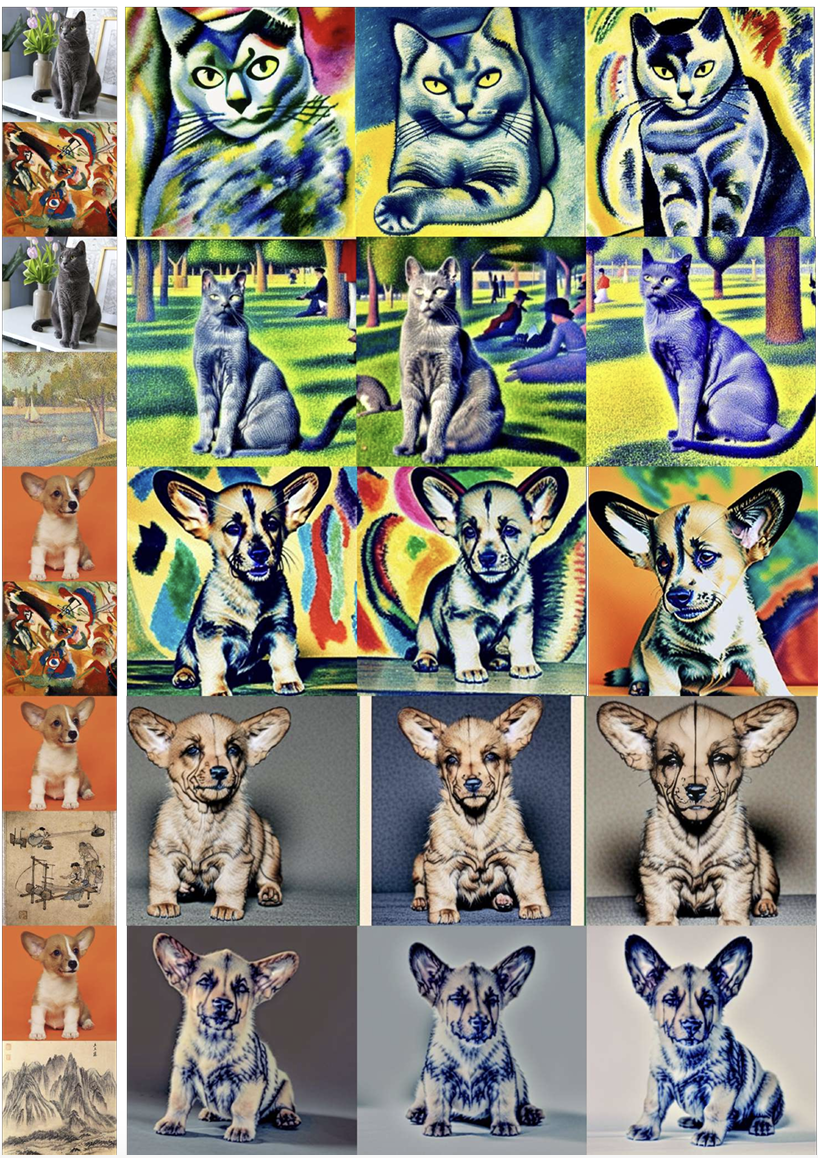
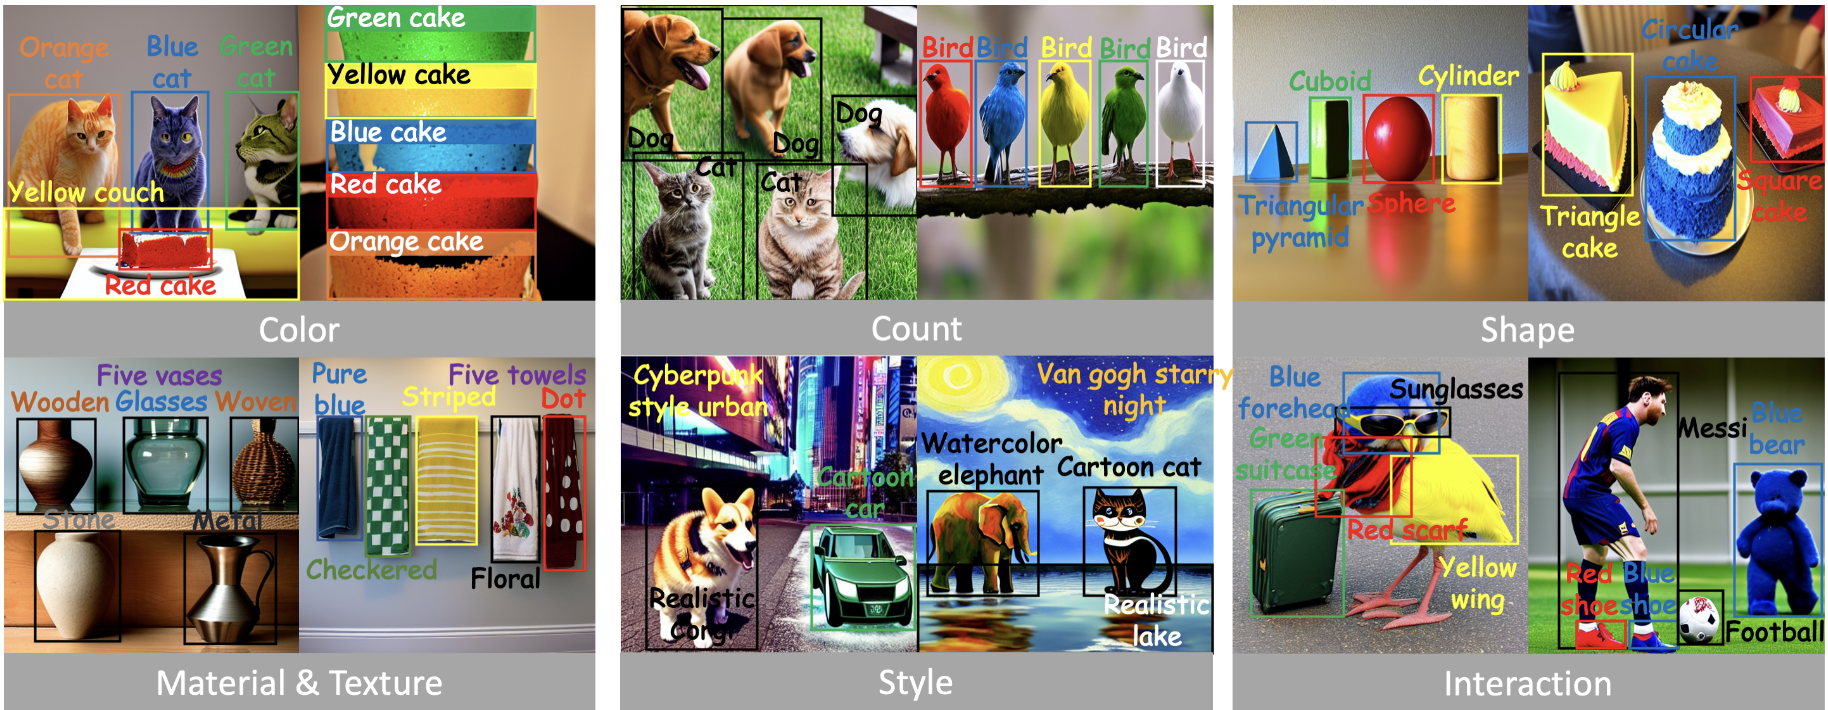
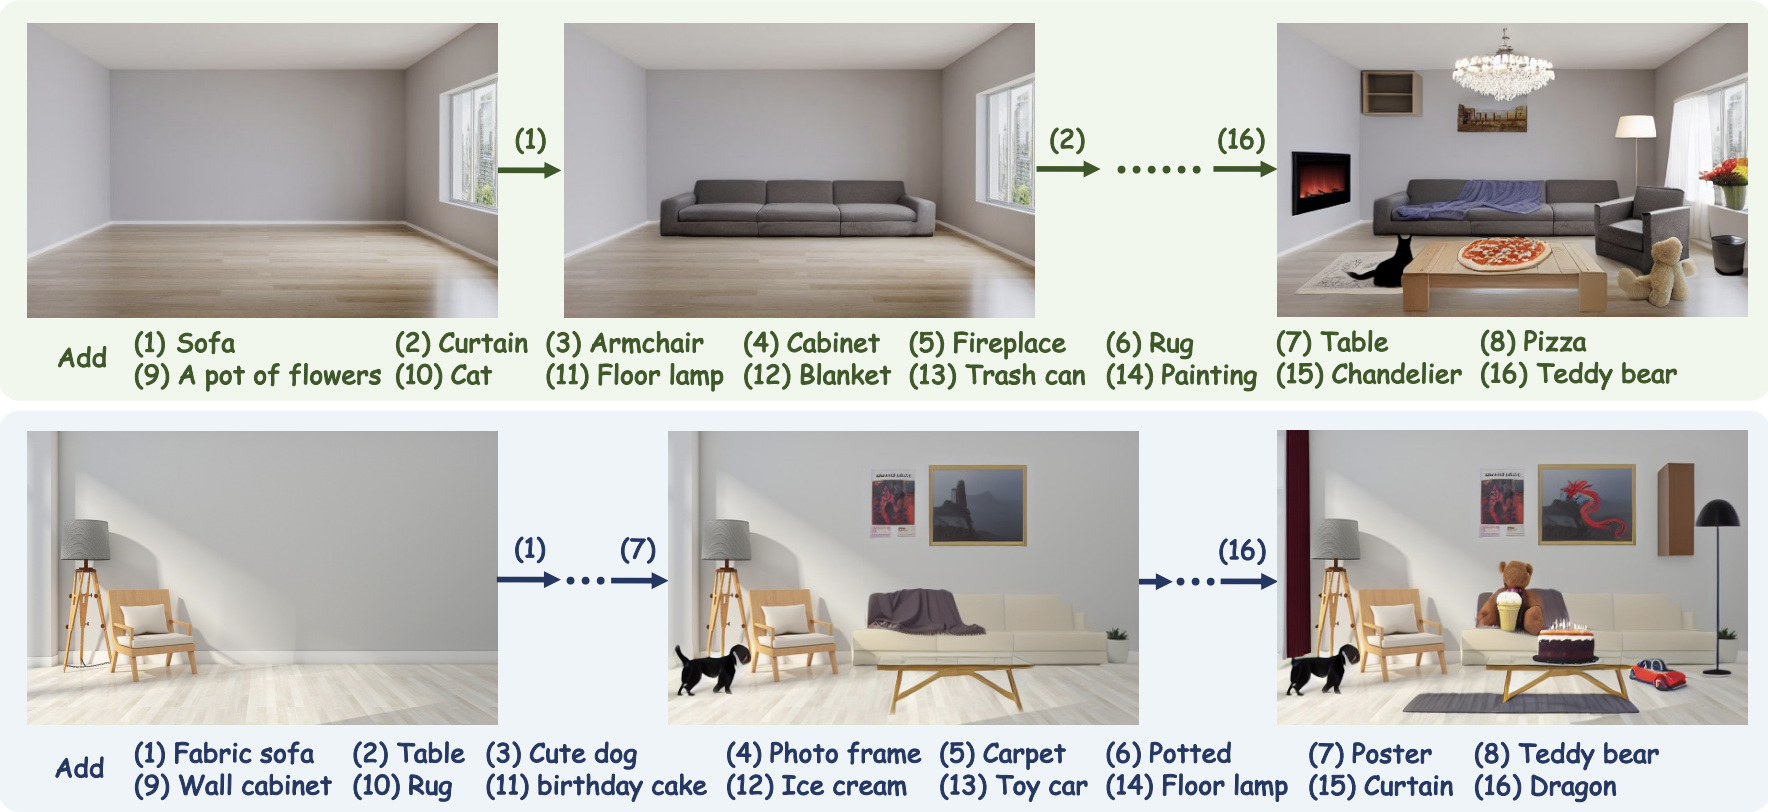
DRAGTEXT: Rethinking Text Embedding in Point-based Image Editing
arxiv{Paper}Details

2023
-
Drag Your GAN: Interactive Point-based Manipulation on the Generative Image Manifold
SIGGRAPH 2023{Paper} {Code} {Webpage}Interactive manipulation of the generative image manifold!Details

-
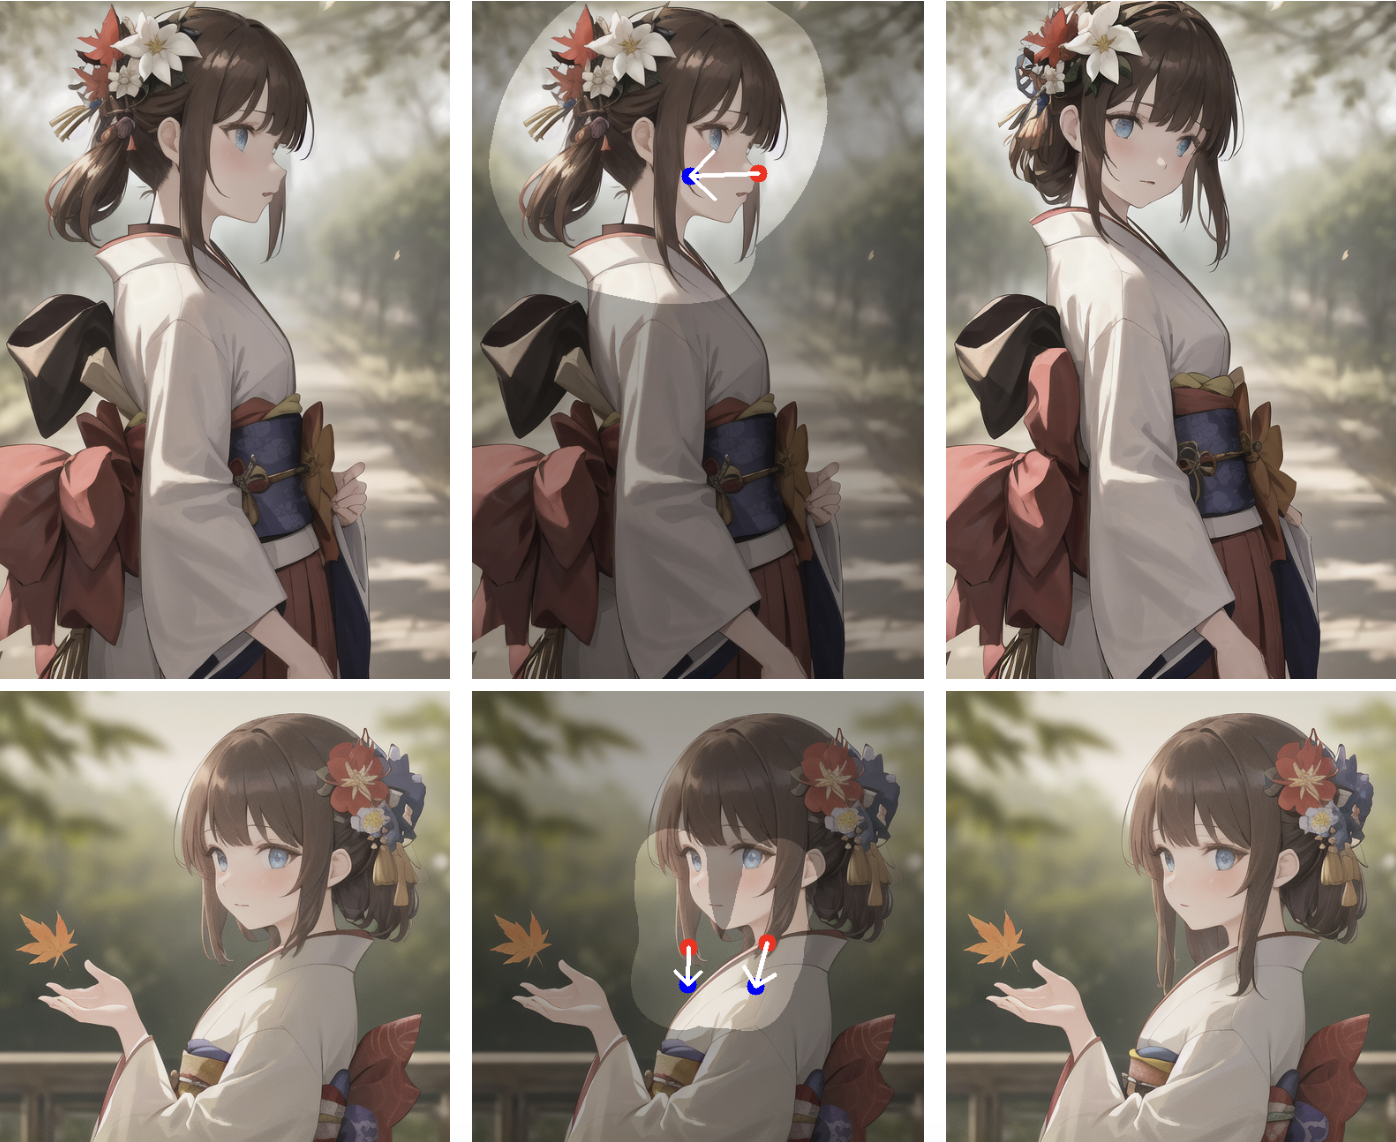
DragDiffusion: Harnessing Diffusion Models for Interactive Point-based Image Editing
CVPR 2024{Paper} {Code} {Webpage}Details
-
Expressive Text-to-Image Generation with Rich Text
ICCV 2023{Paper} {Code} {Webpage}Details

Customized 2D Text-to-Image
Text-guided Portrait Generation
2024
-
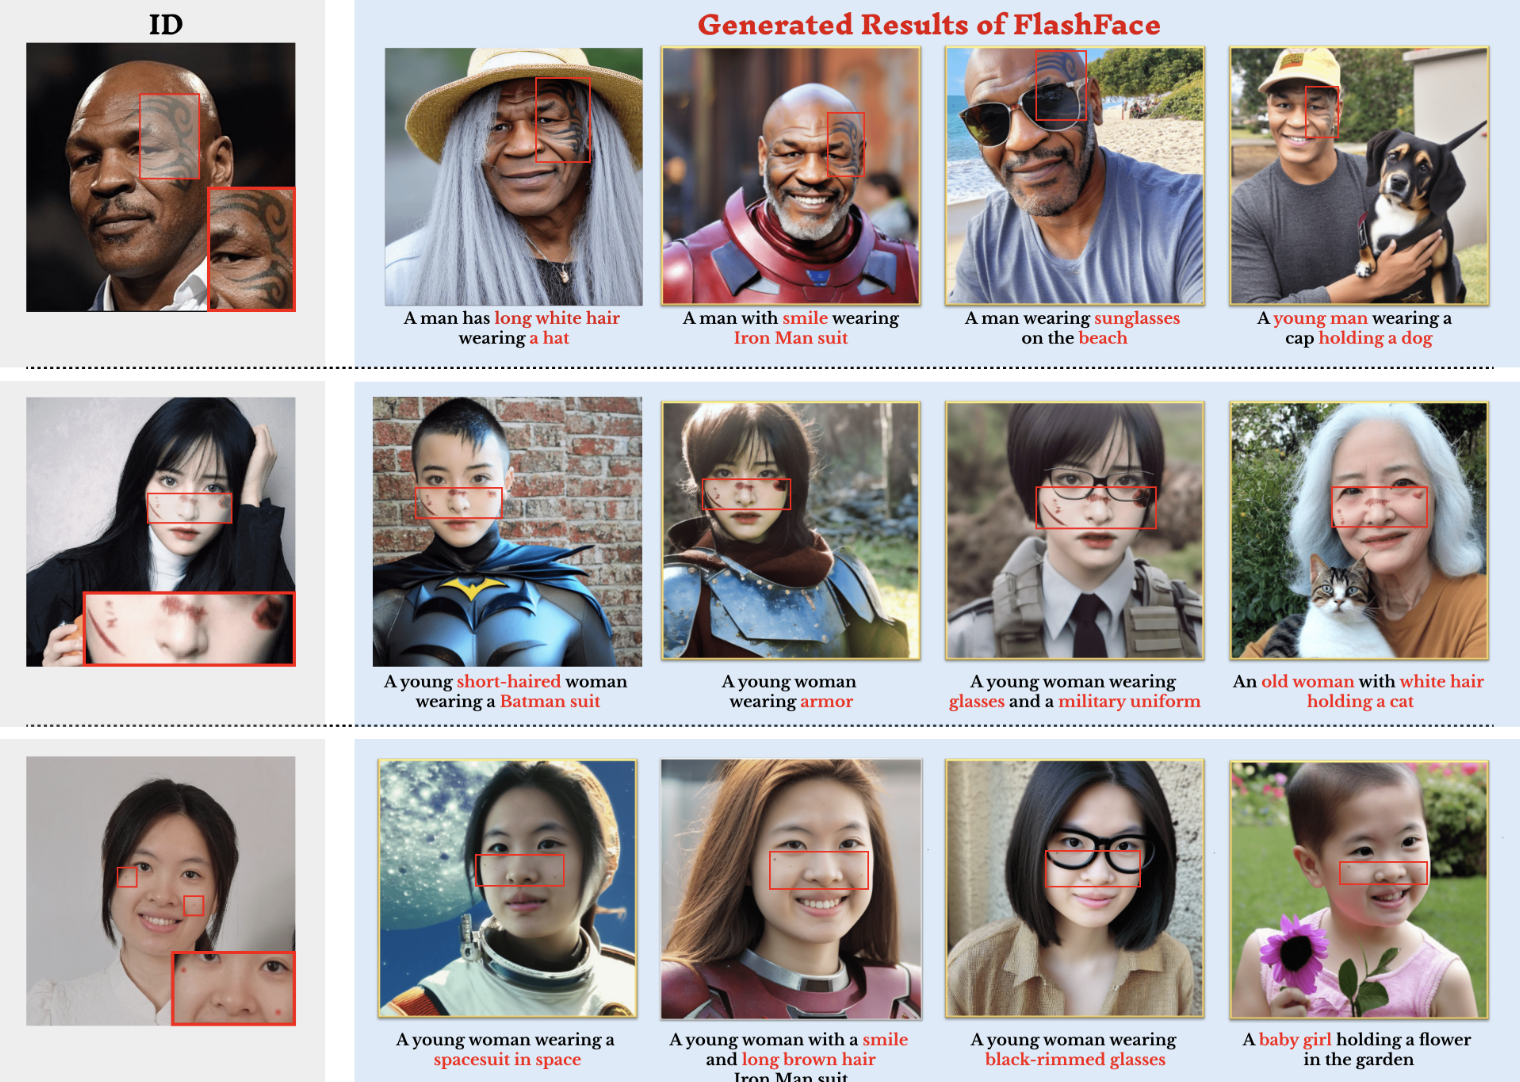
FlashFace: Human Image Personalization with High-fidelity Identity Preservation
arxiv{Paper} {Code} {Webpage}Details
-
Pick-and-Draw: Training-free Semantic Guidance for Text-to-Image Personalization
arxiv{Paper}Details
-
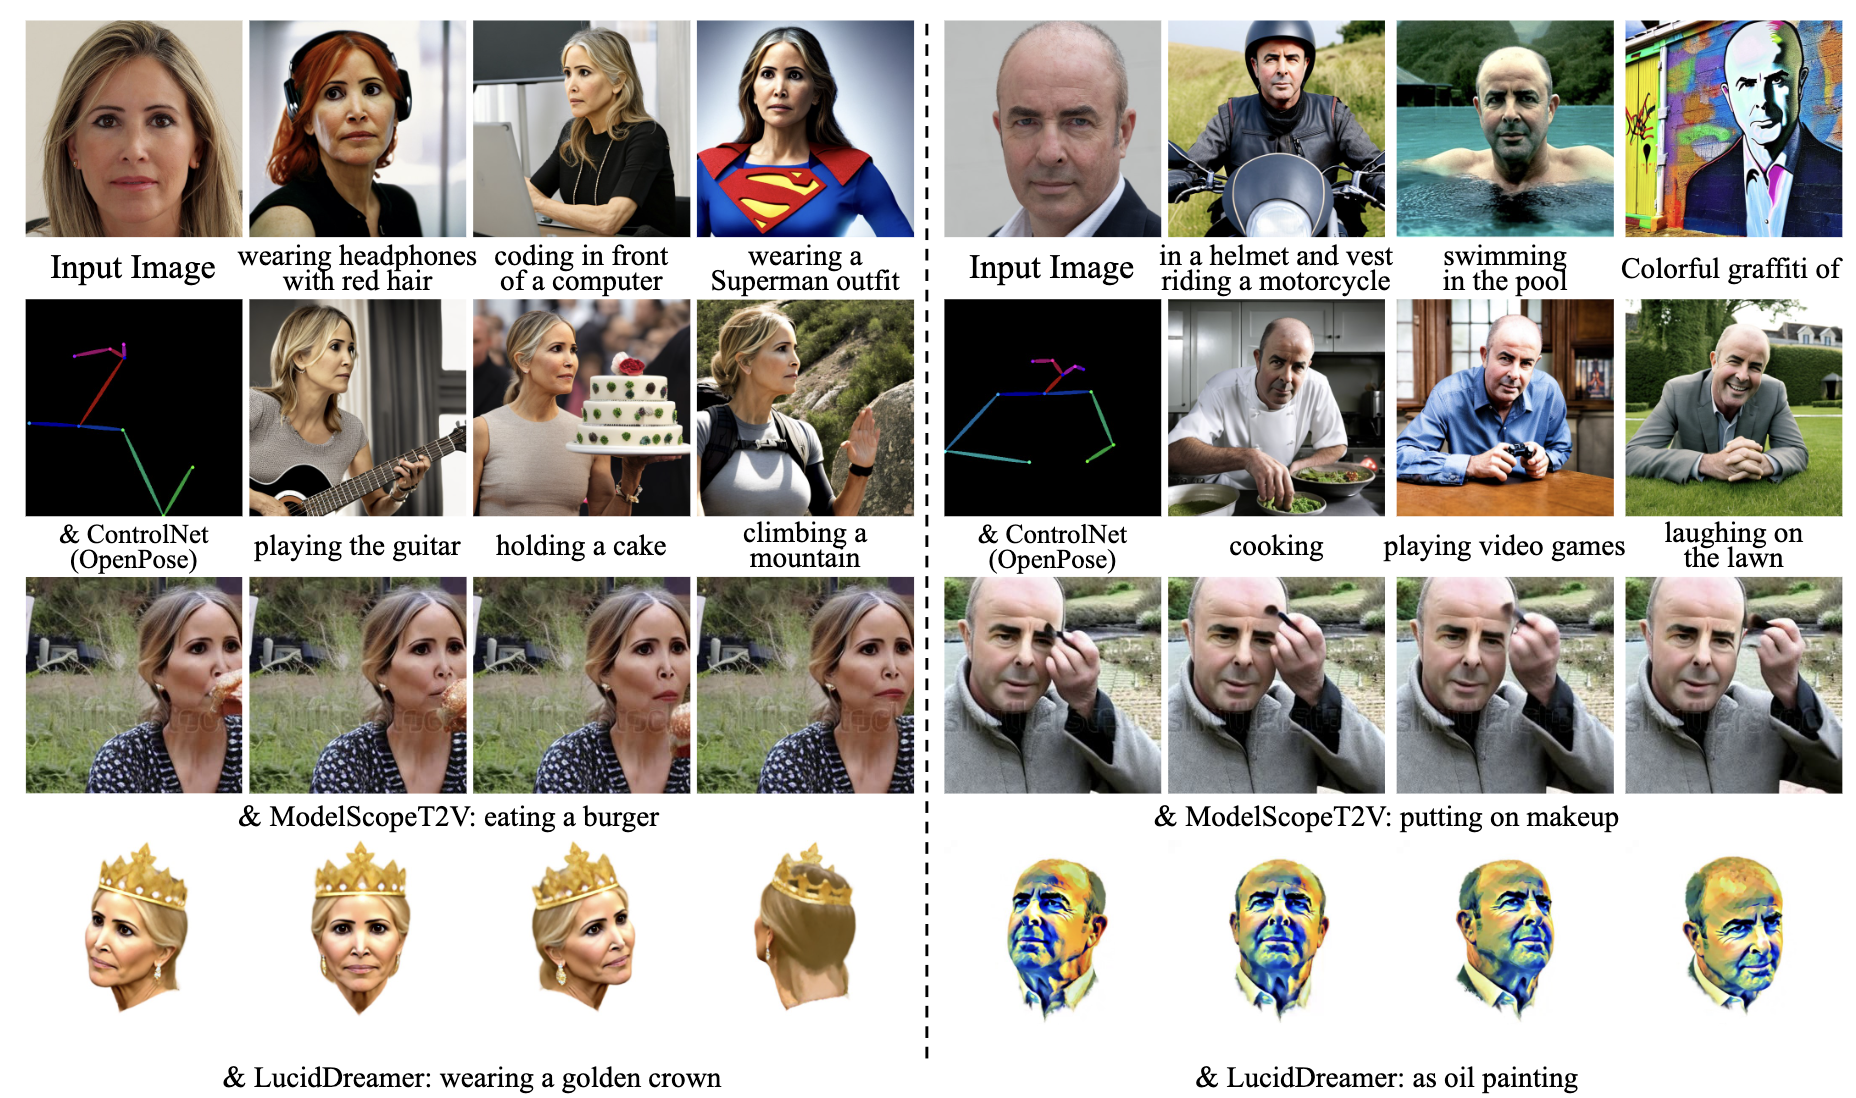
StableIdentity: Inserting Anybody into Anywhere at First Sight
arxiv{Paper} {Code} {Webpage}
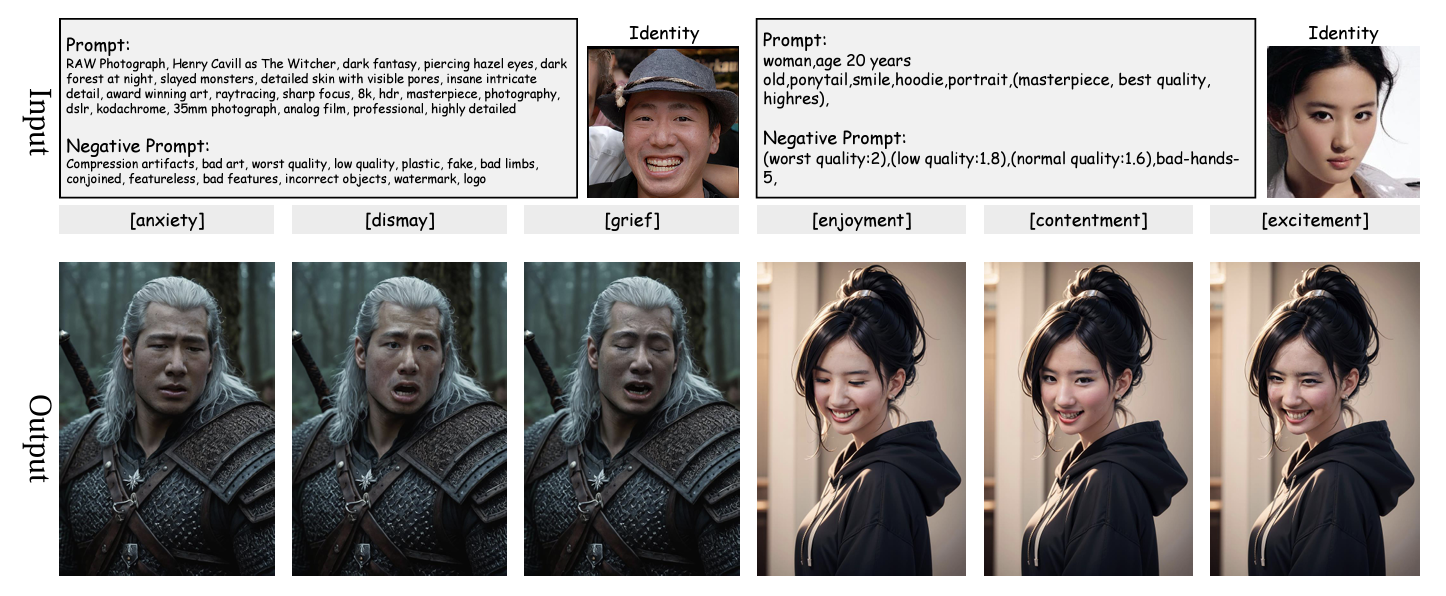
- Towards a Simultaneous and Granular Identity-Expression Control in Personalized Face Generation
arxiv{Paper}Details
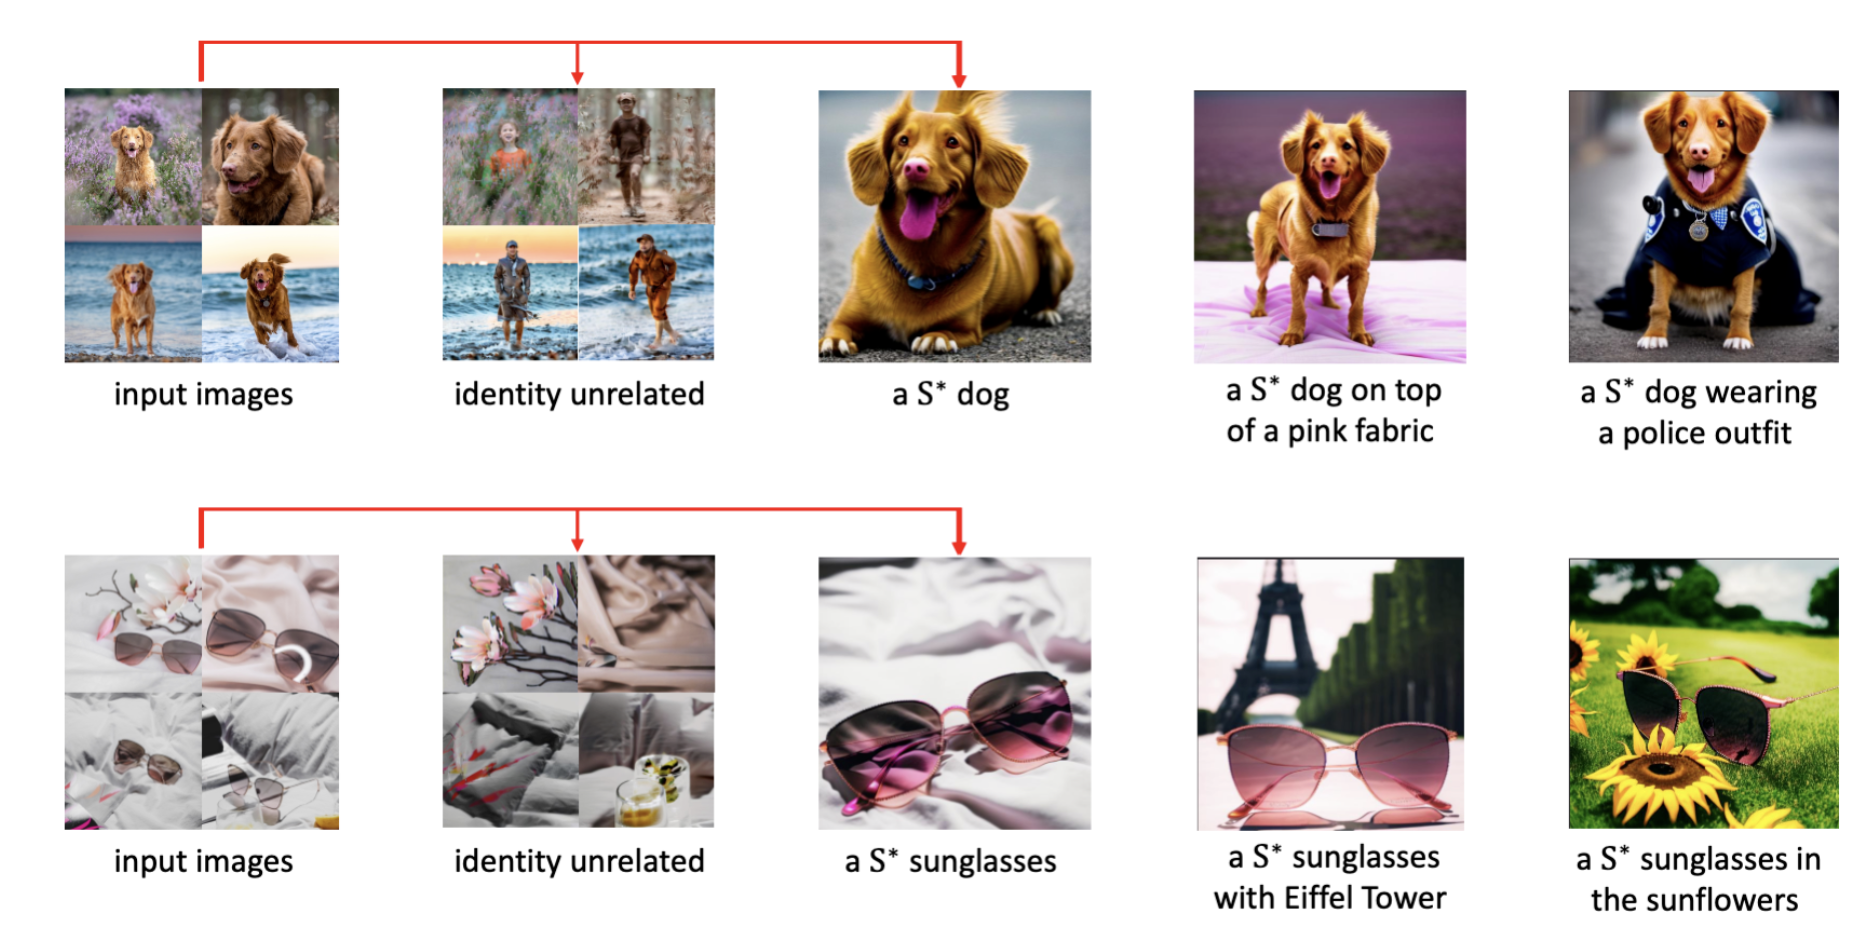
- DisenBooth: Identity-Preserving Disentangled Tuning for Subject-Driven Text-to-Image Generation
ICLR2024{Paper} {Code} {Webpage}Details
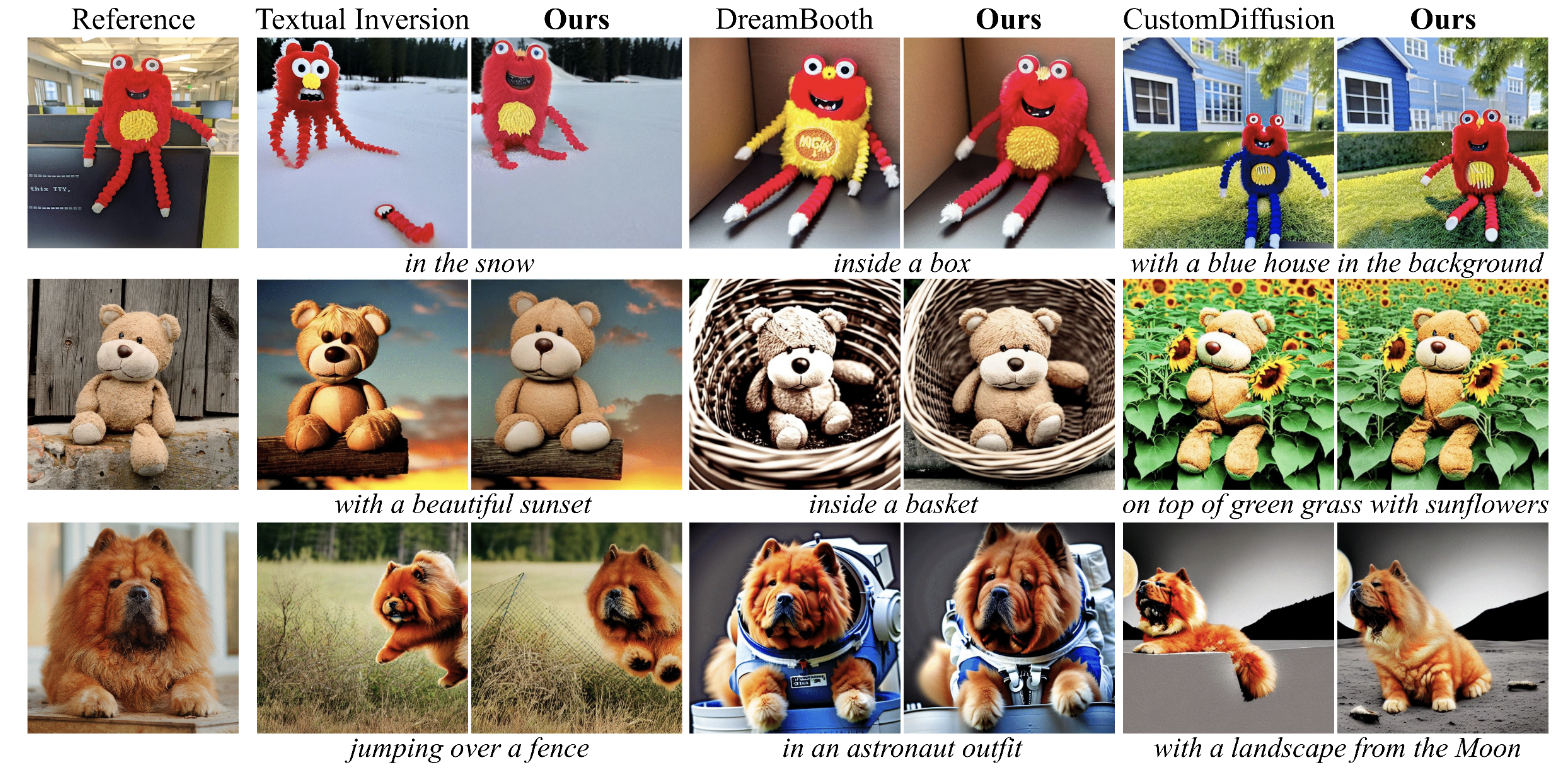
- DreamMatcher: Appearance Matching Self-Attention
for Semantically-Consistent Text-to-Image Personalization
CVPR2024{Paper} {Code} {Webpage}Details
-
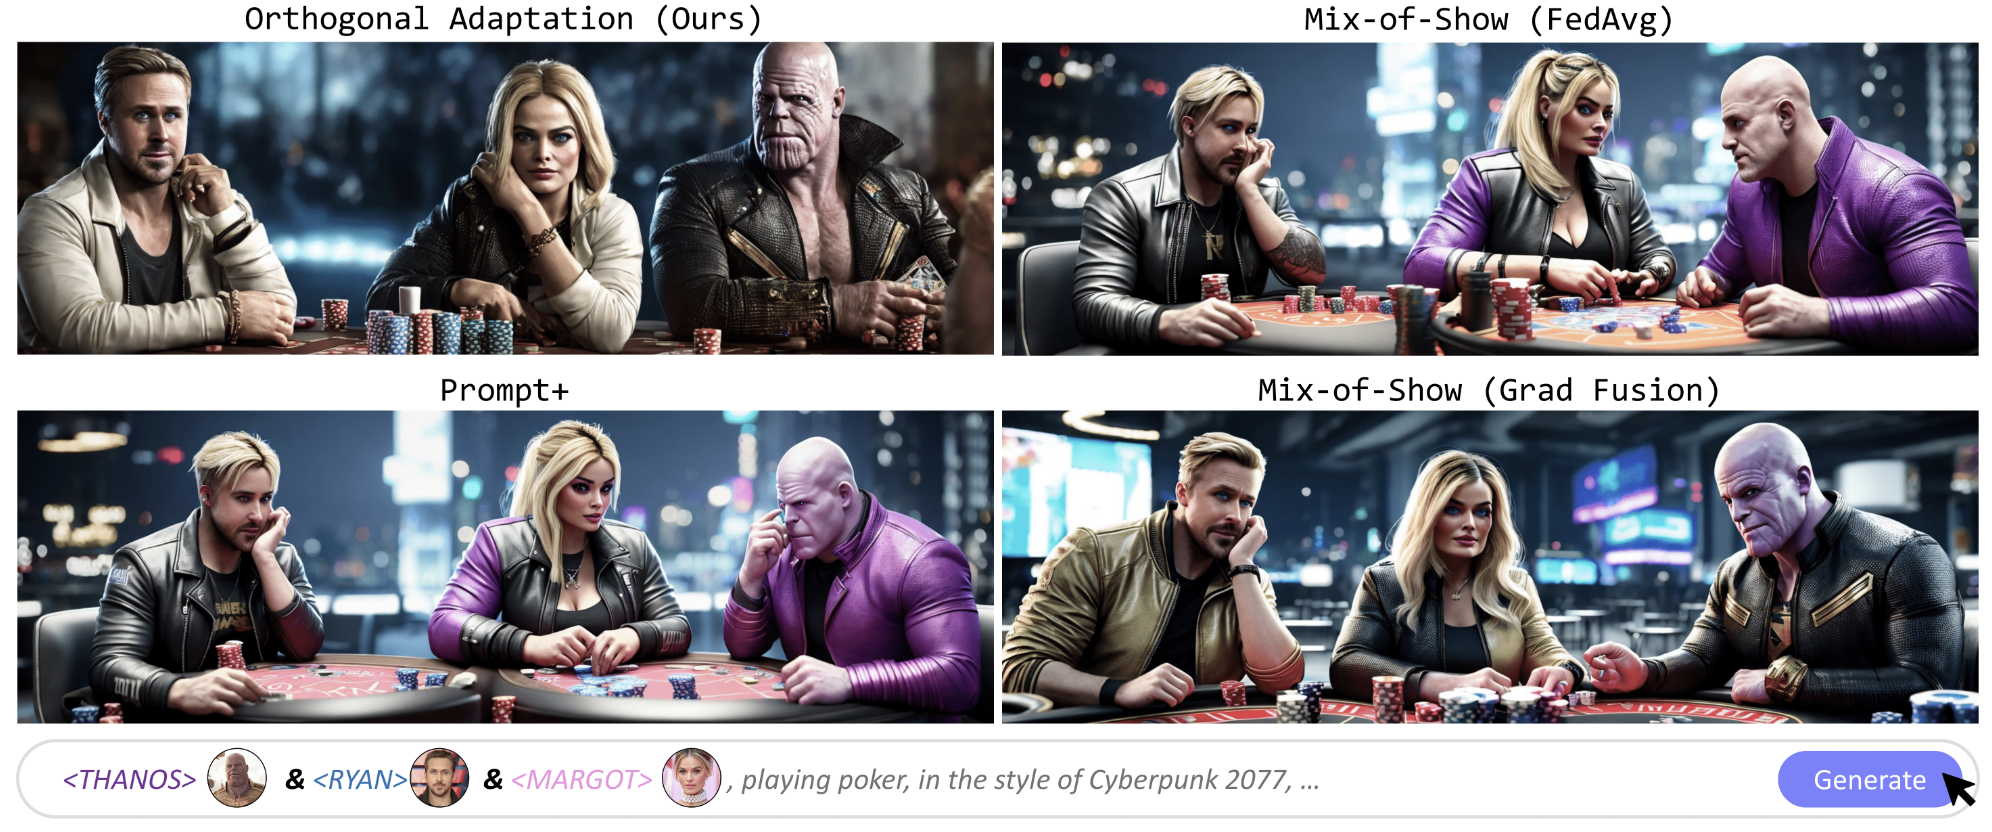
Orthogonal Adaptation for Modular Customization of Diffusion Models
CVPR2024{Paper} {Webpage} -
High-fidelity Person-centric Subject-to-Image Synthesis
CVPR 2024{Paper} {Code} -
Non-confusing Generation of Customized Concepts in Diffusion Models
ICML 2024{Paper} {Code} {Webpage}

2023
-
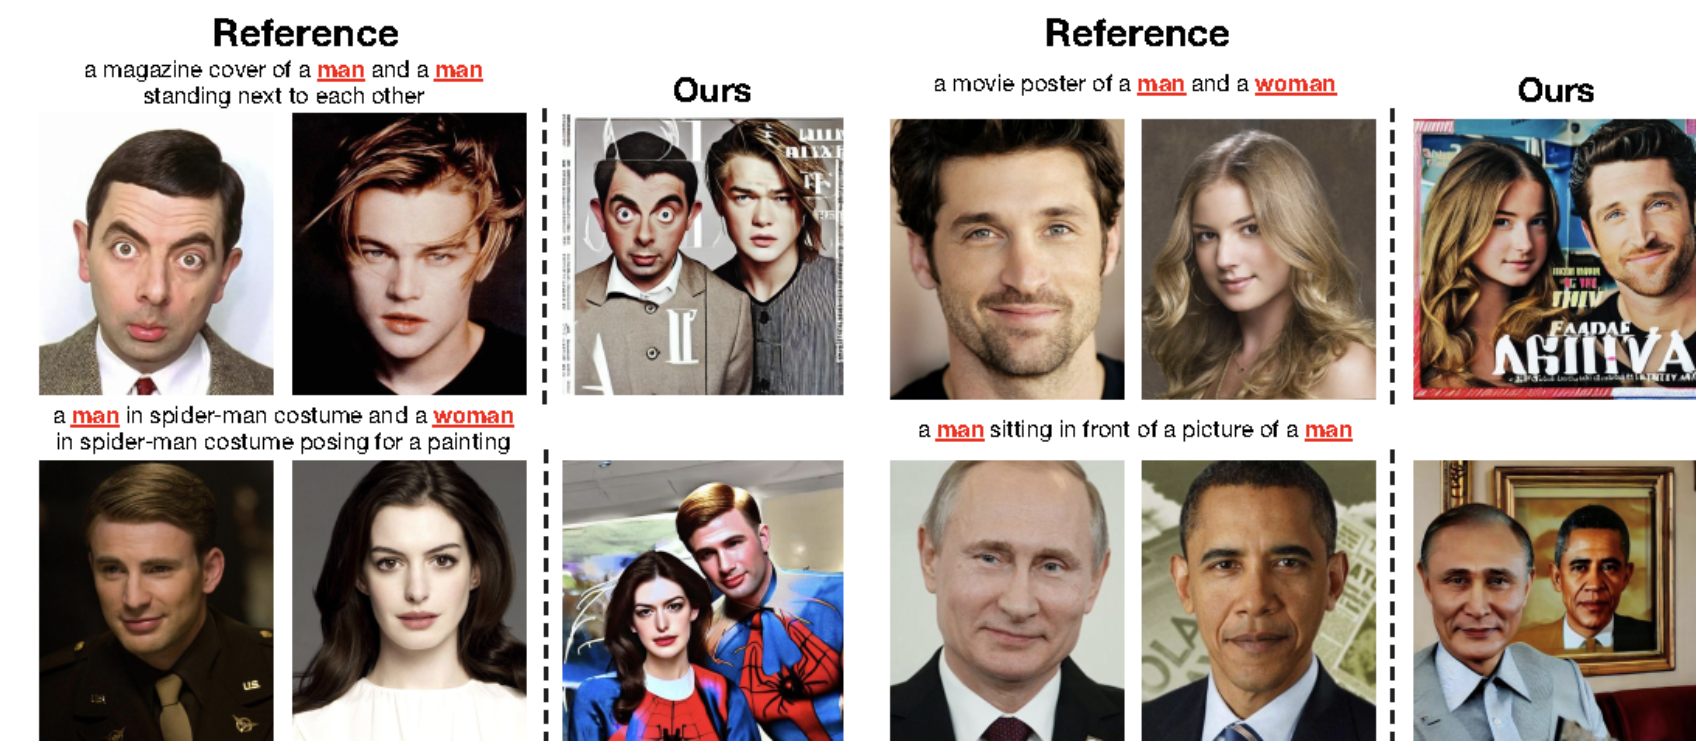
IP-Adapter: Text Compatible Image Prompt Adapter for Text-to-Image Diffusion Models
arxiv{Paper} {Code} {Webpage} -
Real-World Image Variation by Aligning Diffusion Inversion Chain
NeurIPS2023{Paper} {Code} {Webpage} -
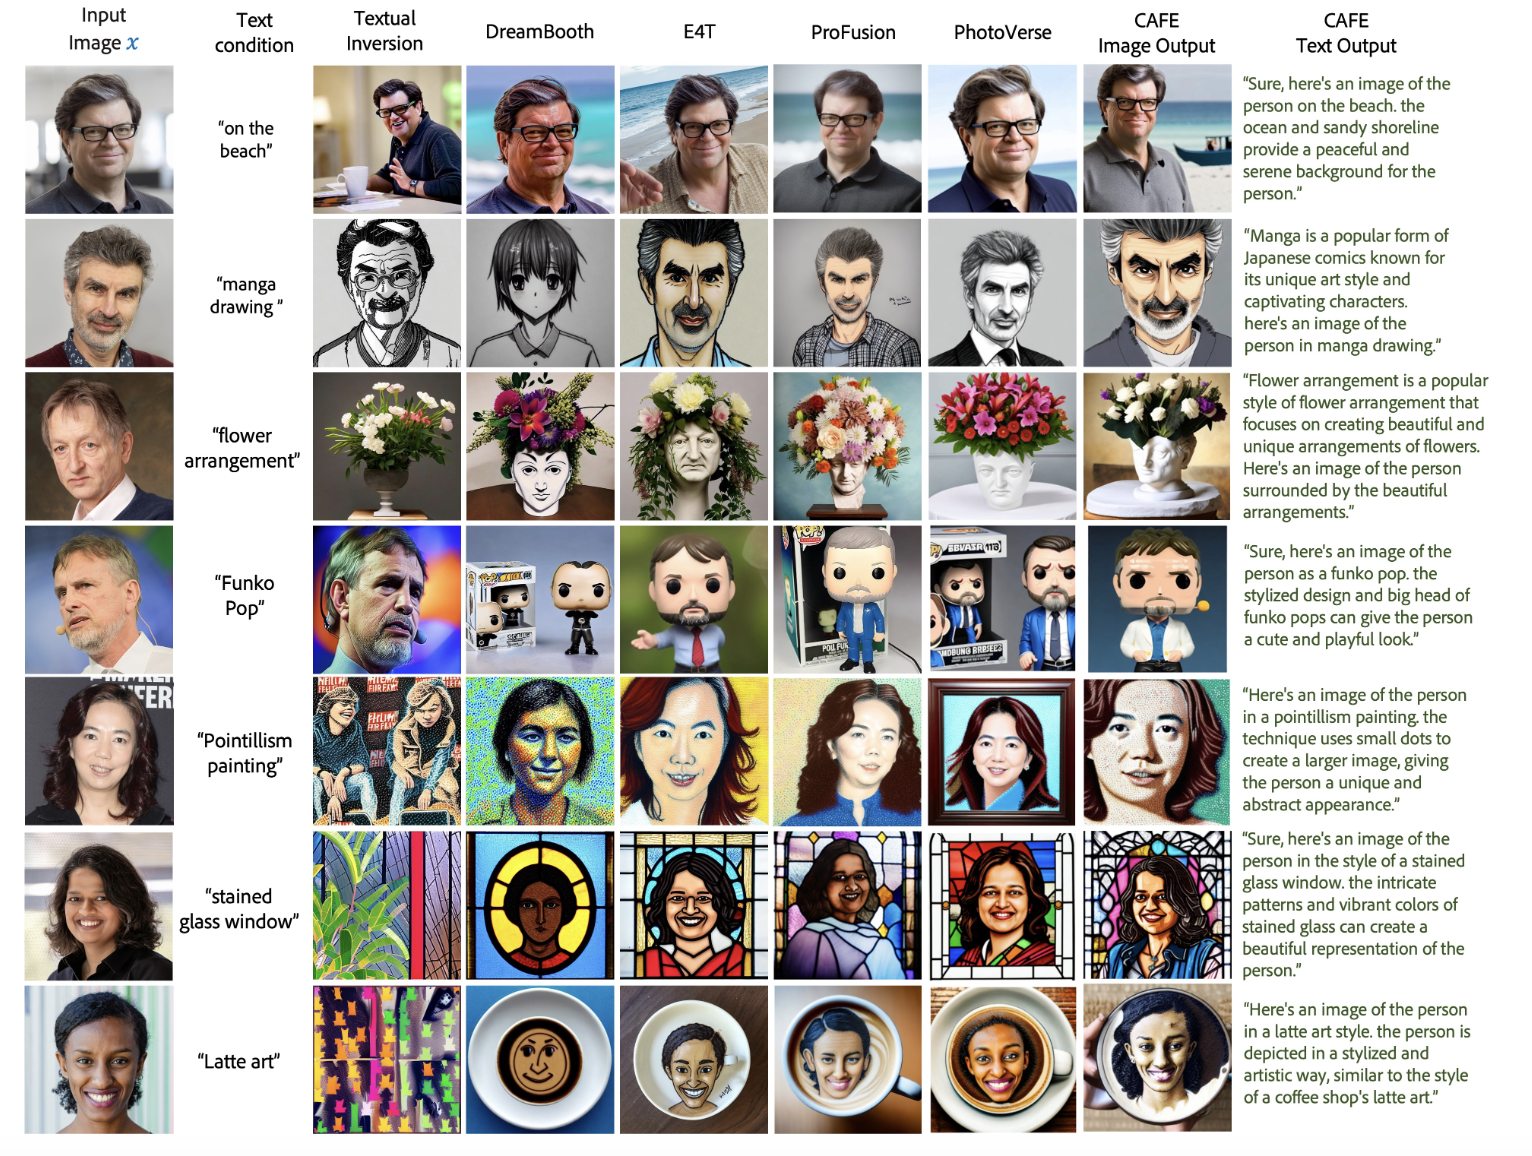
Customization Assistant for Text-to-image Generation
arxiv{Paper} {Code}Details
-
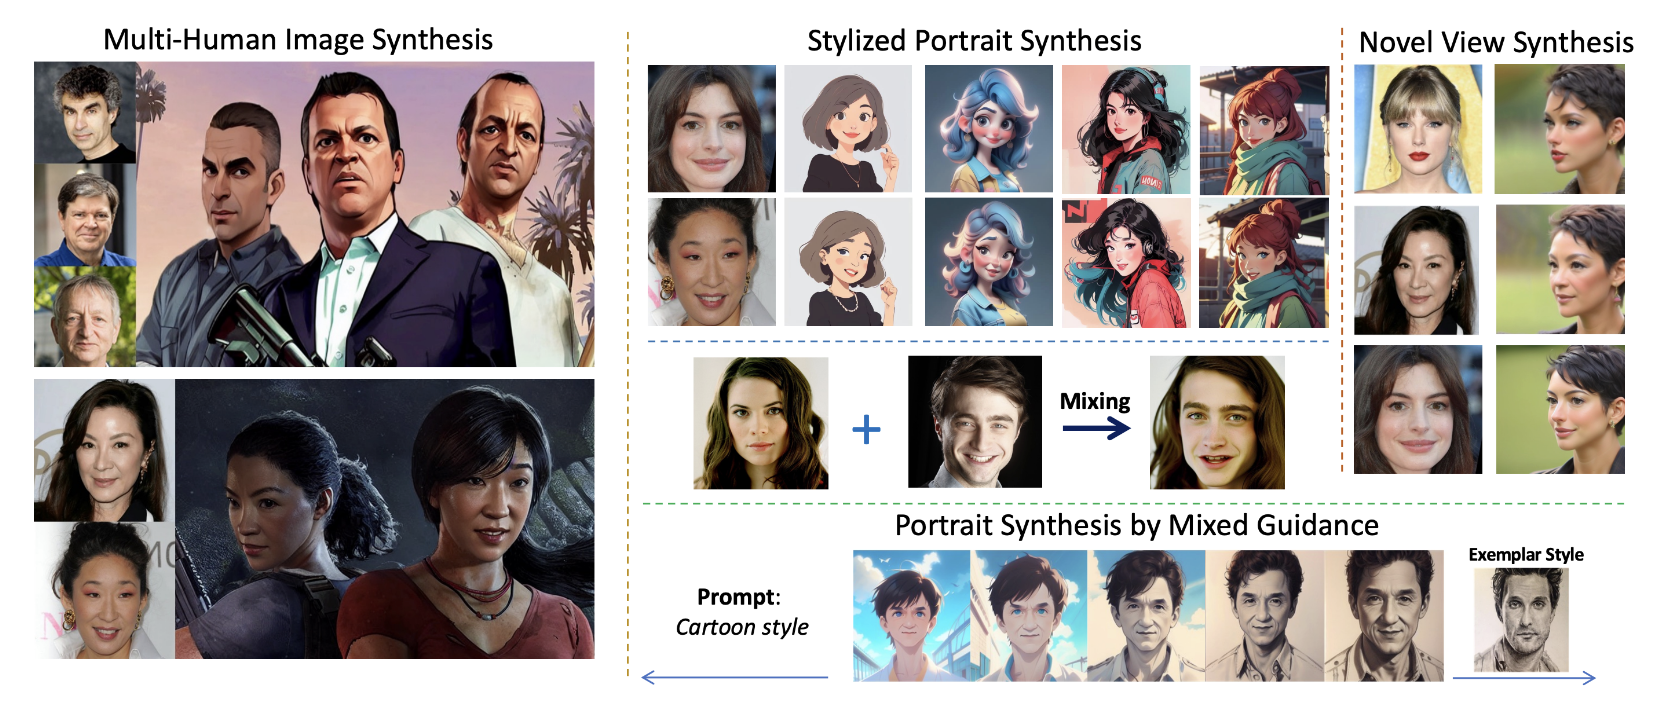
FaceStudio: Put Your Face Everywhere in Seconds
arxiv{Paper} {Code} {Webpage}Details
-
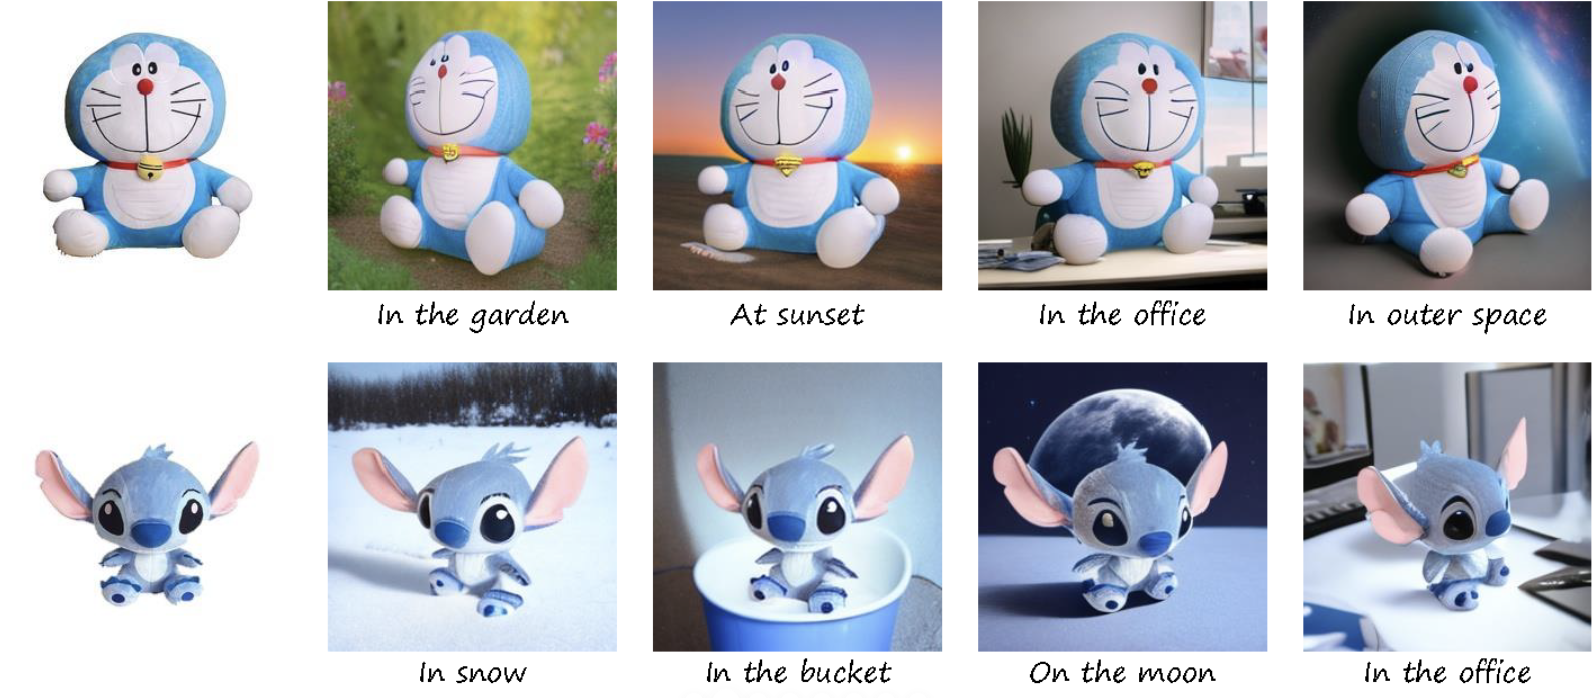
CustomNet: Zero-shot Object Customization with Variable-Viewpoints in Text-to-Image Diffusion Models
arxiv{Paper} {Code} {Webpage}Details
-
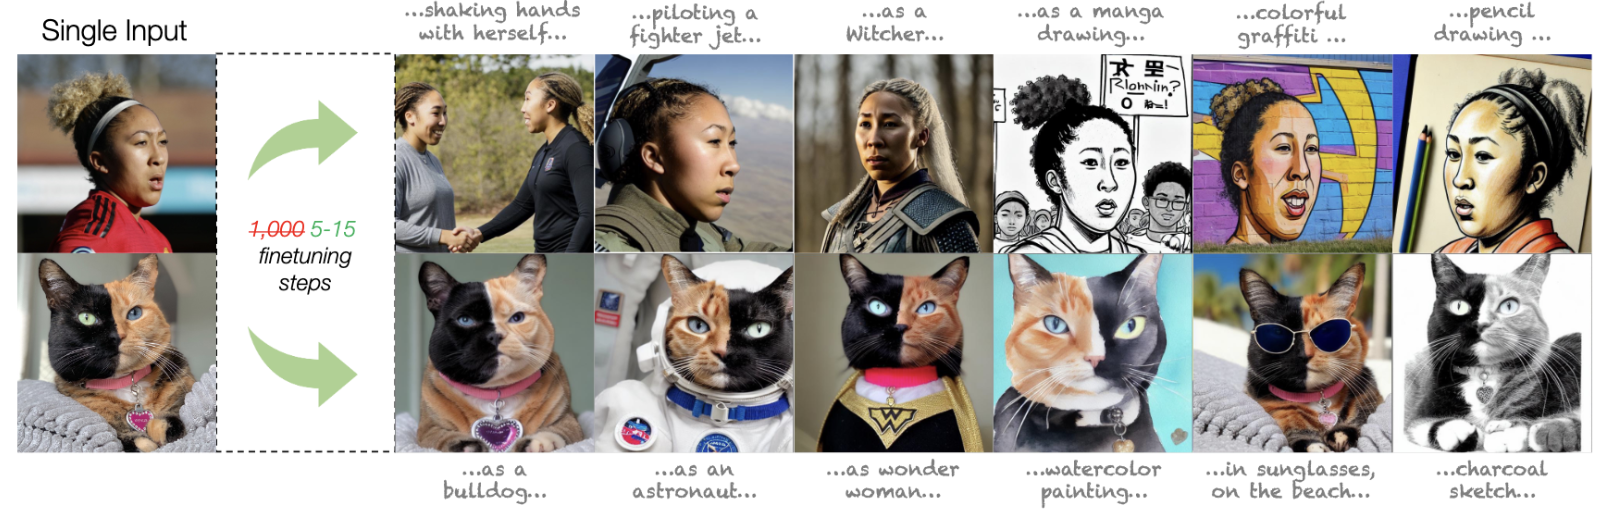
Encoder-based Domain Tuning for Fast Personalization of Text-to-Image Models
arxiv{Paper} {Code}Details
-
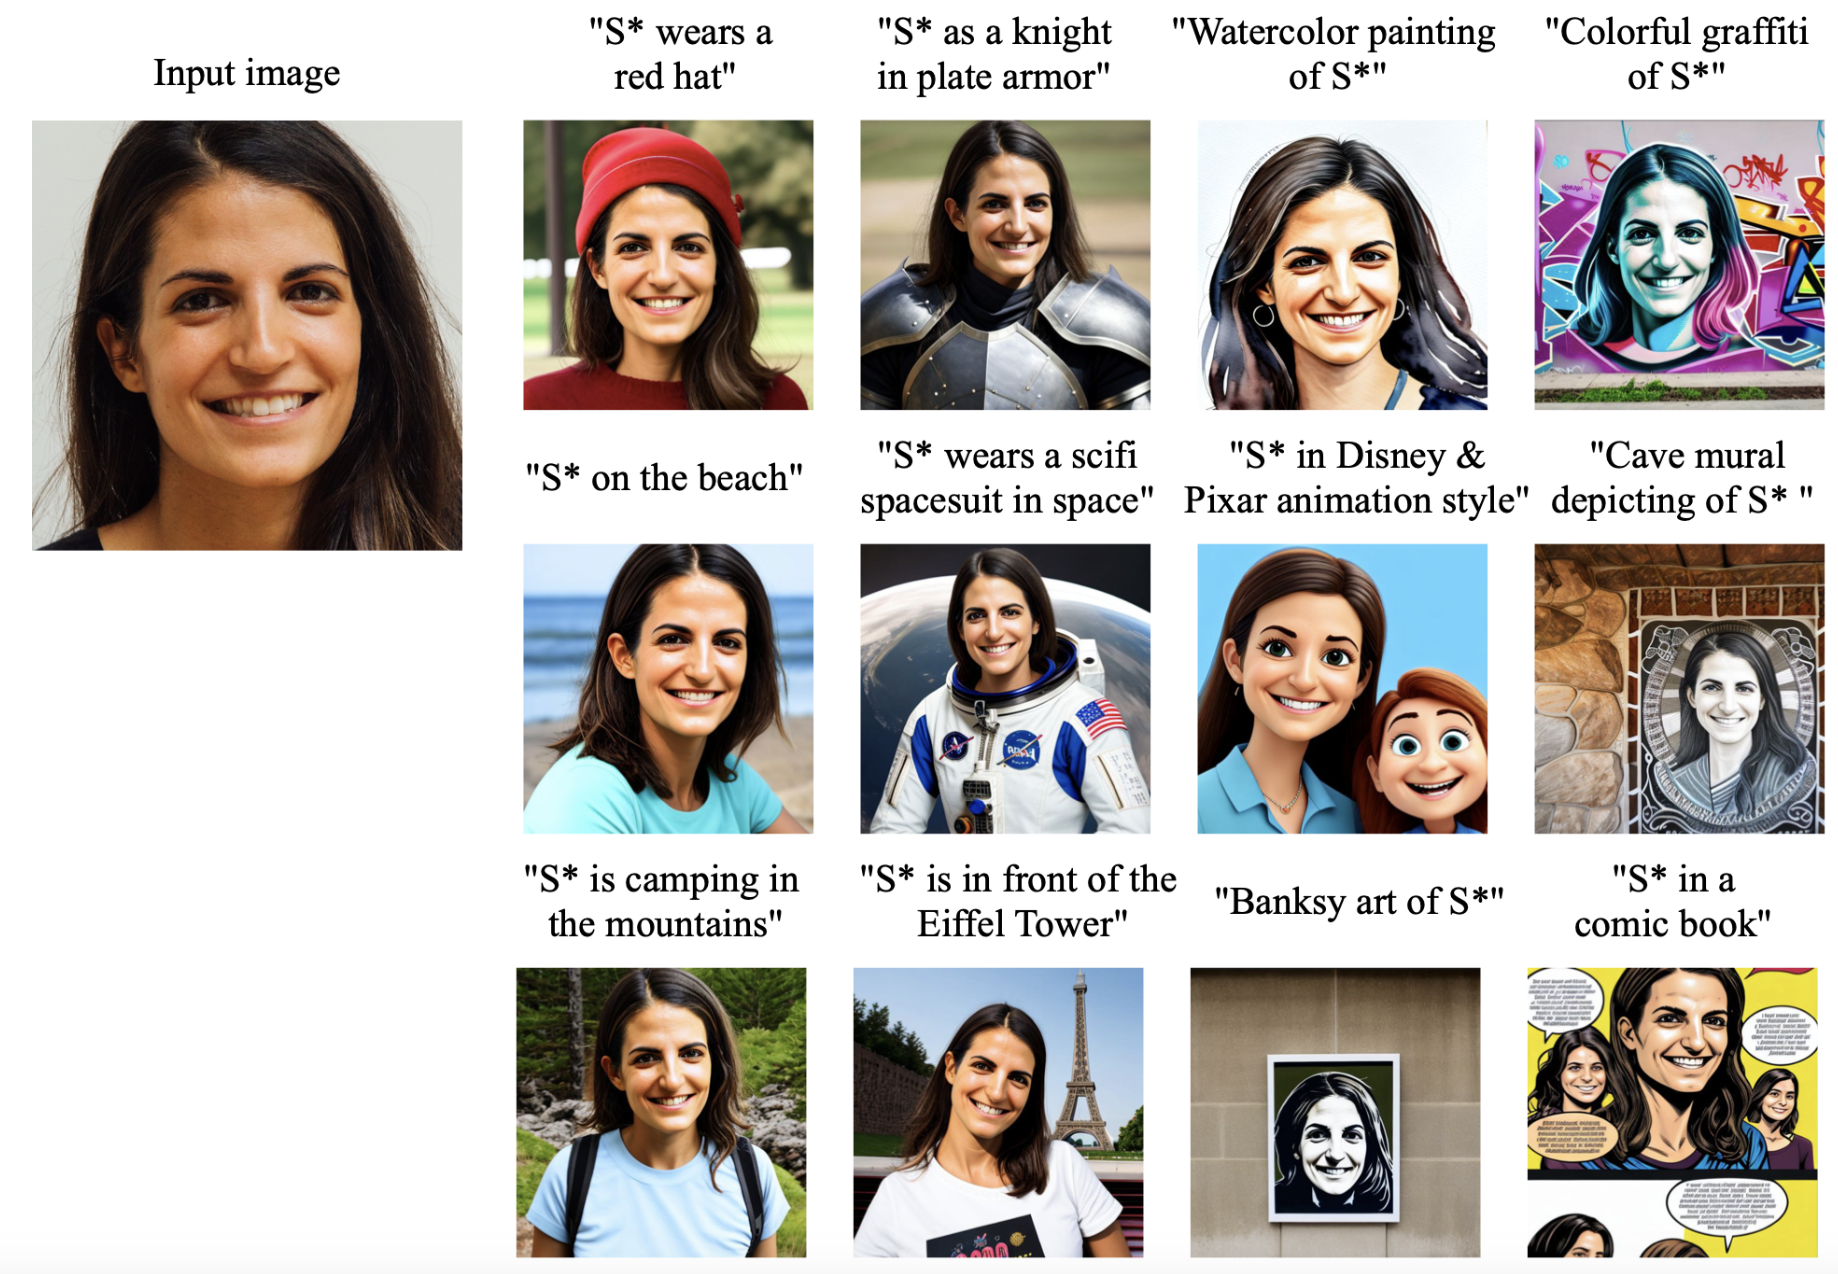
PhotoVerse: Tuning-Free Image Customization with Text-to-Image Diffusion Models
arxiv{Paper} {Webpage}Details
-
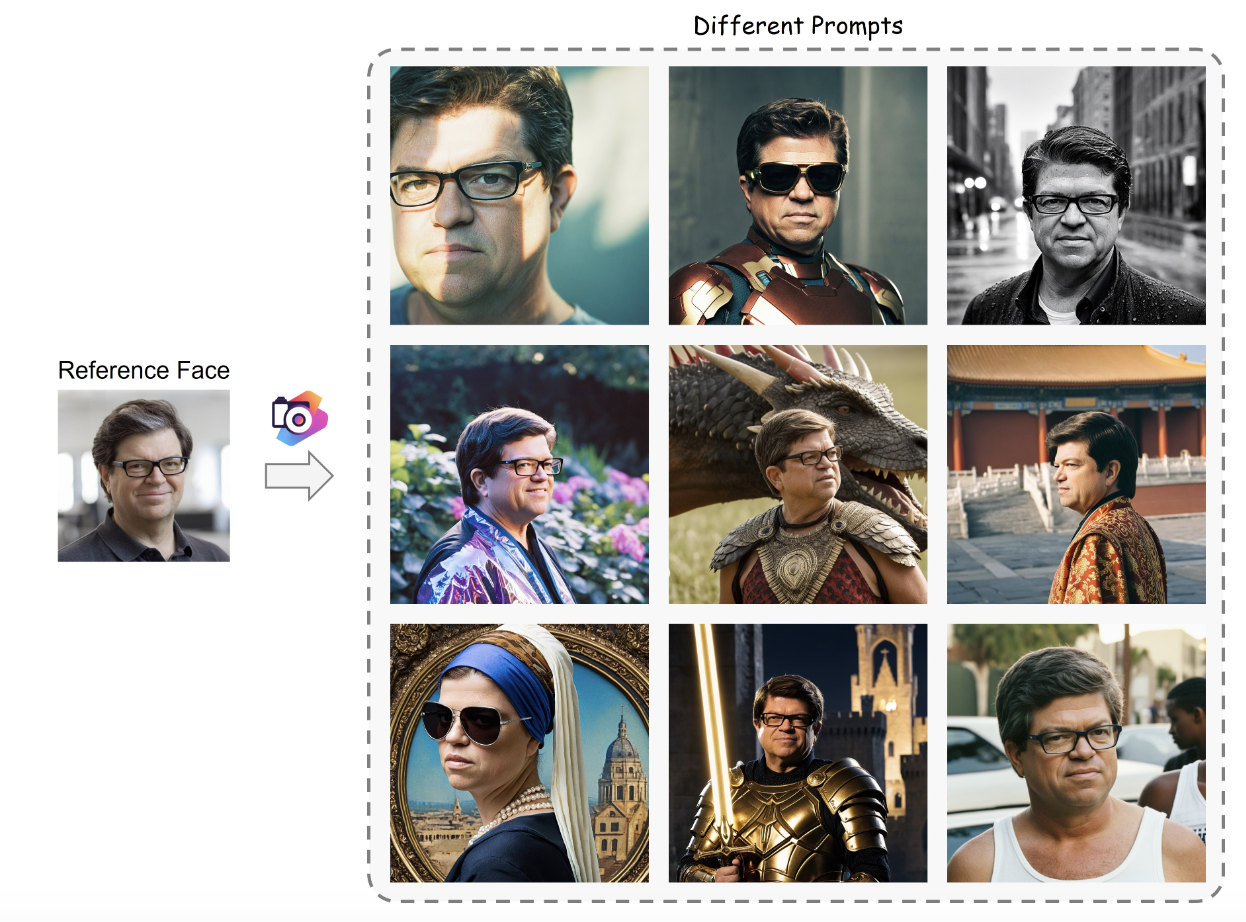
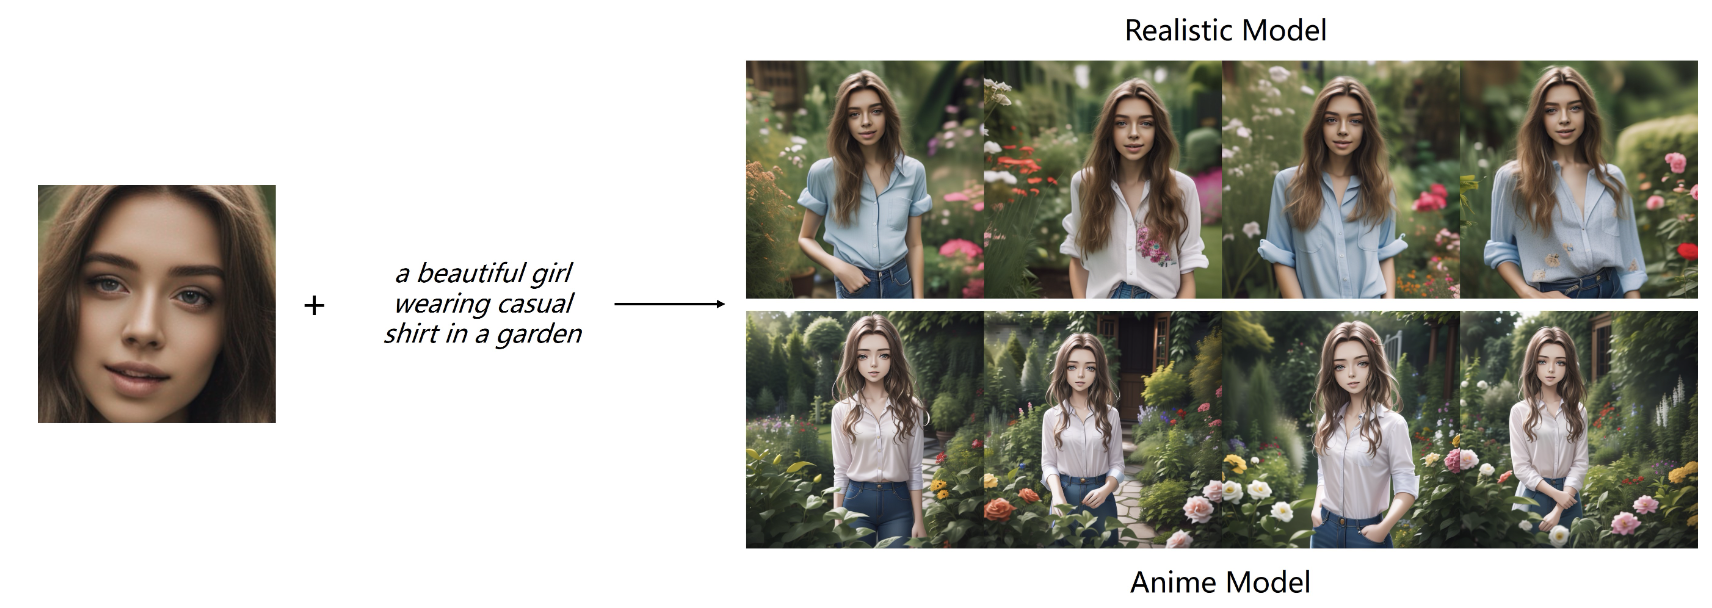
PhotoMaker: Customizing Realistic Human Photos via Stacked ID Embedding
arxiv{Paper} {Code} {Webpage}Details
-
DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation
CVPR2022{Paper} {Code} {Webpage}Details

-
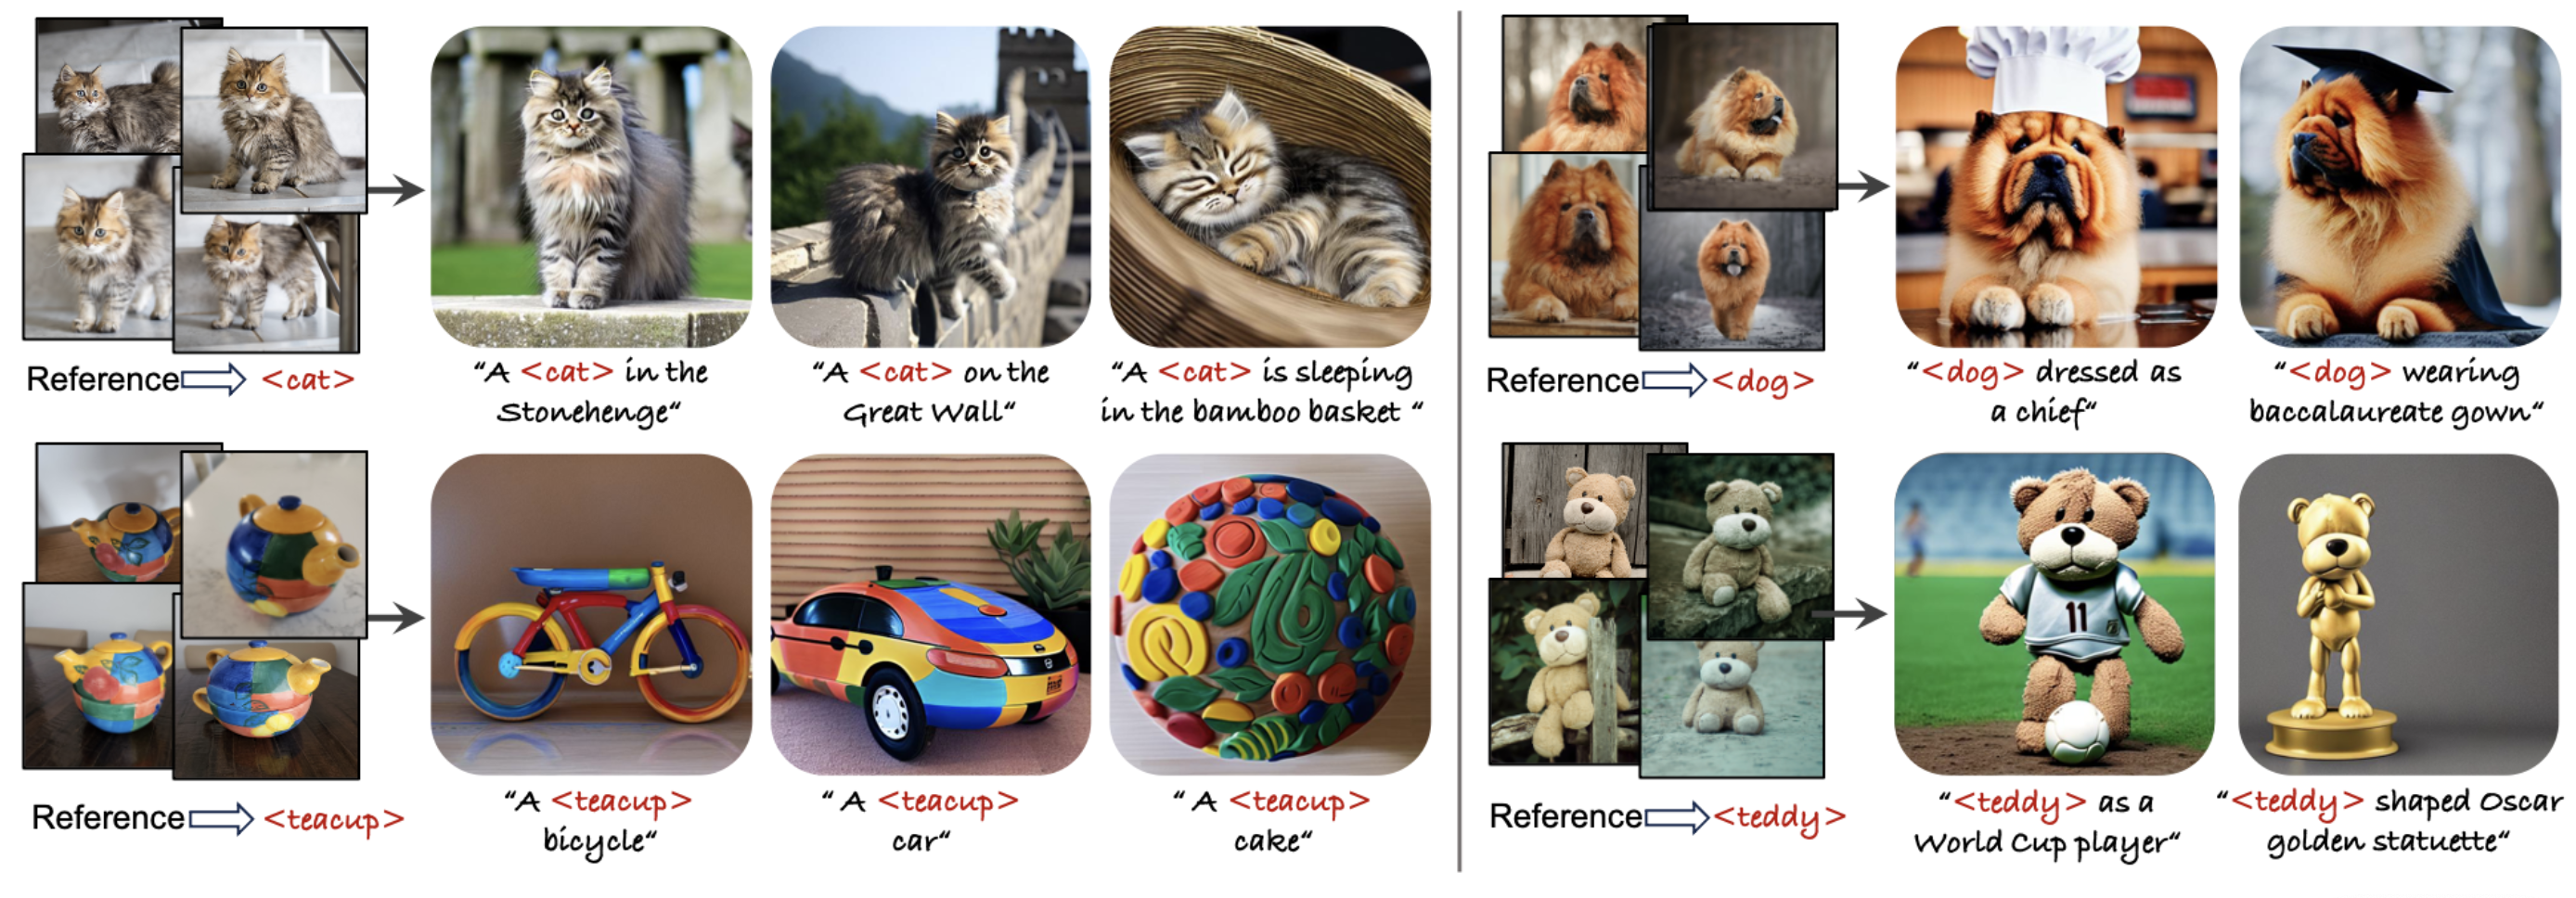
CatVersion: Concatenating Embeddings for Diffusion-Based Text-to-Image Personalization
arxiv{Paper} {Code} {Webpage}Details
-
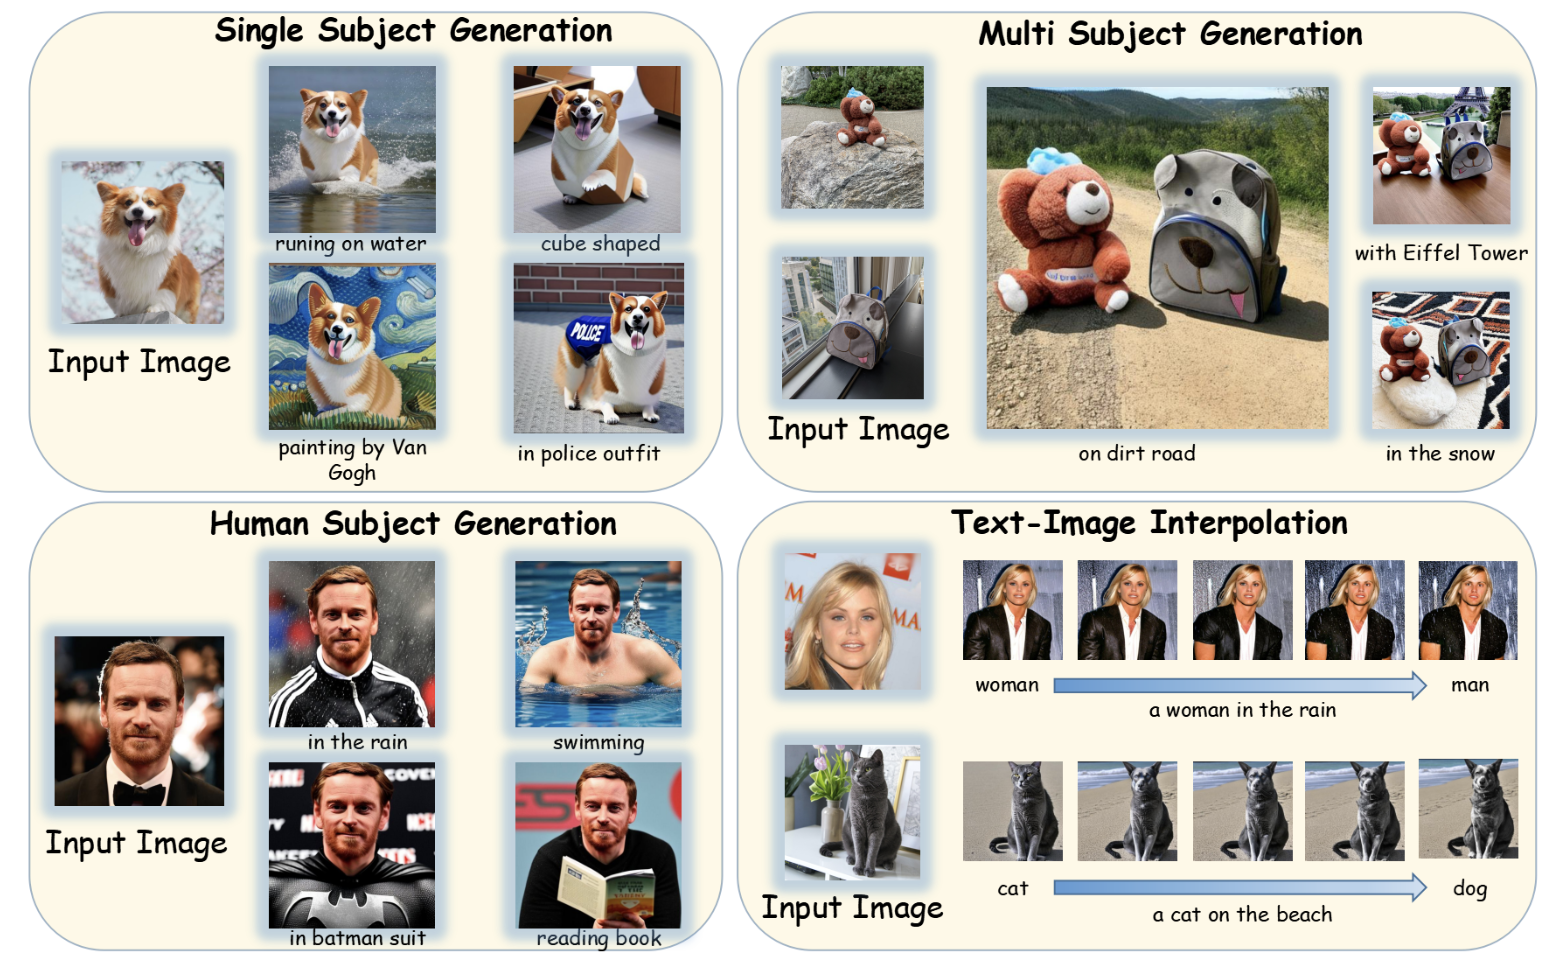
Subject-Diffusion:Open Domain Personalized Text-to-Image Generation without Test-time Fine-tuning
arxiv{Paper} {Code} {Webpage}Details
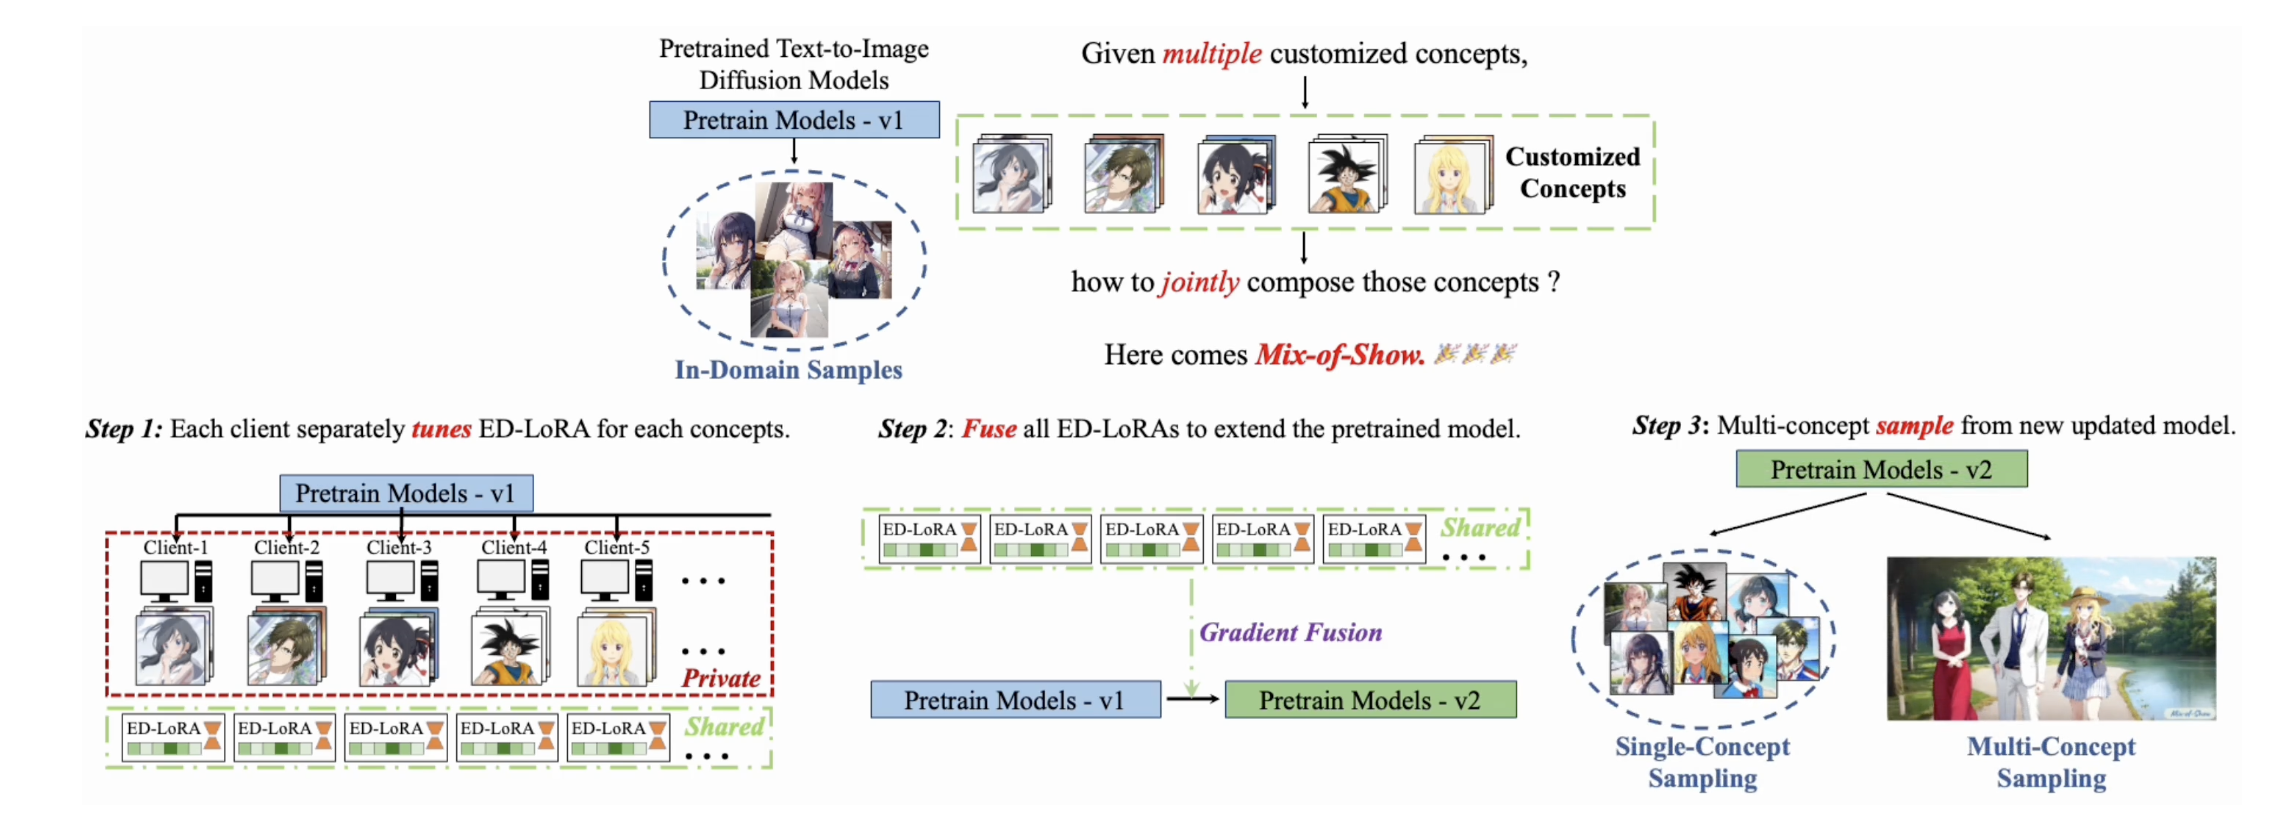
-
Mix-of-Show: Decentralized Low-Rank Adaptation for Multi-Concept Customization of Diffusion Models
NeurIPS2023{Paper} {Code} {Webpage} -
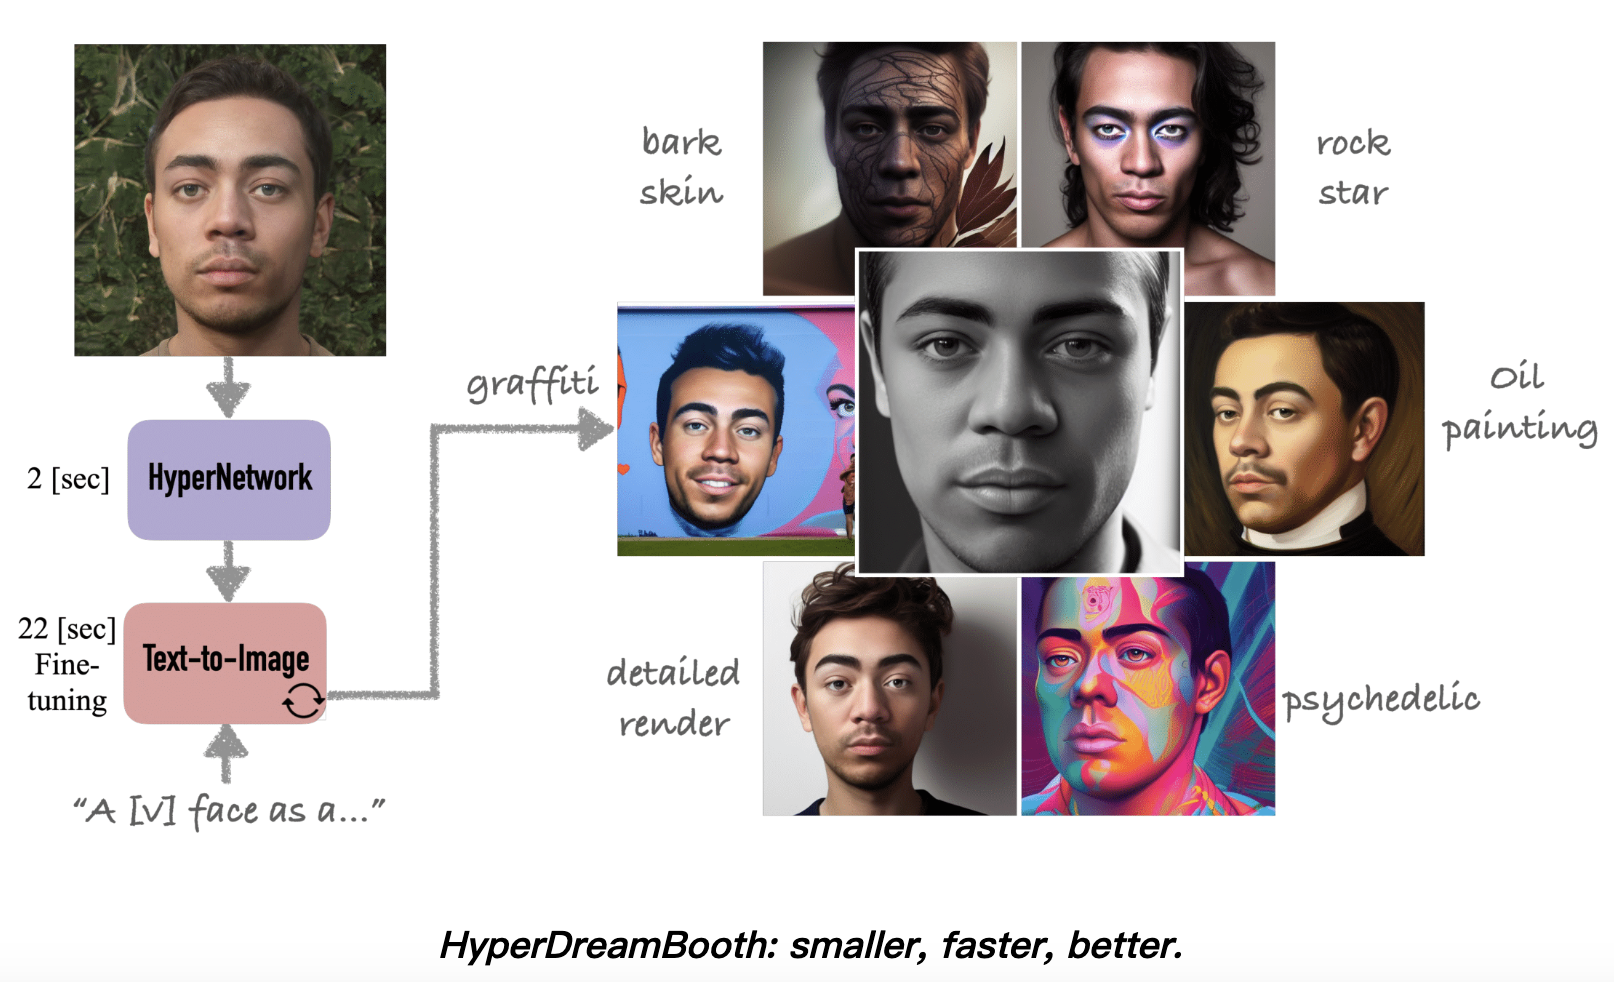
HyperDreamBooth: HyperNetworks for Fast Personalization of Text-to-Image Models
arxiv{Paper} {Code} {Webpage}Details
-
SingleInsert: Inserting New Concepts from a Single Image into Text-to-Image Models for Flexible Editing
arxiv{Paper} {Code} {Webpage} -
Cones 2: Customizable Image Synthesis with Multiple Subjects
NeurIPS2023{Paper} {Code} {Webpage} -
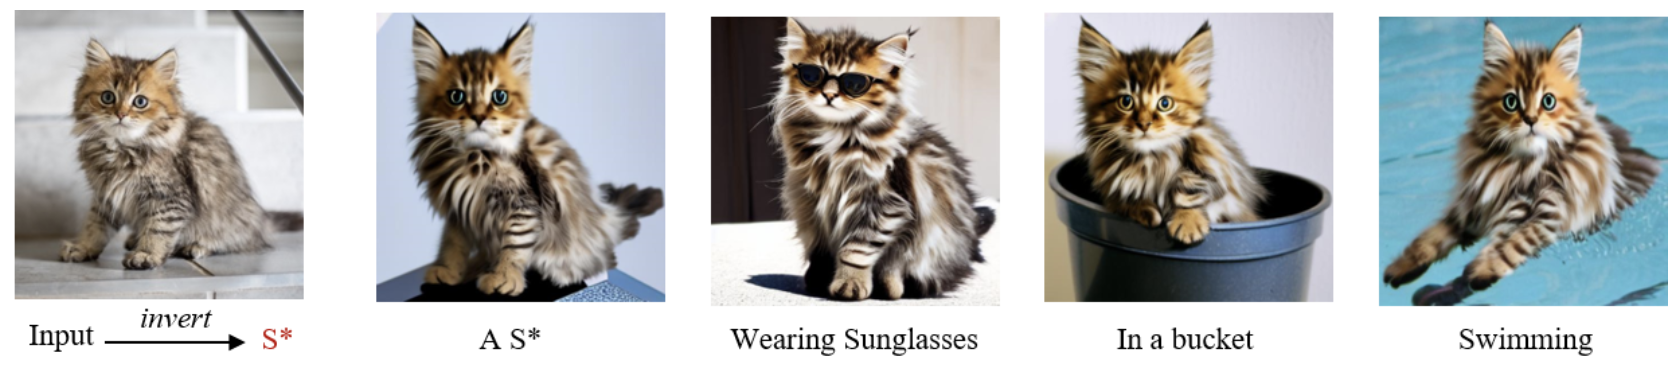
ELITE: Encoding Visual Concepts into Textual Embeddings for Customized Text-to-Image Generation
ICCV 2023{Paper} {Code}Details
Text-guided Image Editing
2024
-
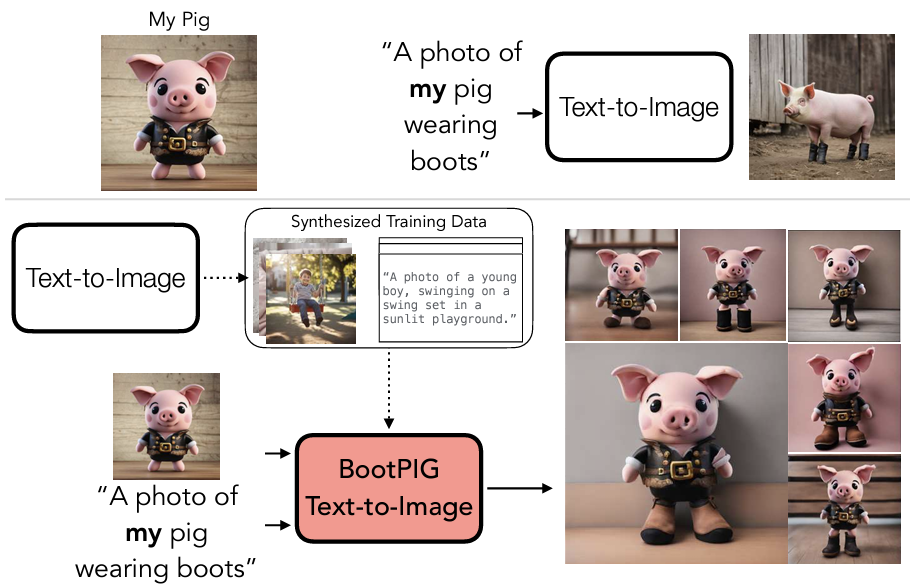
BootPIG: Bootstrapping Zero-shot Personalized Image Generation Capabilities in Pretrained Diffusion Models
arxiv{Paper}Details
-
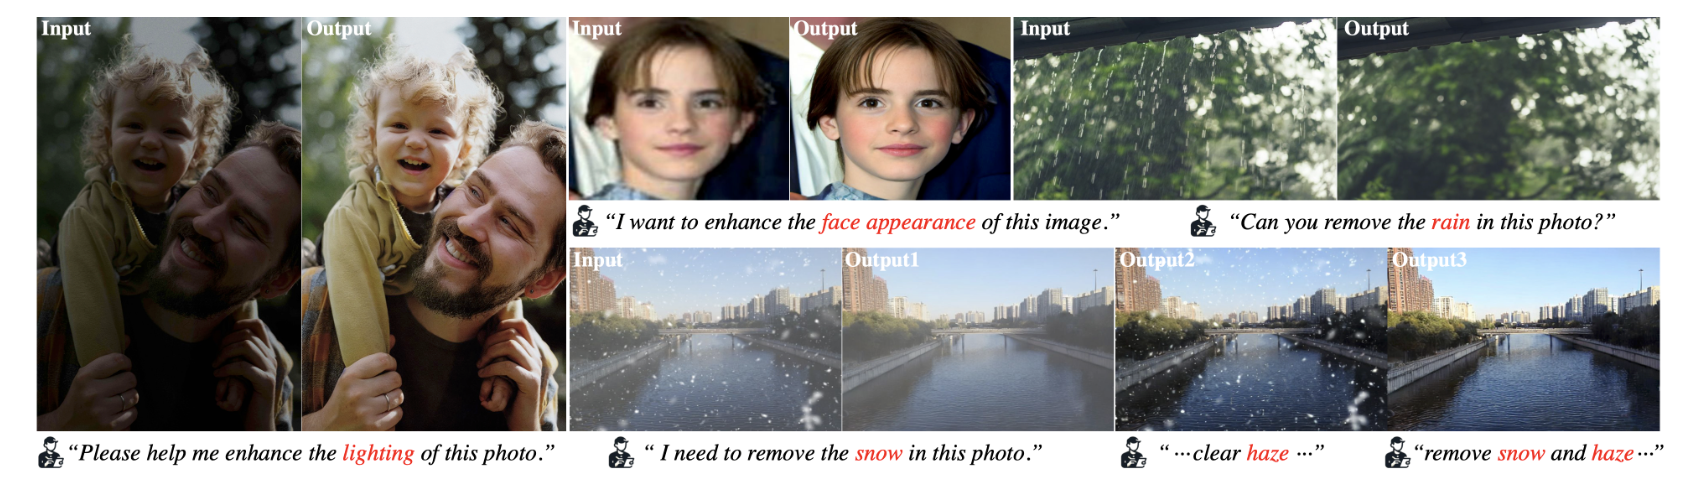
Diff-Plugin: Revitalizing Details for Diffusion-based Low-level Tasks
CVPR 2024{Paper} {Code} {Webpage}Details
-
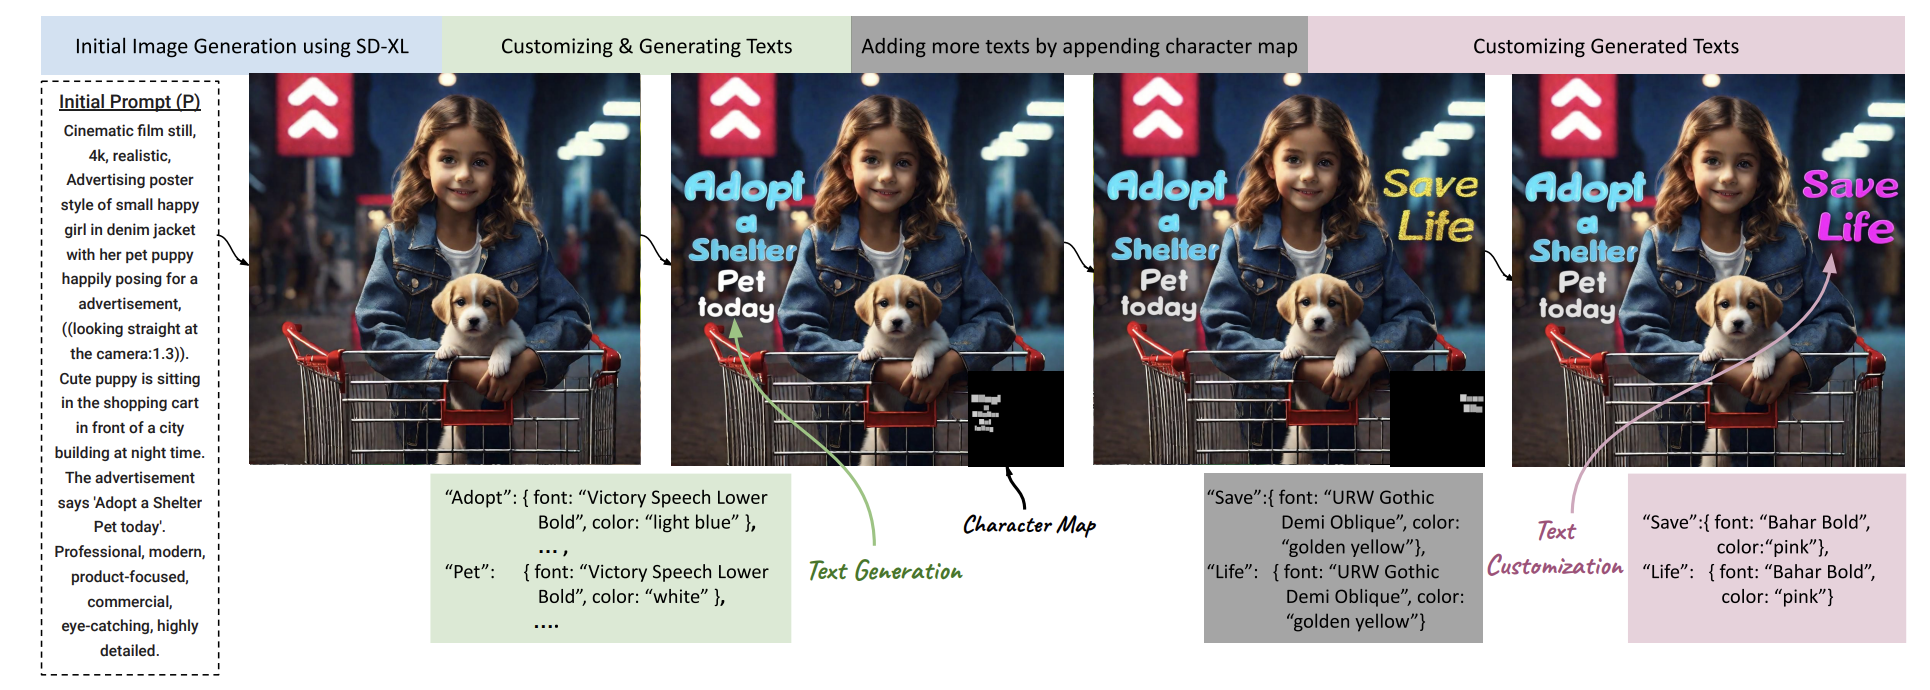
CustomText: Customized Textual Image Generation using Diffusion Models
arxiv{Paper}Details
-
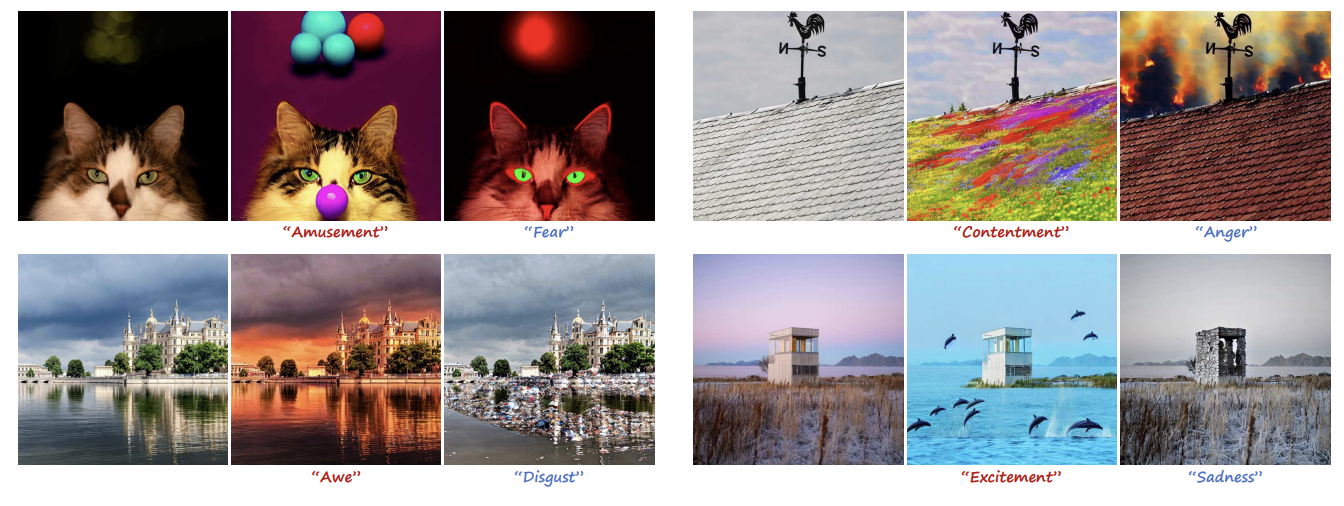
EmoEdit: Evoking Emotions through Image Manipulation
arxiv{Paper}Details
-
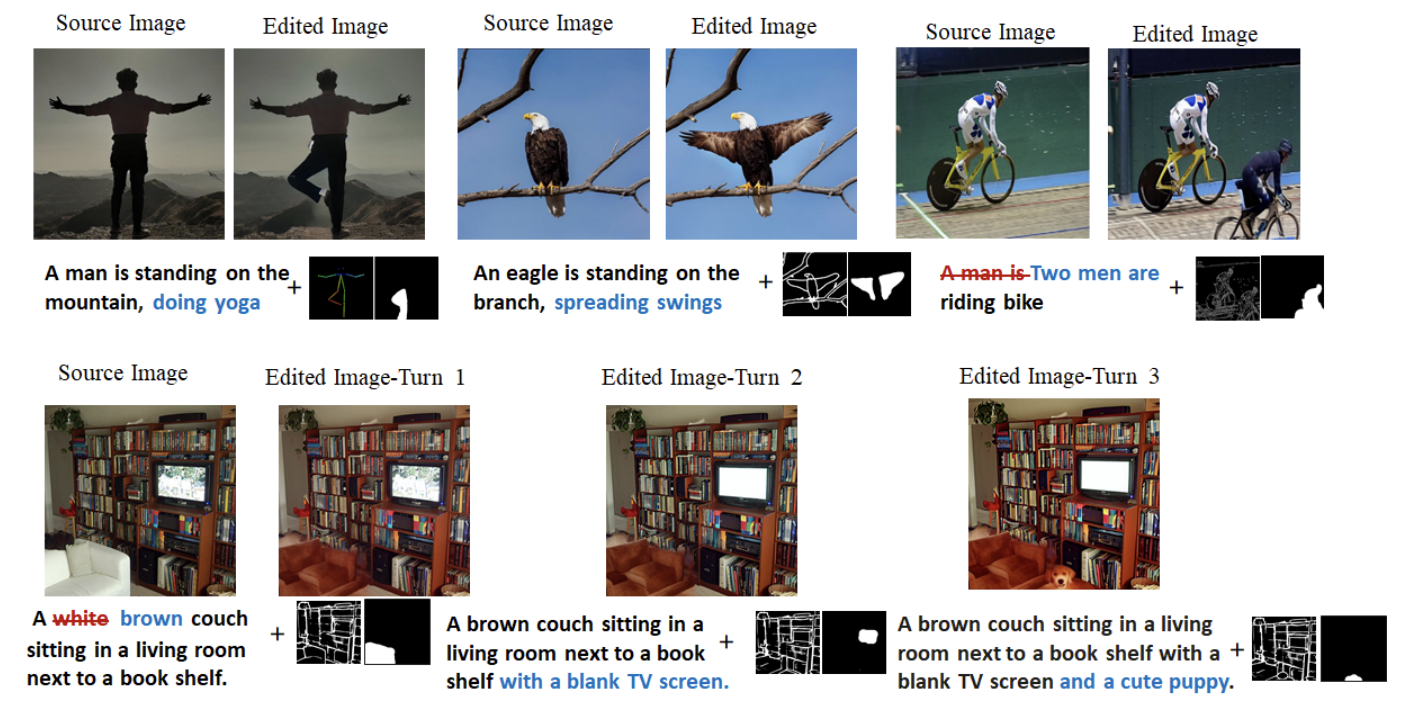
Enhancing Text-to-Image Editing via Hybrid Mask-Informed Fusion
arxiv{Paper}Details
-
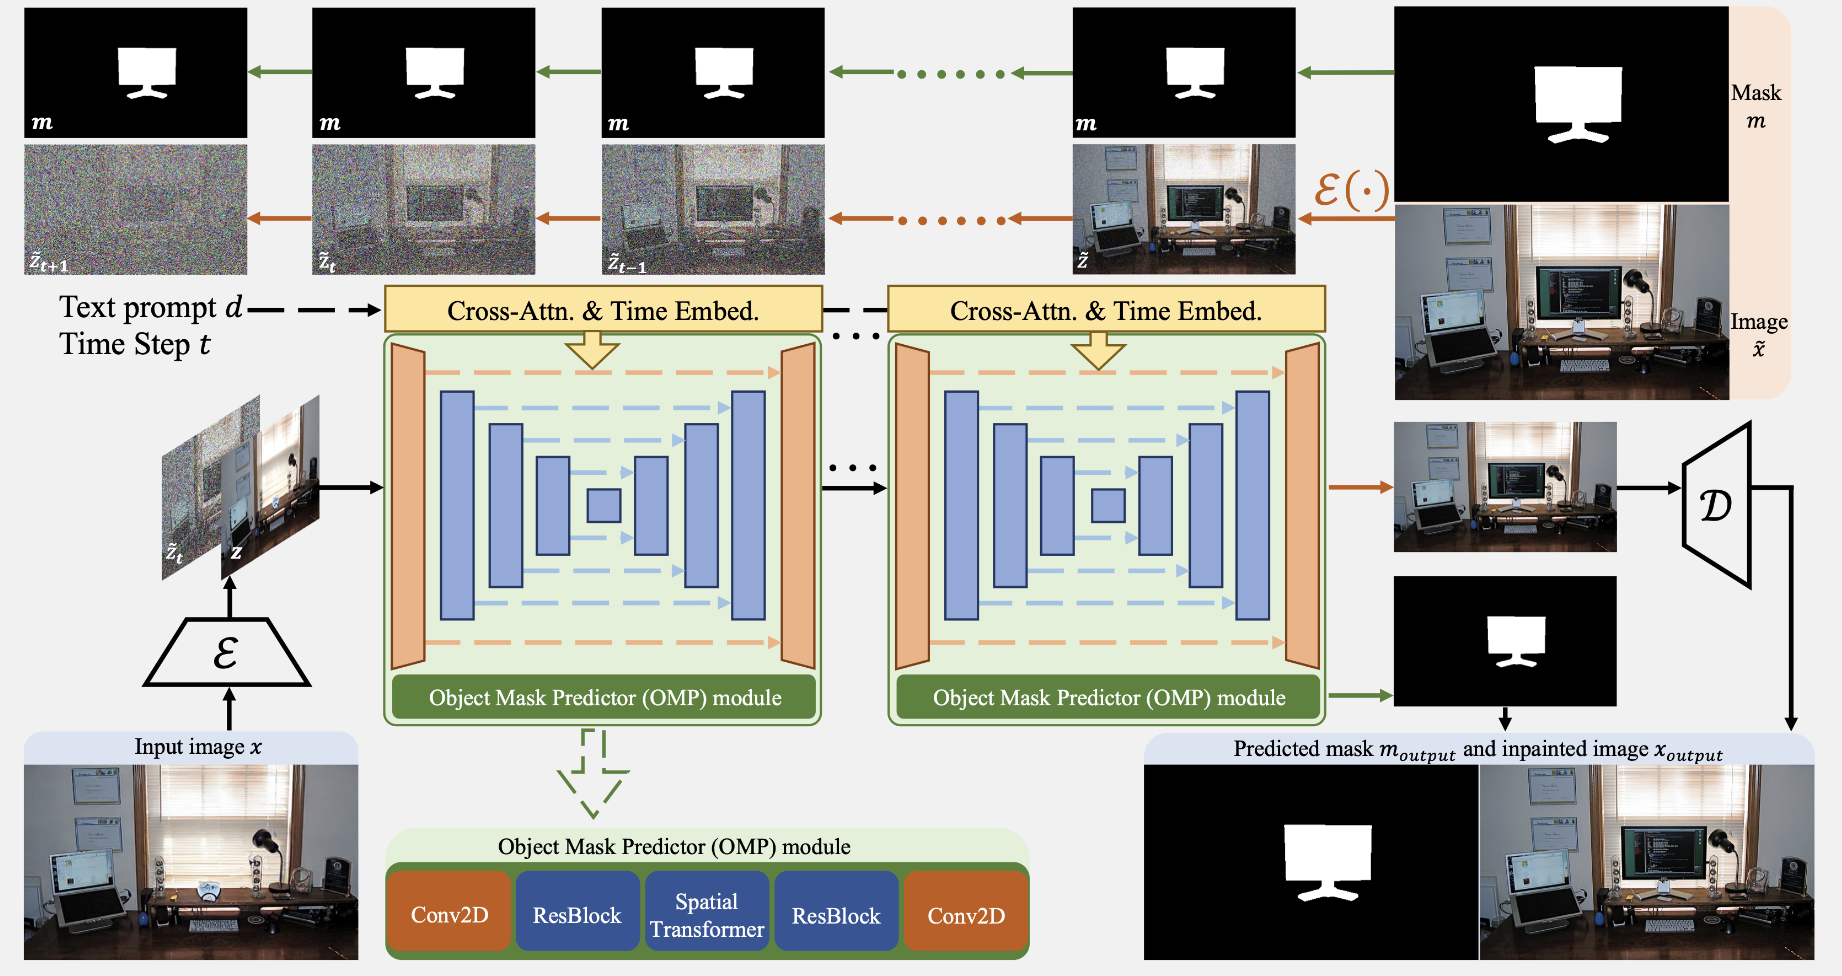
Diffree: Text-Guided Shape Free Object Inpainting with Diffusion Model
arxiv{Paper} {Code} {Webpage}
2023
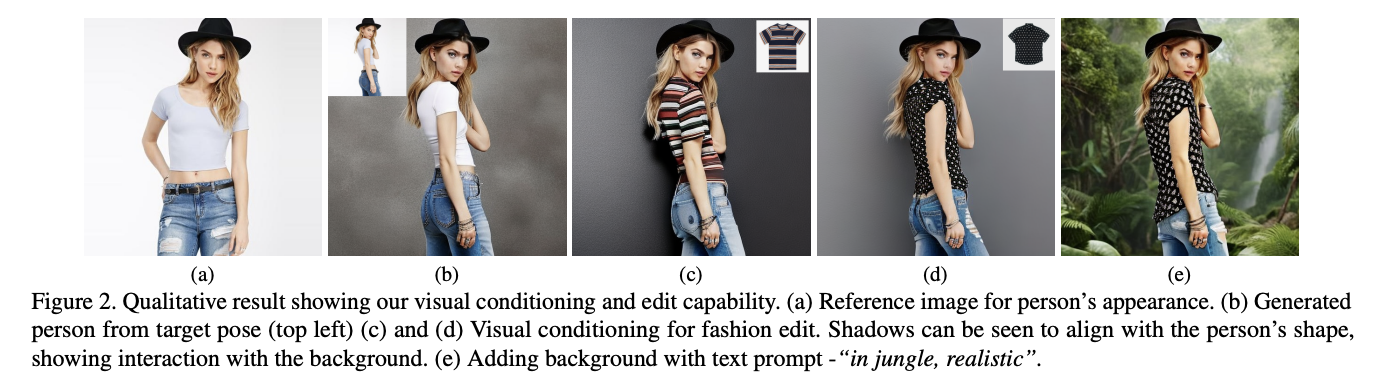
- ViscoNet: Bridging and Harmonizing Visual and Textual Conditioning for ControlNet
arxiv{Paper} {Code} {Webpage}
-
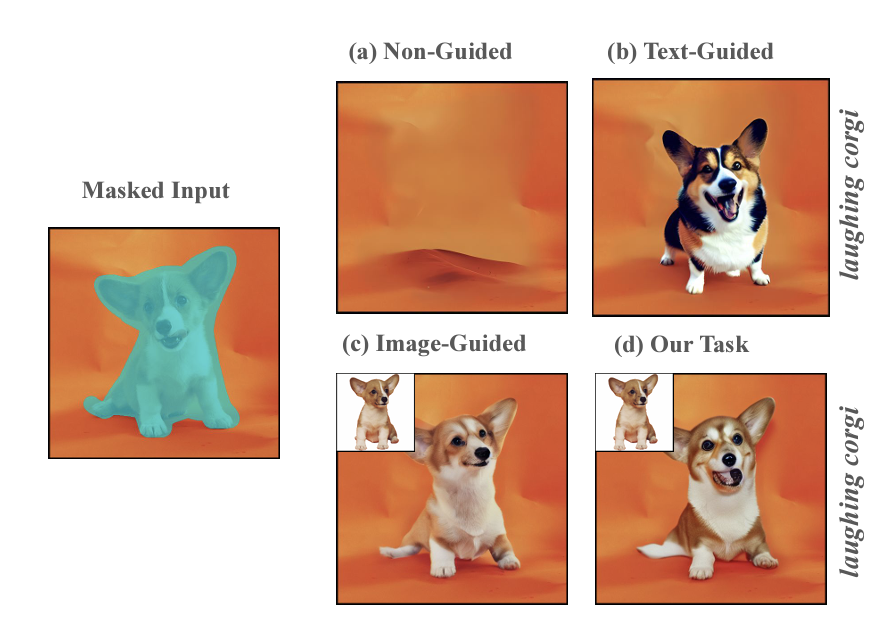
DreamInpainter: Text-Guided Subject-Driven Image Inpainting with Diffusion Models
arxiv{Paper}Details
-
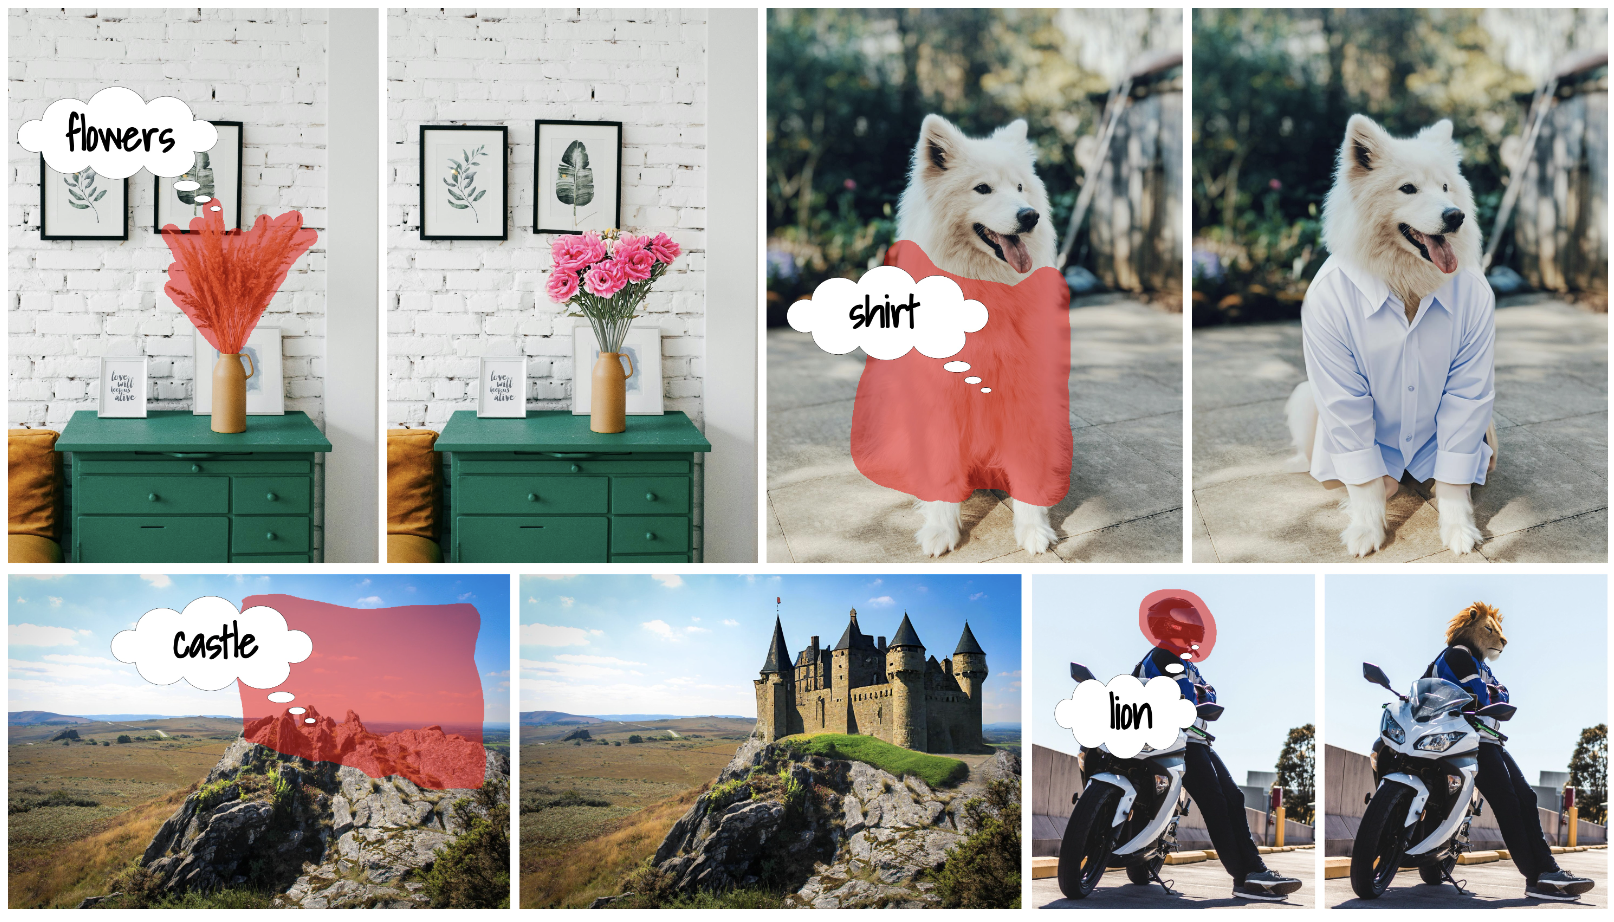
HD-Painter: High-Resolution and Prompt-Faithful Text-Guided Image Inpainting with Diffusion Models
arxiv{Paper} {Code} {HuggingFace}Details
-
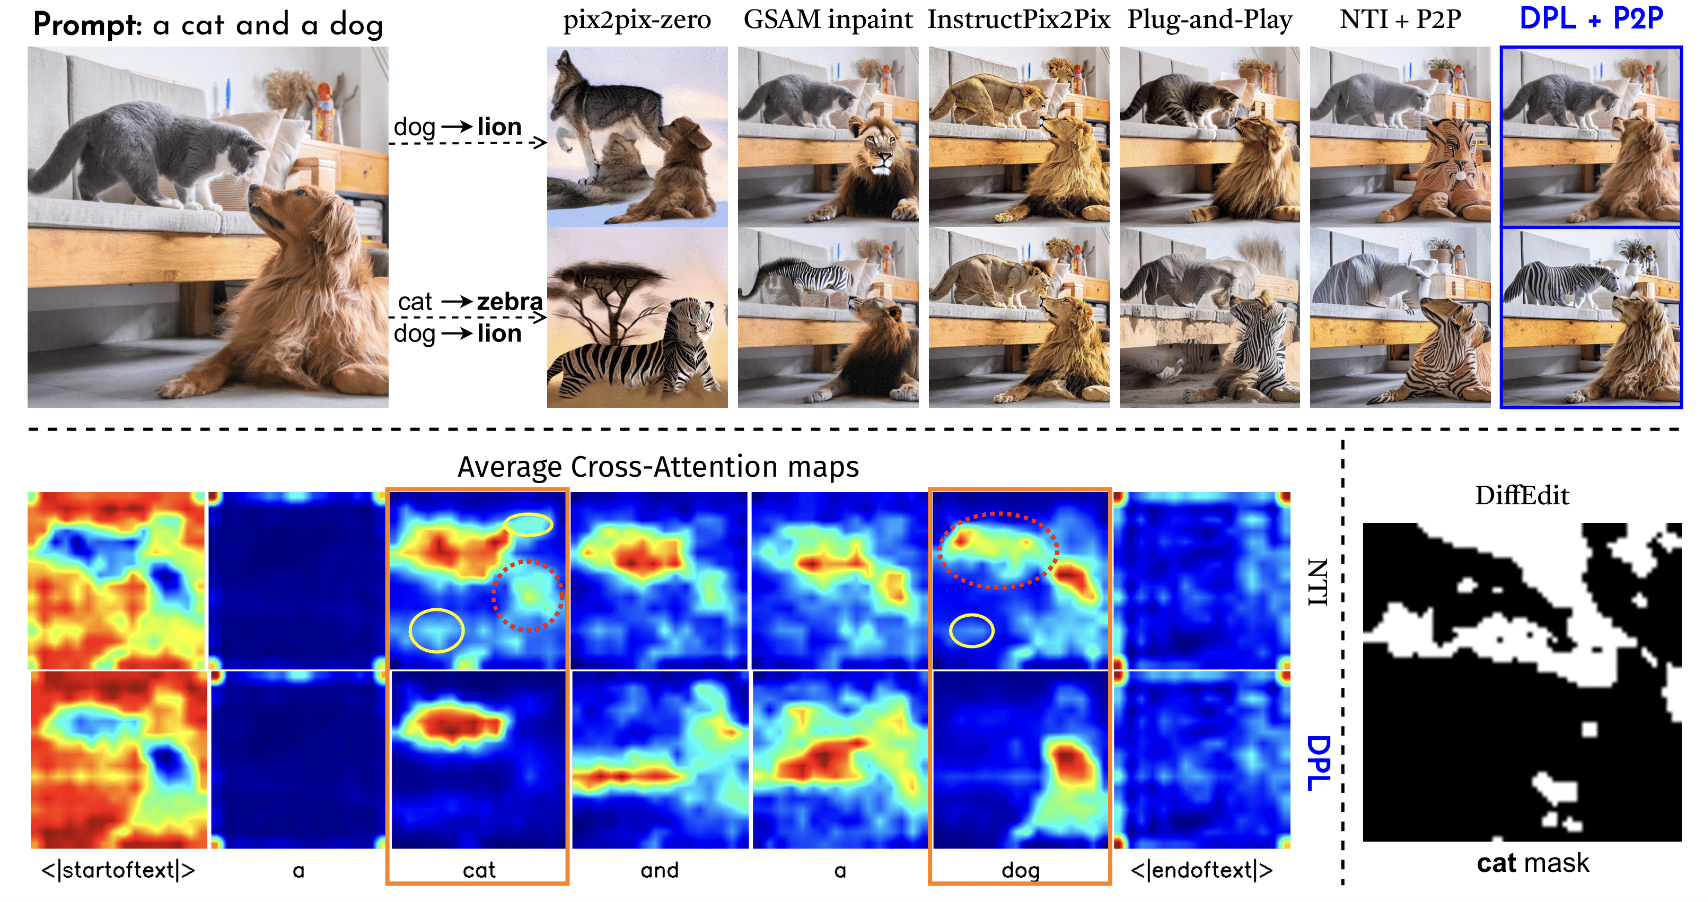
Dynamic Prompt Learning: Addressing Cross-Attention Leakage for Text-Based Image Editing
NeurIPS 2023{Paper} {Code}Details
Customized 3D Generation/Manipulation
Image-prompted 3D Generation
2024
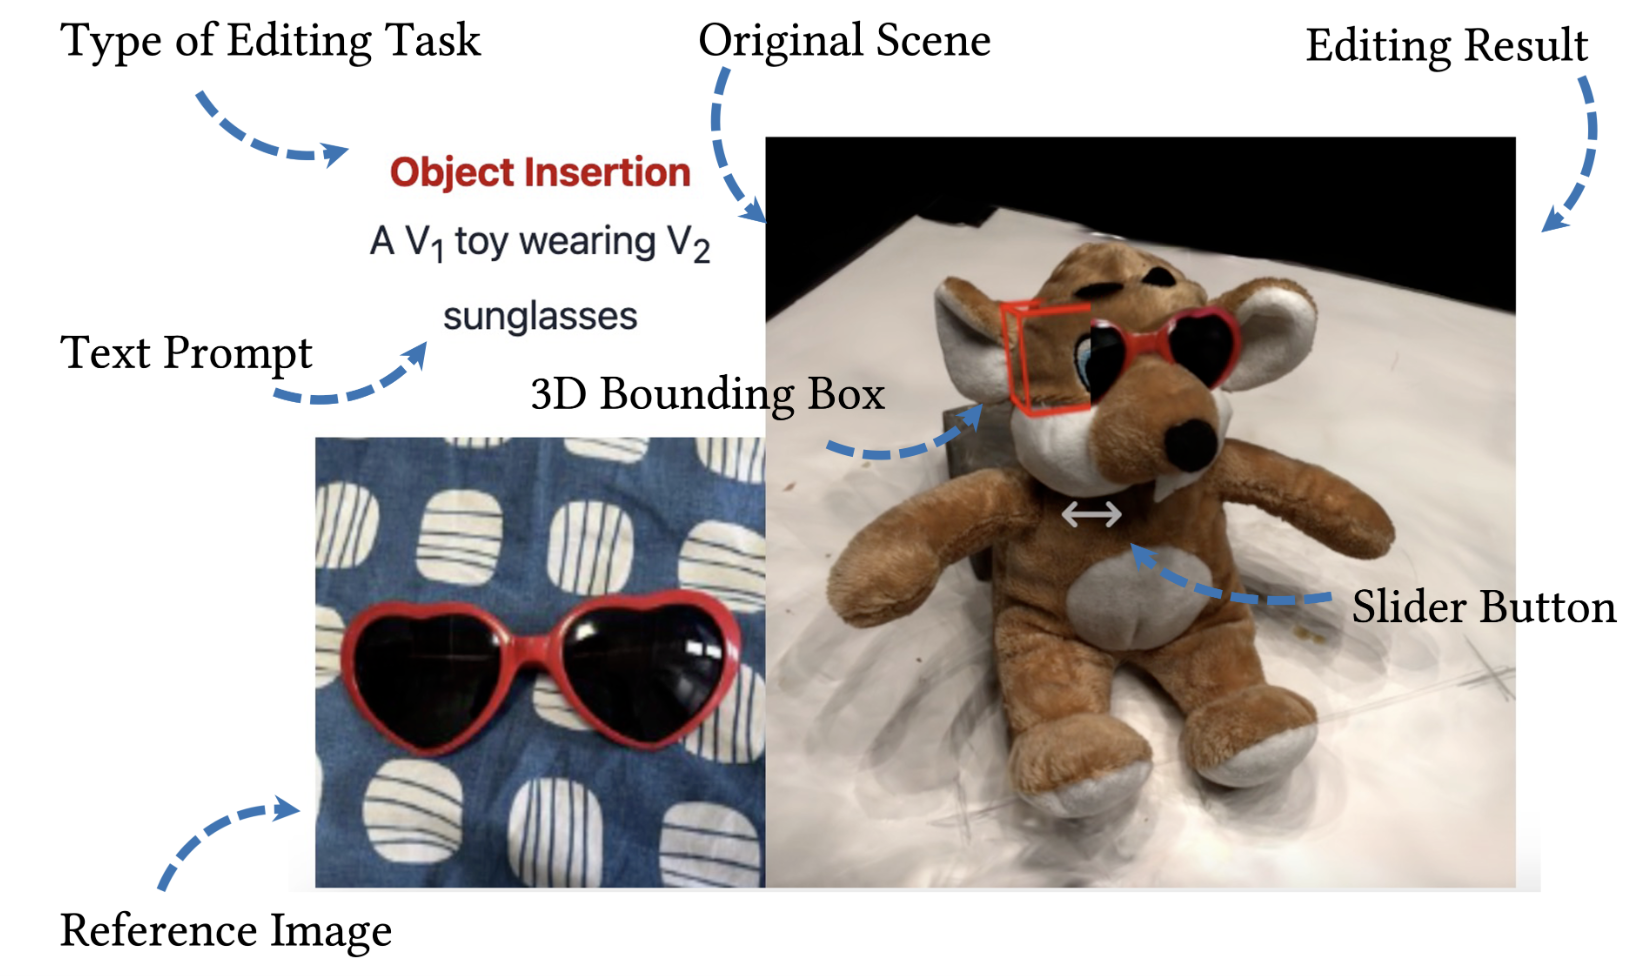
- TIP-Editor: An Accurate 3D Editor Following Both Text-Prompts And Image-Prompts
arxiv{Paper} {Webpage}
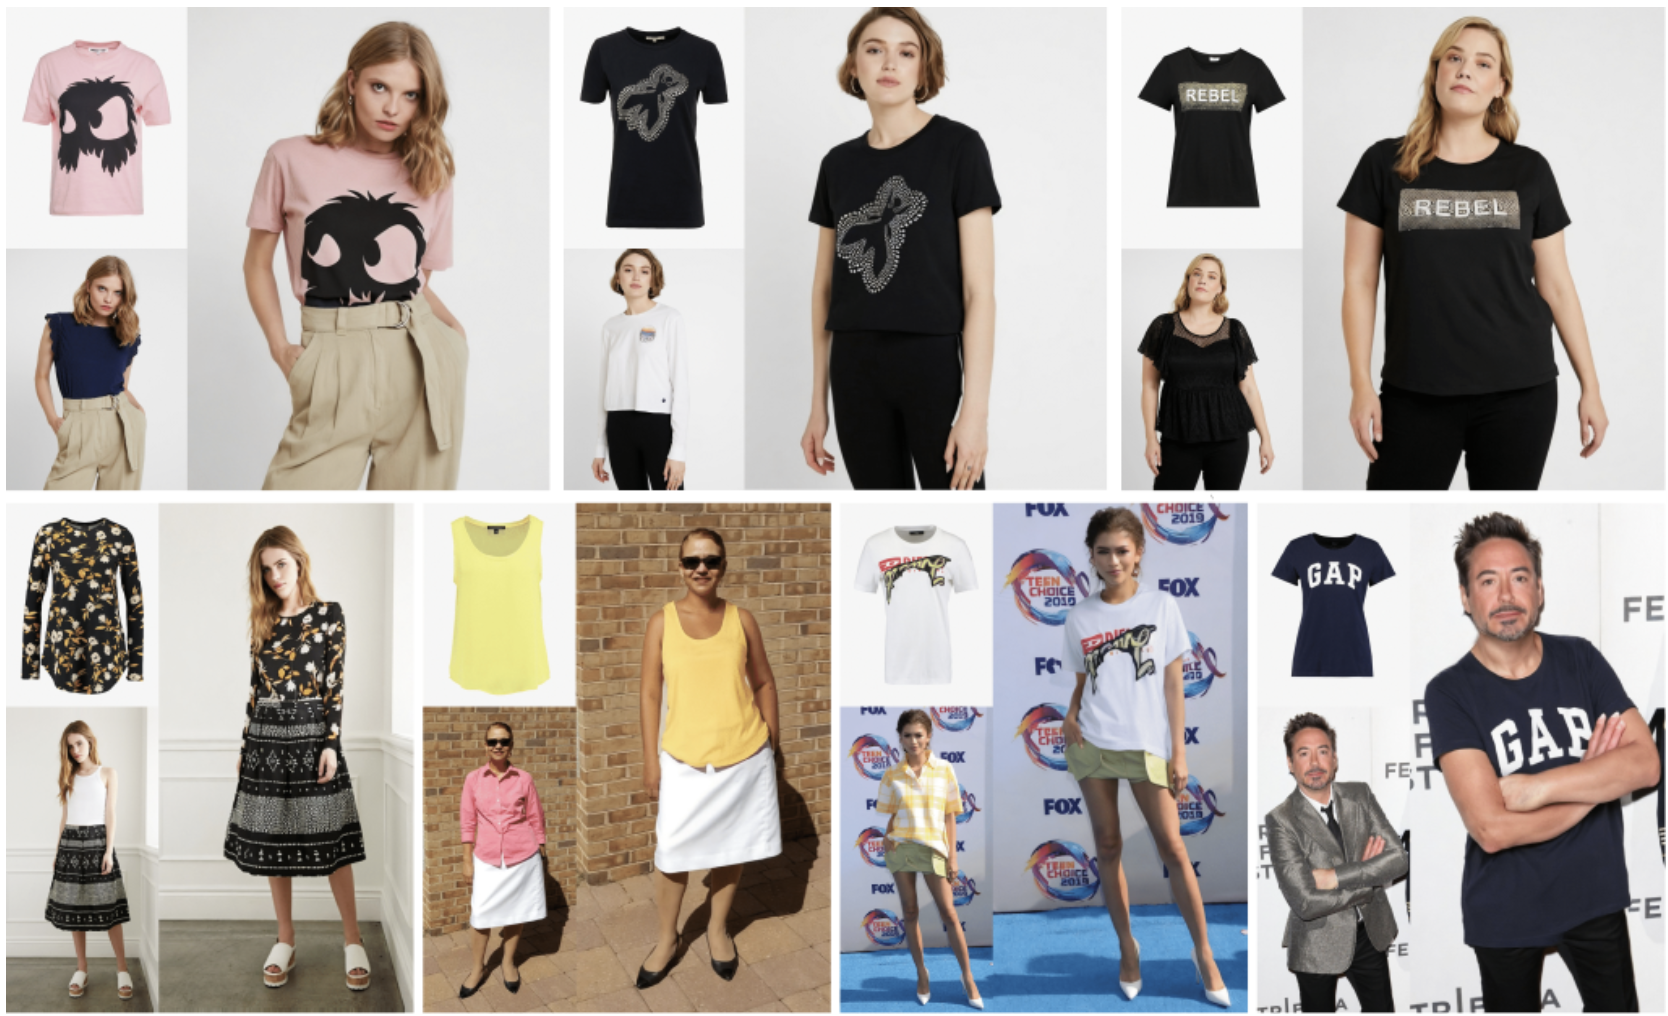
- StableVITON: Learning Semantic Correspondence with Latent Diffusion Model for Virtual Try-On
CVPR 2024{Paper} {Code} {Webpage}Details
-
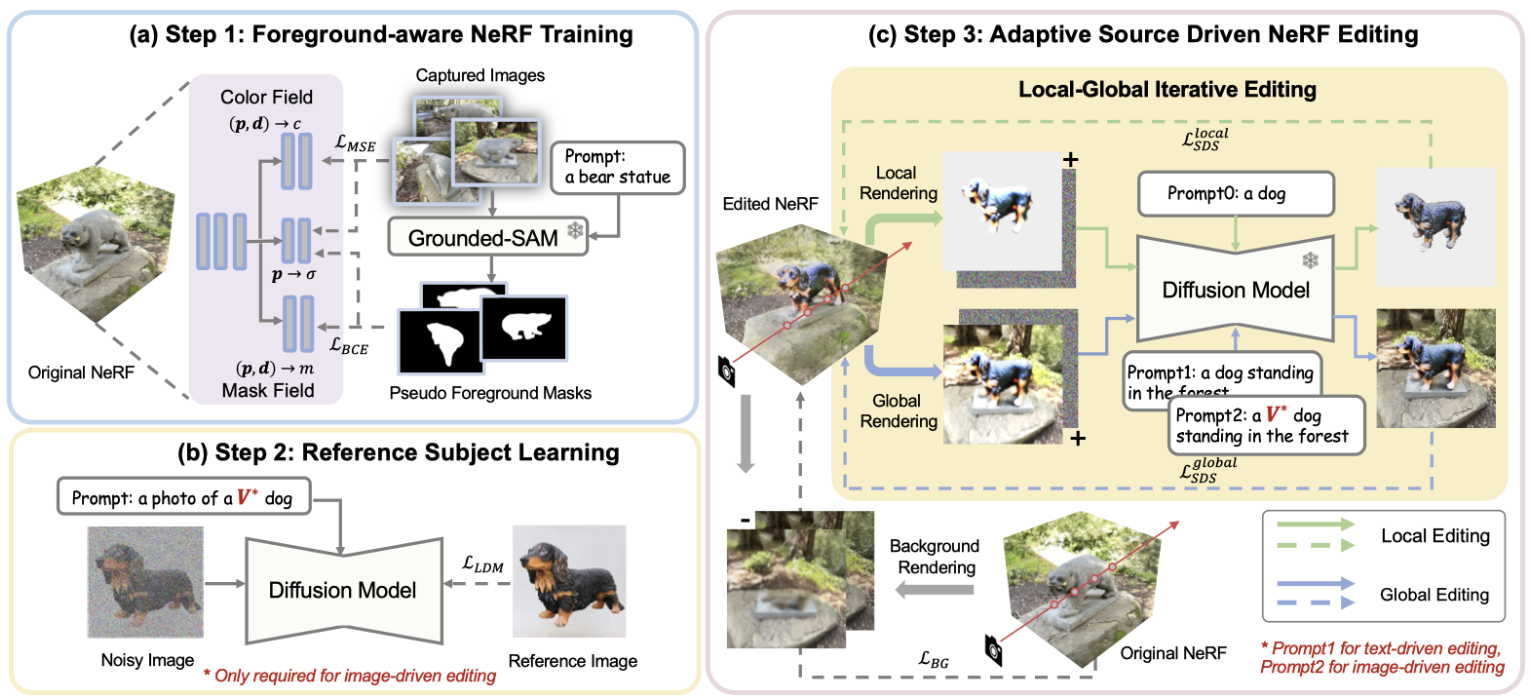
Customize your NeRF: Adaptive Source Driven 3D Scene Editing via Local-Global Iterative Training
CVPR2024{Paper} {Code} {Webpage} -
SplattingAvatar: Realistic Real-Time Human Avatars with Mesh-Embedded Gaussian Splatting
CVPR 2024{Paper} {Code} {Webpage}Details
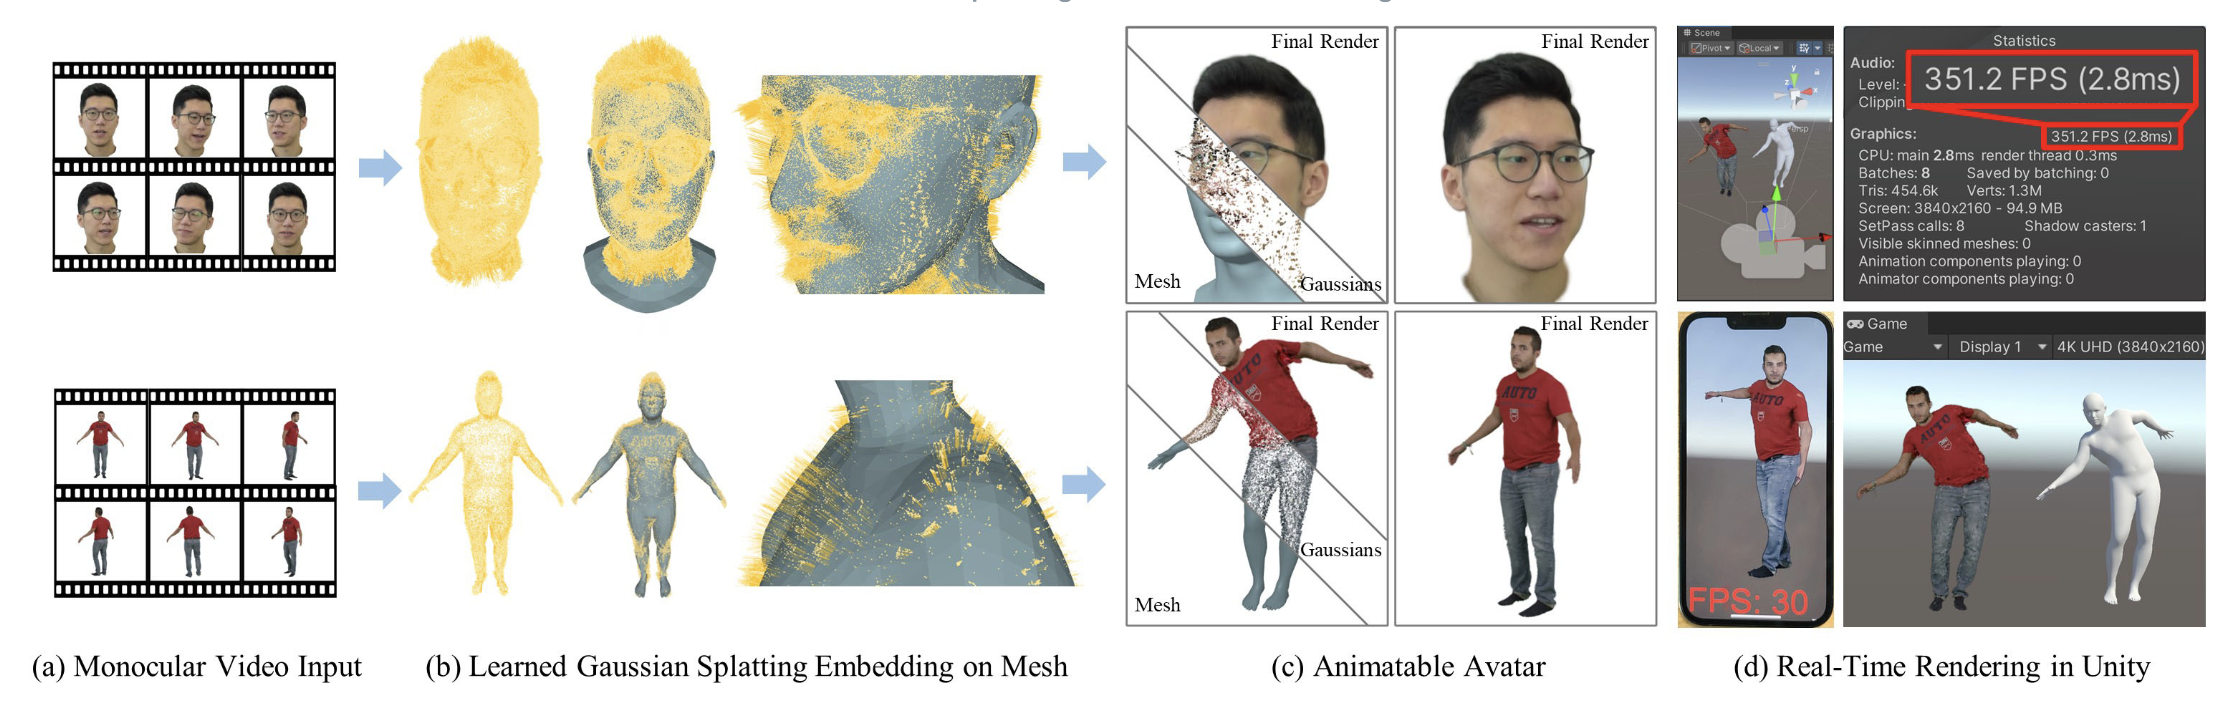
-
ViewDiff: 3D-Consistent Image Generation with Text-to-Image Models
CVPR 2024{Paper} {Code} {Webpage}Details
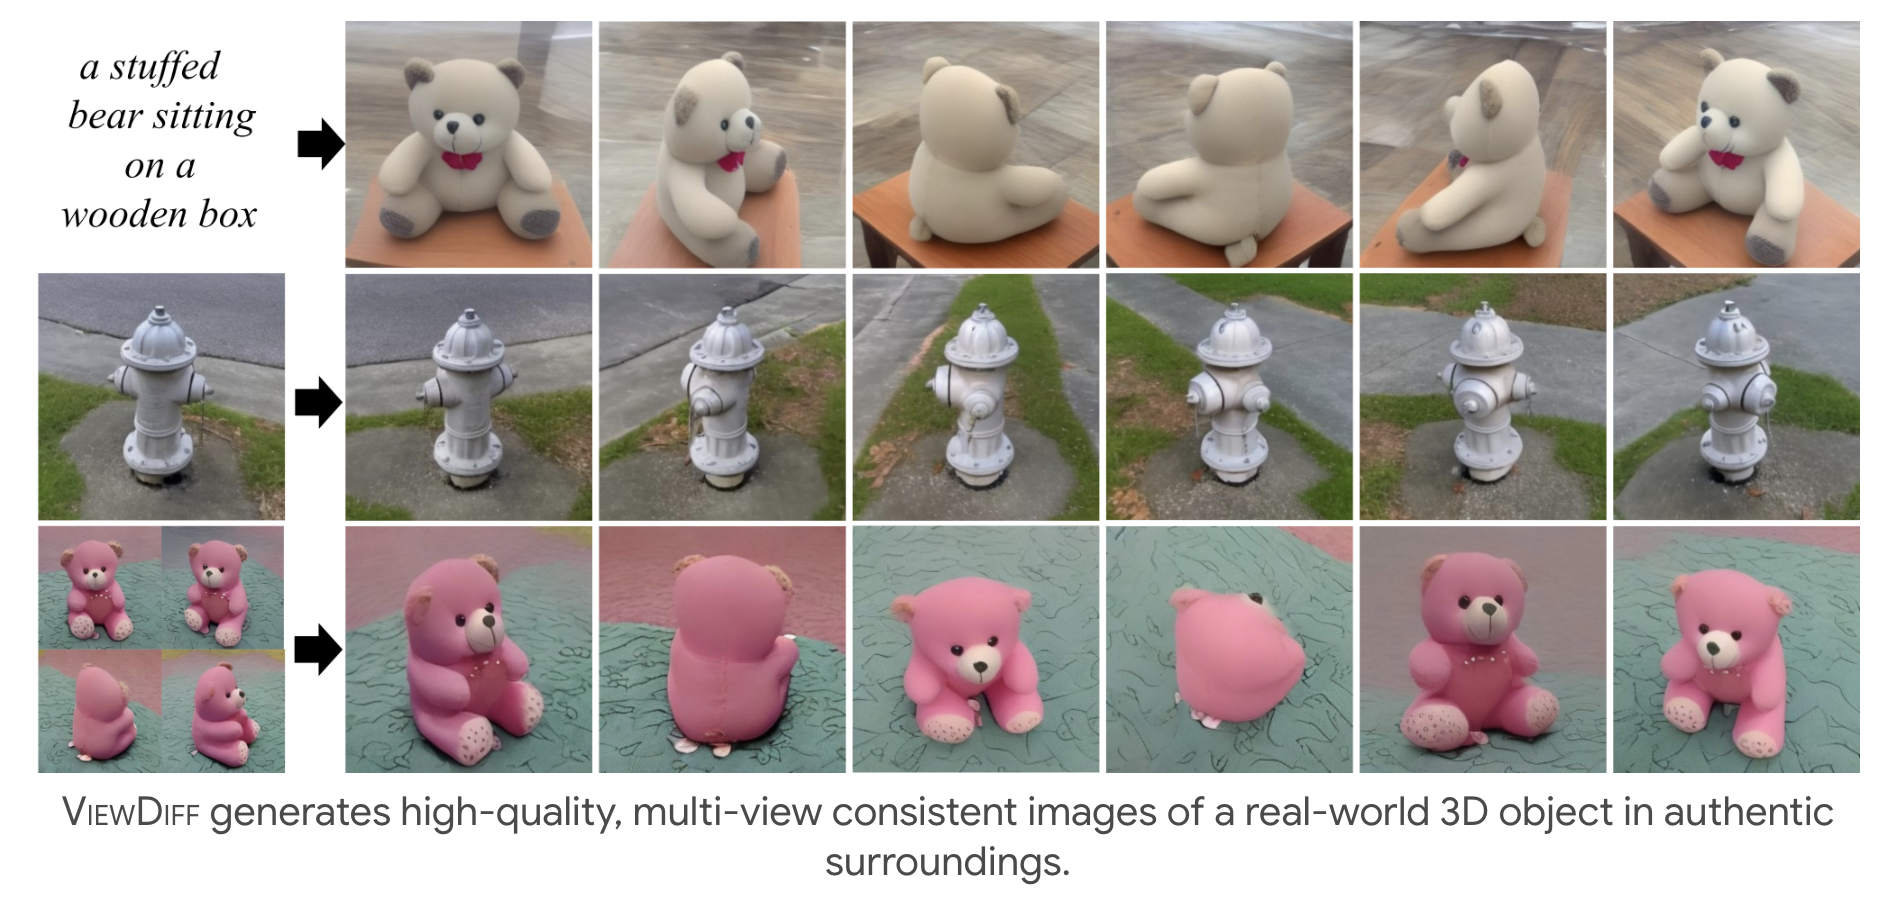
-
LeftRefill: Filling Right Canvas based on Left Reference through Generalized Text-to-Image Diffusion Model
CVPR 2024{Paper} {Code} {Webpage}Details
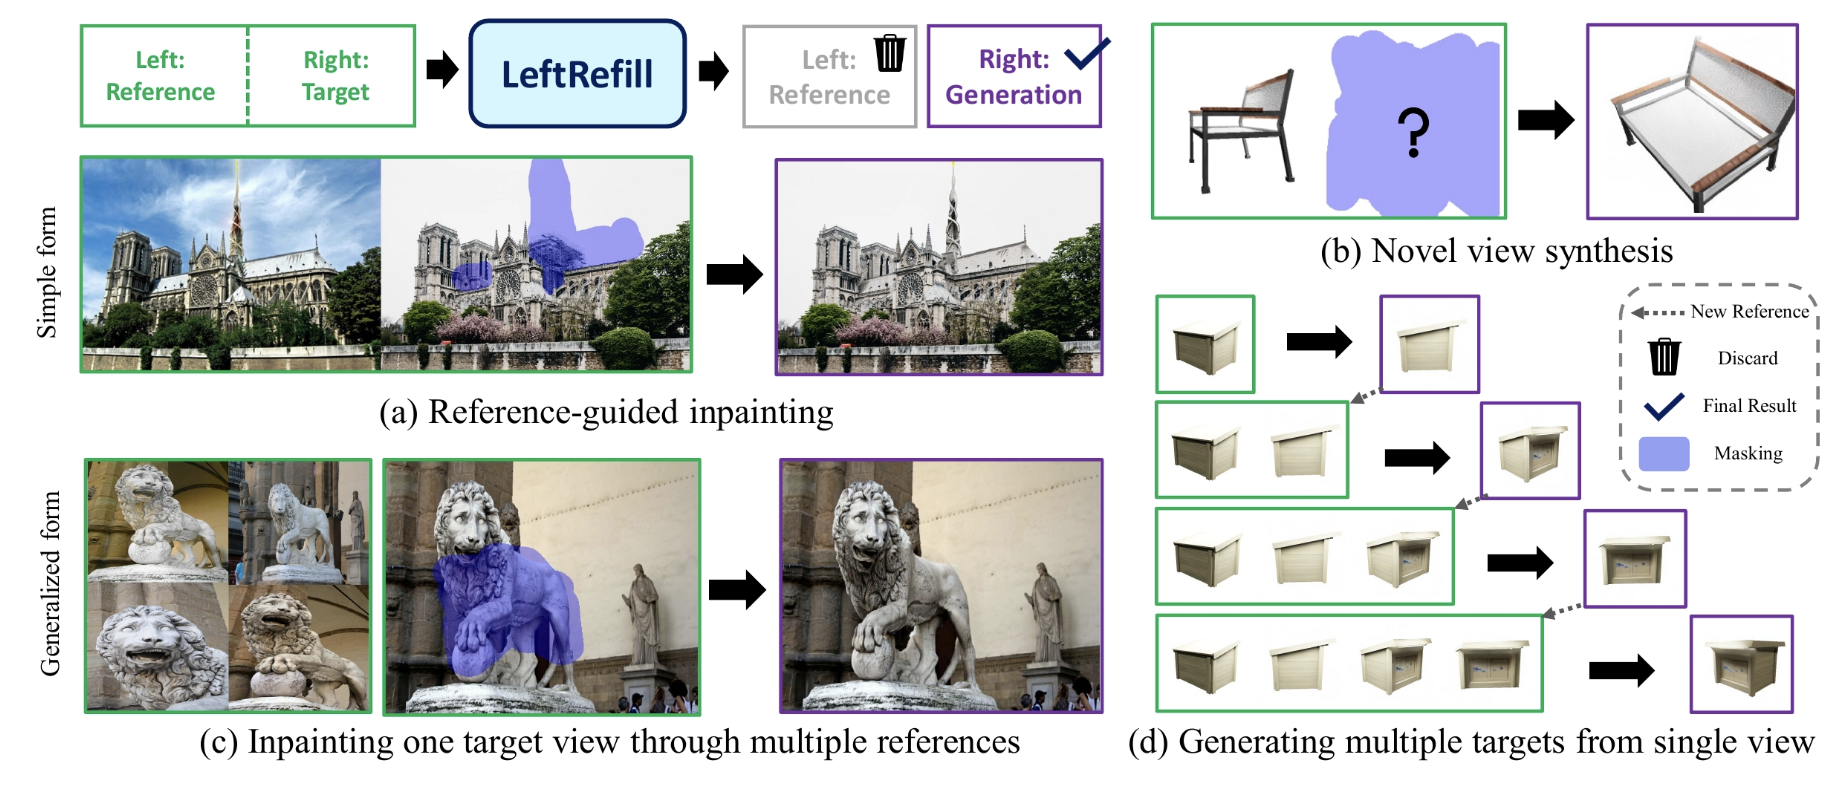
-
Diffusion Time-step Curriculum for One Image to 3D Generation
CVPR 2024{Paper} {Code}Details
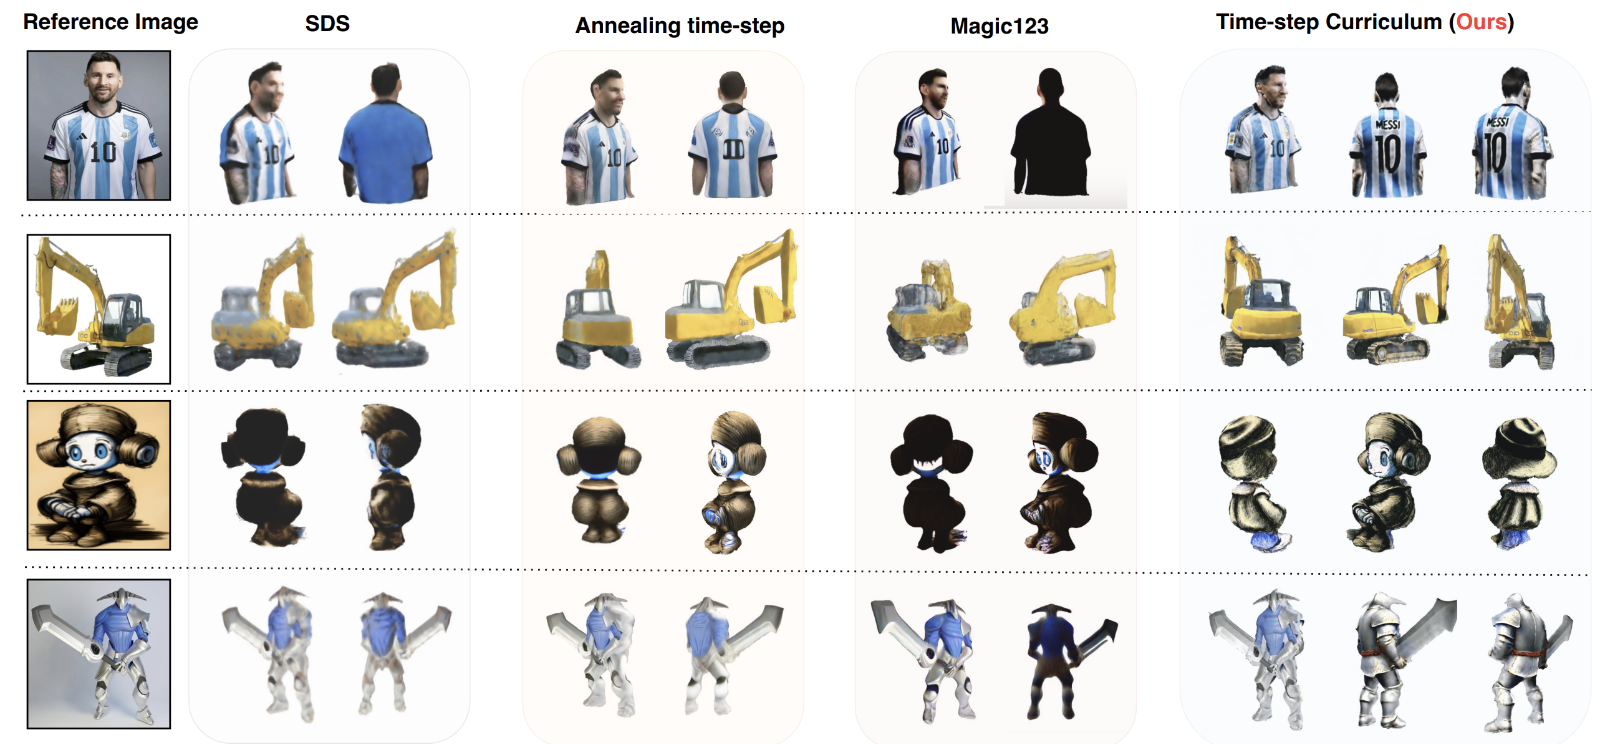
-
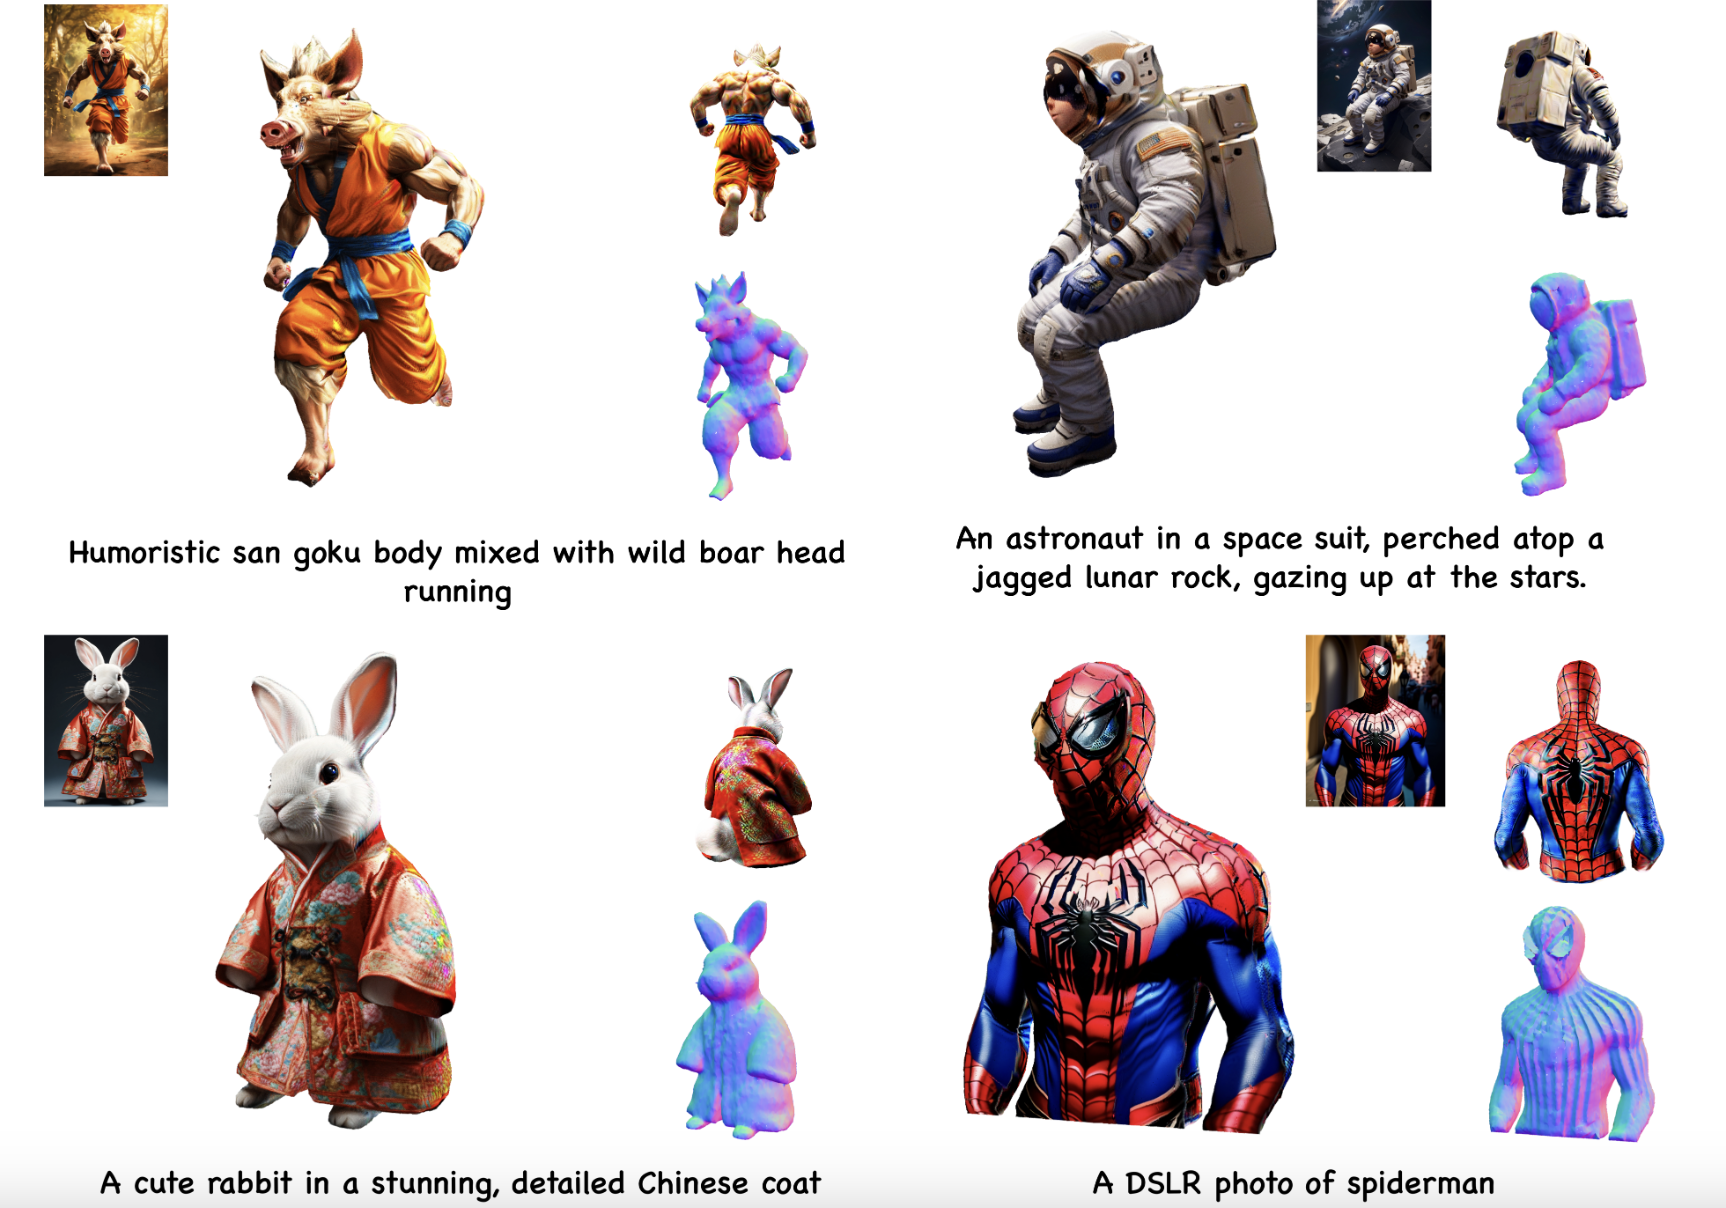
DreamCraft3D: Hierarchical 3D Generation with Bootstrapped Diffusion Prior
ICLR 2024{Paper} {Code} {Webpage}Details
 `
-
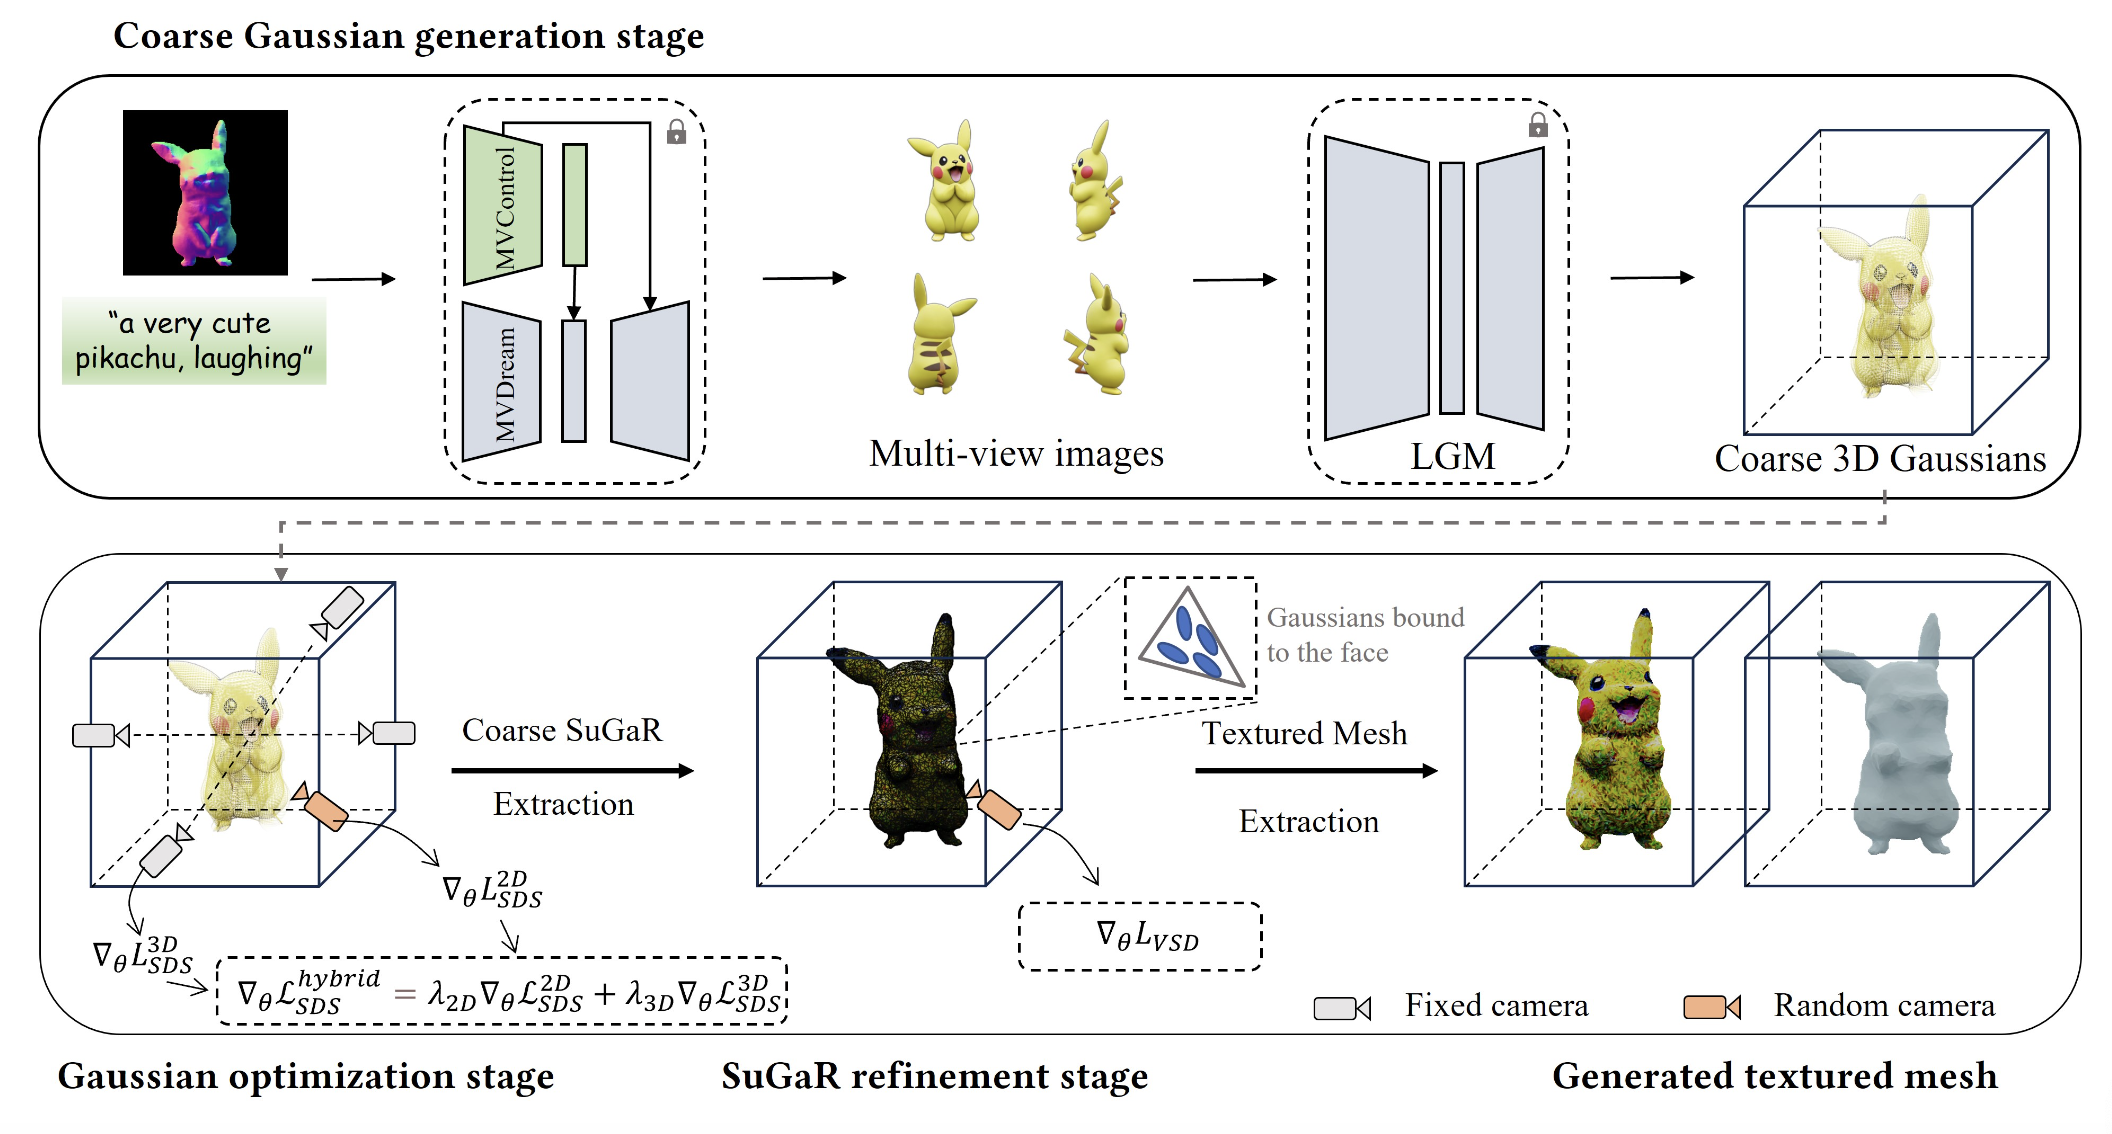
Controllable Text-to-3D Generation via Surface-Aligned Gaussian Splatting
arxiv{Paper} {Code} {Webpage}Details
-
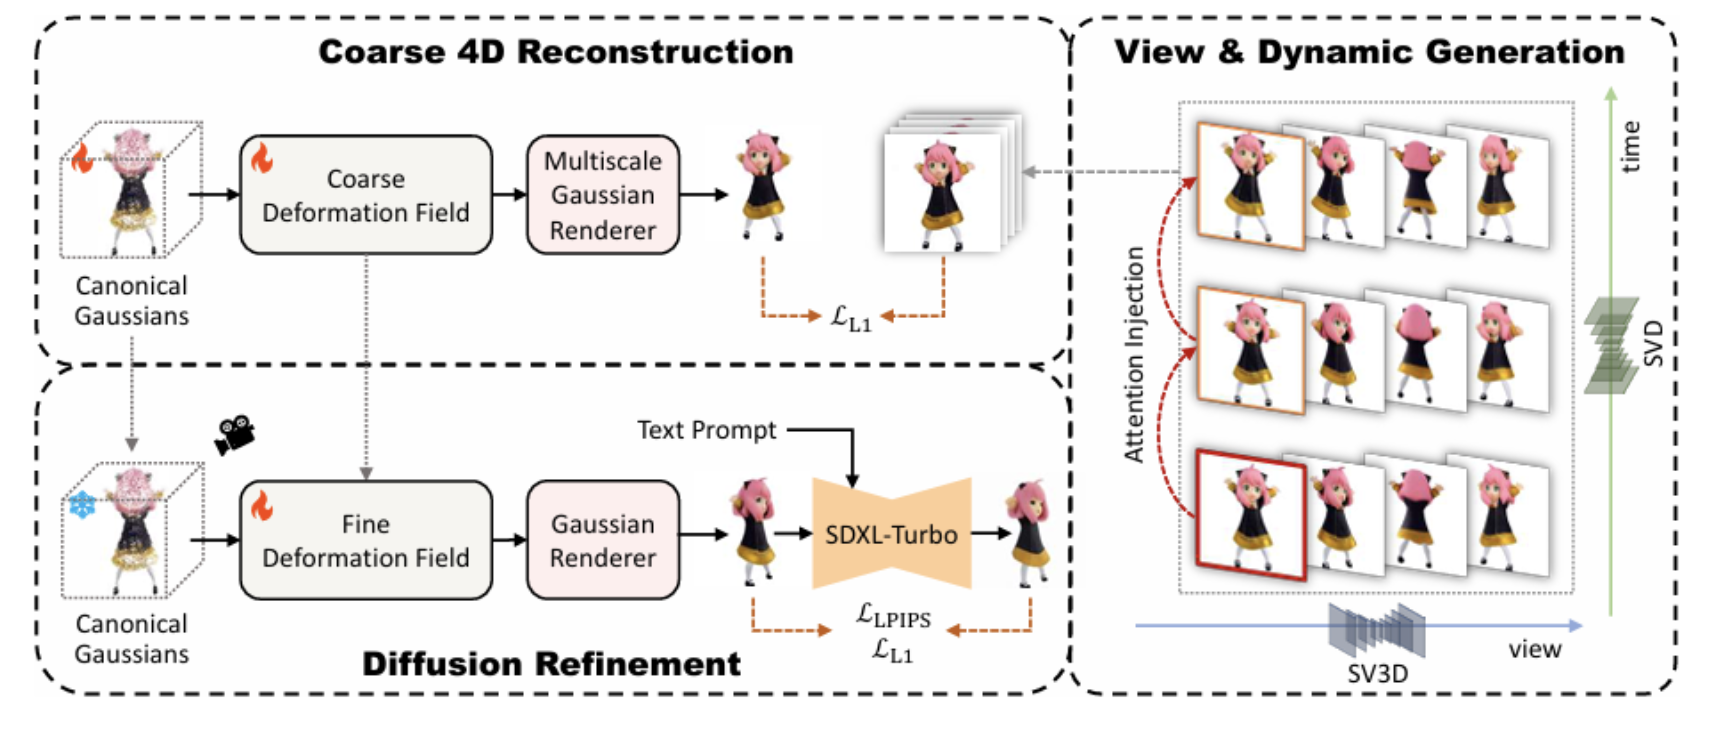
EG4D: Explicit Generation of 4D Object without Score Distillation
arxiv{Paper} {Code}Details
-
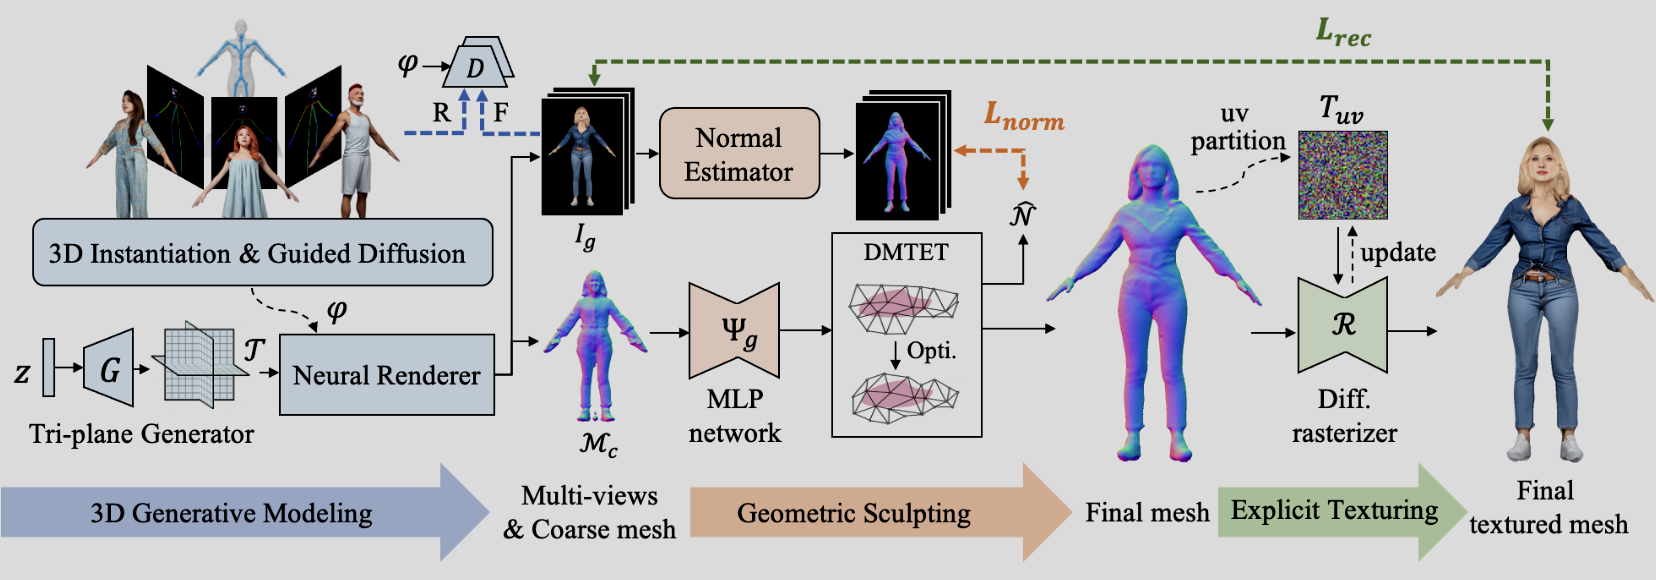
En3D: An Enhanced Generative Model for Sculpting 3D Humans from 2D Synthetic Data
arxiv{Paper} {Code} {Webpage} -
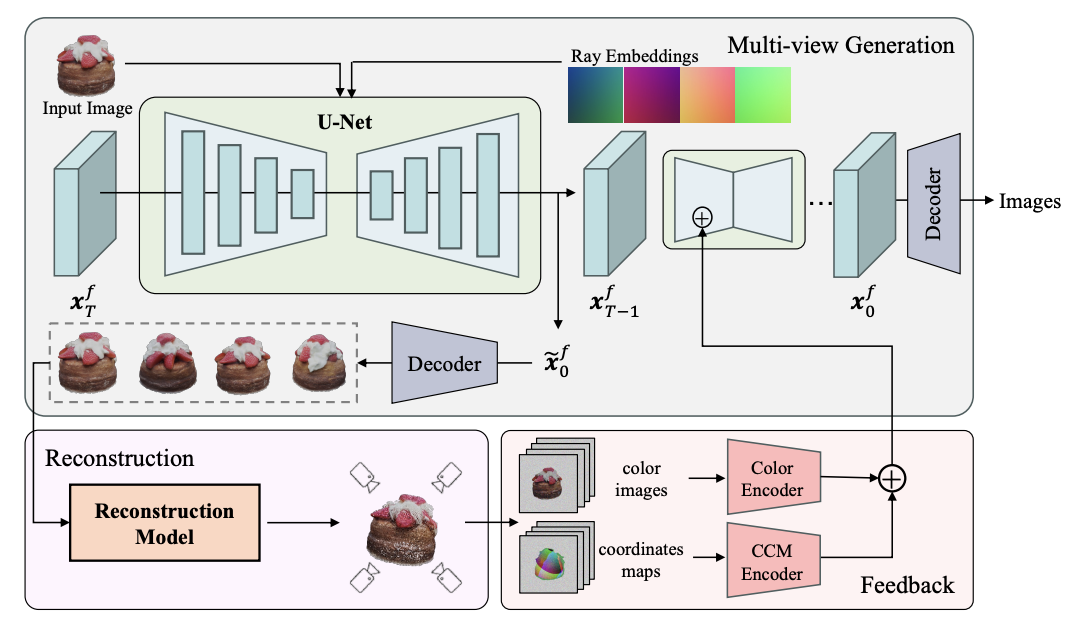
Ouroboros3D: Image-to-3D Generation via 3D-aware Recursive Diffusion
arxiv{Paper} {Code} {webpage}Details
-
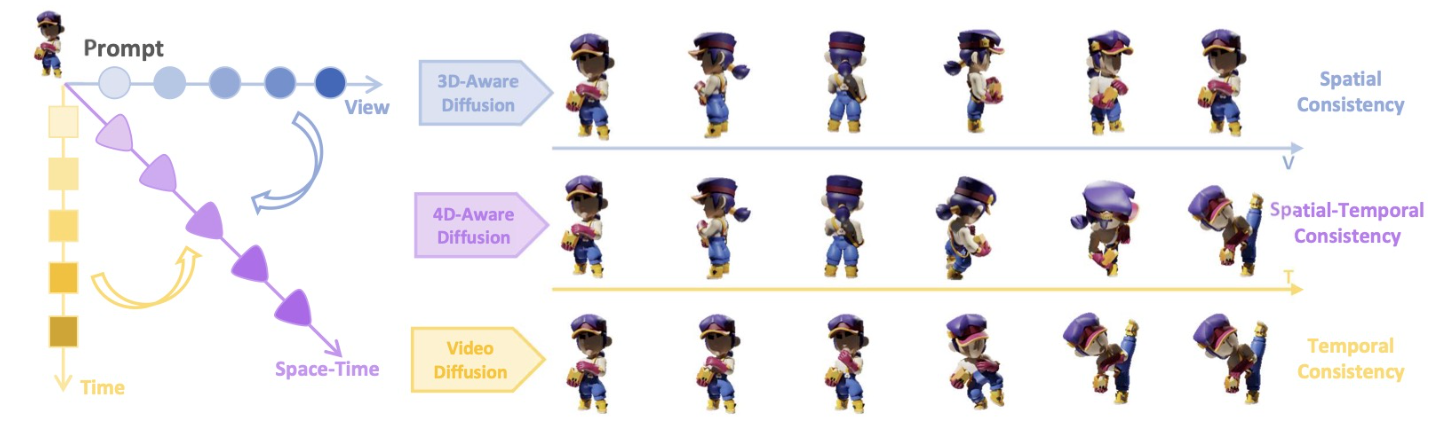
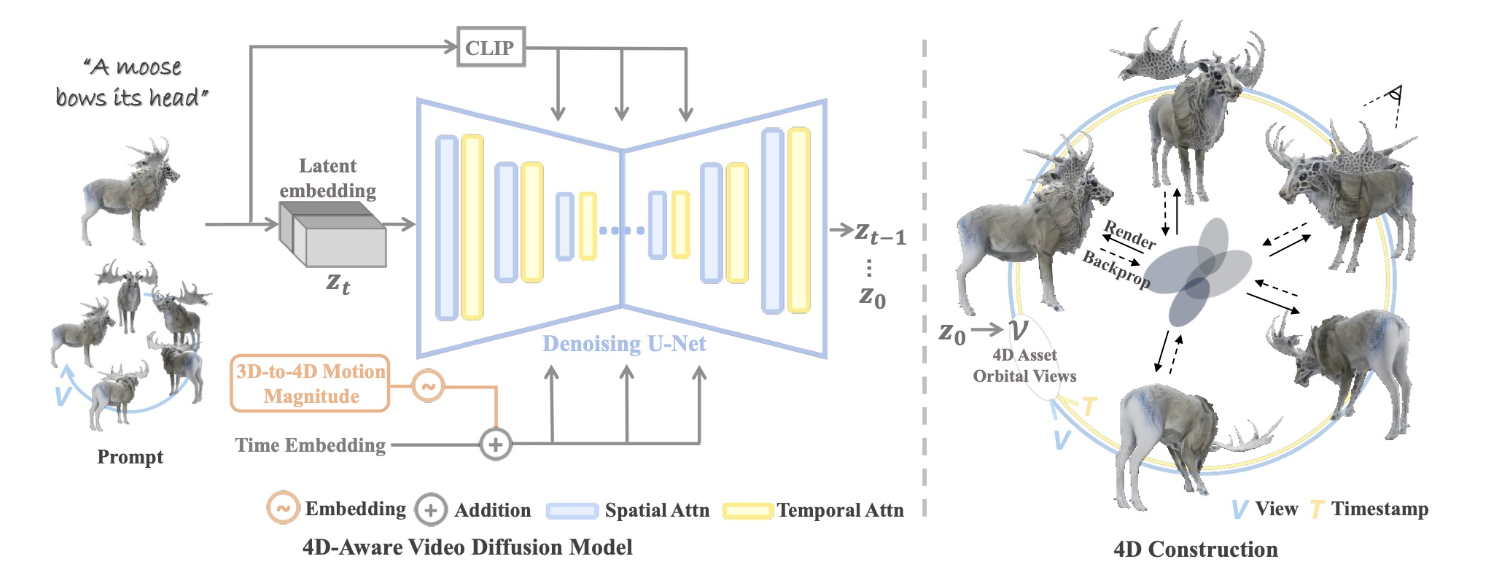
Diffusion4D: Fast Spatial-temporal Consistent 4D Generation via Video Diffusion Models
arxiv{Paper} {Code} {Webpage}
2023
- GP-VTON: Towards General Purpose Virtual Try-on via Collaborative Local-Flow Global-Parsing Learning
CVPR2023{Paper} {Code}Details

-
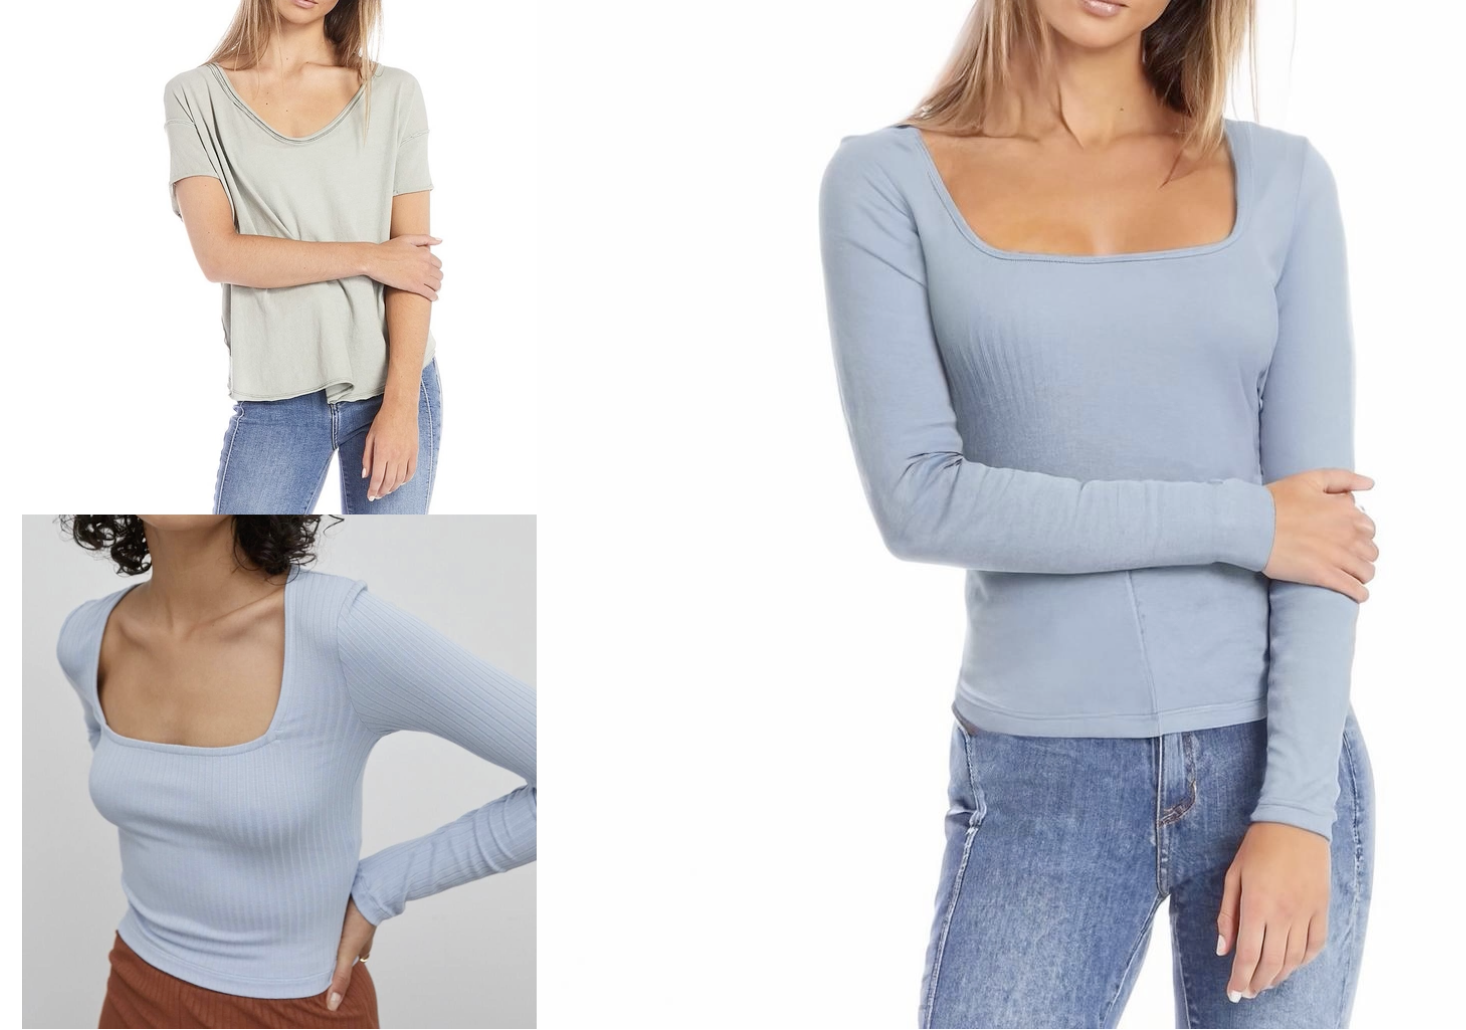
TryOnDiffusion: A Tale of Two UNets
CVPR 2023{Paper} {Code} {Webpage}Details
-
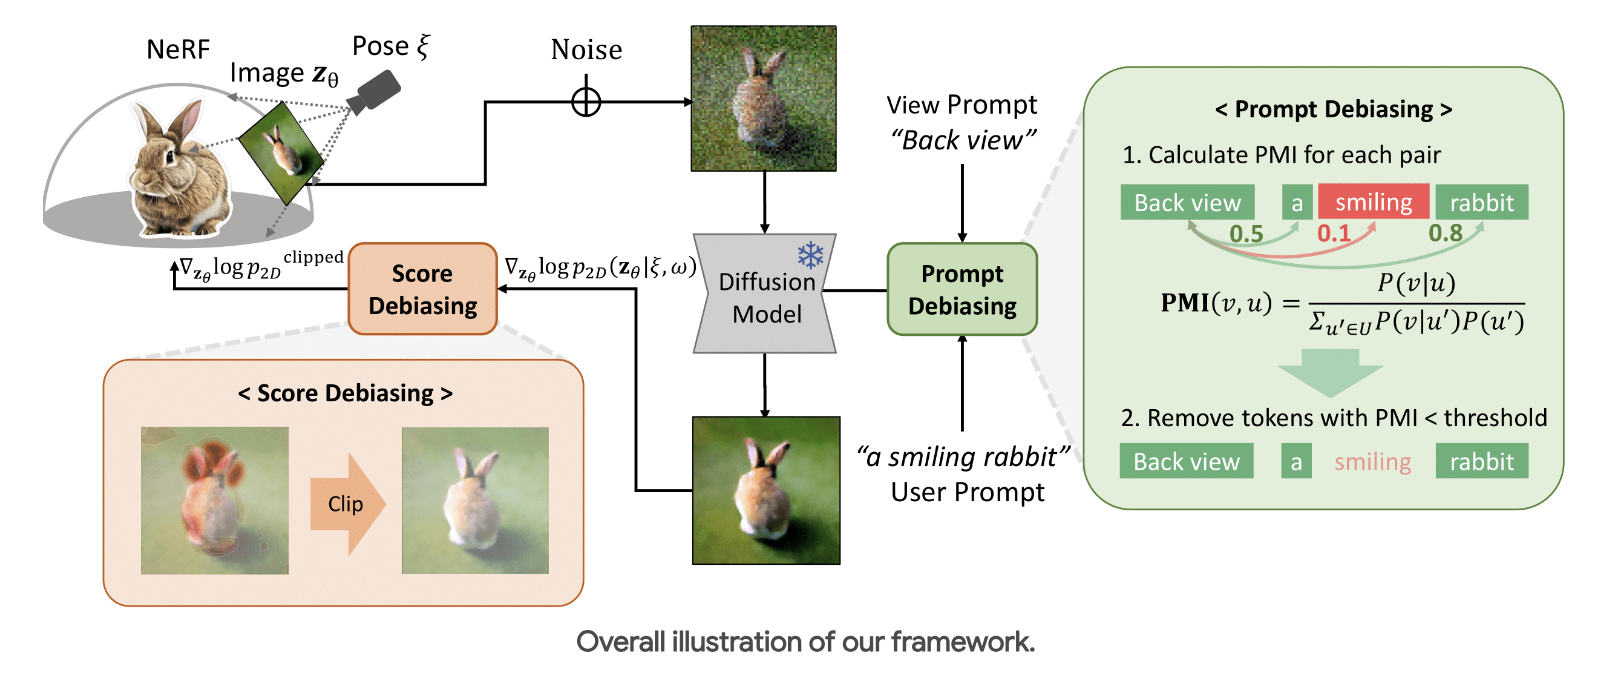
Debiasing Scores and Prompts of 2D Diffusion for View-consistent Text-to-3D Generation
NeurIPS 2023{Paper} {Code} {Webpage}Details
Text-prompted 3D Manipulation
2024
-
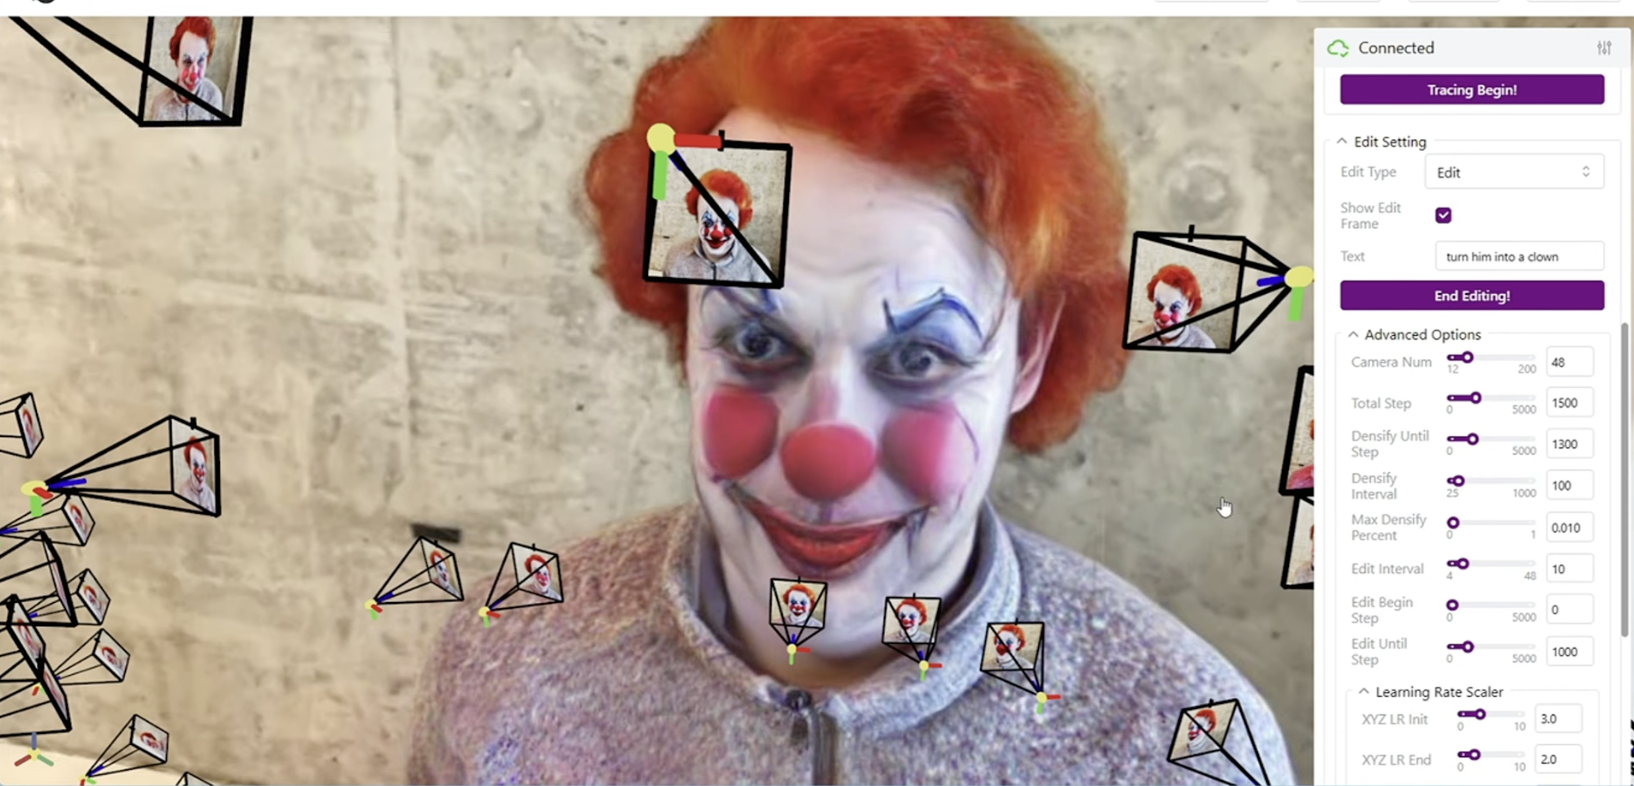
GaussianEditor (S-Lab, NTU, etc.): Swift and Controllable 3D Editing with Gaussian Splatting
CVPR2024{Paper} {Code} {Webpage}Details
-
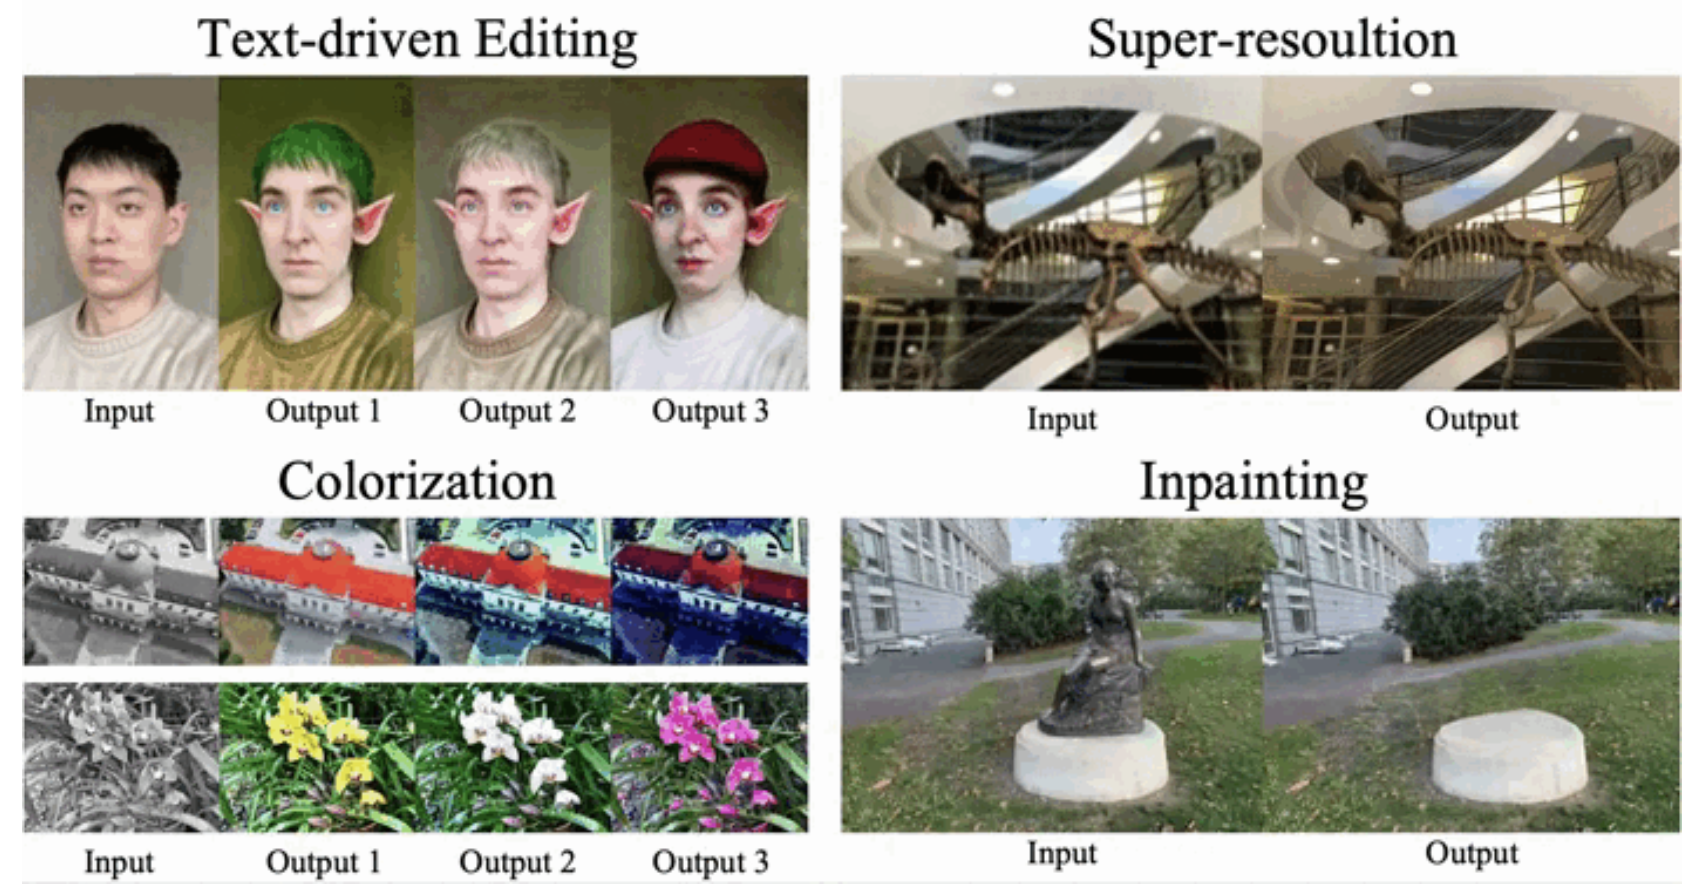
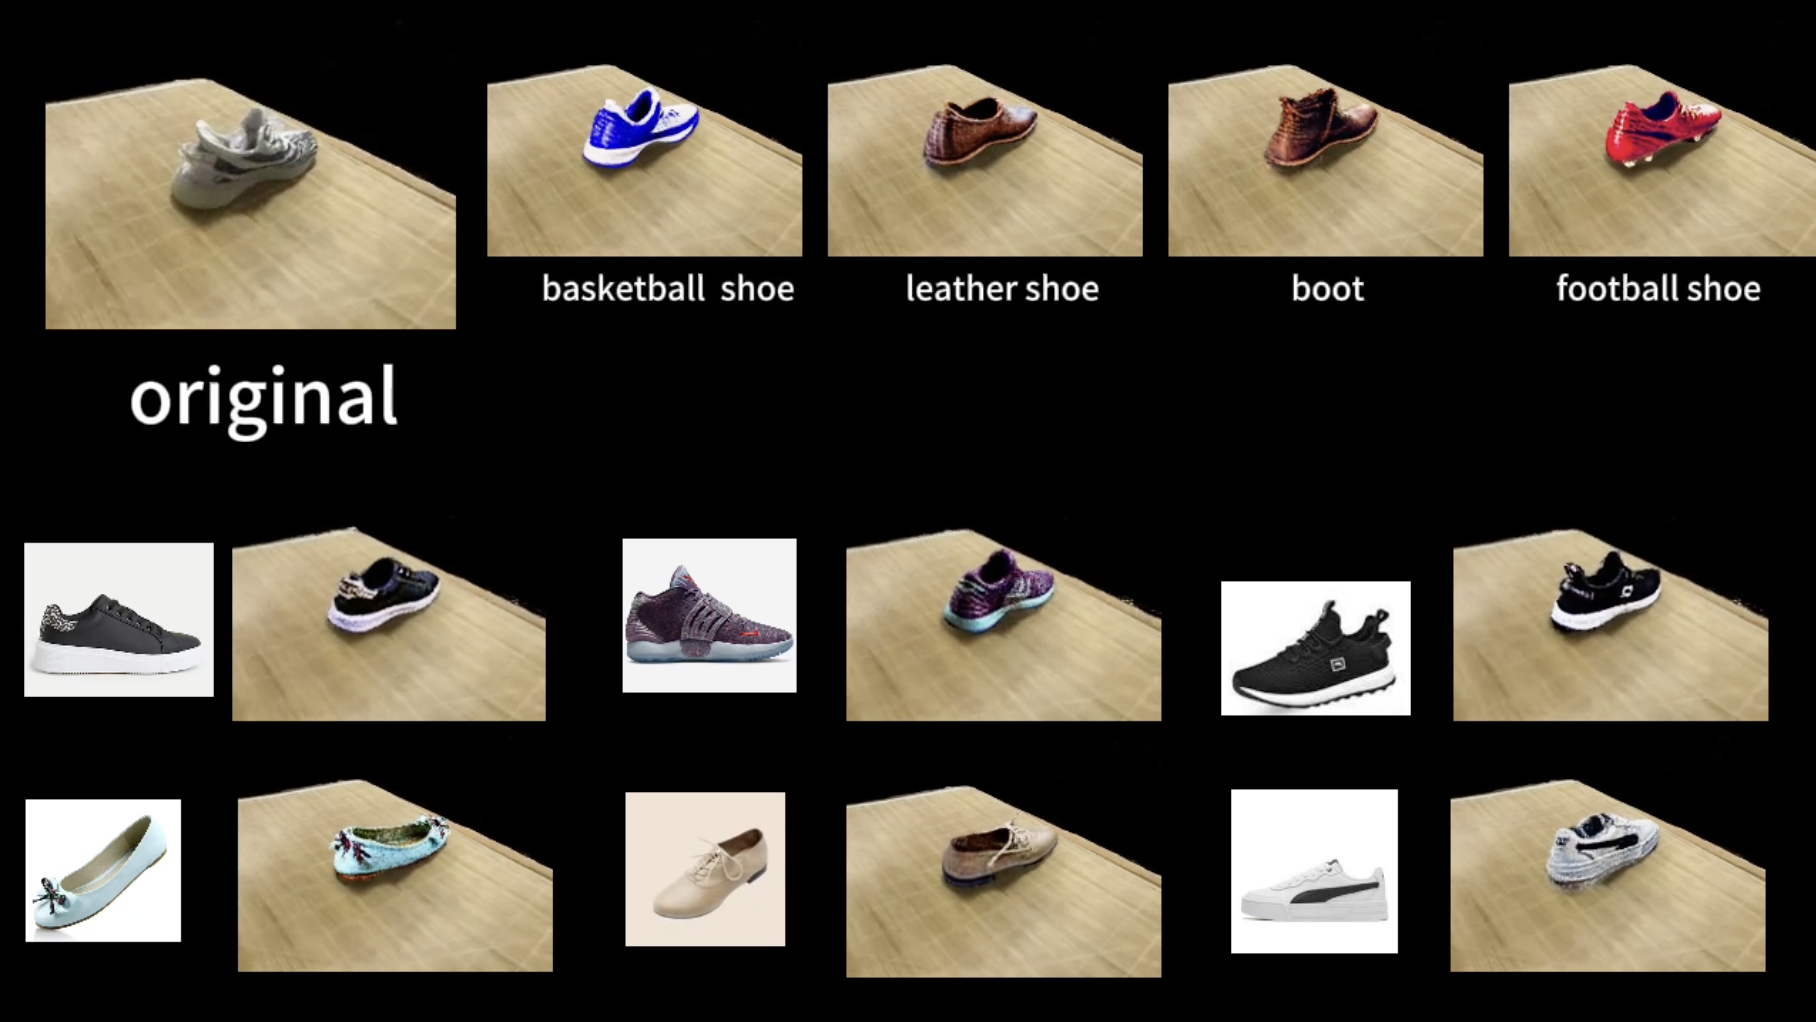
GenN2N: Generative NeRF2NeRF Translation for 3D Shape Manipulation
CVPR2024{Paper} {Code} {Webpage}Details
-
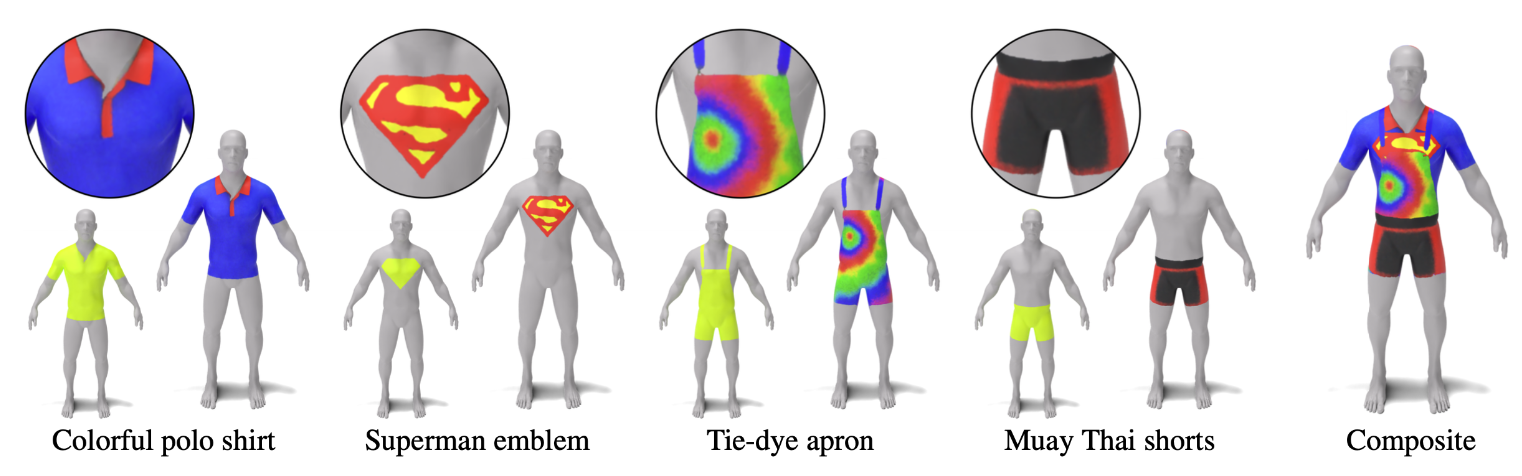
3D Paintbrush: Local Stylization of 3D Shapes with Cascaded Score Distillation
CVPR2024{Paper} {Code} {Webpage}Details
-
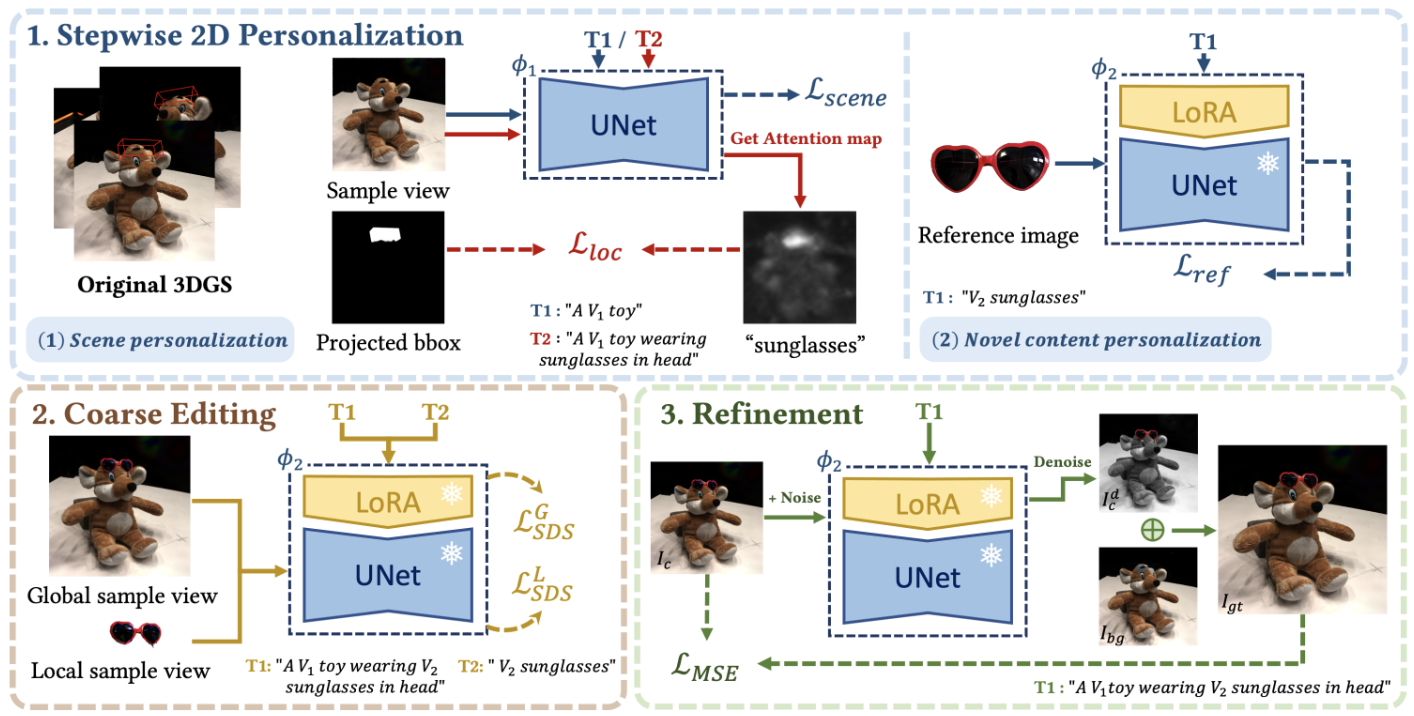
TIP-Editor: An Accurate 3D Editor Following Both Text-Prompts And Image-Prompts
arxiv{Paper} {Webpage}
-
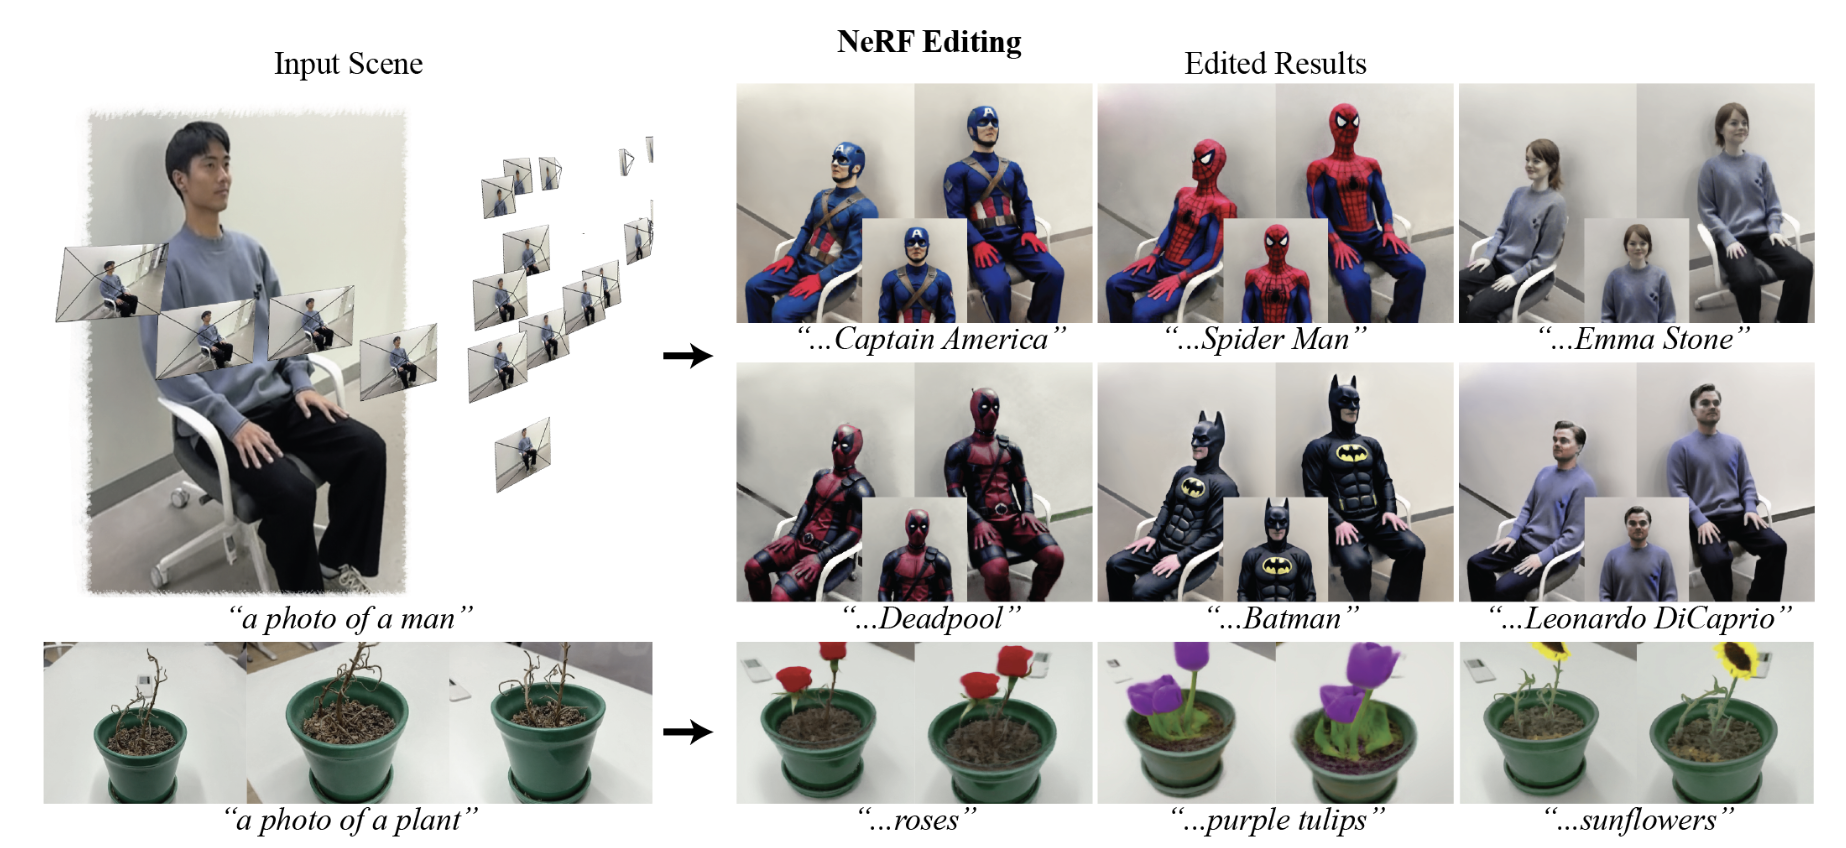
Customize your NeRF: Adaptive Source Driven 3D Scene Editing via Local-Global Iterative Training
CVPR2024{Paper} {Code} {Webpage} -
Posterior Distillation Sampling
CVPR 2024{Paper} {Code} {Webpage}Details
-
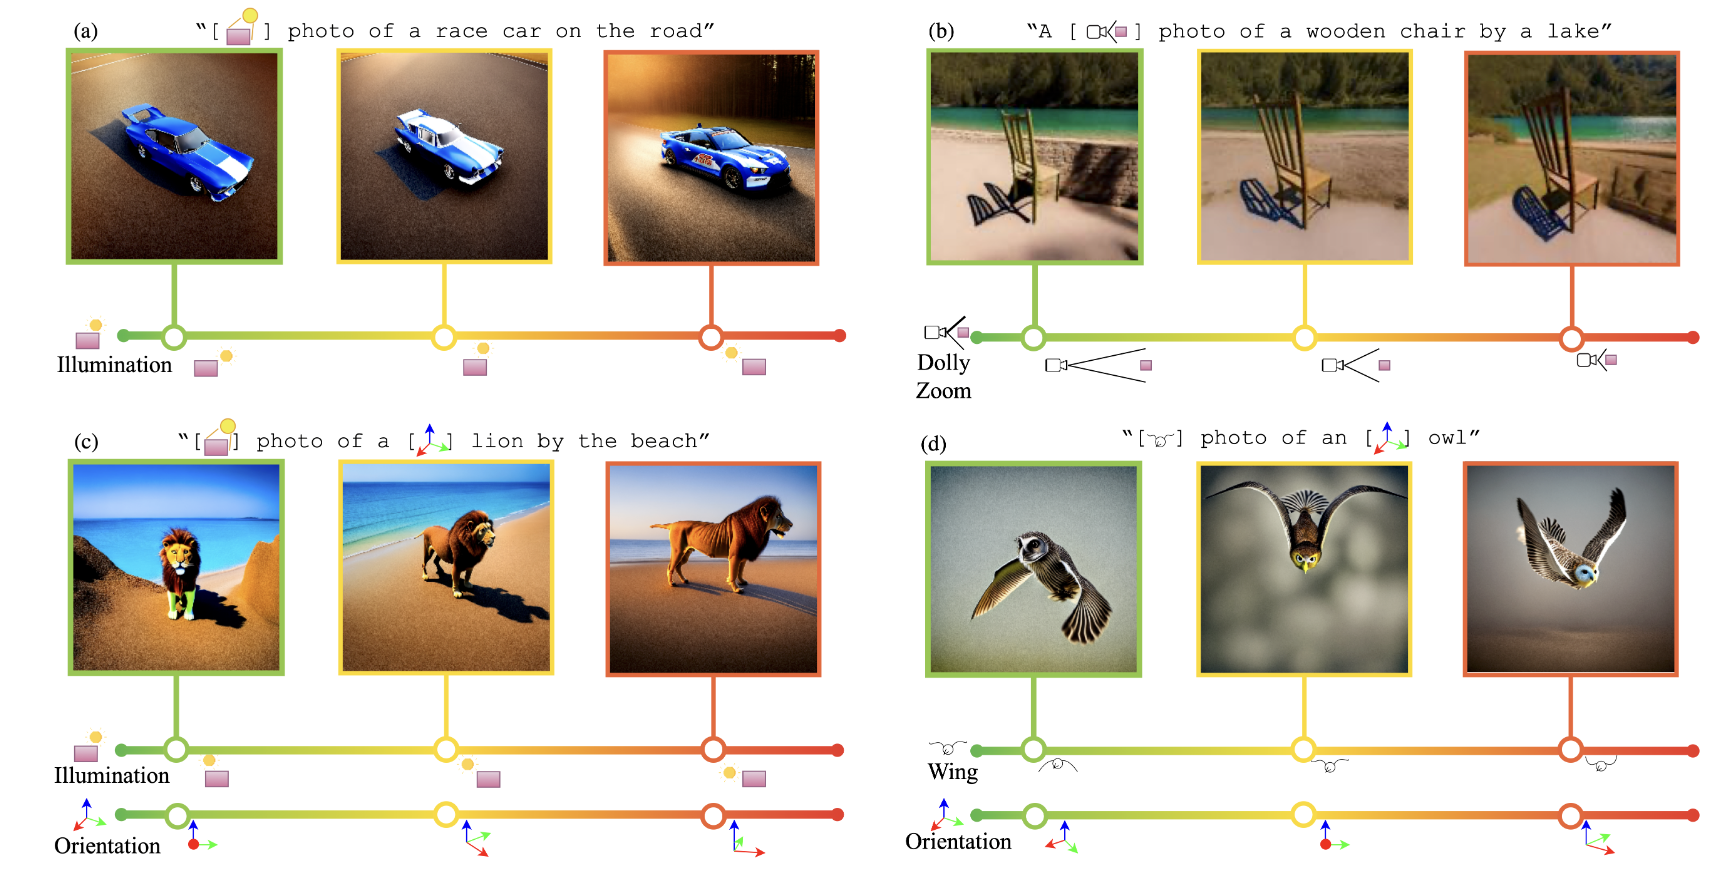
Learning Continuous 3D Words for Text-to-Image Generation
CVPR 2024{Paper} {Code} {Webpage}Details
-
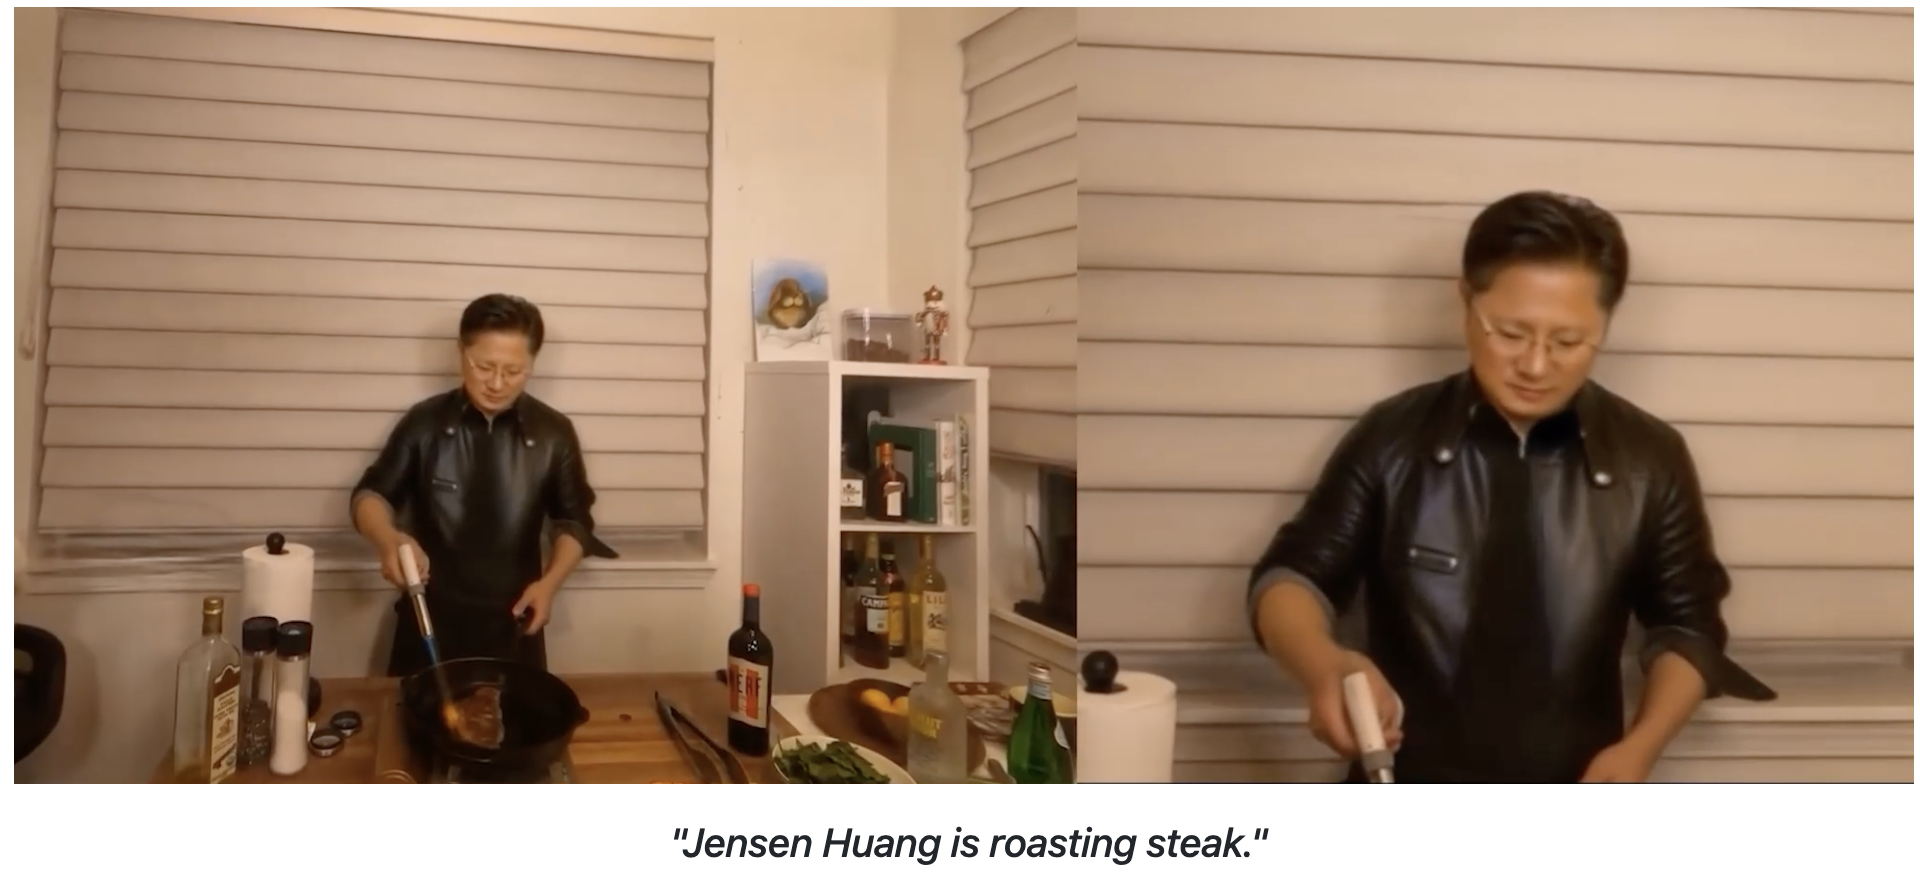
Control4D: Efficient 4D Portrait Editing with Text
CVPR 2024{Paper}{Webpage}Details
-
En3D: An Enhanced Generative Model for Sculpting 3D Humans from 2D Synthetic Data
arxiv{Paper} {Code} {Webpage} -
Diffusion4D: Fast Spatial-temporal Consistent 4D Generation via Video Diffusion Models
arxiv{Paper} {Code} {Webpage}
2023
-
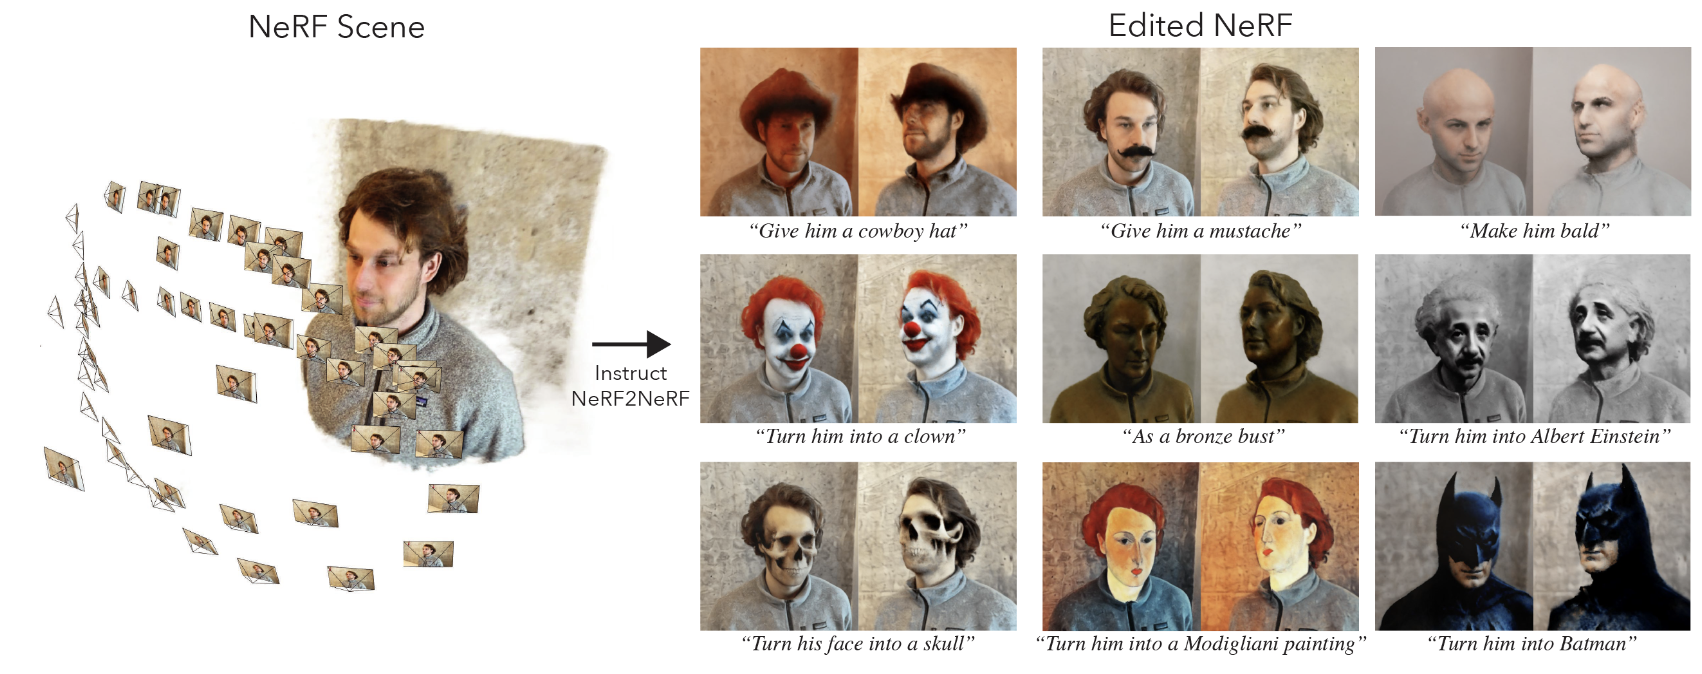
Instruct-NeRF2NeRF: Editing 3D Scenes with Instructions
ICCV2023{Paper} {Code}Details
-
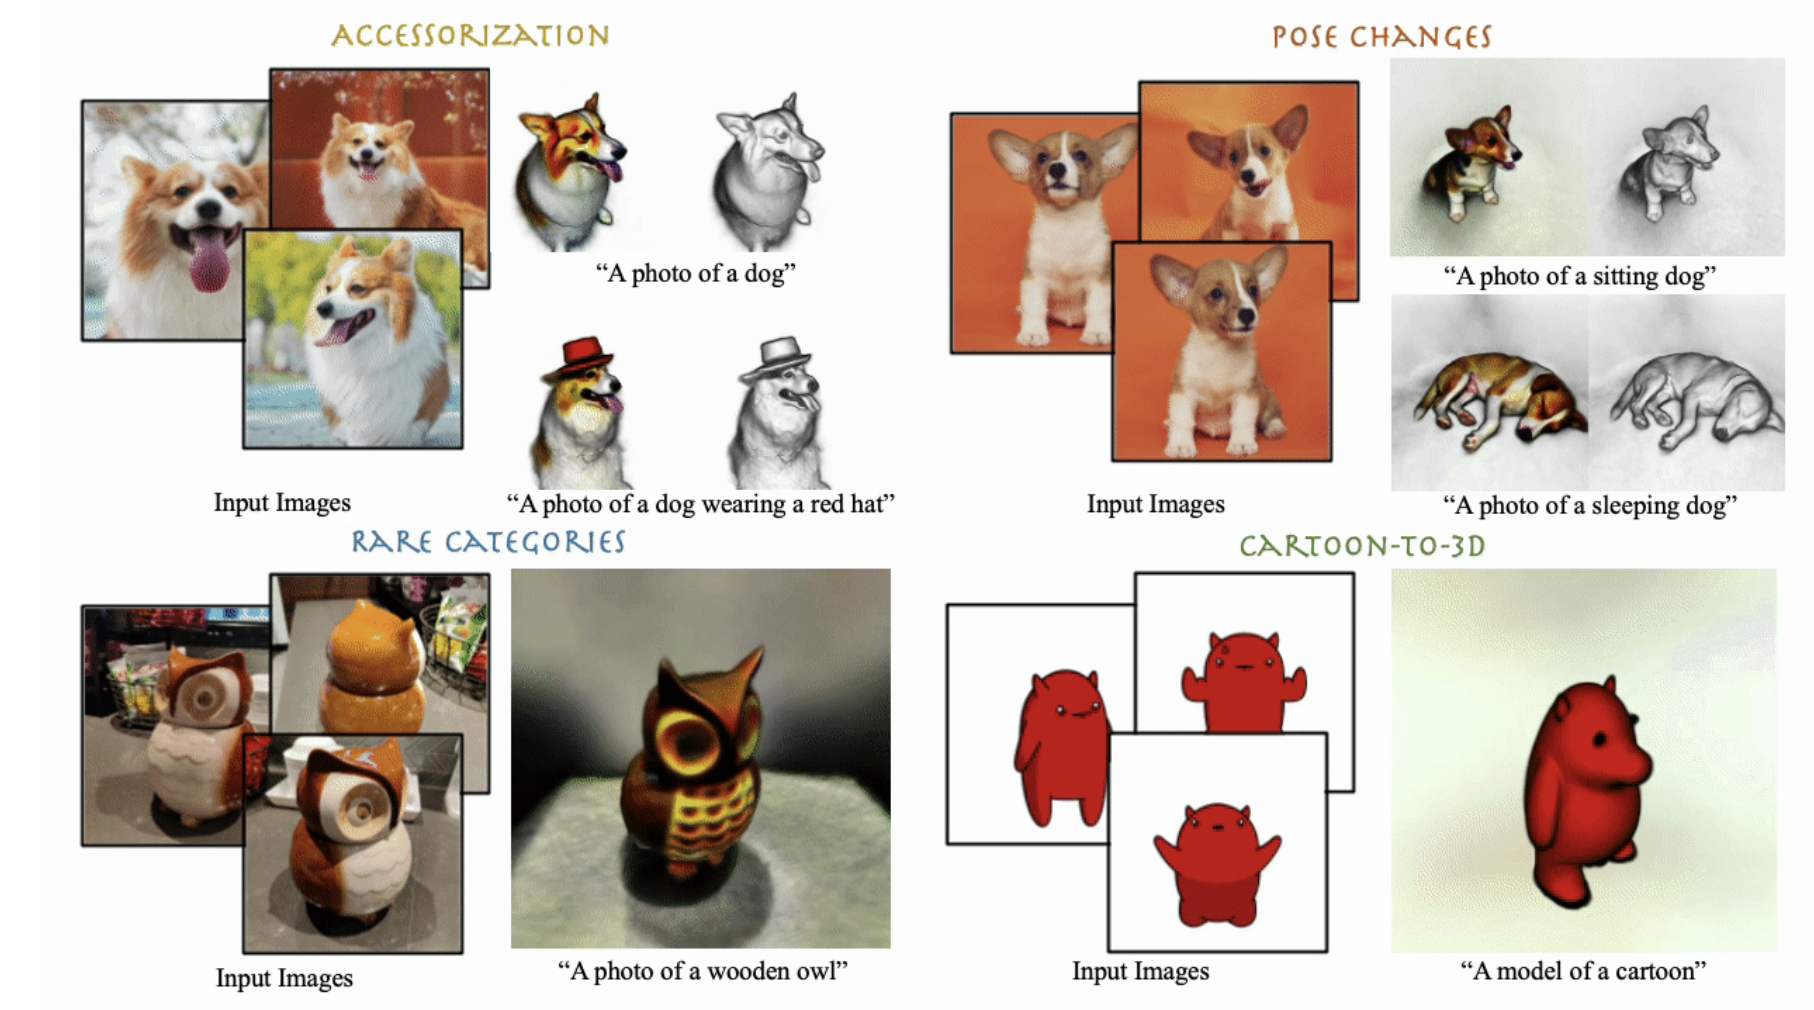
DreamBooth3D: Subject-Driven Text-to-3D Generation with Dream Fields
ICCV2023{Paper} {Webpage}Details
-
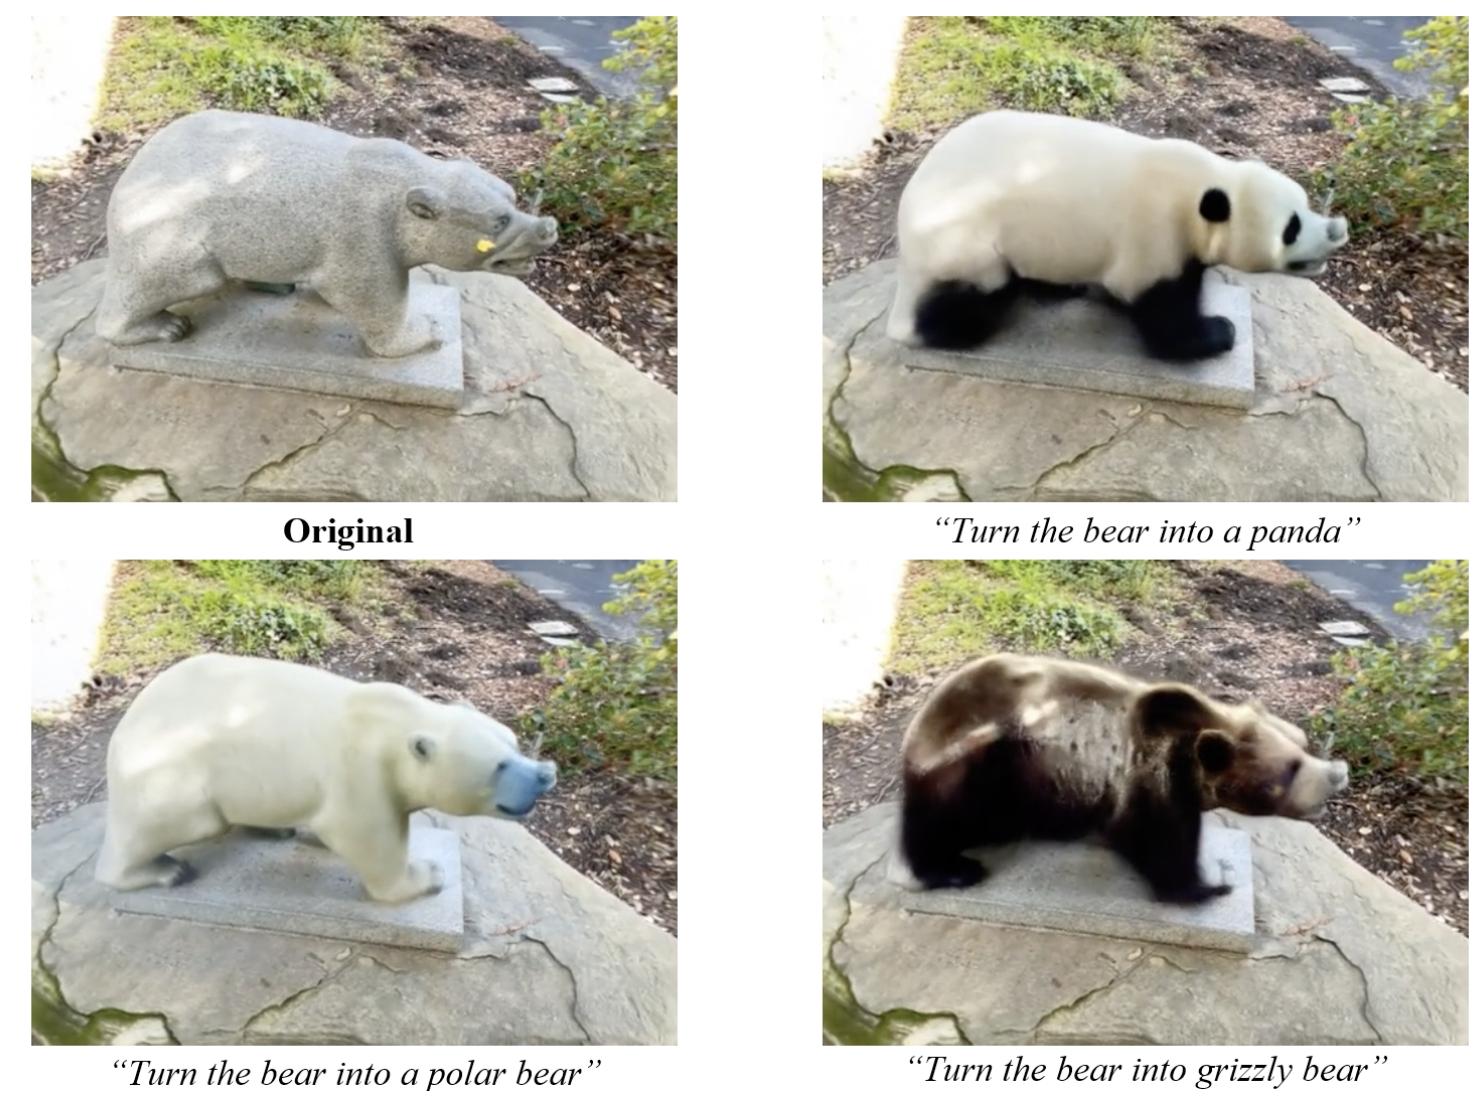
GaussianEditor (Huawei): Editing 3D Gaussians Delicately with Text Instructions
arxiv{Paper} {Webpage}Details
-
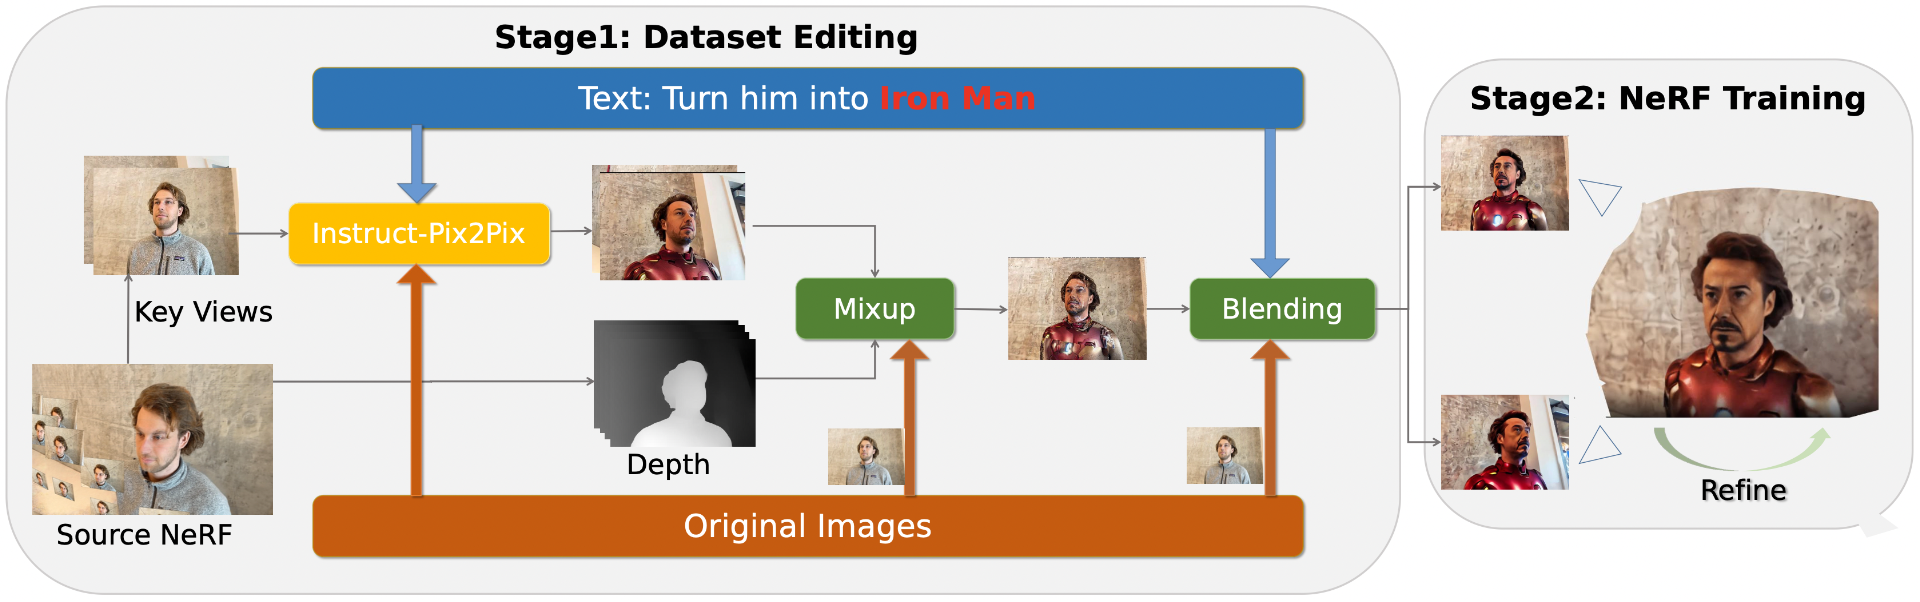
ViCA-NeRF: View-Consistency-Aware 3D Editing of Neural Radiance Fields
NeurIPS 2023{Paper} {Code} {Webpage}Details
Customized Video Generation
Image-prompted Video Generation
2024
-
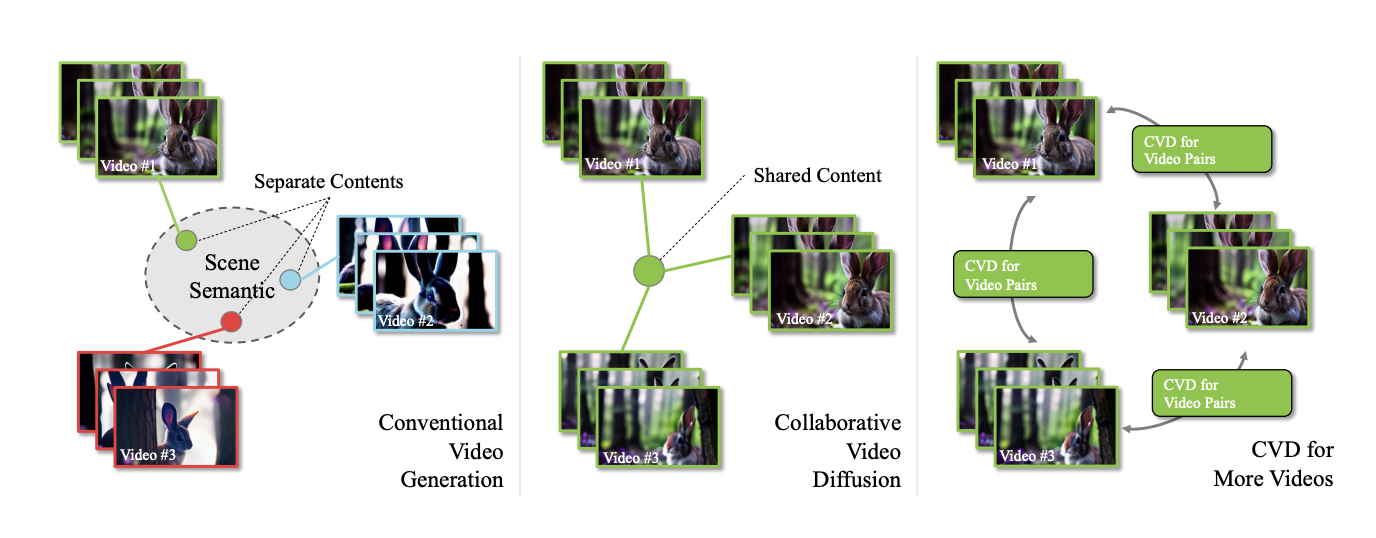
Collaborative Video Diffusion: Consistent Multi-video Generation with Camera Control
arxiv{Paper} {Code} {Webpage}Details
-
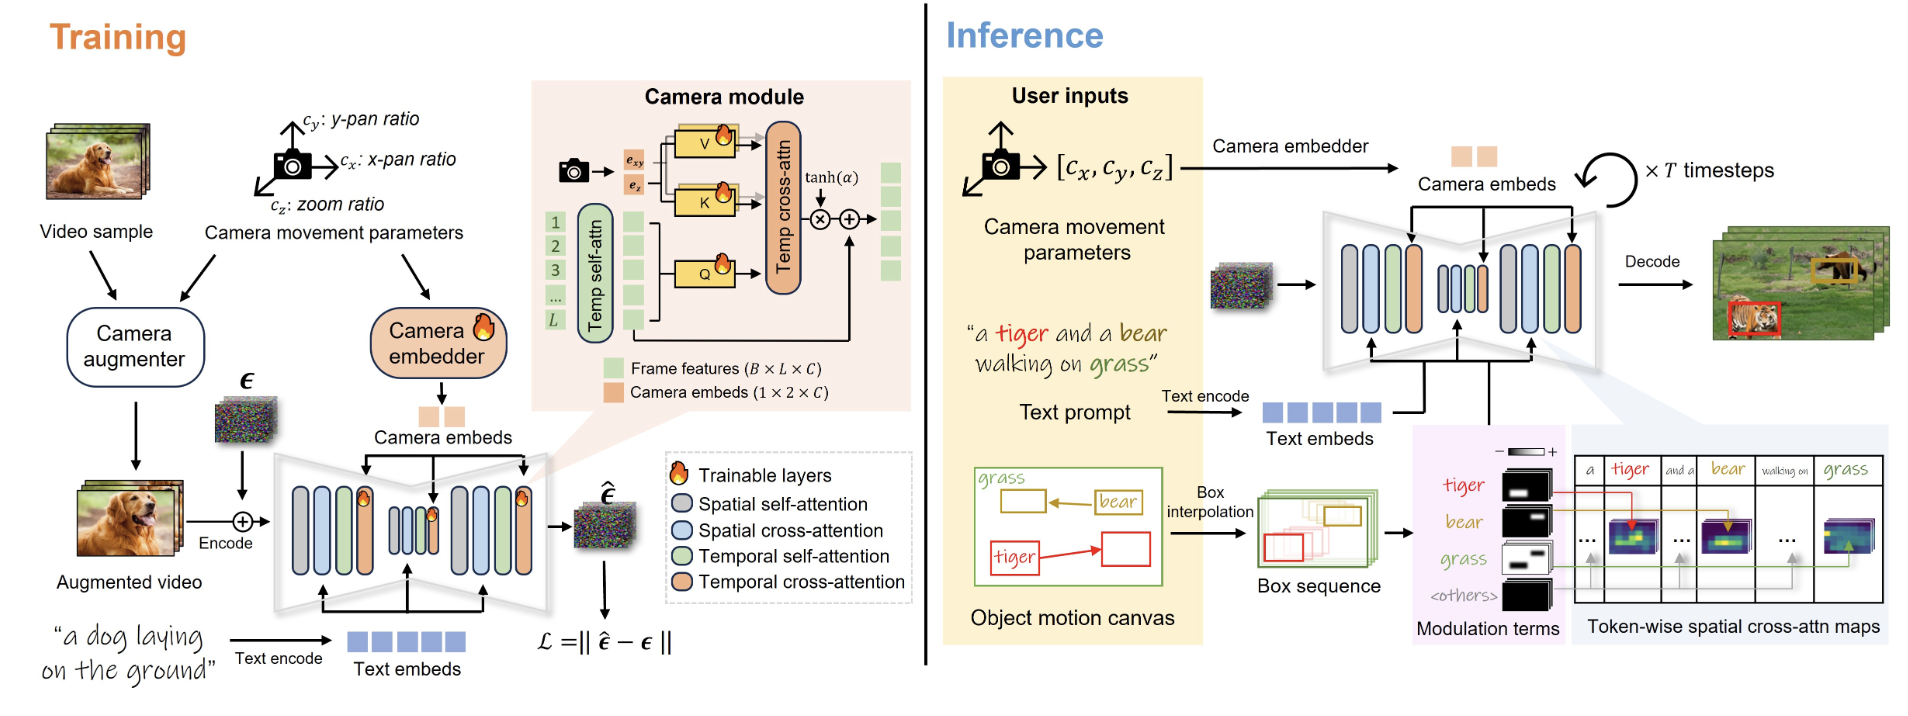
Direct-a-Video: Customized Video Generation with User-Directed Camera Movement and Object Motion
arxiv{Paper} {Code} {Webpage} -
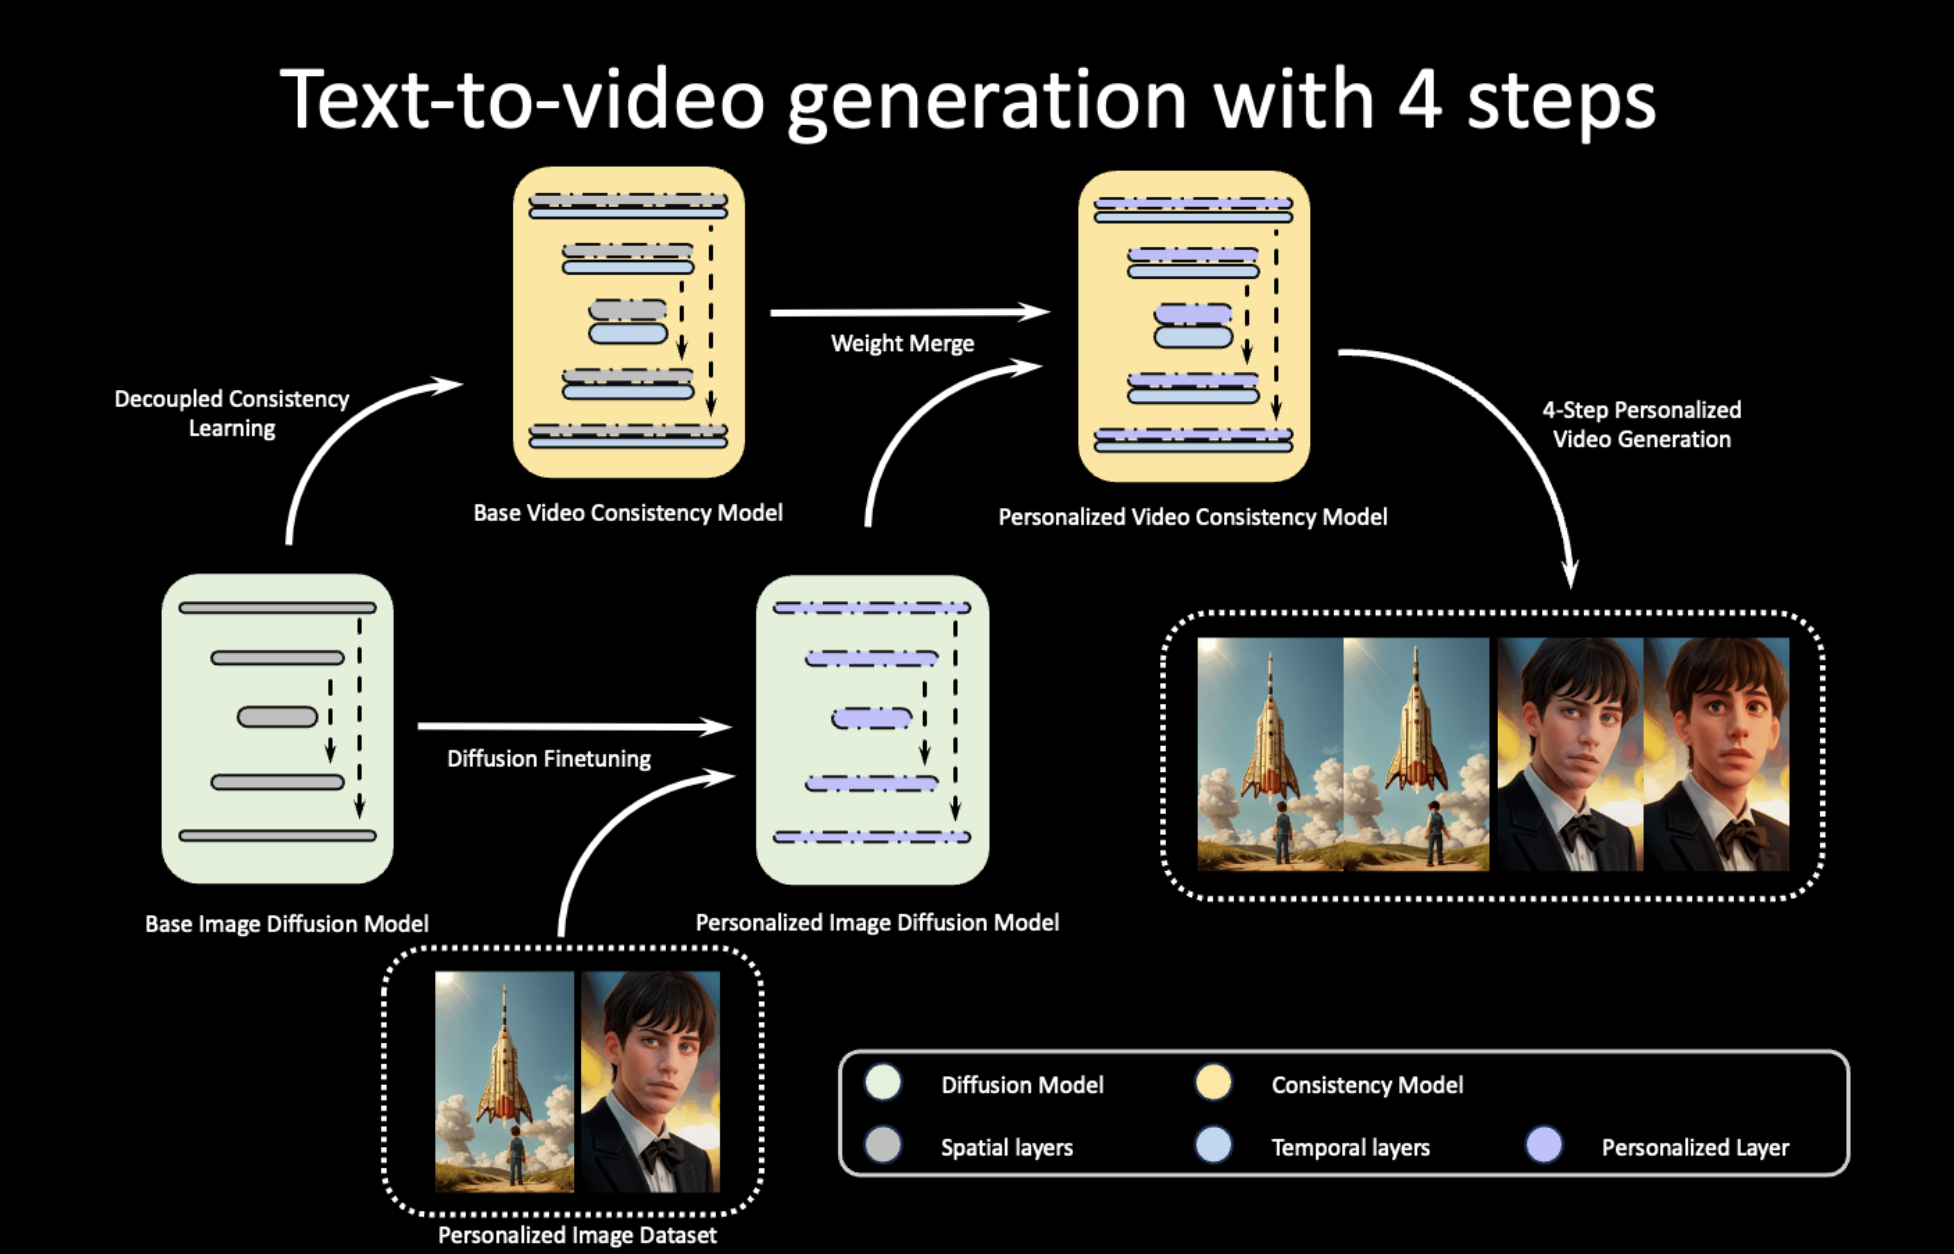
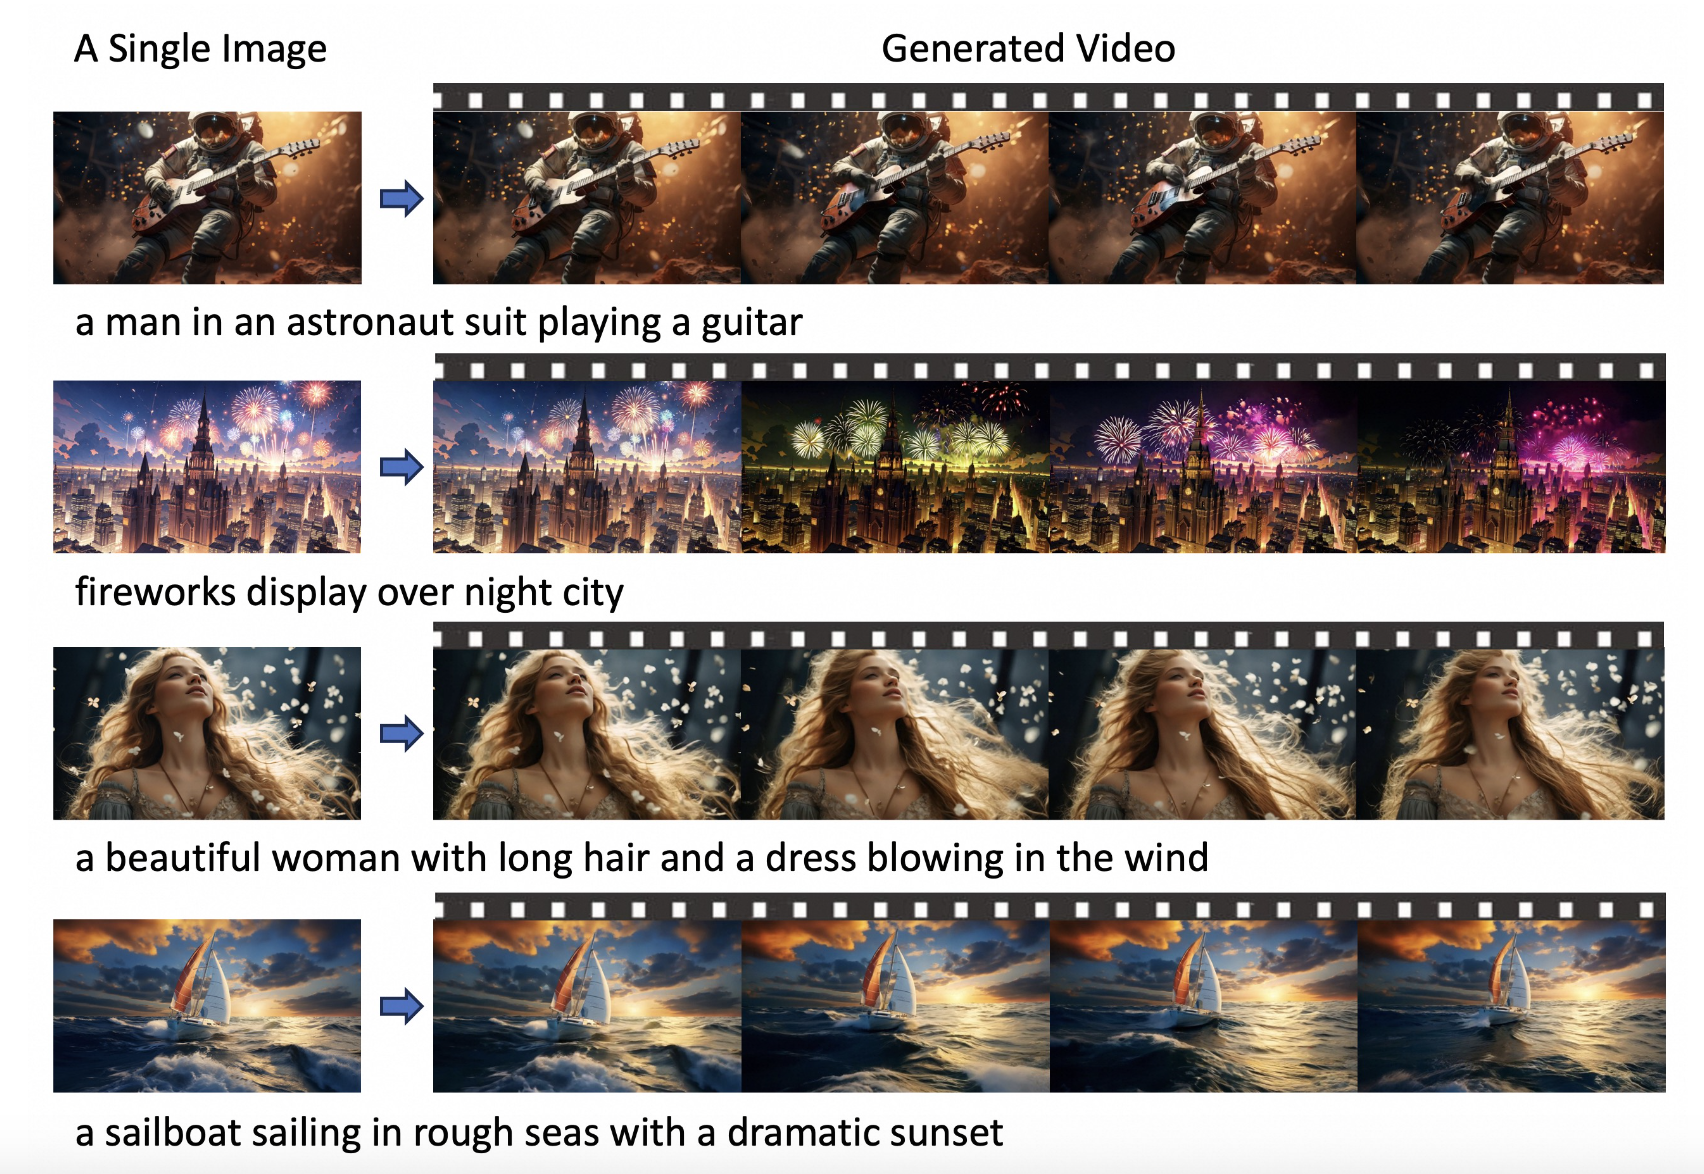
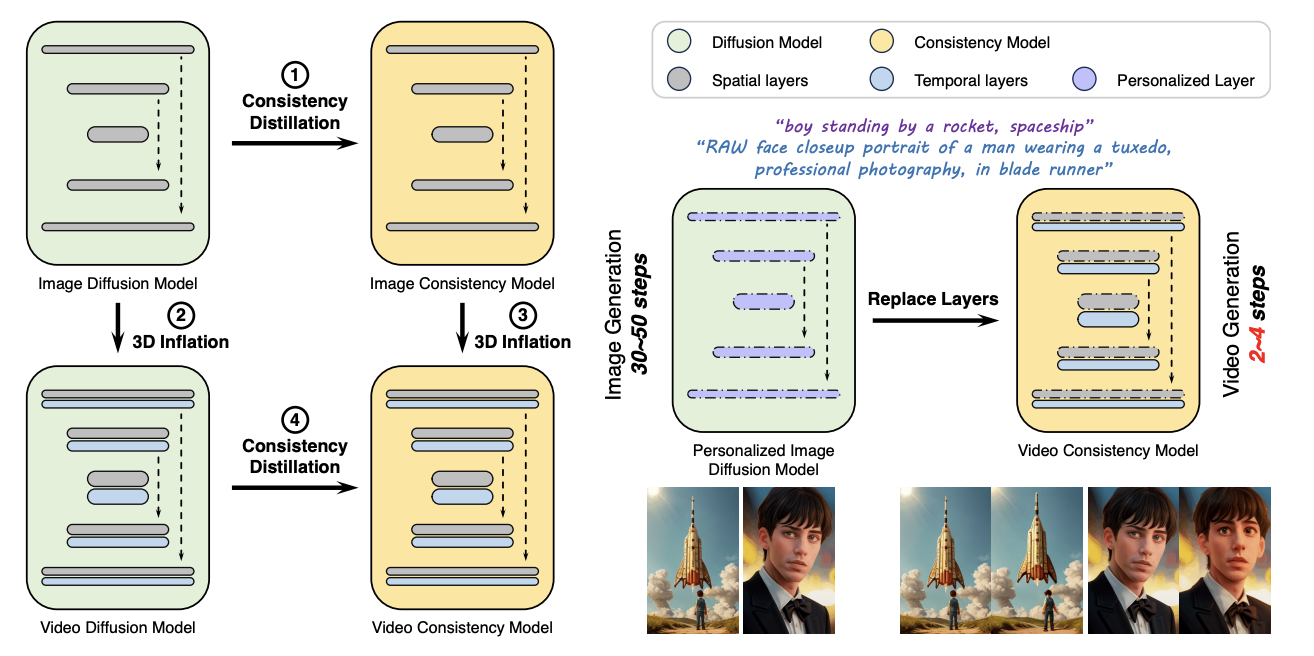
AnimateLCM: Accelerating the Animation of Personalized Diffusion Models and Adapters with Decoupled Consistency Learning
arxiv{Paper} {Code} {Webpage} -
Motion Consistency Model: Accelerating Video Diffusion with Disentangled Motion-Appearance Distillation
arxiv{Paper} {Code} {Webpage} -
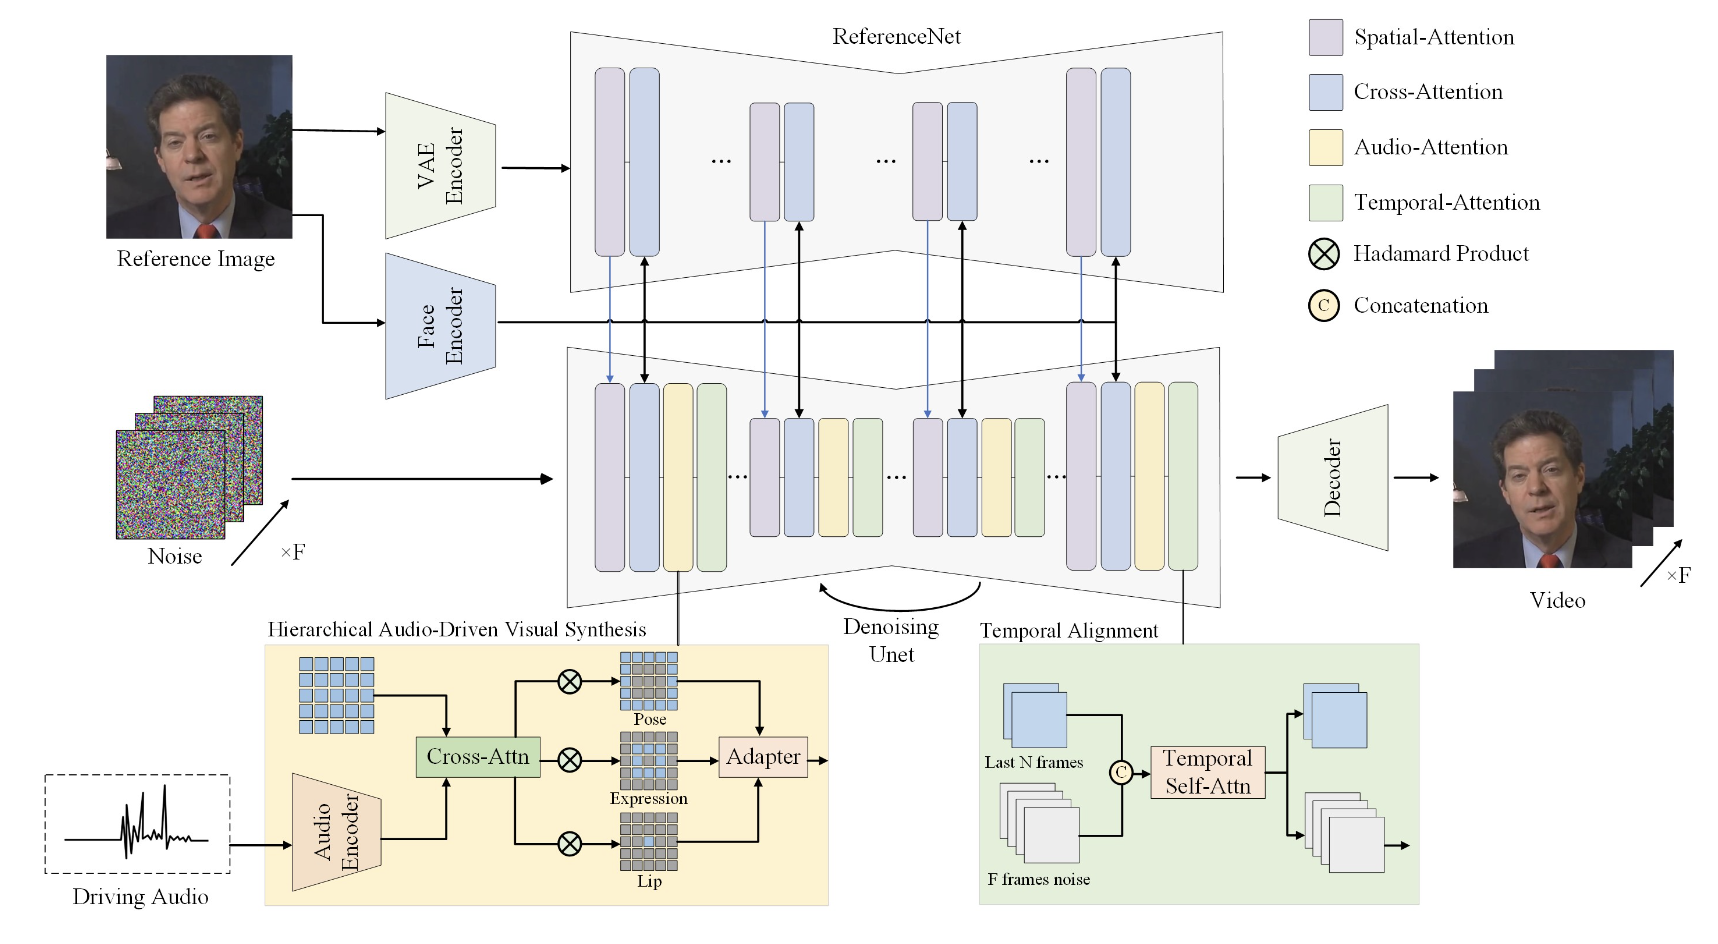
Hallo: Hierarchical Audio-Driven Visual Synthesis for Portrait Image Animation
arxiv{Paper} {Code} {Webpage}Details
-
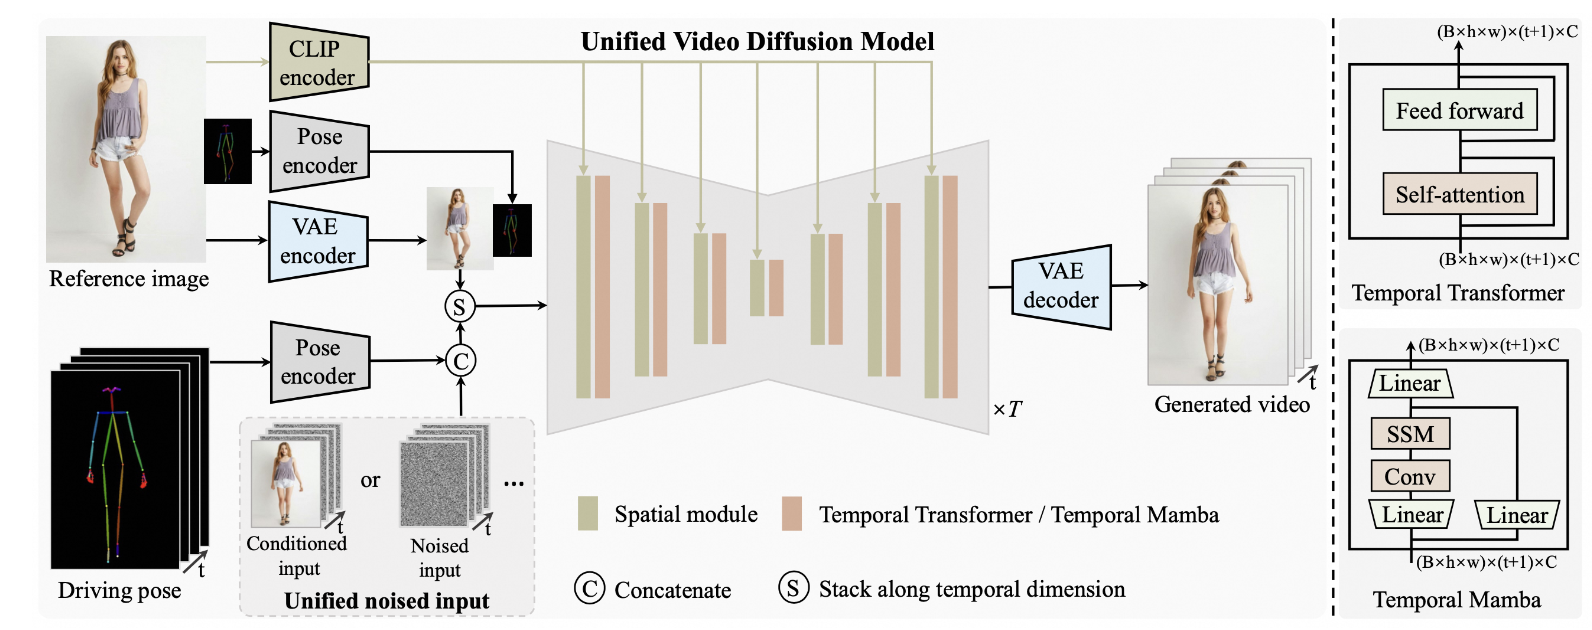
UniAnimate: Taming Unified Video Diffusion Models for Consistent Human Image Animation
arxiv{Paper} {Code} {Webpage}Details
-
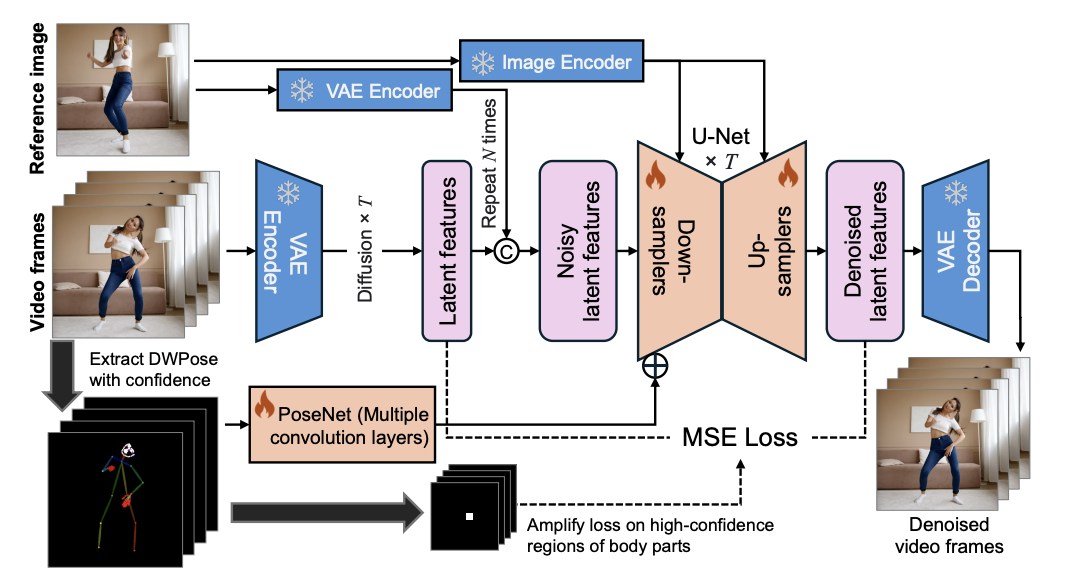
MimicMotion: High-Quality Human Motion Video Generation with Confidence-aware Pose Guidance
arxiv{Paper} {Code} {Webpage}Details
-
EasyAnimate: A High-Performance Long Video Generation Method based on Transformer Architecture
arxiv{Paper} {Code} {Webpage} -
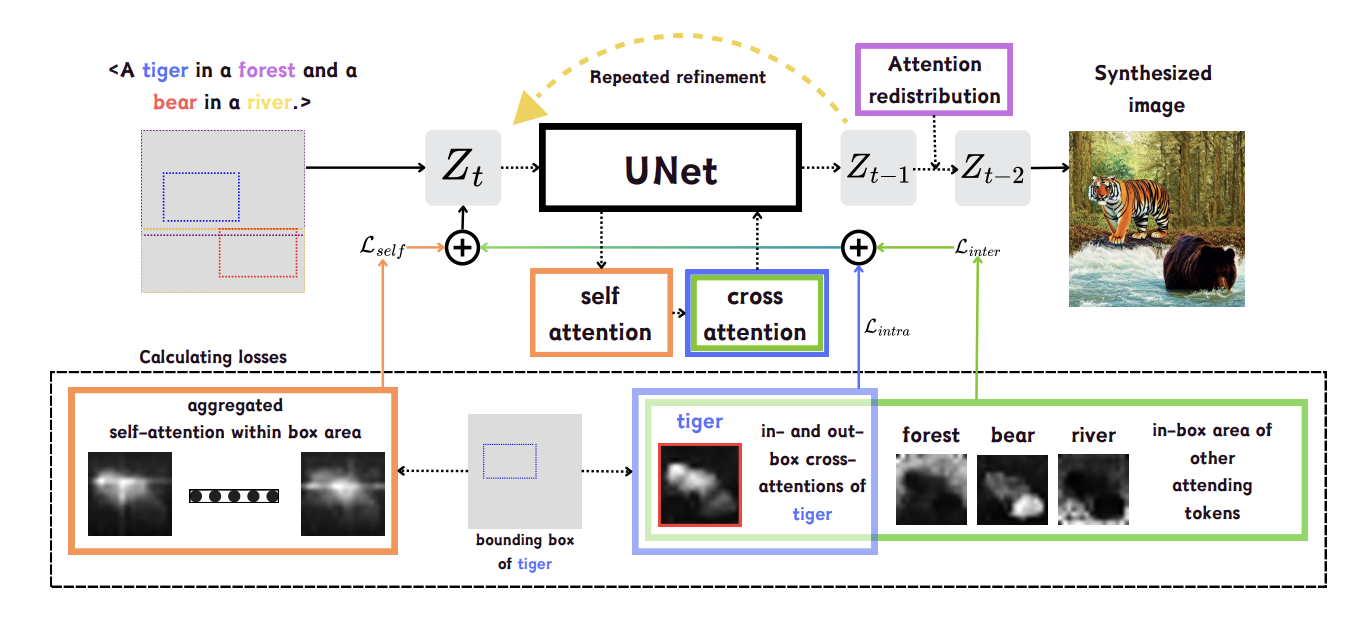
Training-free Composite Scene Generation for Layout-to-Image Synthesis
arxiv{Paper} {Code}Details
-
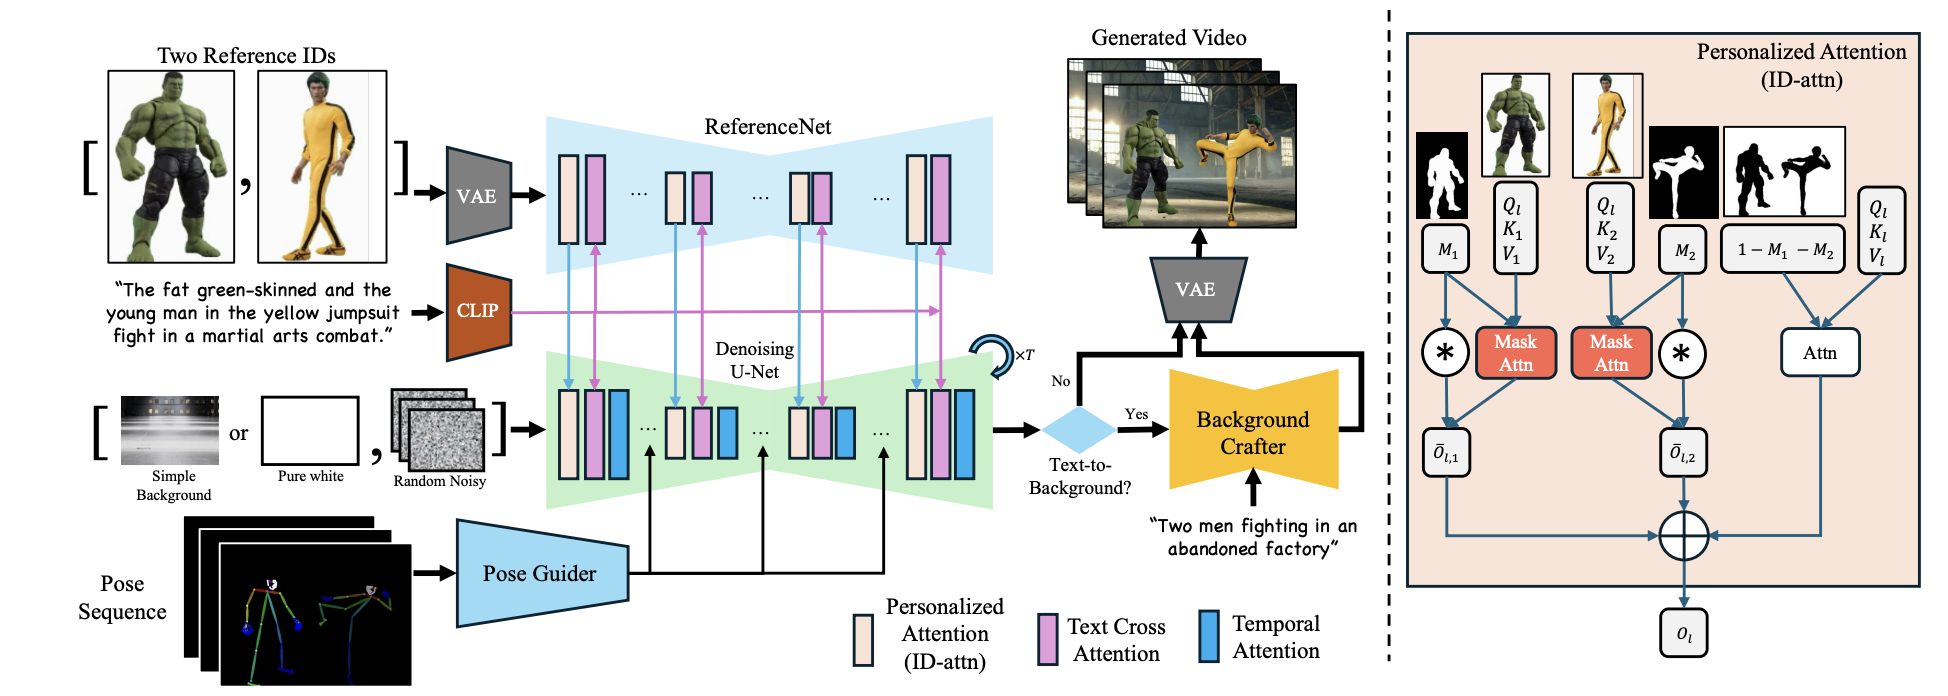
MagicFight: Personalized Martial Arts Combat Video Generation
openreview{Paper}Details
-
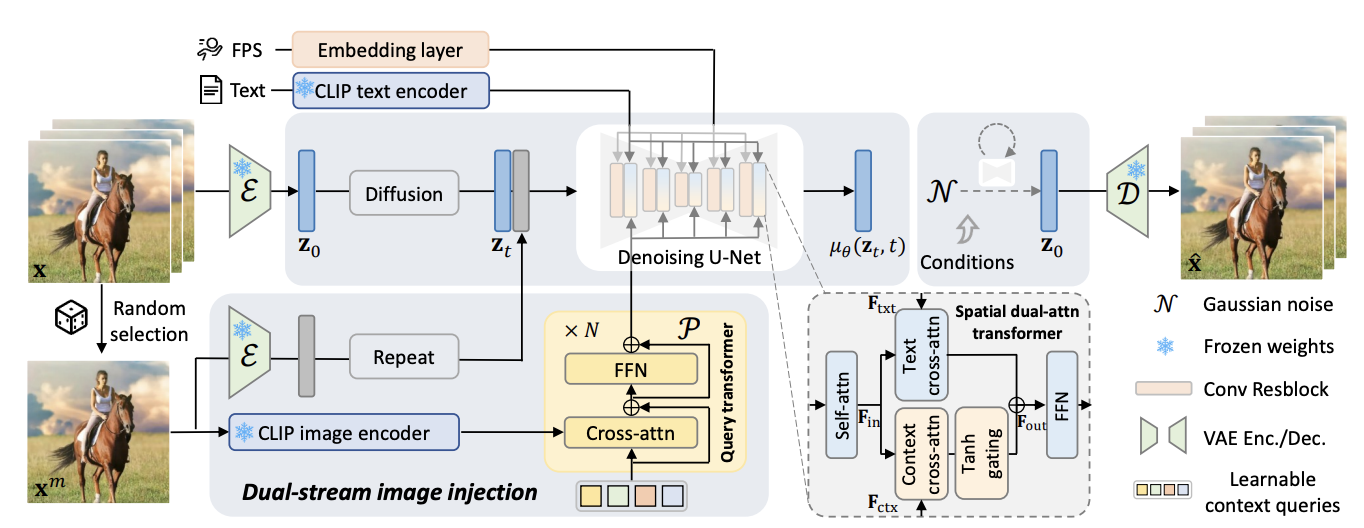
DynamiCrafter: Animating Open-domain Images with Video Diffusion Priors
ECCV 2024{Paper} {Code} {Webpage}Details

Text-prompted Video Generation
2024
-
Direct-a-Video: Customized Video Generation with User-Directed Camera Movement and Object Motion
arxiv{Paper} {Code} {Webpage} -
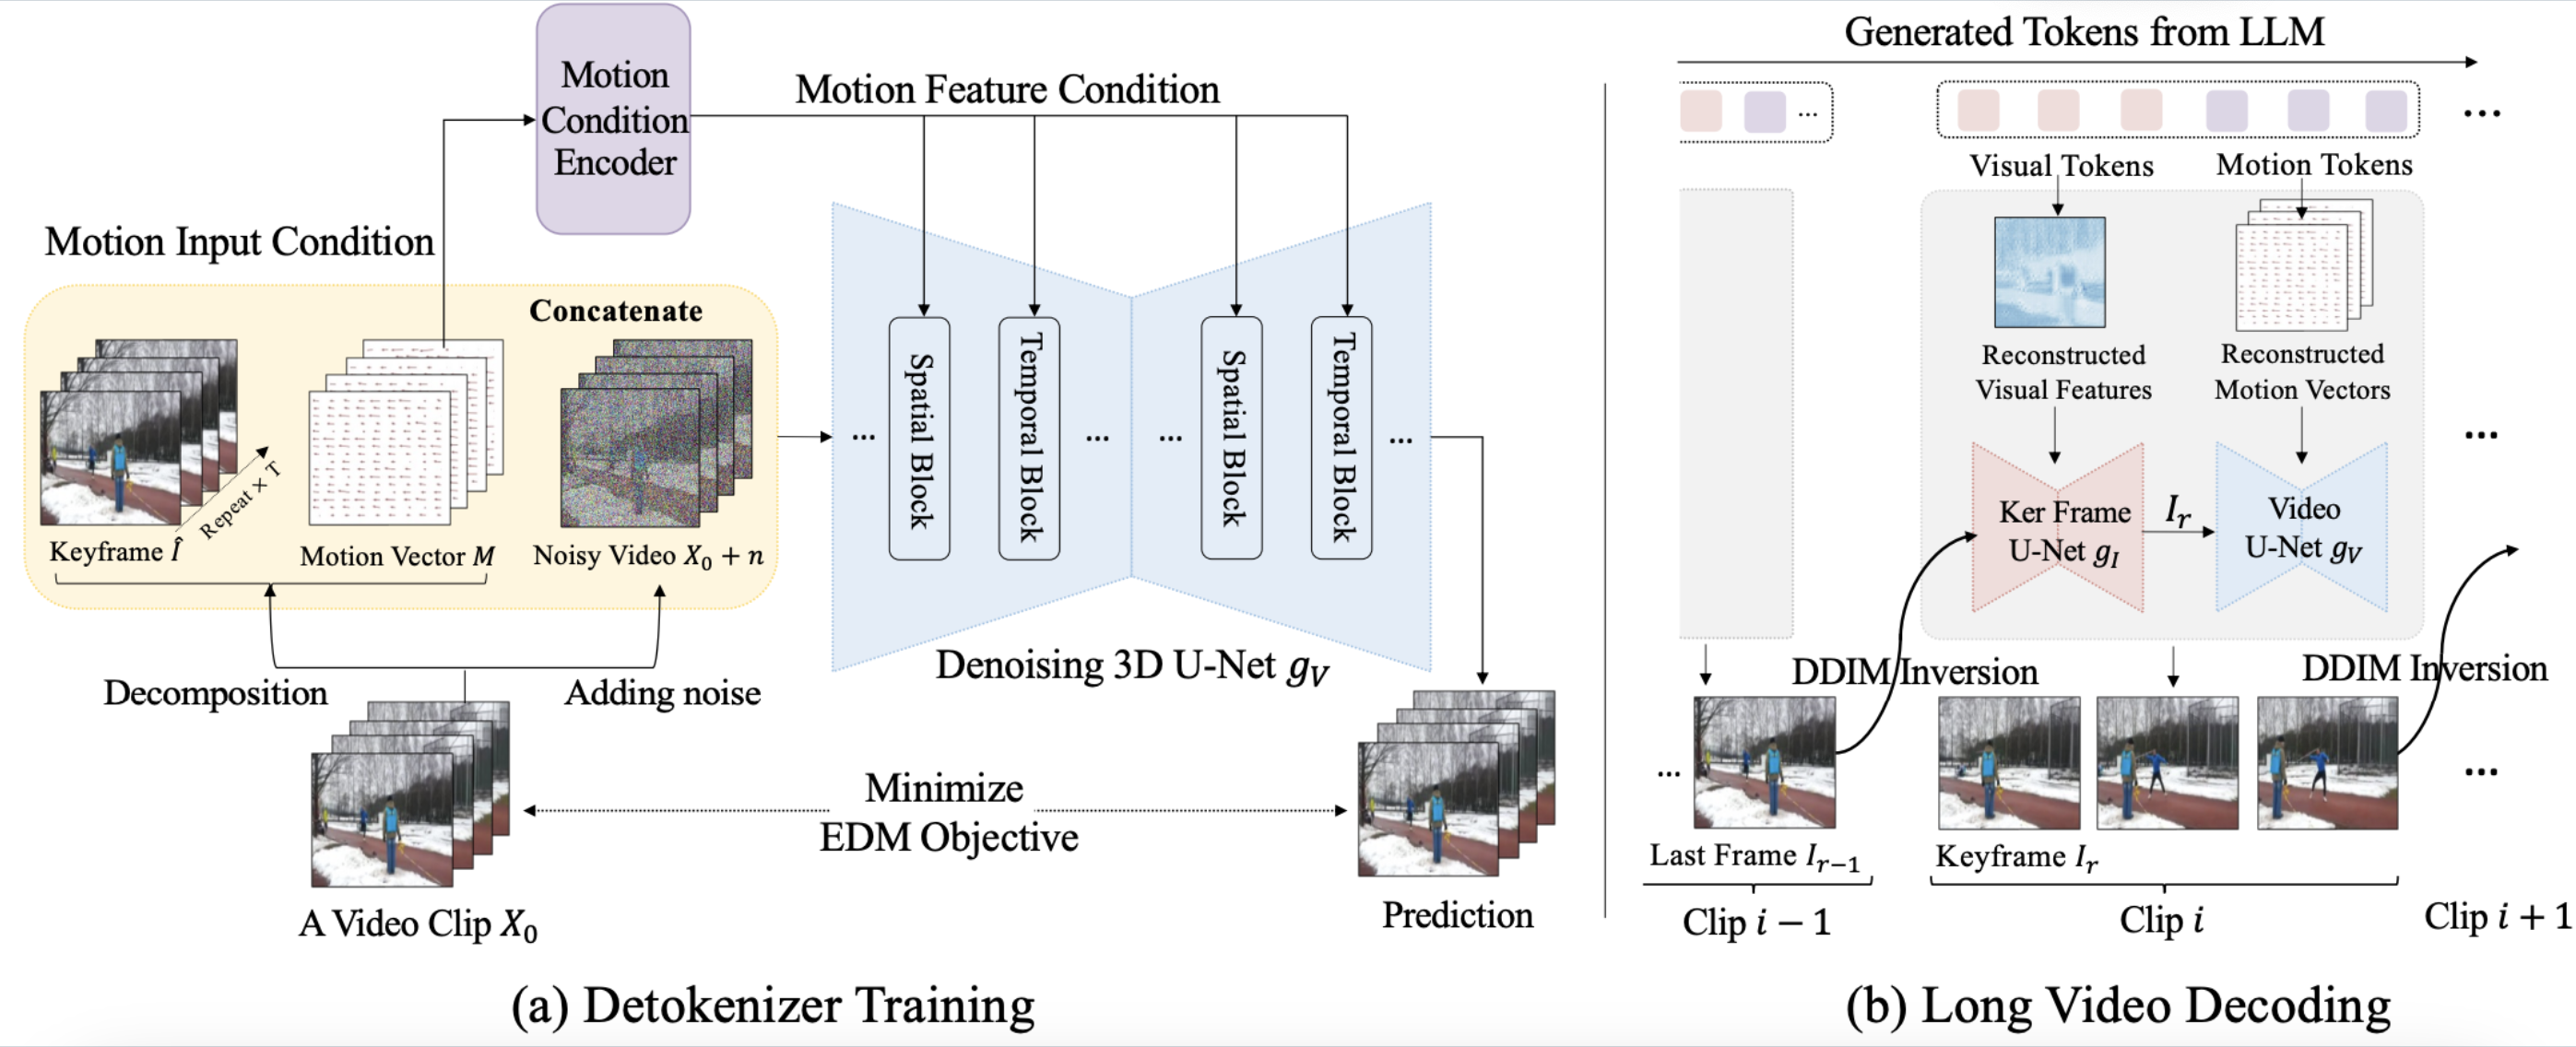
Video-LaVIT: Unified Video-Language Pre-training with Decoupled Visual-Motional Tokenization
ICML 2024 Oral{Paper} {Code} {Webpage}Details
-
AnimateLCM: Accelerating the Animation of Personalized Diffusion Models and Adapters with Decoupled Consistency Learning
arxiv{Paper} {Code} {Webpage} -
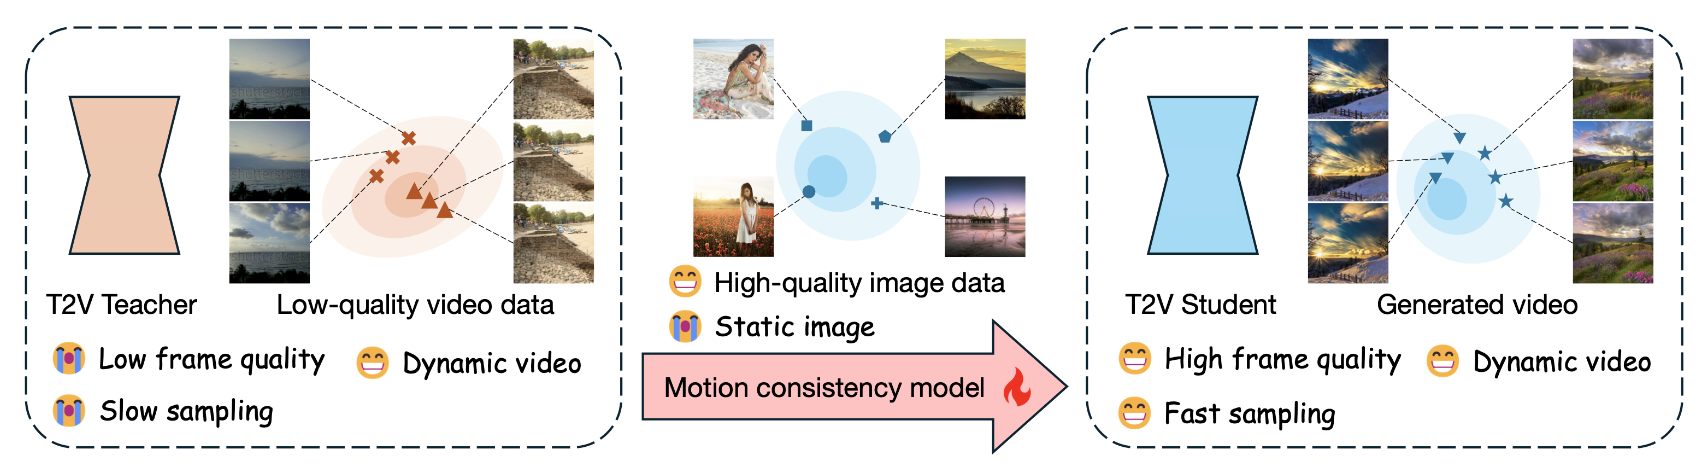
Motion Consistency Model: Accelerating Video Diffusion with Disentangled Motion-Appearance Distillation
arxiv{Paper} {Code} {Webpage} -
Text-Animator: Controllable Visual Text Video Generation
arxiv{Paper} {Code} {Webpage}Details
-
MotionBooth: Motion-Aware Customized Text-to-Video Generation
arxiv{Paper} {Code} {Webpage}Details
Customized in Motion control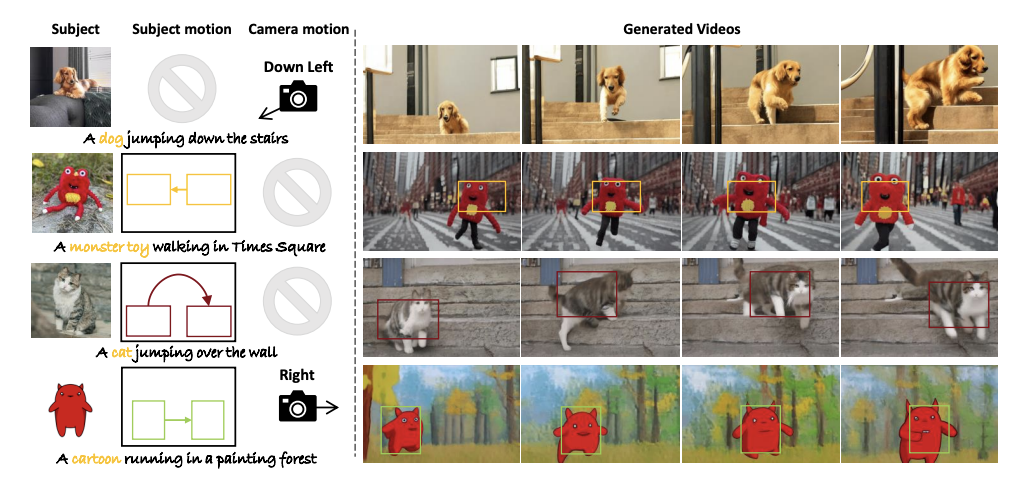
-
EasyAnimate: A High-Performance Long Video Generation Method based on Transformer Architecture
arxiv{Paper} {Code} {Webpage} -
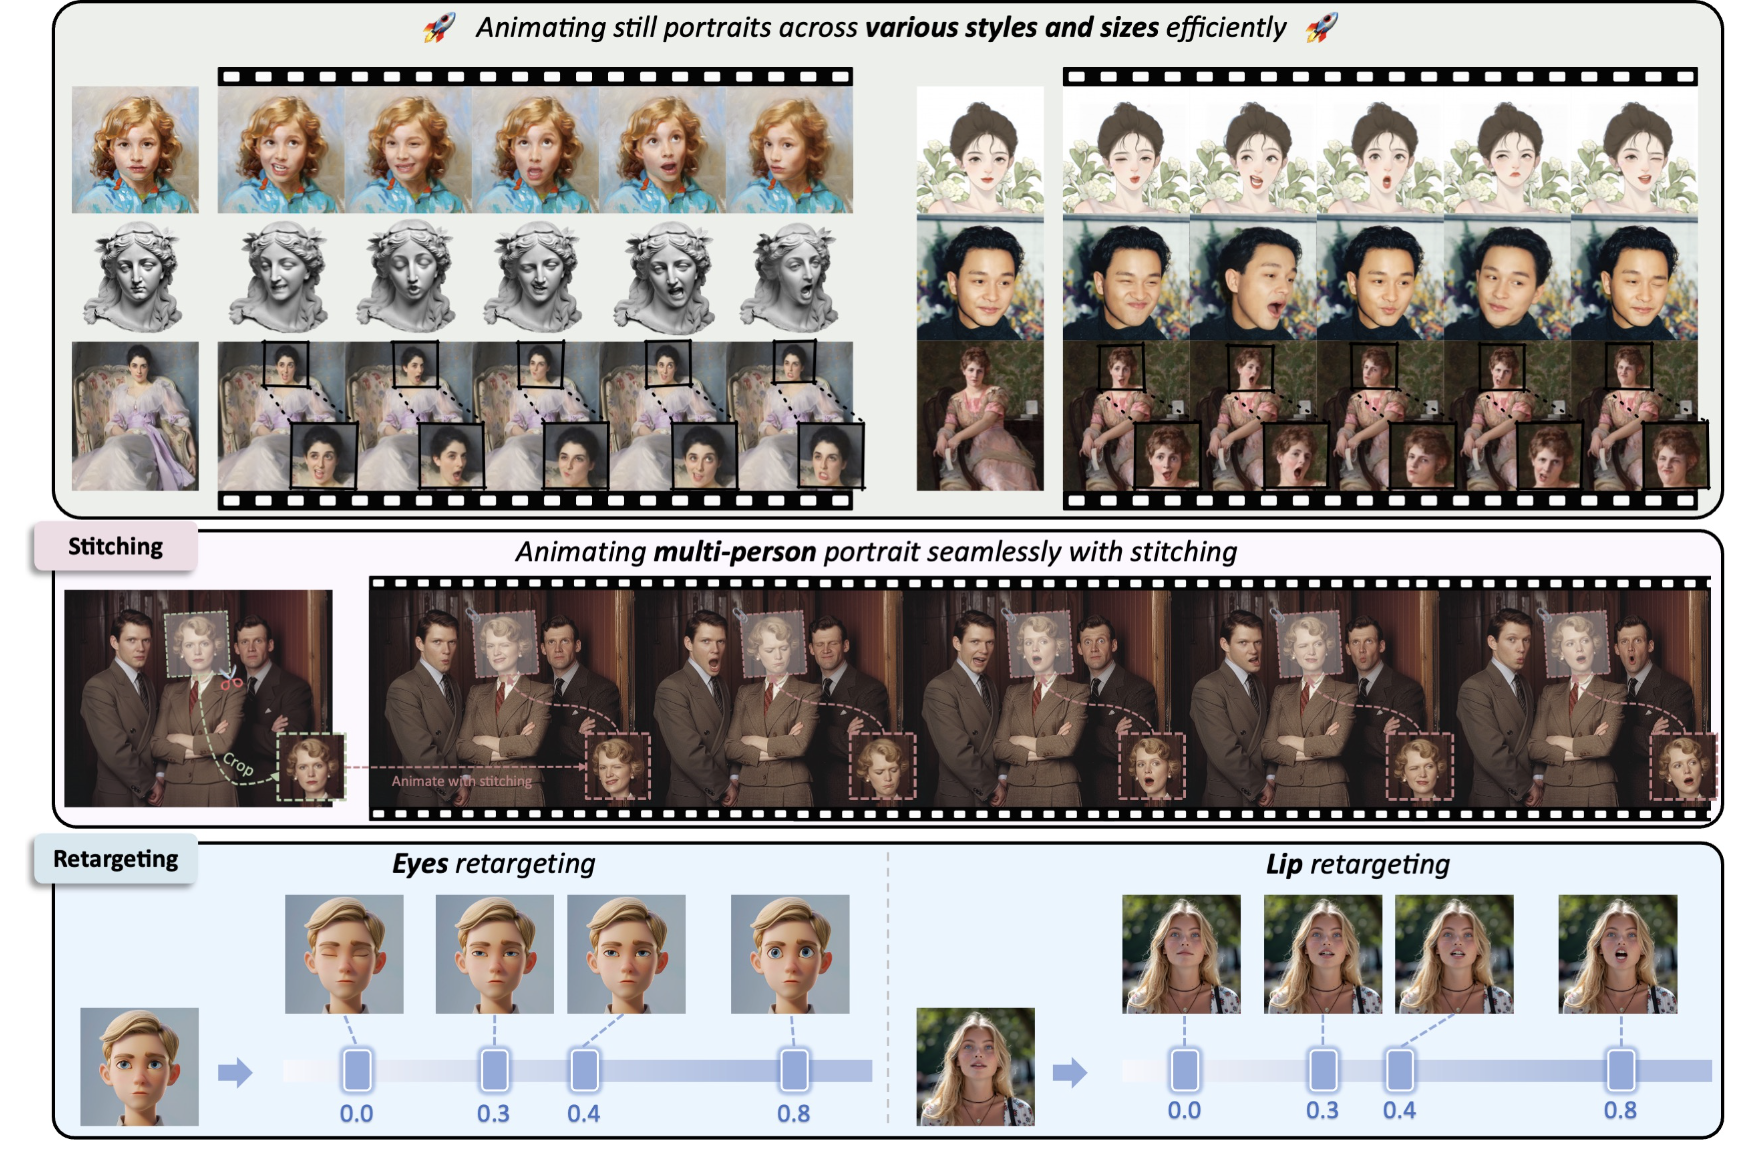
LivePortrait: Efficient Portrait Animation with Stitching and Retargeting Control
arxiv{Paper} {Code} {Webpage}Details
-
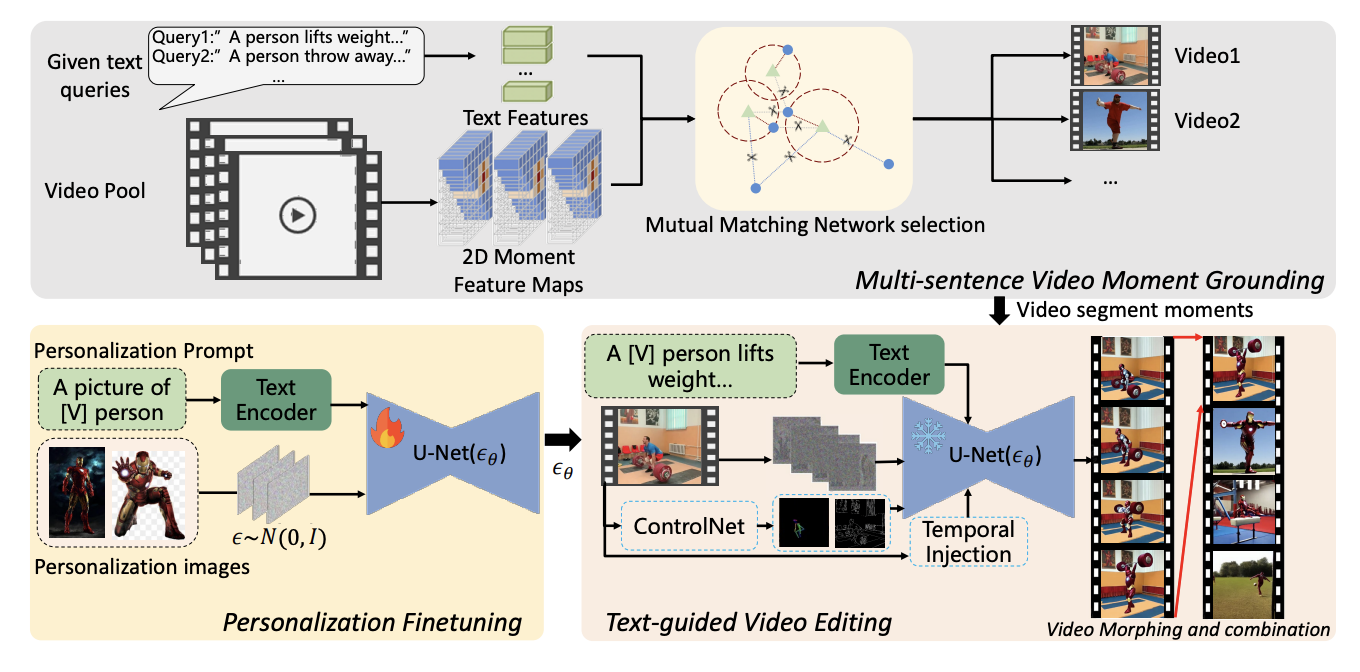
Multi-sentence Video Grounding for Long Video Generation
arxiv{Paper}Details
-
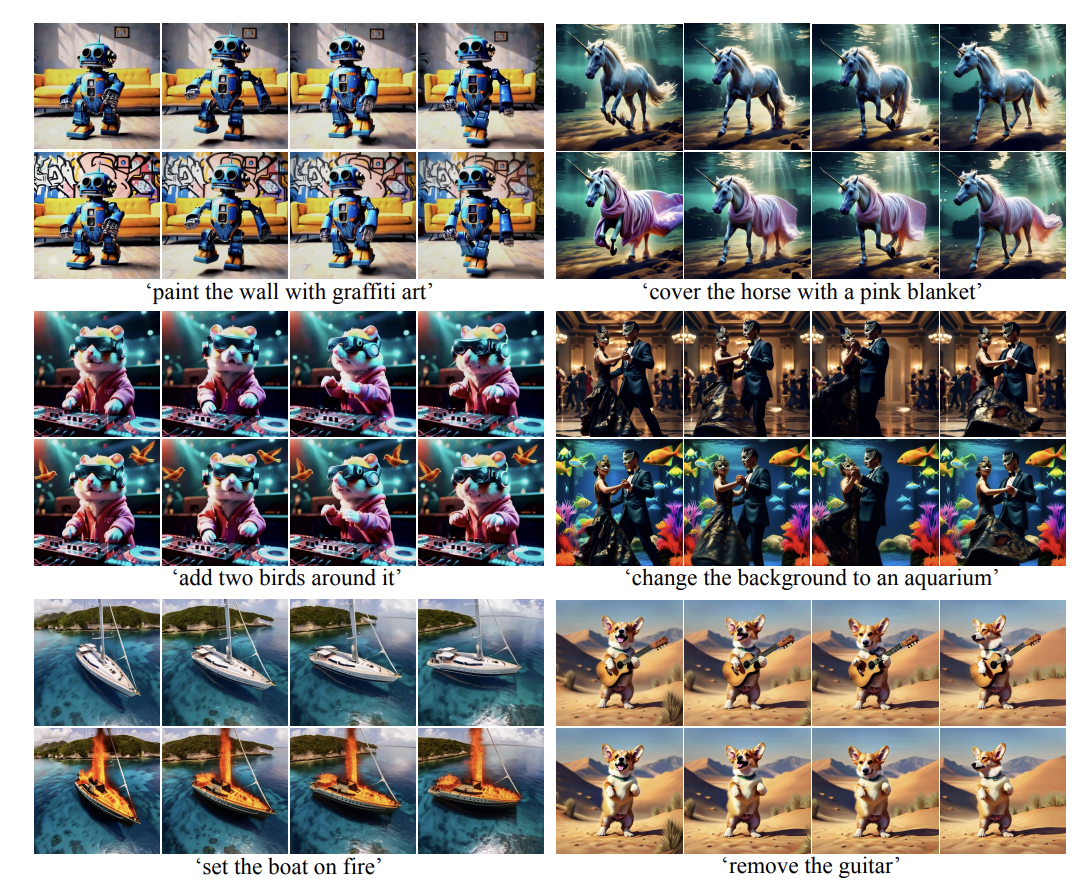
Video Editing via Factorized Diffusion Distillation
ECCV 2024{Paper} {Webpage}Details
2023
- Animate-A-Story: Storytelling with Retrieval-Augmented Video Generation
arxiv{Paper} {Code} {Webpage}Details
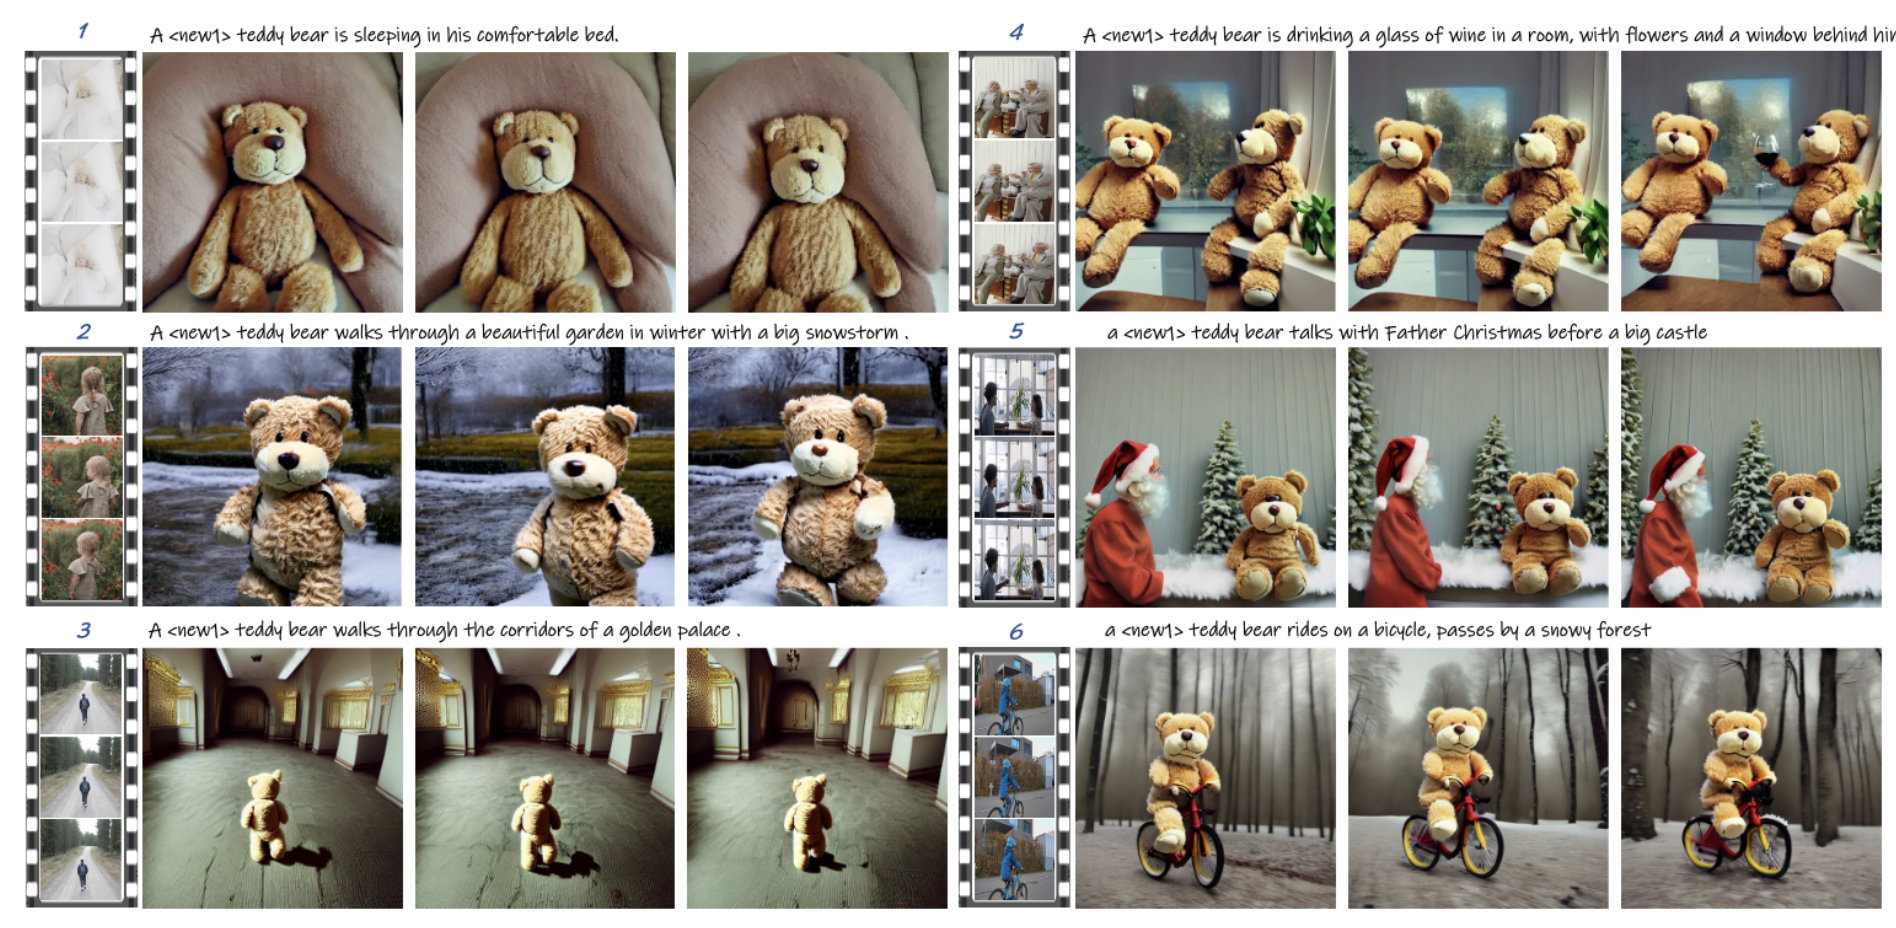
Other Resources
Generic Benchmarks
Video Benchmarks
-
TC-Bench: Benchmarking Temporal Compositionality in Text-to-Video and Image-to-Video Generation
Text-to-Video-Benchmark{Paper} {Code} {Webpage} -
VBench: Comprehensive Benchmark Suite for Video Generative Models
CVPR 2024{Paper} {Code} {Webpage}
Generic Datasets
-
Flickr-Faces-HQ Dataset (FFHQ) {Paper} {Code} {Download}
-
CelebAMask-HQ {Paper} {Code} {Download}
-
Multi-Modal-CelebA-HQ
CVPR 2021{Paper} {Code} {Download} -
Dress Code: High-Resolution Multi-Category Virtual Try-On.
ECCV 2022{Paper} {Code} {Download}
Generic Pre-trained Models
-
SD-v1-4 {Paper} {Code} {HuggingFace} {Blog} {Download}
CompVis/stable-diffusion-v1-4Details
-
SD-1-5 {Paper} {Code} {HuggingFace} {Blog} {Download}
runwayml/stable-diffusion-v1-5Details
-
SD-2-1-base {Paper} {Code} {HuggingFace} {Download}
stabilityai/stable-diffusion-2-1-baseDetails
-
SD-XL: Improving Latent Diffusion Models for High-Resolution Image Synthesis {Paper} {Code} {HuggingFace} {Download}
stabilityai/stable-diffusion-xl-base-1.0Details
-
sdxl-turbo (Adversarial Diffusion Distillation) {Paper} {Code} {HuggingFace} {Download} {Demo}
stabilityai/sdxl-turboDetails
Contributors

59 commits
Similar repos


Papers and codes collection for customized, personalized and editable generative models
28
59 commits
updated Oct 1, 2024
README
awesome-customized-generative-AI
Papers and codes collection for customize, personalized and editable generative models in 2D and 3D domains.
Introduction
Artificial Intelligence Generated Content (AIGC) has become ubiquitous, demonstrating the power of generating mesmerizing results of random portraits. However, users generally show greater interest in personalized information (for example, faces from familiar people or celebrities) in these generated results than in generic faces. This tendency toward customization in AIGC arouses attention to customized, personalized, and editable generative AI.
This repo mainly focuses on visual generative models (leaving out LLMs), including 2D image-to-image, 2D text-to-image, and text-guided 3D generation/manipulation, collecting customized, personalized, and editable works in these specific domains. For any addition about other 2D/3D AIGC domains or bugs report, please open an issue, pull requests, or e-mail me at normanzheng6606@gmail.com for better communication.
Frequantly updating, please stay tuned!
Table of Contents
Customized 2D Image-to-Image
Image-prompted Generation
2024
-
FreeControl: Training-Free Spatial Control of Any Text-to-Image Diffusion Model with Any Condition
CVPR2024{Paper} {Code} {Webpage}Details
-
Face2Diffusion for Fast and Editable Face Personalization
CVPR2024{Paper} {Code} {Webpage}Details
-
InstantID: Zero-shot Identity-Preserving Generation in Seconds
arxiv{Paper} {Code} {Webpage}Details
-
X-Adapter: Adding Universal Compatibility of Plugins for Upgraded Diffusion Model
CVPR2024{Paper} {Code} {Webpage}Details
-
MagiCapture: High-Resolution Multi-Concept Portrait Customization
AAAI2024{Paper} {Code} {Webpage} -
Texture-Preserving Diffusion Models for High-Fidelity Virtual Try-On
CVPR2024{Paper} {Code}Details
-
Orthogonal Adaptation for Modular Customization of Diffusion Models
CVPR2024{Paper} {Webpage} -
High-fidelity Person-centric Subject-to-Image Synthesis
CVPR 2024{Paper} {Code} -
Coarse-to-Fine Latent Diffusion for Pose-Guided Person Image Synthesis
CVPR 2024{Paper} {Code}Details
-
Non-confusing Generation of Customized Concepts in Diffusion Models
ICML 2024{Paper} {Code} {Webpage} -
MC2: Multi-concept Guidance for Customized Multi-concept Generation
arxiv{Paper} {Code}Details
-
ToonCrafter: Generative Cartoon Interpolation
arxiv{Paper} {Code} {Webpage}Details
-
PCM : Phased Consistency Model
arxiv{Paper} {Code} {Webpage}Details
2023
-
IP-Adapter: Text Compatible Image Prompt Adapter for Text-to-Image Diffusion Models
arxiv{Paper} {Code} {Webpage} -
ViscoNet: Bridging and Harmonizing Visual and Textual Conditioning for ControlNet
arxiv{Paper} {Code} {Webpage}
- When StyleGAN Meets Stable Diffusion: a 𝒲+ Adapter for Personalized Image Generation
arxiv{Paper} {Code}Details
-
Real-World Image Variation by Aligning Diffusion Inversion Chain
NeurIPS2023{Paper} {Code} {Webpage} -
MyStyle++: A Controllable Personalized Generative Prior
SIGGRAPH ASIA 2023{Paper} {Code} {Webpage}Details
-
Mix-of-Show: Decentralized Low-Rank Adaptation for Multi-Concept Customization of Diffusion Models
NeurIPS2023{Paper} {Code} {Webpage} -
SingleInsert: Inserting New Concepts from a Single Image into Text-to-Image Models for Flexible Editing
arxiv{Paper} {Code} {Webpage} -
Cones 2: Customizable Image Synthesis with Multiple Subjects
NeurIPS2023{Paper} {Code} {Webpage} -
LaDI-VTON: Latent Diffusion Textual-Inversion Enhanced Virtual Try-On
ACM MM 2023{Paper} {Code}Details
2022
Portrait Style Transfer
2024
- InstantStyle: Free Lunch towards Style-Preserving in Text-to-Image Generation
arxiv{Paper} {Code}Details
-
DEADiff: An Efficient Stylization Diffusion Model with Disentangled Representations
CVPR 2024{Paper} {Code} {Webpage}Details
-
Customizing Text-to-Image Models with a Single Image Pair
arxiv{Paper}Details
2023
- ViscoNet: Bridging and Harmonizing Visual and Textual Conditioning for ControlNet
arxiv{Paper} {Code} {Webpage}
-
DemoCaricature: Democratising Caricature Generation with a Rough Sketch
arxiv{Paper} {Webpage}Details
-
Real-World Image Variation by Aligning Diffusion Inversion Chain
NeurIPS2023{Paper} {Code} {Webpage} -
ArtAdapter: Text-to-Image Style Transfer using Multi-Level Style Encoder and Explicit Adaptation
arxiv{Paper} {Code} {Webpage}Details
Interactive Image Editing
2024
- Transparent Image Layer Diffusion using Latent Transparency
arxiv{Paper} {Code}Powerful PhotoShop cutout replacement!Details
-
MagiCapture: High-Resolution Multi-Concept Portrait Customization
AAAI2024{Paper} {Code} {Webpage} -
MIGC: Multi-Instance Generation Controller for Text-to-Image Synthesis
CVPR 2024{Paper} {Code} {Webpage} -
LocInv: Localization-aware Inversion for Text-Guided Image Editing
arxiv{Paper}Details
-
IDM-VTON : Improving Diffusion Models for Authentic Virtual Try-on in the Wild
arxiv{Paper} {Code} {Webpage}Details
-
Diffree: Text-Guided Shape Free Object Inpainting with Diffusion Model
arxiv{Paper} {Code} {Webpage} -
DRAGTEXT: Rethinking Text Embedding in Point-based Image Editing
arxiv{Paper}Details
2023
-
Drag Your GAN: Interactive Point-based Manipulation on the Generative Image Manifold
SIGGRAPH 2023{Paper} {Code} {Webpage}Interactive manipulation of the generative image manifold!Details
-
DragDiffusion: Harnessing Diffusion Models for Interactive Point-based Image Editing
CVPR 2024{Paper} {Code} {Webpage}Details
-
Expressive Text-to-Image Generation with Rich Text
ICCV 2023{Paper} {Code} {Webpage}Details
Customized 2D Text-to-Image
Text-guided Portrait Generation
2024
-
FlashFace: Human Image Personalization with High-fidelity Identity Preservation
arxiv{Paper} {Code} {Webpage}Details
-
Pick-and-Draw: Training-free Semantic Guidance for Text-to-Image Personalization
arxiv{Paper}Details
-
StableIdentity: Inserting Anybody into Anywhere at First Sight
arxiv{Paper} {Code} {Webpage}
- Towards a Simultaneous and Granular Identity-Expression Control in Personalized Face Generation
arxiv{Paper}Details
- DisenBooth: Identity-Preserving Disentangled Tuning for Subject-Driven Text-to-Image Generation
ICLR2024{Paper} {Code} {Webpage}Details
- DreamMatcher: Appearance Matching Self-Attention
for Semantically-Consistent Text-to-Image Personalization
CVPR2024{Paper} {Code} {Webpage}Details
-
Orthogonal Adaptation for Modular Customization of Diffusion Models
CVPR2024{Paper} {Webpage} -
High-fidelity Person-centric Subject-to-Image Synthesis
CVPR 2024{Paper} {Code} -
Non-confusing Generation of Customized Concepts in Diffusion Models
ICML 2024{Paper} {Code} {Webpage}
2023
-
IP-Adapter: Text Compatible Image Prompt Adapter for Text-to-Image Diffusion Models
arxiv{Paper} {Code} {Webpage} -
Real-World Image Variation by Aligning Diffusion Inversion Chain
NeurIPS2023{Paper} {Code} {Webpage} -
Customization Assistant for Text-to-image Generation
arxiv{Paper} {Code}Details
-
FaceStudio: Put Your Face Everywhere in Seconds
arxiv{Paper} {Code} {Webpage}Details
-
CustomNet: Zero-shot Object Customization with Variable-Viewpoints in Text-to-Image Diffusion Models
arxiv{Paper} {Code} {Webpage}Details
-
Encoder-based Domain Tuning for Fast Personalization of Text-to-Image Models
arxiv{Paper} {Code}Details
-
PhotoVerse: Tuning-Free Image Customization with Text-to-Image Diffusion Models
arxiv{Paper} {Webpage}Details
-
PhotoMaker: Customizing Realistic Human Photos via Stacked ID Embedding
arxiv{Paper} {Code} {Webpage}Details
-
DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation
CVPR2022{Paper} {Code} {Webpage}Details
-
CatVersion: Concatenating Embeddings for Diffusion-Based Text-to-Image Personalization
arxiv{Paper} {Code} {Webpage}Details
-
Subject-Diffusion:Open Domain Personalized Text-to-Image Generation without Test-time Fine-tuning
arxiv{Paper} {Code} {Webpage}Details
-
Mix-of-Show: Decentralized Low-Rank Adaptation for Multi-Concept Customization of Diffusion Models
NeurIPS2023{Paper} {Code} {Webpage} -
HyperDreamBooth: HyperNetworks for Fast Personalization of Text-to-Image Models
arxiv{Paper} {Code} {Webpage}Details
-
SingleInsert: Inserting New Concepts from a Single Image into Text-to-Image Models for Flexible Editing
arxiv{Paper} {Code} {Webpage} -
Cones 2: Customizable Image Synthesis with Multiple Subjects
NeurIPS2023{Paper} {Code} {Webpage} -
ELITE: Encoding Visual Concepts into Textual Embeddings for Customized Text-to-Image Generation
ICCV 2023{Paper} {Code}Details
Text-guided Image Editing
2024
-
BootPIG: Bootstrapping Zero-shot Personalized Image Generation Capabilities in Pretrained Diffusion Models
arxiv{Paper}Details
-
Diff-Plugin: Revitalizing Details for Diffusion-based Low-level Tasks
CVPR 2024{Paper} {Code} {Webpage}Details
-
CustomText: Customized Textual Image Generation using Diffusion Models
arxiv{Paper}Details
-
EmoEdit: Evoking Emotions through Image Manipulation
arxiv{Paper}Details
-
Enhancing Text-to-Image Editing via Hybrid Mask-Informed Fusion
arxiv{Paper}Details
-
Diffree: Text-Guided Shape Free Object Inpainting with Diffusion Model
arxiv{Paper} {Code} {Webpage}
2023
- ViscoNet: Bridging and Harmonizing Visual and Textual Conditioning for ControlNet
arxiv{Paper} {Code} {Webpage}
-
DreamInpainter: Text-Guided Subject-Driven Image Inpainting with Diffusion Models
arxiv{Paper}Details
-
HD-Painter: High-Resolution and Prompt-Faithful Text-Guided Image Inpainting with Diffusion Models
arxiv{Paper} {Code} {HuggingFace}Details
-
Dynamic Prompt Learning: Addressing Cross-Attention Leakage for Text-Based Image Editing
NeurIPS 2023{Paper} {Code}Details
Customized 3D Generation/Manipulation
Image-prompted 3D Generation
2024
- TIP-Editor: An Accurate 3D Editor Following Both Text-Prompts And Image-Prompts
arxiv{Paper} {Webpage}
- StableVITON: Learning Semantic Correspondence with Latent Diffusion Model for Virtual Try-On
CVPR 2024{Paper} {Code} {Webpage}Details
-
Customize your NeRF: Adaptive Source Driven 3D Scene Editing via Local-Global Iterative Training
CVPR2024{Paper} {Code} {Webpage} -
SplattingAvatar: Realistic Real-Time Human Avatars with Mesh-Embedded Gaussian Splatting
CVPR 2024{Paper} {Code} {Webpage}Details
-
ViewDiff: 3D-Consistent Image Generation with Text-to-Image Models
CVPR 2024{Paper} {Code} {Webpage}Details
-
LeftRefill: Filling Right Canvas based on Left Reference through Generalized Text-to-Image Diffusion Model
CVPR 2024{Paper} {Code} {Webpage}Details
-
Diffusion Time-step Curriculum for One Image to 3D Generation
CVPR 2024{Paper} {Code}Details
-
DreamCraft3D: Hierarchical 3D Generation with Bootstrapped Diffusion Prior
ICLR 2024{Paper} {Code} {Webpage}Details
` -
Controllable Text-to-3D Generation via Surface-Aligned Gaussian Splatting
arxiv{Paper} {Code} {Webpage}Details
-
EG4D: Explicit Generation of 4D Object without Score Distillation
arxiv{Paper} {Code}Details
-
En3D: An Enhanced Generative Model for Sculpting 3D Humans from 2D Synthetic Data
arxiv{Paper} {Code} {Webpage} -
Ouroboros3D: Image-to-3D Generation via 3D-aware Recursive Diffusion
arxiv{Paper} {Code} {webpage}Details
-
Diffusion4D: Fast Spatial-temporal Consistent 4D Generation via Video Diffusion Models
arxiv{Paper} {Code} {Webpage}
2023
- GP-VTON: Towards General Purpose Virtual Try-on via Collaborative Local-Flow Global-Parsing Learning
CVPR2023{Paper} {Code}Details
-
TryOnDiffusion: A Tale of Two UNets
CVPR 2023{Paper} {Code} {Webpage}Details
-
Debiasing Scores and Prompts of 2D Diffusion for View-consistent Text-to-3D Generation
NeurIPS 2023{Paper} {Code} {Webpage}Details
Text-prompted 3D Manipulation
2024
-
GaussianEditor (S-Lab, NTU, etc.): Swift and Controllable 3D Editing with Gaussian Splatting
CVPR2024{Paper} {Code} {Webpage}Details
-
GenN2N: Generative NeRF2NeRF Translation for 3D Shape Manipulation
CVPR2024{Paper} {Code} {Webpage}Details
-
3D Paintbrush: Local Stylization of 3D Shapes with Cascaded Score Distillation
CVPR2024{Paper} {Code} {Webpage}Details
-
TIP-Editor: An Accurate 3D Editor Following Both Text-Prompts And Image-Prompts
arxiv{Paper} {Webpage}
-
Customize your NeRF: Adaptive Source Driven 3D Scene Editing via Local-Global Iterative Training
CVPR2024{Paper} {Code} {Webpage} -
Posterior Distillation Sampling
CVPR 2024{Paper} {Code} {Webpage}Details
-
Learning Continuous 3D Words for Text-to-Image Generation
CVPR 2024{Paper} {Code} {Webpage}Details
-
Control4D: Efficient 4D Portrait Editing with Text
CVPR 2024{Paper}{Webpage}Details
-
En3D: An Enhanced Generative Model for Sculpting 3D Humans from 2D Synthetic Data
arxiv{Paper} {Code} {Webpage} -
Diffusion4D: Fast Spatial-temporal Consistent 4D Generation via Video Diffusion Models
arxiv{Paper} {Code} {Webpage}
2023
-
Instruct-NeRF2NeRF: Editing 3D Scenes with Instructions
ICCV2023{Paper} {Code}Details
-
DreamBooth3D: Subject-Driven Text-to-3D Generation with Dream Fields
ICCV2023{Paper} {Webpage}Details
-
GaussianEditor (Huawei): Editing 3D Gaussians Delicately with Text Instructions
arxiv{Paper} {Webpage}Details
-
ViCA-NeRF: View-Consistency-Aware 3D Editing of Neural Radiance Fields
NeurIPS 2023{Paper} {Code} {Webpage}Details
Customized Video Generation
Image-prompted Video Generation
2024
-
Collaborative Video Diffusion: Consistent Multi-video Generation with Camera Control
arxiv{Paper} {Code} {Webpage}Details
-
Direct-a-Video: Customized Video Generation with User-Directed Camera Movement and Object Motion
arxiv{Paper} {Code} {Webpage} -
AnimateLCM: Accelerating the Animation of Personalized Diffusion Models and Adapters with Decoupled Consistency Learning
arxiv{Paper} {Code} {Webpage} -
Motion Consistency Model: Accelerating Video Diffusion with Disentangled Motion-Appearance Distillation
arxiv{Paper} {Code} {Webpage} -
Hallo: Hierarchical Audio-Driven Visual Synthesis for Portrait Image Animation
arxiv{Paper} {Code} {Webpage}Details
-
UniAnimate: Taming Unified Video Diffusion Models for Consistent Human Image Animation
arxiv{Paper} {Code} {Webpage}Details
-
MimicMotion: High-Quality Human Motion Video Generation with Confidence-aware Pose Guidance
arxiv{Paper} {Code} {Webpage}Details
-
EasyAnimate: A High-Performance Long Video Generation Method based on Transformer Architecture
arxiv{Paper} {Code} {Webpage} -
Training-free Composite Scene Generation for Layout-to-Image Synthesis
arxiv{Paper} {Code}Details
-
MagicFight: Personalized Martial Arts Combat Video Generation
openreview{Paper}Details
-
DynamiCrafter: Animating Open-domain Images with Video Diffusion Priors
ECCV 2024{Paper} {Code} {Webpage}Details
Text-prompted Video Generation
2024
-
Direct-a-Video: Customized Video Generation with User-Directed Camera Movement and Object Motion
arxiv{Paper} {Code} {Webpage} -
Video-LaVIT: Unified Video-Language Pre-training with Decoupled Visual-Motional Tokenization
ICML 2024 Oral{Paper} {Code} {Webpage}Details
-
AnimateLCM: Accelerating the Animation of Personalized Diffusion Models and Adapters with Decoupled Consistency Learning
arxiv{Paper} {Code} {Webpage} -
Motion Consistency Model: Accelerating Video Diffusion with Disentangled Motion-Appearance Distillation
arxiv{Paper} {Code} {Webpage} -
Text-Animator: Controllable Visual Text Video Generation
arxiv{Paper} {Code} {Webpage}Details
-
MotionBooth: Motion-Aware Customized Text-to-Video Generation
arxiv{Paper} {Code} {Webpage}Details
Customized in Motion control -
EasyAnimate: A High-Performance Long Video Generation Method based on Transformer Architecture
arxiv{Paper} {Code} {Webpage} -
LivePortrait: Efficient Portrait Animation with Stitching and Retargeting Control
arxiv{Paper} {Code} {Webpage}Details
-
Multi-sentence Video Grounding for Long Video Generation
arxiv{Paper}Details
-
Video Editing via Factorized Diffusion Distillation
ECCV 2024{Paper} {Webpage}Details
2023
- Animate-A-Story: Storytelling with Retrieval-Augmented Video Generation
arxiv{Paper} {Code} {Webpage}Details
Other Resources
Generic Benchmarks
Video Benchmarks
-
TC-Bench: Benchmarking Temporal Compositionality in Text-to-Video and Image-to-Video Generation
Text-to-Video-Benchmark{Paper} {Code} {Webpage} -
VBench: Comprehensive Benchmark Suite for Video Generative Models
CVPR 2024{Paper} {Code} {Webpage}
Generic Datasets
-
Flickr-Faces-HQ Dataset (FFHQ) {Paper} {Code} {Download}
-
CelebAMask-HQ {Paper} {Code} {Download}
-
Multi-Modal-CelebA-HQ
CVPR 2021{Paper} {Code} {Download} -
Dress Code: High-Resolution Multi-Category Virtual Try-On.
ECCV 2022{Paper} {Code} {Download}
Generic Pre-trained Models
-
SD-v1-4 {Paper} {Code} {HuggingFace} {Blog} {Download}
CompVis/stable-diffusion-v1-4Details
-
SD-1-5 {Paper} {Code} {HuggingFace} {Blog} {Download}
runwayml/stable-diffusion-v1-5Details
-
SD-2-1-base {Paper} {Code} {HuggingFace} {Download}
stabilityai/stable-diffusion-2-1-baseDetails
-
SD-XL: Improving Latent Diffusion Models for High-Resolution Image Synthesis {Paper} {Code} {HuggingFace} {Download}
stabilityai/stable-diffusion-xl-base-1.0Details
-
sdxl-turbo (Adversarial Diffusion Distillation) {Paper} {Code} {HuggingFace} {Download} {Demo}
stabilityai/sdxl-turboDetails
Similar repos
Contributors
59 commits