
Official repo for "OmniEarth-Bench: Towards Holistic Evaluation of Earth's Six Spheres and Cross-Spheres Interactions with Multimodal Observational Earth Data"
Python
12
13 commits
updated May 3, 2026
README
OmniEarth-Bench: Towards Holistic Evaluation of Earth's Six Spheres and Cross-Spheres Interactions with Multimodal Observational Earth Data
[📃 Paper] [🌐 Website] [🤗 OmniEarth-Bench] [🏆 Leaderboard]
🔥News
- [2025-05-15] Dataset released on Hugging Face.
📚 Contents
🔍Dataset Overview
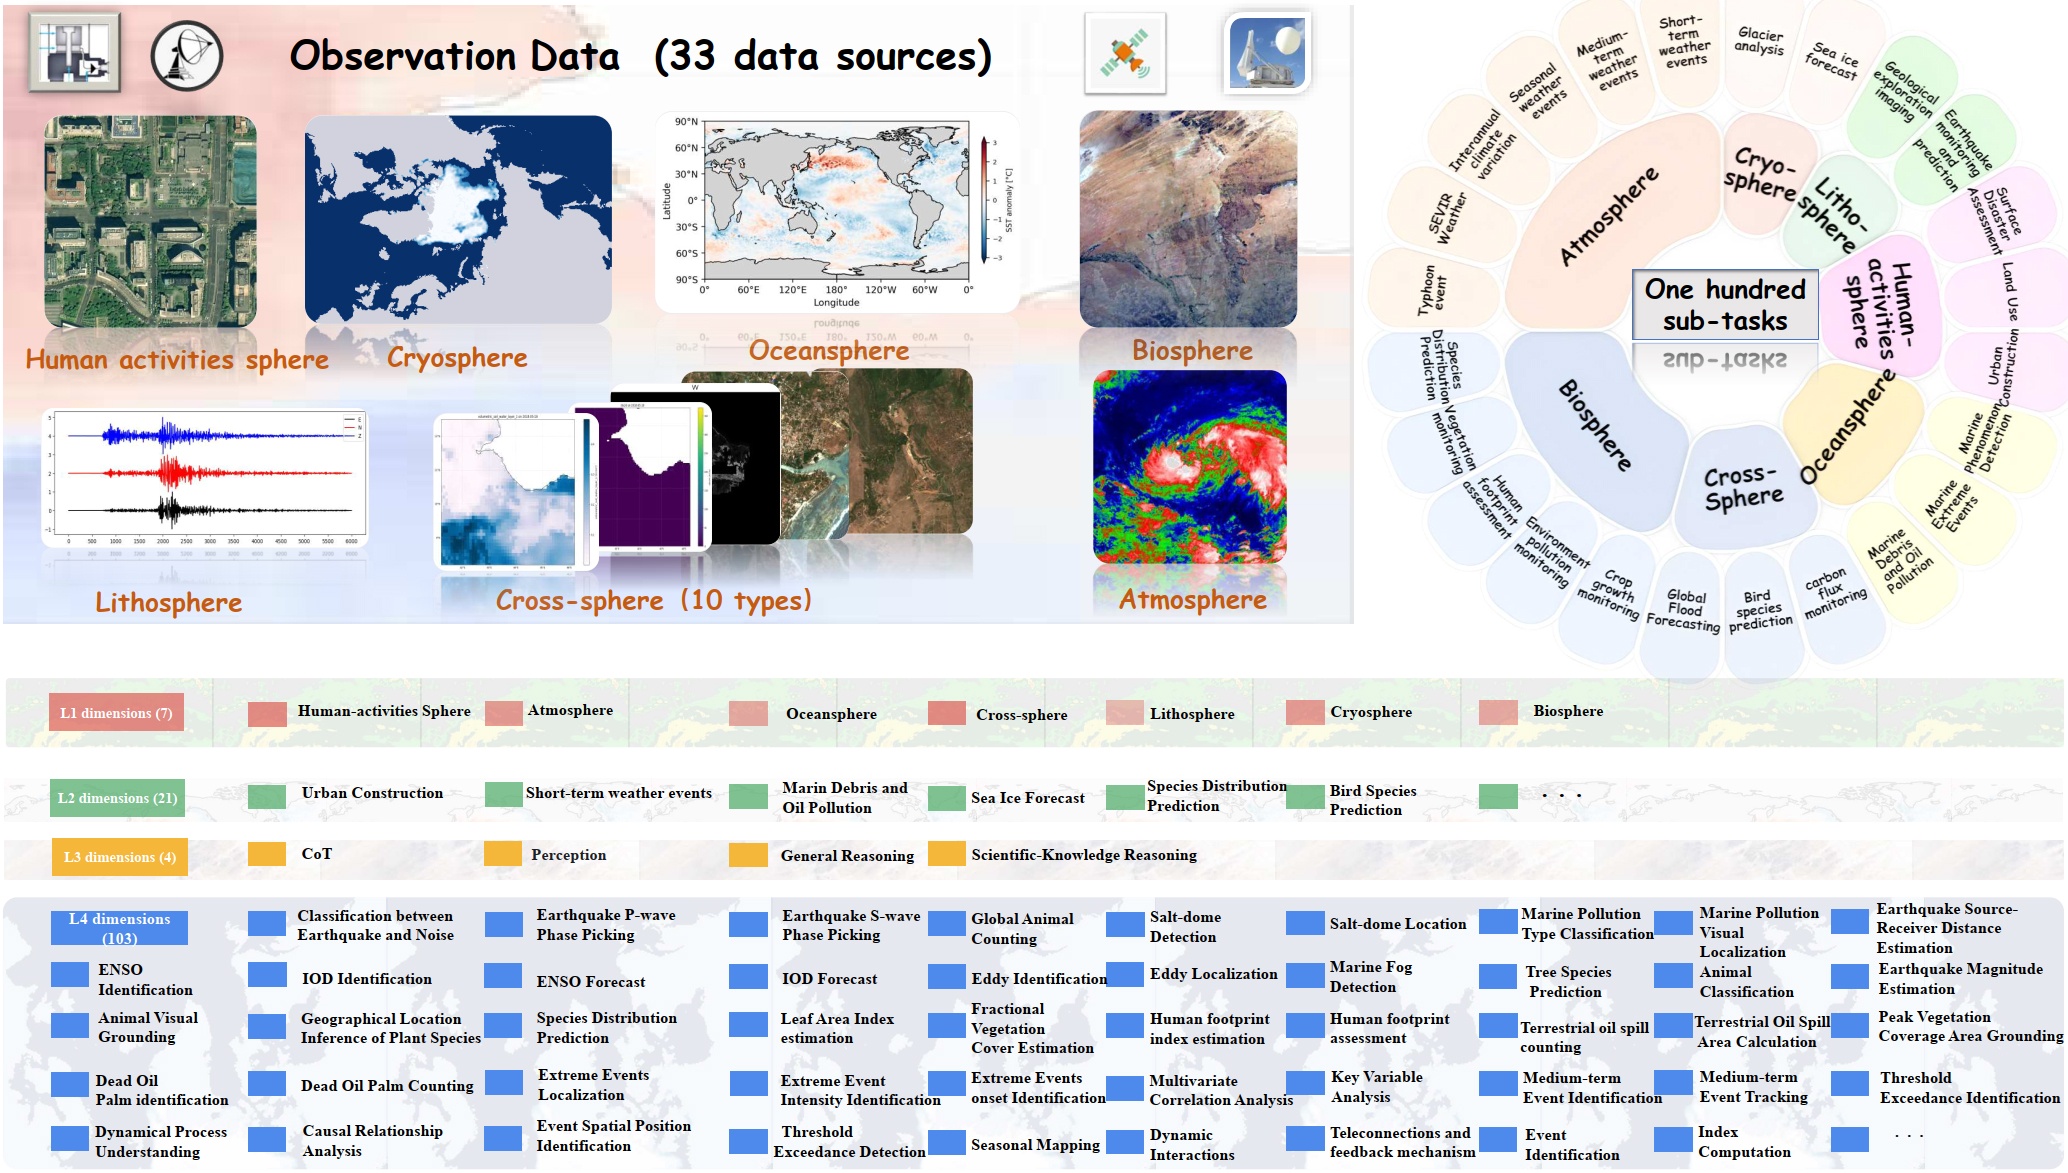
Fig 1. Overview of OmniEarth-Bench.
We introduce OmniEarth-Bench, the first comprehensive multimodal benchmark spanning all six Earth science spheres (atmosphere, lithosphere, Oceansphere, cryosphere, biosphere and Human-activities sphere) and cross-spheres with one hundred expert-curated evaluation dimensions. Leveraging observational data from satellite sensors and in-situ measurements, OmniEarth-Bench integrates 29,779 annotations across four tiers: perception, general reasoning, Scientific‑knowledge reasoning and chain-of-thought (CoT) reasoning. The key contributions are:
- Comprehensive Evaluation Across All Six Spheres. OmniEarth-Bench is the first benchmark to extensively cover all Earth science spheres, offering 58 practical and comprehensive evaluation dimensions that significantly surpass prior benchmarks.
- Pioneering Cross-Sphere Evaluation Dimensions. To address complex real-world scenarios, OmniEarth-Bench introduces cross-sphere evaluation capabilities for societally important tasks such as disaster prediction and ecological forecasting.
- CoT-Based Reasoning Evaluations in Earth Science. OmniEarth-Bench establishes, for the first time, CoT-based evaluations tailored for complex Earth science reasoning tasks, addressing scenarios where previous benchmarks showed near-zero accuracy, and explores how CoT strategies might enhance reasoning capabilities in the Earth domain.
📸Dataset
Comparision and Examples
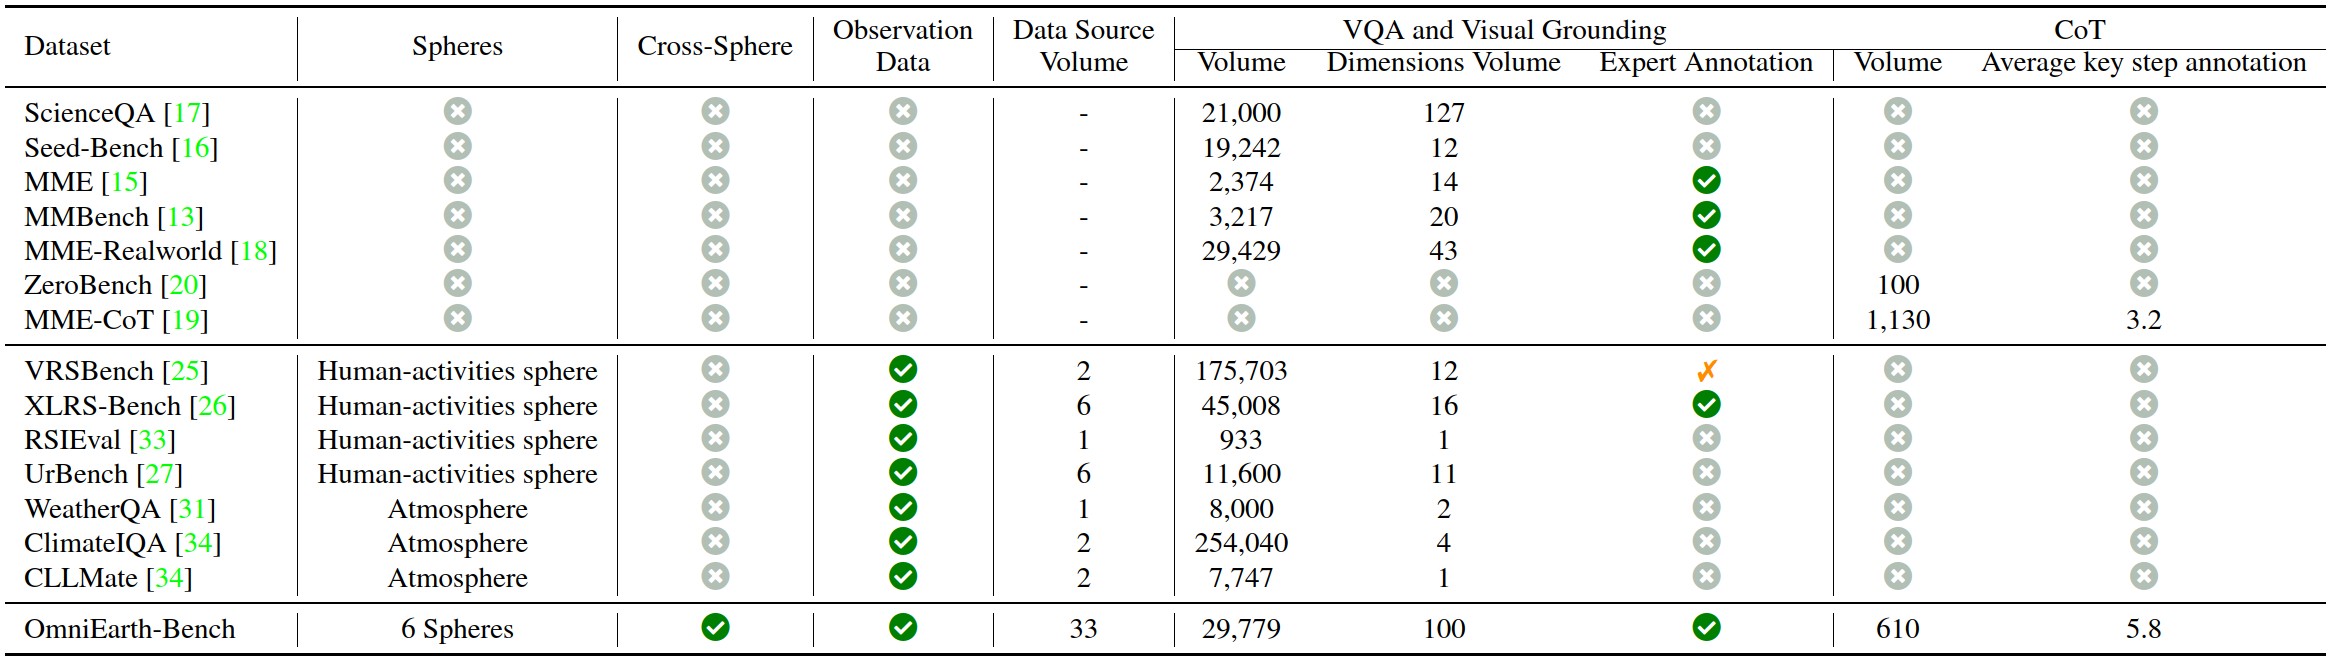
Fig 2. Comparision with existing benchmarks.
OmniEarth-Bench defines tasks across four hierarchical levels (L1–L4), comprising 7 L1 dimensions, 23 L2 dimensions, 4 L3 dimensions, and 103 expert-defined L4 subtasks with real-world applicability. One representative L4 subtask from each L1 sphere is illustrated in Fig 3. Detailed descriptions of the L3 and L4 dimensions are provided in the paper's appendix.
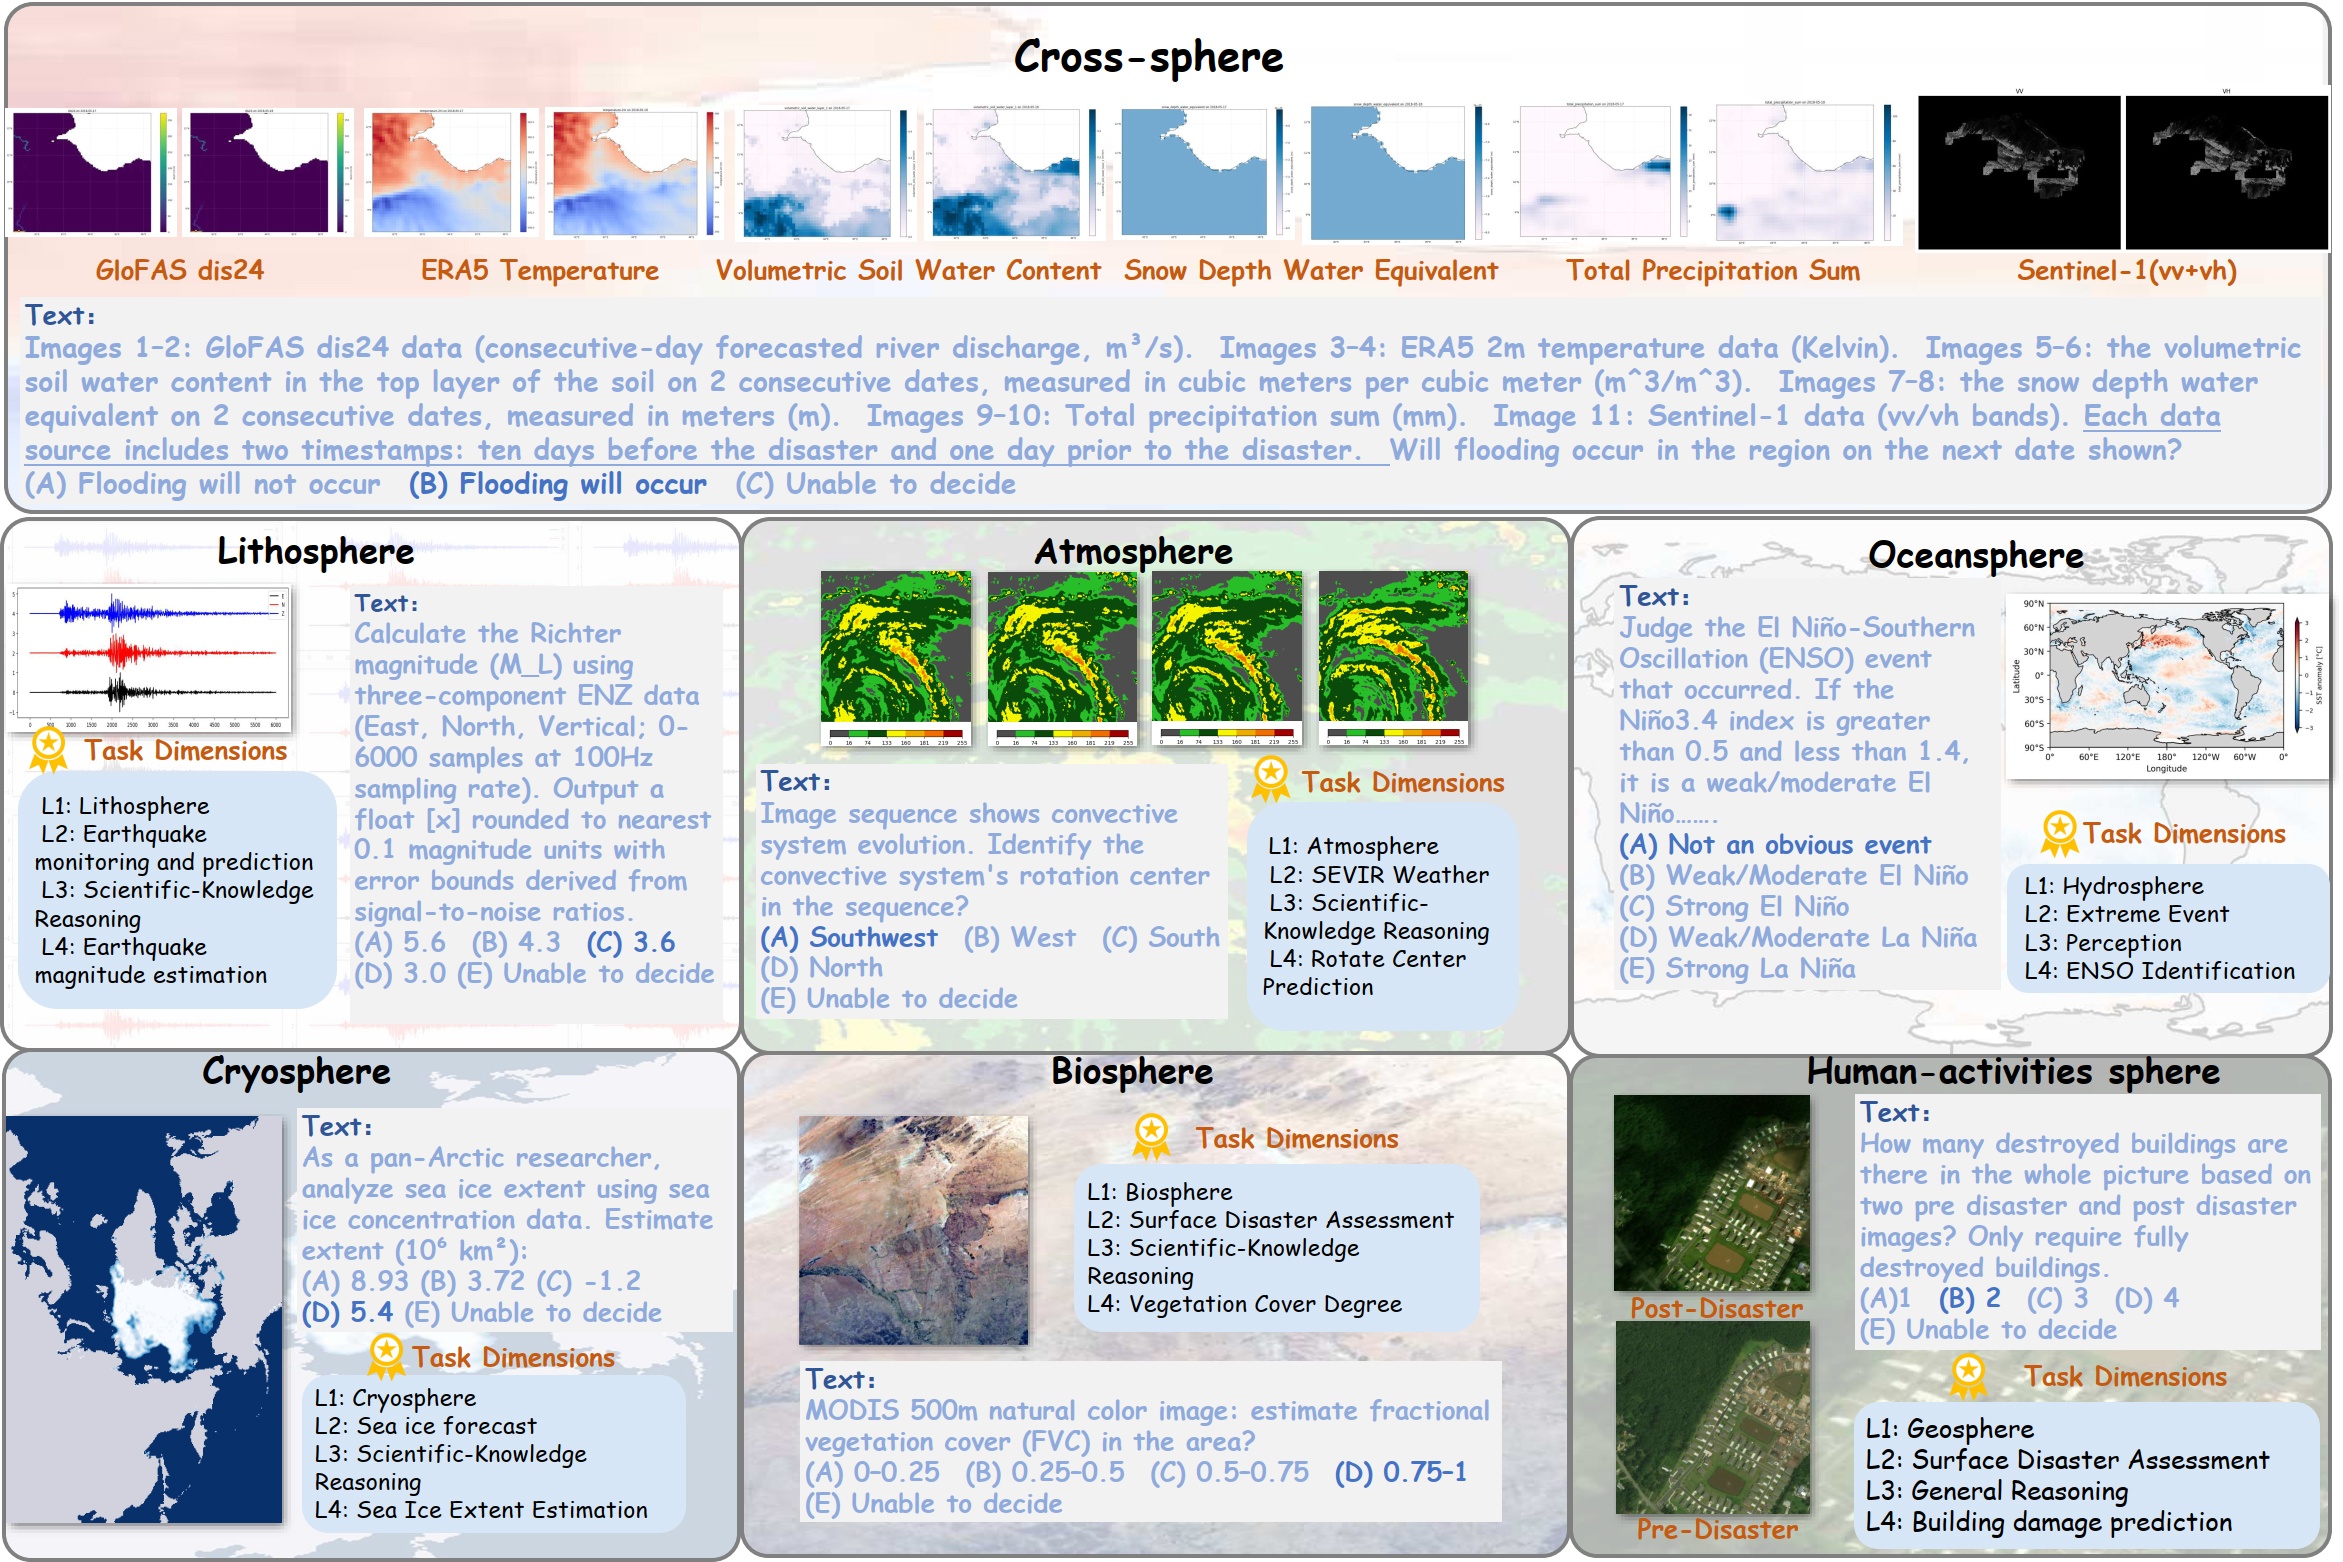
Fig 3. Examples of OmniEarth-Bench.
🚀Evaluation
Evaluation
1. Prepare data
- First download the dataset from huggingface.
- Unzip raw.tar, and copy
jsons/andraw/intoprepare_data/. - Run
mk_shards.py. This will generate parquet files used in evaluation.
2. Prepare task config
-
Enter the
task_config/folder and runmk_yaml.py. This will generate yaml task files, each of which stands for a L2 task used inlmms-eval.Note: to evaluate CoT tasks, you need to manually update the parquet path in
cot.yaml. -
Install lmms-eval and copy
task_config/intolmms_eval/tasks/
3. Benchmark
To test on L1 task Atmosphere, for example, run the following command:
TASKS="Atmosphere"	# A tag, can also be Biosphere, Pedosphere, etc.
MODEL="qwen2_5_vl"
PRETRAINED_MODEL="Qwen/Qwen2.5-VL-7B-Instruct"
MODEL_ARGS="pretrained=${PRETRAINED_MODEL},use_flash_attention_2=True"
LOG_SUFFIX="${MODEL}_${TASKS}"

accelerate launch --num_processes 8 --main_process_port 12345 -m lmms_eval \
    --model "qwen2_5_vl" \
    --model_args ${MODEL_ARGS}  \
    --tasks ${TASKS} \
    --batch_size 1 \
    --log_samples \
    --log_samples_suffix ${LOG_SUFFIX} \
    --output_path ./logs/
Check the yaml files for task names to run. The key task for each L2 tasks and tag for L1 tasks.
🔗Citation
If you find our work helpful, please consider citing:
@article{wang2025omniearthbenchholisticevaluationearths,
      title={OmniEarth-Bench: Towards Holistic Evaluation of Earth's Six Spheres and Cross-Spheres Interactions with Multimodal Observational Earth Data},
      author={Fengxiang Wang and Mingshuo Chen and Xuming He and YiFan Zhang and Feng Liu and Zijie Guo and Zhenghao Hu and Jiong Wang and Jingyi Xu and Zhangrui Li and Fenghua Ling and Ben Fei and Weijia Li and Long Lan and Wenjing Yang and Wenlong Zhang and Lei Bai},
  journal={arXiv preprint arXiv:2505.23522},
      year={2025},
}
📬Contact
For any other questions please contact:
- Fengxiang Wang at wfx23@nudt.edu.cn
- Mingshuo Chen at chen.mingshuo@bupt.edu.cn
Similar repos


Languages
Python
98.7%
Shell
1.3%
Official repo for "OmniEarth-Bench: Towards Holistic Evaluation of Earth's Six Spheres and Cross-Spheres Interactions with Multimodal Observational Earth Data"
Python
12
13 commits
updated May 3, 2026
README
OmniEarth-Bench: Towards Holistic Evaluation of Earth's Six Spheres and Cross-Spheres Interactions with Multimodal Observational Earth Data
[📃 Paper] [🌐 Website] [🤗 OmniEarth-Bench] [🏆 Leaderboard]
🔥News
- [2025-05-15] Dataset released on Hugging Face.
📚 Contents
🔍Dataset Overview
Fig 1. Overview of OmniEarth-Bench.
We introduce OmniEarth-Bench, the first comprehensive multimodal benchmark spanning all six Earth science spheres (atmosphere, lithosphere, Oceansphere, cryosphere, biosphere and Human-activities sphere) and cross-spheres with one hundred expert-curated evaluation dimensions. Leveraging observational data from satellite sensors and in-situ measurements, OmniEarth-Bench integrates 29,779 annotations across four tiers: perception, general reasoning, Scientific‑knowledge reasoning and chain-of-thought (CoT) reasoning. The key contributions are:
- Comprehensive Evaluation Across All Six Spheres. OmniEarth-Bench is the first benchmark to extensively cover all Earth science spheres, offering 58 practical and comprehensive evaluation dimensions that significantly surpass prior benchmarks.
- Pioneering Cross-Sphere Evaluation Dimensions. To address complex real-world scenarios, OmniEarth-Bench introduces cross-sphere evaluation capabilities for societally important tasks such as disaster prediction and ecological forecasting.
- CoT-Based Reasoning Evaluations in Earth Science. OmniEarth-Bench establishes, for the first time, CoT-based evaluations tailored for complex Earth science reasoning tasks, addressing scenarios where previous benchmarks showed near-zero accuracy, and explores how CoT strategies might enhance reasoning capabilities in the Earth domain.
📸Dataset
Comparision and Examples
Fig 2. Comparision with existing benchmarks.
OmniEarth-Bench defines tasks across four hierarchical levels (L1–L4), comprising 7 L1 dimensions, 23 L2 dimensions, 4 L3 dimensions, and 103 expert-defined L4 subtasks with real-world applicability. One representative L4 subtask from each L1 sphere is illustrated in Fig 3. Detailed descriptions of the L3 and L4 dimensions are provided in the paper's appendix.
Fig 3. Examples of OmniEarth-Bench.
🚀Evaluation
Evaluation
1. Prepare data
- First download the dataset from huggingface.
- Unzip raw.tar, and copy
jsons/andraw/intoprepare_data/. - Run
mk_shards.py. This will generate parquet files used in evaluation.
2. Prepare task config
-
Enter the
task_config/folder and runmk_yaml.py. This will generate yaml task files, each of which stands for a L2 task used inlmms-eval.Note: to evaluate CoT tasks, you need to manually update the parquet path in
cot.yaml. -
Install lmms-eval and copy
task_config/intolmms_eval/tasks/
3. Benchmark
To test on L1 task Atmosphere, for example, run the following command:
TASKS="Atmosphere"	# A tag, can also be Biosphere, Pedosphere, etc.
MODEL="qwen2_5_vl"
PRETRAINED_MODEL="Qwen/Qwen2.5-VL-7B-Instruct"
MODEL_ARGS="pretrained=${PRETRAINED_MODEL},use_flash_attention_2=True"
LOG_SUFFIX="${MODEL}_${TASKS}"

accelerate launch --num_processes 8 --main_process_port 12345 -m lmms_eval \
    --model "qwen2_5_vl" \
    --model_args ${MODEL_ARGS}  \
    --tasks ${TASKS} \
    --batch_size 1 \
    --log_samples \
    --log_samples_suffix ${LOG_SUFFIX} \
    --output_path ./logs/
Check the yaml files for task names to run. The key task for each L2 tasks and tag for L1 tasks.
🔗Citation
If you find our work helpful, please consider citing:
@article{wang2025omniearthbenchholisticevaluationearths,
      title={OmniEarth-Bench: Towards Holistic Evaluation of Earth's Six Spheres and Cross-Spheres Interactions with Multimodal Observational Earth Data},
      author={Fengxiang Wang and Mingshuo Chen and Xuming He and YiFan Zhang and Feng Liu and Zijie Guo and Zhenghao Hu and Jiong Wang and Jingyi Xu and Zhangrui Li and Fenghua Ling and Ben Fei and Weijia Li and Long Lan and Wenjing Yang and Wenlong Zhang and Lei Bai},
  journal={arXiv preprint arXiv:2505.23522},
      year={2025},
}
📬Contact
For any other questions please contact:
- Fengxiang Wang at wfx23@nudt.edu.cn
- Mingshuo Chen at chen.mingshuo@bupt.edu.cn
Similar repos
Languages
Python
98.7%
Shell
1.3%