
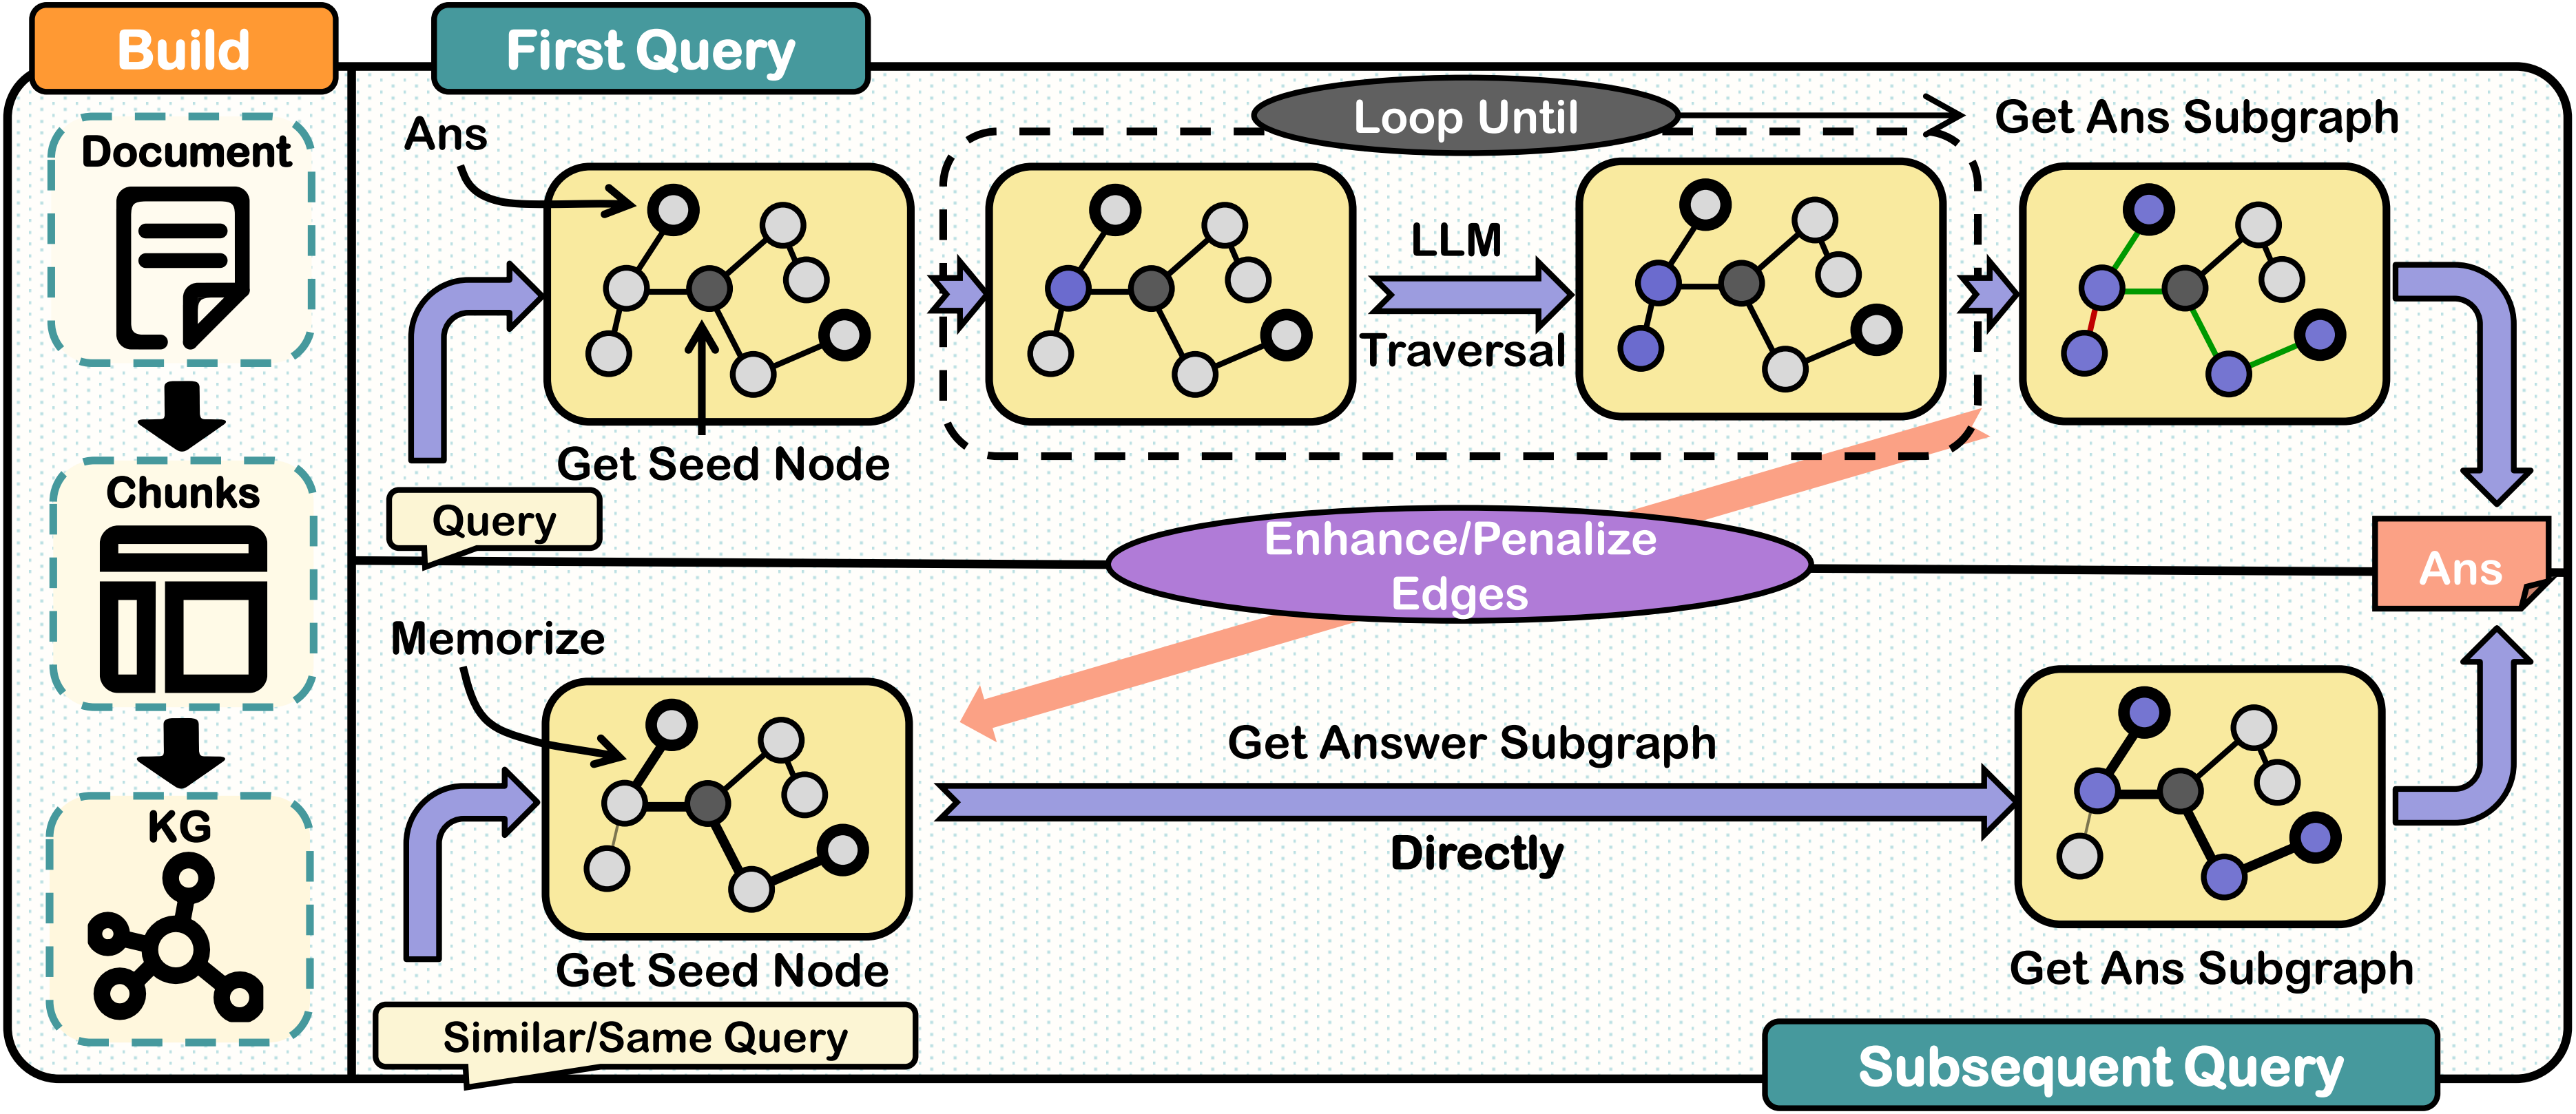
Unlike traditional methods, it resolves long dependencies and multi-hop reasoning while minimizing computational overhead. By memorizing traversal paths without additional training, ReMindRAG boosts accuracy and reduces retrieval costs for similar queries. Experiments show superior performance in complex tasks—especially multi-hop reasoning and long-range dependencies—with improved robustness, adaptability, and cost efficiency compared to existing approaches.
CS 5542 — Lab 7 Reproducibility Submission Team: Tony Nguyen · Daniel Evans· Joel Vinas Repository: mosomo82/ReMindRAG_Week7 📺 Demo Video: Watch on YouTube
docker build -t remindrag:latest .
docker run --rm remindrag:latest
# Expected: SUCCESS: RAG pipeline successfully retrieved chunks from the database.
pip install -r requirements.txt --extra-index-url https://download.pytorch.org/whl/cu126
python tests/smoke_test.py
# Writes result to: artifacts/smoke_test_result.json
make setup       # Install dependencies
make smoke       # Run smoke test
make test        # Run full 17-test audit suite
make streamlit   # Run the standalone Streamlit interface
See RUN.md for complete run instructions including evaluation scripts and WebUI.
| Document | Purpose |
|---|---|
| RUN.md | Complete run instructions — Docker, native, Makefile, eval |
| REPRO_AUDIT.md | 14-issue reproducibility audit with severity ratings and test evidence |
| RELATED_WORK_REPRO.md | Reproduction attempt — what worked, what failed, gaps, improvements |
| reproduce.sh | Cross-platform automation script (Linux/macOS) |
| reproduce.ps1 | PowerShell automation script (Windows) |
| Makefile | Convenience targets: setup, smoke, test, docker, clean |
| config.yaml | Config-driven execution — all hyperparameters in one place |
| tests/smoke_test.py | Smoke test — exits 0 on success, writes JSON artifact |
| tests/test_reproducibility.py | 17-test audit suite covering all 14 reproducibility fixes |
| artifacts/smoke_test_result.json | Sample output artifact |
| BENCHMARKING.md | Paper-vs-repro comparison, constrained LooGLE/HotpotQA results |
| REPRO_VERIFICATION.md | 26-test suite design, CI YAML, manual verification table |
| .env.template | Secure onboarding template for API keys |
| Severity | Issues Fixed |
|---|---|
| CRITICAL | Missing directory creation (model_cache/, chroma_data/, logs/, temp/), UTF-16 encoded requirements file, missing CUDA wheel index URL. NEW: PyTorch +cu126 wheels crashed Streamlit Cloud deployments; fixed by dropping namespace to standard PyPI wheels. |
| HIGH | Hardcoded judge model, missing eval resume guard, daatabase_description typo, undocumented HuggingFace auth. NEW: NaiveChunker crashed on Markdown tables (token sequence > 512); fixed by pre-splitting on newlines before NLTK sent_tokenize. |
| MEDIUM | Windows path separators → os.path.join, CWD-relative imports → __file__-relative, missing --seed arg. NEW: Added reproduce.ps1 for native Windows environment bootstrapping. Added einops dependency explicitly required for gated Nomic MoE models. |
All fixes verified by automated test suite and Streamlit runtime validations.
conda create -n ReMindRag python==3.13.2
conda activate ReMindRag
pip install -r requirements.txt --extra-index-url https://download.pytorch.org/whl/cu126
Note: The
--extra-index-urlflag is required because PyTorch CUDA 12.6 wheels (torch==2.6.0+cu126) are hosted on PyTorch's own server, not PyPI. For CPU-only, omit the flag or use+cpusuffix.
Note: The embedding model (
nomic-ai/nomic-embed-text-v2-moe) requirestrust_remote_code=True. This is set automatically inside the library. SetTRUST_REMOTE_CODE=1if you encounter a hang in non-interactive shells.
Fill in api_key.json:
[{ "base_url": "https://api.openai.com/v1", "api_key": "sk-proj-..." }]
# Persistent (recommended)
huggingface-cli login

# Or per-session
export HF_TOKEN="hf_YourTokenHere"           # Linux/Mac
$env:HF_TOKEN = "hf_YourTokenHere"           # Windows PowerShell
Download nomic-ai/nomic-embed-text-v2-moe into ./model_cache/.
For a lightweight smoke test, use
sentence-transformers/all-MiniLM-L6-v2(384-dim, no HF token needed).
python example/example.py
Step 1: Download preprocessed LooGLE dataset from Google Drive and extract to eval/dataset_cache/LooGLE-rewrite-data/.
Step 2: Run evaluation:
python eval/eval_LooGLE.py \
  --title_index 0 --data_type longdep_qa \
  --question_type origin --seed 42 \
  --judge_model_name gpt-4o-mini

python eval/eval_Hotpot.py --seed 42 --judge_model_name gpt-4o-mini
--seedensures deterministic results.--judge_model_namelets you use a cheaper judge (e.g.gpt-4o-miniinstead ofgpt-4o).
All parameters can be set in config.yaml instead of CLI flags:
python eval/eval_LooGLE.py --config config.yaml
| Parameter | Type | Default | Description |
|---|---|---|---|
edge_weight_coefficient | Float | 0.1 | Adjusts reliance on edge embedding for strong links (range 0.1–0.2) |
strong_connection_threshold | Float | 0.55 | Practical range 0.5–0.75 balances retrieval cost and memory capacity |
synonym_threshold | Float | 0.7 | Merges entities when embedding similarity exceeds this value |
database_description | Str | None | A brief one-sentence description of your data |
save_dir | Str | None | Your data storage path |
logger_level | Int | None | Logger level (Level 5 = Trace, lowest) |
log_path | Str | None | Your log storage path |
| Parameter | Type | Default | Description |
|---|---|---|---|
max_jumps | Int | 10 | Controls nodes expanded during subgraph queries |
max_split_question_num | Int | 1 | Max sub-questions from semantic decomposition (set 1 to skip split) |
search_key_nums | Int | 2 | Number of seed nodes in query initialization |
system_prompt | Str | None | System prompt (uses default if not set) |
force_do_rag | Bool | False | If False, system decides automatically whether to do RAG |
do_update | Bool | True | If False, memory function is disabled for this query |
from ReMindRag.llms import OpenaiAgent
agent = OpenaiAgent("your_api_key_url", "your_api_key", "your model name")
Subclass AgentBase in ReMindRag/llms/base.py for custom LLMs.
from ReMindRag.embeddings import HgEmbedding
embedding = HgEmbedding("your model name", "your model cache dir")
Subclass EmbeddingBase in ReMindRag/embeddings/base.py for custom embeddings.
from ReMindRag.chunking import NaiveChunker
chunker = NaiveChunker("your tokenizer name", "your tokenizer cache dir", max_token_length=200)
Subclass ChunkerBase in ReMindRag/chunking/base.py for custom chunking.
ReMindRAG/
├── ReMindRag/                    # Core library
│   ├── rag_main.py               # Main entry point
│   ├── chunking/                 # Text chunking strategies
│   ├── llms/                     # LLM agent interfaces
│   ├── embeddings/               # Embedding model interfaces
│   ├── database/                 # ChromaDB + entity extraction
│   ├── generator/                # Query preprocessing + KG traversal
│   ├── kg/                       # Knowledge graph visualization
│   ├── utils/                    # Utility components
│   └── webui/                    # Flask WebUI
├── eval/                         # Evaluation scripts (LooGLE, HotpotQA)
├── example/                      # Demo script + example data
├── tests/
│   ├── smoke_test.py             # Quick smoke test (no API key needed)
│   └── test_reproducibility.py  # 17-test audit suite
├── artifacts/
│   └── smoke_test_result.json   # Smoke test output artifact
├── logs/                         # Runtime logs
├── Dockerfile                    # Reproducible container build
├── .dockerignore                 # Excludes stale cache from image
├── config.yaml                   # Config-driven execution
├── reproduce.sh                  # Cross-platform automation script
├── Makefile                      # Convenience targets
├── requirements.txt              # Pinned dependencies (146 packages)
├── environment.yml               # Conda environment spec
├── RUN.md                        # Complete run instructions
├── REPRO_AUDIT.md                # 14-issue reproducibility audit
└── RELATED_WORK_REPRO.md         # Related work reproduction report



