Video-Action Models for Generalizable Robot Control Beyond VLAs
See the codePaper · Website · Checkpoints
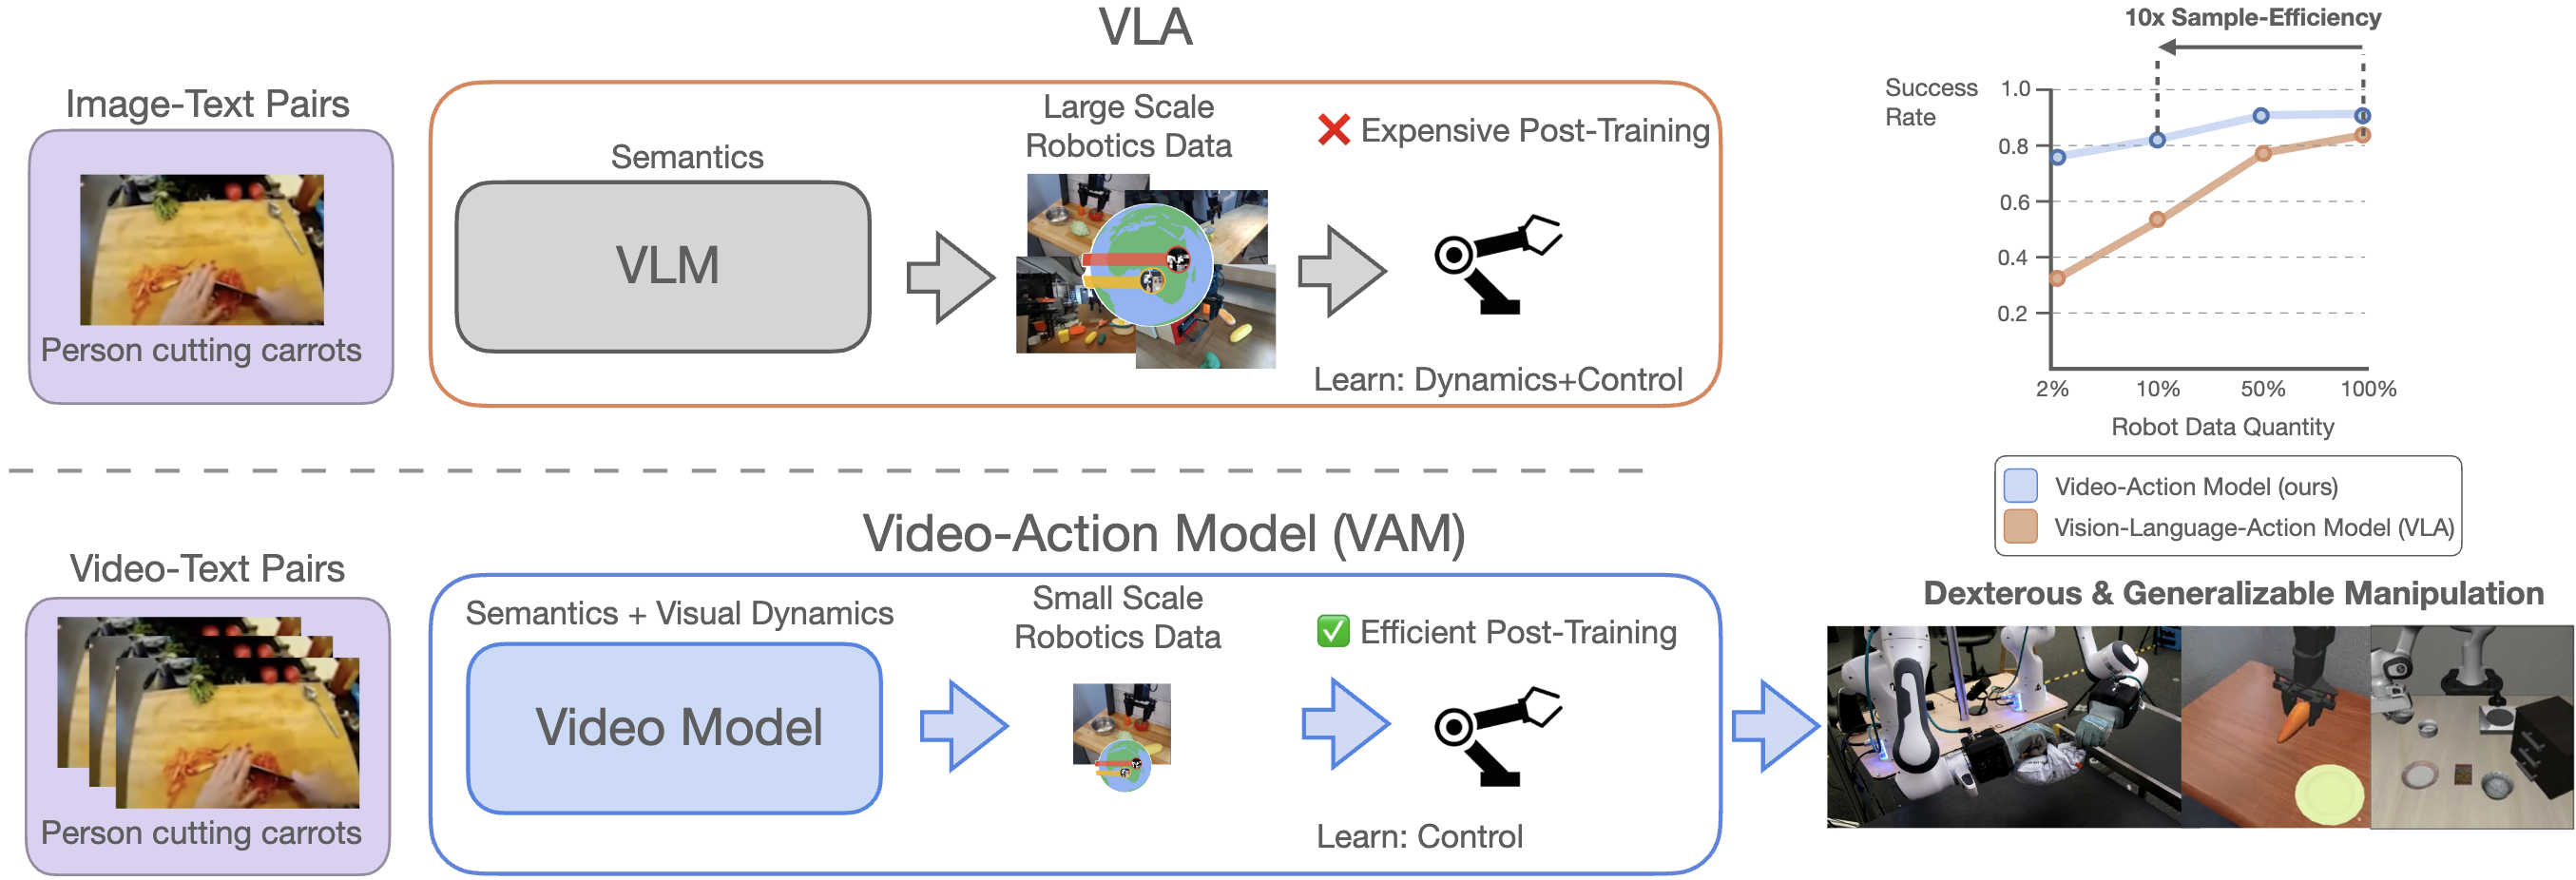
mimic-video extracts generalist language-conditioned robot policies (Video-Action Models / VAMs) from pretrained video models by conditioning small action decoders on the video backbones' latent representations. By drawing on the video model's knowledge of real-world dynamics and behaviors, performant action decoders can be learned efficiently and without updating the video model. Employing decoupled flow times for video and for actions, efficient inference can be performed with a single video model forward pass per action chunk.
We instantiate our approach with the lightweight 2B Cosmos-Predict2 video model and release trained checkpoints for Bridge and LIBERO.
We provide our data (DATA.md), modeling (MODEL.md), and evaluation (Evaluation) code. See the respective markdowns for details.
mimic-video
├── data_preprocessing  # data preprocessing
├── eval                # evaluation
└── model               # dataloading, model architecture, training, and inference
curl -LsSf https://astral.sh/uv/install.sh | sh
cd model

# for hopper
uv sync --extra cu126
# for blackwell
uv sync --extra cu129

source .venv/bin/activate
hf auth login

python scripts/download_checkpoints.py
If you want to run guardrails (default enabled), additionally request access to and download nvidia/Cosmos-Guardrail1 and meta-llama/Llama-Guard-3-8B to the checkpoints directory.
You can find an overview over the training repository (which is built on the Cosmos-Predict2 repo) in MODEL.md. A quickstart to training your own models is given below.
Multi-node & multi-gpu configuration is handled through torchrun.
Fill in your wandb entity name in the wandb callback config.
This assumes you have downloaded at least the text encoder, video tokenizer, and v2w_pretrained_cosmos.
/path/to/data/dataset/./path/to/data/dataset/video/ with ep.mp4 and /path/to/data/dataset/metas/ with ep.txt files. Example scripts for bridge and libero are provided in data_preprocessing/video. Instructions for downloading these datasets (and fixing libero) are in Action Decoder Pretraining./path/to/data/dataset/language_embeddings/.cd data_preprocessing/video/
python precompute_t5_embeddings.py --dataset-path /path/to/data/dataset/
/path/to/data/dataset/video_embeddings/.python precompute_video_embeddings.py --dataset-dir /path/to/data/dataset/ --target-fps ? --num-samples-per-second ?
train_datasets in data_video.py.torchrun -m scripts.train --config=cosmos_predict2/configs/config.py -- experiment=...
This assumes you have downloaded the text encoder, video tokenizer, and the video backbone you would like to train an action decoder for.
aria2c -x 16 -s 16 -c "https://rail.eecs.berkeley.edu/datasets/bridge_release/data/demos_8_17.zip"
7z x demos_8_17.zip -obridge_raw/
rm bridge_raw/raw/traj.tar  # a duplicate episode
rm -r bridge_raw/raw/bridge_data_v1/berkeley/toykitchen1/flip_pot_upright_in_sink_distractors/2021-06-02_16-36-21/raw/traj_group0/traj18/  # only three images
rm -r bridge_raw/raw/bridge_data_v2/datacol2_toykitchen1/pnp_push_sweep/04/2023-07-05_16-29-29/raw/traj_group0/traj49/  # no lowdim data
rm -r bridge_raw/raw/bridge_data_v2/datacol2_toykitchen1/pnp_push_sweep/01/2023-07-03_15-11-24/raw/traj_group0/traj24/  # no lowdim data
cd data_preprocessing/action/
python process_bridge.py --raw-dir ../../bridge_raw/raw --output-dir /path/to/data/bridge/
# If you already computed them for video model finetuning:
python transfer_t5_bridge.py --dataset-path /path/to/data/bridge/ --language-embeddings-path /path/to/data/bridge_video/language_embeddings/
# Otherwise:
python precompute_t5.py --dataset-path /path/to/data/bridge/
python transfer_video_embeddings_bridge.py --dataset-path /path/to/data/bridge/ --video-embeddings-path /path/to/data/bridge_video/video_embeddings/
cd ../../model
torchrun -m scripts.train --config=cosmos_predict2/configs/config.py -- experiment=...
cd LIBERO
python benchmark_scripts/download_libero_datasets.py --use-huggingface
cd ../../../data_preprocessing/action/
PYTHONPATH=../../eval/libero/LIBERO/ python regenerate_libero.py --in-dir /path/to/libero/datasets/ --out-dir /path/to/libero/regenerated_datasets/
python process_libero.py --input-dir /path/to/libero/regenerated_datasets/ --output-dir /path/to/data/libero/
# It takes ~no time
python precompute_t5.py --dataset-path /path/to/data/libero/
python transfer_video_embeddings_libero.py --dataset-path /path/to/data/libero/ --video-embeddings-path /path/to/data/libero_video/video_embeddings/
cd ../../model
torchrun -m scripts.train --config=cosmos_predict2/configs/config.py -- experiment=...
We have integrated vanilla SIMPLER-Bridge, human-in-the-loop SIMPLER-Bridge (for ground-truth future video generation), and vanilla LIBERO evals in this repo. To reproduce the sim results with our checkpoints, follow these quick steps:
sudo apt install libvulkan1

cd eval/bridge

uv pip install -r SimplerEnv/requirements.txt
uv pip install -e SimplerEnv/ManiSkill2_real2sim
uv pip install -e SimplerEnv
This assumes you have the checkpoints from Environment Setup and Downloading Checkpoints.
# Adapt the `GPUS` list (line 1) to which GPUs to parallelize over (now: 0-7).
# Adapt line 8 for how many evals can run in parallel per GPU (now: 2).
# Fill in `checkpoint_dir` with the path to the checkpoint directory (line 33).
bash eval.sh
For this one, you have to sit down and teleop. The policy will get the ground-truth future video from the teleop, add noise, and then decode actions.
# Fill in `checkpoint_dir` with the path to the checkpoint directory (line 1).
bash eval_hil.sh
cd eval/libero

uv pip install -r LIBERO/requirements.txt
uv pip install -e LIBERO
This also assumes you have the checkpoints from Environment Setup and Downloading Checkpoints.
# Adapt the `GPUS` list (line 1) to which GPUs to parallelize over (now: 0-7).
# Adapt line 8 for how many evals can run in parallel per GPU (now: 2).
# Fill in `checkpoint_dir` with the path to the checkpoint directory (line 29).
bash eval.sh
Copyright 2026 mimic-video authors and mimic robotics AG

Licensed under the Apache License, Version 2.0 (the "License");
you may not use this repository except in compliance with the License.
You may obtain a copy of the License at

      http://www.apache.org/licenses/LICENSE-2.0

Unless required by applicable law or agreed to in writing, software
distributed under the License is distributed on an "AS IS" BASIS,
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
See the License for the specific language governing permissions and
limitations under the License.
@misc{pai2025mimicvideo,
      title={mimic-video: Video-Action Models for Generalizable Robot Control Beyond VLAs},
      author={Jonas Pai and Liam Achenbach and Victoriano Montesinos and Benedek Forrai and Oier Mees and Elvis Nava},
      year={2025},
      eprint={2512.15692},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2512.15692},
}
344 followers · starred Apr 2026
832 followers · starred Sep 2026
201 followers · starred Apr 2026
114 followers · starred Apr 2026
Video-Action Models for Generalizable Robot Control Beyond VLAs
See the codePaper · Website · Checkpoints
mimic-video extracts generalist language-conditioned robot policies (Video-Action Models / VAMs) from pretrained video models by conditioning small action decoders on the video backbones' latent representations. By drawing on the video model's knowledge of real-world dynamics and behaviors, performant action decoders can be learned efficiently and without updating the video model. Employing decoupled flow times for video and for actions, efficient inference can be performed with a single video model forward pass per action chunk.
We instantiate our approach with the lightweight 2B Cosmos-Predict2 video model and release trained checkpoints for Bridge and LIBERO.
We provide our data (DATA.md), modeling (MODEL.md), and evaluation (Evaluation) code. See the respective markdowns for details.
mimic-video
├── data_preprocessing  # data preprocessing
├── eval                # evaluation
└── model               # dataloading, model architecture, training, and inference
curl -LsSf https://astral.sh/uv/install.sh | sh
cd model

# for hopper
uv sync --extra cu126
# for blackwell
uv sync --extra cu129

source .venv/bin/activate
hf auth login

python scripts/download_checkpoints.py
If you want to run guardrails (default enabled), additionally request access to and download nvidia/Cosmos-Guardrail1 and meta-llama/Llama-Guard-3-8B to the checkpoints directory.
You can find an overview over the training repository (which is built on the Cosmos-Predict2 repo) in MODEL.md. A quickstart to training your own models is given below.
Multi-node & multi-gpu configuration is handled through torchrun.
Fill in your wandb entity name in the wandb callback config.
This assumes you have downloaded at least the text encoder, video tokenizer, and v2w_pretrained_cosmos.
/path/to/data/dataset/./path/to/data/dataset/video/ with ep.mp4 and /path/to/data/dataset/metas/ with ep.txt files. Example scripts for bridge and libero are provided in data_preprocessing/video. Instructions for downloading these datasets (and fixing libero) are in Action Decoder Pretraining./path/to/data/dataset/language_embeddings/.cd data_preprocessing/video/
python precompute_t5_embeddings.py --dataset-path /path/to/data/dataset/
/path/to/data/dataset/video_embeddings/.python precompute_video_embeddings.py --dataset-dir /path/to/data/dataset/ --target-fps ? --num-samples-per-second ?
train_datasets in data_video.py.torchrun -m scripts.train --config=cosmos_predict2/configs/config.py -- experiment=...
This assumes you have downloaded the text encoder, video tokenizer, and the video backbone you would like to train an action decoder for.
aria2c -x 16 -s 16 -c "https://rail.eecs.berkeley.edu/datasets/bridge_release/data/demos_8_17.zip"
7z x demos_8_17.zip -obridge_raw/
rm bridge_raw/raw/traj.tar  # a duplicate episode
rm -r bridge_raw/raw/bridge_data_v1/berkeley/toykitchen1/flip_pot_upright_in_sink_distractors/2021-06-02_16-36-21/raw/traj_group0/traj18/  # only three images
rm -r bridge_raw/raw/bridge_data_v2/datacol2_toykitchen1/pnp_push_sweep/04/2023-07-05_16-29-29/raw/traj_group0/traj49/  # no lowdim data
rm -r bridge_raw/raw/bridge_data_v2/datacol2_toykitchen1/pnp_push_sweep/01/2023-07-03_15-11-24/raw/traj_group0/traj24/  # no lowdim data
cd data_preprocessing/action/
python process_bridge.py --raw-dir ../../bridge_raw/raw --output-dir /path/to/data/bridge/
# If you already computed them for video model finetuning:
python transfer_t5_bridge.py --dataset-path /path/to/data/bridge/ --language-embeddings-path /path/to/data/bridge_video/language_embeddings/
# Otherwise:
python precompute_t5.py --dataset-path /path/to/data/bridge/
python transfer_video_embeddings_bridge.py --dataset-path /path/to/data/bridge/ --video-embeddings-path /path/to/data/bridge_video/video_embeddings/
cd ../../model
torchrun -m scripts.train --config=cosmos_predict2/configs/config.py -- experiment=...
cd LIBERO
python benchmark_scripts/download_libero_datasets.py --use-huggingface
cd ../../../data_preprocessing/action/
PYTHONPATH=../../eval/libero/LIBERO/ python regenerate_libero.py --in-dir /path/to/libero/datasets/ --out-dir /path/to/libero/regenerated_datasets/
python process_libero.py --input-dir /path/to/libero/regenerated_datasets/ --output-dir /path/to/data/libero/
# It takes ~no time
python precompute_t5.py --dataset-path /path/to/data/libero/
python transfer_video_embeddings_libero.py --dataset-path /path/to/data/libero/ --video-embeddings-path /path/to/data/libero_video/video_embeddings/
cd ../../model
torchrun -m scripts.train --config=cosmos_predict2/configs/config.py -- experiment=...
We have integrated vanilla SIMPLER-Bridge, human-in-the-loop SIMPLER-Bridge (for ground-truth future video generation), and vanilla LIBERO evals in this repo. To reproduce the sim results with our checkpoints, follow these quick steps:
sudo apt install libvulkan1

cd eval/bridge

uv pip install -r SimplerEnv/requirements.txt
uv pip install -e SimplerEnv/ManiSkill2_real2sim
uv pip install -e SimplerEnv
This assumes you have the checkpoints from Environment Setup and Downloading Checkpoints.
# Adapt the `GPUS` list (line 1) to which GPUs to parallelize over (now: 0-7).
# Adapt line 8 for how many evals can run in parallel per GPU (now: 2).
# Fill in `checkpoint_dir` with the path to the checkpoint directory (line 33).
bash eval.sh
For this one, you have to sit down and teleop. The policy will get the ground-truth future video from the teleop, add noise, and then decode actions.
# Fill in `checkpoint_dir` with the path to the checkpoint directory (line 1).
bash eval_hil.sh
cd eval/libero

uv pip install -r LIBERO/requirements.txt
uv pip install -e LIBERO
This also assumes you have the checkpoints from Environment Setup and Downloading Checkpoints.
# Adapt the `GPUS` list (line 1) to which GPUs to parallelize over (now: 0-7).
# Adapt line 8 for how many evals can run in parallel per GPU (now: 2).
# Fill in `checkpoint_dir` with the path to the checkpoint directory (line 29).
bash eval.sh
Copyright 2026 mimic-video authors and mimic robotics AG

Licensed under the Apache License, Version 2.0 (the "License");
you may not use this repository except in compliance with the License.
You may obtain a copy of the License at

      http://www.apache.org/licenses/LICENSE-2.0

Unless required by applicable law or agreed to in writing, software
distributed under the License is distributed on an "AS IS" BASIS,
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
See the License for the specific language governing permissions and
limitations under the License.
@misc{pai2025mimicvideo,
      title={mimic-video: Video-Action Models for Generalizable Robot Control Beyond VLAs},
      author={Jonas Pai and Liam Achenbach and Victoriano Montesinos and Benedek Forrai and Oier Mees and Elvis Nava},
      year={2025},
      eprint={2512.15692},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2512.15692},
}
344 followers · starred Apr 2026
832 followers · starred Sep 2026
201 followers · starred Apr 2026
114 followers · starred Apr 2026