A simple SWE style browser+desktop agent framework that achieves SOTA results on long horizon web tasks.
Python
6,048
56 commits
updated Oct 6, 2026
Webwright is now CUAWright. Alongside browser automation, you can now run desktop tasks in an Ubuntu VM. Use
cuawright webfor browser tasks andcuawright desktopfor desktop tasks. Existingwebwrightcommands and Python imports still work.
Turn coding models into browser and desktop agents

CUAWright gives coding models a terminal to automate browsers and desktop applications. Use Webwright to browse the web and build reusable Playwright scripts, or run your own desktop task and reproduce OSWorld-V2 benchmarks in an Ubuntu VM.
Start with the browser quick start or desktop quick start.
Already got your favorite agents, and wonder how to make Claude Code, Codex, Hermes more capable in browser tasks? Consider adding CUAWright browser plugin/skill!
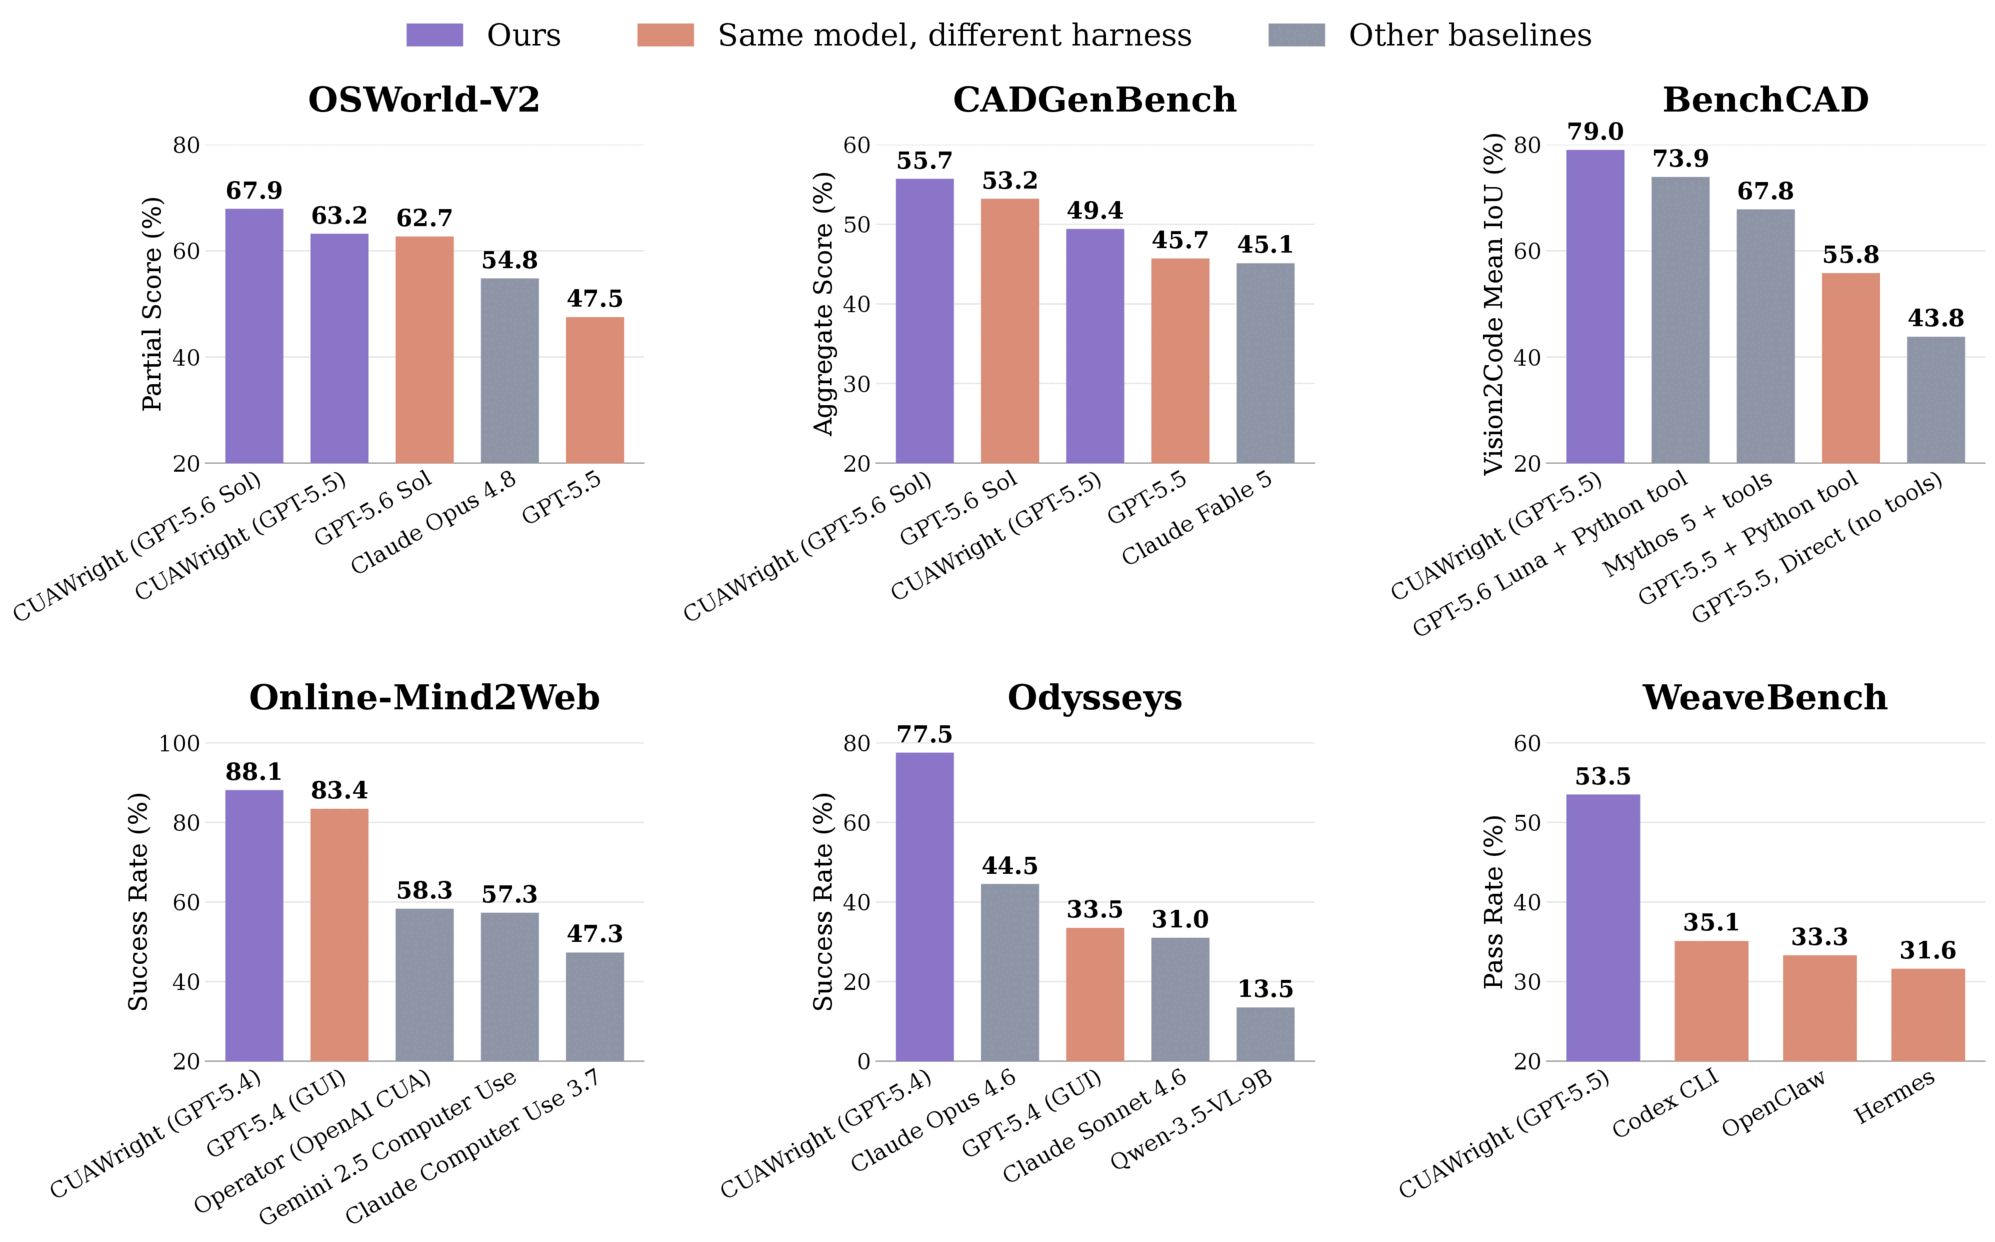
cuawright.webwright, and OSWorld desktop support lives at cuawright.desktop. Existing webwright commands and imports remain compatible. See desktop setup.run_command tool calls improve performance to 88.1% on Online-Mind2Web and 77.5% on Odysseys./plugin install cuawright@cuawright. Hermes Agent integration shipped; the same skills/cuawright-web/ folder now loads across Claude Code, Codex, and Hermes.Most web agents today treat the browser session itself as the workspace: at each step the model receives the current page state and predicts a single next operation — a click, a type, a DOM selector, or a short tool call. Whatever the format, the agent is locked into predicting one web action at a time inside a predefined interaction loop. That harness was useful when LLMs were weaker. As models get stronger at writing and debugging code, the same harness becomes a bottleneck.
Webwright takes a different stance: separate the agent from the browser, and treat the browser as something the agent can launch, inspect, and discard while developing a program. The persistent artifact is not the browser session — it's the code and logs in the local workspace.
Most web agent frameworks bury the actual agent loop under layers of abstractions. Webwright takes the opposite stance:
src/cuawright/webwright/.httpx, pydantic, playwright, and typer.If you want a minimal, easy-to-debug starting point for browser-using agents instead of another heavyweight platform, this is it.
How they differ at the architectural level:
| Stagehand (Browserbase) | agent-browser (Vercel) | browser-use | Webwright | |
|---|---|---|---|---|
| Paradigm | Hybrid: code + NL primitives (act / extract / agent) | CLI tool that another agent (Claude Code, Codex, etc.) calls | Autonomous LLM agent loop over DOM/AX snapshots | Coding agent with a terminal; browser is just an environment it spawns |
| Action space | Playwright code, or NL → LLM-translated Playwright | Discrete subcommands (open, click @e2, snapshot, eval) | Indexed click/type actions selected by the LLM | Free-form Python (writes Playwright scripts itself) |
| What is "state"? | The browser session | The browser session (held by daemon across CLI calls) | The browser session | The local workspace — code, screenshots, logs. Browser is disposable. |
| Loop shape | Imperative; agent() does multi-step when needed | One CLI invocation per micro-step | observe → predict next action → execute → repeat | write code → execute → inspect screenshots → repair (code-as-action) |
CUAWright demo
https://github.com/user-attachments/assets/2063be64-4d0a-40a2-9d1f-7906be43f2c9
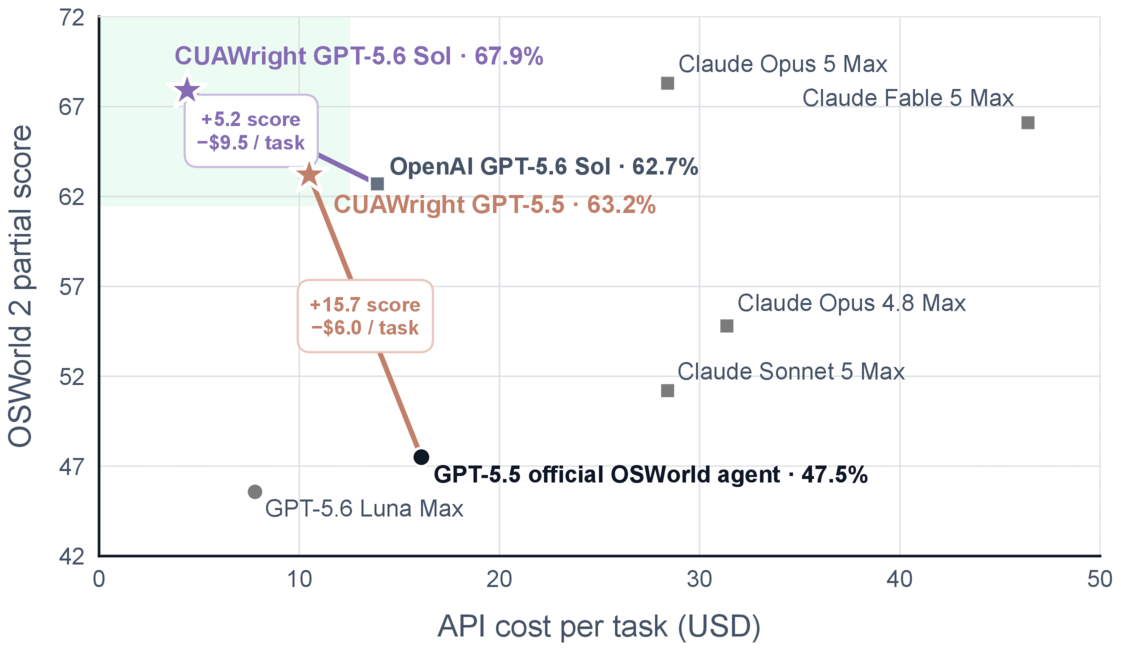
CUAWright beats the same model running in a different harness on every benchmark below, from desktop and CAD to long-horizon web tasks. See the paper for full details.
CUAWright/
├── pyproject.toml                      # package, dependency extras, CLI commands
├── setup.py                            # desktop provenance in wheels and source archives
├── src/
│   ├── cuawright/
│   │   ├── core/                       # shared API helpers
│   │   ├── webwright/                  # browser runtime
│   │   │   ├── agents/                 # browser agent loop
│   │   │   ├── environments/           # browser and terminal workspaces
│   │   │   ├── models/                 # OpenAI, Anthropic, OpenRouter backends
│   │   │   ├── tools/                  # browser sessions, images, self-reflection
│   │   │   ├── config/                 # stackable browser YAML configs
│   │   │   ├── run/                    # cuawright-web CLI and doctor
│   │   │   └── utils/                  # evidence, logging, serialization
│   │   └── desktop/                    # persistent desktop runtime
│   │       ├── agents/                 # desktop agent loop and call budget
│   │       ├── environments/osworld/   # VM commands, screenshots, and submission
│   │       ├── models/                 # standard Responses API transport and tools
│   │       ├── config/prompts.py       # desktop prompts
│   │       ├── setup.py                # pinned OSWorld setup and verification
│   │       ├── run/cli.py              # custom and official desktop workflows
│   │       ├── run/benchmarks/          # official task setup and evaluation
│   │       └── utils/                  # artifacts and provenance
│   └── webwright/__init__.py           # legacy Python import compatibility
├── extensions/skill-factory/           # optional cuawright-skill-factory distribution
│   ├── pyproject.toml                  # separate wheel; depends on the base package
│   └── src/cuawright/webwright/        # skill_factory/ and tools/skill_use.py
├── skills/cuawright-web/               # browser skill, commands, reference guides
├── .claude-plugin/                     # Claude Code plugin and marketplace manifests
├── .codex-plugin/                      # Codex plugin manifest
├── docs/                               # desktop setup and Skill Factory guides
├── tests/                              # browser, Skill Factory, compatibility tests
├── release/osworld/tests/              # desktop request, lifecycle, privacy tests
├── .github/workflows/                  # runtime and Skill Factory CI
├── assets/                             # showcase, trajectory viewer, figures, logos
├── LICENSE                             # MIT browser license
├── licenses/                           # Apache-2.0 desktop runtime license
└── NOTICE                              # imported runtime attribution
Webwright lets a coding model launch browsers, inspect pages, and debug its work from a terminal. Script-based runs produce a reusable Python script. Live-browser mode keeps a page open across steps and returns an answer without creating a script.
pip install -e .
playwright install chromium
Export credentials for the configured backend (for example, OPENAI_API_KEY
with model_openai.yaml or ANTHROPIC_API_KEY with model_claude.yaml). Then:
python -m cuawright.webwright.run.cli main \
    -c base.yaml -c model_openai.yaml \
    -t "Report the page title and the destination of its main link." \
    --start-url https://example.com \
    --task-id demo_openai \
    -o outputs/default
The image_qa and self_reflection tools use the run's configured model.
When running a tool separately, pass --model-config with an absolute path to a
private YAML file containing your model: settings. Keep that file outside the
checkout and results directory.
For incremental browsing with native OpenAI run_command tool calls, use:
cuawright-web main -c best_default_judge_json_persistent_cli.yaml -c model_openai.yaml \
  -t "<task>" --start-url "<url>" --task-id example -o outputs/example
This config keeps a Browserbase cloud session across commands. Set
OPENAI_API_KEY, BROWSERBASE_API_KEY, and BROWSERBASE_PROJECT_ID before running.
The agent runs shell commands, inspects the results, and checks its work before
finishing. See the browser workflow guide for image reading and
trajectory verification.
| Flag | Description |
|---|---|
-c | Config file(s) from src/cuawright/webwright/config/ (stackable). |
-t | Task instruction. |
--start-url | Initial page. |
--task-id | Output subfolder name. |
-o | Output directory. |
cuawright desktop runs tasks in an OSWorld-V2 Ubuntu VM. The agent uses a
terminal to inspect applications, run commands, view screenshots, and save its work.
You can give it your own task or run an official benchmark task with a score.
pip install -e ".[desktop]"
Before setup, accept access to the tasks and assets on Hugging Face, then log in:
pip install huggingface_hub
hf auth login
cuawright setup osworld --root ~/.cache/cuawright/osworld-v2-2026.08.08
cuawright verify osworld \
  --setup ~/.cache/cuawright/osworld-v2-2026.08.08/setup.json
Setup downloads the pinned source, task classes, assets, and VM by default; existing
resources can be registered without copying. Put the API key in a
user-owned file with mode 0600, outside source, task, asset, and result directories.
Choose a new result directory whose parent already exists.
cuawright desktop run \
  --setup /absolute/path/to/setup.json \
  --credentials /absolute/path/to/api-key \
  --results /absolute/path/to/results/custom \
  --model YOUR_MODEL \
  --instruction "<task>"
This workflow has no evaluator or score. For an official scored task:
cuawright desktop reproduce osworld \
  --setup /absolute/path/to/setup.json \
  --credentials /absolute/path/to/api-key \
  --results /absolute/path/to/results/task-001 \
  --task-id 001 --model YOUR_MODEL --reasoning xhigh
For another Responses-compatible provider, pass its full API URL with
--responses-url. See task selection and proxies
for official task IDs and --proxy-config setup.
Each run saves its settings in manifest.json, the agent's actions in trace.jsonl,
and the outcome in result.json. Images viewed by the agent are embedded in the
trace; desktop runs do not export separate screenshot files. Official benchmark
runs also include the evaluator score. Files created in the VM are not automatically
copied to the host; see custom tasks.
See REPRODUCE.md for setup, smoke tests, and reproduction commands,
or desktop setup and execution for more detail.
CUAWright ships plugin manifests for both Claude Code (.claude-plugin/plugin.json) and OpenAI Codex (.codex-plugin/plugin.json), with the shared skill at skills/cuawright-web/ and slash commands at skills/cuawright-web/commands/. The host agent drives the Webwright loop natively — no extra LLM API key or cost beyond your host subscription. Hosts that read PNG screenshots natively skip the image_qa / self_reflection tools.
The bundled cuawright-web skill handles browser tasks. Desktop tasks use
cuawright-desktop; see desktop setup.
Common runtime deps (install once after either path):
pip install -e .
playwright install chromium
Install through the bundled marketplace inside Claude Code:
# 1. Add this repo as a Claude Code plugin marketplace
/plugin marketplace add microsoft/Webwright

# 2. Install the plugin from that marketplace
/plugin install cuawright@cuawright
Prefer a local checkout? Point the marketplace command at the cloned repo instead:
/plugin marketplace add /absolute/path/to/Webwright
/plugin install cuawright@cuawright
Start a new Claude Code session after installing — plugins are loaded at session start and won't appear until you restart.
You can either ask Claude Code in plain English (the skill auto-activates from its description), or use one of the slash commands:
/cuawright:run search Google Flights for flights from SEA to JFK on 2026-08-15 to 2026-08-20
/cuawright:craft search a ticket on Google Flights from LAX to SFO depart June 7 return June 14
/cuawright:run (or any plain prompt) produces a one-shot final_script.py for the literal task values./cuawright:craft produces a reusable CLI tool: final_script.py becomes one parameterized function with a Google-style Args: docstring and an argparse wrapper whose flags default to the concrete task values, so you can rerun it later with different arguments — e.g. python final_script.py --origin JFK --destination LAX --depart-date 2026-07-01.In both modes Claude Code scaffolds a workspace with plan.md, runs instrumented Playwright scripts under final_runs/run_<id>/, and visually self-verifies each critical point against the saved screenshots.
Codex reads Claude-style marketplaces, so the same repo works as a Codex plugin marketplace. From the Codex CLI:
# 1. Add this repo as a Codex plugin marketplace
codex plugin marketplace add microsoft/Webwright

# 2. Open the plugin browser and install CUAWright
codex
/plugins
Prefer a local checkout?
codex plugin marketplace add /absolute/path/to/Webwright
Then restart Codex so the new marketplace and plugin are picked up.
In a new Codex thread, either ask in plain English (the skill auto-activates from its description) or invoke the bundled skill explicitly with @cuawright-web:
@cuawright-web search Google Flights for flights from SEA to JFK on 2026-08-15 to 2026-08-20
Codex scaffolds a workspace with plan.md, runs instrumented Playwright scripts under final_runs/run_<id>/, and visually self-verifies each critical point against the saved screenshots.
To turn the plugin off without uninstalling, set its entry in ~/.codex/config.toml to enabled = false and restart Codex.
Hermes Agent is a skills-compatible client, so the same skills/cuawright-web/ folder loads as a Hermes skill. Symlink it into your Hermes user-skills directory:
mkdir -p ~/.hermes/skills
ln -sfn /absolute/path/to/Webwright/skills/cuawright-web ~/.hermes/skills/cuawright-web
No Hermes-specific manifest is needed; only SKILL.md is loaded.
Start Hermes (hermes) and ask it to drive a web task in natural language — the skill auto-activates from its description. You can also invoke it explicitly with /cuawright-web.
Note: the named subcommands shipped under skills/cuawright-web/commands/ (/cuawright:run, /cuawright:craft) are a Claude Code / Codex convention and are inert in Hermes; the skill itself still works end-to-end.
A tiny Flask app under assets/task_showcase/ consolidates
Webwright runs for repeatable odyssey tasks (deals, inventory, listings,
job boards, weather, etc.) into a single dashboard. Each task ships only two
files — task.json (metadata) and report.json (curated, structured output:
sources + result sections like tables, lists, summaries) — and the templates
render them generically, so adding a new task is just dropping a new folder
in assets/task_showcase/tasks/.
pip install flask
python assets/task_showcase/app.py    # http://127.0.0.1:5005
To have Webwright produce a renderer-ready task folder at runtime, stack the Task Showcase overlay:
python -m cuawright.webwright.run.cli main \
    -c base.yaml -c model_openai.yaml -c task_showcase.yaml \
    -t "<repeatable web task>" \
    --task-id my_repeatable_task \
    -o outputs/default
Note:
report.jsonis only generated when-c task_showcase.yamlis included. A plainbase.yamlrun producestrajectory.jsonand debug artifacts but noreport.json.
The run writes task_showcase/tasks/<short_id>/task.json and report.json
inside the output workspace. Render those generated files without copying them
back into the repo:
python assets/task_showcase/app.py \
    --tasks-dir outputs/default/<run>/task_showcase/tasks
Skill Factory is an optional extension for learning and reusing browser automation scripts. Install it from this checkout:
pip install -e ".[skill-factory]" -e extensions/skill-factory
cuawright-skill-factory --help
For desktop execution and Skill Factory together, use
pip install -e ".[desktop,skill-factory]" -e extensions/skill-factory.
Most agent skills are context the model reads. Ours are programs.
cuawright.webwright.skill_factory distills the script every solve leaves
behind into a growing library of reusable, verified, parameterized skills — code you can run
without a model and compose into the next task instead of re-exploring the site. Plugs in with
no change to the agent loop:
recommend):
route either runs a matching skill directly (no model) or injects it into the prompt as a prior
({verdict: run|adapt|skip, skill_id, source_path}); the agent reuses the hint without ever
querying the library itself.python -m cuawright.webwright.skill_factory learn outputs/ --library ./library
groups solves of the same template and distills one parameterized skill (build does solve→learn
in one shot; update is manual-manifest mode).Before adding a skill, the input gate compares the result with gold answers when available. Otherwise it checks the output's shape and the agent's reported success; this fallback can admit an incorrect answer. The generated script is then replayed without a model, and updates are checked against previous examples.
Once learned, a skill runs standalone in ~40 s with zero tokens. On WebArena (10 retrieve-type
templates, 3 self-hosted sites, gpt-5.4) reuse lifts held-out accuracy 55% → 70% (+15 pp) while
cutting steps. See extensions/skill-factory/src/cuawright/webwright/skill_factory/README.md.
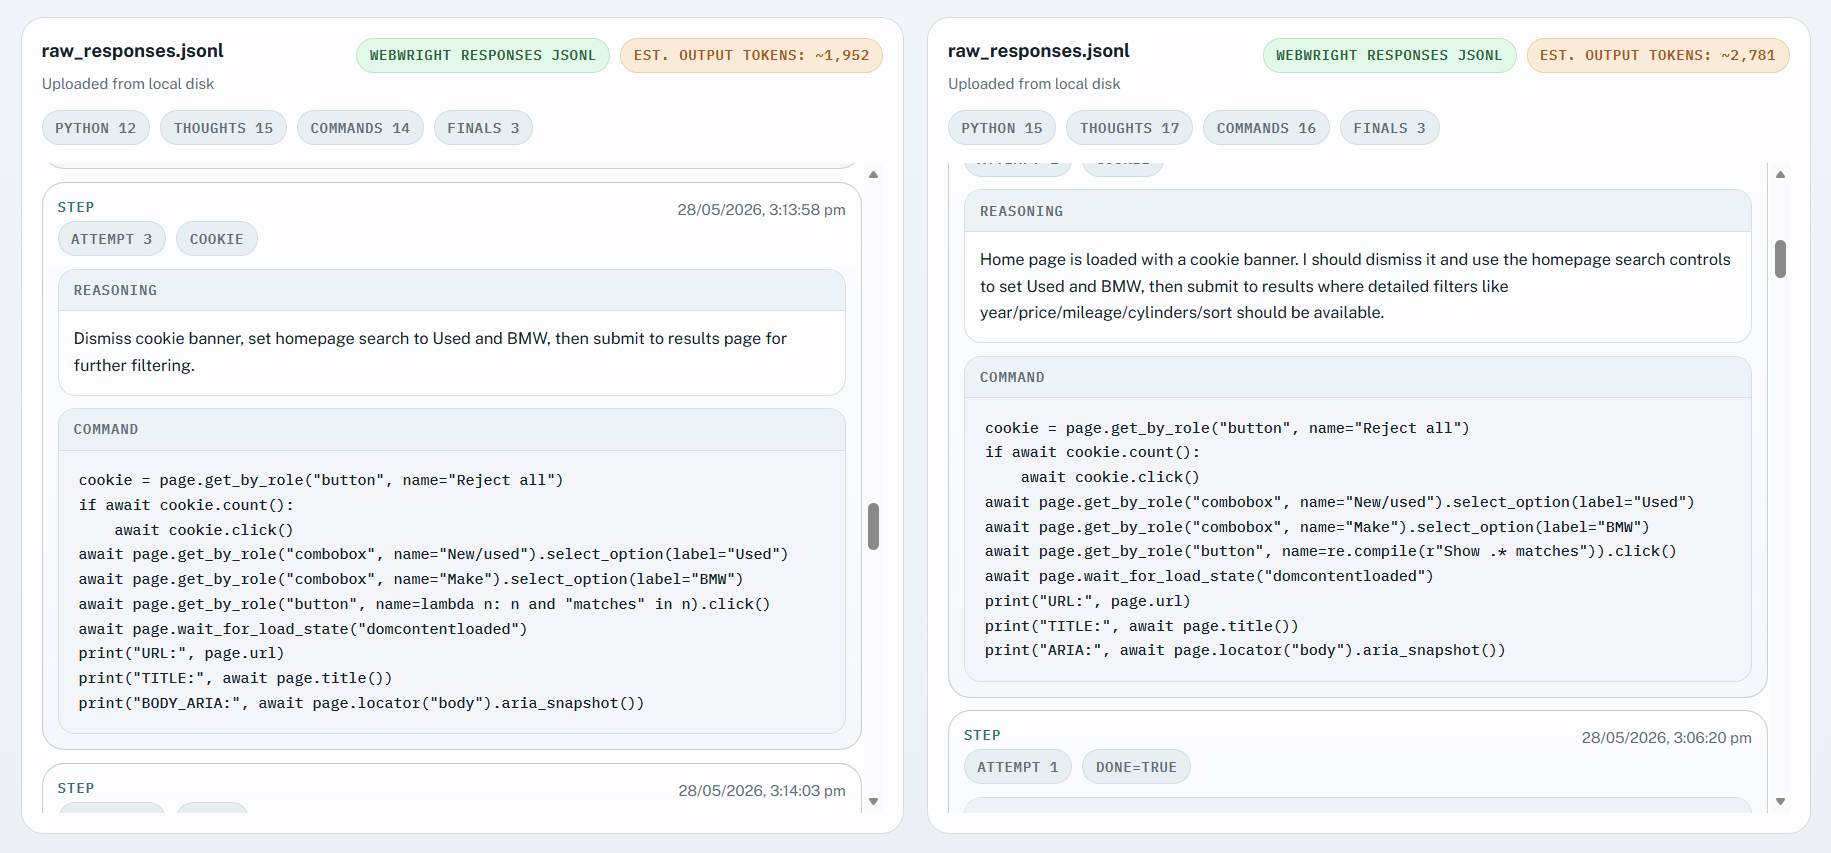
You can run the same tasks using the Webwright harness and its Codex / GitHub Copilot skill variant, and see how token usage and trajectories stack up between different harnesses. The trajectory viewer supports Codex, GitHub Copilot and Webwright harness traces.
cd assets/compare_trajectory/
python3 -m http.server
Open the webpage in your browser and upload the Webwright raw_responses.jsonl and attach trajectory.json to view. Then on the other side you can upload your Codex or GitHub Copilot trace.
ls ~/.codex/sessions/2026/MONTH/DAY/SESSION_ID.jsonl
/export file session
-> session.md is the uploadable trace
| Tokens | Webwright Harness (Local Browser Mode) | Codex Webwright Skill |
|---|---|---|
| Input | 420,433 | 3,271,143 |
| Output | 3,593 | 20,040 |
| Reasoning | 0 | 4,410 |
| Cached | 217,216 | — |
| Total | 424,026 | 3,291,183 |
The Codex cached-token count is omitted because the recorded figure needs verification. Individual runs and results may vary.
If you use CUAWright or Webwright in your research or build on it, please cite:
@misc{lu2026cuawright,
  title         = {CUAWright: A Minimal Unified Interface for Digital Agents},
  author        = {Lu, Yadong and Lee, Theodore and Li, Yifei and Jang, Lawrence Keunho and Xue, Tianci and Su, Yu and Sun, Huan and Awadallah, Ahmed Hassan},
  year          = {2026},
  eprint        = {2610.04116},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  url           = {https://arxiv.org/abs/2610.04116}
}

@misc{webwright2026,
  title        = {Webwright: A terminal is all you need for web agents},
  author       = {Lu, Yadong and Xu, Lingrui and Huang, Chao and Awadallah, Ahmed},
  year         = {2026},
  howpublished = {\url{https://github.com/microsoft/Webwright}},
  note         = {GitHub repository}
}
(top 24 of 40)
53,255 followers · starred May 2026
53,255 followers · starred May 2026
2,241 followers · starred May 2026
102 followers · starred May 2026
A simple SWE style browser+desktop agent framework that achieves SOTA results on long horizon web tasks.
Python
6,048
56 commits
updated Oct 6, 2026
Webwright is now CUAWright. Alongside browser automation, you can now run desktop tasks in an Ubuntu VM. Use
cuawright webfor browser tasks andcuawright desktopfor desktop tasks. Existingwebwrightcommands and Python imports still work.
Turn coding models into browser and desktop agents
CUAWright gives coding models a terminal to automate browsers and desktop applications. Use Webwright to browse the web and build reusable Playwright scripts, or run your own desktop task and reproduce OSWorld-V2 benchmarks in an Ubuntu VM.
Start with the browser quick start or desktop quick start.
Already got your favorite agents, and wonder how to make Claude Code, Codex, Hermes more capable in browser tasks? Consider adding CUAWright browser plugin/skill!
cuawright.webwright, and OSWorld desktop support lives at cuawright.desktop. Existing webwright commands and imports remain compatible. See desktop setup.run_command tool calls improve performance to 88.1% on Online-Mind2Web and 77.5% on Odysseys./plugin install cuawright@cuawright. Hermes Agent integration shipped; the same skills/cuawright-web/ folder now loads across Claude Code, Codex, and Hermes.Most web agents today treat the browser session itself as the workspace: at each step the model receives the current page state and predicts a single next operation — a click, a type, a DOM selector, or a short tool call. Whatever the format, the agent is locked into predicting one web action at a time inside a predefined interaction loop. That harness was useful when LLMs were weaker. As models get stronger at writing and debugging code, the same harness becomes a bottleneck.
Webwright takes a different stance: separate the agent from the browser, and treat the browser as something the agent can launch, inspect, and discard while developing a program. The persistent artifact is not the browser session — it's the code and logs in the local workspace.
Most web agent frameworks bury the actual agent loop under layers of abstractions. Webwright takes the opposite stance:
src/cuawright/webwright/.httpx, pydantic, playwright, and typer.If you want a minimal, easy-to-debug starting point for browser-using agents instead of another heavyweight platform, this is it.
How they differ at the architectural level:
| Stagehand (Browserbase) | agent-browser (Vercel) | browser-use | Webwright | |
|---|---|---|---|---|
| Paradigm | Hybrid: code + NL primitives (act / extract / agent) | CLI tool that another agent (Claude Code, Codex, etc.) calls | Autonomous LLM agent loop over DOM/AX snapshots | Coding agent with a terminal; browser is just an environment it spawns |
| Action space | Playwright code, or NL → LLM-translated Playwright | Discrete subcommands (open, click @e2, snapshot, eval) | Indexed click/type actions selected by the LLM | Free-form Python (writes Playwright scripts itself) |
| What is "state"? | The browser session | The browser session (held by daemon across CLI calls) | The browser session | The local workspace — code, screenshots, logs. Browser is disposable. |
| Loop shape | Imperative; agent() does multi-step when needed | One CLI invocation per micro-step | observe → predict next action → execute → repeat | write code → execute → inspect screenshots → repair (code-as-action) |
CUAWright demo
https://github.com/user-attachments/assets/2063be64-4d0a-40a2-9d1f-7906be43f2c9
CUAWright beats the same model running in a different harness on every benchmark below, from desktop and CAD to long-horizon web tasks. See the paper for full details.
CUAWright/
├── pyproject.toml                      # package, dependency extras, CLI commands
├── setup.py                            # desktop provenance in wheels and source archives
├── src/
│   ├── cuawright/
│   │   ├── core/                       # shared API helpers
│   │   ├── webwright/                  # browser runtime
│   │   │   ├── agents/                 # browser agent loop
│   │   │   ├── environments/           # browser and terminal workspaces
│   │   │   ├── models/                 # OpenAI, Anthropic, OpenRouter backends
│   │   │   ├── tools/                  # browser sessions, images, self-reflection
│   │   │   ├── config/                 # stackable browser YAML configs
│   │   │   ├── run/                    # cuawright-web CLI and doctor
│   │   │   └── utils/                  # evidence, logging, serialization
│   │   └── desktop/                    # persistent desktop runtime
│   │       ├── agents/                 # desktop agent loop and call budget
│   │       ├── environments/osworld/   # VM commands, screenshots, and submission
│   │       ├── models/                 # standard Responses API transport and tools
│   │       ├── config/prompts.py       # desktop prompts
│   │       ├── setup.py                # pinned OSWorld setup and verification
│   │       ├── run/cli.py              # custom and official desktop workflows
│   │       ├── run/benchmarks/          # official task setup and evaluation
│   │       └── utils/                  # artifacts and provenance
│   └── webwright/__init__.py           # legacy Python import compatibility
├── extensions/skill-factory/           # optional cuawright-skill-factory distribution
│   ├── pyproject.toml                  # separate wheel; depends on the base package
│   └── src/cuawright/webwright/        # skill_factory/ and tools/skill_use.py
├── skills/cuawright-web/               # browser skill, commands, reference guides
├── .claude-plugin/                     # Claude Code plugin and marketplace manifests
├── .codex-plugin/                      # Codex plugin manifest
├── docs/                               # desktop setup and Skill Factory guides
├── tests/                              # browser, Skill Factory, compatibility tests
├── release/osworld/tests/              # desktop request, lifecycle, privacy tests
├── .github/workflows/                  # runtime and Skill Factory CI
├── assets/                             # showcase, trajectory viewer, figures, logos
├── LICENSE                             # MIT browser license
├── licenses/                           # Apache-2.0 desktop runtime license
└── NOTICE                              # imported runtime attribution
Webwright lets a coding model launch browsers, inspect pages, and debug its work from a terminal. Script-based runs produce a reusable Python script. Live-browser mode keeps a page open across steps and returns an answer without creating a script.
pip install -e .
playwright install chromium
Export credentials for the configured backend (for example, OPENAI_API_KEY
with model_openai.yaml or ANTHROPIC_API_KEY with model_claude.yaml). Then:
python -m cuawright.webwright.run.cli main \
    -c base.yaml -c model_openai.yaml \
    -t "Report the page title and the destination of its main link." \
    --start-url https://example.com \
    --task-id demo_openai \
    -o outputs/default
The image_qa and self_reflection tools use the run's configured model.
When running a tool separately, pass --model-config with an absolute path to a
private YAML file containing your model: settings. Keep that file outside the
checkout and results directory.
For incremental browsing with native OpenAI run_command tool calls, use:
cuawright-web main -c best_default_judge_json_persistent_cli.yaml -c model_openai.yaml \
  -t "<task>" --start-url "<url>" --task-id example -o outputs/example
This config keeps a Browserbase cloud session across commands. Set
OPENAI_API_KEY, BROWSERBASE_API_KEY, and BROWSERBASE_PROJECT_ID before running.
The agent runs shell commands, inspects the results, and checks its work before
finishing. See the browser workflow guide for image reading and
trajectory verification.
| Flag | Description |
|---|---|
-c | Config file(s) from src/cuawright/webwright/config/ (stackable). |
-t | Task instruction. |
--start-url | Initial page. |
--task-id | Output subfolder name. |
-o | Output directory. |
cuawright desktop runs tasks in an OSWorld-V2 Ubuntu VM. The agent uses a
terminal to inspect applications, run commands, view screenshots, and save its work.
You can give it your own task or run an official benchmark task with a score.
pip install -e ".[desktop]"
Before setup, accept access to the tasks and assets on Hugging Face, then log in:
pip install huggingface_hub
hf auth login
cuawright setup osworld --root ~/.cache/cuawright/osworld-v2-2026.08.08
cuawright verify osworld \
  --setup ~/.cache/cuawright/osworld-v2-2026.08.08/setup.json
Setup downloads the pinned source, task classes, assets, and VM by default; existing
resources can be registered without copying. Put the API key in a
user-owned file with mode 0600, outside source, task, asset, and result directories.
Choose a new result directory whose parent already exists.
cuawright desktop run \
  --setup /absolute/path/to/setup.json \
  --credentials /absolute/path/to/api-key \
  --results /absolute/path/to/results/custom \
  --model YOUR_MODEL \
  --instruction "<task>"
This workflow has no evaluator or score. For an official scored task:
cuawright desktop reproduce osworld \
  --setup /absolute/path/to/setup.json \
  --credentials /absolute/path/to/api-key \
  --results /absolute/path/to/results/task-001 \
  --task-id 001 --model YOUR_MODEL --reasoning xhigh
For another Responses-compatible provider, pass its full API URL with
--responses-url. See task selection and proxies
for official task IDs and --proxy-config setup.
Each run saves its settings in manifest.json, the agent's actions in trace.jsonl,
and the outcome in result.json. Images viewed by the agent are embedded in the
trace; desktop runs do not export separate screenshot files. Official benchmark
runs also include the evaluator score. Files created in the VM are not automatically
copied to the host; see custom tasks.
See REPRODUCE.md for setup, smoke tests, and reproduction commands,
or desktop setup and execution for more detail.
CUAWright ships plugin manifests for both Claude Code (.claude-plugin/plugin.json) and OpenAI Codex (.codex-plugin/plugin.json), with the shared skill at skills/cuawright-web/ and slash commands at skills/cuawright-web/commands/. The host agent drives the Webwright loop natively — no extra LLM API key or cost beyond your host subscription. Hosts that read PNG screenshots natively skip the image_qa / self_reflection tools.
The bundled cuawright-web skill handles browser tasks. Desktop tasks use
cuawright-desktop; see desktop setup.
Common runtime deps (install once after either path):
pip install -e .
playwright install chromium
Install through the bundled marketplace inside Claude Code:
# 1. Add this repo as a Claude Code plugin marketplace
/plugin marketplace add microsoft/Webwright

# 2. Install the plugin from that marketplace
/plugin install cuawright@cuawright
Prefer a local checkout? Point the marketplace command at the cloned repo instead:
/plugin marketplace add /absolute/path/to/Webwright
/plugin install cuawright@cuawright
Start a new Claude Code session after installing — plugins are loaded at session start and won't appear until you restart.
You can either ask Claude Code in plain English (the skill auto-activates from its description), or use one of the slash commands:
/cuawright:run search Google Flights for flights from SEA to JFK on 2026-08-15 to 2026-08-20
/cuawright:craft search a ticket on Google Flights from LAX to SFO depart June 7 return June 14
/cuawright:run (or any plain prompt) produces a one-shot final_script.py for the literal task values./cuawright:craft produces a reusable CLI tool: final_script.py becomes one parameterized function with a Google-style Args: docstring and an argparse wrapper whose flags default to the concrete task values, so you can rerun it later with different arguments — e.g. python final_script.py --origin JFK --destination LAX --depart-date 2026-07-01.In both modes Claude Code scaffolds a workspace with plan.md, runs instrumented Playwright scripts under final_runs/run_<id>/, and visually self-verifies each critical point against the saved screenshots.
Codex reads Claude-style marketplaces, so the same repo works as a Codex plugin marketplace. From the Codex CLI:
# 1. Add this repo as a Codex plugin marketplace
codex plugin marketplace add microsoft/Webwright

# 2. Open the plugin browser and install CUAWright
codex
/plugins
Prefer a local checkout?
codex plugin marketplace add /absolute/path/to/Webwright
Then restart Codex so the new marketplace and plugin are picked up.
In a new Codex thread, either ask in plain English (the skill auto-activates from its description) or invoke the bundled skill explicitly with @cuawright-web:
@cuawright-web search Google Flights for flights from SEA to JFK on 2026-08-15 to 2026-08-20
Codex scaffolds a workspace with plan.md, runs instrumented Playwright scripts under final_runs/run_<id>/, and visually self-verifies each critical point against the saved screenshots.
To turn the plugin off without uninstalling, set its entry in ~/.codex/config.toml to enabled = false and restart Codex.
Hermes Agent is a skills-compatible client, so the same skills/cuawright-web/ folder loads as a Hermes skill. Symlink it into your Hermes user-skills directory:
mkdir -p ~/.hermes/skills
ln -sfn /absolute/path/to/Webwright/skills/cuawright-web ~/.hermes/skills/cuawright-web
No Hermes-specific manifest is needed; only SKILL.md is loaded.
Start Hermes (hermes) and ask it to drive a web task in natural language — the skill auto-activates from its description. You can also invoke it explicitly with /cuawright-web.
Note: the named subcommands shipped under skills/cuawright-web/commands/ (/cuawright:run, /cuawright:craft) are a Claude Code / Codex convention and are inert in Hermes; the skill itself still works end-to-end.
A tiny Flask app under assets/task_showcase/ consolidates
Webwright runs for repeatable odyssey tasks (deals, inventory, listings,
job boards, weather, etc.) into a single dashboard. Each task ships only two
files — task.json (metadata) and report.json (curated, structured output:
sources + result sections like tables, lists, summaries) — and the templates
render them generically, so adding a new task is just dropping a new folder
in assets/task_showcase/tasks/.
pip install flask
python assets/task_showcase/app.py    # http://127.0.0.1:5005
To have Webwright produce a renderer-ready task folder at runtime, stack the Task Showcase overlay:
python -m cuawright.webwright.run.cli main \
    -c base.yaml -c model_openai.yaml -c task_showcase.yaml \
    -t "<repeatable web task>" \
    --task-id my_repeatable_task \
    -o outputs/default
Note:
report.jsonis only generated when-c task_showcase.yamlis included. A plainbase.yamlrun producestrajectory.jsonand debug artifacts but noreport.json.
The run writes task_showcase/tasks/<short_id>/task.json and report.json
inside the output workspace. Render those generated files without copying them
back into the repo:
python assets/task_showcase/app.py \
    --tasks-dir outputs/default/<run>/task_showcase/tasks
Skill Factory is an optional extension for learning and reusing browser automation scripts. Install it from this checkout:
pip install -e ".[skill-factory]" -e extensions/skill-factory
cuawright-skill-factory --help
For desktop execution and Skill Factory together, use
pip install -e ".[desktop,skill-factory]" -e extensions/skill-factory.
Most agent skills are context the model reads. Ours are programs.
cuawright.webwright.skill_factory distills the script every solve leaves
behind into a growing library of reusable, verified, parameterized skills — code you can run
without a model and compose into the next task instead of re-exploring the site. Plugs in with
no change to the agent loop:
recommend):
route either runs a matching skill directly (no model) or injects it into the prompt as a prior
({verdict: run|adapt|skip, skill_id, source_path}); the agent reuses the hint without ever
querying the library itself.python -m cuawright.webwright.skill_factory learn outputs/ --library ./library
groups solves of the same template and distills one parameterized skill (build does solve→learn
in one shot; update is manual-manifest mode).Before adding a skill, the input gate compares the result with gold answers when available. Otherwise it checks the output's shape and the agent's reported success; this fallback can admit an incorrect answer. The generated script is then replayed without a model, and updates are checked against previous examples.
Once learned, a skill runs standalone in ~40 s with zero tokens. On WebArena (10 retrieve-type
templates, 3 self-hosted sites, gpt-5.4) reuse lifts held-out accuracy 55% → 70% (+15 pp) while
cutting steps. See extensions/skill-factory/src/cuawright/webwright/skill_factory/README.md.
You can run the same tasks using the Webwright harness and its Codex / GitHub Copilot skill variant, and see how token usage and trajectories stack up between different harnesses. The trajectory viewer supports Codex, GitHub Copilot and Webwright harness traces.
cd assets/compare_trajectory/
python3 -m http.server
Open the webpage in your browser and upload the Webwright raw_responses.jsonl and attach trajectory.json to view. Then on the other side you can upload your Codex or GitHub Copilot trace.
ls ~/.codex/sessions/2026/MONTH/DAY/SESSION_ID.jsonl
/export file session
-> session.md is the uploadable trace
| Tokens | Webwright Harness (Local Browser Mode) | Codex Webwright Skill |
|---|---|---|
| Input | 420,433 | 3,271,143 |
| Output | 3,593 | 20,040 |
| Reasoning | 0 | 4,410 |
| Cached | 217,216 | — |
| Total | 424,026 | 3,291,183 |
The Codex cached-token count is omitted because the recorded figure needs verification. Individual runs and results may vary.
If you use CUAWright or Webwright in your research or build on it, please cite:
@misc{lu2026cuawright,
  title         = {CUAWright: A Minimal Unified Interface for Digital Agents},
  author        = {Lu, Yadong and Lee, Theodore and Li, Yifei and Jang, Lawrence Keunho and Xue, Tianci and Su, Yu and Sun, Huan and Awadallah, Ahmed Hassan},
  year          = {2026},
  eprint        = {2610.04116},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  url           = {https://arxiv.org/abs/2610.04116}
}

@misc{webwright2026,
  title        = {Webwright: A terminal is all you need for web agents},
  author       = {Lu, Yadong and Xu, Lingrui and Huang, Chao and Awadallah, Ahmed},
  year         = {2026},
  howpublished = {\url{https://github.com/microsoft/Webwright}},
  note         = {GitHub repository}
}
(top 24 of 40)
53,255 followers · starred May 2026
53,255 followers · starred May 2026
2,241 followers · starred May 2026
102 followers · starred May 2026