
Implementation of 🥥 Coconut, Chain of Continuous Thought, in Pytorch
Python
185
45 commits
updated Jun 20, 2025
README
🥥 Coconut
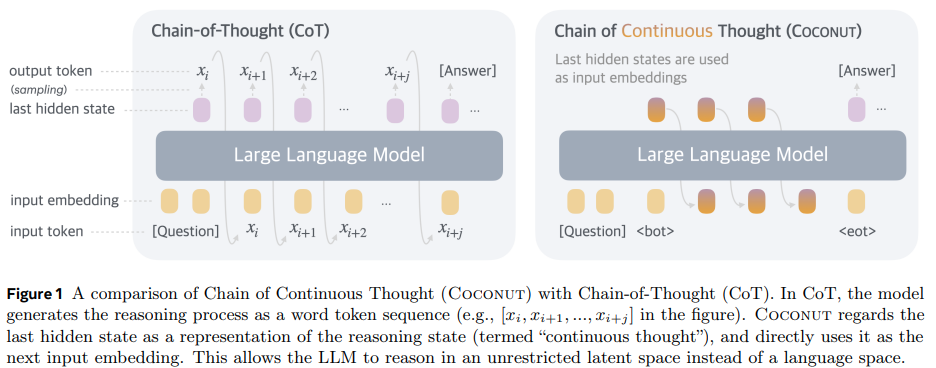
Implementation of Coconut, proposed by the paper Training Large Language Models to Reason in a Continuous Latent Space out of FAIR, in Pytorch
Architecture wise, the closest work to the one proposed here would be RMT, where the memory tokens there could serve as the continuous latent tokens. Both directions are worth exploring
Install
$ pip install coconut-pytorch
Usage
import torch
from coconut_pytorch import Coconut

model = Coconut(
    num_reasoning_steps = 3,
    num_latents_per_step = 1,
    transformer = dict(
        num_tokens = 256,
        dim = 512,
        depth = 6
    )
)

prompt = torch.randint(0, 256, (2, 1024))
answer = torch.randint(0, 256, (2, 64))

loss = model(prompt, answer)
loss.backward()

# after much training

answer = model.generate(prompt, max_length = 64) # (2, 64)
Citation
@inproceedings{Hao2024TrainingLL,
    title   = {Training Large Language Models to Reason in a Continuous Latent Space},
    author  = {Shibo Hao and Sainbayar Sukhbaatar and DiJia Su and Xian Li and Zhiting Hu and Jason Weston and Yuandong Tian},
    year    = {2024},
    url     = {https://api.semanticscholar.org/CorpusID:274610816}
}
@article{Burtsev2021MultiStreamT,
    title   = {Multi-Stream Transformers},
    author  = {Mikhail S. Burtsev and Anna Rumshisky},
    journal = {ArXiv},
    year    = {2021},
    volume  = {abs/2107.10342},
    url     = {https://api.semanticscholar.org/CorpusID:236171087}
}
@article{Zhu2024HyperConnections,
    title   = {Hyper-Connections},
    author  = {Defa Zhu and Hongzhi Huang and Zihao Huang and Yutao Zeng and Yunyao Mao and Banggu Wu and Qiyang Min and Xun Zhou},
    journal = {ArXiv},
    year    = {2024},
    volume  = {abs/2409.19606},
    url     = {https://api.semanticscholar.org/CorpusID:272987528}
}
@inproceedings{Zhou2024ValueRL,
    title   = {Value Residual Learning For Alleviating Attention Concentration In Transformers},
    author  = {Zhanchao Zhou and Tianyi Wu and Zhiyun Jiang and Zhenzhong Lan},
    year    = {2024},
    url     = {https://api.semanticscholar.org/CorpusID:273532030}
}
@inproceedings{Zhu2025ReasoningBS,
    title     = {Reasoning by Superposition: A Theoretical Perspective on Chain of Continuous Thought},
    author    = {Hanlin Zhu and Shibo Hao and Zhiting Hu and Jiantao Jiao and Stuart Russell and Yuandong Tian},
    year      = {2025},
    url       = {https://api.semanticscholar.org/CorpusID:278740606}
}
Significant stargazers

40 followers · starred Apr 2025
Similar repos

Languages
Python
100.0%
Implementation of 🥥 Coconut, Chain of Continuous Thought, in Pytorch
Python
185
45 commits
updated Jun 20, 2025
README
🥥 Coconut
Implementation of Coconut, proposed by the paper Training Large Language Models to Reason in a Continuous Latent Space out of FAIR, in Pytorch
Architecture wise, the closest work to the one proposed here would be RMT, where the memory tokens there could serve as the continuous latent tokens. Both directions are worth exploring
Install
$ pip install coconut-pytorch
Usage
import torch
from coconut_pytorch import Coconut

model = Coconut(
    num_reasoning_steps = 3,
    num_latents_per_step = 1,
    transformer = dict(
        num_tokens = 256,
        dim = 512,
        depth = 6
    )
)

prompt = torch.randint(0, 256, (2, 1024))
answer = torch.randint(0, 256, (2, 64))

loss = model(prompt, answer)
loss.backward()

# after much training

answer = model.generate(prompt, max_length = 64) # (2, 64)
Citation
@inproceedings{Hao2024TrainingLL,
    title   = {Training Large Language Models to Reason in a Continuous Latent Space},
    author  = {Shibo Hao and Sainbayar Sukhbaatar and DiJia Su and Xian Li and Zhiting Hu and Jason Weston and Yuandong Tian},
    year    = {2024},
    url     = {https://api.semanticscholar.org/CorpusID:274610816}
}
@article{Burtsev2021MultiStreamT,
    title   = {Multi-Stream Transformers},
    author  = {Mikhail S. Burtsev and Anna Rumshisky},
    journal = {ArXiv},
    year    = {2021},
    volume  = {abs/2107.10342},
    url     = {https://api.semanticscholar.org/CorpusID:236171087}
}
@article{Zhu2024HyperConnections,
    title   = {Hyper-Connections},
    author  = {Defa Zhu and Hongzhi Huang and Zihao Huang and Yutao Zeng and Yunyao Mao and Banggu Wu and Qiyang Min and Xun Zhou},
    journal = {ArXiv},
    year    = {2024},
    volume  = {abs/2409.19606},
    url     = {https://api.semanticscholar.org/CorpusID:272987528}
}
@inproceedings{Zhou2024ValueRL,
    title   = {Value Residual Learning For Alleviating Attention Concentration In Transformers},
    author  = {Zhanchao Zhou and Tianyi Wu and Zhiyun Jiang and Zhenzhong Lan},
    year    = {2024},
    url     = {https://api.semanticscholar.org/CorpusID:273532030}
}
@inproceedings{Zhu2025ReasoningBS,
    title     = {Reasoning by Superposition: A Theoretical Perspective on Chain of Continuous Thought},
    author    = {Hanlin Zhu and Shibo Hao and Zhiting Hu and Jiantao Jiao and Stuart Russell and Yuandong Tian},
    year      = {2025},
    url       = {https://api.semanticscholar.org/CorpusID:278740606}
}
Similar repos
Significant stargazers
40 followers · starred Apr 2025
Languages
Python
100.0%