
Implementation of the proposed DeepCrossAttention by Heddes et al at Google research, in Pytorch
Python
107
22 commits
updated Apr 3, 2026
README
Deep Cross Attention
Implementation of the proposed DeepCrossAttention by Mike Heddes while at Google research, in Pytorch
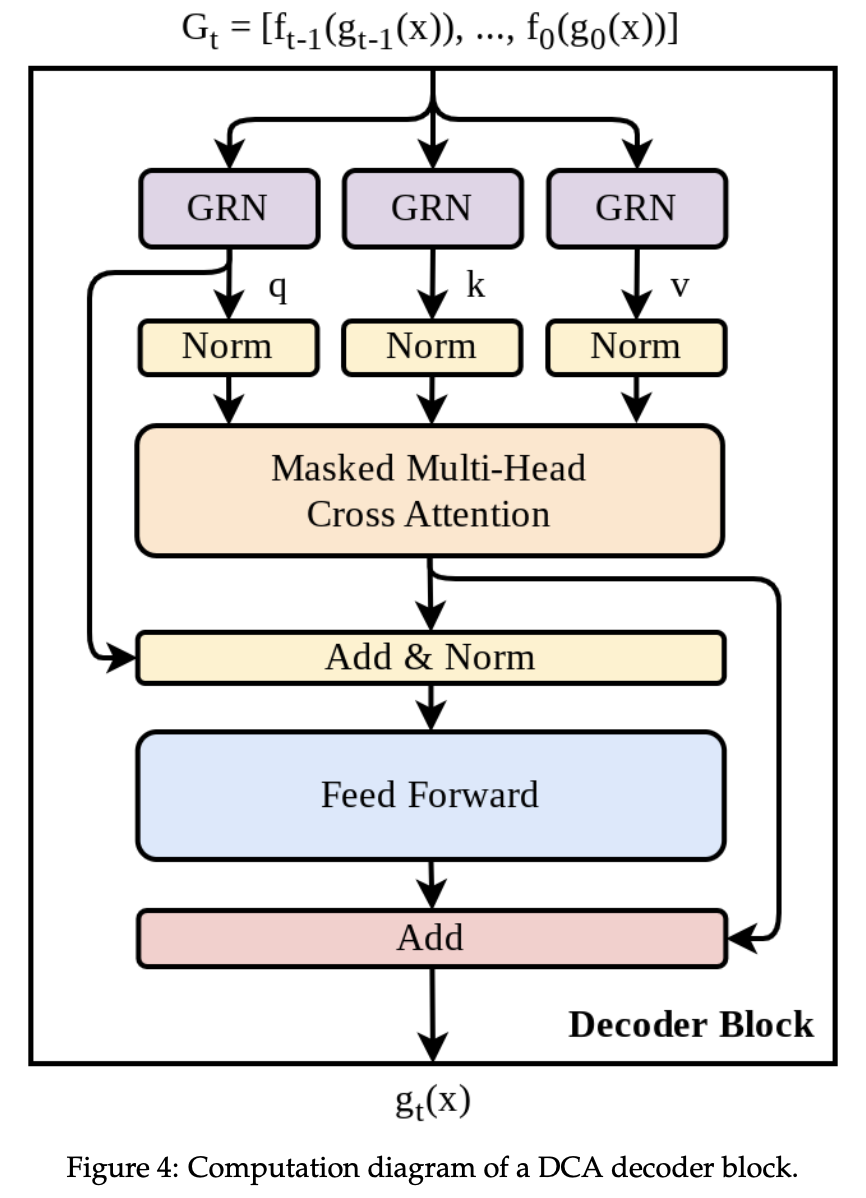
My analysis is although I still prefer Hyper Connections, they have an important idea here that I have been trying concurrently. Mainly the queries, keys, values can be routed from different layers of the past. The reason this is cool is because it generalizes the recent value residual learning improvement. It may (or may not) also address an issue for neural memories
Appreciation
- Minh Hoang for spotting some issues with the GRN
Install
$ pip install deep-cross-attention
Usage
import torch
from deep_cross_attention import DCAGPT

gpt = DCAGPT(
    num_tokens = 256,
    dim = 512,
    depth = 6,
    heads = 8,
    dim_head = 64,
    past_layers_k = 2
)

ids = torch.randint(0, 256, (2, 4096))

logits = gpt(ids) # (2, 4096, 256)
Example
First
$ pip install .[examples]
Next
$ python train.py
Citations
@inproceedings{Heddes2025DeepCrossAttentionST,
    title   = {DeepCrossAttention: Supercharging Transformer Residual Connections},
    author  = {Mike Heddes and Adel Javanmard and Kyriakos Axiotis and Gang Fu and MohammadHossein Bateni and Vahab S. Mirrokni},
    year    = {2025},
    url     = {https://api.semanticscholar.org/CorpusID:276250576}
}
Contributors

20 commits

2 commits
Similar repos


Languages
Python
100.0%
Implementation of the proposed DeepCrossAttention by Heddes et al at Google research, in Pytorch
Python
107
22 commits
updated Apr 3, 2026
README
Deep Cross Attention
Implementation of the proposed DeepCrossAttention by Mike Heddes while at Google research, in Pytorch
My analysis is although I still prefer Hyper Connections, they have an important idea here that I have been trying concurrently. Mainly the queries, keys, values can be routed from different layers of the past. The reason this is cool is because it generalizes the recent value residual learning improvement. It may (or may not) also address an issue for neural memories
Appreciation
- Minh Hoang for spotting some issues with the GRN
Install
$ pip install deep-cross-attention
Usage
import torch
from deep_cross_attention import DCAGPT

gpt = DCAGPT(
    num_tokens = 256,
    dim = 512,
    depth = 6,
    heads = 8,
    dim_head = 64,
    past_layers_k = 2
)

ids = torch.randint(0, 256, (2, 4096))

logits = gpt(ids) # (2, 4096, 256)
Example
First
$ pip install .[examples]
Next
$ python train.py
Citations
@inproceedings{Heddes2025DeepCrossAttentionST,
    title   = {DeepCrossAttention: Supercharging Transformer Residual Connections},
    author  = {Mike Heddes and Adel Javanmard and Kyriakos Axiotis and Gang Fu and MohammadHossein Bateni and Vahab S. Mirrokni},
    year    = {2025},
    url     = {https://api.semanticscholar.org/CorpusID:276250576}
}
Similar repos
Contributors
20 commits
2 commits
Languages
Python
100.0%