
Latest open-source "Thinking with images" (O3/O4-mini) papers, covering training-free, SFT-based, and RL-enhanced methods for "fine-grained visual understanding".
114
15 commits
updated Aug 21, 2025
README
Awesome-Thinking-With-Images
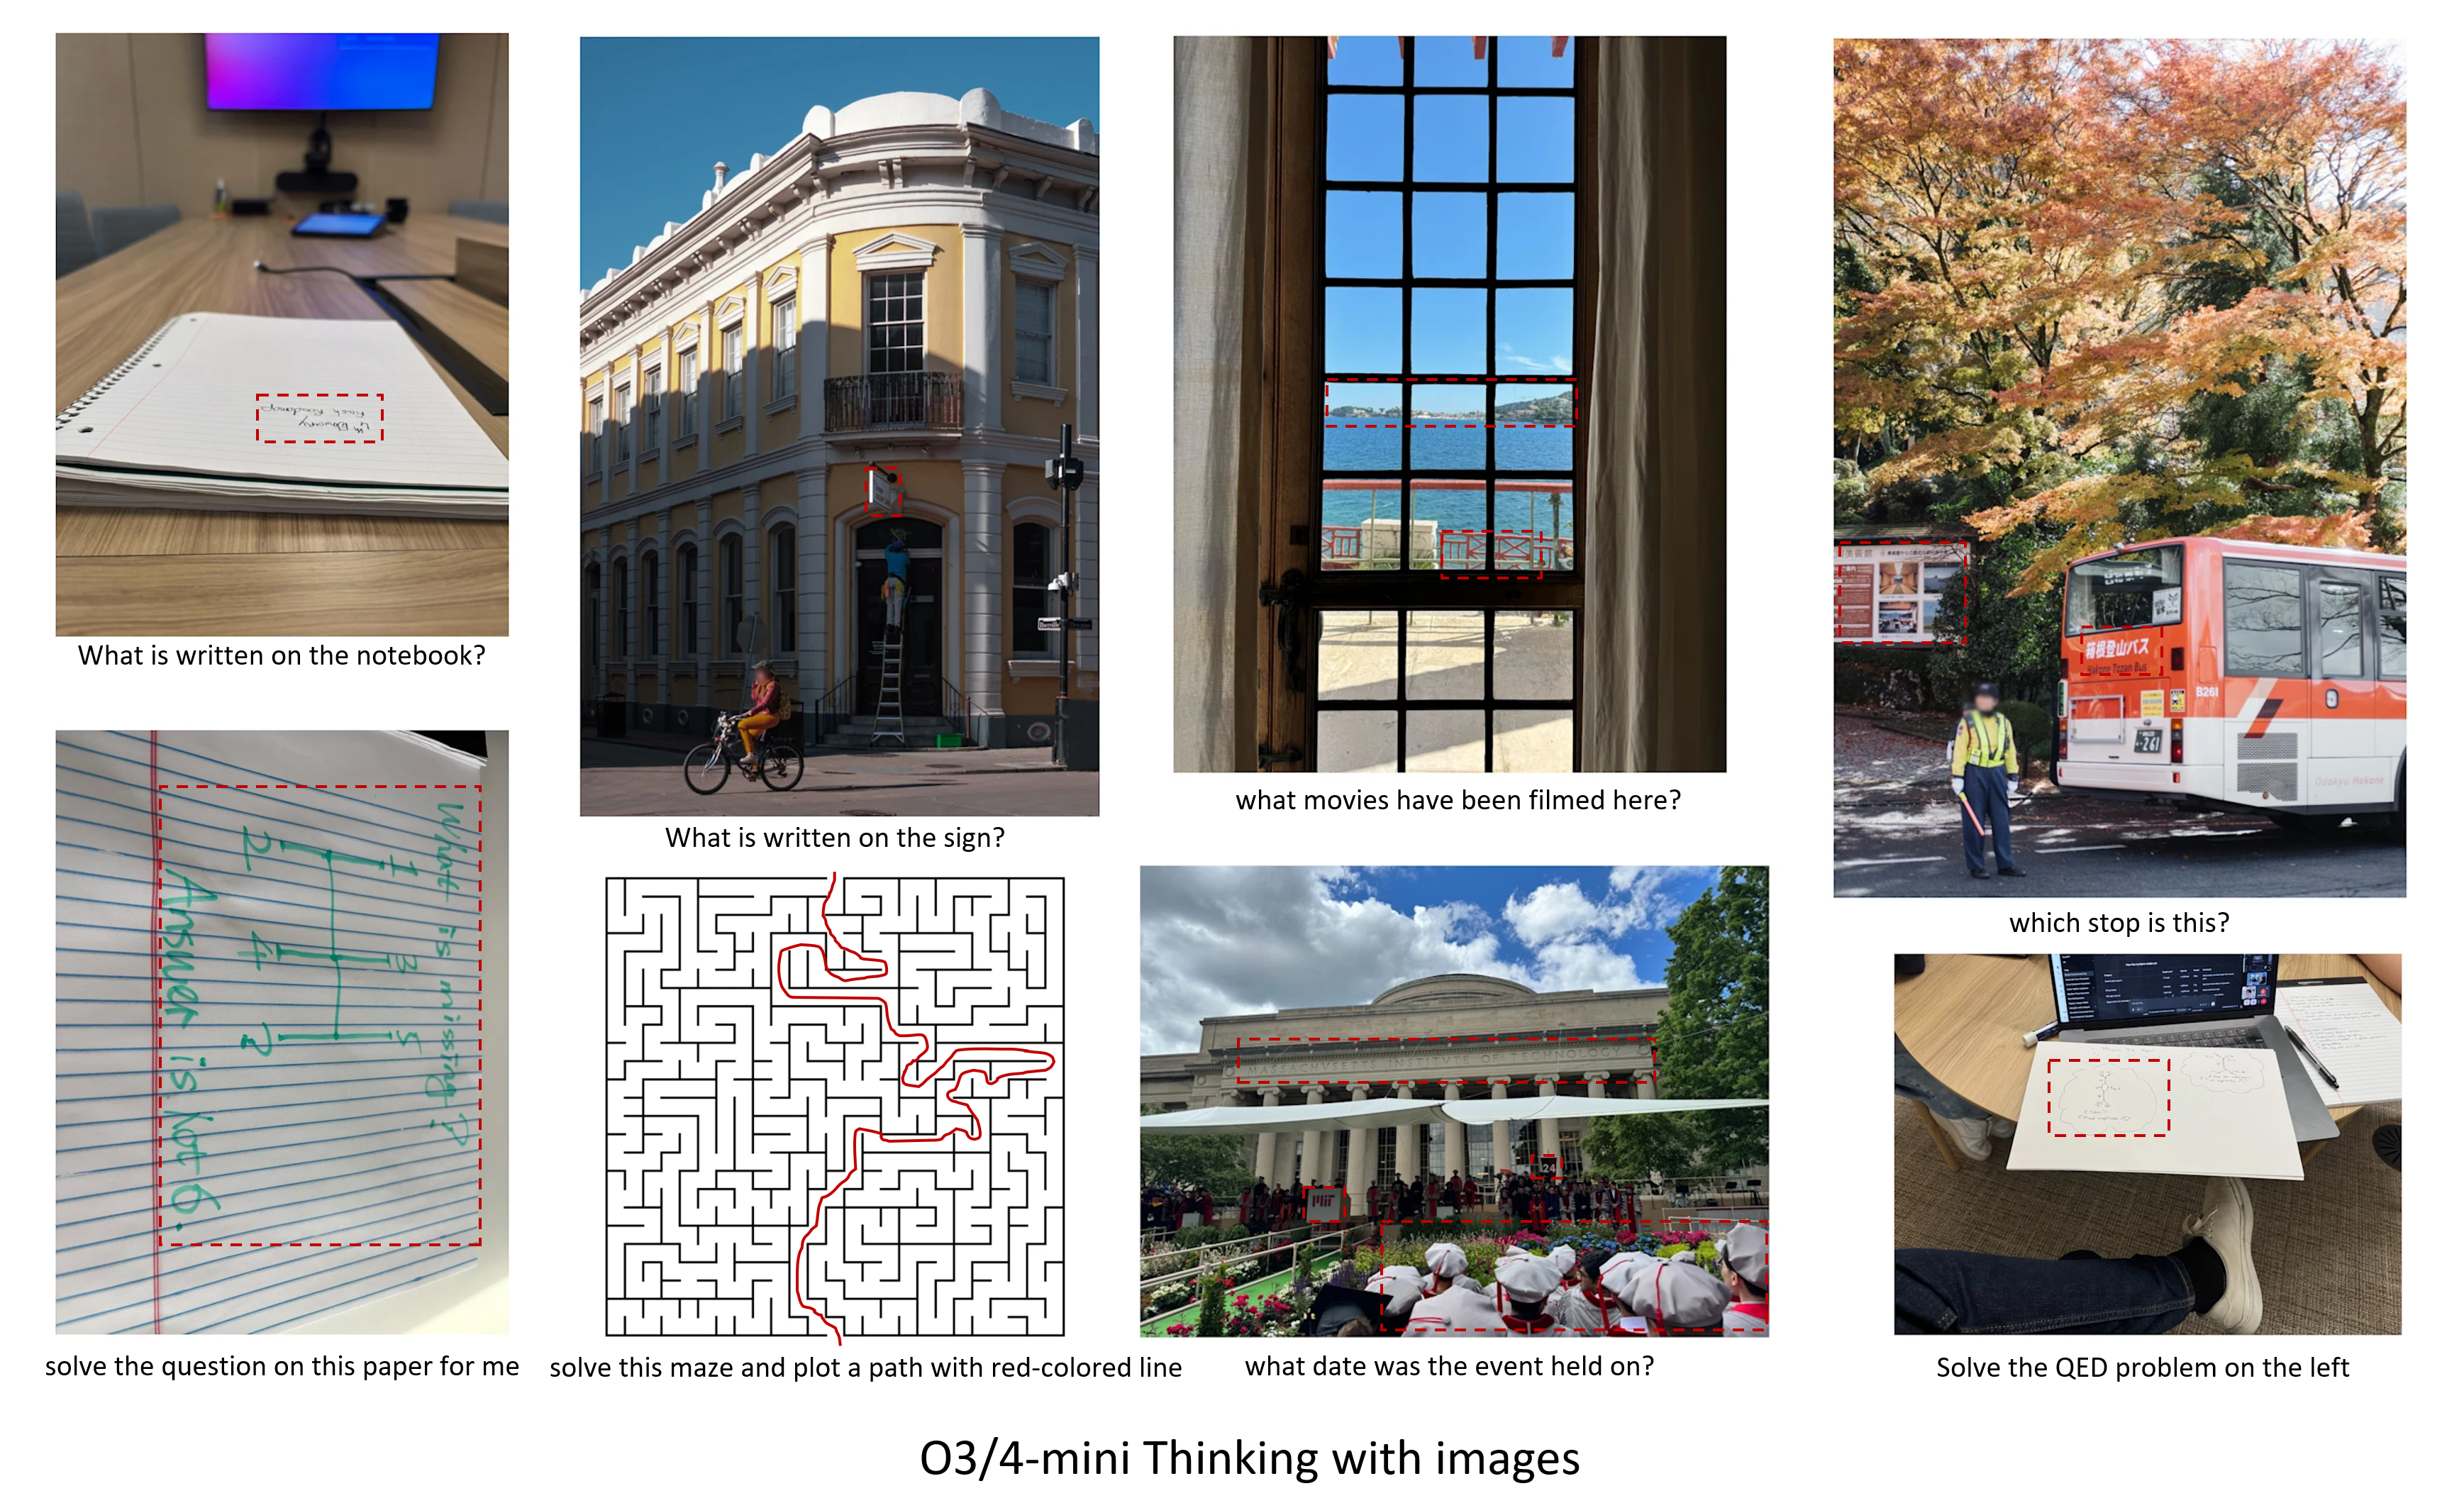
A curated list of research methods and datasets exploring image thinking — the ability to perform reasoning with images. We focus particularly on methods and benchmarks designed for fine-grained visual understanding tasks, which refers to problems with Dense, Cluttered, Complex Visual Input, but only Tiny, Subtle, Ambiguous Visual Regions Subsets are useful for answering.
This includes:
- Multimodal reasoning with visual context
- Visual chain-of-thought prompting
- Dynamic visual attention / focus adjustment
- Vision-language models with interpretable intermediate states
Feel free to contribute! Pull requests and issues recommendation are welcome.
📚 Awesome Papers
🔹 Training-Free / No-Training Methods


🔹 Supervised Fine-tuning Methods
| Paper | Venue | Date | Resources |
|---|---|---|---|
 Simple o3: Towards Interleaved Vision-Language Reasoning | arXiv | 2025-08 | N/A |
| Enhancing Spatial Reasoning through Visual and Textual Thinking | arXiv | 2025-07 | N/A |
 Understand, Think, and Answer: Advancing Visual Reasoning with Large Multimodal Models | arXiv | 2025-05 | GitHub |
 Visual Agents as Fast and Slow Thinkers | ICLR | 2024-08 | GitHub |
 From the Least to the Most: Building a Plug-and-Play Visual Reasoner via Data Synthesis | arXiv | 2024-06 | GitHub |
 Instruction-Guided Visual Masking | NeurIPS | 2024-05 | GitHub |
 COGCOM: A VISUAL LANGUAGE MODEL WITH CHAIN-OF-MANIPULATIONS REASONING | arXiv | 2024-02 | GitHub |
 V*: Guided Visual Search as a Core Mechanism in Multimodal LLMs | CVPR | 2023-12 | GitHub |
🔹 RL-Enhanced Methods



🔹 SFT-RL Hybrid Methods
| Paper | Venue | Date | Resources |
|---|---|---|---|
 Thyme: Think Beyond Images | arXiv | 2025-08 | GitHub |
🎯 Domain Application
🏥 Medical Domain
| Paper | Venue | Date | Resources |
|---|---|---|---|
| GEMeX-ThinkVG: Towards Thinking with Visual Grounding in Medical VQA via Reinforcement Learning | arXiv | 2025-06 | HuggingFace |
🤖 GUI Robot
| Paper | Venue | Date | Resources |
|---|---|---|---|
 UI-AGILE: Advancing GUI Agents with Effective Reinforcement Learning and Precise Inference-Time Grounding | arXiv | 2025-07 | GitHub |
🧪 Benchmarks & Datasets
| Dataset | Task | Resources |
|---|---|---|
| V* | Attribute Recognition & Spatial Reasoning | HuggingFace |
| HR-Bench | Fine-grained Single/Cross-instance Perception | HuggingFace |
| MME-RealWorld | High-Resolution Real-World Scenarios | HuggingFace |
| TreeBench | Visual Grounded Reasoning | GitHub |
| OCR-Reasoning | Text-Rich Image Reasoning | GitHub |
🤝 Contributing
If you know any relevant papers, datasets, or demos, feel free to submit a pull request or leava an issue!
🔍 Related Lists
- Awesome Multimodal LLMs
- Awesome Think with Images for LVLMs (A broader list covering more than just fine-grained visual understanding)
Contributors

15 commits
Similar repos


Latest open-source "Thinking with images" (O3/O4-mini) papers, covering training-free, SFT-based, and RL-enhanced methods for "fine-grained visual understanding".
114
15 commits
updated Aug 21, 2025
README
Awesome-Thinking-With-Images
A curated list of research methods and datasets exploring image thinking — the ability to perform reasoning with images. We focus particularly on methods and benchmarks designed for fine-grained visual understanding tasks, which refers to problems with Dense, Cluttered, Complex Visual Input, but only Tiny, Subtle, Ambiguous Visual Regions Subsets are useful for answering.
This includes:
- Multimodal reasoning with visual context
- Visual chain-of-thought prompting
- Dynamic visual attention / focus adjustment
- Vision-language models with interpretable intermediate states
Feel free to contribute! Pull requests and issues recommendation are welcome.
📚 Awesome Papers
🔹 Training-Free / No-Training Methods
🔹 Supervised Fine-tuning Methods
| Paper | Venue | Date | Resources |
|---|---|---|---|
| Simple o3: Towards Interleaved Vision-Language Reasoning | arXiv | 2025-08 | N/A |
| Enhancing Spatial Reasoning through Visual and Textual Thinking | arXiv | 2025-07 | N/A |
| Understand, Think, and Answer: Advancing Visual Reasoning with Large Multimodal Models | arXiv | 2025-05 | GitHub |
| Visual Agents as Fast and Slow Thinkers | ICLR | 2024-08 | GitHub |
| From the Least to the Most: Building a Plug-and-Play Visual Reasoner via Data Synthesis | arXiv | 2024-06 | GitHub |
| Instruction-Guided Visual Masking | NeurIPS | 2024-05 | GitHub |
| COGCOM: A VISUAL LANGUAGE MODEL WITH CHAIN-OF-MANIPULATIONS REASONING | arXiv | 2024-02 | GitHub |
| V*: Guided Visual Search as a Core Mechanism in Multimodal LLMs | CVPR | 2023-12 | GitHub |
🔹 RL-Enhanced Methods
🔹 SFT-RL Hybrid Methods
| Paper | Venue | Date | Resources |
|---|---|---|---|
| Thyme: Think Beyond Images | arXiv | 2025-08 | GitHub |
🎯 Domain Application
🏥 Medical Domain
| Paper | Venue | Date | Resources |
|---|---|---|---|
| GEMeX-ThinkVG: Towards Thinking with Visual Grounding in Medical VQA via Reinforcement Learning | arXiv | 2025-06 | HuggingFace |
🤖 GUI Robot
| Paper | Venue | Date | Resources |
|---|---|---|---|
| UI-AGILE: Advancing GUI Agents with Effective Reinforcement Learning and Precise Inference-Time Grounding | arXiv | 2025-07 | GitHub |
🧪 Benchmarks & Datasets
| Dataset | Task | Resources |
|---|---|---|
| V* | Attribute Recognition & Spatial Reasoning | HuggingFace |
| HR-Bench | Fine-grained Single/Cross-instance Perception | HuggingFace |
| MME-RealWorld | High-Resolution Real-World Scenarios | HuggingFace |
| TreeBench | Visual Grounded Reasoning | GitHub |
| OCR-Reasoning | Text-Rich Image Reasoning | GitHub |
🤝 Contributing
If you know any relevant papers, datasets, or demos, feel free to submit a pull request or leava an issue!
🔍 Related Lists
- Awesome Multimodal LLMs
- Awesome Think with Images for LVLMs (A broader list covering more than just fine-grained visual understanding)
Similar repos
Contributors
15 commits