
README
Inference-Time Control for Trustworthy Large Language Models


We welcome everyone to open an issue for any related work we haven't covered, and we'll try to address it in the next release!
🎉 News
- [2026-05] 🔥 Paper available on preprints.org: https://www.preprints.org/manuscript/202605.1041
🎈 Citation
If you find this work helpful, please cite us:
@article{bai2026inferencetime,
  title     = {Inference-Time Control for Trustworthy Large Language Models},
  author    = {Bai, Yuyang and Liu, Zheyuan and Yan, Han and Xu, Zhangchen and Wan, Yixin and Chen, Canyu and Wang, Zehong and Yuan, Xiangchi and Huang, Yue and Dou, Guangyao and Zhang, Yuji and Zhu, Hangxiao and Li, Zhuofeng and Li, Manling and Zhang, Xiangliang and Bansal, Mohit and Koyejo, Sanmi and Chang, Kai-Wei and Zhang, Yu and Jiang, Meng},
  journal   = {Preprints},
  year      = {2026},
  month     = {May},
  publisher = {Preprints},
  doi       = {10.20944/preprints202605.1041.v1},
  url       = {https://doi.org/10.20944/preprints202605.1041.v1}
}
📖 Contents
🗺️ Overview
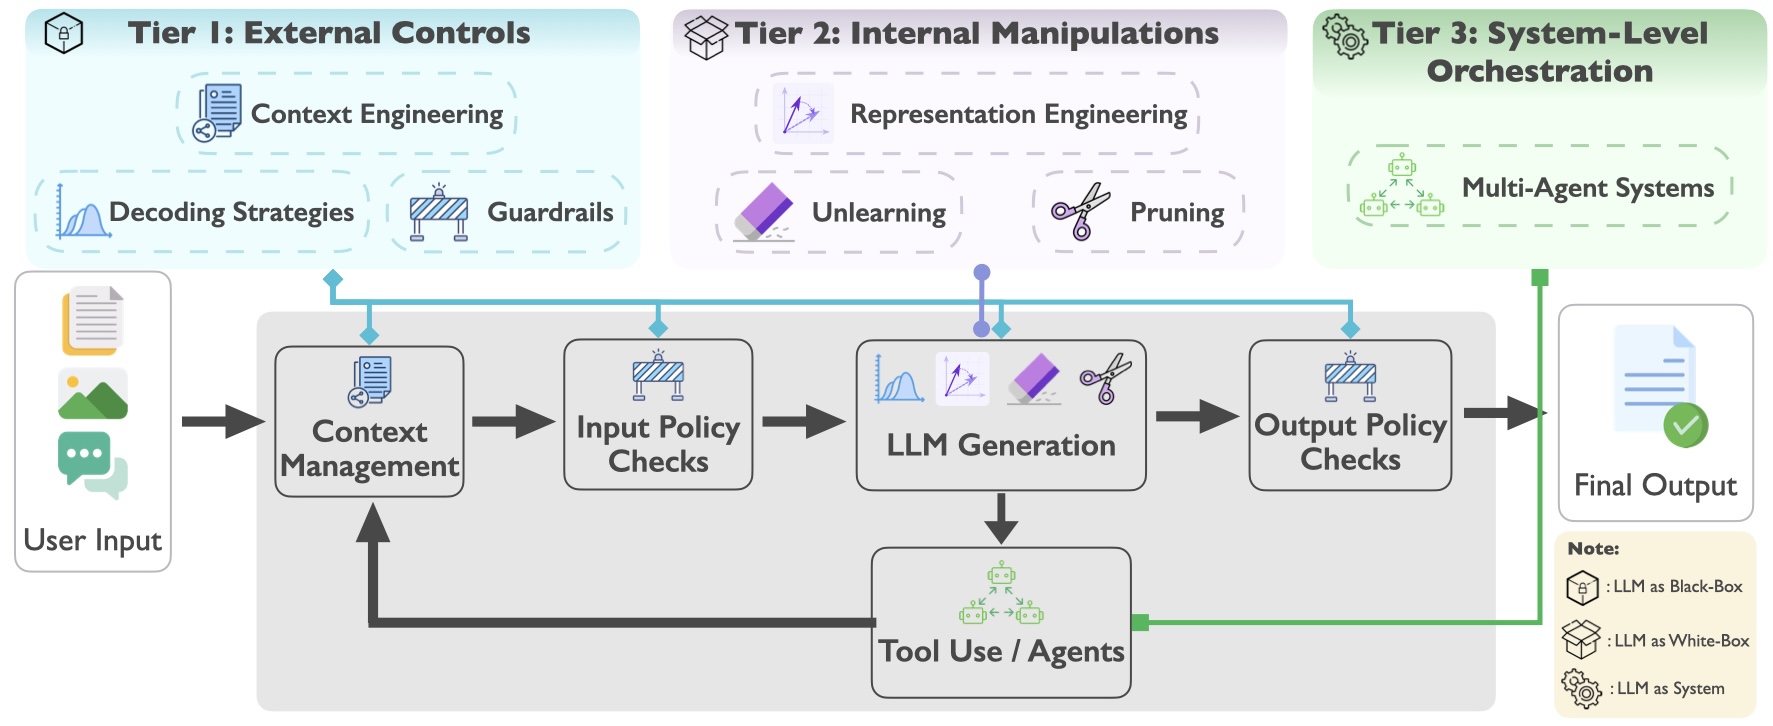
This work covers Inference-Time Control methods for building trustworthy LLMs, organized into three tiers:
-
Tier 1 — External Controls: Treat the model as a black box. Shape behavior by modifying inputs, decoding process, or outputs, without changing internal weights or activations.
- Context Engineering: Strategic prompt design through rules, instructions, or few-shot exemplars.
- Guardrails: External modules that inspect inputs/outputs against safety or policy constraints.
- Decoding Strategies: Manipulation of token-level distributions during generation.
-
Tier 2 — Internal Manipulations: Require white-box access. Intervene directly in the model's internal computation.
- Representation Engineering: Direct modification of internal activations via steering vectors.
- Unlearning: Targeted removal of information, behaviors, or biases from a pre-trained model.
- Pruning: Post-training removal of weights, neurons, or attention heads for trust-related effects.
-
Tier 3 — System-Level Orchestration: Coordinate multiple LLM agents through structured interaction patterns.
- Multi-Agent Systems: Coordinated agent interactions such as debate or cross-verification.
📄 Paper List
Tier 1: External Controls
Context Engineering
| Year | Title | Paper | Github |
|---|---|---|---|
| 2023.10 | Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection |  |  |
| 2023.09 | Defending Against Alignment-Breaking Attacks via Robustly Aligned LLM | |  |
| 2024.05 | Phantom: General Trigger Attacks on Retrieval Augmented Language Generation | | - |
| 2024.12 | Improving Factuality with Explicit Working Memory | | - |
| 2024.11 | SPICA: Retrieving Scenarios for Pluralistic In-Context Alignment | |  |
| 2023.07 | Queer People Are People First: Deconstructing Sexual Identity Stereotypes in Large Language Models | | - |
| 2023.09 | Chain-of-Verification Reduces Hallucination in Large Language Models | |  |
| 2023.12 | Breaking the Bias: Gender Fairness in LLMs Using Prompt Engineering and In-Context Learning | | - |
| 2025.02 | FACTER: Fairness-Aware Conformal Thresholding and Prompt Engineering for Enabling Fair LLM-Based Recommender Systems | |  |
| 2024.06 | Teaching LLMs to Abstain across Languages via Multilingual Feedback | |  |
| 2023.05 | Why So Gullible? Enhancing the Robustness of Retrieval-Augmented Models against Counterfactual Noise | |  |
| 2023.09 | Bias Testing and Mitigation in LLM-Based Code Generation | |  |
| 2024.02 | Defending Large Language Models Against Jailbreak Attacks via Semantic Smoothing | |  |
| 2024.04 | Prompting Techniques for Reducing Social Bias in LLMs through System 1 and System 2 Cognitive Processes | |  |
| 2023.09 | Certifying LLM Safety against Adversarial Prompting | |  |
| 2024.03 | Think Twice Before Trusting: Self-Detection for Large Language Models through Comprehensive Answer Reflection | | - |
| 2024.10 | SafetyAnalyst: Interpretable, Transparent, and Steerable Safety Moderation for AI Behavior | |  |
| 2022.10 | Measuring and Narrowing the Compositionality Gap in Language Models | |  |
| 2025.06 | Saffron-1: Towards an Inference Scaling Paradigm for LLM Safety Assurance | |  |
| 2023.01 | REPLUG: Retrieval-Augmented Black-Box Language Models | |  |
| 2024.03 | FairRAG: Fair Human Generation via Fair Retrieval Augmentation | | - |
| 2023.10 | InferDPT: Privacy-Preserving Inference for Black-Box Large Language Models | |  |
| 2024.02 | DELL: Generating Reactions and Explanations for LLM-Based Misinformation Detection | |  |
| 2023.06 | Augmenting Language Models with Long-Term Memory | |  |
| 2023.10 | Jailbreak and Guard Aligned Language Models with Only Few In-Context Demonstrations | | - |
| 2023.10 | Quantifying Privacy Risks of Prompts in Visual Prompt Learning | |  |
| 2022.09 | Generate rather than Retrieve: Large Language Models are Strong Context Generators | |  |
| 2023.10 | Poisoning Retrieval Corpora by Injecting Adversarial Passages | |  |
| 2023.03 | Context-Faithful Prompting for Large Language Models | |  |
| 2024.02 | Defending Jailbreak Prompts via In-Context Adversarial Game | |  |
| 2024.02 | Metacognitive Retrieval-Augmented Large Language Models | |  |
| 2024.02 | PoisonedRAG: Knowledge Corruption Attacks to Retrieval-Augmented Generation of Large Language Models | |  |
Guardrails
| Year | Title | Paper | Github |
|---|---|---|---|
| 2019.03 | Nuanced Metrics for Measuring Unintended Bias with Real Data for Text Classification | |  |
| 2025.05 | LlamaFirewall: An Open Source Guardrail System for Building Secure AI Agents | |  |
| 2024.11 | Llama Guard 3 Vision: Safeguarding Human-AI Image Understanding Conversations | | |
| 2017.03 | Automated Hate Speech Detection and the Problem of Offensive Language | |  |
| 2024.04 | AEGIS: Online Adaptive AI Content Safety Moderation with Ensemble of LLM Experts | | - |
| 2024.06 | WildGuard: Open One-Stop Moderation Tools for Safety Risks, Jailbreaks, and Refusals of LLMs | |  |
| 2025.02 | Bridging the Safety Gap: A Guardrail Pipeline for Trustworthy LLM Inferences | | - |
| 2022.03 | ToxiGen: A Large-Scale Machine-Generated Dataset for Adversarial and Implicit Hate Speech Detection | |  |
| 2023.12 | Llama Guard: LLM-based Input-Output Safeguard for Human-AI Conversations | |  |
| 2024.07 | POSTER: Identifying and Mitigating Vulnerabilities in LLM-Integrated Applications | | - |
| 2024.02 | ArtPrompt: ASCII Art-based Jailbreak Attacks against Aligned LLMs | |  |
| 2024.07 | R2-Guard: Robust Reasoning Enabled LLM Guardrail via Knowledge-Enhanced Logical Reasoning | |  |
| 2024.10 | Palisade — Prompt Injection Detection Framework | | - |
| 2025.04 | PolyGuard: A Multilingual Safety Moderation Tool for 17 Languages | |  |
| 2025.02 | SafeRoute: Adaptive Model Selection for Efficient and Accurate Safety Guardrails in Large Language Models | |  |
| 2022.02 | A New Generation of Perspective API: Efficient Multilingual Character-level Transformers | |  |
| 2025.01 | GuardReasoner: Towards Reasoning-based LLM Safeguards | |  |
| 2020.12 | HateXplain: A Benchmark Dataset for Explainable Hate Speech Detection | |  |
| 2024.12 | Granite Guardian | |  |
| 2023.10 | NeMo Guardrails: A Toolkit for Controllable and Safe LLM Applications with Programmable Rails | |  |
| 2023.04 | Rebuff: Prompt Injection Detection for LLM Applications | |  |
| 2025.01 | Constitutional Classifiers: Defending against Universal Jailbreaks across Thousands of Hours of Red Teaming | | - |
| 2025.04 | X-Guard: Multilingual Guard Agent for Content Moderation | |  |
| 2025.06 | SoK: Evaluating Jailbreak Guardrails for Large Language Models | |  |
| 2024.07 | ShieldGemma: Generative AI Content Moderation Based on Gemma | | - |
| 2025.04 | ShieldGemma 2: Robust and Tractable Image Content Moderation | | - |
| 2023.06 | Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena | |  |
| 2025.06 | RSafe: Incentivizing Proactive Reasoning to Build Robust and Adaptive LLM Safeguards | |  |
| 2023.07 | Universal and Transferable Adversarial Attacks on Aligned Language Models | |  |
| 2026.01 | Prompt Shields in Azure AI Content Safety | | - |
| 2025.04 | Bypassing Prompt Injection and Jailbreak Detection in LLM Guardrails | |  |
| 2026.04 | Guardian-as-an-Advisor: Advancing Next-Generation Guardian Models for Trustworthy LLMs | | - |
| 2025.04 | Llama Prompt Guard Documentation | | |
Decoding Strategies
| Year | Title | Paper | Github |
|---|---|---|---|
| 2024.06 | SafeInfer: Context Adaptive Decoding Time Safety Alignment for Large Language Models | |  |
| 2024.05 | Decoding by Contrasting Knowledge: Enhancing LLMs' Confidence on Edited Facts | |  |
| 2024.08 | The Unreasonable Ineffectiveness of Nucleus Sampling on Mitigating Text Memorization | |  |
| 2024.12 | FlexLLM: Exploring LLM Customization for Moving Target Defense on Black-Box LLMs Against Jailbreak Attacks | | - |
| 2024.08 | Lower Layers Matter: Alleviating Hallucination via Multi-Layer Fusion Contrastive Decoding with Truthfulness Refocused | | - |
| 2022.10 | Quantifying Bias from Decoding Techniques in Natural Language Generation | | - |
| 2022.10 | An Analysis of The Effects of Decoding Algorithms on Fairness in Open-Ended Language Generation | | - |
| 2024.05 | MoGU: A Framework for Enhancing Safety of Open-Sourced LLMs While Preserving Their Usability | |  |
| 2025.02 | MetaSC: Test-Time Safety Specification Optimization for Language Models | |  |
| 2024.09 | CoCA: Regaining Safety-awareness of Multimodal Large Language Models with Constitutional Calibration | | - |
| 2024.11 | Immune: Improving Safety Against Jailbreaks in Multi-modal LLMs via Inference-Time Alignment | |  |
| 2024.06 | SafeAligner: Safety Alignment against Jailbreak Attacks via Response Disparity Guidance | |  |
| 2025.01 | Dynamic Attention-Guided Context Decoding for Mitigating Context Faithfulness Hallucinations in Large Language Models | |  |
| 2024.10 | What's New in My Data? Novelty Exploration via Contrastive Generation | | - |
| 2024.06 | CleanGen: Mitigating Backdoor Attacks for Generation Tasks in Large Language Models | |  |
| 2024.09 | Mitigating Hallucination in Visual-Language Models via Re-Balancing Contrastive Decoding | | - |
| 2024.08 | Alignment-Enhanced Decoding: Defending Jailbreaks via Token-Level Adaptive Refining of Probability Distributions | |  |
| 2022.05 | Differentially Private Decoding in Large Language Models | | - |
| 2024.06 | Decoding with Limited Teacher Supervision Requires Understanding When to Trust the Teacher | |  |
| 2024.08 | ConVis: Contrastive Decoding with Hallucination Visualization for Mitigating Hallucinations in Multimodal Large Language Models | |  |
| 2024.09 | Reference Trustable Decoding: A Training-Free Augmentation Paradigm for Large Language Models | |  |
| 2025.03 | Octopus: Alleviating Hallucination via Dynamic Contrastive Decoding | |  |
| 2024.10 | MLLM Can See? Dynamic Correction Decoding for Hallucination Mitigation | |  |
| 2025.08 | Privacy-Aware Decoding: Mitigating Privacy Leakage of Large Language Models in Retrieval-Augmented Generation | |  |
| 2024.11 | Privacy Risks of Speculative Decoding in Large Language Models | | - |
| 2024.02 | SafeDecoding: Defending against Jailbreak Attacks via Safety-Aware Decoding | |  |
| 2024.09 | HELPD: Mitigating Hallucination of LVLMs by Hierarchical Feedback Learning with Vision-enhanced Penalty Decoding | |  |
| 2024.10 | Root Defence Strategies: Ensuring Safety of LLM at the Decoding Level | |  |
| 2024.10 | Controllable Safety Alignment: Inference-Time Adaptation to Diverse Safety Requirements | |  |
| 2024.06 | Adversarial Contrastive Decoding: Boosting Safety Alignment of Large Language Models via Opposite Prompt Optimization | |  |
| 2024.02 | ROSE Doesn't Do That: Boosting the Safety of Instruction-Tuned Large Language Models with Reverse Prompt Contrastive Decoding | |  |
Tier 2: Internal Manipulations
Representation Engineering
| Year | Title | Paper | Github |
|---|---|---|---|
| 2023.11 | Trojan Activation Attack: Red-Teaming Large Language Models using Steering Vectors for Safety-Alignment | |  |
| 2024.09 | HSF: Defending against Jailbreak Attacks with Hidden State Filtering | | - |
| 2024.06 | Refusal in Language Models Is Mediated by a Single Direction | |  |
| 2023.06 | LEACE: Perfect Linear Concept Erasure in Closed Form | |  |
| 2024.10 | Towards Inference-Time Category-wise Safety Steering for Large Language Models | | - |
| 2025.05 | Breaking Bad Tokens: Detoxification of LLMs Using Sparse Autoencoders | |  |
| 2023.12 | TaCo: Targeted Concept Erasure Prevents Non-Linear Classifiers From Detecting Protected Attributes | |  |
| 2024.09 | Programming Refusal with Conditional Activation Steering | |  |
| 2025.04 | FairSteer: Inference-Time Debiasing for LLMs with Dynamic Activation Steering | |  |
| 2020.07 | Towards Debiasing Sentence Representations | |  |
| 2025.08 | Steering Towards Fairness: Mitigating Political Bias in LLMs | | - |
| 2024.11 | Steering Language Model Refusal with Sparse Autoencoders | | - |
| 2020.04 | Null It Out: Guarding Protected Attributes by Iterative Nullspace Projection | |  |
| 2024.10 | Jailbreak Antidote: Runtime Safety-Utility Balance via Sparse Representation Adjustment in Large Language Models | | - |
| 2025.06 | AlphaSteer: Learning Refusal Steering with Principled Null-Space Constraint | |  |
| 2025.03 | Shifting Perspectives: Steering Vectors for Robust Bias Mitigation in LLMs | |  |
| 2024.10 | Surgical, Cheap, and Flexible: Mitigating False Refusal in Language Models via Single Vector Ablation | |  |
| 2024.01 | InferAligner: Inference-Time Alignment for Harmlessness through Cross-Model Guidance | |  |
| 2025.03 | BIASEdit: Debiasing Stereotyped Language Models via Model Editing | |  |
| 2025.02 | Representation Engineering for Large-Language Models: Survey and Research Challenges | | - |
| 2024.05 | Enhanced Language Model Truthfulness with Learnable Intervention and Uncertainty Expression | |  |
| 2024.08 | SCANS: Mitigating the Exaggerated Safety for LLMs via Safety-Conscious Activation Steering | |  |
| 2023.09 | Sparse Autoencoders Find Highly Interpretable Features in Language Models | |  |
| 2024.09 | Rethinking the Reliability of Representation Engineering: A Causal Perspective | | - |
| 2024.12 | Shaping the Safety Boundaries: Understanding and Defending Against Jailbreaks in Large Language Models | | - |
| 2025.02 | SafeSwitch: Steering Unsafe LLM Behavior via Internal Activation Signals | |  |
| 2024.03 | Non-Linear Inference Time Intervention: Improving LLM Truthfulness | |  |
| 2024.06 | Jailbreaking Large Language Models Through Alignment Vulnerabilities in Out-of-Distribution Settings | | - |
| 2025.08 | MSRS: Adaptive Multi-Subspace Representation Steering for Attribute Alignment in Large Language Models | | - |
| 2024.10 | Sparse Autoencoders Reveal Universal Feature Spaces Across Large Language Models | |  |
| 2023.06 | Inference-Time Intervention: Eliciting Truthful Answers from a Language Model | |  |
| 2025.05 | Truth Neurons | |  |
| 2024.07 | On the Universal Truthfulness Hyperplane Inside LLMs | |  |
| 2025.07 | PII Jailbreaking in LLMs via Activation Steering Reveals Personal Information Leakage | | - |
| 2025.02 | Multi-Attribute Steering of Language Models via Targeted Intervention | |  |
| 2023.11 | The Linear Representation Hypothesis and the Geometry of Large Language Models | |  |
| 2025.01 | Sparse Autoencoders Trained on the Same Data Learn Different Features | |  |
| 2023.12 | Steering Llama 2 via Contrastive Activation Addition | |  |
| 2025.03 | Mitigating Memorization in LLMs using Activation Steering | | - |
| 2023.08 | Steering Language Models with Activation Engineering | |  |
| 2024.06 | Adaptive Activation Steering: A Tuning-Free LLM Truthfulness Improvement Method for Diverse Hallucinations Categories | |  |
| 2025.02 | Taxonomy, Opportunities, and Challenges of Representation Engineering for Large Language Models | | - |
| 2024.04 | ReFT: Representation Finetuning for Language Models | |  |
| 2023.09 | Towards Best Practices of Activation Patching in Language Models: Metrics and Methods | | - |
| 2025.07 | LLMs Encode Harmfulness and Refusal Separately | |  |
| 2024.10 | On the Role of Attention Heads in Large Language Model Safety | |  |
| 2025.03 | Compositional Subspace Representation Fine-tuning for Adaptive Large Language Models | | - |
| 2023.10 | Representation Engineering: A Top-Down Approach to AI Transparency | |  |
Unlearning
| Year | Title | Paper | Github |
|---|---|---|---|
| 2025.05 | Guard: Generation-Time LLM Unlearning via Adaptive Restriction and Detection | | - |
| 2024.06 | Avoiding Copyright Infringement via Large Language Model Unlearning | |  |
| 2025.02 | Beyond Single-Value Metrics: Evaluating and Enhancing LLM Unlearning with Cognitive Diagnosis | |  |
| 2023.09 | Mitigating the Alignment Tax of RLHF | |  |
| 2023.10 | Breaking the Trilemma of Privacy, Utility, and Efficiency via Controllable Machine Unlearning | |  |
| 2024.06 | Large Language Model Unlearning via Embedding-Corrupted Prompts | |  |
| 2024.07 | Learning to Refuse: Towards Mitigating Privacy Risks in LLMs | |  |
| 2024.02 | Towards Safer Large Language Models through Machine Unlearning | |  |
| 2024.09 | An Adversarial Perspective on Machine Unlearning for AI Safety | |  |
| 2024.02 | Fast Exact Unlearning for In-Context Learning Data for LLMs | | - |
| 2023.10 | In-Context Unlearning: Language Models as Few Shot Unlearners | |  |
| 2025.02 | Agents Are All You Need for LLM Unlearning | |  |
| 2024.10 | Answer When Needed, Forget When Not: Language Models Pretend to Forget via In-Context Knowledge Unlearning | |  |
| 2024.07 | From Theft to Bomb-Making: The Ripple Effect of Unlearning in Defending Against Jailbreak Attacks | |  |
| 2024.02 | Visual In-Context Learning for Large Vision-Language Models | | - |
Pruning
| Year | Title | Paper | Github |
|---|---|---|---|
| 2024.10 | Is C4 Dataset Optimal for Pruning? An Investigation of Calibration Data for LLM Pruning | |  |
| 2025.07 | SafePTR: Token-Level Jailbreak Defense in Multimodal LLMs via Prune-then-Restore Mechanism | |  |
| 2023.11 | Investigating Hallucinations in Pruned Large Language Models for Abstractive Summarization | |  |
| 2025.03 | Attention Pruning: Automated Fairness Repair of Language Models via Surrogate Simulated Annealing | | - |
| 2025.05 | Exploring Federated Pruning for Large Language Models | |  |
| 2024.01 | Pruning for Protection: Increasing Jailbreak Resistance in Aligned LLMs Without Fine-Tuning | | - |
| 2023.07 | Measuring Faithfulness in Chain-of-Thought Reasoning | | - |
| 2025.05 | Hierarchical Safety Realignment: Lightweight Restoration of Safety in Pruned Large Vision-Language Models | |  |
| 2025.02 | Modality-Aware Neuron Pruning for Unlearning in Multimodal Large Language Models | |  |
| 2025.02 | Breaking Down Bias: On The Limits of Generalizable Pruning Strategies | | - |
| 2024.03 | Dissecting Language Models: Machine Unlearning via Selective Pruning | |  |
| 2024.12 | Lightweight Safety Classification Using Pruned Language Models | | - |
| 2024.02 | Assessing the Brittleness of Safety Alignment via Pruning and Low-Rank Modifications | |  |
| 2024.12 | NLSR: Neuron-Level Safety Realignment of Large Language Models Against Harmful Fine-Tuning | |  |
| 2023.12 | Fairness-Aware Structured Pruning in Transformers | |  |
| 2025.02 | Activation Approximations Can Incur Safety Vulnerabilities Even in Aligned LLMs: Comprehensive Analysis and Defense | |  |
| 2025.01 | Understanding and Enhancing Safety Mechanisms of LLMs via Safety-Specific Neuron | |  |
Tier 3: System-Level Orchestration
Multi-Agent Systems
| Year | Title | Paper | Github |
|---|---|---|---|
| 2023.05 | Improving Factuality and Reasoning in Language Models through Multiagent Debate | |  |
| 2024.02 | Debating with More Persuasive LLMs Leads to More Truthful Answers | |  |
| 2024.06 | Towards Detecting LLMs Hallucination via Markov Chain-based Multi-agent Debate Framework | | - |
| 2025.06 | RedDebate: Safer Responses through Multi-Agent Red Teaming Debates | |  |
| 2024.10 | Towards Implicit Bias Detection and Mitigation in Multi-Agent LLM Interactions | |  |
| 2024.06 | Counterfactual Debating with Preset Stances for Hallucination Elimination of LLMs | |  |
| 2025.05 | An Adversary-Resistant Multi-Agent LLM System via Credibility Scoring | | - |
| 2025.05 | PeerGuard: Defending Multi-Agent Systems Against Backdoor Attacks Through Mutual Reasoning | |  |
| 2024.02 | Don't Hallucinate, Abstain: Identifying LLM Knowledge Gaps via Multi-LLM Collaboration | |  |
| 2025.02 | Red-Teaming LLM Multi-Agent Systems via Communication Attacks | | - |
| 2026.03 | Emergent Social Intelligence Risks in Generative Multi-Agent Systems | | - |
| 2025.05 | Multiple LLM Agents Debate for Equitable Cultural Alignment | |  |
| 2024.02 | Can LLMs Produce Faithful Explanations For Fact-Checking? Towards Faithful Explainable Fact-Checking via Multi-Agent Debate | |  |
| 2025.08 | 1-2-3 Check: Enhancing Contextual Privacy in LLM via Multi-Agent Reasoning | |  |
| 2025.03 | A Multi-Agent Framework with Automated Decision Rule Optimization for Cross-Domain Misinformation Detection | | - |
| 2024.09 | A Multi-LLM Debiasing Framework | | - |
| 2025.04 | Amplified Vulnerabilities: Structured Jailbreak Attacks on LLM-based Multi-Agent Debate | | - |
| 2024.08 | Audit-LLM: Multi-Agent Collaboration for Log-based Insider Threat Detection | | - |
| 2023.08 | Towards CausalGPT: A Multi-Agent Approach for Faithful Knowledge Reasoning via Promoting Causal Consistency in LLMs | | - |
| 2024.04 | White Men Lead, Black Women Help? Benchmarking and Mitigating Language Agency Social Biases in LLMs | |  |
| 2025.03 | MAMM-Refine: A Recipe for Improving Faithfulness in Generation with Multi-Agent Collaboration | |  |
| 2025.09 | Which Cultural Lens Do Models Adopt? On Cultural Positioning Bias and Agentic Mitigation in LLMs | | - |
| 2025.05 | IP Leakage Attacks Targeting LLM-Based Multi-Agent Systems | | - |
| 2024.04 | Confidence Calibration and Rationalization for LLMs via Multi-Agent Deliberation | |  |
| 2024.03 | AutoDefense: Multi-Agent LLM Defense against Jailbreak Attacks | |  |
| 2024.01 | PsySafe: A Comprehensive Framework for Psychological-based Attack, Defense, and Evaluation of Multi-agent System Safety | |  |
| 2025.05 | GUARDIAN: Safeguarding LLM Multi-Agent Collaborations with Temporal Graph Modeling | |  |
| 2025.05 | MASTER: Multi-Agent Security Through Exploration of Roles and Topological Structures | | - |
Evaluation
| Year | Title | Paper | Github |
|---|---|---|---|
| 2023.06 | TrustGPT: A Benchmark for Trustworthy and Responsible Large Language Models | |  |
| 2025.04 | TrustEval: A Dynamic Evaluation Toolkit on Trustworthiness of Generative Foundation Models | |  |
| 2024.10 | Justice or Prejudice? Quantifying Biases in LLM-as-a-Judge | |  |
| 2023.06 | Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena | | |
| 2024.04 | AEGIS: Online Adaptive AI Content Safety Moderation with Ensemble of LLM Experts | | - |
| 2024.06 | WildGuard: Open One-Stop Moderation Tools for Safety Risks, Jailbreaks, and Refusals of LLMs | | |
| 2025.06 | SoK: Evaluating Jailbreak Guardrails for Large Language Models | | |
| 2024.02 | SafeDecoding: Defending against Jailbreak Attacks via Safety-Aware Decoding | | |
| 2024.06 | SafeAligner: Safety Alignment against Jailbreak Attacks via Response Disparity Guidance | | |
| 2024.10 | Root Defence Strategies: Ensuring Safety of LLM at the Decoding Level | | |
| 2023.06 | Inference-Time Intervention: Eliciting Truthful Answers from a Language Model | | |
| 2024.01 | InferAligner: Inference-Time Alignment for Harmlessness through Cross-Model Guidance | | |
| 2025.01 | GuardReasoner: Towards Reasoning-based LLM Safeguards | | |
| 2024.12 | Granite Guardian | | |
| 2024.02 | Assessing the Brittleness of Safety Alignment via Pruning and Low-Rank Modifications | | |
| 2025.03 | Attention Pruning: Automated Fairness Repair of Language Models via Surrogate Simulated Annealing | | - |
| 2025.05 | Guard: Generation-Time LLM Unlearning via Adaptive Restriction and Detection | | - |
| 2023.10 | In-Context Unlearning: Language Models as Few Shot Unlearners | | |
| 2024.07 | From Theft to Bomb-Making: The Ripple Effect of Unlearning in Defending Against Jailbreak Attacks | | |
| 2025.05 | GUARDIAN: Safeguarding LLM Multi-Agent Collaborations with Temporal Graph Modeling | | |
| 2024.04 | Confidence Calibration and Rationalization for LLMs via Multi-Agent Deliberation | | |
| 2025.06 | RedDebate: Safer Responses through Multi-Agent Red Teaming Debates | | |
| 2025.05 | PeerGuard: Defending Multi-Agent Systems Against Backdoor Attacks Through Mutual Reasoning | | |
| 2025.07 | SafePTR: Token-Level Jailbreak Defense in Multimodal LLMs via Prune-then-Restore Mechanism | | |
| 2025.07 | PII Jailbreaking in LLMs via Activation Steering Reveals Personal Information Leakage | | - |
| 2024.10 | Mitigating Gender Bias in Code Large Language Models via Model Editing | | - |
| 2025.06 | Saffron-1: Towards an Inference Scaling Paradigm for LLM Safety Assurance | | |
🌟 Acknowledgments
We thank all the researchers who contributed to this field. This list is maintained by the authors. If you find any missing papers or errors, please open an issue.
✨ Star History
Contributors

10 commits

3 commits
Similar repos


README
Inference-Time Control for Trustworthy Large Language Models
We welcome everyone to open an issue for any related work we haven't covered, and we'll try to address it in the next release!
🎉 News
- [2026-05] 🔥 Paper available on preprints.org: https://www.preprints.org/manuscript/202605.1041
🎈 Citation
If you find this work helpful, please cite us:
@article{bai2026inferencetime,
  title     = {Inference-Time Control for Trustworthy Large Language Models},
  author    = {Bai, Yuyang and Liu, Zheyuan and Yan, Han and Xu, Zhangchen and Wan, Yixin and Chen, Canyu and Wang, Zehong and Yuan, Xiangchi and Huang, Yue and Dou, Guangyao and Zhang, Yuji and Zhu, Hangxiao and Li, Zhuofeng and Li, Manling and Zhang, Xiangliang and Bansal, Mohit and Koyejo, Sanmi and Chang, Kai-Wei and Zhang, Yu and Jiang, Meng},
  journal   = {Preprints},
  year      = {2026},
  month     = {May},
  publisher = {Preprints},
  doi       = {10.20944/preprints202605.1041.v1},
  url       = {https://doi.org/10.20944/preprints202605.1041.v1}
}
📖 Contents
🗺️ Overview
This work covers Inference-Time Control methods for building trustworthy LLMs, organized into three tiers:
-
Tier 1 — External Controls: Treat the model as a black box. Shape behavior by modifying inputs, decoding process, or outputs, without changing internal weights or activations.
- Context Engineering: Strategic prompt design through rules, instructions, or few-shot exemplars.
- Guardrails: External modules that inspect inputs/outputs against safety or policy constraints.
- Decoding Strategies: Manipulation of token-level distributions during generation.
-
Tier 2 — Internal Manipulations: Require white-box access. Intervene directly in the model's internal computation.
- Representation Engineering: Direct modification of internal activations via steering vectors.
- Unlearning: Targeted removal of information, behaviors, or biases from a pre-trained model.
- Pruning: Post-training removal of weights, neurons, or attention heads for trust-related effects.
-
Tier 3 — System-Level Orchestration: Coordinate multiple LLM agents through structured interaction patterns.
- Multi-Agent Systems: Coordinated agent interactions such as debate or cross-verification.
📄 Paper List
Tier 1: External Controls
Context Engineering
| Year | Title | Paper | Github |
|---|---|---|---|
| 2023.10 | Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection | | |
| 2023.09 | Defending Against Alignment-Breaking Attacks via Robustly Aligned LLM | | |
| 2024.05 | Phantom: General Trigger Attacks on Retrieval Augmented Language Generation | | - |
| 2024.12 | Improving Factuality with Explicit Working Memory | | - |
| 2024.11 | SPICA: Retrieving Scenarios for Pluralistic In-Context Alignment | | |
| 2023.07 | Queer People Are People First: Deconstructing Sexual Identity Stereotypes in Large Language Models | | - |
| 2023.09 | Chain-of-Verification Reduces Hallucination in Large Language Models | | |
| 2023.12 | Breaking the Bias: Gender Fairness in LLMs Using Prompt Engineering and In-Context Learning | | - |
| 2025.02 | FACTER: Fairness-Aware Conformal Thresholding and Prompt Engineering for Enabling Fair LLM-Based Recommender Systems | | |
| 2024.06 | Teaching LLMs to Abstain across Languages via Multilingual Feedback | | |
| 2023.05 | Why So Gullible? Enhancing the Robustness of Retrieval-Augmented Models against Counterfactual Noise | | |
| 2023.09 | Bias Testing and Mitigation in LLM-Based Code Generation | | |
| 2024.02 | Defending Large Language Models Against Jailbreak Attacks via Semantic Smoothing | | |
| 2024.04 | Prompting Techniques for Reducing Social Bias in LLMs through System 1 and System 2 Cognitive Processes | | |
| 2023.09 | Certifying LLM Safety against Adversarial Prompting | | |
| 2024.03 | Think Twice Before Trusting: Self-Detection for Large Language Models through Comprehensive Answer Reflection | | - |
| 2024.10 | SafetyAnalyst: Interpretable, Transparent, and Steerable Safety Moderation for AI Behavior | | |
| 2022.10 | Measuring and Narrowing the Compositionality Gap in Language Models | | |
| 2025.06 | Saffron-1: Towards an Inference Scaling Paradigm for LLM Safety Assurance | | |
| 2023.01 | REPLUG: Retrieval-Augmented Black-Box Language Models | | |
| 2024.03 | FairRAG: Fair Human Generation via Fair Retrieval Augmentation | | - |
| 2023.10 | InferDPT: Privacy-Preserving Inference for Black-Box Large Language Models | | |
| 2024.02 | DELL: Generating Reactions and Explanations for LLM-Based Misinformation Detection | | |
| 2023.06 | Augmenting Language Models with Long-Term Memory | | |
| 2023.10 | Jailbreak and Guard Aligned Language Models with Only Few In-Context Demonstrations | | - |
| 2023.10 | Quantifying Privacy Risks of Prompts in Visual Prompt Learning | | |
| 2022.09 | Generate rather than Retrieve: Large Language Models are Strong Context Generators | | |
| 2023.10 | Poisoning Retrieval Corpora by Injecting Adversarial Passages | | |
| 2023.03 | Context-Faithful Prompting for Large Language Models | | |
| 2024.02 | Defending Jailbreak Prompts via In-Context Adversarial Game | | |
| 2024.02 | Metacognitive Retrieval-Augmented Large Language Models | | |
| 2024.02 | PoisonedRAG: Knowledge Corruption Attacks to Retrieval-Augmented Generation of Large Language Models | | |
Guardrails
| Year | Title | Paper | Github |
|---|---|---|---|
| 2019.03 | Nuanced Metrics for Measuring Unintended Bias with Real Data for Text Classification | | |
| 2025.05 | LlamaFirewall: An Open Source Guardrail System for Building Secure AI Agents | | |
| 2024.11 | Llama Guard 3 Vision: Safeguarding Human-AI Image Understanding Conversations | | |
| 2017.03 | Automated Hate Speech Detection and the Problem of Offensive Language | | |
| 2024.04 | AEGIS: Online Adaptive AI Content Safety Moderation with Ensemble of LLM Experts | | - |
| 2024.06 | WildGuard: Open One-Stop Moderation Tools for Safety Risks, Jailbreaks, and Refusals of LLMs | | |
| 2025.02 | Bridging the Safety Gap: A Guardrail Pipeline for Trustworthy LLM Inferences | | - |
| 2022.03 | ToxiGen: A Large-Scale Machine-Generated Dataset for Adversarial and Implicit Hate Speech Detection | | |
| 2023.12 | Llama Guard: LLM-based Input-Output Safeguard for Human-AI Conversations | | |
| 2024.07 | POSTER: Identifying and Mitigating Vulnerabilities in LLM-Integrated Applications | | - |
| 2024.02 | ArtPrompt: ASCII Art-based Jailbreak Attacks against Aligned LLMs | | |
| 2024.07 | R2-Guard: Robust Reasoning Enabled LLM Guardrail via Knowledge-Enhanced Logical Reasoning | | |
| 2024.10 | Palisade — Prompt Injection Detection Framework | | - |
| 2025.04 | PolyGuard: A Multilingual Safety Moderation Tool for 17 Languages | | |
| 2025.02 | SafeRoute: Adaptive Model Selection for Efficient and Accurate Safety Guardrails in Large Language Models | | |
| 2022.02 | A New Generation of Perspective API: Efficient Multilingual Character-level Transformers | | |
| 2025.01 | GuardReasoner: Towards Reasoning-based LLM Safeguards | | |
| 2020.12 | HateXplain: A Benchmark Dataset for Explainable Hate Speech Detection | | |
| 2024.12 | Granite Guardian | | |
| 2023.10 | NeMo Guardrails: A Toolkit for Controllable and Safe LLM Applications with Programmable Rails | | |
| 2023.04 | Rebuff: Prompt Injection Detection for LLM Applications | | |
| 2025.01 | Constitutional Classifiers: Defending against Universal Jailbreaks across Thousands of Hours of Red Teaming | | - |
| 2025.04 | X-Guard: Multilingual Guard Agent for Content Moderation | | |
| 2025.06 | SoK: Evaluating Jailbreak Guardrails for Large Language Models | | |
| 2024.07 | ShieldGemma: Generative AI Content Moderation Based on Gemma | | - |
| 2025.04 | ShieldGemma 2: Robust and Tractable Image Content Moderation | | - |
| 2023.06 | Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena | | |
| 2025.06 | RSafe: Incentivizing Proactive Reasoning to Build Robust and Adaptive LLM Safeguards | | |
| 2023.07 | Universal and Transferable Adversarial Attacks on Aligned Language Models | | |
| 2026.01 | Prompt Shields in Azure AI Content Safety | | - |
| 2025.04 | Bypassing Prompt Injection and Jailbreak Detection in LLM Guardrails | | |
| 2026.04 | Guardian-as-an-Advisor: Advancing Next-Generation Guardian Models for Trustworthy LLMs | | - |
| 2025.04 | Llama Prompt Guard Documentation | | |
Decoding Strategies
| Year | Title | Paper | Github |
|---|---|---|---|
| 2024.06 | SafeInfer: Context Adaptive Decoding Time Safety Alignment for Large Language Models | | |
| 2024.05 | Decoding by Contrasting Knowledge: Enhancing LLMs' Confidence on Edited Facts | | |
| 2024.08 | The Unreasonable Ineffectiveness of Nucleus Sampling on Mitigating Text Memorization | | |
| 2024.12 | FlexLLM: Exploring LLM Customization for Moving Target Defense on Black-Box LLMs Against Jailbreak Attacks | | - |
| 2024.08 | Lower Layers Matter: Alleviating Hallucination via Multi-Layer Fusion Contrastive Decoding with Truthfulness Refocused | | - |
| 2022.10 | Quantifying Bias from Decoding Techniques in Natural Language Generation | | - |
| 2022.10 | An Analysis of The Effects of Decoding Algorithms on Fairness in Open-Ended Language Generation | | - |
| 2024.05 | MoGU: A Framework for Enhancing Safety of Open-Sourced LLMs While Preserving Their Usability | | |
| 2025.02 | MetaSC: Test-Time Safety Specification Optimization for Language Models | | |
| 2024.09 | CoCA: Regaining Safety-awareness of Multimodal Large Language Models with Constitutional Calibration | | - |
| 2024.11 | Immune: Improving Safety Against Jailbreaks in Multi-modal LLMs via Inference-Time Alignment | | |
| 2024.06 | SafeAligner: Safety Alignment against Jailbreak Attacks via Response Disparity Guidance | | |
| 2025.01 | Dynamic Attention-Guided Context Decoding for Mitigating Context Faithfulness Hallucinations in Large Language Models | | |
| 2024.10 | What's New in My Data? Novelty Exploration via Contrastive Generation | | - |
| 2024.06 | CleanGen: Mitigating Backdoor Attacks for Generation Tasks in Large Language Models | | |
| 2024.09 | Mitigating Hallucination in Visual-Language Models via Re-Balancing Contrastive Decoding | | - |
| 2024.08 | Alignment-Enhanced Decoding: Defending Jailbreaks via Token-Level Adaptive Refining of Probability Distributions | | |
| 2022.05 | Differentially Private Decoding in Large Language Models | | - |
| 2024.06 | Decoding with Limited Teacher Supervision Requires Understanding When to Trust the Teacher | | |
| 2024.08 | ConVis: Contrastive Decoding with Hallucination Visualization for Mitigating Hallucinations in Multimodal Large Language Models | | |
| 2024.09 | Reference Trustable Decoding: A Training-Free Augmentation Paradigm for Large Language Models | | |
| 2025.03 | Octopus: Alleviating Hallucination via Dynamic Contrastive Decoding | | |
| 2024.10 | MLLM Can See? Dynamic Correction Decoding for Hallucination Mitigation | | |
| 2025.08 | Privacy-Aware Decoding: Mitigating Privacy Leakage of Large Language Models in Retrieval-Augmented Generation | | |
| 2024.11 | Privacy Risks of Speculative Decoding in Large Language Models | | - |
| 2024.02 | SafeDecoding: Defending against Jailbreak Attacks via Safety-Aware Decoding | | |
| 2024.09 | HELPD: Mitigating Hallucination of LVLMs by Hierarchical Feedback Learning with Vision-enhanced Penalty Decoding | | |
| 2024.10 | Root Defence Strategies: Ensuring Safety of LLM at the Decoding Level | | |
| 2024.10 | Controllable Safety Alignment: Inference-Time Adaptation to Diverse Safety Requirements | | |
| 2024.06 | Adversarial Contrastive Decoding: Boosting Safety Alignment of Large Language Models via Opposite Prompt Optimization | | |
| 2024.02 | ROSE Doesn't Do That: Boosting the Safety of Instruction-Tuned Large Language Models with Reverse Prompt Contrastive Decoding | | |
Tier 2: Internal Manipulations
Representation Engineering
| Year | Title | Paper | Github |
|---|---|---|---|
| 2023.11 | Trojan Activation Attack: Red-Teaming Large Language Models using Steering Vectors for Safety-Alignment | | |
| 2024.09 | HSF: Defending against Jailbreak Attacks with Hidden State Filtering | | - |
| 2024.06 | Refusal in Language Models Is Mediated by a Single Direction | | |
| 2023.06 | LEACE: Perfect Linear Concept Erasure in Closed Form | | |
| 2024.10 | Towards Inference-Time Category-wise Safety Steering for Large Language Models | | - |
| 2025.05 | Breaking Bad Tokens: Detoxification of LLMs Using Sparse Autoencoders | | |
| 2023.12 | TaCo: Targeted Concept Erasure Prevents Non-Linear Classifiers From Detecting Protected Attributes | | |
| 2024.09 | Programming Refusal with Conditional Activation Steering | | |
| 2025.04 | FairSteer: Inference-Time Debiasing for LLMs with Dynamic Activation Steering | | |
| 2020.07 | Towards Debiasing Sentence Representations | | |
| 2025.08 | Steering Towards Fairness: Mitigating Political Bias in LLMs | | - |
| 2024.11 | Steering Language Model Refusal with Sparse Autoencoders | | - |
| 2020.04 | Null It Out: Guarding Protected Attributes by Iterative Nullspace Projection | | |
| 2024.10 | Jailbreak Antidote: Runtime Safety-Utility Balance via Sparse Representation Adjustment in Large Language Models | | - |
| 2025.06 | AlphaSteer: Learning Refusal Steering with Principled Null-Space Constraint | | |
| 2025.03 | Shifting Perspectives: Steering Vectors for Robust Bias Mitigation in LLMs | | |
| 2024.10 | Surgical, Cheap, and Flexible: Mitigating False Refusal in Language Models via Single Vector Ablation | | |
| 2024.01 | InferAligner: Inference-Time Alignment for Harmlessness through Cross-Model Guidance | | |
| 2025.03 | BIASEdit: Debiasing Stereotyped Language Models via Model Editing | | |
| 2025.02 | Representation Engineering for Large-Language Models: Survey and Research Challenges | | - |
| 2024.05 | Enhanced Language Model Truthfulness with Learnable Intervention and Uncertainty Expression | | |
| 2024.08 | SCANS: Mitigating the Exaggerated Safety for LLMs via Safety-Conscious Activation Steering | | |
| 2023.09 | Sparse Autoencoders Find Highly Interpretable Features in Language Models | | |
| 2024.09 | Rethinking the Reliability of Representation Engineering: A Causal Perspective | | - |
| 2024.12 | Shaping the Safety Boundaries: Understanding and Defending Against Jailbreaks in Large Language Models | | - |
| 2025.02 | SafeSwitch: Steering Unsafe LLM Behavior via Internal Activation Signals | | |
| 2024.03 | Non-Linear Inference Time Intervention: Improving LLM Truthfulness | | |
| 2024.06 | Jailbreaking Large Language Models Through Alignment Vulnerabilities in Out-of-Distribution Settings | | - |
| 2025.08 | MSRS: Adaptive Multi-Subspace Representation Steering for Attribute Alignment in Large Language Models | | - |
| 2024.10 | Sparse Autoencoders Reveal Universal Feature Spaces Across Large Language Models | | |
| 2023.06 | Inference-Time Intervention: Eliciting Truthful Answers from a Language Model | | |
| 2025.05 | Truth Neurons | | |
| 2024.07 | On the Universal Truthfulness Hyperplane Inside LLMs | | |
| 2025.07 | PII Jailbreaking in LLMs via Activation Steering Reveals Personal Information Leakage | | - |
| 2025.02 | Multi-Attribute Steering of Language Models via Targeted Intervention | | |
| 2023.11 | The Linear Representation Hypothesis and the Geometry of Large Language Models | | |
| 2025.01 | Sparse Autoencoders Trained on the Same Data Learn Different Features | | |
| 2023.12 | Steering Llama 2 via Contrastive Activation Addition | | |
| 2025.03 | Mitigating Memorization in LLMs using Activation Steering | | - |
| 2023.08 | Steering Language Models with Activation Engineering | | |
| 2024.06 | Adaptive Activation Steering: A Tuning-Free LLM Truthfulness Improvement Method for Diverse Hallucinations Categories | | |
| 2025.02 | Taxonomy, Opportunities, and Challenges of Representation Engineering for Large Language Models | | - |
| 2024.04 | ReFT: Representation Finetuning for Language Models | | |
| 2023.09 | Towards Best Practices of Activation Patching in Language Models: Metrics and Methods | | - |
| 2025.07 | LLMs Encode Harmfulness and Refusal Separately | | |
| 2024.10 | On the Role of Attention Heads in Large Language Model Safety | | |
| 2025.03 | Compositional Subspace Representation Fine-tuning for Adaptive Large Language Models | | - |
| 2023.10 | Representation Engineering: A Top-Down Approach to AI Transparency | | |
Unlearning
| Year | Title | Paper | Github |
|---|---|---|---|
| 2025.05 | Guard: Generation-Time LLM Unlearning via Adaptive Restriction and Detection | | - |
| 2024.06 | Avoiding Copyright Infringement via Large Language Model Unlearning | | |
| 2025.02 | Beyond Single-Value Metrics: Evaluating and Enhancing LLM Unlearning with Cognitive Diagnosis | | |
| 2023.09 | Mitigating the Alignment Tax of RLHF | | |
| 2023.10 | Breaking the Trilemma of Privacy, Utility, and Efficiency via Controllable Machine Unlearning | | |
| 2024.06 | Large Language Model Unlearning via Embedding-Corrupted Prompts | | |
| 2024.07 | Learning to Refuse: Towards Mitigating Privacy Risks in LLMs | | |
| 2024.02 | Towards Safer Large Language Models through Machine Unlearning | | |
| 2024.09 | An Adversarial Perspective on Machine Unlearning for AI Safety | | |
| 2024.02 | Fast Exact Unlearning for In-Context Learning Data for LLMs | | - |
| 2023.10 | In-Context Unlearning: Language Models as Few Shot Unlearners | | |
| 2025.02 | Agents Are All You Need for LLM Unlearning | | |
| 2024.10 | Answer When Needed, Forget When Not: Language Models Pretend to Forget via In-Context Knowledge Unlearning | | |
| 2024.07 | From Theft to Bomb-Making: The Ripple Effect of Unlearning in Defending Against Jailbreak Attacks | | |
| 2024.02 | Visual In-Context Learning for Large Vision-Language Models | | - |
Pruning
| Year | Title | Paper | Github |
|---|---|---|---|
| 2024.10 | Is C4 Dataset Optimal for Pruning? An Investigation of Calibration Data for LLM Pruning | | |
| 2025.07 | SafePTR: Token-Level Jailbreak Defense in Multimodal LLMs via Prune-then-Restore Mechanism | | |
| 2023.11 | Investigating Hallucinations in Pruned Large Language Models for Abstractive Summarization | | |
| 2025.03 | Attention Pruning: Automated Fairness Repair of Language Models via Surrogate Simulated Annealing | | - |
| 2025.05 | Exploring Federated Pruning for Large Language Models | | |
| 2024.01 | Pruning for Protection: Increasing Jailbreak Resistance in Aligned LLMs Without Fine-Tuning | | - |
| 2023.07 | Measuring Faithfulness in Chain-of-Thought Reasoning | | - |
| 2025.05 | Hierarchical Safety Realignment: Lightweight Restoration of Safety in Pruned Large Vision-Language Models | | |
| 2025.02 | Modality-Aware Neuron Pruning for Unlearning in Multimodal Large Language Models | | |
| 2025.02 | Breaking Down Bias: On The Limits of Generalizable Pruning Strategies | | - |
| 2024.03 | Dissecting Language Models: Machine Unlearning via Selective Pruning | | |
| 2024.12 | Lightweight Safety Classification Using Pruned Language Models | | - |
| 2024.02 | Assessing the Brittleness of Safety Alignment via Pruning and Low-Rank Modifications | | |
| 2024.12 | NLSR: Neuron-Level Safety Realignment of Large Language Models Against Harmful Fine-Tuning | | |
| 2023.12 | Fairness-Aware Structured Pruning in Transformers | | |
| 2025.02 | Activation Approximations Can Incur Safety Vulnerabilities Even in Aligned LLMs: Comprehensive Analysis and Defense | | |
| 2025.01 | Understanding and Enhancing Safety Mechanisms of LLMs via Safety-Specific Neuron | | |
Tier 3: System-Level Orchestration
Multi-Agent Systems
| Year | Title | Paper | Github |
|---|---|---|---|
| 2023.05 | Improving Factuality and Reasoning in Language Models through Multiagent Debate | | |
| 2024.02 | Debating with More Persuasive LLMs Leads to More Truthful Answers | | |
| 2024.06 | Towards Detecting LLMs Hallucination via Markov Chain-based Multi-agent Debate Framework | | - |
| 2025.06 | RedDebate: Safer Responses through Multi-Agent Red Teaming Debates | | |
| 2024.10 | Towards Implicit Bias Detection and Mitigation in Multi-Agent LLM Interactions | | |
| 2024.06 | Counterfactual Debating with Preset Stances for Hallucination Elimination of LLMs | | |
| 2025.05 | An Adversary-Resistant Multi-Agent LLM System via Credibility Scoring | | - |
| 2025.05 | PeerGuard: Defending Multi-Agent Systems Against Backdoor Attacks Through Mutual Reasoning | | |
| 2024.02 | Don't Hallucinate, Abstain: Identifying LLM Knowledge Gaps via Multi-LLM Collaboration | | |
| 2025.02 | Red-Teaming LLM Multi-Agent Systems via Communication Attacks | | - |
| 2026.03 | Emergent Social Intelligence Risks in Generative Multi-Agent Systems | | - |
| 2025.05 | Multiple LLM Agents Debate for Equitable Cultural Alignment | | |
| 2024.02 | Can LLMs Produce Faithful Explanations For Fact-Checking? Towards Faithful Explainable Fact-Checking via Multi-Agent Debate | | |
| 2025.08 | 1-2-3 Check: Enhancing Contextual Privacy in LLM via Multi-Agent Reasoning | | |
| 2025.03 | A Multi-Agent Framework with Automated Decision Rule Optimization for Cross-Domain Misinformation Detection | | - |
| 2024.09 | A Multi-LLM Debiasing Framework | | - |
| 2025.04 | Amplified Vulnerabilities: Structured Jailbreak Attacks on LLM-based Multi-Agent Debate | | - |
| 2024.08 | Audit-LLM: Multi-Agent Collaboration for Log-based Insider Threat Detection | | - |
| 2023.08 | Towards CausalGPT: A Multi-Agent Approach for Faithful Knowledge Reasoning via Promoting Causal Consistency in LLMs | | - |
| 2024.04 | White Men Lead, Black Women Help? Benchmarking and Mitigating Language Agency Social Biases in LLMs | | |
| 2025.03 | MAMM-Refine: A Recipe for Improving Faithfulness in Generation with Multi-Agent Collaboration | | |
| 2025.09 | Which Cultural Lens Do Models Adopt? On Cultural Positioning Bias and Agentic Mitigation in LLMs | | - |
| 2025.05 | IP Leakage Attacks Targeting LLM-Based Multi-Agent Systems | | - |
| 2024.04 | Confidence Calibration and Rationalization for LLMs via Multi-Agent Deliberation | | |
| 2024.03 | AutoDefense: Multi-Agent LLM Defense against Jailbreak Attacks | | |
| 2024.01 | PsySafe: A Comprehensive Framework for Psychological-based Attack, Defense, and Evaluation of Multi-agent System Safety | | |
| 2025.05 | GUARDIAN: Safeguarding LLM Multi-Agent Collaborations with Temporal Graph Modeling | | |
| 2025.05 | MASTER: Multi-Agent Security Through Exploration of Roles and Topological Structures | | - |
Evaluation
| Year | Title | Paper | Github |
|---|---|---|---|
| 2023.06 | TrustGPT: A Benchmark for Trustworthy and Responsible Large Language Models | | |
| 2025.04 | TrustEval: A Dynamic Evaluation Toolkit on Trustworthiness of Generative Foundation Models | | |
| 2024.10 | Justice or Prejudice? Quantifying Biases in LLM-as-a-Judge | | |
| 2023.06 | Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena | | |
| 2024.04 | AEGIS: Online Adaptive AI Content Safety Moderation with Ensemble of LLM Experts | | - |
| 2024.06 | WildGuard: Open One-Stop Moderation Tools for Safety Risks, Jailbreaks, and Refusals of LLMs | | |
| 2025.06 | SoK: Evaluating Jailbreak Guardrails for Large Language Models | | |
| 2024.02 | SafeDecoding: Defending against Jailbreak Attacks via Safety-Aware Decoding | | |
| 2024.06 | SafeAligner: Safety Alignment against Jailbreak Attacks via Response Disparity Guidance | | |
| 2024.10 | Root Defence Strategies: Ensuring Safety of LLM at the Decoding Level | | |
| 2023.06 | Inference-Time Intervention: Eliciting Truthful Answers from a Language Model | | |
| 2024.01 | InferAligner: Inference-Time Alignment for Harmlessness through Cross-Model Guidance | | |
| 2025.01 | GuardReasoner: Towards Reasoning-based LLM Safeguards | | |
| 2024.12 | Granite Guardian | | |
| 2024.02 | Assessing the Brittleness of Safety Alignment via Pruning and Low-Rank Modifications | | |
| 2025.03 | Attention Pruning: Automated Fairness Repair of Language Models via Surrogate Simulated Annealing | | - |
| 2025.05 | Guard: Generation-Time LLM Unlearning via Adaptive Restriction and Detection | | - |
| 2023.10 | In-Context Unlearning: Language Models as Few Shot Unlearners | | |
| 2024.07 | From Theft to Bomb-Making: The Ripple Effect of Unlearning in Defending Against Jailbreak Attacks | | |
| 2025.05 | GUARDIAN: Safeguarding LLM Multi-Agent Collaborations with Temporal Graph Modeling | | |
| 2024.04 | Confidence Calibration and Rationalization for LLMs via Multi-Agent Deliberation | | |
| 2025.06 | RedDebate: Safer Responses through Multi-Agent Red Teaming Debates | | |
| 2025.05 | PeerGuard: Defending Multi-Agent Systems Against Backdoor Attacks Through Mutual Reasoning | | |
| 2025.07 | SafePTR: Token-Level Jailbreak Defense in Multimodal LLMs via Prune-then-Restore Mechanism | | |
| 2025.07 | PII Jailbreaking in LLMs via Activation Steering Reveals Personal Information Leakage | | - |
| 2024.10 | Mitigating Gender Bias in Code Large Language Models via Model Editing | | - |
| 2025.06 | Saffron-1: Towards an Inference Scaling Paradigm for LLM Safety Assurance | | |
🌟 Acknowledgments
We thank all the researchers who contributed to this field. This list is maintained by the authors. If you find any missing papers or errors, please open an issue.
✨ Star History
Similar repos
Contributors
10 commits
3 commits