Official Code implementation of "Flex-Judge: Text-Only Reasoning Unleashes Zero-Shot Multimodal Evaluators"
See the code
 Flex-Judge Official Repository

Flex-Judge: Text-Only Reasoning Unleashes Zero-Shot Multimodal Evaluators (NeurIPS 2025)
Jongwoo Ko1*,
Sungnyun Kim2*,
Sungwoo Cho2,
Se-Young Yun2
1 Microsoft, 2 KAIST AI, * equal contribution
Our training codebase is built upon the s1 repo. The following steps will guide you through the installation process.
First, create a conda virtual environment using:
conda create -n flex python=3.9 && conda activate flex
You can then install the remaining package dependencies of s1 as follows:
pip install -r requirements.txt
If you want to train Flex-Omni-7B, you’ll need to install a specific version of transformers released for Qwen2.5-Omni-7B,
pip uninstall transformers
pip install git+https://github.com/huggingface/[email protected]
pip install accelerate
You will also need Flash Attention 2 installed, which can be done by running:
python -m pip install flash-attn --no-build-isolation
python utils/judgelrm_generation.py --seed 13 --temperature 0.1
python lrm_process.py
You should select the training samples based on longer reasoning and by considering format divergence. We have also attached the final data in data/train.jsonl.
We provide four training config files for the four training setups reported in our paper. The training config is set for 2xA6000 or 4xA6000 GPUs. You may need to adjust num_processes and per_device_train_batch_size based on your computation environment.
bash train/vl.sh
bash train/omni.sh
For our evaluation benchmark, we use MLLM-as-a-Judge, VL-RewardBench, MJ-Bench, and GenAI-Bench for vision tasks. All responses are generated using vLLM.
To run Flex-VL-7B, create a conda environment with the latest version of vllm:
conda create -n vllm python=3.11 && conda activate vllm
pip install vllm==0.8.5
To run Flex-Omni-7B -- which is used for audio tasks such as NISQA, BVCC, SOMOS, and VoxSim, and is also compatible with vision tasks -- create a separate environment named vllm-omni:
conda create -n vllm-omni python=3.11 && conda activate vllm-omni
pip install git+https://github.com/huggingface/[email protected]
pip install vllm==0.8.5
python test/{benchmark}_vllm.py --ckpt $CKPT --split $SPLIT
For example, you can generate judge results for image edition task of GenAI-Bench as follows:
python test/genai_bench_vllm.py --ckpt ckpts/vl --split editing
or, for NISQA speech quality assessment:
python test/nisqa_vllm.py --ckpt ckpts/omni --root /path/to/nisqa
python test/evaluate.py --benchmark genai_bench --model ckpts/vl --split editing
Change benchmark to evaluate on other benchmarks.
Here are the resources for evaluation benchamarks such as MLLM-as-a-Judge, MJ-Bench, GenAI-Bench, as follows:
MLLM-as-a-Judge: Please refer to the MLLM-as-a-Judge repo for evaluation.
VL-RewardBench: Please refer to to the VL-RewardBench huggingface for evaluation.
MJ-Bench: Please refer to the MJ-Bench huggingface for evaluation.
GenAI-Bench: Please refer to the GenAI-Bench huggingface for evaluation.
Audio benchmarks: Please refer to the ByteDance/SALMONN repo for data setup and evaluation.
Disclaimer: We're currently fixing our code for VL-RewardBench and MJ-Bench as the original datasets have recently been changed.
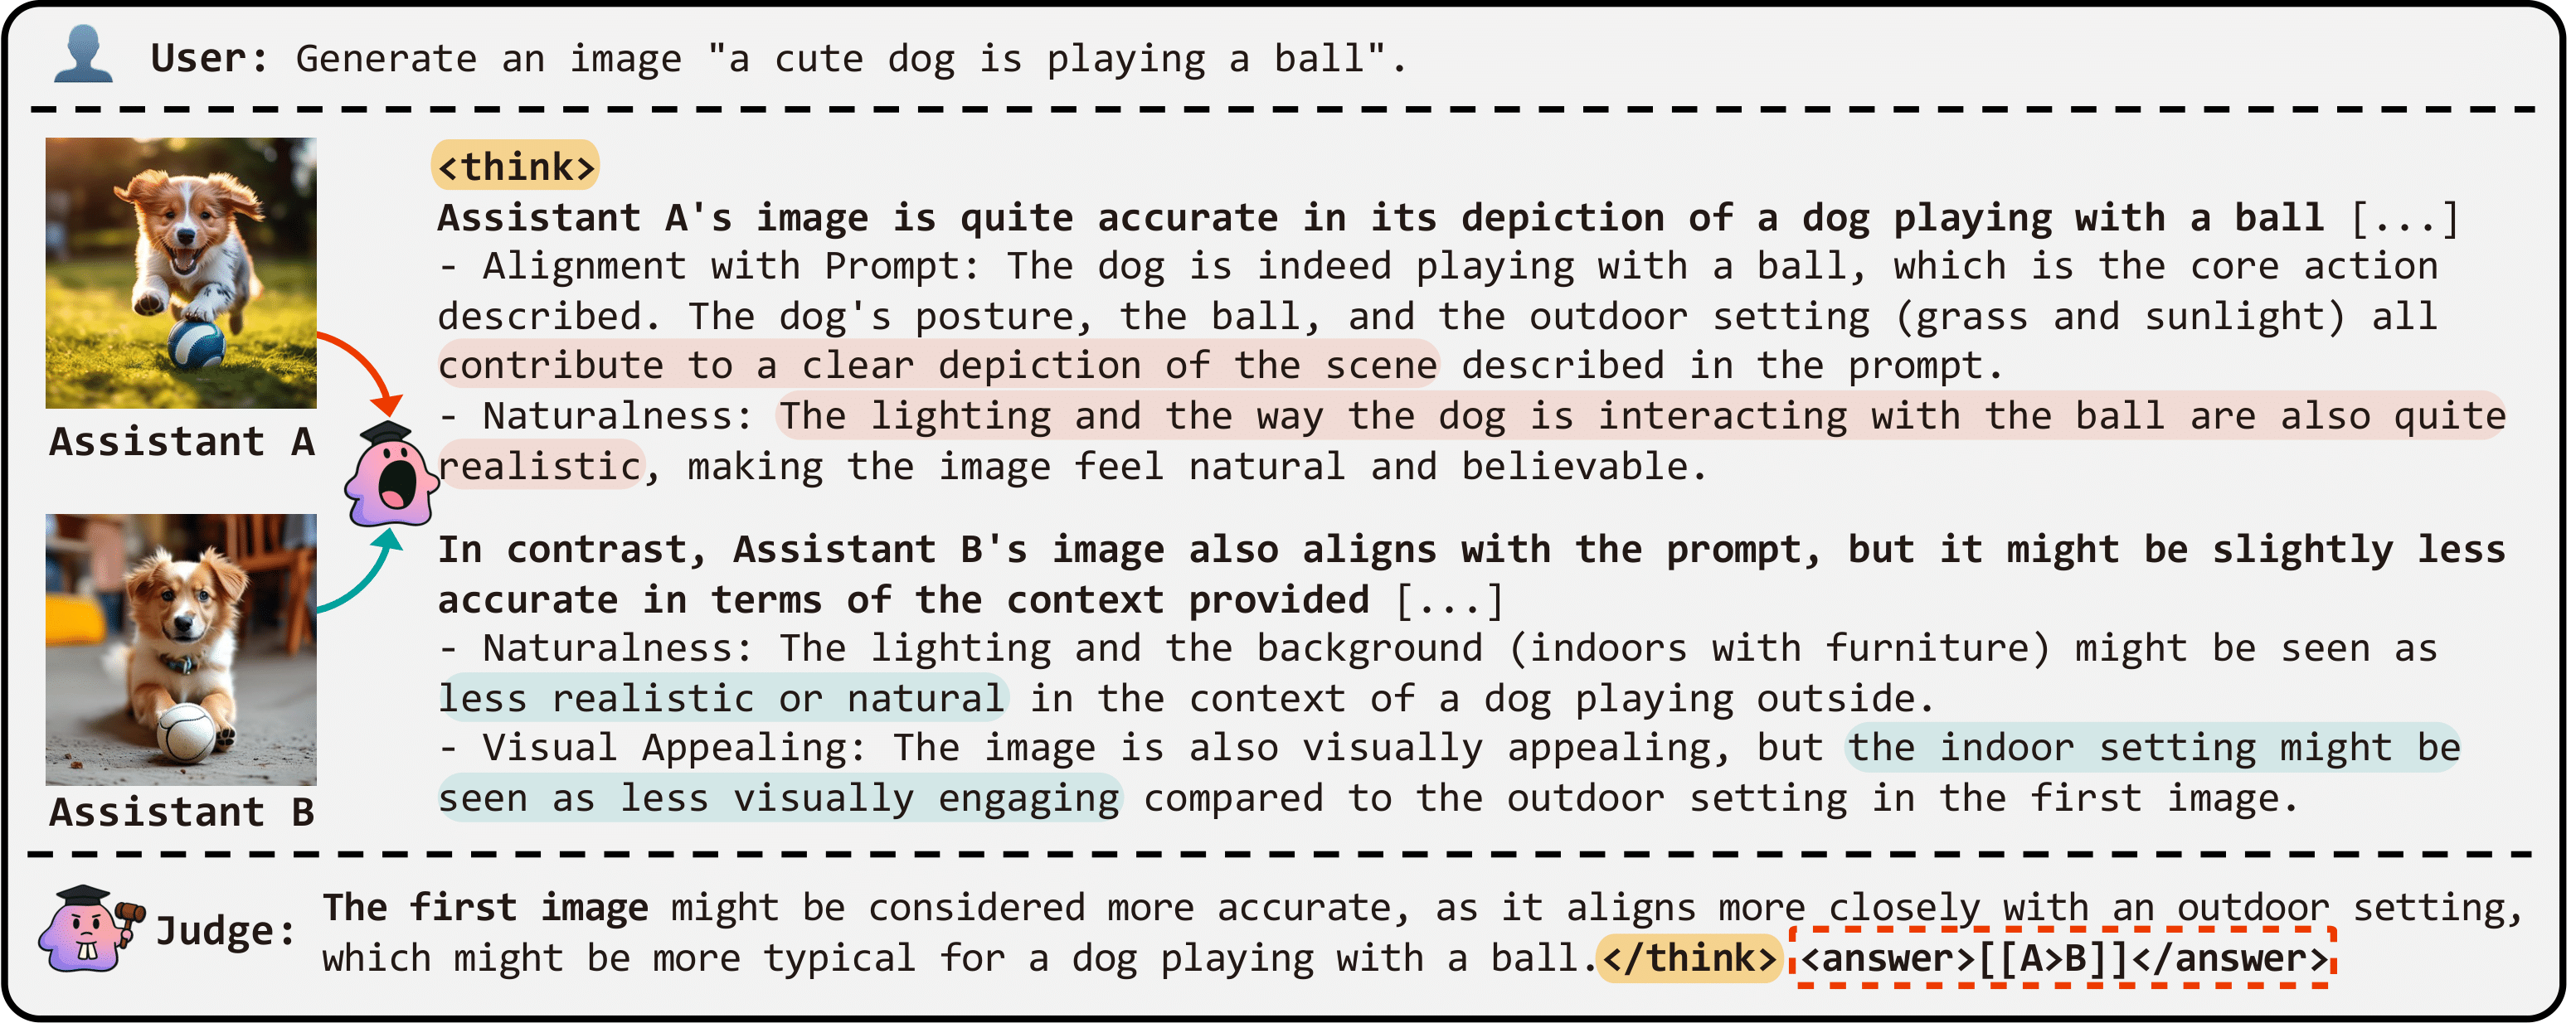
example/README.md.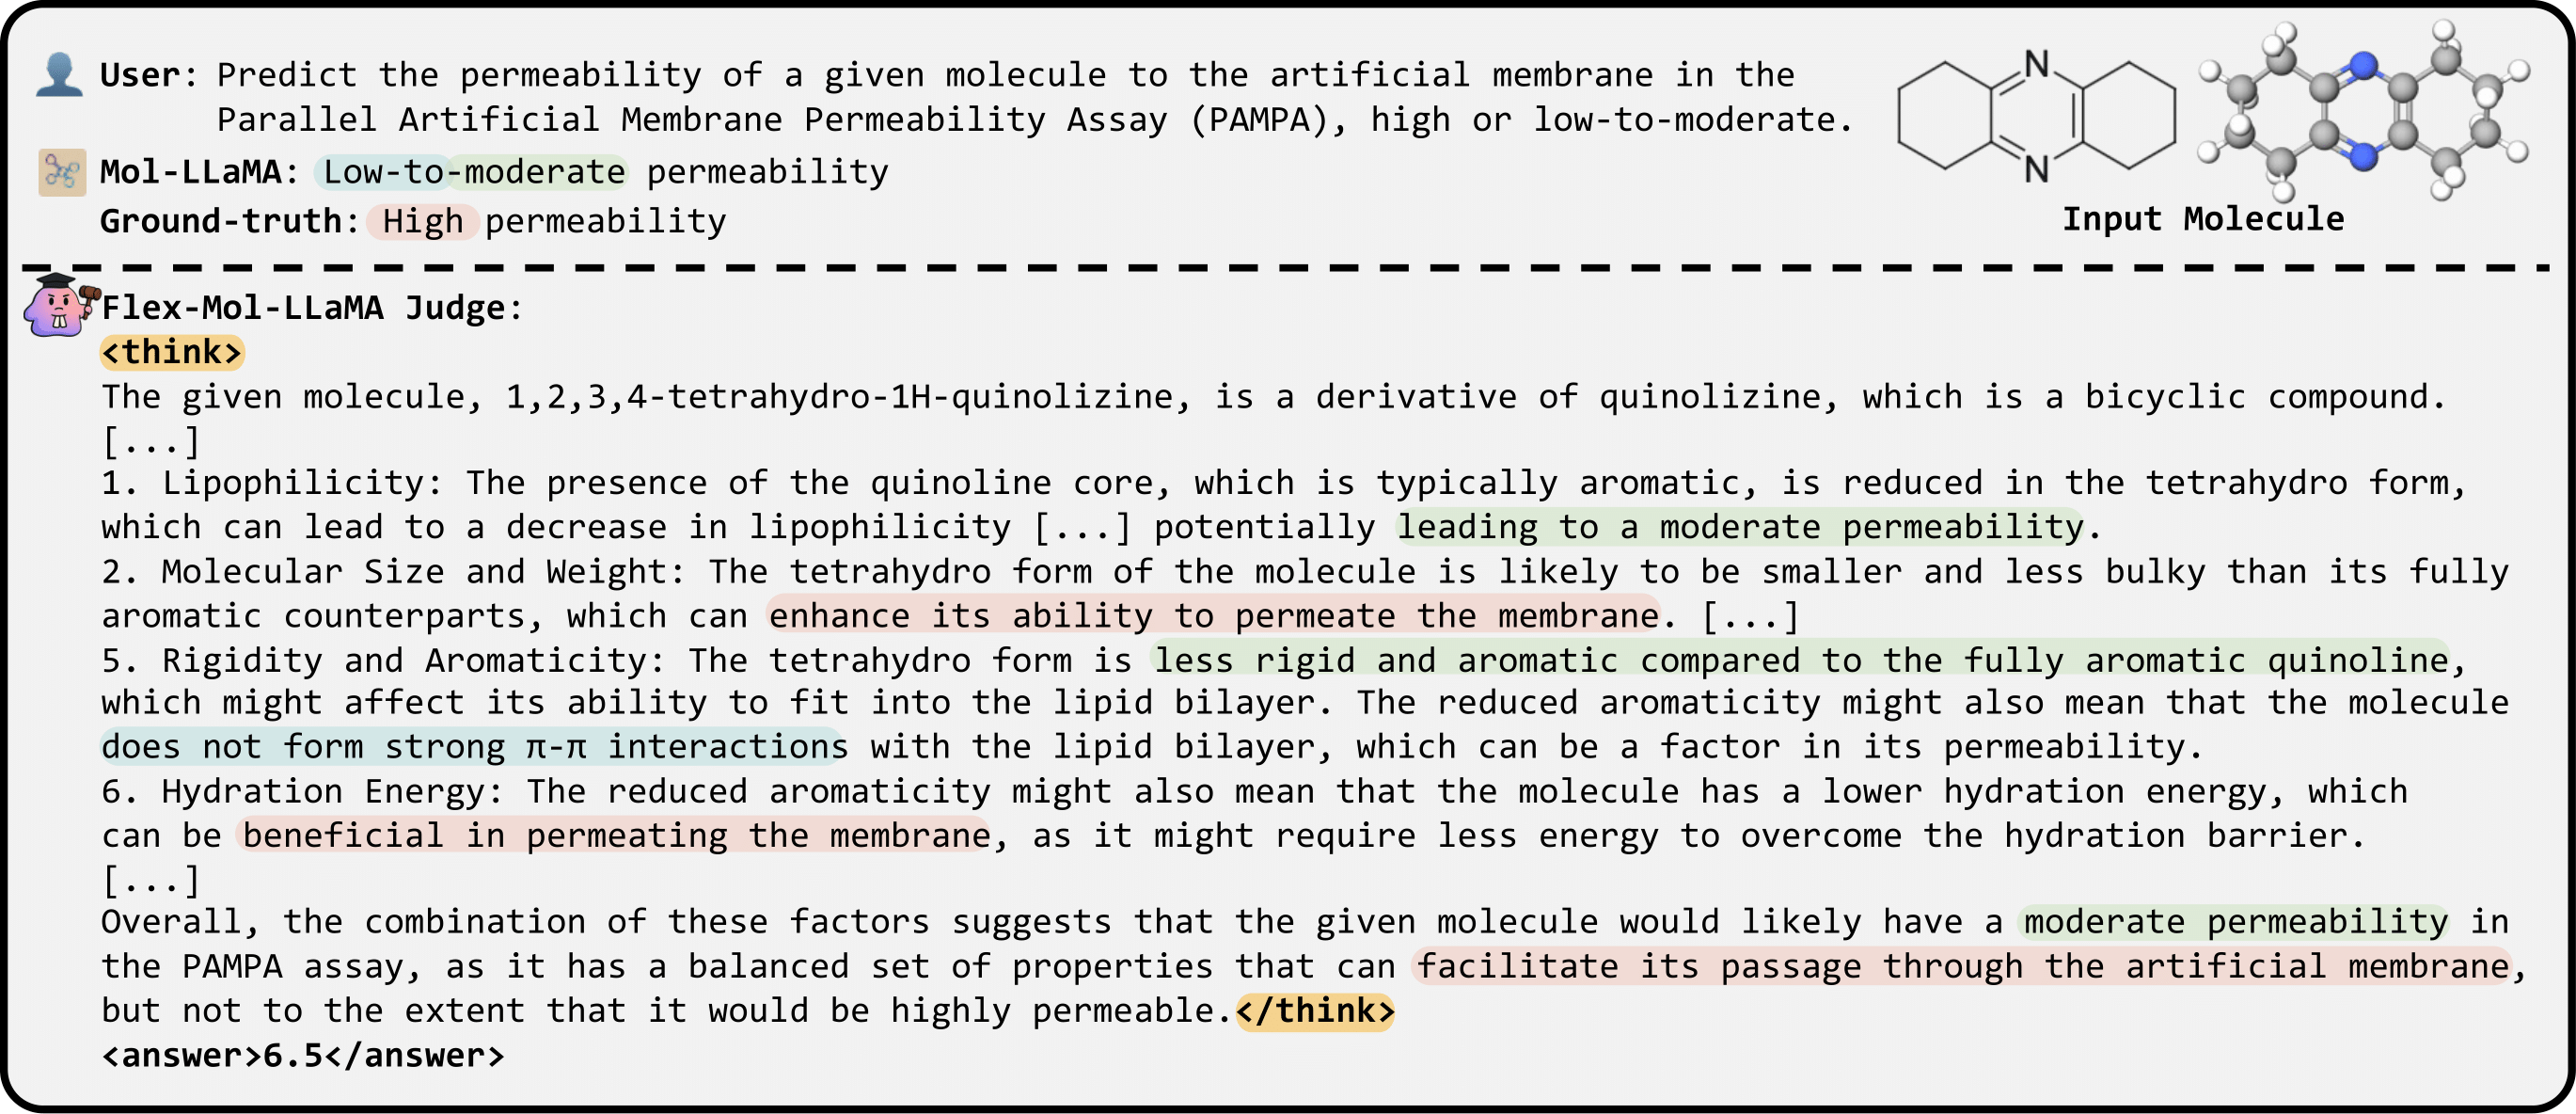
If you find this repo useful for your research, please consider citing our paper:
@article{ko2025flex,
  title={Flex-Judge: Text-Only Reasoning Unleashes Zero-Shot Multimodal Evaluators},
  author={Ko, Jongwoo and Kim, Sungnyun and Cho, Sungwoo and Yun, Se-Young},
  journal={arXiv preprint arXiv:2505.18601},
  year={2025}
}
Official Code implementation of "Flex-Judge: Text-Only Reasoning Unleashes Zero-Shot Multimodal Evaluators"
See the code Flex-Judge Official Repository
Flex-Judge: Text-Only Reasoning Unleashes Zero-Shot Multimodal Evaluators (NeurIPS 2025)
Jongwoo Ko1*,
Sungnyun Kim2*,
Sungwoo Cho2,
Se-Young Yun2
1 Microsoft, 2 KAIST AI, * equal contribution
Our training codebase is built upon the s1 repo. The following steps will guide you through the installation process.
First, create a conda virtual environment using:
conda create -n flex python=3.9 && conda activate flex
You can then install the remaining package dependencies of s1 as follows:
pip install -r requirements.txt
If you want to train Flex-Omni-7B, you’ll need to install a specific version of transformers released for Qwen2.5-Omni-7B,
pip uninstall transformers
pip install git+https://github.com/huggingface/[email protected]
pip install accelerate
You will also need Flash Attention 2 installed, which can be done by running:
python -m pip install flash-attn --no-build-isolation
python utils/judgelrm_generation.py --seed 13 --temperature 0.1
python lrm_process.py
You should select the training samples based on longer reasoning and by considering format divergence. We have also attached the final data in data/train.jsonl.
We provide four training config files for the four training setups reported in our paper. The training config is set for 2xA6000 or 4xA6000 GPUs. You may need to adjust num_processes and per_device_train_batch_size based on your computation environment.
bash train/vl.sh
bash train/omni.sh
For our evaluation benchmark, we use MLLM-as-a-Judge, VL-RewardBench, MJ-Bench, and GenAI-Bench for vision tasks. All responses are generated using vLLM.
To run Flex-VL-7B, create a conda environment with the latest version of vllm:
conda create -n vllm python=3.11 && conda activate vllm
pip install vllm==0.8.5
To run Flex-Omni-7B -- which is used for audio tasks such as NISQA, BVCC, SOMOS, and VoxSim, and is also compatible with vision tasks -- create a separate environment named vllm-omni:
conda create -n vllm-omni python=3.11 && conda activate vllm-omni
pip install git+https://github.com/huggingface/[email protected]
pip install vllm==0.8.5
python test/{benchmark}_vllm.py --ckpt $CKPT --split $SPLIT
For example, you can generate judge results for image edition task of GenAI-Bench as follows:
python test/genai_bench_vllm.py --ckpt ckpts/vl --split editing
or, for NISQA speech quality assessment:
python test/nisqa_vllm.py --ckpt ckpts/omni --root /path/to/nisqa
python test/evaluate.py --benchmark genai_bench --model ckpts/vl --split editing
Change benchmark to evaluate on other benchmarks.
Here are the resources for evaluation benchamarks such as MLLM-as-a-Judge, MJ-Bench, GenAI-Bench, as follows:
MLLM-as-a-Judge: Please refer to the MLLM-as-a-Judge repo for evaluation.
VL-RewardBench: Please refer to to the VL-RewardBench huggingface for evaluation.
MJ-Bench: Please refer to the MJ-Bench huggingface for evaluation.
GenAI-Bench: Please refer to the GenAI-Bench huggingface for evaluation.
Audio benchmarks: Please refer to the ByteDance/SALMONN repo for data setup and evaluation.
Disclaimer: We're currently fixing our code for VL-RewardBench and MJ-Bench as the original datasets have recently been changed.
example/README.md.
If you find this repo useful for your research, please consider citing our paper:
@article{ko2025flex,
  title={Flex-Judge: Text-Only Reasoning Unleashes Zero-Shot Multimodal Evaluators},
  author={Ko, Jongwoo and Kim, Sungnyun and Cho, Sungwoo and Yun, Se-Young},
  journal={arXiv preprint arXiv:2505.18601},
  year={2025}
}






