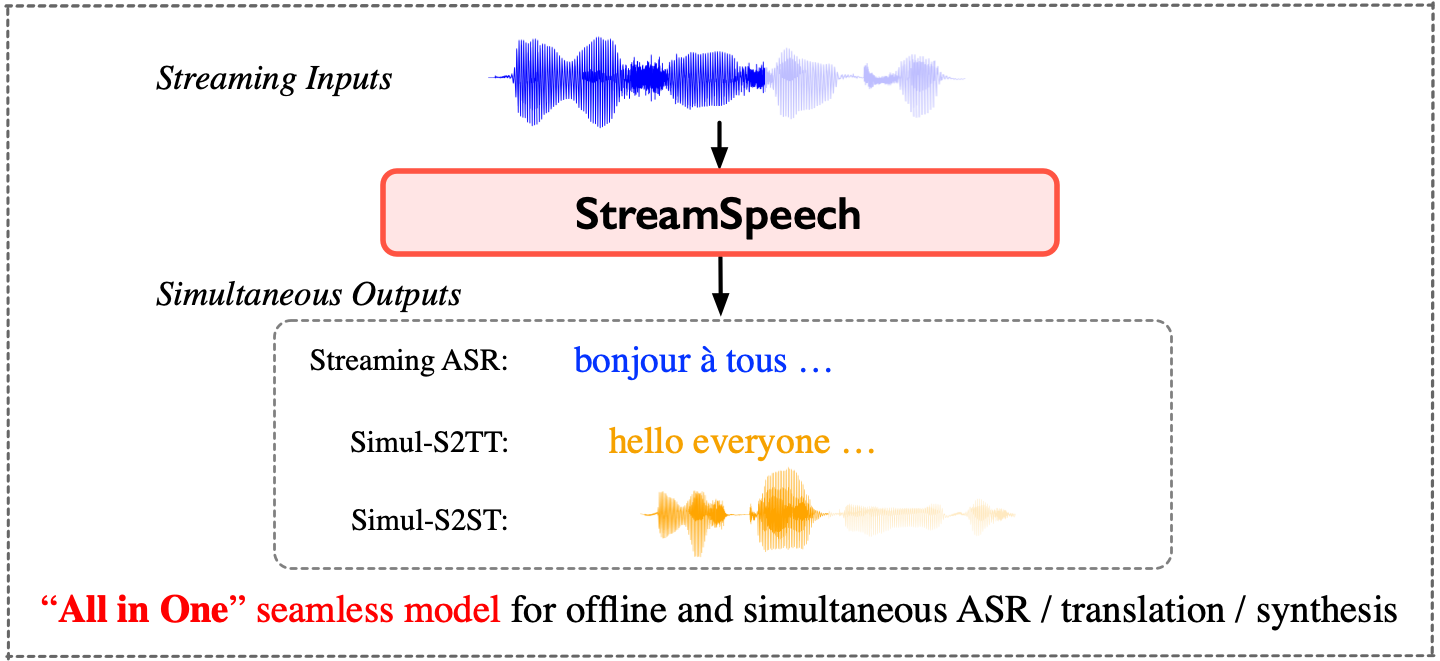
StreamSpeech is an “All in One” seamless model for offline and simultaneous speech recognition, speech translation and speech synthesis.
See the code


Authors: Shaolei Zhang, Qingkai Fang, Shoutao Guo, Zhengrui Ma, Min Zhang, Yang Feng*
Code for ACL 2024 paper "StreamSpeech: Simultaneous Speech-to-Speech Translation with Multi-task Learning".
🎧 Listen to StreamSpeech's translated speech 🎧
💡Highlight:
[2025.06.17] We are excited to extend the "All-in-One" feature of StreamSpeech to more general multimodal interactions via developing Stream-Omni. 👉Refer to paper, code & demo, model for more details.
[2024.06.17] Add Web GUI demo, now you can experience StreamSpeech in your local browser.
[2024.06.05] Paper, code, models and demo of StreamSpeech are available!
https://github.com/ictnlp/StreamSpeech/assets/34680227/4d9bdabf-af66-4320-ae7d-0f23e721cd71
Simultaneously provide ASR, translation, and synthesis results via a seamless model
Speech Input: example/wavs/common_voice_fr_17301936.mp3
Transcription (ground truth): jai donc lexpérience des années passées jen dirai un mot tout à lheure
Translation (ground truth): i therefore have the experience of the passed years i'll say a few words about that later
| StreamSpeech | Simultaneous | Offline |
|---|---|---|
| Speech Recognition | jai donc expérience des années passé jen dirairai un mot tout à lheure | jai donc lexpérience des années passé jen dirairai un mot tout à lheure |
| Speech-to-Text Translation | i therefore have an experience of last years i will tell a word later | so i have the experience in the past years i'll say a word later |
| Speech-to-Speech Translation | ||
| Text-to-Speech Synthesis (incrementally synthesize speech word by word) |
Python == 3.10, PyTorch == 2.0.1, Install fairseq & SimulEval
cd fairseq
pip install --editable ./ --no-build-isolation
cd SimulEval
pip install --editable ./
| Language | UnitY | StreamSpeech (offline) | StreamSpeech (simultaneous) |
|---|---|---|---|
| Fr-En | unity.fr-en.pt [Huggingface] [Baidu] | streamspeech.offline.fr-en.pt [Huggingface] [Baidu] | streamspeech.simultaneous.fr-en.pt [Huggingface] [Baidu] |
| Es-En | unity.es-en.pt [Huggingface] [Baidu] | streamspeech.offline.es-en.pt [Huggingface] [Baidu] | streamspeech.simultaneous.es-en.pt [Huggingface] [Baidu] |
| De-En | unity.de-en.pt [Huggingface] [Baidu] | streamspeech.offline.de-en.pt [Huggingface] [Baidu] | streamspeech.simultaneous.de-en.pt [Huggingface] [Baidu] |
Replace /data/zhangshaolei/StreamSpeech in files configs/fr-en/config_gcmvn.yaml and configs/fr-en/config_mtl_asr_st_ctcst.yaml with your local address of StreamSpeech repo.
Prepare test data following SimulEval format. example/ provides an example:
Run these scripts to inference StreamSpeech on streaming ASR, simultaneous S2TT and simultaneous S2ST.
--source-segment-size: set the chunk size (millisecond) to any value to control the latency
--output-asr-translation: whether to output the intermediate ASR and translated text results during simultaneous speech-to-speech translation.
export CUDA_VISIBLE_DEVICES=0

ROOT=/data/zhangshaolei/StreamSpeech # path to StreamSpeech repo
PRETRAIN_ROOT=/data/zhangshaolei/pretrain_models
VOCODER_CKPT=$PRETRAIN_ROOT/unit-based_HiFi-GAN_vocoder/mHuBERT.layer11.km1000.en/g_00500000 # path to downloaded Unit-based HiFi-GAN Vocoder
VOCODER_CFG=$PRETRAIN_ROOT/unit-based_HiFi-GAN_vocoder/mHuBERT.layer11.km1000.en/config.json # path to downloaded Unit-based HiFi-GAN Vocoder

LANG=fr
file=streamspeech.simultaneous.${LANG}-en.pt # path to downloaded StreamSpeech model
output_dir=$ROOT/res/streamspeech.simultaneous.${LANG}-en/simul-s2st

chunk_size=320 #ms
PYTHONPATH=$ROOT/fairseq simuleval --data-bin ${ROOT}/configs/${LANG}-en \
    --user-dir ${ROOT}/researches/ctc_unity --agent-dir ${ROOT}/agent \
    --source example/wav_list.txt --target example/target.txt \
    --model-path $file \
    --config-yaml config_gcmvn.yaml --multitask-config-yaml config_mtl_asr_st_ctcst.yaml \
    --agent $ROOT/agent/speech_to_speech.streamspeech.agent.py \
    --vocoder $VOCODER_CKPT --vocoder-cfg $VOCODER_CFG --dur-prediction \
    --output $output_dir/chunk_size=$chunk_size \
    --source-segment-size $chunk_size \
    --quality-metrics ASR_BLEU  --target-speech-lang en --latency-metrics AL AP DAL StartOffset EndOffset LAAL ATD NumChunks DiscontinuitySum DiscontinuityAve DiscontinuityNum RTF \
    --device gpu --computation-aware \
    --output-asr-translation True
You should get the following outputs:
fairseq plugins loaded...
fairseq plugins loaded...
fairseq plugins loaded...
fairseq plugins loaded...
2024-06-06 09:45:46 | INFO     | fairseq.tasks.speech_to_speech | dictionary size: 1,004
import agents...
Removing weight norm...
2024-06-06 09:45:50 | INFO     | agent.tts.vocoder | loaded CodeHiFiGAN checkpoint from /data/zhangshaolei/pretrain_models/unit-based_HiFi-GAN_vocoder/mHuBERT.layer11.km1000.en/g_00500000
2024-06-06 09:45:50 | INFO     | simuleval.utils.agent | System will run on device: gpu.
2024-06-06 09:45:50 | INFO     | simuleval.dataloader | Evaluating from speech to speech.
  0%|                                                                                                                                                                              | 0/2 [00:00<?, ?it/s]
Streaming ASR:
Streaming ASR:
Streaming ASR: je
Simultaneous translation: i would
Streaming ASR: je voudrais
Simultaneous translation: i would like to
Streaming ASR: je voudrais soumettre
Simultaneous translation: i would like to sub
Streaming ASR: je voudrais soumettre cette
Simultaneous translation: i would like to submit
Streaming ASR: je voudrais soumettre cette idée
Simultaneous translation: i would like to submit this
Streaming ASR: je voudrais soumettre cette idée à la
Simultaneous translation: i would like to submit this idea to
Streaming ASR: je voudrais soumettre cette idée à la réflexion
Simultaneous translation: i would like to submit this idea to the
Streaming ASR: je voudrais soumettre cette idée à la réflexion de
Simultaneous translation: i would like to submit this idea to the reflection
Streaming ASR: je voudrais soumettre cette idée à la réflexion de lassemblée
Simultaneous translation: i would like to submit this idea to the reflection of
Streaming ASR: je voudrais soumettre cette idée à la réflexion de lassemblée nationale
Simultaneous translation: i would like to submit this idea to the reflection of the
Streaming ASR: je voudrais soumettre cette idée à la réflexion de lassemblée nationale
Simultaneous translation: i would like to submit this idea to the reflection of the national assembly
 50%|███████████████████████████████████████████████████████████████████████████████████                                                                                   | 1/2 [00:04<00:04,  4.08s/it]
Streaming ASR:
Streaming ASR:
Streaming ASR:
Streaming ASR:
Streaming ASR: jai donc
Simultaneous translation: i therefore
Streaming ASR: jai donc
Streaming ASR: jai donc expérience des
Simultaneous translation: i therefore have an experience
Streaming ASR: jai donc expérience des années
Streaming ASR: jai donc expérience des années passé
Simultaneous translation: i therefore have an experience of last
Streaming ASR: jai donc expérience des années passé jen
Simultaneous translation: i therefore have an experience of last years
Streaming ASR: jai donc expérience des années passé jen dirairai
Simultaneous translation: i therefore have an experience of last years i will
Streaming ASR: jai donc expérience des années passé jen dirairai un mot
Simultaneous translation: i therefore have an experience of last years i will tell a
Streaming ASR: jai donc expérience des années passé jen dirairai un mot tout à lheure
Simultaneous translation: i therefore have an experience of last years i will tell a word
Streaming ASR: jai donc expérience des années passé jen dirairai un mot tout à lheure
Simultaneous translation: i therefore have an experience of last years i will tell a word later
100%|██████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 2/2 [00:06<00:00,  3.02s/it]
2024-06-06 09:45:56 | WARNING  | simuleval.scorer.asr_bleu | Beta feature: Evaluating speech output. Faieseq is required.
2024-06-06 09:46:12 | INFO | fairseq.tasks.audio_finetuning | Using dict_path : /data/zhangshaolei/.cache/ust_asr/en/dict.ltr.txt
Transcribing predictions: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 2/2 [00:01<00:00,  1.63it/s]
2024-06-06 09:46:21 | INFO     | simuleval.sentence_level_evaluator | Results:
 ASR_BLEU       AL    AL_CA    AP  AP_CA      DAL  DAL_CA  StartOffset  StartOffset_CA  EndOffset  EndOffset_CA     LAAL  LAAL_CA      ATD   ATD_CA  NumChunks  NumChunks_CA  DiscontinuitySum  DiscontinuitySum_CA  DiscontinuityAve  DiscontinuityAve_CA  DiscontinuityNum  DiscontinuityNum_CA   RTF  RTF_CA
   15.448 1724.895 2913.508 0.425  0.776 1358.812 3137.55       1280.0        2213.906     1366.0        1366.0 1724.895 2913.508 1440.146 3389.374        9.5           9.5             110.0                110.0              55.0                 55.0                 1                    1 1.326   1.326
Logs and evaluation results are stored in $output_dir/chunk_size=$chunk_size:
$output_dir/chunk_size=$chunk_size
├── wavs/
│   ├── 0_pred.wav # generated speech
│   ├── 1_pred.wav
│   ├── 0_pred.txt # asr transcription for ASR-BLEU tookit
│   ├── 1_pred.txt
├── config.yaml
├── asr_transcripts.txt # ASR-BLEU transcription results
├── metrics.tsv
├── scores.tsv
├── asr_cmd.bash
└── instances.log # logs of Simul-S2ST
export CUDA_VISIBLE_DEVICES=0

ROOT=/data/zhangshaolei/StreamSpeech # path to StreamSpeech repo

LANG=fr
file=streamspeech.simultaneous.${LANG}-en.pt # path to downloaded StreamSpeech model
output_dir=$ROOT/res/streamspeech.simultaneous.${LANG}-en/simul-s2tt

chunk_size=320 #ms
PYTHONPATH=$ROOT/fairseq simuleval --data-bin ${ROOT}/configs/${LANG}-en \
    --user-dir ${ROOT}/researches/ctc_unity --agent-dir ${ROOT}/agent \
    --source example/wav_list.txt --target example/target.txt \
    --model-path $file \
    --config-yaml config_gcmvn.yaml --multitask-config-yaml config_mtl_asr_st_ctcst.yaml \
    --agent $ROOT/agent/speech_to_text.s2tt.streamspeech.agent.py\
    --output $output_dir/chunk_size=$chunk_size \
    --source-segment-size $chunk_size \
    --quality-metrics BLEU  --latency-metrics AL AP DAL StartOffset EndOffset LAAL ATD NumChunks RTF \
    --device gpu --computation-aware
export CUDA_VISIBLE_DEVICES=0

ROOT=/data/zhangshaolei/StreamSpeech # path to StreamSpeech repo

LANG=fr
file=streamspeech.simultaneous.${LANG}-en.pt # path to downloaded StreamSpeech model
output_dir=$ROOT/res/streamspeech.simultaneous.${LANG}-en/streaming-asr

chunk_size=320 #ms
PYTHONPATH=$ROOT/fairseq simuleval --data-bin ${ROOT}/configs/${LANG}-en \
    --user-dir ${ROOT}/researches/ctc_unity --agent-dir ${ROOT}/agent \
    --source example/wav_list.txt --target example/source.txt \
    --model-path $file \
    --config-yaml config_gcmvn.yaml --multitask-config-yaml config_mtl_asr_st_ctcst.yaml \
    --agent $ROOT/agent/speech_to_text.asr.streamspeech.agent.py\
    --output $output_dir/chunk_size=$chunk_size \
    --source-segment-size $chunk_size \
    --quality-metrics BLEU  --latency-metrics AL AP DAL StartOffset EndOffset LAAL ATD NumChunks RTF \
    --device gpu --computation-aware
./preprocess_scripts to process CVSS-C data.[!Note] You can directly use the downloaded StreamSpeech model for evaluation and skip training.
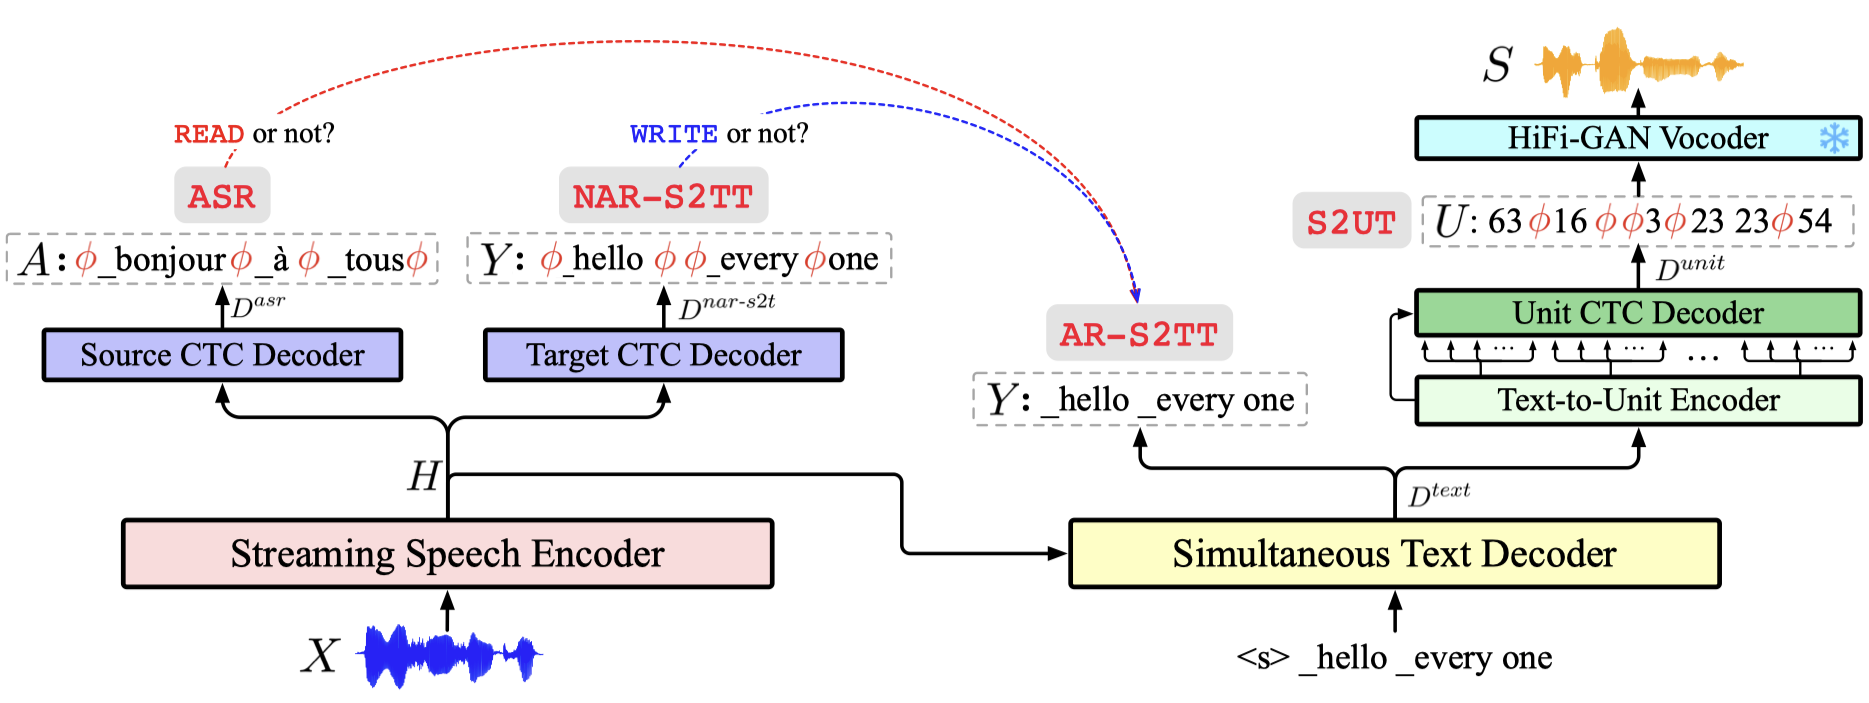
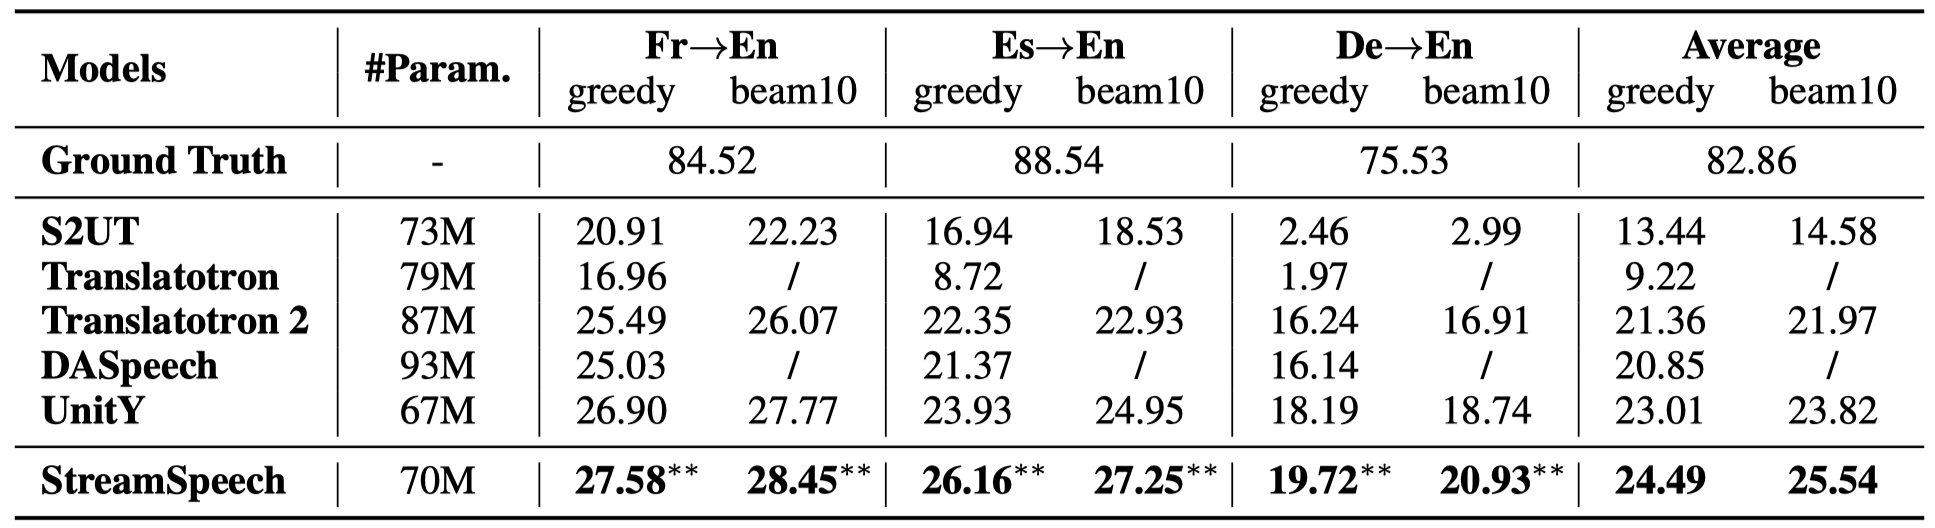
researches/ctc_unity/train_scripts/train.simul-s2st.sh to train StreamSpeech for simultaneous speech-to-speech translation.researches/ctc_unity/train_scripts/train.offline-s2st.sh to train StreamSpeech for offline speech-to-speech translation.| Model | --user-dir | --arch | Description |
|---|---|---|---|
| Translatotron 2 | researches/translatotron | s2spect2_conformer_modified | Translatotron 2 |
| UnitY | researches/translatotron | unity_conformer_modified | UnitY |
| Uni-UnitY | researches/uni_unity | uni_unity_conformer | Change all encoders in UnitY into unidirectional |
| Chunk-UnitY | researches/chunk_unity | chunk_unity_conformer | Change the Conformer in UnitY into Chunk-based Conformer |
| StreamSpeech | researches/ctc_unity | streamspeech | StreamSpeech |
| StreamSpeech (cascade) | researches/ctc_unity | streamspeech_cascade | Cascaded StreamSpeech of S2TT and TTS. TTS module can be used independently for real-time TTS given incremental text. |
| HMT | researches/hmt | hmt_transformer_iwslt_de_en | HMT: strong simultaneous text-to-text translation method |
| DiSeg | researches/diseg | convtransformer_espnet_base_seg | DiSeg: strong simultaneous speech-to-text translation method |
[!Tip] The
train_scripts/andtest_scripts/in directory--user-dirgive the training and testing scripts for each model. Refer to official repo of UnitY, Translatotron 2, HMT and DiSeg for more details.
Follow pred.offline-s2st.sh to evaluate the offline performance of StreamSpeech on ASR, S2TT and S2ST.
A trained StreamSpeech model can be used for streaming ASR, simultaneous speech-to-text translation and simultaneous speech-to-speech translation. We provide agent/ for these three tasks:
agent/speech_to_speech.streamspeech.agent.py: simultaneous speech-to-speech translationagent/speech_to_text.s2tt.streamspeech.agent.py: simultaneous speech-to-text translationagent/speech_to_text.asr.streamspeech.agent.py: streaming ASRFollow simuleval.simul-s2st.sh, simuleval.simul-s2tt.sh, simuleval.streaming-asr.sh to evaluate StreamSpeech.
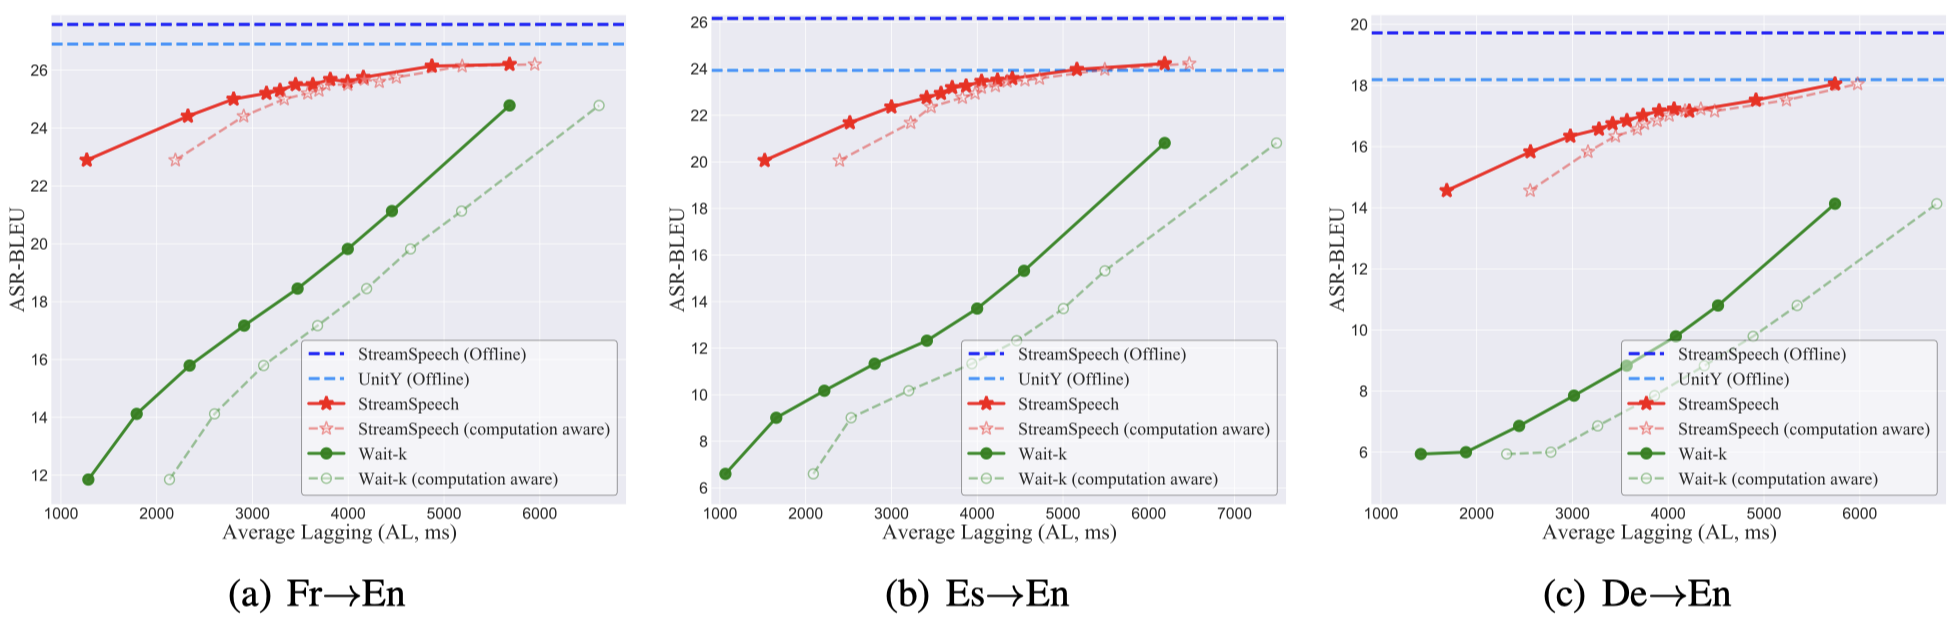
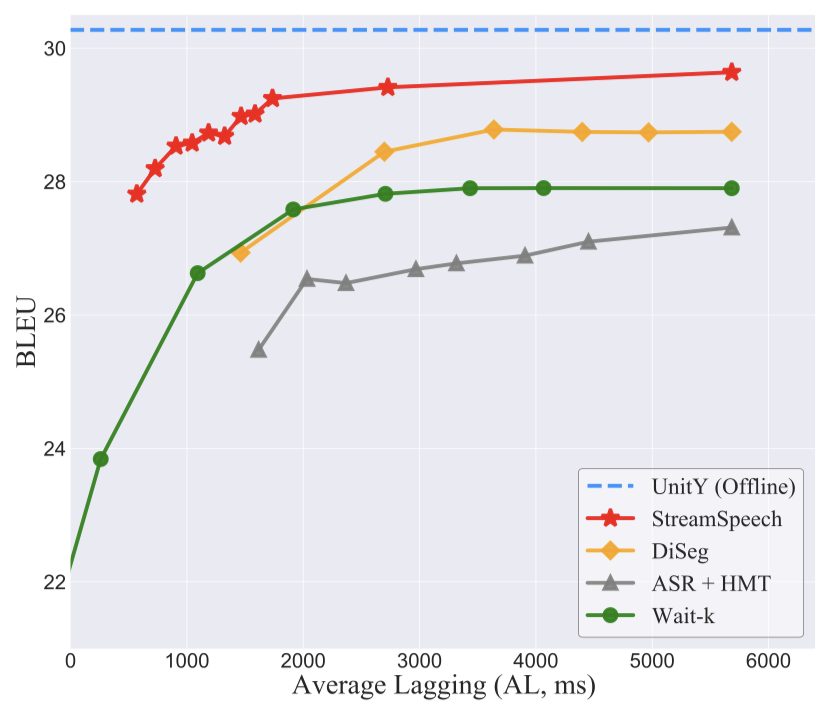
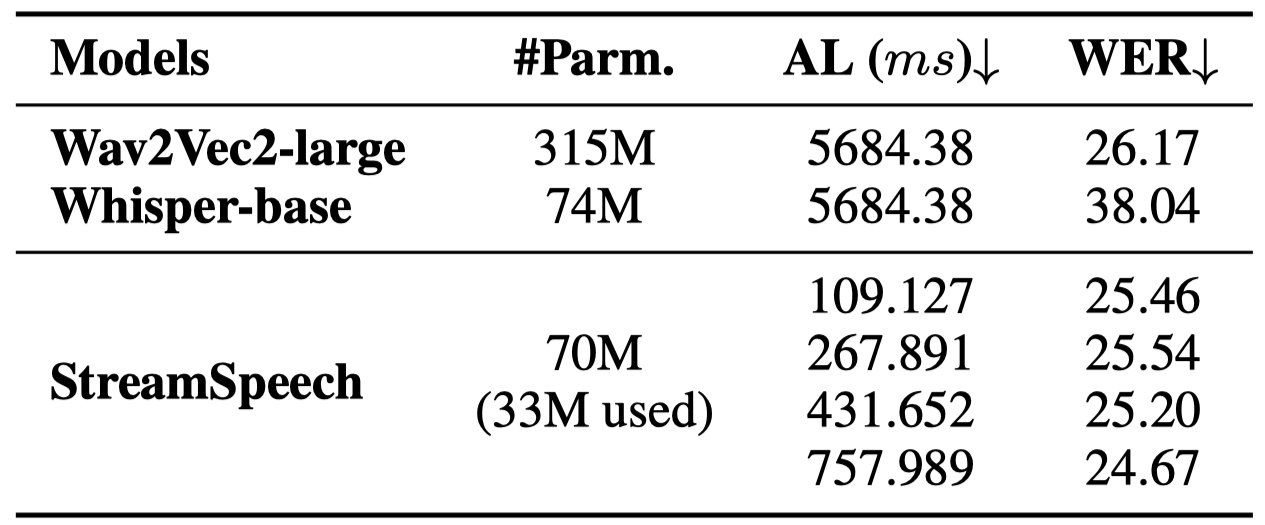
Our project page (https://ictnlp.github.io/StreamSpeech-site/) provides some translated speech generated by StreamSpeech, listen to it 🎧.
If you have any questions, please feel free to submit an issue or contact [email protected].
If our work is useful for you, please cite as:
@inproceedings{streamspeech,
      title={StreamSpeech: Simultaneous Speech-to-Speech Translation with Multi-task Learning},
      author={Shaolei Zhang and Qingkai Fang and Shoutao Guo and Zhengrui Ma and Min Zhang and Yang Feng},
      year={2024},
      booktitle = {Proceedings of the 62th Annual Meeting of the Association for Computational Linguistics (Long Papers)},
      publisher = {Association for Computational Linguistics}
}
479 followers · starred Jul 2024
121 followers · starred Jun 2026
200 followers · starred Jun 2024
139 followers · starred Jun 2024
StreamSpeech is an “All in One” seamless model for offline and simultaneous speech recognition, speech translation and speech synthesis.
See the code
Authors: Shaolei Zhang, Qingkai Fang, Shoutao Guo, Zhengrui Ma, Min Zhang, Yang Feng*
Code for ACL 2024 paper "StreamSpeech: Simultaneous Speech-to-Speech Translation with Multi-task Learning".
🎧 Listen to StreamSpeech's translated speech 🎧
💡Highlight:
[2025.06.17] We are excited to extend the "All-in-One" feature of StreamSpeech to more general multimodal interactions via developing Stream-Omni. 👉Refer to paper, code & demo, model for more details.
[2024.06.17] Add Web GUI demo, now you can experience StreamSpeech in your local browser.
[2024.06.05] Paper, code, models and demo of StreamSpeech are available!
https://github.com/ictnlp/StreamSpeech/assets/34680227/4d9bdabf-af66-4320-ae7d-0f23e721cd71
Simultaneously provide ASR, translation, and synthesis results via a seamless model
Speech Input: example/wavs/common_voice_fr_17301936.mp3
Transcription (ground truth): jai donc lexpérience des années passées jen dirai un mot tout à lheure
Translation (ground truth): i therefore have the experience of the passed years i'll say a few words about that later
| StreamSpeech | Simultaneous | Offline |
|---|---|---|
| Speech Recognition | jai donc expérience des années passé jen dirairai un mot tout à lheure | jai donc lexpérience des années passé jen dirairai un mot tout à lheure |
| Speech-to-Text Translation | i therefore have an experience of last years i will tell a word later | so i have the experience in the past years i'll say a word later |
| Speech-to-Speech Translation | ||
| Text-to-Speech Synthesis (incrementally synthesize speech word by word) |
Python == 3.10, PyTorch == 2.0.1, Install fairseq & SimulEval
cd fairseq
pip install --editable ./ --no-build-isolation
cd SimulEval
pip install --editable ./
| Language | UnitY | StreamSpeech (offline) | StreamSpeech (simultaneous) |
|---|---|---|---|
| Fr-En | unity.fr-en.pt [Huggingface] [Baidu] | streamspeech.offline.fr-en.pt [Huggingface] [Baidu] | streamspeech.simultaneous.fr-en.pt [Huggingface] [Baidu] |
| Es-En | unity.es-en.pt [Huggingface] [Baidu] | streamspeech.offline.es-en.pt [Huggingface] [Baidu] | streamspeech.simultaneous.es-en.pt [Huggingface] [Baidu] |
| De-En | unity.de-en.pt [Huggingface] [Baidu] | streamspeech.offline.de-en.pt [Huggingface] [Baidu] | streamspeech.simultaneous.de-en.pt [Huggingface] [Baidu] |
Replace /data/zhangshaolei/StreamSpeech in files configs/fr-en/config_gcmvn.yaml and configs/fr-en/config_mtl_asr_st_ctcst.yaml with your local address of StreamSpeech repo.
Prepare test data following SimulEval format. example/ provides an example:
Run these scripts to inference StreamSpeech on streaming ASR, simultaneous S2TT and simultaneous S2ST.
--source-segment-size: set the chunk size (millisecond) to any value to control the latency
--output-asr-translation: whether to output the intermediate ASR and translated text results during simultaneous speech-to-speech translation.
export CUDA_VISIBLE_DEVICES=0

ROOT=/data/zhangshaolei/StreamSpeech # path to StreamSpeech repo
PRETRAIN_ROOT=/data/zhangshaolei/pretrain_models
VOCODER_CKPT=$PRETRAIN_ROOT/unit-based_HiFi-GAN_vocoder/mHuBERT.layer11.km1000.en/g_00500000 # path to downloaded Unit-based HiFi-GAN Vocoder
VOCODER_CFG=$PRETRAIN_ROOT/unit-based_HiFi-GAN_vocoder/mHuBERT.layer11.km1000.en/config.json # path to downloaded Unit-based HiFi-GAN Vocoder

LANG=fr
file=streamspeech.simultaneous.${LANG}-en.pt # path to downloaded StreamSpeech model
output_dir=$ROOT/res/streamspeech.simultaneous.${LANG}-en/simul-s2st

chunk_size=320 #ms
PYTHONPATH=$ROOT/fairseq simuleval --data-bin ${ROOT}/configs/${LANG}-en \
    --user-dir ${ROOT}/researches/ctc_unity --agent-dir ${ROOT}/agent \
    --source example/wav_list.txt --target example/target.txt \
    --model-path $file \
    --config-yaml config_gcmvn.yaml --multitask-config-yaml config_mtl_asr_st_ctcst.yaml \
    --agent $ROOT/agent/speech_to_speech.streamspeech.agent.py \
    --vocoder $VOCODER_CKPT --vocoder-cfg $VOCODER_CFG --dur-prediction \
    --output $output_dir/chunk_size=$chunk_size \
    --source-segment-size $chunk_size \
    --quality-metrics ASR_BLEU  --target-speech-lang en --latency-metrics AL AP DAL StartOffset EndOffset LAAL ATD NumChunks DiscontinuitySum DiscontinuityAve DiscontinuityNum RTF \
    --device gpu --computation-aware \
    --output-asr-translation True
You should get the following outputs:
fairseq plugins loaded...
fairseq plugins loaded...
fairseq plugins loaded...
fairseq plugins loaded...
2024-06-06 09:45:46 | INFO     | fairseq.tasks.speech_to_speech | dictionary size: 1,004
import agents...
Removing weight norm...
2024-06-06 09:45:50 | INFO     | agent.tts.vocoder | loaded CodeHiFiGAN checkpoint from /data/zhangshaolei/pretrain_models/unit-based_HiFi-GAN_vocoder/mHuBERT.layer11.km1000.en/g_00500000
2024-06-06 09:45:50 | INFO     | simuleval.utils.agent | System will run on device: gpu.
2024-06-06 09:45:50 | INFO     | simuleval.dataloader | Evaluating from speech to speech.
  0%|                                                                                                                                                                              | 0/2 [00:00<?, ?it/s]
Streaming ASR:
Streaming ASR:
Streaming ASR: je
Simultaneous translation: i would
Streaming ASR: je voudrais
Simultaneous translation: i would like to
Streaming ASR: je voudrais soumettre
Simultaneous translation: i would like to sub
Streaming ASR: je voudrais soumettre cette
Simultaneous translation: i would like to submit
Streaming ASR: je voudrais soumettre cette idée
Simultaneous translation: i would like to submit this
Streaming ASR: je voudrais soumettre cette idée à la
Simultaneous translation: i would like to submit this idea to
Streaming ASR: je voudrais soumettre cette idée à la réflexion
Simultaneous translation: i would like to submit this idea to the
Streaming ASR: je voudrais soumettre cette idée à la réflexion de
Simultaneous translation: i would like to submit this idea to the reflection
Streaming ASR: je voudrais soumettre cette idée à la réflexion de lassemblée
Simultaneous translation: i would like to submit this idea to the reflection of
Streaming ASR: je voudrais soumettre cette idée à la réflexion de lassemblée nationale
Simultaneous translation: i would like to submit this idea to the reflection of the
Streaming ASR: je voudrais soumettre cette idée à la réflexion de lassemblée nationale
Simultaneous translation: i would like to submit this idea to the reflection of the national assembly
 50%|███████████████████████████████████████████████████████████████████████████████████                                                                                   | 1/2 [00:04<00:04,  4.08s/it]
Streaming ASR:
Streaming ASR:
Streaming ASR:
Streaming ASR:
Streaming ASR: jai donc
Simultaneous translation: i therefore
Streaming ASR: jai donc
Streaming ASR: jai donc expérience des
Simultaneous translation: i therefore have an experience
Streaming ASR: jai donc expérience des années
Streaming ASR: jai donc expérience des années passé
Simultaneous translation: i therefore have an experience of last
Streaming ASR: jai donc expérience des années passé jen
Simultaneous translation: i therefore have an experience of last years
Streaming ASR: jai donc expérience des années passé jen dirairai
Simultaneous translation: i therefore have an experience of last years i will
Streaming ASR: jai donc expérience des années passé jen dirairai un mot
Simultaneous translation: i therefore have an experience of last years i will tell a
Streaming ASR: jai donc expérience des années passé jen dirairai un mot tout à lheure
Simultaneous translation: i therefore have an experience of last years i will tell a word
Streaming ASR: jai donc expérience des années passé jen dirairai un mot tout à lheure
Simultaneous translation: i therefore have an experience of last years i will tell a word later
100%|██████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 2/2 [00:06<00:00,  3.02s/it]
2024-06-06 09:45:56 | WARNING  | simuleval.scorer.asr_bleu | Beta feature: Evaluating speech output. Faieseq is required.
2024-06-06 09:46:12 | INFO | fairseq.tasks.audio_finetuning | Using dict_path : /data/zhangshaolei/.cache/ust_asr/en/dict.ltr.txt
Transcribing predictions: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 2/2 [00:01<00:00,  1.63it/s]
2024-06-06 09:46:21 | INFO     | simuleval.sentence_level_evaluator | Results:
 ASR_BLEU       AL    AL_CA    AP  AP_CA      DAL  DAL_CA  StartOffset  StartOffset_CA  EndOffset  EndOffset_CA     LAAL  LAAL_CA      ATD   ATD_CA  NumChunks  NumChunks_CA  DiscontinuitySum  DiscontinuitySum_CA  DiscontinuityAve  DiscontinuityAve_CA  DiscontinuityNum  DiscontinuityNum_CA   RTF  RTF_CA
   15.448 1724.895 2913.508 0.425  0.776 1358.812 3137.55       1280.0        2213.906     1366.0        1366.0 1724.895 2913.508 1440.146 3389.374        9.5           9.5             110.0                110.0              55.0                 55.0                 1                    1 1.326   1.326
Logs and evaluation results are stored in $output_dir/chunk_size=$chunk_size:
$output_dir/chunk_size=$chunk_size
├── wavs/
│   ├── 0_pred.wav # generated speech
│   ├── 1_pred.wav
│   ├── 0_pred.txt # asr transcription for ASR-BLEU tookit
│   ├── 1_pred.txt
├── config.yaml
├── asr_transcripts.txt # ASR-BLEU transcription results
├── metrics.tsv
├── scores.tsv
├── asr_cmd.bash
└── instances.log # logs of Simul-S2ST
export CUDA_VISIBLE_DEVICES=0

ROOT=/data/zhangshaolei/StreamSpeech # path to StreamSpeech repo

LANG=fr
file=streamspeech.simultaneous.${LANG}-en.pt # path to downloaded StreamSpeech model
output_dir=$ROOT/res/streamspeech.simultaneous.${LANG}-en/simul-s2tt

chunk_size=320 #ms
PYTHONPATH=$ROOT/fairseq simuleval --data-bin ${ROOT}/configs/${LANG}-en \
    --user-dir ${ROOT}/researches/ctc_unity --agent-dir ${ROOT}/agent \
    --source example/wav_list.txt --target example/target.txt \
    --model-path $file \
    --config-yaml config_gcmvn.yaml --multitask-config-yaml config_mtl_asr_st_ctcst.yaml \
    --agent $ROOT/agent/speech_to_text.s2tt.streamspeech.agent.py\
    --output $output_dir/chunk_size=$chunk_size \
    --source-segment-size $chunk_size \
    --quality-metrics BLEU  --latency-metrics AL AP DAL StartOffset EndOffset LAAL ATD NumChunks RTF \
    --device gpu --computation-aware
export CUDA_VISIBLE_DEVICES=0

ROOT=/data/zhangshaolei/StreamSpeech # path to StreamSpeech repo

LANG=fr
file=streamspeech.simultaneous.${LANG}-en.pt # path to downloaded StreamSpeech model
output_dir=$ROOT/res/streamspeech.simultaneous.${LANG}-en/streaming-asr

chunk_size=320 #ms
PYTHONPATH=$ROOT/fairseq simuleval --data-bin ${ROOT}/configs/${LANG}-en \
    --user-dir ${ROOT}/researches/ctc_unity --agent-dir ${ROOT}/agent \
    --source example/wav_list.txt --target example/source.txt \
    --model-path $file \
    --config-yaml config_gcmvn.yaml --multitask-config-yaml config_mtl_asr_st_ctcst.yaml \
    --agent $ROOT/agent/speech_to_text.asr.streamspeech.agent.py\
    --output $output_dir/chunk_size=$chunk_size \
    --source-segment-size $chunk_size \
    --quality-metrics BLEU  --latency-metrics AL AP DAL StartOffset EndOffset LAAL ATD NumChunks RTF \
    --device gpu --computation-aware
./preprocess_scripts to process CVSS-C data.[!Note] You can directly use the downloaded StreamSpeech model for evaluation and skip training.
researches/ctc_unity/train_scripts/train.simul-s2st.sh to train StreamSpeech for simultaneous speech-to-speech translation.researches/ctc_unity/train_scripts/train.offline-s2st.sh to train StreamSpeech for offline speech-to-speech translation.| Model | --user-dir | --arch | Description |
|---|---|---|---|
| Translatotron 2 | researches/translatotron | s2spect2_conformer_modified | Translatotron 2 |
| UnitY | researches/translatotron | unity_conformer_modified | UnitY |
| Uni-UnitY | researches/uni_unity | uni_unity_conformer | Change all encoders in UnitY into unidirectional |
| Chunk-UnitY | researches/chunk_unity | chunk_unity_conformer | Change the Conformer in UnitY into Chunk-based Conformer |
| StreamSpeech | researches/ctc_unity | streamspeech | StreamSpeech |
| StreamSpeech (cascade) | researches/ctc_unity | streamspeech_cascade | Cascaded StreamSpeech of S2TT and TTS. TTS module can be used independently for real-time TTS given incremental text. |
| HMT | researches/hmt | hmt_transformer_iwslt_de_en | HMT: strong simultaneous text-to-text translation method |
| DiSeg | researches/diseg | convtransformer_espnet_base_seg | DiSeg: strong simultaneous speech-to-text translation method |
[!Tip] The
train_scripts/andtest_scripts/in directory--user-dirgive the training and testing scripts for each model. Refer to official repo of UnitY, Translatotron 2, HMT and DiSeg for more details.
Follow pred.offline-s2st.sh to evaluate the offline performance of StreamSpeech on ASR, S2TT and S2ST.
A trained StreamSpeech model can be used for streaming ASR, simultaneous speech-to-text translation and simultaneous speech-to-speech translation. We provide agent/ for these three tasks:
agent/speech_to_speech.streamspeech.agent.py: simultaneous speech-to-speech translationagent/speech_to_text.s2tt.streamspeech.agent.py: simultaneous speech-to-text translationagent/speech_to_text.asr.streamspeech.agent.py: streaming ASRFollow simuleval.simul-s2st.sh, simuleval.simul-s2tt.sh, simuleval.streaming-asr.sh to evaluate StreamSpeech.
Our project page (https://ictnlp.github.io/StreamSpeech-site/) provides some translated speech generated by StreamSpeech, listen to it 🎧.
If you have any questions, please feel free to submit an issue or contact [email protected].
If our work is useful for you, please cite as:
@inproceedings{streamspeech,
      title={StreamSpeech: Simultaneous Speech-to-Speech Translation with Multi-task Learning},
      author={Shaolei Zhang and Qingkai Fang and Shoutao Guo and Zhengrui Ma and Min Zhang and Yang Feng},
      year={2024},
      booktitle = {Proceedings of the 62th Annual Meeting of the Association for Computational Linguistics (Long Papers)},
      publisher = {Association for Computational Linguistics}
}
479 followers · starred Jul 2024
121 followers · starred Jun 2026
200 followers · starred Jun 2024
139 followers · starred Jun 2024