
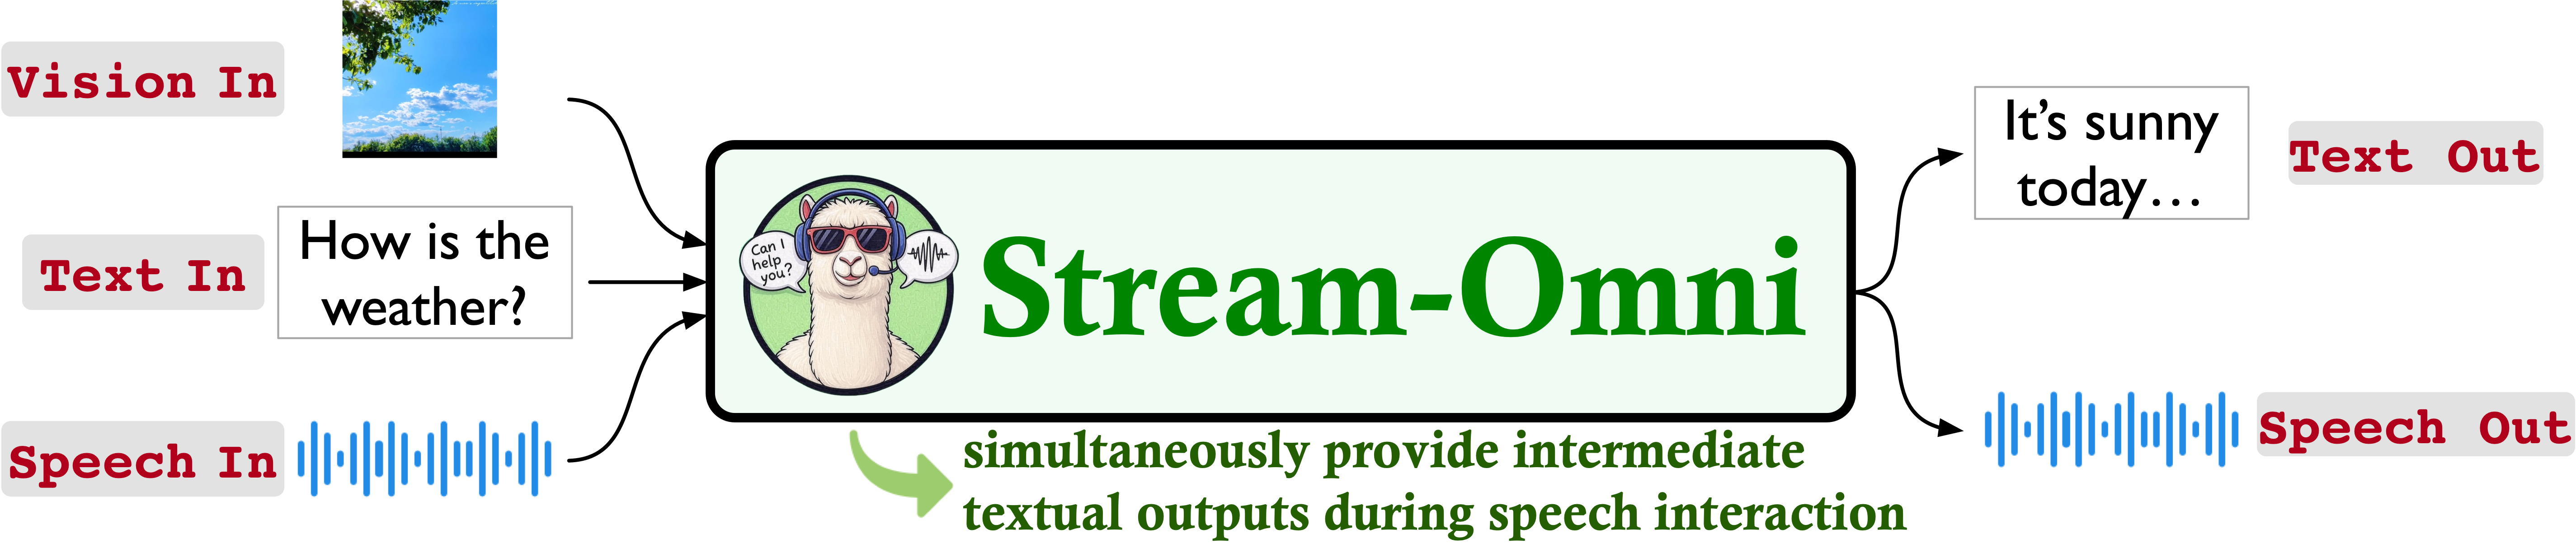
Stream-Omni is a GPT-4o-like language-vision-speech chatbot that simultaneously supports interaction across various modality combinations.
See the codeREADME
Stream-Omni: Simultaneous Multimodal Interactions with Large Language-Vision-Speech Model


Shaolei Zhang, Shoutao Guo, Qingkai Fang, Yan Zhou, Yang Feng*
Stream-Omni is a GPT-4o-like language-vision-speech chatbot that simultaneously supports interaction across various modality combinations, with the following features💡:
- Omni Interaction: Support multimodal inputs including text, vision, and speech, and generate both text and speech responses.
- Seamless "see-while-hear" Experience: Simultaneously output intermediate textual results (e.g., ASR transcriptions and model responses) during speech interactions, like the advanced voice service of GPT-4o.
- Efficient Training: Require only a small amount of omni-modal data for training.
🖥 Demo
🎧 Vision-grounded Speech Interaction (simultaneously produce intermediate text) 🎧
https://github.com/user-attachments/assets/25807982-aa95-4633-9e92-10d995900258
https://github.com/user-attachments/assets/df8d79ba-63db-487c-a4a9-f183372168a1
[!NOTE]
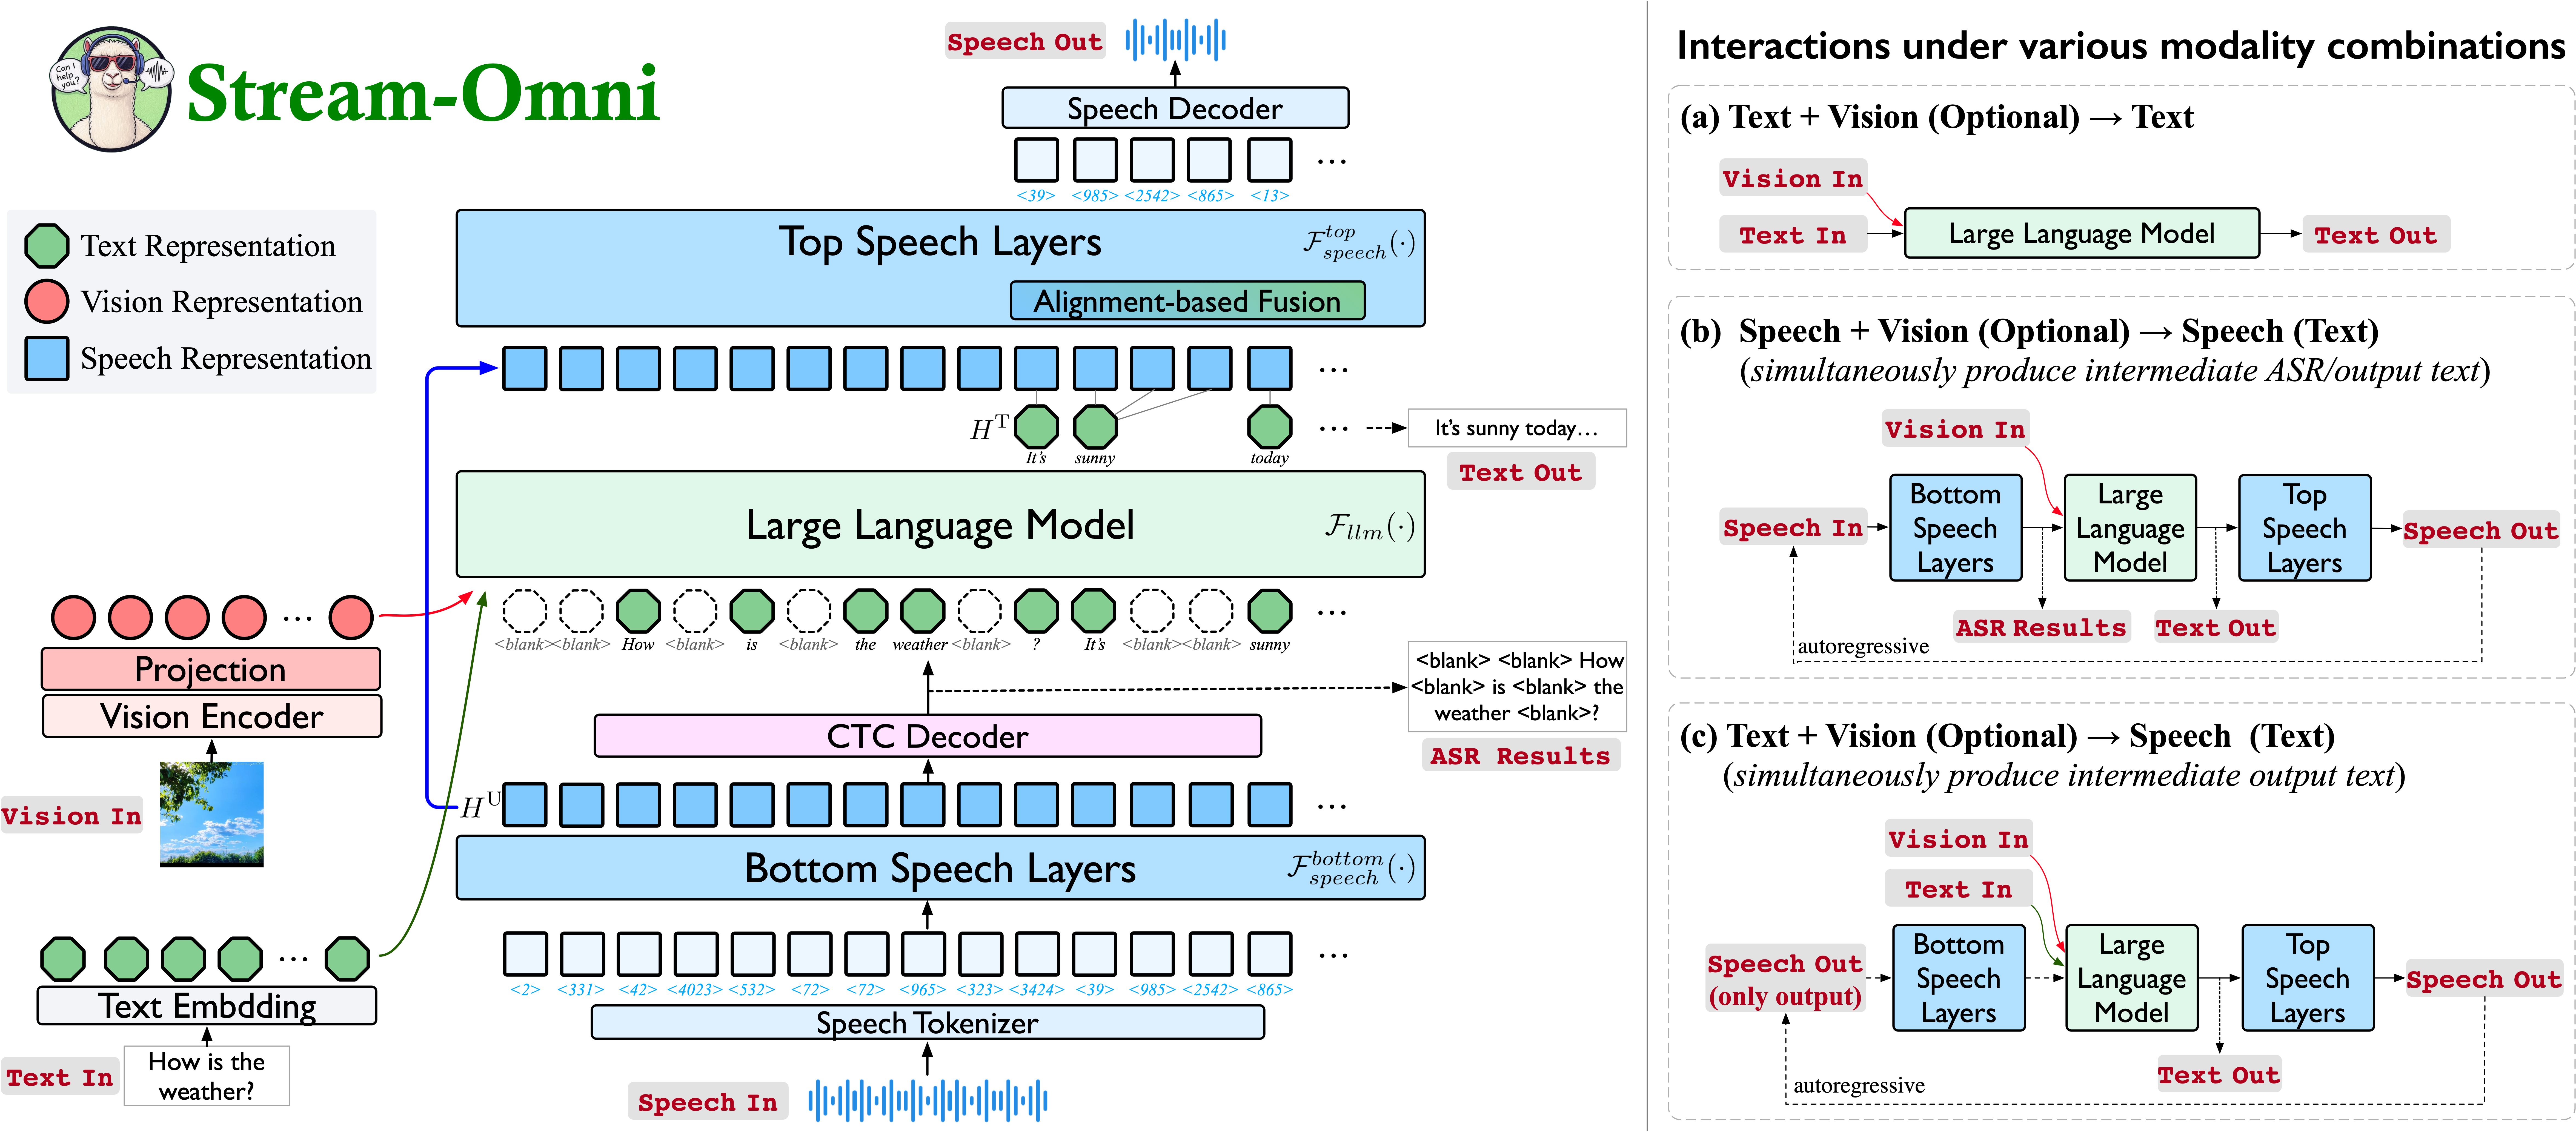
Stream-Omni can produce intermediate textual results (ASR transcription and text response) during speech interaction, offering users a seamless "see-while-hear" experience.
- Downlaod Stream-Omni model from here, put in
${STREAMOMNI_CKPT}. - Downlaod CosyVoice (Tokenizer & Flow Model) from here, put in
COSYVOICE_CKPT=./CosyVoice-300M-25Hz:from modelscope import snapshot_download snapshot_download('iic/CosyVoice-300M-25Hz', local_dir='./CosyVoice-300M-25Hz') - Run these scripts to launch the API and interface, and then interact through the browser (http://localhost:7860):
# controller python stream_omni/serve/controller.py --host 0.0.0.0 --port 10000 # CosyVoice worker COSYVOICE_CKPT=path_to_CosyVoice-300M-25Hz # e.g., ./CosyVoice-300M-25Hz WAV_DIR=path_to_save_generated_audio CUDA_VISIBLE_DEVICES=0 PYTHONPATH=CosyVoice/third_party/Matcha-TTS python ./CosyVoice/cosyvoice_worker.py --port 21003 --model ${COSYVOICE_CKPT} --wav_dir ./gen_wavs/ # Stream-Omni worker, add --load-8bit for VRAM lower than 32GB STREAMOMNI_CKPT=path_to_stream-omni-8b # e.g., ./stream-omni-8b CUDA_VISIBLE_DEVICES=1 python ./stream_omni/serve/model_worker.py --host 0.0.0.0 --controller http://localhost:10000 --port 40000 --worker http://localhost:40000 --model-path ${STREAMOMNI_CKPT} --model-name stream-omni # Interface python stream_omni/serve/gradio_web.py --controller http://localhost:10000 --model-list-mode reload --port 7860 - You can also refer to
api.pyfor the usage of API.
🔥 Quick Start
[!Tip]
Stream-Omni achieves modality alignments through sequence-dimension concatenation for vision-text alignment and layer-dimension mapping for speech-text alignment.
Requirements
- Install packages:
conda create -n streamomni python=3.10 -y
conda activate streamomni
pip install -e .
pip install flash-attn --no-build-isolation
pip install -r requirements.txt
pip install -r CosyVoice/requirements.txt
Command Interaction
-
Run these scripts for vision-grounded speech interaction:
export CUDA_VISIBLE_DEVICES=0
export PYTHONPATH=CosyVoice/third_party/Matcha-TTS

STREAMOMNI_CKPT=path_to_stream-omni-8b

# Replace the path of cosyvoice model in run_stream_omni.py (e.g., cosyvoice = CosyVoiceModel('./CosyVoice-300M-25Hz'))
# add --load-8bit for VRAM lower than 32GB
python ./stream_omni/eval/run_stream_omni.py \
    --model-path ${STREAMOMNI_CKPT} \
    --image-file ./stream_omni/serve/examples/cat.jpg --conv-mode stream_omni_llama_3_1 --model-name stream-omni  \
    --query ./stream_omni/serve/examples/cat_color.wav
You should get the following outputs:
ASR Outputs: What is the color of the cat LLM Outputs: The cat is gray and black. Speech Tokens: <Audio_2164><Audio_2247><Audio_671><Audio_246><Audio_2172><Audio_1406><Audio_119><Audio_203><Audio_2858><Audio_2099><Audio_1716><Audio_22><Audio_1736><Audio_1038><Audio_4082><Audio_1655><Audio_2409><Audio_2104><Audio_571><Audio_2255><Audio_73><Audio_760><Audio_822><Audio_701><Audio_2583><Audio_1038><Audio_2203><Audio_1185><Audio_2103><Audio_1718><Audio_2610><Audio_1883><Audio_16><Audio_792><Audio_8><Audio_8><Audio_535><Audio_67> Speech Outputs: Audio saved at ./output_893af1597afe2551d76c37a75c813b16.wav -
Interaction across various modality combinations:
Inputs Outputs Intermediate Outputs Scripts Text + Vision (or None) Text / run_stream_omni_t2t.pyText + Vision (or None) Speech Text result of model outputs run_stream_omni_t2s.pySpeech + Vision (or None) Text ASR transciption of user inputs run_stream_omni_s2t.pySpeech + Vision (or None) Speech Text result of model outputs, ASR transciption of user inputs run_stream_omni_s2s.pyControl the interaction mode via
inference_typeinmodel.generate()(select fromtext_to_text,text_to_speech,speech_to_text,speech_to_speech)
Evaluation
- Refer to
./scripts/stream_omni/for evaluation scripts.
🤝 Acknowledgement
- LLaVA/LLaVA-NeXT/LLaVA-OneVision: Stream-Omni is built upon the LLaVA and LLaVA-NeXT codebases and incorporates image instruction data from LLaVA-OneVision.
- CosyVoice: Stream-Omni uses the tokenizer and flow model of CosyVoice.
- UltraEval-Audio: Some normalization processing during evaluation refer to UltraEval-Audio.
- VisIT-Bench: Stream-Omni constructs SpokenVisIT benchmark based on VisIT-Bench for the evaluation of vision-grounded speech interaction.
🖋Citation
If this repository is useful for you, please cite as:
@misc{streamomni,
      title={Stream-Omni: Simultaneous Multimodal Interactions with Large Language-Vision-Speech Model},
      author={Shaolei Zhang and Shoutao Guo and Qingkai Fang and Yan Zhou and Yang Feng},
      year={2025},
      eprint={2506.13642},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2506.13642},
}
If you have any questions, please feel free to submit an issue or contact zhangshaolei20z@ict.ac.cn.
Contributors

8 commits
Similar repos



Languages
Python
96.5%
Shell
3.4%
Stream-Omni is a GPT-4o-like language-vision-speech chatbot that simultaneously supports interaction across various modality combinations.
See the codeREADME
Stream-Omni: Simultaneous Multimodal Interactions with Large Language-Vision-Speech Model
Shaolei Zhang, Shoutao Guo, Qingkai Fang, Yan Zhou, Yang Feng*
Stream-Omni is a GPT-4o-like language-vision-speech chatbot that simultaneously supports interaction across various modality combinations, with the following features💡:
- Omni Interaction: Support multimodal inputs including text, vision, and speech, and generate both text and speech responses.
- Seamless "see-while-hear" Experience: Simultaneously output intermediate textual results (e.g., ASR transcriptions and model responses) during speech interactions, like the advanced voice service of GPT-4o.
- Efficient Training: Require only a small amount of omni-modal data for training.
🖥 Demo
🎧 Vision-grounded Speech Interaction (simultaneously produce intermediate text) 🎧
https://github.com/user-attachments/assets/25807982-aa95-4633-9e92-10d995900258
https://github.com/user-attachments/assets/df8d79ba-63db-487c-a4a9-f183372168a1
[!NOTE]
Stream-Omni can produce intermediate textual results (ASR transcription and text response) during speech interaction, offering users a seamless "see-while-hear" experience.
- Downlaod Stream-Omni model from here, put in
${STREAMOMNI_CKPT}. - Downlaod CosyVoice (Tokenizer & Flow Model) from here, put in
COSYVOICE_CKPT=./CosyVoice-300M-25Hz:from modelscope import snapshot_download snapshot_download('iic/CosyVoice-300M-25Hz', local_dir='./CosyVoice-300M-25Hz') - Run these scripts to launch the API and interface, and then interact through the browser (http://localhost:7860):
# controller python stream_omni/serve/controller.py --host 0.0.0.0 --port 10000 # CosyVoice worker COSYVOICE_CKPT=path_to_CosyVoice-300M-25Hz # e.g., ./CosyVoice-300M-25Hz WAV_DIR=path_to_save_generated_audio CUDA_VISIBLE_DEVICES=0 PYTHONPATH=CosyVoice/third_party/Matcha-TTS python ./CosyVoice/cosyvoice_worker.py --port 21003 --model ${COSYVOICE_CKPT} --wav_dir ./gen_wavs/ # Stream-Omni worker, add --load-8bit for VRAM lower than 32GB STREAMOMNI_CKPT=path_to_stream-omni-8b # e.g., ./stream-omni-8b CUDA_VISIBLE_DEVICES=1 python ./stream_omni/serve/model_worker.py --host 0.0.0.0 --controller http://localhost:10000 --port 40000 --worker http://localhost:40000 --model-path ${STREAMOMNI_CKPT} --model-name stream-omni # Interface python stream_omni/serve/gradio_web.py --controller http://localhost:10000 --model-list-mode reload --port 7860 - You can also refer to
api.pyfor the usage of API.
🔥 Quick Start
[!Tip]
Stream-Omni achieves modality alignments through sequence-dimension concatenation for vision-text alignment and layer-dimension mapping for speech-text alignment.
Requirements
- Install packages:
conda create -n streamomni python=3.10 -y
conda activate streamomni
pip install -e .
pip install flash-attn --no-build-isolation
pip install -r requirements.txt
pip install -r CosyVoice/requirements.txt
Command Interaction
-
Run these scripts for vision-grounded speech interaction:
export CUDA_VISIBLE_DEVICES=0
export PYTHONPATH=CosyVoice/third_party/Matcha-TTS

STREAMOMNI_CKPT=path_to_stream-omni-8b

# Replace the path of cosyvoice model in run_stream_omni.py (e.g., cosyvoice = CosyVoiceModel('./CosyVoice-300M-25Hz'))
# add --load-8bit for VRAM lower than 32GB
python ./stream_omni/eval/run_stream_omni.py \
    --model-path ${STREAMOMNI_CKPT} \
    --image-file ./stream_omni/serve/examples/cat.jpg --conv-mode stream_omni_llama_3_1 --model-name stream-omni  \
    --query ./stream_omni/serve/examples/cat_color.wav
You should get the following outputs:
ASR Outputs: What is the color of the cat LLM Outputs: The cat is gray and black. Speech Tokens: <Audio_2164><Audio_2247><Audio_671><Audio_246><Audio_2172><Audio_1406><Audio_119><Audio_203><Audio_2858><Audio_2099><Audio_1716><Audio_22><Audio_1736><Audio_1038><Audio_4082><Audio_1655><Audio_2409><Audio_2104><Audio_571><Audio_2255><Audio_73><Audio_760><Audio_822><Audio_701><Audio_2583><Audio_1038><Audio_2203><Audio_1185><Audio_2103><Audio_1718><Audio_2610><Audio_1883><Audio_16><Audio_792><Audio_8><Audio_8><Audio_535><Audio_67> Speech Outputs: Audio saved at ./output_893af1597afe2551d76c37a75c813b16.wav -
Interaction across various modality combinations:
Inputs Outputs Intermediate Outputs Scripts Text + Vision (or None) Text / run_stream_omni_t2t.pyText + Vision (or None) Speech Text result of model outputs run_stream_omni_t2s.pySpeech + Vision (or None) Text ASR transciption of user inputs run_stream_omni_s2t.pySpeech + Vision (or None) Speech Text result of model outputs, ASR transciption of user inputs run_stream_omni_s2s.pyControl the interaction mode via
inference_typeinmodel.generate()(select fromtext_to_text,text_to_speech,speech_to_text,speech_to_speech)
Evaluation
- Refer to
./scripts/stream_omni/for evaluation scripts.
🤝 Acknowledgement
- LLaVA/LLaVA-NeXT/LLaVA-OneVision: Stream-Omni is built upon the LLaVA and LLaVA-NeXT codebases and incorporates image instruction data from LLaVA-OneVision.
- CosyVoice: Stream-Omni uses the tokenizer and flow model of CosyVoice.
- UltraEval-Audio: Some normalization processing during evaluation refer to UltraEval-Audio.
- VisIT-Bench: Stream-Omni constructs SpokenVisIT benchmark based on VisIT-Bench for the evaluation of vision-grounded speech interaction.
🖋Citation
If this repository is useful for you, please cite as:
@misc{streamomni,
      title={Stream-Omni: Simultaneous Multimodal Interactions with Large Language-Vision-Speech Model},
      author={Shaolei Zhang and Shoutao Guo and Qingkai Fang and Yan Zhou and Yang Feng},
      year={2025},
      eprint={2506.13642},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2506.13642},
}
If you have any questions, please feel free to submit an issue or contact zhangshaolei20z@ict.ac.cn.
Similar repos
Contributors
8 commits
Languages
Python
96.5%
Shell
3.4%