Unified pure C# .NET 10 LLM command-line application (glacier). Universal inference (Llama, Phi, DeepSeek, Mistral, Qwen), in-process LoRA fine-tuning, GGUF adapter fusion, in-process GraphRAG, and PagedAttention continuous batching server.
C#
0
15 commits
updated Oct 9, 2026
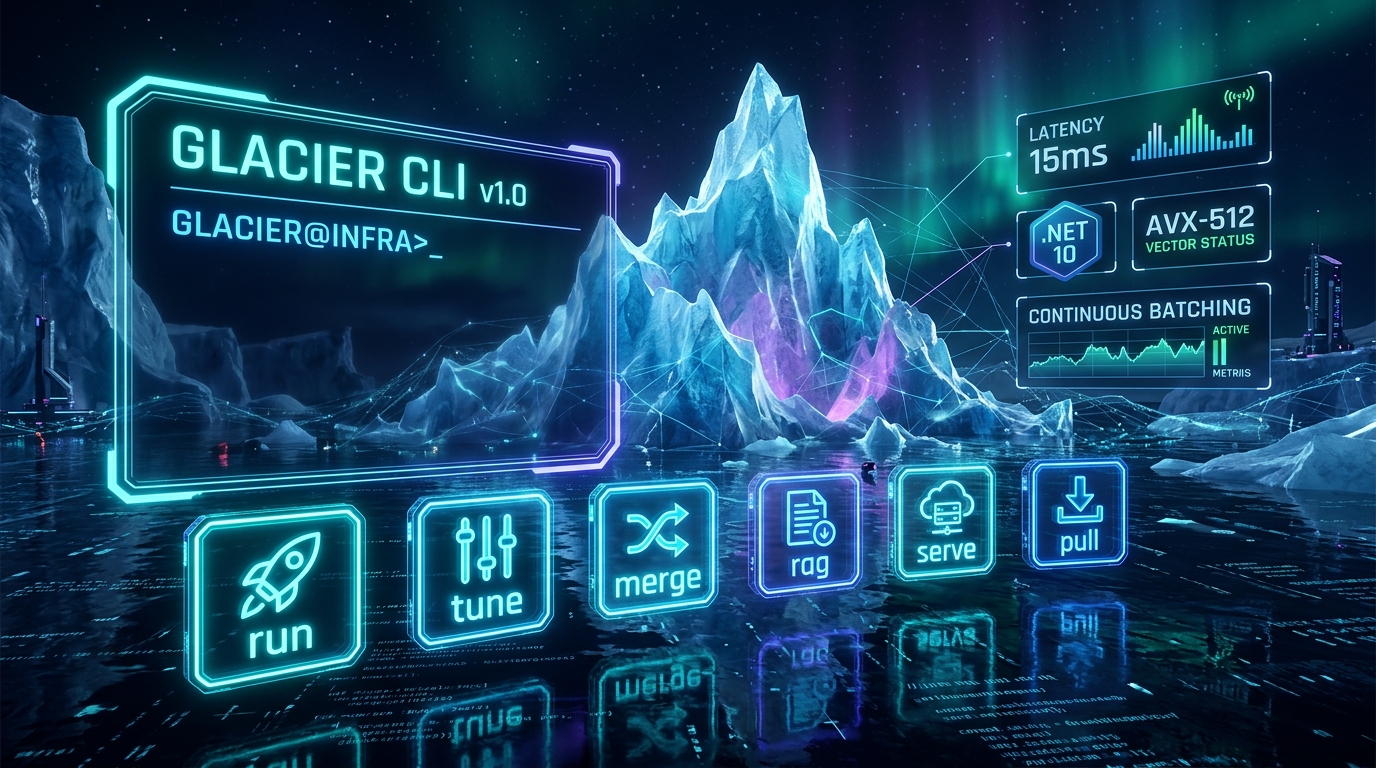
One single global CLI tool replacing Ollama, vLLM, HuggingFace CLI, Unsloth, and RAGFlow.


irm https://raw.githubusercontent.com/ian-cowley/Glacier.Cli/main/install.ps1 | iex
Or download glacier-win-x64.zip and double-click install.bat.
curl -fsSL https://raw.githubusercontent.com/ian-cowley/Glacier.Cli/main/install.sh | bash
dotnet tool install -g Glacier.Cli
| Command | Purpose | Benchmark / Highlight |
|---|---|---|
glacier run | Instant GPU/CPU streaming inference & REPL | <15ms cold start, AVX-512 & Bare-Metal SASS (>64 tok/s generation) |
glacier tune | In-process PEFT LoRA fine-tuning | 6.96s / step (46 tok/s, 320 tokens/step, 10-step run) on RTX 4060 |
glacier merge | Zero-copy GGUF adapter fusion | < 60s (6.82s physical fusion) lossless Q8_0 fusion |
glacier rag | SIMD Vector + CSR Knowledge Graph RAG | < 10ms end-to-end (27–29 µs in-process scan), zero-copy graph traversal |
glacier serve | Ollama & OpenAI HTTP continuous batching | PagedAttention, 17,046 req/s socket turnaround (7.2M req/s pipeline capacity) |
glacier pull | High-speed chunked GGUF downloader | Multi-threaded download with live ETA & speed gauge |
# Streaming answer to a single prompt
glacier run model.gguf "Explain quantum computing in two sentences"

# Interactive terminal chat REPL
glacier run model.gguf
# Fine-tune directly in pure .NET 10 (GPU VRAM-resident + AVX-512)
glacier tune base.gguf --data dataset.jsonl --epochs 3 --rank 16 --out adapter.bin

# Fuse LoRA adapter directly into a standalone production GGUF
glacier merge base.gguf adapter.bin model-enterprise.gguf
# Index documents and stream grounded responses with structural graph hops
glacier rag --model model.gguf --docs ./knowledge --query "What is our architecture?"
# Serves POST /v1/chat/completions (OpenAI) and POST /api/chat (Ollama)
glacier serve model.gguf --port 11434 --blocks 1024 --batch-size 16
# Pull directly from HuggingFace with live progress tracking
glacier pull lmstudio-community/Meta-Llama-3.1-8B-Instruct-GGUF
Q4_K_M, Q5_K_M, Q6_K, Q8_0, Q4_0, MXFP4, F16, F32.CliArgumentParsingTests.cs verifying argument constraints, missing flags, error codes, and hardware device discovery.Console.Out contention under xUnit parallel test execution.Developed by Ian Cowley and Antigravity (Google DeepMind).
MIT License. High-Performance Pure C# .NET 10 Ecosystem.
Unified pure C# .NET 10 LLM command-line application (glacier). Universal inference (Llama, Phi, DeepSeek, Mistral, Qwen), in-process LoRA fine-tuning, GGUF adapter fusion, in-process GraphRAG, and PagedAttention continuous batching server.
C#
0
15 commits
updated Oct 9, 2026
One single global CLI tool replacing Ollama, vLLM, HuggingFace CLI, Unsloth, and RAGFlow.
irm https://raw.githubusercontent.com/ian-cowley/Glacier.Cli/main/install.ps1 | iex
Or download glacier-win-x64.zip and double-click install.bat.
curl -fsSL https://raw.githubusercontent.com/ian-cowley/Glacier.Cli/main/install.sh | bash
dotnet tool install -g Glacier.Cli
| Command | Purpose | Benchmark / Highlight |
|---|---|---|
glacier run | Instant GPU/CPU streaming inference & REPL | <15ms cold start, AVX-512 & Bare-Metal SASS (>64 tok/s generation) |
glacier tune | In-process PEFT LoRA fine-tuning | 6.96s / step (46 tok/s, 320 tokens/step, 10-step run) on RTX 4060 |
glacier merge | Zero-copy GGUF adapter fusion | < 60s (6.82s physical fusion) lossless Q8_0 fusion |
glacier rag | SIMD Vector + CSR Knowledge Graph RAG | < 10ms end-to-end (27–29 µs in-process scan), zero-copy graph traversal |
glacier serve | Ollama & OpenAI HTTP continuous batching | PagedAttention, 17,046 req/s socket turnaround (7.2M req/s pipeline capacity) |
glacier pull | High-speed chunked GGUF downloader | Multi-threaded download with live ETA & speed gauge |
# Streaming answer to a single prompt
glacier run model.gguf "Explain quantum computing in two sentences"

# Interactive terminal chat REPL
glacier run model.gguf
# Fine-tune directly in pure .NET 10 (GPU VRAM-resident + AVX-512)
glacier tune base.gguf --data dataset.jsonl --epochs 3 --rank 16 --out adapter.bin

# Fuse LoRA adapter directly into a standalone production GGUF
glacier merge base.gguf adapter.bin model-enterprise.gguf
# Index documents and stream grounded responses with structural graph hops
glacier rag --model model.gguf --docs ./knowledge --query "What is our architecture?"
# Serves POST /v1/chat/completions (OpenAI) and POST /api/chat (Ollama)
glacier serve model.gguf --port 11434 --blocks 1024 --batch-size 16
# Pull directly from HuggingFace with live progress tracking
glacier pull lmstudio-community/Meta-Llama-3.1-8B-Instruct-GGUF
Q4_K_M, Q5_K_M, Q6_K, Q8_0, Q4_0, MXFP4, F16, F32.CliArgumentParsingTests.cs verifying argument constraints, missing flags, error codes, and hardware device discovery.Console.Out contention under xUnit parallel test execution.Developed by Ian Cowley and Antigravity (Google DeepMind).
MIT License. High-Performance Pure C# .NET 10 Ecosystem.