
README
Awesome-MLLMs-for-Video-Temporal-Grounding 
🔥 A Survey on Video Temporal Grounding with Multimodal Large Language Model
Jianlong Wu1,
Wei Liu1,
Ye Liu4,
Meng Liu2,
Liqiang Nie1,
Zhouchen Lin3,
Chang Wen Chen4,
1Harbin Institute of Technology, Shenzhen,
2Shandong Jianzhu University,
3Peking University,
4The Hong Kong Polytechnic University
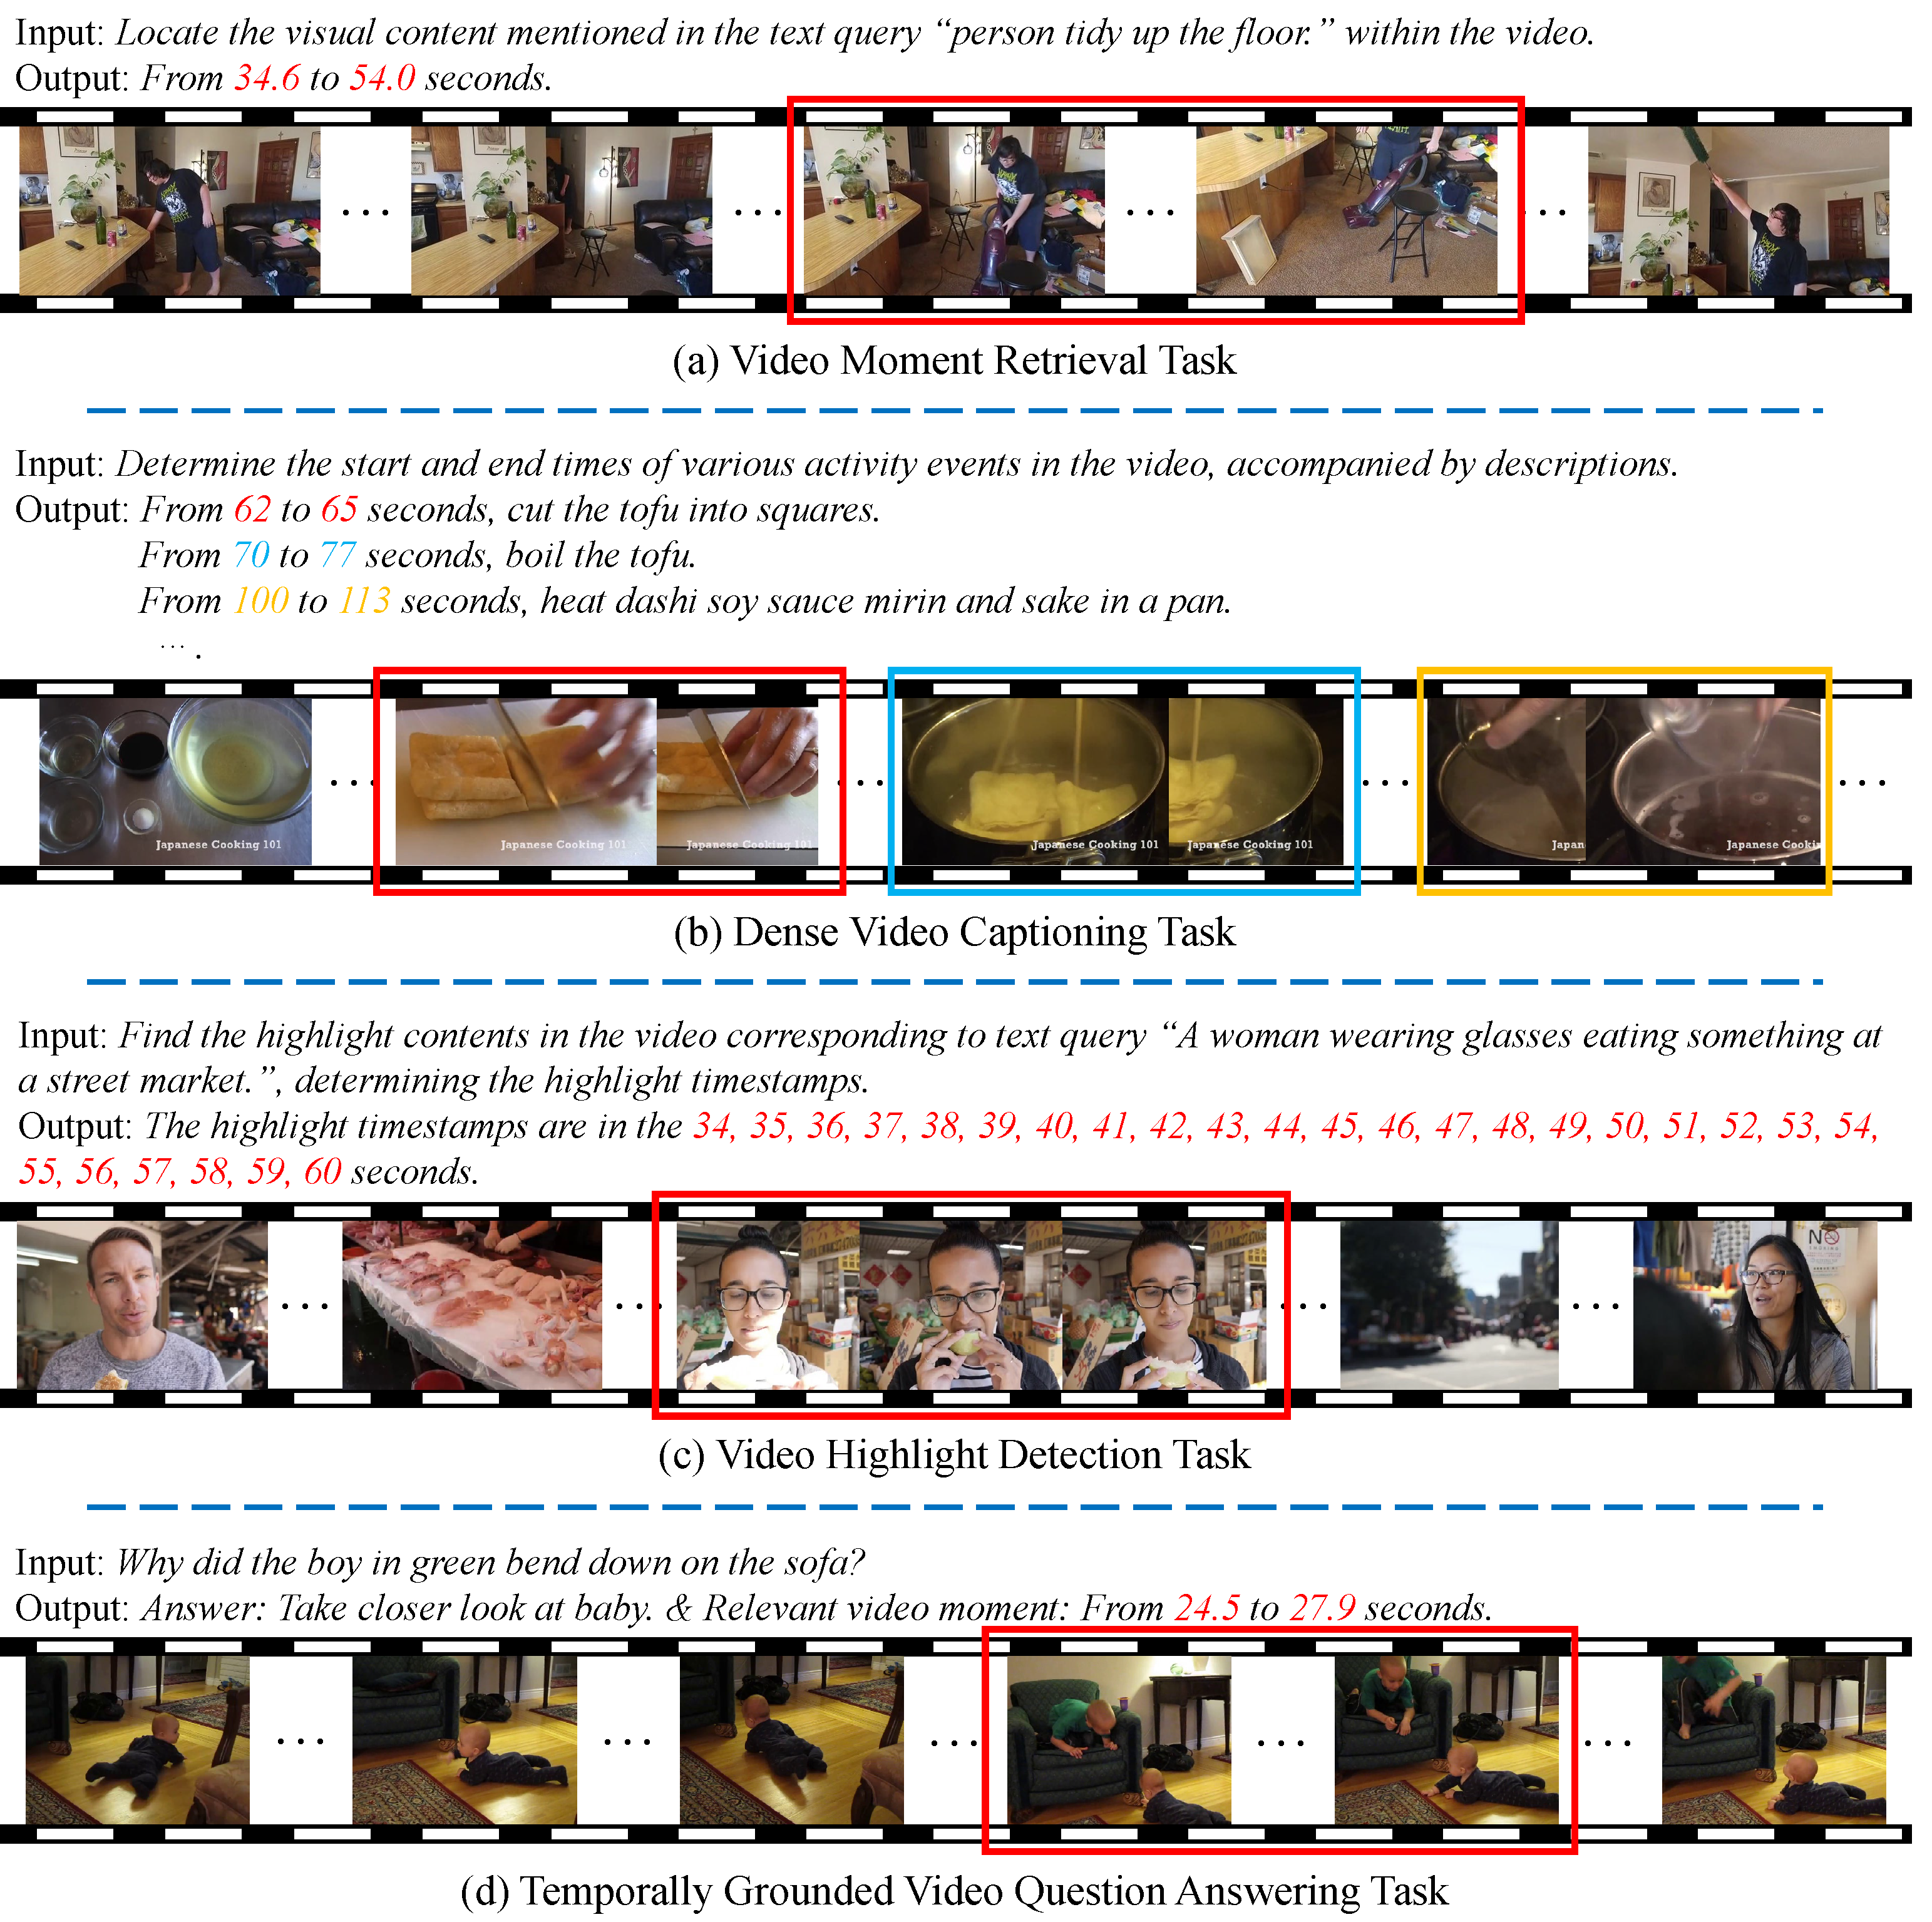
Video Temporal Grounding (VTG) focuses on locating and understanding temporal segments in untrimmed videos based on multimodal queries. Core tasks include video moment retrieval, dense video captioning, video highlight detection, and temporally grounded video QA, all requiring fine-grained temporal reasoning.
With the rise of Multimodal Large Language Models (MLLMs), VTG has seen transformative progress. These models bring powerful cross-modal alignment and semantic reasoning abilities, enabling flexible, generalizable solutions across VTG tasks.
This repository aims to serve as a curated reference point for researchers and practitioners interested in advancing the field of video temporal grounding through the lens of large multimodal models.
News
- [2025.09.23] The survey has been accepted to IEEE TPAMI.
Table of Contents
🧠 Functional Roles of MLLMs in VTG-MLLMs
Facilitator
MLLMs generate structured textual representations from video content to support downstream modules.
Executor
MLLMs directly perform temporal boundary prediction via integrated multimodal reasoning.
🛠️ Training Paradigms of VTG-MLLMs
Pretraining
Pretraining in VTG-MLLMs aims to establish strong temporal reasoning capabilities through large-scale supervised learning.
Fine-Tuning
Adapts general-purpose MLLMs to downstream VTG tasks through supervised fine-tuning on temporally annotated training datasets.
Training-Free
Training-free approaches integrate pre-trained foundation models with specialized expert tools through the carefully designed pipeline architecture.
| Title | Model | Date | Link | Venue |
|---|---|---|---|---|
| Grounding-Prompter: Prompting LLM with Multimodal Information for Temporal Sentence Grounding in Long Videos | Grounding-Prompter | 12/2023 | - | arXiv |
| VTG-GPT: Tuning-Free Zero-Shot Video Temporal Grounding with GPT | VTG-GPT | 03/2024 | project | Applied Sciences |
| Training-free Video Temporal Grounding using Large-scale Pre-trained Models | TFVTG | 08/2024 | project | ECCV |
| Question-Answering Dense Video Events | DeVi | 09/2024 | project | SIGIR |
| ChatVTG: Video Temporal Grounding via Chat with Video Dialogue Large Language Models | ChatVTG | 10/2024 | - | CVPR |
| Number it: Temporal Grounding Videos like Flipping Manga | NumPro | 11/2024 | project | CVPR |
| Zero-shot Video Moment Retrieval via Off-the-shelf Multimodal Large Language Models | Moment-GPT | 01/2025 | - | AAAI |
🎞️ Video Feature Processing in VTG-MLLMs
Visual Feature
Efficient visual feature handling is essential for capturing more fine-grained temporal cues without overwhelming the model.
Compression
Directly compress visual features from densely sampled frames within budget constraints.
Refinement
Gradually refine predictions to maintain performance with the input token limitations.
| Title | Model | Date | Link | Venue |
|---|---|---|---|---|
| Self-Chained Image-Language Model for Video Localization and Question Answering | SeViLA | 05/2023 | project | NeurIPS |
| HawkEye: Training Video-Text LLMs for Grounding Text in Videos | HawkEye | 03/2024 | project | arXiv |
| SlowFocus: Enhancing Fine-grained Temporal Understanding in Video LLM | SlowFocus | 09/2024 | project | NeurIPS |
| ReVisionLLM: Recursive Vision-Language Model for Temporal Grounding in Hour-Long Videos | ReVisionLLM | 11/2024 | project | CVPR |
| VideoMind: A Chain-of-LoRA Agent for Long Video Reasoning | VideoMind | 04/2025 | project | arXiv |
Temporal Feature
Precise temporal feature representation and modeling is crucial for aligning visual content with fine-grained timestamp intervals, enabling accurate temporal reasoning in VTG tasks.
Explicit
Explicit modeling strategies directly furnish MLLMs with unambiguous temporal information, offering direct control and interpretability over temporal cues.
Implicit
Implicit modeling strategies are divided into two main types: Feature Infusion, which subtly integrates temporal context during feature extraction, and Intrinsic Reasoning, which leverages the inherent sequential processing of LLMs. By default, methods under this category are considered part of Intrinsic Reasoning, unless they explicitly incorporate external temporal features during encoding—in which case they are classified as Feature Infusion. The table below highlights representative works employing the Feature Infusion approach.
| Title | Model | Date | Link | Venue |
|---|---|---|---|---|
| TimeChat: A Time-sensitive Multimodal Large Language Model for Long Video Understanding | TimeChat | 12/2023 | project | CVPR |
| TimeSuite: Improving MLLMs for Long Video Understanding via Grounded Tuning | TimeSuite | 10/2024 | project | ICLR |
| Video LLMs for Temporal Reasoning in Long Videos | TemporalVLM | 12/2024 | project | arXiv |
Contact
If you find our survey is useful in your research, please consider giving us a star 🌟 and cite the following paper:
@article{wu2025surveyvideotemporalgrounding,
  title={A Survey on Video Temporal Grounding with Multimodal Large Language Model},
  author={Wu Jianlong and Liu Wei and Liu Ye and Liu Meng and Nie Liqiang and Lin Zhouchen and Chen Chang Wen},
  journal = {arXiv preprint arXiv:2508.10922},
  year={2025}
}
If you have any question about this project, do not hesitate to contact me liuwei030224@gmail.com.
Similar repos


README
Awesome-MLLMs-for-Video-Temporal-Grounding
🔥 A Survey on Video Temporal Grounding with Multimodal Large Language Model
Jianlong Wu1,
Wei Liu1,
Ye Liu4,
Meng Liu2,
Liqiang Nie1,
Zhouchen Lin3,
Chang Wen Chen4,
1Harbin Institute of Technology, Shenzhen,
2Shandong Jianzhu University,
3Peking University,
4The Hong Kong Polytechnic University
Video Temporal Grounding (VTG) focuses on locating and understanding temporal segments in untrimmed videos based on multimodal queries. Core tasks include video moment retrieval, dense video captioning, video highlight detection, and temporally grounded video QA, all requiring fine-grained temporal reasoning.
With the rise of Multimodal Large Language Models (MLLMs), VTG has seen transformative progress. These models bring powerful cross-modal alignment and semantic reasoning abilities, enabling flexible, generalizable solutions across VTG tasks.
This repository aims to serve as a curated reference point for researchers and practitioners interested in advancing the field of video temporal grounding through the lens of large multimodal models.
News
- [2025.09.23] The survey has been accepted to IEEE TPAMI.
Table of Contents
🧠 Functional Roles of MLLMs in VTG-MLLMs
Facilitator
MLLMs generate structured textual representations from video content to support downstream modules.
Executor
MLLMs directly perform temporal boundary prediction via integrated multimodal reasoning.
🛠️ Training Paradigms of VTG-MLLMs
Pretraining
Pretraining in VTG-MLLMs aims to establish strong temporal reasoning capabilities through large-scale supervised learning.
Fine-Tuning
Adapts general-purpose MLLMs to downstream VTG tasks through supervised fine-tuning on temporally annotated training datasets.
Training-Free
Training-free approaches integrate pre-trained foundation models with specialized expert tools through the carefully designed pipeline architecture.
| Title | Model | Date | Link | Venue |
|---|---|---|---|---|
| Grounding-Prompter: Prompting LLM with Multimodal Information for Temporal Sentence Grounding in Long Videos | Grounding-Prompter | 12/2023 | - | arXiv |
| VTG-GPT: Tuning-Free Zero-Shot Video Temporal Grounding with GPT | VTG-GPT | 03/2024 | project | Applied Sciences |
| Training-free Video Temporal Grounding using Large-scale Pre-trained Models | TFVTG | 08/2024 | project | ECCV |
| Question-Answering Dense Video Events | DeVi | 09/2024 | project | SIGIR |
| ChatVTG: Video Temporal Grounding via Chat with Video Dialogue Large Language Models | ChatVTG | 10/2024 | - | CVPR |
| Number it: Temporal Grounding Videos like Flipping Manga | NumPro | 11/2024 | project | CVPR |
| Zero-shot Video Moment Retrieval via Off-the-shelf Multimodal Large Language Models | Moment-GPT | 01/2025 | - | AAAI |
🎞️ Video Feature Processing in VTG-MLLMs
Visual Feature
Efficient visual feature handling is essential for capturing more fine-grained temporal cues without overwhelming the model.
Compression
Directly compress visual features from densely sampled frames within budget constraints.
Refinement
Gradually refine predictions to maintain performance with the input token limitations.
| Title | Model | Date | Link | Venue |
|---|---|---|---|---|
| Self-Chained Image-Language Model for Video Localization and Question Answering | SeViLA | 05/2023 | project | NeurIPS |
| HawkEye: Training Video-Text LLMs for Grounding Text in Videos | HawkEye | 03/2024 | project | arXiv |
| SlowFocus: Enhancing Fine-grained Temporal Understanding in Video LLM | SlowFocus | 09/2024 | project | NeurIPS |
| ReVisionLLM: Recursive Vision-Language Model for Temporal Grounding in Hour-Long Videos | ReVisionLLM | 11/2024 | project | CVPR |
| VideoMind: A Chain-of-LoRA Agent for Long Video Reasoning | VideoMind | 04/2025 | project | arXiv |
Temporal Feature
Precise temporal feature representation and modeling is crucial for aligning visual content with fine-grained timestamp intervals, enabling accurate temporal reasoning in VTG tasks.
Explicit
Explicit modeling strategies directly furnish MLLMs with unambiguous temporal information, offering direct control and interpretability over temporal cues.
Implicit
Implicit modeling strategies are divided into two main types: Feature Infusion, which subtly integrates temporal context during feature extraction, and Intrinsic Reasoning, which leverages the inherent sequential processing of LLMs. By default, methods under this category are considered part of Intrinsic Reasoning, unless they explicitly incorporate external temporal features during encoding—in which case they are classified as Feature Infusion. The table below highlights representative works employing the Feature Infusion approach.
| Title | Model | Date | Link | Venue |
|---|---|---|---|---|
| TimeChat: A Time-sensitive Multimodal Large Language Model for Long Video Understanding | TimeChat | 12/2023 | project | CVPR |
| TimeSuite: Improving MLLMs for Long Video Understanding via Grounded Tuning | TimeSuite | 10/2024 | project | ICLR |
| Video LLMs for Temporal Reasoning in Long Videos | TemporalVLM | 12/2024 | project | arXiv |
Contact
If you find our survey is useful in your research, please consider giving us a star 🌟 and cite the following paper:
@article{wu2025surveyvideotemporalgrounding,
  title={A Survey on Video Temporal Grounding with Multimodal Large Language Model},
  author={Wu Jianlong and Liu Wei and Liu Ye and Liu Meng and Nie Liqiang and Lin Zhouchen and Chen Chang Wen},
  journal = {arXiv preprint arXiv:2508.10922},
  year={2025}
}
If you have any question about this project, do not hesitate to contact me liuwei030224@gmail.com.